

1.51 TB
295 files
Updated 4 months ago
Ctrl+K
TKMGLM-52 - Tekmonks Version

Introduction
Introducing Tekmonks tuned GLM-5.2, our latest flagship model for long-horizon tasks. It marks a substantial leap in long-horizon task capability over its predecessor GLM-5.1 and, for the first time, delivers that capability on a solid 1M-token context. GLM-5.2's new capabilities include:
- Solid 1M Context: A solid 1M-token context that stably sustains long-horizon work
- Advanced Coding with Flexible Effort: Stronger coding capabilities with multiple thinking effort levels to balance performance and latency
- Improved Architecture: We propose IndexShare, which reuses the same indexer across every four sparse attention layers, reducing per-token FLOPs by 2.9× at a 1M context length. We also improve GLM-5.2’s MTP layer for speculative decoding, increasing the acceptance length by up to 20%
- Pure Open: An MIT open-source license — no regional limits, technical access without borders
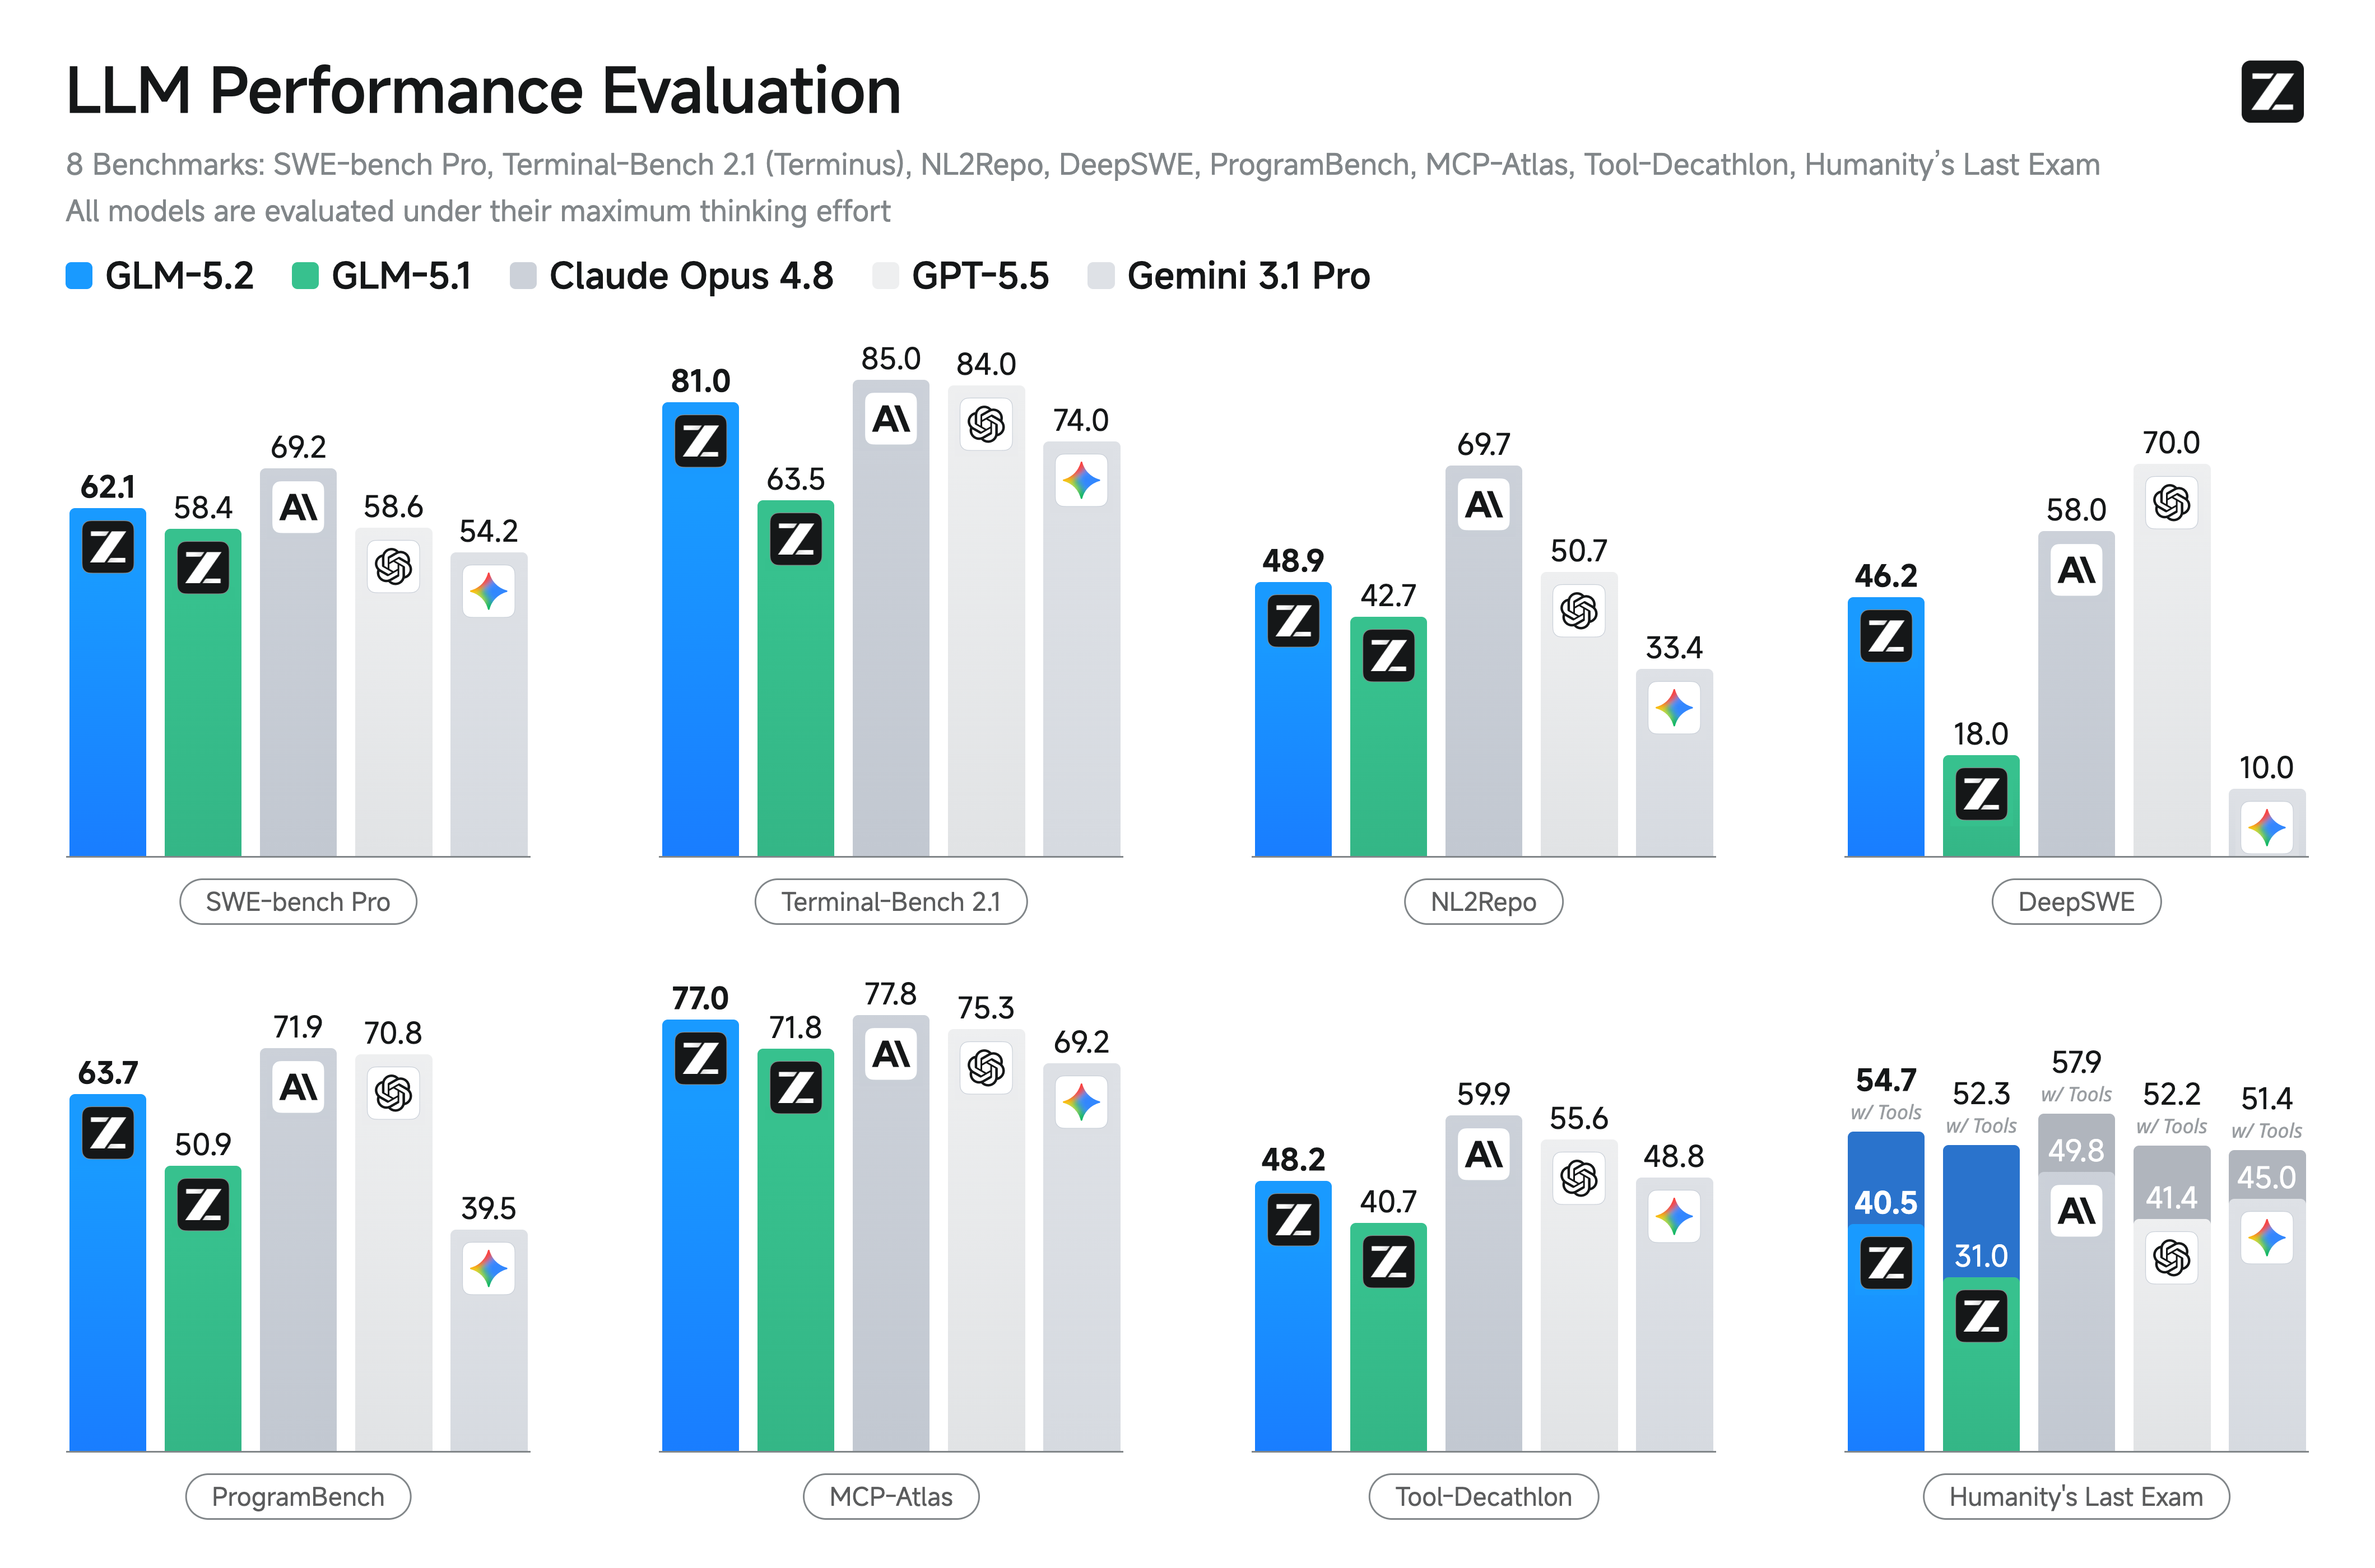
Benchmark
| Benchmark | TKMGLM-52 | GLM-5.1 | Qwen3.7-Max | MiniMax M3 | DeepSeek-V4-Pro | Claude Opus 4.8 | GPT-5.5 | Gemini 3.1 Pro |
|---|---|---|---|---|---|---|---|---|
| Reasoning | ||||||||
| HLE | 40.5 | 31 | 41.4 | 37 | 37.7 | 49.8* | 41.4* | 45 |
| HLE (w/ Tools) | 54.7 | 52.3 | 53.5 | - | 48.2 | 57.9* | 52.2* | 51.4* |
| CritPt | 20.9 | 4.6 | 13.4 | 3.7 | 12.9 | 20.9 | 27.1 | 17.7 |
| AIME 2026 | 99.2 | 95.3 | 97 | - | 94.6 | 95.7 | 98.3 | 98.2 |
| HMMT Nov. 2025 | 94.4 | 94 | 95 | 84.4 | 94.4 | 96.5 | 96.5 | 94.8 |
| HMMT Feb. 2026 | 92.5 | 82.6 | 97.1 | 84.4 | 95.2 | 96.7 | 96.7 | 87.3 |
| IMOAnswerBench | 91.0 | 83.8 | 90 | - | 89.8 | 83.5 | - | 81 |
| GPQA-Diamond | 91.2 | 86.2 | 90 | 93 | 90.1 | 93.6 | 93.6 | 94.3 |
| Coding | ||||||||
| SWE-bench Pro | 62.1 | 58.4 | 60.6 | 59 | 55.4 | 69.2 | 58.6 | 54.2 |
| NL2Repo | 48.9 | 42.7 | 47.2 | 42.1 | 35.5 | 69.7 | 50.7 | 33.4 |
| DeepSWE | 46.2 | 18 | 18 | 20 | 8 | 58 | 70 | 10 |
| ProgramBench | 63.7 | 50.9 | - | - | 47.8 | 71.9 | 70.8 | 39.5 |
| Terminal Bench 2.1 (Terminus-2) | 81.0 | 63.5 | 75 | 65 | 64 | 85 | 84 | 74 |
| Terminal Bench 2.1 (Best Reported Harness) | 82.7 | 69 | - | - | - | 78.9 | 83.4 | 70.7 |
| FrontierSWE (Dominance) | 74.4 | 30.5 | - | - | 29.0 | 75.1 | 72.6 | 39.6 |
| PostTrainBench | 34.3 | 20.1 | - | - | - | 37.2 | 28.4 | 21.6 |
| SWE-Marathon | 13.0 | 1.0 | - | - | - | 26.0 | 12.0 | 4.0 |
| Agentic | ||||||||
| MCP-Atlas (Public Set) | 76.8 | 71.8 | 76.4 | 74.2 | 73.6 | 77.8 | 75.3 | 69.2 |
| Tool-Decathlon | 48.2 | 40.7 | - | - | 52.8 | 59.9 | 55.6 | 48.8 |
Serve TKMGLM-5.2 Locally
TKMGLM-5.2 supports deployment with the following frameworks. Feel free to try them out:
- SGLang (v0.5.13.post1+) — see cookbook
- vLLM (v0.23.0+) — see recipes
- Transformers (v0.5.12+) — see transformers docs
- KTransformers (v0.5.12+) — see tutorial
- Unsloth (v0.1.47-beta+) — see guide
- For deployment on the
Ascend NPUplatform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — see here.
Footnote
- Humanity’s Last Exam (HLE) & other reasoning tasks: We use sampling parameters of
temperature=1.0,top_p=0.95for evaluation. We evaluate with a maximum generation length of163,840tokens. By default, we report the text-only subset; results marked with * are from the full set. For AIME, HMMT and IMOAnswerBench, we evaluate each question using the following system prompt:Your response should be in the following format:\nExplanation: {your explanation for your final answer}\nExact Answer: {your succinct, final answer}\nConfidence: {your confidence score between 0% and 100% for your answer}.We use GPT-5.5 (medium) as the judge model. For HLE-with-tools, we use a maximum context length of 300,000 tokens, with no context management strategy. - SWE-Bench Pro: We run the SWE-Bench Pro suite with OpenHands using a tailored instruction prompt. Settings:
temperature=1,top_p=1,max_new_tokens=32k, with a 400K context window. - NL2Repo: We evaluated NL2Repo with
temperature=1.0,top_p=1.0, andmax_new_tokens=48kunder 400k context. To prevent hacking, we use rule-based and a LLM-based judgement to prevent malicious behaviors (e.g., unauthorized pip or curl operations). - DeepSWE: We run DeepSWE with the official pier evaluation framework and the mini-swe-agent harness (
temperature=1.0,top_p=1.0,timeout=2h, 400K context). Each task is solved in an isolated container with 2 CPUs, 8 GB RAM, and no internet access. - ProgramBench: We evaluate ProgramBench (200 instances) with Claude-Code 2.1.156 using
temperature=1.0, top_p=1.0, max_tokens=64000, max_turns=2000, sample_timeout=6h, reasoning_effort=max, with a 400K context window. Each instance runs in a (4 CPUs, 8 GB RAM) sandbox with internet access disabled. - Terminal-Bench 2.1 (Terminus 2): We evaluate Terminal-Bench 2.1 with Terminus-2 framework using
parser=json,timeout=4h,temperature=1.0,top_p=1.0,max_new_tokens=48k,max_episodes=500, with a 256K context window. Resource limits are capped at 4 CPUs and 8 GB RAM. - Terminal-Bench 2.1 (Claude Code): We evaluate in Claude Code 2.1.167 with
temperature=1.0, top_p=0.95, max_new_tokens=131072. We override max_new_tokens to 128k via a transparent proxy, bypassing the 64k CLI cap to restore the configurability ofCLAUDE_CODE_MAX_OUTPUT_TOKENS. We remove wall-clock time limits, while preserving per-task CPU and memory constraints. Scores are averaged over 5 runs. - MCP-Atlas: All models were evaluated in think mode on the 500-task public subset with a 10-minute timeout per task. We use Gemini-3.0-Pro as the judge model for evaluation.
- Tool-Decathlon: We use the official evaluation service and set max_token to 128K.
- FrontierSWE: The evaluation was conducted by Proximal with 1M context length, max effort level, and 128K maximum output tokens. Dominance score reported as of 2026/06/16.
- PostTrainBench: The evaluation was conducted by PostTrainBench with 1M context length, max effort level, and 128K maximum output tokens.
- SWE-Marathon: The evaluation was conducted by Abundant AI with 1M context length, max effort level, and 128K maximum output tokens.
- Total size
- 1.51 TB
- Files
- 295
- Last updated
- Jul 1
- Pre-warmed CDN
- US EU US EU
