

Tacet Sonata


Tacet Sonata (codepawl/tacet-sonata) answers typed questions about a piece of state and gives a probability for every
option. It is an encoder, not a text generator: all questions and the state are packed into one
sequence and answered in one forward pass. 144M parameters, fine tuned from
jhu-clsp/mmBERT-small.
- choice: pick one of N named options, with a probability per option and a confidence.
- score: place the state on an ordered rubric, with a distribution over the levels and the expected score.
- noul: yes or no, with the probability of yes.
Use
pip install tacet
import tacet
from tacet import choice, score, noul

model = tacet.load("codepawl/tacet-sonata")
result = model.decide(
    state={"ticket": "I was charged twice for my March invoice. Please refund the second charge."},
    questions={
        "route": choice("Which team should handle this?",
                        {"billing": "payments, invoices, refunds", "tech": "bugs and outages"}),
        "urgency": score("How urgent is this?", ["low", "medium", "high"]),
        "refund": noul("Is the customer asking for a refund?"),
    },
)
print(result["answers"]["route"]["probabilities"])
Or serve the Tacet HTTP API (/v1/systemone, /v1/chat/completions) on localhost:
tacet serve --model codepawl/tacet-sonata
The code, the wire format and the error codes are documented at github.com/codepawl/tacet.
The weights are not a transformers model on their own: the head and the packed input format
live in the tacet package.
Evaluation
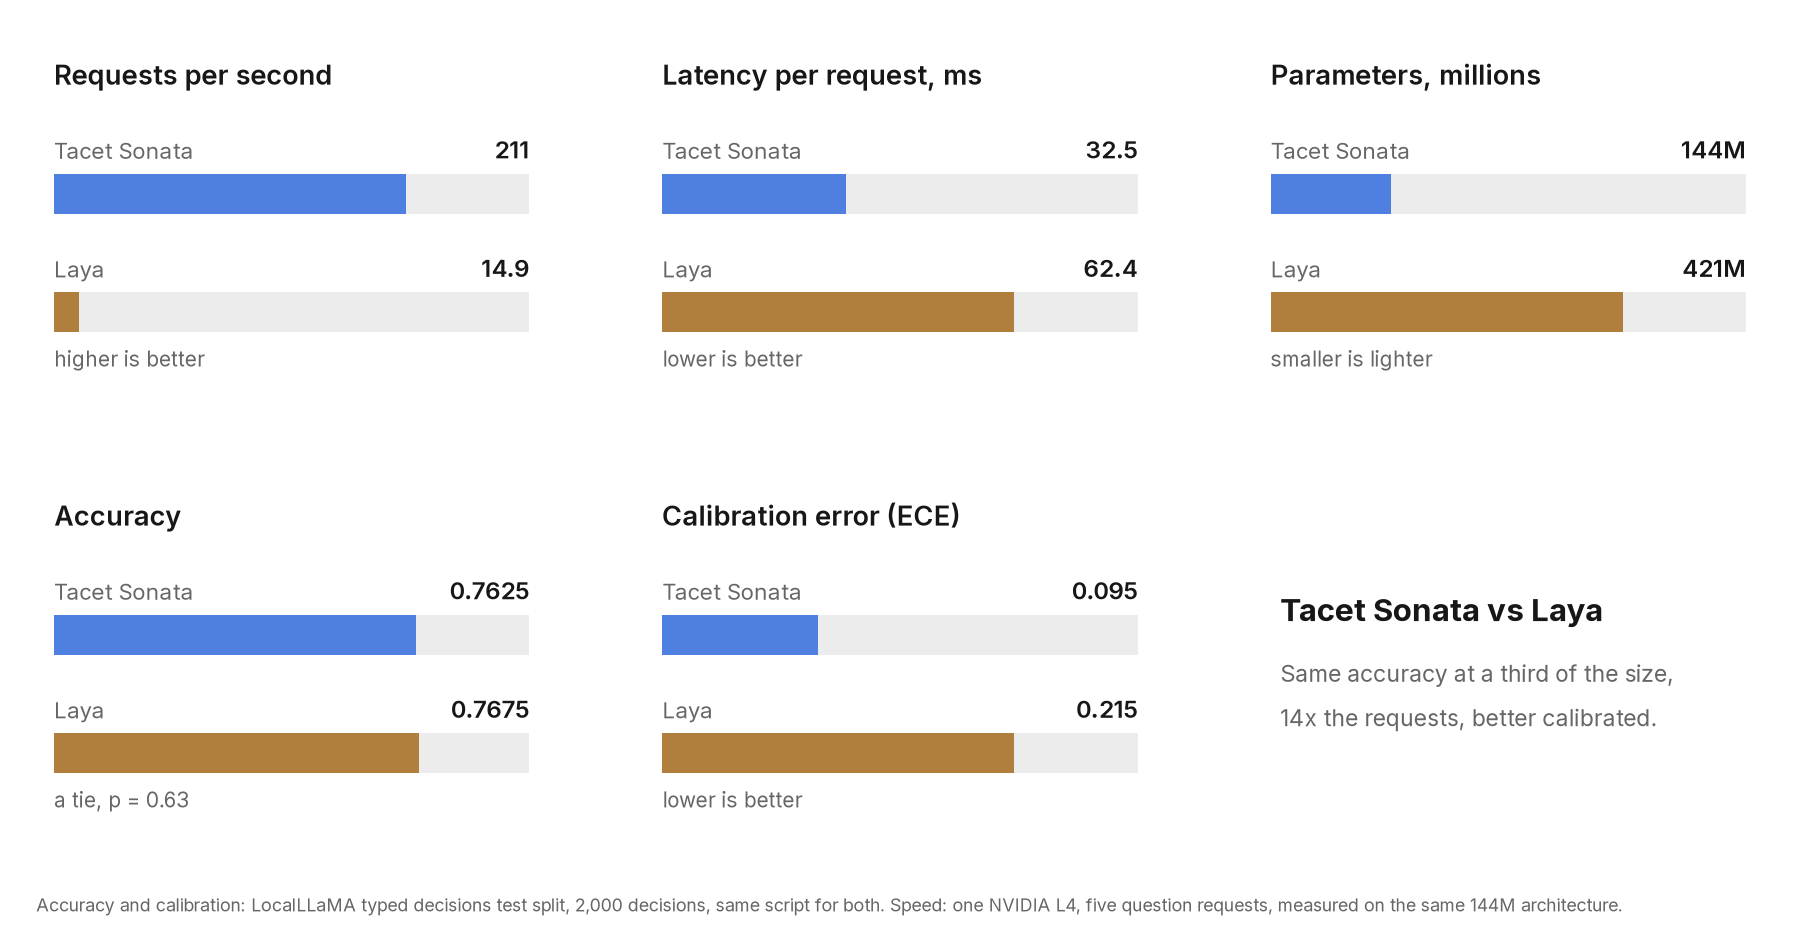
LocalLLaMA/typed-decisions test split, 400 cases, 2,000 decisions, scored with
scripts/benchmark.py in the tacet repository:
| model | parameters | accuracy | Brier | ECE (15 bins) |
|---|---|---|---|---|
| Tacet Sonata | 144M | 0.7625 | 0.0678 | 0.095 |
| Laya | 421M | 0.7675 | 0.0615 | 0.215 |
Both rows were scored with the same script on the same 2,000 decisions. The accuracy gap is not significant (paired McNemar p = 0.63), so treat it as a tie. Tacet's probabilities are closer to how often it is right (lower ECE), while Laya has the lower Brier score. The train split of this benchmark is part of the training data for both models, so these are in distribution numbers for its four workflows.
Other checks, on data outside that benchmark:
| evaluation | Tacet Sonata | first release candidate (benchmark only) |
|---|---|---|
| our hand written free text suite, 386 cases in 8 languages, 1,192 questions (not public) | 0.539 | 0.379 |
| MASSIVE intent and domain, test split, 16 languages | 0.778 | 0.370 |
Chance on the free text suite is about 0.35. The suite's cases were written for evaluation only and never trained on.
Limits
- Strong on the benchmark's four workflows (customer service, invoice processing, security incidents, agent trace observability) and on routing and triage questions like them.
- Yes or no answers depend a lot on wording. They are more reliable when the question uses the same words as the text than when it paraphrases.
- Weaker on long free text, on questions that need date arithmetic, and on counting. If a decision depends on a number, compute it in code and put it in the state.
- The probabilities are calibrated on the training distribution. Check them against your own labelled examples before you gate anything on a confidence threshold.
- Reads at most 1536 tokens by default and up to 4096 with
max_length. A longer state is cut and the response says so (usage.state_truncated). - Does not generate text or explain its answers.
Training data
| data | cases | licence |
|---|---|---|
| Synthetic cases in 16 languages, written and labelled by Qwen3-30B-A3B-Instruct-2507, disputed questions relabelled by Qwen3-30B-A3B-Thinking-2507 | 14,355 | Apache 2.0 |
| LocalLLaMA/typed-decisions (train split) | 1,200 | Apache 2.0 |
| AmazonScience MASSIVE | 601 | CC BY 4.0 |
| PolyAI banking77 | 137 | CC BY 4.0 |
| Bitext customer support | 141 | CDLA Sharing 1.0 (no obligations on Results, section 3.5) |
| google/civil_comments | 134 | CC0 1.0 |
The labelled datasets were turned into typed decision cases: their labels became the answers to choice, score and yes or no questions. Nothing with a share alike licence or an unknown upstream licence is in the mix. The weights are an average of three training runs with different seeds.
License
Apache 2.0. The backbone, mmBERT by JHU CLSP, is MIT licensed; its notice and the other attributions are in the NOTICE file in this repository.
Contact: hello@codepawl.com
- Downloads last month
- 18
Model tree for codepawl/tacet-sonata
Base model
jhu-clsp/mmBERT-smallDatasets used to train codepawl/tacet-sonata
Evaluation results
- Accuracy on LocalLLaMA/typed-decisionstest set self-reported0.762
- Brier score on LocalLLaMA/typed-decisionstest set self-reported0.068
- Expected calibration error on LocalLLaMA/typed-decisionstest set self-reported0.095