
Datasets:

video video 0.04 335 | label class label 3
classes |
|---|---|
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real | |
00_real |
LipSync-A
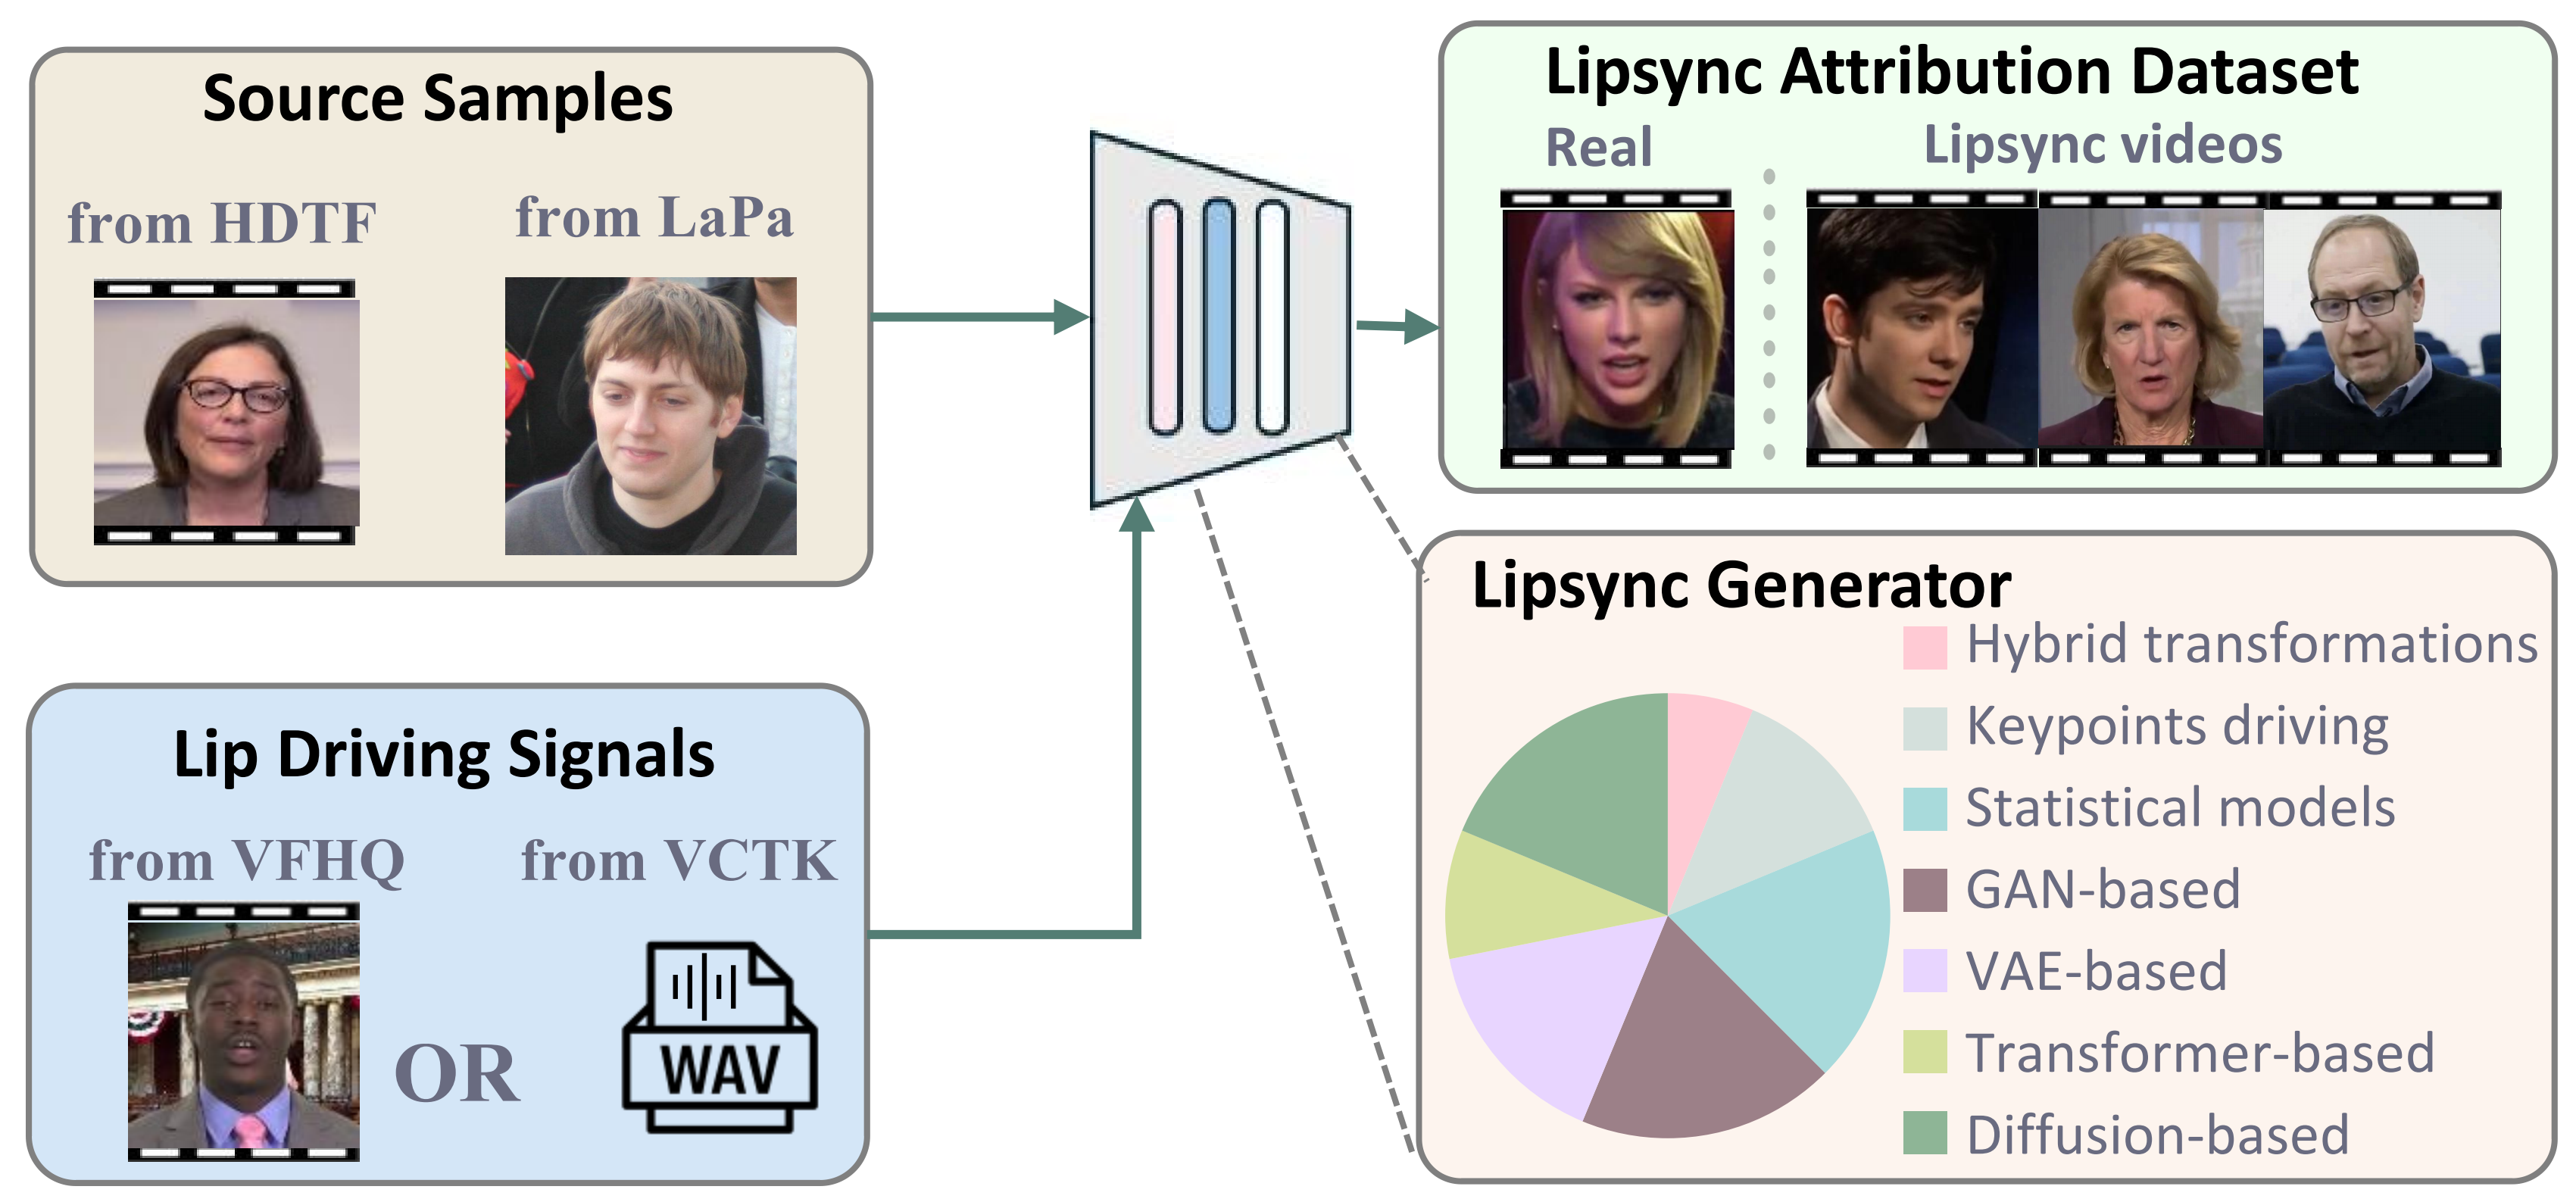
Overview
LipSync-A is a multi-generator talking-head dataset for LipSync detection and source attribution. It is introduced in Ariadne’s Thread of LipSync: Unraveling Forgeries via Inconsistency between Lip Motions and Head Poses (ICML 2026).
LipSync forgeries keep the source face and fabricate speech that was never spoken. LipSync-A labels every clip with its generator so a model can both detect the forgery and trace which method produced it.
This release contains 21 generators and 10,573 forged videos. 9,474 of them have a paired real clip. Identity and driving signals come from VFHQ, VoxCeleb, VCTK, HDTF, and LaPa.
Dataset structure
Each generator is one top-level folder. The folder name is the attribution label.
| Path | Content |
|---|---|
1_fake/ |
Forged talking-head video |
2_identity/ |
Identity image or video |
3_audio/ |
Driving audio (audio-driven methods) |
0_real/ |
Paired real video, same stem as 1_fake |
selection.json |
Sample list and source metadata |
0_real is the identity-source clip for audio-driven methods, and the driving video for video-driven methods. LaPa / MEAD stills and commercial Wan outputs have no recoverable real video, so those samples have no 0_real.
Methods
The table below is the composition of this release: each folder is one generator, labeled by architecture family, driving paradigm, and the data used to train the original model.
| Generator | Category | Paradigm | Training Data |
|---|---|---|---|
| X2Face (Wiles et al., 2018) | Geometric | Video-driven | VoxCeleb |
| TPSM (Zhao & Zhang, 2022) | Landmark | Video-driven | VoxCeleb |
| FaceVid (Wang et al., 2021) | Landmark | Video-driven | VoxCeleb |
| LIA (Wang et al.) | Latent Space | Video-driven | VoxCeleb |
| DINet (Zhang et al., 2023) | CNN | Audio-driven | HDTF, MEAD |
| DaGAN (Hong et al., 2022) | GAN | Video-driven | VoxCeleb |
| MakeItTalk (Zhou et al., 2020) | GAN | Audio-driven | VoxCeleb, ObamaSet |
| Wav2Lip (Prajwal et al., 2020) | GAN | Audio-driven | LRW, LRS2 |
| TalkLip (Wang et al., 2023) | GAN | Audio-driven | LRS |
| SadTalker (Zhang et al., 2023) | VAE | Audio-driven | VoxCeleb |
| V-Express (Wang et al., 2024) | VAE | Audio-driven | VFHQ |
| IP_LAP (Zhong et al., 2023) | Transformer | Audio-driven | LRS2 |
| EAT (Gan et al., 2023) | Transformer | Audio-driven | MEAD, LRW |
| DreamTalk (Ma et al., 2023) | Diffusion | Audio-driven | MEAD, HDTF |
| Sonic (Ji et al., 2025) | Diffusion | Audio-driven | VFHQ, CelebV-Text |
| KDTalker (Yang et al., 2025) | Diffusion | Audio-driven | HDTF |
| OmniSync (Peng et al., 2025) | Diffusion | Audio-driven | Web-Collected |
| InfiniteTalk (Yang et al., 2025) | Diffusion | Audio-driven | Internal |
| LatentSync (Li et al., 2024) | Diffusion | Audio-driven | VoxCeleb2, HDTF |
| SkyReels | Diffusion | Audio-driven | Internal |
| WavSV (Wan, commercial) | Diffusion | Audio-driven | Internal |
Folder names match the attribution labels: face_vid, wav2lip, talklip, and dreamtalk correspond to FaceVid, Wav2Lip, TalkLip, and DreamTalk.
Citation
@inproceedings{she2026ariadne,
  title     = {Ariadne's Thread of LipSync: Unraveling Forgeries via Inconsistency between Lip Motions and Head Poses},
  author    = {She, Tianyi and Liu, Jiawei and Liu, Weifeng and Zhao, Hanqing and Zhang, Weiming and Chen, Kejiang},
  booktitle = {Proceedings of the 43rd International Conference on Machine Learning},
  year      = {2026}
}
Ethical Statement
When using this dataset, comply with applicable laws and regulations. Do not use it to create misleading or deceptive media.
- Downloads last month
- -