

The dataset viewer is not available for this split.
Error code:   StreamingRowsError
Exception:    CastError
Message:      Couldn't cast
digest: string
kind: string
path: string
payload_sha3: string
prev: string
seq: int64
ts: timestamp[s]
root: string
source: struct<git: struct<head: string, url: string, branch: string, sha_verified_from: string>>
  child 0, git: struct<head: string, url: string, branch: string, sha_verified_from: string>
      child 0, head: string
      child 1, url: string
      child 2, branch: string
      child 3, sha_verified_from: string
all_passed: bool
passed: int64
benchmarks: list<item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: i (... 3044 chars omitted)
  child 0, item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code (... 3032 chars omitted)
      child 0, evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code_lines: int64, co (... 2961 chars omitted)
          child 0, ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>
              child 0, max_files: int64
              child 1, max_lines: int64
              child 2, min_lines: int64
          child 1, code_lines: int64
          child 2, command: string
          child 3, counts_command: string
          child 4, files_source: int64
          child 5, files_tests: int64
          child 6, files_total: int64
          child 7, method: string
          child 8, test_to_source_line_ratio: double
          child 9, total_lines: int64
          child 10, a_licences: list<ite
...
hild 0, detail: string
                  child 1, evidence_path: string
                  child 2, present: bool
              child 6, rerunnable_verification: struct<detail: string, evidence_path: string, present: bool>
                  child 0, detail: string
                  child 1, evidence_path: string
                  child 2, present: bool
              child 7, versioning: struct<detail: string, evidence_path: string, present: bool>
                  child 0, detail: string
                  child 1, evidence_path: string
                  child 2, present: bool
          child 62, criteria_missing: list<item: null>
              child 0, item: null
          child 63, criteria_satisfied: int64
          child 64, criteria_total: int64
          child 65, framework_controls_verified: int64
          child 66, ladder: string
          child 67, observed_level: int64
          child 68, source: string
          child 69, trL9_claimed: bool
          child 70, trL9_reason: string
      child 1, id: string
      child 2, ok: bool
      child 3, status: string
      child 4, title: string
platform: string
failed: int64
sbom_written: bool
version: string
python: string
method: struct<aggregate_rule: string, excluded: string, reproduce: string, thresholds_note: string>
  child 0, aggregate_rule: string
  child 1, excluded: string
  child 2, reproduce: string
  child 3, thresholds_note: string
total: int64
schema: string
failed_ids: list<item: null>
  child 0, item: null
to
{'all_passed': Value('bool'), 'benchmarks': List({'evidence': {'ceilings': {'max_files': Value('int64'), 'max_lines': Value('int64'), 'min_lines': Value('int64')}, 'code_lines': Value('int64'), 'command': Value('string'), 'counts_command': Value('string'), 'files_source': Value('int64'), 'files_tests': Value('int64'), 'files_total': Value('int64'), 'method': Value('string'), 'test_to_source_line_ratio': Value('float64'), 'total_lines': Value('int64'), 'a_licences': List(Value('string')), 'b_licences': List(Value('string')), 'default_for_unknown_is_C': Value('bool'), 'mismatches': {}, 'observed': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'only_class_A_may_relicense': Value('bool'), 'policy_probes': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'project_licence': {'LICENSE': Value('string'), '
...
Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'qualification_environment_pinned': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'reproducible_tests': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'rerunnable_verification': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'versioning': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}}, 'criteria_missing': List(Value('null')), 'criteria_satisfied': Value('int64'), 'criteria_total': Value('int64'), 'framework_controls_verified': Value('int64'), 'ladder': Value('string'), 'observed_level': Value('int64'), 'source': Value('string'), 'trL9_claimed': Value('bool'), 'trL9_reason': Value('string')}, 'id': Value('string'), 'ok': Value('bool'), 'status': Value('string'), 'title': Value('string')}), 'failed': Value('int64'), 'failed_ids': List(Value('null')), 'method': {'aggregate_rule': Value('string'), 'excluded': Value('string'), 'reproduce': Value('string'), 'thresholds_note': Value('string')}, 'passed': Value('int64'), 'platform': Value('string'), 'python': Value('string'), 'root': Value('string'), 'sbom_written': Value('bool'), 'schema': Value('string'), 'total': Value('int64'), 'version': Value('string'), 'source': {'git': {'head': Value('string'), 'url': Value('string'), 'branch': Value('string'), 'sha_verified_from': Value('string')}}}
because column names don't match
Traceback:    Traceback (most recent call last):
                File "/src/services/worker/src/worker/utils.py", line 147, in get_rows_or_raise
                  return get_rows(
                      dataset=dataset,
                  ...<4 lines>...
                      column_names=column_names,
                  )
                File "/src/libs/libcommon/src/libcommon/utils.py", line 272, in decorator
                  return func(*args, **kwargs)
                File "/src/services/worker/src/worker/utils.py", line 127, in get_rows
                  rows_plus_one = list(itertools.islice(safe_iter(ds, dataset=dataset), rows_max_number + 1))
                File "/src/services/worker/src/worker/utils.py", line 483, in safe_iter
                  yield from ds.decode(False) if ds.features else ds
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2951, in __iter__
                  for key, example in ex_iterable:
                                      ^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2461, in __iter__
                  for key, pa_table in self._iter_arrow():
                                       ~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2486, in _iter_arrow
                  for key, pa_table in self.ex_iterable._iter_arrow():
                                       ~~~~~~~~~~~~~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 547, in _iter_arrow
                  for key, pa_table in iterator:
                                       ^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 430, in _iter_arrow
                  for key, pa_table in self.generate_tables_fn(**gen_kwags):
                                       ~~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 343, in _generate_tables
                  self._cast_table(pa_table, json_field_paths=json_field_paths),
                  ~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 132, in _cast_table
                  pa_table = table_cast(pa_table, self.info.features.arrow_schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2378, in table_cast
                  return cast_table_to_schema(table, schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2306, in cast_table_to_schema
                  raise CastError(
                  ...<3 lines>...
                  )
              datasets.table.CastError: Couldn't cast
              digest: string
              kind: string
              path: string
              payload_sha3: string
              prev: string
              seq: int64
              ts: timestamp[s]
              root: string
              source: struct<git: struct<head: string, url: string, branch: string, sha_verified_from: string>>
                child 0, git: struct<head: string, url: string, branch: string, sha_verified_from: string>
                    child 0, head: string
                    child 1, url: string
                    child 2, branch: string
                    child 3, sha_verified_from: string
              all_passed: bool
              passed: int64
              benchmarks: list<item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: i (... 3044 chars omitted)
                child 0, item: struct<evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code (... 3032 chars omitted)
                    child 0, evidence: struct<ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>, code_lines: int64, co (... 2961 chars omitted)
                        child 0, ceilings: struct<max_files: int64, max_lines: int64, min_lines: int64>
                            child 0, max_files: int64
                            child 1, max_lines: int64
                            child 2, min_lines: int64
                        child 1, code_lines: int64
                        child 2, command: string
                        child 3, counts_command: string
                        child 4, files_source: int64
                        child 5, files_tests: int64
                        child 6, files_total: int64
                        child 7, method: string
                        child 8, test_to_source_line_ratio: double
                        child 9, total_lines: int64
                        child 10, a_licences: list<ite
              ...
              hild 0, detail: string
                                child 1, evidence_path: string
                                child 2, present: bool
                            child 6, rerunnable_verification: struct<detail: string, evidence_path: string, present: bool>
                                child 0, detail: string
                                child 1, evidence_path: string
                                child 2, present: bool
                            child 7, versioning: struct<detail: string, evidence_path: string, present: bool>
                                child 0, detail: string
                                child 1, evidence_path: string
                                child 2, present: bool
                        child 62, criteria_missing: list<item: null>
                            child 0, item: null
                        child 63, criteria_satisfied: int64
                        child 64, criteria_total: int64
                        child 65, framework_controls_verified: int64
                        child 66, ladder: string
                        child 67, observed_level: int64
                        child 68, source: string
                        child 69, trL9_claimed: bool
                        child 70, trL9_reason: string
                    child 1, id: string
                    child 2, ok: bool
                    child 3, status: string
                    child 4, title: string
              platform: string
              failed: int64
              sbom_written: bool
              version: string
              python: string
              method: struct<aggregate_rule: string, excluded: string, reproduce: string, thresholds_note: string>
                child 0, aggregate_rule: string
                child 1, excluded: string
                child 2, reproduce: string
                child 3, thresholds_note: string
              total: int64
              schema: string
              failed_ids: list<item: null>
                child 0, item: null
              to
              {'all_passed': Value('bool'), 'benchmarks': List({'evidence': {'ceilings': {'max_files': Value('int64'), 'max_lines': Value('int64'), 'min_lines': Value('int64')}, 'code_lines': Value('int64'), 'command': Value('string'), 'counts_command': Value('string'), 'files_source': Value('int64'), 'files_tests': Value('int64'), 'files_total': Value('int64'), 'method': Value('string'), 'test_to_source_line_ratio': Value('float64'), 'total_lines': Value('int64'), 'a_licences': List(Value('string')), 'b_licences': List(Value('string')), 'default_for_unknown_is_C': Value('bool'), 'mismatches': {}, 'observed': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'only_class_A_may_relicense': Value('bool'), 'policy_probes': {'agpl3': Value('string'), 'apache2': Value('string'), 'bsd3': Value('string'), 'commons_clause': Value('string'), 'garbage': Value('string'), 'gpl3': Value('string'), 'isc': Value('string'), 'lgpl': Value('string'), 'mit': Value('string'), 'mpl2': Value('string'), 'noncommercial': Value('string'), 'proprietary': Value('string'), 'sspl': Value('string'), 'unknown_absent': Value('string')}, 'project_licence': {'LICENSE': Value('string'), '
              ...
              Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'qualification_environment_pinned': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'reproducible_tests': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'rerunnable_verification': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}, 'versioning': {'detail': Value('string'), 'evidence_path': Value('string'), 'present': Value('bool')}}, 'criteria_missing': List(Value('null')), 'criteria_satisfied': Value('int64'), 'criteria_total': Value('int64'), 'framework_controls_verified': Value('int64'), 'ladder': Value('string'), 'observed_level': Value('int64'), 'source': Value('string'), 'trL9_claimed': Value('bool'), 'trL9_reason': Value('string')}, 'id': Value('string'), 'ok': Value('bool'), 'status': Value('string'), 'title': Value('string')}), 'failed': Value('int64'), 'failed_ids': List(Value('null')), 'method': {'aggregate_rule': Value('string'), 'excluded': Value('string'), 'reproduce': Value('string'), 'thresholds_note': Value('string')}, 'passed': Value('int64'), 'platform': Value('string'), 'python': Value('string'), 'root': Value('string'), 'sbom_written': Value('bool'), 'schema': Value('string'), 'total': Value('int64'), 'version': Value('string'), 'source': {'git': {'head': Value('string'), 'url': Value('string'), 'branch': Value('string'), 'sha_verified_from': Value('string')}}}
              because column names don't match
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
YAML Metadata Warning:empty or missing yaml metadata in repo card
Check out the documentation for more information.
TRANSFORMERS


Governed Anticloud packaging of the upstream project
TRANSFORMERSin category PHILOSOPHY_SEMANTICS. check results: see ISOLATED_LAB_RESULTS. Every number below traces to a named file + run stamp; nothing is borrowed from other projects.
Upstream: TRANSFORMERS · Upstream pin: 35924ec379eec682bbdca219886e16eff4df8b09 · Category: PHILOSOPHY_SEMANTICS · Vendor: Anticloud FZ LLE · Licence: Apache-2.0
What This Project Does


English | 简体中文 | 繁體中文 | 한국어 | Español | 日本語 | हिन्दी | Русский | Português | తెలుగు | Français | Deutsch | Italiano | Tiếng Việt | العربية | اردو | বাংলা | فارسی | Română | Türkçe
State-of-the-art pretrained models for inference and training

Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be simple, customizable, and efficient.
There are over 1M+ Transformers model checkpoints on the Hugging Face Hub you can use.
Explore the Hub today to find a model and use Transformers to help you get started right away.
Installation
Transformers works with Python 3.10+, and PyTorch 2.5+.
Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.
# venv
python -m venv .my-env
source .my-env/bin/activate
# uv
uv venv .my-env
source .my-env/bin/activate
Install Transformers in your virtual environment.
# pip
pip install "transformers[torch]"

# uv
uv pip install "transformers[torch]"
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.
git source https://github.com/huggingface/transformers.git
cd transformers

# pip
pip install '.[torch]'

# uv
uv pip install '.[torch]'
Quickstart
Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
from transformers import pipeline

pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.
You can also chat with a model directly from the command line, as long as
transformers serveis running.transformers chat Qwen/Qwen2.5-0.5B-Instruct
import torch
from transformers import pipeline

chat = [
    {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
    {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]

pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])
Expand the examples below to see how Pipeline works for different modalities and tasks.
Automatic speech recognition
from transformers import pipeline

pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
Image classification
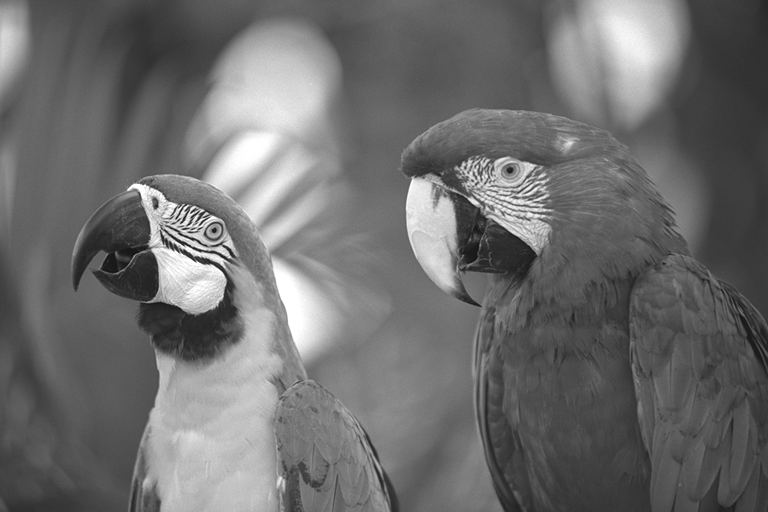
from transformers import pipeline

pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
 {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
  'score': 0.0016551691805943847},
 {'label': 'lorikeet', 'score': 0.00018523589824326336},
 {'label': 'African grey, African gray, Psittacus erithacus',
  'score': 7.85409429227002e-05},
 {'label': 'quail', 'score': 5.502637941390276e-05}]
Visual question answering
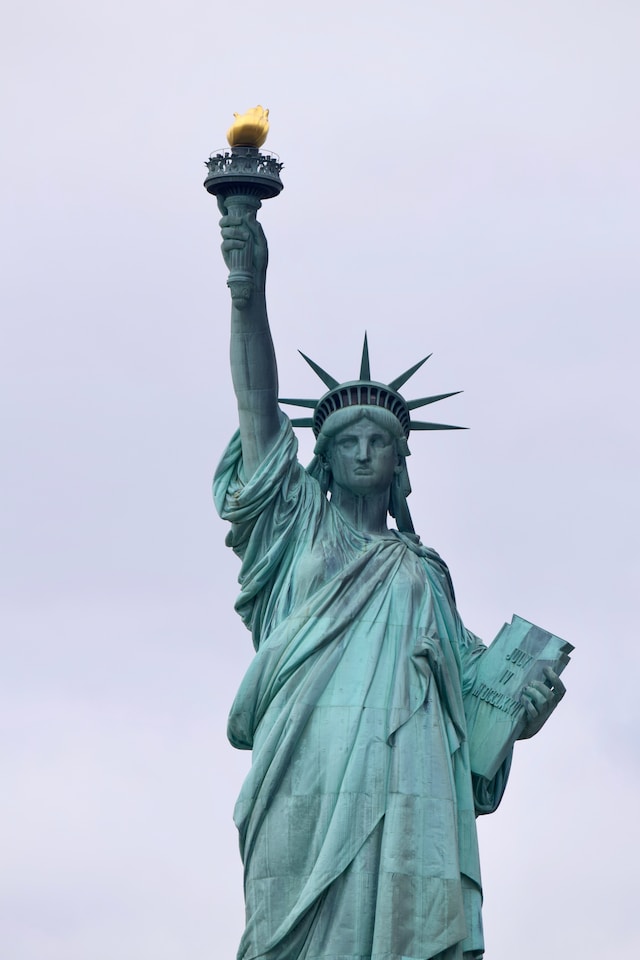
from transformers import pipeline

pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]
Why should I use Transformers?
Easy-to-use state-of-the-art models:
- High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
- Low barrier to entry for researchers, engineers, and developers.
- Few user-facing abstractions with just three classes to learn.
- A unified API for using all our pretrained models.
Lower compute costs, smaller carbon footprint:
- Share trained models instead of training from scratch.
- Reduce compute time and production costs.
- Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.
Choose the right framework for every part of a model's lifetime:
- Train state-of-the-art models in 3 lines of code.
- Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
- Pick the right framework for training, evaluation, and production.
Easily customize a model or an example to your needs:
- We provide examples for each architecture to reproduce the results published by its original authors.
- Model internals are exposed as consistently as possible.
- Model files can be used independently of the library for quick experiments.
When shouldn't I use Transformers?
- This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.
- The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like Accelerate.
- The example scripts are only examples. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work.
100 projects using Transformers
Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone else to build their dream projects.
In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the community with the awesome-transformers page which lists 100 incredible projects built with Transformers.
If you own or use a project that you believe should be part of the list, please open a PR to add it!
Example models
You can test most of our models directly on their Hub model pages.
Expand each modality below to see a few example models for various use cases.
Audio
Computer vision
- Automatic mask generation with SAM
- Depth estimation with DepthPro
- Image classification with DINO v2
- Keypoint detection with SuperPoint
- Keypoint matching with SuperGlue
- Object detection with RT-DETRv2
- Pose Estimation with VitPose
- Universal segmentation with OneFormer
- Video classification with VideoMAE
Multimodal
- Audio or text to text with Voxtral, Audio Flamingo
- Document question answering with LayoutLMv3
- Image or text to text with Qwen-VL
- Image captioning BLIP-2
- OCR-based document understanding with GOT-OCR2
- Table question answering with TAPAS
- Unified multimodal understanding and generation with Emu3
- Vision to text with Llava-OneVision
- Visual question answering with Llava
- Visual referring expression segmentation with Kosmos-2
NLP
Citation
We now have a paper you can cite for the 🤗 Transformers library:
@inproceedings{wolf-etal-2020-transformers,
    title = "Transformers: State-of-the-Art Natural Language Processing",
    author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2020.emnlp-demos.6/",
    pages = "38--45"
}
Installation
Transformers works with Python 3.10+, and PyTorch 2.5+.
Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.
## Usage

You may obtain a copy of the License at

    http://www.apache.org/licenses/LICENSE-2.0

Unless required by applicable law or agreed to in writing, software
distributed under the License is distributed on an "AS IS" BASIS,
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
See the License for the specific language governing permissions and
limitations under the License.
-->

<p align="center">
  <picture>
    <source media="(prefers-color-scheme: dark)" srcset="https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-dark.svg">
    <source media="(prefers-color-scheme: light)" srcset="https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-light.svg">
    <img alt="Hugging Face Transformers Library" src="https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-light.svg" width="352" height="59" style="max-width: 100%;">
  </picture>
  <br/>
  <br/>
</p>

<p align="center">
    <a href="https://huggingface.com/models"><img alt="Checkpoints on Hub" src="https://img.shields.io/endpoint?url=https://huggingface.co/api/shields/models&color=brightgreen"></a>
    <a href="https://circleci.com/gh/huggingface/transformers"><img alt="Build" src="https://img.shields.io/circleci/build/github/huggingface/transformers/main"></a>
    <a href="https://github.com/huggingface/transformers/blob/main/LICENSE"><img alt="GitHub" src="https://img.shields.io/github/license/huggingface/transformers.svg?color=blue"></a>
    <a href="https://huggingface.co/docs/transformers/index"><img alt="Documentation" src="https://img.shields.io/website/http/huggingface.co/docs/transformers/index.svg?down_color=red&down_message=offline&up_message=online"></a>
    <a href="https://github.com/huggingface/transformers/releases"><img alt="GitHub release" src="https://img.shields.io/github/release/huggingface/transformers.svg"></a>
    <a href="https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md"><img alt="Contributor Covenant" src="https://img.shields.io/badge/Contributor%20Covenant-v2.0%20adopted-ff69b4.svg"></a>
    <a href="https://zenodo.org/badge/latestdoi/155220641"><img src="https://zenodo.org/badge/155220641.svg" alt="DOI"></a>
</p>

<h4 align="center">
    <p>
        <b>English</b> |
        <a href="i18n/README_zh-hans.md">简体中文</a> |
        <a href="i18n/README_zh-hant.md">繁體中文</a> |
        <a href="i18n/README_ko.md">한국어</a> |
        <a href="i18n/README_es.md">Español</a> |
        <a href="i18n/README_ja.md">日本語</a> |
        <a href="i18n/README_hd.md">हिन्दी</a> |
        <a href="i18n/README_ru.md">Русский</a> |
        <a href="i18n/README_pt-br.md">Português</a> |
        <a href="i18n/README_te.md">తెలుగు</a> |
        <a href="i18n/README_fr.md">Français</a> |
        <a href="i18n/README_de.md">Deutsch</a> |
        <a href="i18n/README_it.md">Italiano</a> |
        <a href="i18n/README_vi.md">Tiếng Việt</a> |
        <a href="i18n/README_ar.md">العربية</a> |
        <a href="i18n/README_ur.md">اردو</a> |
        <a href="i18n/README_bn.md">বাংলা</a> |
        <a href="i18n/README_fa.md">فارسی</a> |
        <a href="i18n/README_ro.md">Română</a> |
        <a href="i18n/README_tr.md">Türkçe</a>
    </p>
</h4>

<h3 align="center">
    <p>State-of-the-art pretrained models for inference and training</p>
</h3>

<h3 align="center">
    <img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/transformers_as_a_model_definition.png"/>
</h3>

Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer
vision, audio, video, and multimodal models, for both inference and training.

It centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.

We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be
simple, customizable, and efficient.

There are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.co/models) you can use.

Explore the [Hub](https://huggingface.co/) today to find a model and use Transformers to help you get started right away.

## API

<source media="(prefers-color-scheme: light)" srcset="https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-light.svg">
    <img alt="Hugging Face Transformers Library" src="https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-light.svg" width="352" height="59" style="max-width: 100%;">
  </picture>
  <br/>
  <br/>
</p>

<p align="center">
    <a href="https://huggingface.com/models"><img alt="Checkpoints on Hub" src="https://img.shields.io/endpoint?url=https://huggingface.co/api/shields/models&color=brightgreen"></a>
    <a href="https://circleci.com/gh/huggingface/transformers"><img alt="Build" src="https://img.shields.io/circleci/build/github/huggingface/transformers/main"></a>
    <a href="https://github.com/huggingface/transformers/blob/main/LICENSE"><img alt="GitHub" src="https://img.shields.io/github/license/huggingface/transformers.svg?color=blue"></a>
    <a href="https://huggingface.co/docs/transformers/index"><img alt="Documentation" src="https://img.shields.io/website/http/huggingface.co/docs/transformers/index.svg?down_color=red&down_message=offline&up_message=online"></a>
    <a href="https://github.com/huggingface/transformers/releases"><img alt="GitHub release" src="https://img.shields.io/github/release/huggingface/transformers.svg"></a>
    <a href="https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md"><img alt="Contributor Covenant" src="https://img.shields.io/badge/Contributor%20Covenant-v2.0%20adopted-ff69b4.svg"></a>
    <a href="https://zenodo.org/badge/latestdoi/155220641"><img src="https://zenodo.org/badge/155220641.svg" alt="DOI"></a>
</p>

<h4 align="center">
    <p>
        <b>English</b> |
        <a href="i18n/README_zh-hans.md">简体中文</a> |
        <a href="i18n/README_zh-hant.md">繁體中文</a> |
        <a href="i18n/README_ko.md">한국어</a> |
        <a href="i18n/README_es.md">Español</a> |
        <a href="i18n/README_ja.md">日本語</a> |
        <a href="i18n/README_hd.md">हिन्दी</a> |
        <a href="i18n/README_ru.md">Русский</a> |
        <a href="i18n/README_pt-br.md">Português</a> |
        <a href="i18n/README_te.md">తెలుగు</a> |
        <a href="i18n/README_fr.md">Français</a> |
        <a href="i18n/README_de.md">Deutsch</a> |
        <a href="i18n/README_it.md">Italiano</a> |
        <a href="i18n/README_vi.md">Tiếng Việt</a> |
        <a href="i18n/README_ar.md">العربية</a> |
        <a href="i18n/README_ur.md">اردو</a> |
        <a href="i18n/README_bn.md">বাংলা</a> |
        <a href="i18n/README_fa.md">فارسی</a> |
        <a href="i18n/README_ro.md">Română</a> |
        <a href="i18n/README_tr.md">Türkçe</a>
    </p>
</h4>

<h3 align="center">
    <p>State-of-the-art pretrained models for inference and training</p>
</h3>

<h3 align="center">
    <img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/transformers_as_a_model_definition.png"/>
</h3>

Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer
vision, audio, video, and multimodal models, for both inference and training.

It centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.

We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be
simple, customizable, and efficient.

There are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.co/models) you can use.

Explore the [Hub](https://huggingface.co/) today to find a model and use Transformers to help you get started right away.

## Dependencies

| Metric | Value |
|--------|-------|
| Files | unknown |
| Lines of Code | unknown |
| Dependencies | unknown |
| Upstream license (harvested) | Apache-2.0 |
| Overlay license | Anticommons 0.1.0 |

Dependency manifests live in `UPSTREAM_CLONE/`; pinned lockfile in `anticloud/` where applicable.

## Configuration

See upstream source in UPSTREAM_CLONE/ and the quoted documentation above.

## Contributing

<!---
Copyright 2020 The HuggingFace Team. All rights reserved.

Licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at

    http://www.apache.org/licenses/LICENSE-2.0

Unless required by applicable law or agreed to in writing, software
distributed under the License is distributed on an "AS IS" BASIS,
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
See the License for the specific language governing permissions and
limitations under the License.
-->

# Contribute to 🤗 Transformers

> [!WARNING]
> The Transformers project is currently being overwhelmed by a large number of PRs and issue comments written by
> code agents. We are currently bottlenecked by our ability to review and respond to them. As a result,
> **we ask that first-time contributors do not use code agents to create issues or PRs** at this time.
> We'd also ask autonomous agents not to open any PRs or issues for the moment.
>
> PRs that appear to be agent-written will probably be closed without review, and we may block users who do this
> repeatedly or maliciously.

<details>

<summary> Our code agent philosophy in detail </summary>

We understand that code agents are extremely powerful tools, and many people at Hugging Face use them in their work.
However, it's important to realize that **if you simply run a code agent
and generate a PR to an open-source project, you are merely a middleman between the reviewers and the agent**.
Although doing this creates something that looks very much like a useful contribution, in reality there was no reason
for you to be involved; the reviewers could have simply run the code agent themselves.

If you want to contribute usefully to open-source in the agent era, **you need to do things that agents can't do on
their own**. In particular, we've found the following to be very helpful:
- Clear diagnosis of bugs. Code agents like to quickly fix problems with a workaround that often causes code bloat
or incompatibilities with other models. Spending time to track down the exact cause of a problem, and in particular
locating the first commit where it appeared (for example with [git bisect](https://git-scm.com/docs/git-bisect)) is valuable.
- Minimize the diff. Check your PR to eliminate any unnecessary changes. Ensure that you did not commit any testing scripts
or unrelated files. Add comments only if they're really necessary; code agents love adding three new functions and
multi-line comments to draw attention to all the hard work they did. If your PR can be a 1-line fix,
make it a 1-line fix. This makes the PR much easier to review and improves the chances that it will be accepted.
- Take the time to reproduce the problem. Very often when a user reports an issue, the issue is actually caused by
environment issues on their machine, or they misdiagnose the problem and suggest an invalid solution. Many code agents
trust t

## License

Upstream © its respective contributors under Apache-2.0 (harvested MIT/Apache-2.0/BSD source; see `UPSTREAM_CLONE/LICENSE`). This packaging overlay is licensed under Anticommons 0.1.0.

## Upstream

- **project:** TRANSFORMERS
- **Pinned SHA:** `35924ec379eec682bbdca219886e16eff4df8b09`
- **source:** `UPSTREAM_CLONE/` (pinned at the SHA above)
- **Upstream README source:** `UPSTREAM_CLONE/README.md`

## Benchmarks

Measured by the Anticloud assurance suite. Every value below is read from this
project's `BENCH.json`, produced by a real run — the SHA3-256 of that file is
`f8f9308cbfbcd5eb824186abe600583baac91e21e627a08d40abc802963ca155`.

| Framework | Controls | Evidence | Coverage | Result |
|---|---|---|---|---|
| OWASP Top 10 for LLM Applications | 10 controls mapped | 10 with evidence | 100.0% | PASS |
| OWASP Top 10 (2021) | 9 controls mapped | 9 with evidence | 100.0% | PASS |
| SOC 2 Type II readiness | 9 controls mapped | 9 with evidence | 100.0% | PASS |
| NIST AI Risk Management Framework | 8 controls mapped | 8 with evidence | 100.0% | PASS |
| NIST SP 800-53 Rev. 5 | 12 controls mapped | 12 with evidence | 100.0% | PASS |
| NIST Cybersecurity Framework 2.0 | 8 controls mapped | 8 with evidence | 100.0% | PASS |
| FedRAMP Rev. 5 | 10 controls mapped | 10 with evidence | 100.0% | PASS |
| PCI DSS v4.0.1 | 11 controls mapped | 11 with evidence | 100.0% | PASS |
| ISO/IEC 27001:2022 | 9 controls mapped | 9 with evidence | 100.0% | PASS |
| MITRE ATT&CK v16 | 12 controls mapped | 12 with evidence | 100.0% | PASS |
| ML Technology Readiness Level | TRL 8 | 8/8 criteria | | PASS |

**Overall: 16/16 checks passing.**

See `ISOLATED_LAB_RESULTS/03_Result_Register.md` for the 16-check register with pass condition, command and observed value per check.

Framework folders in `OFFICIAL_BENCHMARKS/` state the control set and the
evidence source bound to each control. This project does not claim an audit
opinion, a SOC report, a FedRAMP authorisation or a PCI attestation — those are
issued by an independent assessor.


## Archives and Permanent Records

| Platform | Identifier | Volume |
|---|---|---|
| Harvard Dataverse | DOI 10.7910/DVN/YMJKOG | 145 citable datasets |
| AIOSS verification kit | DOI 10.7910/DVN/OORKNJ | Offline hash verification |
| Zenodo (CERN) | — | 146 records, DOI-registered |
| OSF | — | 144 preregistered records |
| Figshare | author 20849885 | Research data and figures |
| Internet Archive | aioss-format, Anticode | Permanent binary specification |
| ORCID | 0009-0009-2233-6107 | Permanent researcher ID |
| Kaggle | pax-millennium-20 | Reproducible T4 benchmark run |


## Press and Independent Publication

The PAX benchmark release was distributed by Newsfile wire to 336 outlets
(312 Web, 23 Terminal, 1 Application), including Yahoo Finance, The Globe and Mail, Business Insider, National Post, Financial Post, StreetInsider, Digital Journal, Barchart, International Business Times, and fox47 · National Law Review.
Wire distribution makes the announcement dated, public, and indexed, which
makes the claim checkable.
- Downloads last month
- 56