


Stage Harbor release files 84001-84500
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_doc/dinat.md +93 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_memory_anatomy.md +255 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_sharing.md +262 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_summary.md +110 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/multilingual.md +178 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pad_truncation.md +63 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/peft.md +214 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_hardware.md +160 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_cpu.md +74 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_gpu_many.md +127 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_gpu_one.md +443 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_special.md +18 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_torch_compile.md +359 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_cpu.md +67 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_cpu_many.md +151 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_gpu_many.md +529 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_gpu_one.md +437 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_special.md +24 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_tpu.md +24 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_tpu_tf.md +168 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/performance.md +68 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perplexity.md +116 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/philosophy.md +67 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_tutorial.md +295 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_webserver.md +132 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pr_checks.md +208 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/preprocessing.md +533 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/quicktour.md +588 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/run_scripts.md +370 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/serialization.md +191 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/task_summary.md +355 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/asr.md +375 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/audio_classification.md +323 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/document_question_answering.md +495 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/idefics.md +430 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_captioning.md +276 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_classification.md +553 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_to_image.md +135 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/knowledge_distillation_for_image_classification.md +188 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/language_modeling.md +437 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/masked_language_modeling.md +449 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/monocular_depth_estimation.md +149 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/multiple_choice.md +374 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/object_detection.md +598 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/prompting.md +438 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/question_answering.md +438 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/semantic_segmentation.md +600 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/sequence_classification.md +604 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/summarization.md +404 -0
- tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/text-to-speech.md +638 -0
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_doc/dinat.md
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Dilated Neighborhood Attention Transformer
|
| 18 |
+
|
| 19 |
+
## Overview
|
| 20 |
+
|
| 21 |
+
DiNAT は [Dilated Neighborhood Attender Transformer](https://arxiv.org/abs/2209.15001) で提案されました。
|
| 22 |
+
Ali Hassani and Humphrey Shi.
|
| 23 |
+
|
| 24 |
+
[NAT](nat) を拡張するために、拡張近隣アテンション パターンを追加してグローバル コンテキストをキャプチャします。
|
| 25 |
+
そしてそれと比較して大幅なパフォーマンスの向上が見られます。
|
| 26 |
+
|
| 27 |
+
論文の要約は次のとおりです。
|
| 28 |
+
|
| 29 |
+
*トランスフォーマーは急速に、さまざまなモダリティにわたって最も頻繁に適用される深層学習アーキテクチャの 1 つになりつつあります。
|
| 30 |
+
ドメインとタスク。ビジョンでは、単純なトランスフォーマーへの継続的な取り組みに加えて、階層型トランスフォーマーが
|
| 31 |
+
また、そのパフォーマンスと既存のフレームワークへの簡単な統合のおかげで、大きな注目を集めました。
|
| 32 |
+
これらのモデルは通常、スライディング ウィンドウの近隣アテンション (NA) などの局所的な注意メカニズムを採用しています。
|
| 33 |
+
または Swin Transformer のシフト ウィンドウ セルフ アテンション。自己注意の二次複雑さを軽減するのに効果的ですが、
|
| 34 |
+
局所的な注意は、自己注意の最も望ましい 2 つの特性を弱めます。それは、長距離の相互依存性モデリングです。
|
| 35 |
+
そして全体的な受容野。このペーパーでは、自然で柔軟で、
|
| 36 |
+
NA への効率的な拡張により、よりグローバルなコンテキストを捕捉し、受容野をゼロから指数関数的に拡張することができます。
|
| 37 |
+
追加費用。 NA のローカルな注目と DiNA のまばらなグローバルな注目は相互に補完し合うため、私たちは
|
| 38 |
+
両方に基づいて構築された新しい階層型ビジョン トランスフォーマーである Dilated Neighborhood Attendant Transformer (DiNAT) を導入します。
|
| 39 |
+
DiNAT のバリアントは、NAT、Swin、ConvNeXt などの強力なベースラインに比べて大幅に改善されています。
|
| 40 |
+
私たちの大規模モデルは、COCO オブジェクト検出において Swin モデルよりも高速で、ボックス AP が 1.5% 優れています。
|
| 41 |
+
COCO インスタンス セグメンテーションでは 1.3% のマスク AP、ADE20K セマンティック セグメンテーションでは 1.1% の mIoU。
|
| 42 |
+
新しいフレームワークと組み合わせた当社の大規模バリアントは、COCO (58.2 PQ) 上の新しい最先端のパノプティック セグメンテーション モデルです。
|
| 43 |
+
および ADE20K (48.5 PQ)、および Cityscapes (44.5 AP) および ADE20K (35.4 AP) のインスタンス セグメンテーション モデル (追加データなし)。
|
| 44 |
+
また、ADE20K (58.2 mIoU) 上の最先端の特殊なセマンティック セグメンテーション モデルとも一致します。
|
| 45 |
+
都市景観 (84.5 mIoU) では 2 位にランクされています (追加データなし)。 *
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
<img
|
| 49 |
+
src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/dilated-neighborhood-attention-pattern.jpg"
|
| 50 |
+
alt="drawing" width="600"/>
|
| 51 |
+
|
| 52 |
+
<small> 異なる拡張値を使用した近隣アテンション。
|
| 53 |
+
<a href="https://arxiv.org/abs/2209.15001">元の論文</a>から抜粋。</small>
|
| 54 |
+
|
| 55 |
+
このモデルは [Ali Hassani](https://huggingface.co/alihassanijr) によって提供されました。
|
| 56 |
+
元のコードは [ここ](https://github.com/SHI-Labs/Neighborhood-Attendance-Transformer) にあります。
|
| 57 |
+
|
| 58 |
+
## Usage tips
|
| 59 |
+
|
| 60 |
+
DiNAT は *バックボーン* として使用できます。 「output_hidden_states = True」の場合、
|
| 61 |
+
`hidden_states` と `reshaped_hidden_states` の両方を出力します。 `reshape_hidden_states` は、`(batch_size, height, width, num_channels)` ではなく、`(batch, num_channels, height, width)` の形状を持っています。
|
| 62 |
+
|
| 63 |
+
ノート:
|
| 64 |
+
- DiNAT は、[NATTEN](https://github.com/SHI-Labs/NATTEN/) による近隣アテンションと拡張近隣アテンションの実装に依存しています。
|
| 65 |
+
[shi-labs.com/natten](https://shi-labs.com/natten) を参照して、Linux 用のビルド済みホイールを使用してインストールするか、`pip install natten` を実行してシステム上に構築できます。
|
| 66 |
+
後者はコンパイルに時間がかかる可能性があることに注意してください。 NATTEN はまだ Windows デバイスをサポートしていません。
|
| 67 |
+
- 現時点ではパッチ サイズ 4 のみがサポートされています。
|
| 68 |
+
|
| 69 |
+
## Resources
|
| 70 |
+
|
| 71 |
+
DiNAT の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
|
| 72 |
+
|
| 73 |
+
<PipelineTag pipeline="image-classification"/>
|
| 74 |
+
|
| 75 |
+
|
| 76 |
+
- [`DinatForImageClassification`] は、この [サンプル スクリプト](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) および [ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)。
|
| 77 |
+
- 参照: [画像分類タスク ガイド](../tasks/image_classification)
|
| 78 |
+
|
| 79 |
+
ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
|
| 80 |
+
|
| 81 |
+
## DinatConfig
|
| 82 |
+
|
| 83 |
+
[[autodoc]] DinatConfig
|
| 84 |
+
|
| 85 |
+
## DinatModel
|
| 86 |
+
|
| 87 |
+
[[autodoc]] DinatModel
|
| 88 |
+
- forward
|
| 89 |
+
|
| 90 |
+
## DinatForImageClassification
|
| 91 |
+
|
| 92 |
+
[[autodoc]] DinatForImageClassification
|
| 93 |
+
- forward
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_memory_anatomy.md
ADDED
|
@@ -0,0 +1,255 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!---
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
you may not use this file except in compliance with the License.
|
| 6 |
+
You may obtain a copy of the License at
|
| 7 |
+
|
| 8 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
|
| 10 |
+
Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
See the License for the specific language governing permissions and
|
| 14 |
+
limitations under the License.
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Model training anatomy
|
| 18 |
+
|
| 19 |
+
モデルトレーニングの効率を向上させるために適用できるパフォーマンス最適化テクニックを理解するには、トレーニング中にGPUがどのように利用されるか、および実行される操作に応じて計算強度がどのように変化するかを理解することが役立ちます。
|
| 20 |
+
|
| 21 |
+
まずは、GPUの利用例とモデルのトレーニング実行に関する示唆に富む例を探求することから始めましょう。デモンストレーションのために、いくつかのライブラリをインストールする必要があります:
|
| 22 |
+
|
| 23 |
+
```bash
|
| 24 |
+
pip install transformers datasets accelerate nvidia-ml-py3
|
| 25 |
+
```
|
| 26 |
+
|
| 27 |
+
`nvidia-ml-py3` ライブラリは、Python内からモデルのメモリ使用状況をモニターすることを可能にします。おそらく、ターミナルでの `nvidia-smi` コマンドについてはお聞きかもしれませんが、このライブラリを使用すると、Pythonから同じ情報にアクセスできます。
|
| 28 |
+
|
| 29 |
+
それから、いくつかのダミーデータを作成します。100から30000の間のランダムなトークンIDと、分類器のためのバイナリラベルです。合計で、512のシーケンスがあり、それぞれの長さは512で、PyTorchフォーマットの [`~datasets.Dataset`] に格納されます。
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
```py
|
| 33 |
+
>>> import numpy as np
|
| 34 |
+
>>> from datasets import Dataset
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
>>> seq_len, dataset_size = 512, 512
|
| 38 |
+
>>> dummy_data = {
|
| 39 |
+
... "input_ids": np.random.randint(100, 30000, (dataset_size, seq_len)),
|
| 40 |
+
... "labels": np.random.randint(0, 1, (dataset_size)),
|
| 41 |
+
... }
|
| 42 |
+
>>> ds = Dataset.from_dict(dummy_data)
|
| 43 |
+
>>> ds.set_format("pt")
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
[`Trainer`]を使用してGPU利用率とトレーニング実行の要約統計情報を表示するために、2つのヘルパー関数を定義します。
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
```py
|
| 51 |
+
>>> from pynvml import *
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
>>> def print_gpu_utilization():
|
| 55 |
+
... nvmlInit()
|
| 56 |
+
... handle = nvmlDeviceGetHandleByIndex(0)
|
| 57 |
+
... info = nvmlDeviceGetMemoryInfo(handle)
|
| 58 |
+
... print(f"GPU memory occupied: {info.used//1024**2} MB.")
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
>>> def print_summary(result):
|
| 62 |
+
... print(f"Time: {result.metrics['train_runtime']:.2f}")
|
| 63 |
+
... print(f"Samples/second: {result.metrics['train_samples_per_second']:.2f}")
|
| 64 |
+
... print_gpu_utilization()
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
以下は、無料のGPUメモリから開始していることを確認しましょう:
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
```py
|
| 71 |
+
>>> print_gpu_utilization()
|
| 72 |
+
GPU memory occupied: 0 MB.
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
GPUメモリがモデルを読み込む前のように占有されていないように見えます。これがお使いのマシンでの状況でない場合は、GPUメモリを使用しているすべてのプロセスを停止してください。ただし、すべての空きGPUメモリをユーザーが使用できるわけではありません。モデルがGPUに読み込まれると、カーネルも読み込まれ、1〜2GBのメモリを使用することがあります。それがどれくらいかを確認するために、GPUに小さなテンソルを読み込むと、カーネルも読み込まれます。
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
```py
|
| 79 |
+
>>> import torch
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
>>> torch.ones((1, 1)).to("cuda")
|
| 83 |
+
>>> print_gpu_utilization()
|
| 84 |
+
GPU memory occupied: 1343 MB.
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
カーネルだけで1.3GBのGPUメモリを使用していることがわかります。次に、モデルがどれだけのスペースを使用しているかを見てみましょう。
|
| 88 |
+
|
| 89 |
+
## Load Model
|
| 90 |
+
|
| 91 |
+
まず、`google-bert/bert-large-uncased` モデルを読み込みます。モデルの重みを直接GPUに読み込むことで、重みだけがどれだけのスペースを使用しているかを確認できます。
|
| 92 |
+
|
| 93 |
+
|
| 94 |
+
```py
|
| 95 |
+
>>> from transformers import AutoModelForSequenceClassification
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-large-uncased").to("cuda")
|
| 99 |
+
>>> print_gpu_utilization()
|
| 100 |
+
GPU memory occupied: 2631 MB.
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
モデルの重みだけで、GPUメモリを1.3 GB使用していることがわかります。正確な数値は、使用している具体的なGPUに依存します。新しいGPUでは、モデルの重みが最適化された方法で読み込まれるため、モデルの使用を高速化することがあるため、モデルがより多くのスペースを占有することがあります。さて、`nvidia-smi` CLIと同じ結果が得られるかを簡単���確認することもできます。
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
```bash
|
| 107 |
+
nvidia-smi
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
```bash
|
| 111 |
+
Tue Jan 11 08:58:05 2022
|
| 112 |
+
+-----------------------------------------------------------------------------+
|
| 113 |
+
| NVIDIA-SMI 460.91.03 Driver Version: 460.91.03 CUDA Version: 11.2 |
|
| 114 |
+
|-------------------------------+----------------------+----------------------+
|
| 115 |
+
| GPU Name Persistence-M| Bus-Id Disp.A | Volatile Uncorr. ECC |
|
| 116 |
+
| Fan Temp Perf Pwr:Usage/Cap| Memory-Usage | GPU-Util Compute M. |
|
| 117 |
+
| | | MIG M. |
|
| 118 |
+
|===============================+======================+======================|
|
| 119 |
+
| 0 Tesla V100-SXM2... On | 00000000:00:04.0 Off | 0 |
|
| 120 |
+
| N/A 37C P0 39W / 300W | 2631MiB / 16160MiB | 0% Default |
|
| 121 |
+
| | | N/A |
|
| 122 |
+
+-------------------------------+----------------------+----------------------+
|
| 123 |
+
|
| 124 |
+
+-----------------------------------------------------------------------------+
|
| 125 |
+
| Processes: |
|
| 126 |
+
| GPU GI CI PID Type Process name GPU Memory |
|
| 127 |
+
| ID ID Usage |
|
| 128 |
+
|=============================================================================|
|
| 129 |
+
| 0 N/A N/A 3721 C ...nvs/codeparrot/bin/python 2629MiB |
|
| 130 |
+
+-----------------------------------------------------------------------------+
|
| 131 |
+
```
|
| 132 |
+
|
| 133 |
+
前回と同じ数値を取得し、16GBのメモリを搭載したV100 GPUを使用していることがわかります。さて、モデルのトレーニングを開始し、GPUメモリの消費がどのように変化するかを確認してみましょう。まず、いくつかの標準的なトレーニング引数を設定します:
|
| 134 |
+
|
| 135 |
+
|
| 136 |
+
```py
|
| 137 |
+
default_args = {
|
| 138 |
+
"output_dir": "tmp",
|
| 139 |
+
"eval_strategy": "steps",
|
| 140 |
+
"num_train_epochs": 1,
|
| 141 |
+
"log_level": "error",
|
| 142 |
+
"report_to": "none",
|
| 143 |
+
}
|
| 144 |
+
```
|
| 145 |
+
|
| 146 |
+
<Tip>
|
| 147 |
+
|
| 148 |
+
複数の実験を実行する予定がある場合、実験間でメモリを適切にクリアするために、実験の間に Python カーネルを再起動してください。
|
| 149 |
+
|
| 150 |
+
</Tip>
|
| 151 |
+
|
| 152 |
+
## Memory utilization at vanilla training
|
| 153 |
+
|
| 154 |
+
[`Trainer`] を使用して、GPU パフォーマンスの最適化テクニックを使用せずにバッチサイズ 4 でモデルをトレーニングしましょう:
|
| 155 |
+
|
| 156 |
+
|
| 157 |
+
```py
|
| 158 |
+
>>> from transformers import TrainingArguments, Trainer, logging
|
| 159 |
+
|
| 160 |
+
>>> logging.set_verbosity_error()
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
>>> training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
|
| 164 |
+
>>> trainer = Trainer(model=model, args=training_args, train_dataset=ds)
|
| 165 |
+
>>> result = trainer.train()
|
| 166 |
+
>>> print_summary(result)
|
| 167 |
+
```
|
| 168 |
+
|
| 169 |
+
```
|
| 170 |
+
Time: 57.82
|
| 171 |
+
Samples/second: 8.86
|
| 172 |
+
GPU memory occupied: 14949 MB.
|
| 173 |
+
```
|
| 174 |
+
|
| 175 |
+
既に、比較的小さいバッチサイズでも、GPUのほとんどのメモリがすでに使用されていることがわかります。しかし、より大きなバッチサイズを使用することは、しばしばモデルの収束が速くなったり、最終的な性能が向上したりすることがあります。したがって、理想的には、バッチサイズをモデルの要件に合わせて調整したいのですが、GPUの制限に合わせて調整する必要はありません。興味深いことに、モデルのサイズよりもはるかに多くのメモリを使用しています。なぜそうなるのかを少し理解するために、モデルの操作とメモリの必要性を見てみましょう。
|
| 176 |
+
|
| 177 |
+
|
| 178 |
+
## Anatomy of Model's Operations
|
| 179 |
+
|
| 180 |
+
Transformerアーキテクチャには、計算強度によって以下の3つの主要な操作グループが含まれています。
|
| 181 |
+
|
| 182 |
+
1. **テンソルの収縮**
|
| 183 |
+
|
| 184 |
+
線形層とMulti-Head Attentionのコンポーネントは、すべてバッチ処理された **行列-行列の乗算** を行います。これらの操作は、Transformerのトレーニングにおいて最も計算集約的な部分です。
|
| 185 |
+
|
| 186 |
+
2. **統計的正規化**
|
| 187 |
+
|
| 188 |
+
Softmaxと層正規化は、テンソルの収縮よりも計算負荷が少なく、1つまたは複数の **縮約操作** を含み、その結果がマップを介して適用されます。
|
| 189 |
+
|
| 190 |
+
3. **要素ごとの演算子**
|
| 191 |
+
|
| 192 |
+
これらは残りの演算子です:**バイアス、ドロップアウト、活性化、および残差接続** です。これらは最も計算集約的な操作ではありません。
|
| 193 |
+
|
| 194 |
+
パフォーマンスのボトルネックを分析する際に、この知識は役立つことがあります。
|
| 195 |
+
|
| 196 |
+
この要約は、[Data Movement Is All You Need: Optimizing Transformers 2020に関するケーススタディ](https://arxiv.org/abs/2007.00072)から派生しています。
|
| 197 |
+
|
| 198 |
+
## Anatomy of Model's Memory
|
| 199 |
+
|
| 200 |
+
モデルのトレーニングがGPUに配置されたモデルよりもはるかに多くのメモリを使用することを見てきました。これは、トレーニング中にGPUメモリを使用する多くのコンポーネントが存在するためです。GPUメモリ上のコンポーネントは以下の通りです:
|
| 201 |
+
|
| 202 |
+
1. モデルの重み
|
| 203 |
+
2. オプティマイザの状態
|
| 204 |
+
3. 勾配
|
| 205 |
+
4. 勾配計算のために保存された前向き活性化
|
| 206 |
+
5. 一時バッファ
|
| 207 |
+
6. 機能固有のメモリ
|
| 208 |
+
|
| 209 |
+
通常、AdamWを使用して混合精度でトレーニングされたモデルは、モデルパラメータごとに18バイトとアクティベーションメモリが必要です。推論ではオプティマイザの状態と勾配は不要ですので、これらを差し引くことができます。したがって、混合精度の推論においては、モデルパラメータごとに6バイトとアクティベーションメモリが必要です。
|
| 210 |
+
|
| 211 |
+
詳細を見てみましょう。
|
| 212 |
+
|
| 213 |
+
|
| 214 |
+
**モデルの重み:**
|
| 215 |
+
|
| 216 |
+
- fp32トレーニングのパラメーター数 * 4バイト
|
| 217 |
+
- ミックスプレシジョントレーニングのパラメーター数 * 6バイト(メモリ内にfp32とfp16のモデルを維持)
|
| 218 |
+
|
| 219 |
+
**オプティマイザの状態:**
|
| 220 |
+
|
| 221 |
+
- 通常のAdamWのパラメーター数 * 8バイト(2つの状態を維持)
|
| 222 |
+
- 8-bit AdamWオプティマイザのパラメーター数 * 2バイト([bitsandbytes](https://github.com/TimDettmers/bitsandbytes)のようなオプティマイザ)
|
| 223 |
+
- モーメンタムを持つSGDのようなオプティマイザのパラメーター数 * 4バイト(1つの状態を維持)
|
| 224 |
+
|
| 225 |
+
**勾配**
|
| 226 |
+
|
| 227 |
+
- fp32またはミックスプレシジョントレーニングのパラメーター数 * 4バイト(勾配は常にfp32で保持)
|
| 228 |
+
|
| 229 |
+
**フォワードアクティベーション**
|
| 230 |
+
|
| 231 |
+
- サイズは多くの要因に依存し、主要な要因はシーケンスの長さ、隠れ層のサイズ、およびバッチサイズです。
|
| 232 |
+
|
| 233 |
+
フォワードとバックワードの関数によって渡され、返される入力と出力、および勾配計算のために保存されるフォワードアクティベーションがあります。
|
| 234 |
+
|
| 235 |
+
**一時的なメモリ**
|
| 236 |
+
|
| 237 |
+
さらに、計算が完了した後に解放されるさまざまな一時変数がありますが、これらは一時的に追加のメモリを必要とし、OOMに達する可能性があります。したがって、コーディング時にはこのような一時変数に戦略的に考え、必要なくなったら明示的に解放することが非常に重要です。
|
| 238 |
+
|
| 239 |
+
**機能固有のメモリ**
|
| 240 |
+
|
| 241 |
+
次に、ソフトウェアには特別なメモリ要件がある場合があります。たとえば、ビームサーチを使用してテキストを生成する場合、ソフトウェアは複数の入力と出力のコピーを維持する必要があります。
|
| 242 |
+
|
| 243 |
+
**`forward`と`backward`の実行速度**
|
| 244 |
+
|
| 245 |
+
畳み込み層と線形層では、バックワードにフォワードと比べて2倍のFLOPSがあり、一般的には約2倍遅くなります(バックワードのサイズが不便であることがあるため、それ以上になることがあります)。 アクティベーションは通常、バンド幅制限されており、バックワードでアクティベーションがフォワードよりも多くのデータを読むことが一般的です(たとえば、アクティベーションフォワードは1回読み取り、1回書き込み、アクティベーションバックワードはフォワードのgradOutputおよび出力を2回読み取り、1回書き込みます)。
|
| 246 |
+
|
| 247 |
+
ご覧の通り、GPUメモリを節約したり操作を高速化できる可能性のあるいくつかの場所があります。 GPUの利用と計算速度に影響を与える要因を理解したので、パフォーマンス最適化の技術については、[単一GPUでの効率的なトレーニングのための方法とツール](perf_train_gpu_one)のドキュメンテーションページを参照してください。
|
| 248 |
+
|
| 249 |
+
詳細を見てみましょう。
|
| 250 |
+
|
| 251 |
+
|
| 252 |
+
|
| 253 |
+
|
| 254 |
+
|
| 255 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_sharing.md
ADDED
|
@@ -0,0 +1,262 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 5 |
+
the License. You may obtain a copy of the License at
|
| 6 |
+
|
| 7 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
|
| 9 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 10 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 11 |
+
specific language governing permissions and limitations under the License.
|
| 12 |
+
|
| 13 |
+
⚠️ このファイルはMarkdownですが、Hugging Faceのドキュメントビルダー(MDXに類似)向けの特定の構文を含んでいるため、Markdownビューアーで適切にレンダリングされないことがあります。
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Share a Model
|
| 18 |
+
|
| 19 |
+
最後の2つのチュートリアルでは、PyTorch、Keras、および🤗 Accelerateを使用してモデルをファインチューニングする方法を示しました。次のステップは、モデルをコミュニティと共有することです!Hugging Faceでは、知識とリソースを公開的に共有し、人工知能を誰にでも提供することを信じています。他の人々が時間とリソースを節約できるように、モデルをコミュニティと共有することを検討することをお勧めします。
|
| 20 |
+
|
| 21 |
+
このチュートリアルでは、訓練済みまたはファインチューニングされたモデルを[Model Hub](https://huggingface.co/models)に共有する2つの方法を学びます:
|
| 22 |
+
|
| 23 |
+
- プログラムでファイルをHubにプッシュする。
|
| 24 |
+
- ウェブインターフェースを使用してファイルをHubにドラッグアンドドロップする。
|
| 25 |
+
|
| 26 |
+
<iframe width="560" height="315" src="https://www.youtube.com/embed/XvSGPZFEjDY" title="YouTube video player"
|
| 27 |
+
frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope;
|
| 28 |
+
picture-in-picture" allowfullscreen></iframe>
|
| 29 |
+
|
| 30 |
+
<Tip>
|
| 31 |
+
|
| 32 |
+
コミュニティとモデルを共有するには、[huggingface.co](https://huggingface.co/join)でアカウントが必要です。既存の組織に参加したり、新しい組織を作成したりすることもできます。
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
## Repository Features
|
| 37 |
+
|
| 38 |
+
Model Hub上の各リポジトリは、通常のGitHubリポジトリのように動作します。リポジトリはバージョニング、コミット履歴、違いの視覚化の機能を提供します。
|
| 39 |
+
|
| 40 |
+
Model Hubの組み込みバージョニングはgitおよび[git-lfs](https://git-lfs.github.com/)に基づいています。言い換えれば、モデルを1つのリポジトリとして扱うことができ、より大きなアクセス制御とスケーラビリティを実現します。バージョン管理には*リビジョン*があり、コミットハッシュ、タグ、またはブランチ名で特定のモデルバージョンをピン留めする方法です。
|
| 41 |
+
|
| 42 |
+
その結果、`revision`パラメータを使用して特定のモデルバージョンをロードできます:
|
| 43 |
+
|
| 44 |
+
```py
|
| 45 |
+
>>> model = AutoModel.from_pretrained(
|
| 46 |
+
... "julien-c/EsperBERTo-small", revision="4c77982" # タグ名、またはブランチ名、またはコミットハッシュ
|
| 47 |
+
... )
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
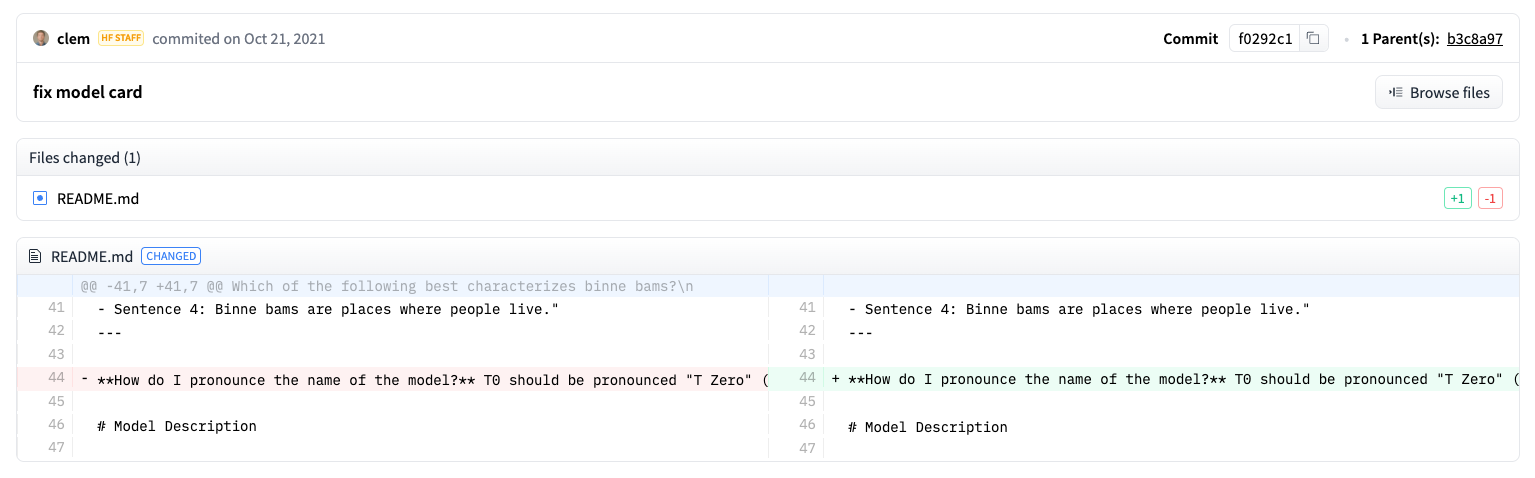
+
ファイルはリポジトリ内で簡単に編集でき、コミット履歴と差分を表示できます:
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
## Set Up
|
| 55 |
+
|
| 56 |
+
モデルをHubに共有する前に、Hugging Faceの認証情報が必要です。ターミナルへのアクセス権がある場合、🤗 Transformersがインストールされている仮想環境で以下のコマンドを実行します。これにより、アクセストークンがHugging Faceのキャッシュフォルダに保存されます(デフォルトでは `~/.cache/` に保存されます):
|
| 57 |
+
|
| 58 |
+
```bash
|
| 59 |
+
huggingface-cli login
|
| 60 |
+
```
|
| 61 |
+
|
| 62 |
+
JupyterやColaboratoryのようなノートブックを使用している場合、[`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library)ライブラリがインストールされていることを確認してください。
|
| 63 |
+
このライブラリを使用すると、Hubとプログラム的に対話できます。
|
| 64 |
+
|
| 65 |
+
```bash
|
| 66 |
+
pip install huggingface_hub
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
次に、`notebook_login`を使用してHubにサインインし、[こちらのリンク](https://huggingface.co/settings/token)にアクセスしてログインに使用するトークンを生成します:
|
| 70 |
+
|
| 71 |
+
```python
|
| 72 |
+
>>> from huggingface_hub import notebook_login
|
| 73 |
+
|
| 74 |
+
>>> notebook_login()
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
## Convert a Model for all frameworks
|
| 78 |
+
|
| 79 |
+
異なるフレームワークで作業している他のユーザーがあなたのモデルを使用できるようにするために、
|
| 80 |
+
PyTorchおよびTensorFlowのチェックポイントでモデルを変換してアップロードすることをお勧めします。
|
| 81 |
+
このステップをスキ���プすると、ユーザーは異なるフレームワークからモデルをロードできますが、
|
| 82 |
+
モデルをオンザフライで変換する必要があるため、遅くなります。
|
| 83 |
+
|
| 84 |
+
別のフレームワーク用にチェックポイントを変換することは簡単です。
|
| 85 |
+
PyTorchとTensorFlowがインストールされていることを確認してください(インストール手順については[こちら](installation)を参照)し、
|
| 86 |
+
その後、他のフレームワーク向けに特定のタスク用のモデルを見つけます。
|
| 87 |
+
|
| 88 |
+
<frameworkcontent>
|
| 89 |
+
<pt>
|
| 90 |
+
TensorFlowからPyTorchにチェックポイントを変換するには、`from_tf=True`を指定します:
|
| 91 |
+
|
| 92 |
+
```python
|
| 93 |
+
>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
|
| 94 |
+
>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
|
| 95 |
+
```
|
| 96 |
+
</pt>
|
| 97 |
+
<tf>
|
| 98 |
+
|
| 99 |
+
指定して、PyTorchからTensorFlowにチェックポイントを変換するには `from_pt=True` を使用します:
|
| 100 |
+
|
| 101 |
+
```python
|
| 102 |
+
>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
|
| 103 |
+
```
|
| 104 |
+
|
| 105 |
+
新しいTensorFlowモデルとその新しいチェックポイントを保存できます:
|
| 106 |
+
|
| 107 |
+
```python
|
| 108 |
+
>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
|
| 109 |
+
```
|
| 110 |
+
</tf>
|
| 111 |
+
<tf>
|
| 112 |
+
<jax>
|
| 113 |
+
Flaxでモデルが利用可能な場合、PyTorchからFlaxへのチェックポイントの変換も行うことができます:
|
| 114 |
+
|
| 115 |
+
```py
|
| 116 |
+
>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
|
| 117 |
+
... "path/to/awesome-name-you-picked", from_pt=True
|
| 118 |
+
... )
|
| 119 |
+
```
|
| 120 |
+
</jax>
|
| 121 |
+
</frameworkcontent>
|
| 122 |
+
|
| 123 |
+
## Push a model during traning
|
| 124 |
+
|
| 125 |
+
<frameworkcontent>
|
| 126 |
+
<pt>
|
| 127 |
+
<Youtube id="Z1-XMy-GNLQ"/>
|
| 128 |
+
|
| 129 |
+
モデルをHubにプッシュすることは、追加のパラメーターまたはコールバックを追加するだけで簡単です。
|
| 130 |
+
[ファインチューニングチュートリアル](training)から思い出してください、[`TrainingArguments`]クラスはハイパーパラメーターと追加のトレーニングオプションを指定する場所です。
|
| 131 |
+
これらのトレーニングオプションの1つに、モデルを直接Hubにプッシュする機能があります。[`TrainingArguments`]で`push_to_hub=True`を設定します:
|
| 132 |
+
|
| 133 |
+
```py
|
| 134 |
+
>>> training_args = TrainingArguments(output_dir="my-awesome-model", push_to_hub=True)
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
Pass your training arguments as usual to [`Trainer`]:
|
| 138 |
+
|
| 139 |
+
```py
|
| 140 |
+
>>> trainer = Trainer(
|
| 141 |
+
... model=model,
|
| 142 |
+
... args=training_args,
|
| 143 |
+
... train_dataset=small_train_dataset,
|
| 144 |
+
... eval_dataset=small_eval_dataset,
|
| 145 |
+
... compute_metrics=compute_metrics,
|
| 146 |
+
... )
|
| 147 |
+
```
|
| 148 |
+
|
| 149 |
+
[`Trainer`]に通常通りトレーニング引数を渡します:
|
| 150 |
+
|
| 151 |
+
```py
|
| 152 |
+
>>> trainer = Trainer(
|
| 153 |
+
... model=model,
|
| 154 |
+
... args=training_args,
|
| 155 |
+
... train_dataset=small_train_dataset,
|
| 156 |
+
... eval_dataset=small_eval_dataset,
|
| 157 |
+
... compute_metrics=compute_metrics,
|
| 158 |
+
... )
|
| 159 |
+
```
|
| 160 |
+
|
| 161 |
+
ファインチューニングが完了したら、[`Trainer`]で[`~transformers.Trainer.push_to_hub`]を呼び出して、トレーニング済みモデルをHubにプッシュします。🤗 Transformersは、トレーニングのハイパーパラメータ、トレーニング結果、およびフレームワークのバージョンを自動的にモデルカードに追加します!
|
| 162 |
+
|
| 163 |
+
```py
|
| 164 |
+
>>> trainer.push_to_hub()
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
</pt>
|
| 168 |
+
<tf>
|
| 169 |
+
|
| 170 |
+
[`PushToHubCallback`]を使用してモデルをHubに共有します。[`PushToHubCallback`]関数には、次のものを追加します:
|
| 171 |
+
|
| 172 |
+
- モデルの出力ディレクトリ。
|
| 173 |
+
- トークナイザ。
|
| 174 |
+
- `hub_model_id`、つまりHubのユーザー名とモデル名。
|
| 175 |
+
|
| 176 |
+
```python
|
| 177 |
+
>>> from transformers import PushToHubCallback
|
| 178 |
+
|
| 179 |
+
>>> push_to_hub_callback = PushToHubCallback(
|
| 180 |
+
... output_dir="./your_model_save_path", tokenizer=tokenizer, hub_model_id="your-username/my-awesome-model"
|
| 181 |
+
... )
|
| 182 |
+
```
|
| 183 |
+
|
| 184 |
+
🤗 Transformersは[`fit`](https://keras.io/api/models/model_training_apis/)にコールバックを追加し、トレーニング済みモデルをHubにプッシュします:
|
| 185 |
+
|
| 186 |
+
```py
|
| 187 |
+
>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3, callbacks=push_to_hub_callback)
|
| 188 |
+
```
|
| 189 |
+
</tf>
|
| 190 |
+
</frameworkcontent>
|
| 191 |
+
|
| 192 |
+
## `push_to_hub` 関数を使用する
|
| 193 |
+
|
| 194 |
+
また、モデルを直接Hubにアップロードするために、`push_to_hub` を呼び出すこともできます。
|
| 195 |
+
|
| 196 |
+
`push_to_hub` でモデル名を指定します:
|
| 197 |
+
|
| 198 |
+
```py
|
| 199 |
+
>>> pt_model.push_to_hub("my-awesome-model")
|
| 200 |
+
```
|
| 201 |
+
|
| 202 |
+
これにより、ユーザー名の下にモデル名 `my-awesome-model` を持つリポジトリが作成されます。
|
| 203 |
+
ユーザーは、`from_pretrained` 関数を使用してモデルをロードできます:
|
| 204 |
+
|
| 205 |
+
```py
|
| 206 |
+
>>> from transformers import AutoModel
|
| 207 |
+
|
| 208 |
+
>>> model = AutoModel.from_pretrained("your_username/my-awesome-model")
|
| 209 |
+
```
|
| 210 |
+
|
| 211 |
+
組織に所属し、モデルを組織名のもとにプッシュしたい場合、`repo_id` にそれを追加して���ださい:
|
| 212 |
+
|
| 213 |
+
```python
|
| 214 |
+
>>> pt_model.push_to_hub("my-awesome-org/my-awesome-model")
|
| 215 |
+
```
|
| 216 |
+
|
| 217 |
+
`push_to_hub`関数は、モデルリポジトリに他のファイルを追加するためにも使用できます。例えば、トークナイザをモデルリポジトリに追加します:
|
| 218 |
+
|
| 219 |
+
```py
|
| 220 |
+
>>> tokenizer.push_to_hub("my-awesome-model")
|
| 221 |
+
```
|
| 222 |
+
|
| 223 |
+
あるいは、ファインチューニングされたPyTorchモデルのTensorFlowバージョンを追加したいかもしれません:
|
| 224 |
+
|
| 225 |
+
```python
|
| 226 |
+
>>> tf_model.push_to_hub("my-awesome-model")
|
| 227 |
+
```
|
| 228 |
+
|
| 229 |
+
Hugging Faceプロフィールに移動すると、新しく作成したモデルリポジトリが表示されるはずです。**Files**タブをクリックすると、リポジトリにアップロードしたすべてのファイルが表示されます。
|
| 230 |
+
|
| 231 |
+
リポジトリにファイルを作成およびアップロードする方法の詳細については、Hubドキュメンテーション[こちら](https://huggingface.co/docs/hub/how-to-upstream)を参照してください。
|
| 232 |
+
|
| 233 |
+
## Upload with the web interface
|
| 234 |
+
|
| 235 |
+
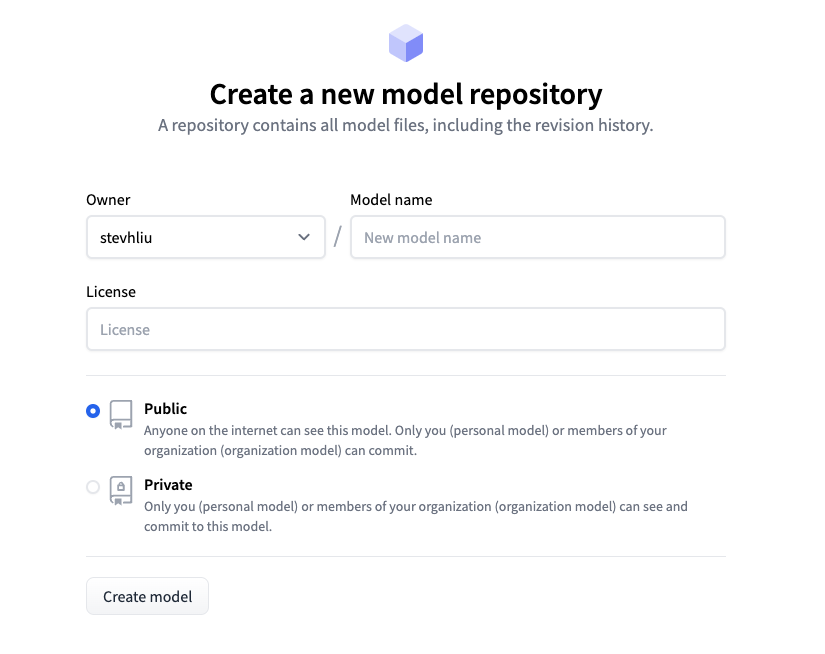
コードを書かずにモデルをアップロードしたいユーザーは、Hubのウェブインターフェースを使用してモデルをアップロードできます。[huggingface.co/new](https://huggingface.co/new)を訪れて新しいリポジトリを作成します:
|
| 236 |
+
|
| 237 |
+
|
| 238 |
+
|
| 239 |
+
ここから、モデルに関するいくつかの情報を追加します:
|
| 240 |
+
|
| 241 |
+
- リポジトリの**所有者**を選択します。これはあなた自身または所属している組織のいずれかです。
|
| 242 |
+
- モデルの名前を選択します。これはリポジトリの名前にもなります。
|
| 243 |
+
- モデルが公開か非公開かを選択します。
|
| 244 |
+
- モデルのライセンス使用方法を指定します。
|
| 245 |
+
|
| 246 |
+
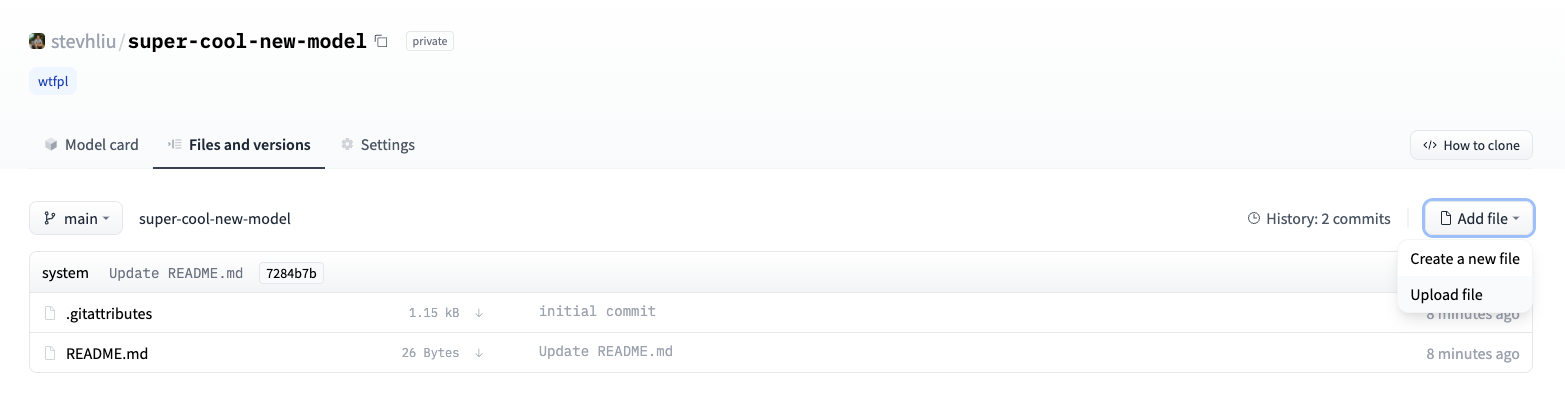
その後、**Files**タブをクリックし、**Add file**ボタンをクリックしてリポジトリに新しいファイルをアップロードします。次に、ファイルをドラッグアンドドロップしてアップロードし、コミットメッセージを追加します。
|
| 247 |
+
|
| 248 |
+
|
| 249 |
+
|
| 250 |
+
## Add a model card
|
| 251 |
+
|
| 252 |
+
ユーザーがモデルの機能、制限、潜在的な偏り、倫理的な考慮事項を理解できるようにするために、モデルリポジトリにモデルカードを追加してください。モデルカードは`README.md`ファイルで定義されます。モデルカードを追加する方法:
|
| 253 |
+
|
| 254 |
+
* 手動で`README.md`ファイルを作成およびアップロードする。
|
| 255 |
+
* モデルリポジトリ内の**Edit model card**ボタンをクリックする。
|
| 256 |
+
|
| 257 |
+
モデルカードに含めるべき情報の例については、DistilBert [モデルカード](https://huggingface.co/distilbert/distilbert-base-uncased)をご覧ください。`README.md`ファイルで制御できる他のオプション、例えばモデルの炭素フットプリントやウィジェットの例などについての詳細は、[こちらのドキュメンテーション](https://huggingface.co/docs/hub/models-cards)を参照してください。
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
|
| 261 |
+
|
| 262 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/model_summary.md
ADDED
|
@@ -0,0 +1,110 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# The Transformer model family
|
| 18 |
+
|
| 19 |
+
2017年に導入されて以来、[元のTransformer](https://arxiv.org/abs/1706.03762)モデルは、自然言語処理(NLP)のタスクを超える多くの新しいエキサイティングなモデルをインスパイアしました。[タンパク質の折りたたまれた構造を予測](https://huggingface.co/blog/deep-learning-with-proteins)するモデル、[チーターを走らせるためのトレーニング](https://huggingface.co/blog/train-decision-transformers)するモデル、そして[時系列予測](https://huggingface.co/blog/time-series-transformers)のためのモデルなどがあります。Transformerのさまざまなバリアントが利用可能ですが、大局を見落とすことがあります。これらのすべてのモデルに共通するのは、元のTransformerアーキテクチャに基づいていることです。一部のモデルはエンコーダまたはデコーダのみを使用し、他のモデルは両方を使用します。これは、Transformerファミリー内のモデルの高レベルの違いをカテゴライズし、調査するための有用な分類法を提供し、以前に出会ったことのないTransformerを理解するのに役立ちます。
|
| 20 |
+
|
| 21 |
+
元のTransformerモデルに慣れていないか、リフレッシュが必要な場合は、Hugging Faceコースの[Transformerの動作原理](https://huggingface.co/course/chapter1/4?fw=pt)章をチェックしてください。
|
| 22 |
+
|
| 23 |
+
<div align="center">
|
| 24 |
+
<iframe width="560" height="315" src="https://www.youtube.com/embed/H39Z_720T5s" title="YouTubeビデオプレーヤー"
|
| 25 |
+
frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope;
|
| 26 |
+
picture-in-picture" allowfullscreen></iframe>
|
| 27 |
+
</div>
|
| 28 |
+
|
| 29 |
+
## Computer vision
|
| 30 |
+
|
| 31 |
+
<iframe style="border: 1px solid rgba(0, 0, 0, 0.1);" width="1000" height="450" src="https://www.figma.com/embed?embed_host=share&url=https%3A%2F%2Fwww.figma.com%2Ffile%2FacQBpeFBVvrDUlzFlkejoz%2FModelscape-timeline%3Fnode-id%3D0%253A1%26t%3Dm0zJ7m2BQ9oe0WtO-1" allowfullscreen></iframe>
|
| 32 |
+
|
| 33 |
+
### Convolutional network
|
| 34 |
+
|
| 35 |
+
長い間、畳み込みネットワーク(CNN)はコンピュータビジョンのタスクにおいて支配的なパラダイムでしたが、[ビジョンTransformer](https://arxiv.org/abs/2010.11929)はそのスケーラビリティと効率性を示しました。それでも、一部のCNNの最高の特性、特に特定のタスクにとっては非常に強力な翻訳不変性など、一部のTransformerはアーキテクチャに畳み込みを組み込んでいます。[ConvNeXt](model_doc/convnext)は、畳み込みを現代化するためにTransformerから設計の選択肢を取り入れ、例えば、ConvNeXtは画像をパッチに分割するために重なり合わないスライディングウィンドウと、グローバル受容野を増加させるための大きなカーネルを使用します。ConvNeXtは、メモリ効率を向上させ、パフォーマンスを向上させるためにいくつかのレイヤーデザインの選択肢も提供し、Transformerと競合的になります!
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
### Encoder[[cv-encoder]]
|
| 39 |
+
|
| 40 |
+
[ビジョン トランスフォーマー(ViT)](model_doc/vit) は、畳み込みを使用しないコンピュータビジョンタスクの扉を開けました。ViT は標準のトランスフォーマーエンコーダーを使用しますが、画像を扱う方法が主要なブレークスルーでした。画像を固定サイズのパッチに分割し、それらをトークンのように使用して埋め込みを作成します。ViT は、当時のCNNと競争力のある結果を示すためにトランスフォーマーの効率的なアーキテクチャを活用しましたが、トレーニングに必要なリソースが少なくて済みました。ViT に続いて、セグメンテーションや検出などの密なビジョンタスクを処理できる他のビジョンモデルも登場しました。
|
| 41 |
+
|
| 42 |
+
これらのモデルの1つが[Swin](model_doc/swin) トランスフォーマーです。Swin トランスフォーマーは、より小さなサイズのパッチから階層的な特徴マップ(CNNのようで ViT とは異なります)を構築し、深層のパッチと隣接するパッチとマージします。注意はローカルウィンドウ内でのみ計算され、ウィンドウは注意のレイヤー間でシフトされ、モデルがより良く学習するのをサポートする接続を作成します。Swin トランスフォーマーは階層的な特徴マップを生成できるため、セグメンテーションや検出などの密な予測タスクに適しています。[SegFormer](model_doc/segformer) も階層的な特徴マップを構築するためにトランスフォーマーエンコーダーを使用しますが、すべての特徴マップを組み合わせて予測するためにシンプルなマルチレイヤーパーセプトロン(MLP)デコーダーを追加します。
|
| 43 |
+
|
| 44 |
+
BeIT および ViTMAE などの他のビジョンモデルは、BERTの事前トレーニング目標からインスピレーションを得ました。[BeIT](model_doc/beit) は *masked image modeling (MIM)* によって事前トレーニングされています。画像パッチはランダムにマスクされ、画像も視覚トークンにトークン化されます。BeIT はマスクされたパッチに対応する視覚トークンを予測するようにトレーニングされます。[ViTMAE](model_doc/vitmae) も似たような事前トレーニング目標を持っており、視覚トークンの代わりにピクセルを予測する必要があります。異例なのは画像パッチの75%がマスクされていることです!デコーダーはマスクされたトークンとエンコードされたパッチからピクセルを再構築します。事前トレーニングの後、デコーダーは捨てられ、エンコーダーはダウンストリームのタスクで使用できる状態です。
|
| 45 |
+
|
| 46 |
+
### Decoder[[cv-decoder]]
|
| 47 |
+
|
| 48 |
+
デコーダーのみのビジョンモデルは珍しいです。なぜなら、ほとんどのビジョンモデルは画像表現を学ぶためにエンコーダーを使用するからです。しかし、画像生成などのユースケースでは、デコーダーは自然な適応です。これは、GPT-2などのテキスト生成モデルから見てきたように、[ImageGPT](model_doc/imagegpt) でも同様のアーキテクチャを使用しますが、シーケンス内の次のトークンを予測する代わりに、画像内の次のピクセルを予測します。画像生成に加えて、ImageGPT は画像分類のためにもファインチューニングできます。
|
| 49 |
+
|
| 50 |
+
### Encoder-decoder[[cv-encoder-decoder]]
|
| 51 |
+
|
| 52 |
+
ビジョンモデルは一般的にエンコーダー(バックボーンとも呼ばれます)を使用して重要な画像特徴を抽出し、それをトランスフォーマーデコーダーに渡すために使用します。[DETR](model_doc/detr) は事前トレーニング済みのバックボーンを持っていますが、オブジェクト検出のために完全なトランスフォーマーエンコーダーデコーダーアーキテクチャも使用しています。エンコーダーは画像表現を学び、デコーダー内のオブジェクトクエリ(各オブジェクトクエリは画像内の領域またはオブジェクトに焦点を当てた学習された埋め込みです)と組み合わせます。DETR は各オブジェクトクエリに対する境界ボックスの座標とクラスラベルを予測します。
|
| 53 |
+
|
| 54 |
+
## Natural lanaguage processing
|
| 55 |
+
|
| 56 |
+
<iframe style="border: 1px solid rgba(0, 0, 0, 0.1);" width="1000" height="450" src="https://www.figma.com/embed?embed_host=share&url=https%3A%2F%2Fwww.figma.com%2Ffile%2FUhbQAZDlpYW5XEpdFy6GoG%2Fnlp-model-timeline%3Fnode-id%3D0%253A1%26t%3D4mZMr4r1vDEYGJ50-1" allowfullscreen></iframe>
|
| 57 |
+
|
| 58 |
+
### Encoder[[nlp-encoder]]
|
| 59 |
+
|
| 60 |
+
[BERT](model_doc/bert) はエンコーダー専用のTransformerで、入力の一部のトークンをランダムにマスクして他のトークンを見ないようにしています。これにより、トークンをマスクした文脈に基づいてマスクされたトークンを予測することが事前トレーニングの目標です。これにより、BERTは入力のより深いかつ豊かな表現を学習するのに左右の文脈を完全に活用できます。しかし、BERTの事前トレーニング戦略にはまだ改善の余地がありました。[RoBERTa](model_doc/roberta) は、トレーニングを長時間行い、より大きなバッチでトレーニングし、事前処理中に一度だけでなく各エポックでトークンをランダムにマスクし、次文予測の目標を削除する新しい事前トレーニングレシピを導入することでこれを改善しました。
|
| 61 |
+
|
| 62 |
+
性能を向上させる主要な戦略はモデルのサイズを増やすことですが、大規模なモデルのトレーニングは計算コストがかかります。計算コストを削減する方法の1つは、[DistilBERT](model_doc/distilbert) のような小さなモデルを使用することです。DistilBERTは[知識蒸留](https://arxiv.org/abs/1503.02531) - 圧縮技術 - を使用して、BERTのほぼすべての言語理解機能を保持しながら、より小さなバージョンを作成します。
|
| 63 |
+
|
| 64 |
+
しかし、ほとんどのTransformerモデルは引き続きより多くのパラメータに焦点を当て、トレーニング効率を向上させる新しいモデルが登場しています。[ALBERT](model_doc/albert) は、2つの方法でパラメータの数を減らすことによってメモリ消費量を削減します。大きな語彙埋め込みを2つの小さな行列に分割し、レイヤーがパラメータを共有できるようにします。[DeBERTa](model_doc/deberta) は、単語とその位置を2つのベクトルで別々にエンコードする解かれた注意機構を追加しました。注意はこれらの別々のベクトルから計算されます。単語と位置の埋め込みが含まれる単一のベクトルではなく、[Longformer](model_doc/longformer) は、特に長いシーケンス長のドキュメントを処理するために注意をより効率的にすることに焦点を当てました。固定されたウィンドウサイズの周りの各トークンから計算されるローカルウィンドウ付き注意(特定のタスクトークン(分類のための `[CLS]` など)のみのためのグローバルな注意を含む)の組み合わせを使用して、完全な注意行列ではなく疎な注意行列を作成します。
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
### Decoder[[nlp-decoder]]
|
| 68 |
+
|
| 69 |
+
[GPT-2](model_doc/gpt2)は、シーケンス内の次の単語を予測するデコーダー専用のTransformerです。モデルは先を見ることができないようにトークンを右にマスクし、"のぞき見"を防ぎます。大量のテキストを事前トレーニングしたことにより、GPT-2はテキスト生成が非常に得意で、テキストが正確であることがあるにしても、時折正確ではないことがあります。しかし、GPT-2にはBERTの事前トレーニングからの双方向コンテキストが不足しており、特定のタスクには適していませんでした。[XLNET](model_doc/xlnet)は、双方向に学習できる順列言語モデリング目標(PLM)を使用することで、BERTとGPT-2の事前トレーニング目標のベストを組み合わせています。
|
| 70 |
+
|
| 71 |
+
GPT-2の後、言語モデルはさらに大きく成長し、今では*大規模言語モデル(LLM)*として知られています。大規模なデータセットで事前トレーニングされれば、LLMはほぼゼロショット学習を示すことがあります。[GPT-J](model_doc/gptj)は、6Bのパラメータを持つLLMで、400Bのトークンでトレーニングされています。GPT-Jには[OPT](model_doc/opt)が続き、そのうち最大のモデルは175Bで、180Bのトークンでトレーニングされています。同じ時期に[BLOOM](model_doc/bloom)がリリースされ、このファミリーの最大のモデルは176Bのパラメータを持ち、46の言語と13のプログラミング言語で366Bのトークンでトレーニングされています。
|
| 72 |
+
|
| 73 |
+
### Encoder-decoder[[nlp-encoder-decoder]]
|
| 74 |
+
|
| 75 |
+
[BART](model_doc/bart)は、元のTransformerアーキテクチャを保持していますが、事前トレーニング目標を*テキスト補完*の破損に変更しています。一部のテキストスパンは単一の`mask`トークンで置換されます。デコーダーは破損していないトークンを予測し(未来のトークンはマスクされます)、エンコーダーの隠れた状態を使用して予測を補助します。[Pegasus](model_doc/pegasus)はBARTに似ていますが、Pegasusはテキストスパンの代わりに文全体をマスクします。マスクされた言語モデリングに加えて、Pegasusはギャップ文生成(GSG)によって事前トレーニングされています。GSGの目標は、文書に重要な文をマスクし、それらを`mask`トークンで置換することです。デコーダーは残りの文から出力を生成しなければなりません。[T5](model_doc/t5)は、すべてのNLPタスクを特定のプレフィックスを使用してテキスト対テキストの問題に変換するよりユニークなモデルです。たとえば、プレフィックス`Summarize:`は要約タスクを示します。T5は教師ありトレーニング(GLUEとSuperGLUE)と自己教師ありトレーニング(トークンの15%をランダムにサンプルしドロップアウト)によって事前トレーニングされています。
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
## Audio
|
| 79 |
+
|
| 80 |
+
<iframe style="border: 1px solid rgba(0, 0, 0, 0.1);" width="1000" height="450" src="https://www.figma.com/embed?embed_host=share&url=https%3A%2F%2Fwww.figma.com%2Ffile%2Fvrchl8jDV9YwNVPWu2W0kK%2Fspeech-and-audio-model-timeline%3Fnode-id%3D0%253A1%26t%3DmM4H8pPMuK23rClL-1" allowfullscreen></iframe>
|
| 81 |
+
|
| 82 |
+
### Encoder[[audio-encoder]]
|
| 83 |
+
|
| 84 |
+
[Wav2Vec2](model_doc/wav2vec2) は、生のオーディオ波形から直接音声表現を学習するためのTransformerエンコーダーを使用します。これは、対照的なタスクで事前学習され、一連の偽の表現から真の音声表現を特定します。 [HuBERT](model_doc/hubert) はWav2Vec2に似ていますが、異なるトレーニングプロセスを持っています。ターゲットラベルは、類似したオーディオセグメントがクラスタに割り当てられ、これが隠れユニットになるクラスタリングステップによって作成されます。隠れユニットは埋め込みにマップされ、予測を行います。
|
| 85 |
+
|
| 86 |
+
### Encoder-decoder[[audio-encoder-decoder]]
|
| 87 |
+
|
| 88 |
+
[Speech2Text](model_doc/speech_to_text) は、自動音声認識(ASR)および音声翻訳のために設計された音声モデルです。このモデルは、オーディオ波形から抽出されたログメルフィルターバンクフィーチャーを受け入れ、事前トレーニングされた自己回帰的にトランスクリプトまたは翻訳を生成します。 [Whisper](model_doc/whisper) もASRモデルですが、他の多くの音声モデルとは異なり、✨ ラベル付き ✨ オーディオトランスクリプションデータを大量に事前に学習して、ゼロショットパフォーマンスを実現します。データセットの大部分には非英語の言語も含まれており、Whisperは低リソース言語にも使用できます。構造的には、WhisperはSpeech2Textに似ています。オーディオ信号はエンコーダーによってエンコードされたログメルスペクトログラムに変換されます。デコーダーはエンコーダーの隠れ状態と前のトークンからトランスクリプトを自己回帰的に生成します。
|
| 89 |
+
|
| 90 |
+
## Multimodal
|
| 91 |
+
|
| 92 |
+
<iframe style="border: 1px solid rgba(0, 0, 0, 0.1);" width="1000" height="450" src="https://www.figma.com/embed?embed_host=share&url=https%3A%2F%2Fwww.figma.com%2Ffile%2FcX125FQHXJS2gxeICiY93p%2Fmultimodal%3Fnode-id%3D0%253A1%26t%3DhPQwdx3HFPWJWnVf-1" allowfullscreen></iframe>
|
| 93 |
+
|
| 94 |
+
### Encoder[[mm-encoder]]
|
| 95 |
+
|
| 96 |
+
[VisualBERT](model_doc/visual_bert) は、BERTの後にリリースされたビジョン言語タスク向けのマルチモーダルモデルです。これはBERTと事前トレーニングされた物体検出システムを組み合わせ、画像特徴をビジュアル埋め込みに抽出し、テキスト埋め込みと一緒にBERTに渡します。VisualBERTは非マスクテキストを基にしたマスクテキストを予測し、テキストが画像と整合しているかどうかも予測する必要があります。ViTがリリースされた際、[ViLT](model_doc/vilt) は画像埋め込みを取得するためにこの方法を採用しました。画像埋め込みはテキスト埋め込みと共に共同で処理されます。それから、ViLTは画像テキストマッチング、マスク言語モデリング、および全単語マスキングによる事前トレーニングが行われます。
|
| 97 |
+
|
| 98 |
+
[CLIP](model_doc/clip) は異なるアプローチを取り、(`画像`、`テキスト`) のペア予測を行います。画像エンコーダー(ViT)とテキストエンコーダー(Transformer)は、(`画像`、`テキスト`) ペアデータセット上で共同トレーニングされ、(`画像`、`テキスト`) ペアの画像とテキストの埋め込みの類似性を最大化します。事前トレーニング後、CLIPを使用して画像からテキストを予測したり、その逆を行うことができます。[OWL-ViT](model_doc/owlvit) は、ゼロショット物体検出のバックボーンとしてCLIPを使用しています。事前トレーニング後、物体検出ヘッドが追加され、(`クラス`、`バウンディングボックス`) ペアに対するセット予測が行われます。
|
| 99 |
+
|
| 100 |
+
### Encoder-decoder[[mm-encoder-decoder]]
|
| 101 |
+
|
| 102 |
+
光学文字認識(OCR)は、通常、画像を理解しテキストを生成するために複数のコンポーネントが関与するテキスト認識タスクです。 [TrOCR](model_doc/trocr) は、エンドツーエンドのTransformerを使用してこのプロセスを簡略化します。エンコーダーは画像を固定サイズのパッチとして処理するためのViTスタイルのモデルであり、デコーダーはエンコーダーの隠れ状態を受け入れ、テキストを自己回帰的に生成します。[Donut](model_doc/donut) はOCRベースのアプローチに依存しないより一般的なビジュアルドキュメント理解モデルで、エンコーダーとしてSwin Transformer、デコーダーとして多言語BARTを使用します。 Donutは画像とテキストの注釈に基づいて次の単語を予測することにより、テキストを読むために事前トレーニングされます。デコーダーはプロンプトを与えられたトー��ンシーケンスを生成します。プロンプトは各ダウンストリームタスクごとに特別なトークンを使用して表現されます。例えば、ドキュメントの解析には`解析`トークンがあり、エンコーダーの隠れ状態と組み合わされてドキュメントを構造化された出力フォーマット(JSON)に解析します。
|
| 103 |
+
|
| 104 |
+
## Reinforcement learning
|
| 105 |
+
|
| 106 |
+
<iframe style="border: 1px solid rgba(0, 0, 0, 0.1);" width="1000" height="450" src="https://www.figma.com/embed?embed_host=share&url=https%3A%2F%2Fwww.figma.com%2Ffile%2FiB3Y6RvWYki7ZuKO6tNgZq%2Freinforcement-learning%3Fnode-id%3D0%253A1%26t%3DhPQwdx3HFPWJWnVf-1" allowfullscreen></iframe>
|
| 107 |
+
|
| 108 |
+
### Decoder[[rl-decoder]]
|
| 109 |
+
|
| 110 |
+
意思決定と軌跡トランスフォーマーは、状態、アクション、報酬をシーケンスモデリングの問題として捉えます。 [Decision Transformer](model_doc/decision_transformer) は、リターン・トゥ・ゴー、過去の状態、およびアクションに基づいて将来の希望リターンにつながるアクションの系列を生成します。最後の *K* タイムステップでは、3つのモダリティそれぞれがトークン埋め込みに変換され、将来のアクショントークンを予測するためにGPTのようなモデルによって処理されます。[Trajectory Transformer](model_doc/trajectory_transformer) も状態、アクション、報酬をトークン化し、GPTアーキテクチャで処理します。報酬調整に焦点を当てたDecision Transformerとは異なり、Trajectory Transformerはビームサーチを使用して将来のアクションを生成します。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/multilingual.md
ADDED
|
@@ -0,0 +1,178 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# 推論のための多言語モデル
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
🤗 Transformers にはいくつかの多言語モデルがあり、それらの推論の使用方法は単一言語モデルとは異なります。ただし、多言語モデルの使用方法がすべて異なるわけではありません。 [google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased) などの一部のモデルは、単一言語モデルと同様に使用できます。 このガイドでは、推論のために使用方法が異なる多言語モデルをどのように使うかを示します。
|
| 22 |
+
|
| 23 |
+
## XLM
|
| 24 |
+
|
| 25 |
+
XLM には10の異なるチェックポイントがあり、そのうちの1つだけが単一言語です。 残りの9つのモデルチェックポイントは、言語埋め込みを使用するチェックポイントと使用しないチェックポイントの2つのカテゴリに分けることができます。
|
| 26 |
+
|
| 27 |
+
### 言語の埋め込みがある XLM
|
| 28 |
+
|
| 29 |
+
次の XLM モデルは、言語の埋め込みを使用して、推論で使用される言語を指定します。
|
| 30 |
+
|
| 31 |
+
- `FacebookAI/xlm-mlm-ende-1024` (マスク化された言語モデリング、英語-ドイツ語)
|
| 32 |
+
- `FacebookAI/xlm-mlm-enfr-1024` (マスク化された言語モデリング、英語-フランス語)
|
| 33 |
+
- `FacebookAI/xlm-mlm-enro-1024` (マスク化された言語モデリング、英語-ルーマニア語)
|
| 34 |
+
- `FacebookAI/xlm-mlm-xnli15-1024` (マスク化された言語モデリング、XNLI 言語)
|
| 35 |
+
- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (マスク化された言語モデリング + 翻訳 + XNLI 言語)
|
| 36 |
+
- `FacebookAI/xlm-clm-enfr-1024` (因果言語モデリング、英語-フランス語)
|
| 37 |
+
- `FacebookAI/xlm-clm-ende-1024` (因果言語モデリング、英語-ドイツ語)
|
| 38 |
+
|
| 39 |
+
言語の埋め込みは、モデルに渡される `input_ids` と同じ形状のテンソルとして表されます。 これらのテンソルの値は、使用される言語に依存し、トークナイザーの `lang2id` および `id2lang` 属性によって識別されます。
|
| 40 |
+
|
| 41 |
+
この例では、`FacebookAI/xlm-clm-enfr-1024` チェックポイントをロードします (因果言語モデリング、英語-フランス語)。
|
| 42 |
+
|
| 43 |
+
```py
|
| 44 |
+
>>> import torch
|
| 45 |
+
>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
|
| 46 |
+
|
| 47 |
+
>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
|
| 48 |
+
>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
|
| 49 |
+
```
|
| 50 |
+
|
| 51 |
+
トークナイザーの `lang2id` 属性は、このモデルの言語とその ID を表示します。
|
| 52 |
+
|
| 53 |
+
```py
|
| 54 |
+
>>> print(tokenizer.lang2id)
|
| 55 |
+
{'en': 0, 'fr': 1}
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
次に、入力例を作成します。
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size of 1
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
言語 ID を `en` に設定し、それを使用して言語の埋め込みを定義します。 言語の埋め込みは、英語の言語 ID であるため、`0` で埋められたテンソルです。 このテンソルは `input_ids` と同じサイズにする必要があります。
|
| 65 |
+
|
| 66 |
+
```py
|
| 67 |
+
>>> language_id = tokenizer.lang2id["en"] # 0
|
| 68 |
+
>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
|
| 69 |
+
|
| 70 |
+
>>> # We reshape it to be of size (batch_size, sequence_length)
|
| 71 |
+
>>> langs = langs.view(1, -1) # is now of shape [1, sequence_length] (we have a batch size of 1)
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
これで、`input_ids` と言語の埋め込みをモデルに渡すことができます。
|
| 75 |
+
|
| 76 |
+
```py
|
| 77 |
+
>>> outputs = model(input_ids, langs=langs)
|
| 78 |
+
```
|
| 79 |
+
|
| 80 |
+
[run_generation.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation/run_generation.py) スクリプトは、`xlm-clm` チェックポイントを使用して、言語が埋め込まれたテキストを生成できます。
|
| 81 |
+
|
| 82 |
+
### 言語の埋め込みがないXLM
|
| 83 |
+
|
| 84 |
+
次の XLM モデルは、推論中に言語の埋め込みを必要としません。
|
| 85 |
+
|
| 86 |
+
- `FacebookAI/xlm-mlm-17-1280` (マスク化された言語モデリング、17の言語)
|
| 87 |
+
- `FacebookAI/xlm-mlm-100-1280` (マスク化された言語モデリング、100の言語)
|
| 88 |
+
|
| 89 |
+
これらのモデルは、以前の XLM チェックポイントとは異なり、一般的な文の表現に使用されます。
|
| 90 |
+
|
| 91 |
+
## BERT
|
| 92 |
+
|
| 93 |
+
以下の BERT モデルは、多言語タスクに使用できます。
|
| 94 |
+
|
| 95 |
+
- `google-bert/bert-base-multilingual-uncased` (マスク化された言語モデリング + 次の文の予測、102の言語)
|
| 96 |
+
- `google-bert/bert-base-multilingual-cased` (マスク化された言語モデリング + 次の文の予測、104の言語)
|
| 97 |
+
|
| 98 |
+
これらのモデルは、推論中に言語の埋め込みを必要としません。 文脈から言語を識別し、それに応じて推測する必要があります。
|
| 99 |
+
|
| 100 |
+
## XLM-RoBERTa
|
| 101 |
+
|
| 102 |
+
次の XLM-RoBERTa モデルは、多言語タスクに使用できます。
|
| 103 |
+
|
| 104 |
+
- `FacebookAI/xlm-roberta-base` (マスク化された言語モデリング、100の言語)
|
| 105 |
+
- `FacebookAI/xlm-roberta-large` (マスク化された言語モデリング、100の言語)
|
| 106 |
+
|
| 107 |
+
XLM-RoBERTa は、100の言語で新しく作成およびクリーニングされた2.5 TB の CommonCrawl データでトレーニングされました。 これは、分類、シーケンスのラベル付け、質問応答などのダウンストリームタスクで、mBERT や XLM などの以前にリリースされた多言語モデルを大幅に改善します。
|
| 108 |
+
|
| 109 |
+
## M2M100
|
| 110 |
+
|
| 111 |
+
次の M2M100 モデルは、多言語翻訳に使用できます。
|
| 112 |
+
|
| 113 |
+
- `facebook/m2m100_418M` (翻訳)
|
| 114 |
+
- `facebook/m2m100_1.2B` (翻訳)
|
| 115 |
+
|
| 116 |
+
この例では、`facebook/m2m100_418M` チェックポイントをロードして、中国語から英語に翻訳します。 トークナイザーでソース言語を設定できます。
|
| 117 |
+
|
| 118 |
+
```py
|
| 119 |
+
>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
|
| 120 |
+
|
| 121 |
+
>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
|
| 122 |
+
>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
|
| 123 |
+
|
| 124 |
+
>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
|
| 125 |
+
>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
テキストをトークン化します。
|
| 129 |
+
|
| 130 |
+
```py
|
| 131 |
+
>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
|
| 132 |
+
```
|
| 133 |
+
|
| 134 |
+
M2M100 は、最初に生成されたトークンとしてターゲット言語 ID を強制的にターゲット言語に翻訳します。 英語に翻訳するには、`generate` メソッドで `forced_bos_token_id` を `en` に設定します。
|
| 135 |
+
|
| 136 |
+
```py
|
| 137 |
+
>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
|
| 138 |
+
>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
|
| 139 |
+
'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
## MBart
|
| 143 |
+
|
| 144 |
+
多言語翻訳には、次の MBart モデルを使用できます。
|
| 145 |
+
|
| 146 |
+
- `facebook/mbart-large-50-one-to-many-mmt` (One-to-many multilingual machine translation, 50 languages)
|
| 147 |
+
- `facebook/mbart-large-50-many-to-many-mmt` (Many-to-many multilingual machine translation, 50 languages)
|
| 148 |
+
- `facebook/mbart-large-50-many-to-one-mmt` (Many-to-one multilingual machine translation, 50 languages)
|
| 149 |
+
- `facebook/mbart-large-50` (Multilingual translation, 50 languages)
|
| 150 |
+
- `facebook/mbart-large-cc25`
|
| 151 |
+
|
| 152 |
+
この例では、`facebook/mbart-large-50-many-to-many-mmt` チェックポイントをロードして、フィンランド語を英語に翻訳します。トークナイザーでソース言語を設定できます。
|
| 153 |
+
|
| 154 |
+
```py
|
| 155 |
+
>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
|
| 156 |
+
|
| 157 |
+
>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
|
| 158 |
+
>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
|
| 159 |
+
|
| 160 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
|
| 161 |
+
>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
|
| 162 |
+
```
|
| 163 |
+
|
| 164 |
+
テキストをトークン化します。
|
| 165 |
+
|
| 166 |
+
```py
|
| 167 |
+
>>> encoded_en = tokenizer(en_text, return_tensors="pt")
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
MBart は、最初に生成されたトークンとしてターゲット言語 ID を強制的にターゲット言語に翻訳します。 英語に翻訳するには、`generate` メソッドで `forced_bos_token_id` を `en` に設定します。
|
| 171 |
+
|
| 172 |
+
```py
|
| 173 |
+
>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
|
| 174 |
+
>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
|
| 175 |
+
"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
|
| 176 |
+
```
|
| 177 |
+
|
| 178 |
+
`facebook/mbart-large-50-many-to-one-mmt` チェックポイントを使用している場合、最初に生成されたトークンとしてターゲット言語 ID を強制する必要はありません。それ以外の場合、使用方法は同じです。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pad_truncation.md
ADDED
|
@@ -0,0 +1,63 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Padding and truncation
|
| 18 |
+
|
| 19 |
+
バッチ入力はしばしば異なる長さであり、固定サイズのテンソルに変換できないため、変動する長さのバッチから長方形のテンソルを作成するための戦略として、パディングと切り詰めがあります。パディングは、短いシーケンスがバッチ内の最長シーケンスまたはモデルが受け入れる最大長と同じ長さになるように、特別な**パディングトークン**を追加します。切り詰めは、長いシーケンスを切り詰めることで逆方向に機能します。
|
| 20 |
+
|
| 21 |
+
ほとんどの場合、バッチを最長シーケンスの長さにパディングし、モデルが受け入れる最大長に切り詰めることで、うまく動作します。ただし、APIはそれ以上の戦略もサポートしています。必要な3つの引数は次のとおりです:`padding`、`truncation`、および `max_length`。
|
| 22 |
+
|
| 23 |
+
`padding`引数はパディングを制御します。ブール値または文字列であることができます:
|
| 24 |
+
|
| 25 |
+
- `True`または`'longest'`:バッチ内の最長シーケンスにパディングを追加します(シーケンスが1つしか提供されない場合、パディングは適用されません)。
|
| 26 |
+
- `max_length'`:`max_length`引数で指定された長さまでパディングを追加します。または`max_length`が提供されていない場合はモデルが受け入れる最大長(`max_length=None`)。シーケンスが1つしか提供されている場合でも、パディングは適用されます。
|
| 27 |
+
- `False`または`'do_not_pad'`:パディングは適用されません。これがデフォルトの動作です。
|
| 28 |
+
|
| 29 |
+
`truncation`引数は切り詰めを制御します。ブール値または文字列であることができます:
|
| 30 |
+
|
| 31 |
+
- `True`または`'longest_first'`:最大長を`max_length`引数で指定するか、モデルが受け入れる最大長(`max_length=None`)まで切り詰めます。これはトークンごとに切り詰め、適切な長さに達するまでペア内の最長シーケンスからトークンを削除します。
|
| 32 |
+
- `'only_second'`:最大長を`max_length`引数で指定するか、モデルが受け入れる最大長(`max_length=None`)まで切り詰めます。これはペアの2番目の文だけを切り詰めます(シーケンスのペアまたはシーケンスのバッチのペアが提供された場合)。
|
| 33 |
+
- `'only_first'`:最大長を`max_length`引数で指定するか、モデルが受け入れる最大長(`max_length=None`)まで切り詰めます。これはペアの最初の文だけを切り詰めます(シーケンスのペアまたはシーケンスのバッチのペアが提供された場合)。
|
| 34 |
+
- `False`または`'do_not_truncate'`:切り詰めは適用されません。これがデフォルトの動作です。
|
| 35 |
+
|
| 36 |
+
`max_length`引数はパディングと切り詰めの長さを制御します。整数または`None`であり、この場合、モデルが受け入れる最大入力長にデフォルトで設定されます。モデルに特定の最大入力長がない場合、`max_length`への切り詰めまたはパディングは無効になります。
|
| 37 |
+
|
| 38 |
+
以下の表は、パディングと切り詰めを設定する推奨方法を要約しています。以下の例のいずれかで入力シーケンスのペアを使用する場合、`truncation=True`を`['only_first', 'only_second', 'longest_first']`で選択した`STRATEGY`に置き換えることができます。つまり、`truncation='only_second'`または`truncation='longest_first'`を使用して、ペア内の両方のシーケンスを前述のように切り詰める方法を制御できます。
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
| Truncation | Padding | Instruction |
|
| 43 |
+
|--------------------------------------|-----------------------------------|---------------------------------------------------------------------------------------------|
|
| 44 |
+
| no truncation | no padding | `tokenizer(batch_sentences)` |
|
| 45 |
+
| | padding to max sequence in batch | `tokenizer(batch_sentences, padding=True)` or |
|
| 46 |
+
| | | `tokenizer(batch_sentences, padding='longest')` |
|
| 47 |
+
| | padding to max model input length | `tokenizer(batch_sentences, padding='max_length')` |
|
| 48 |
+
| | padding to specific length | `tokenizer(batch_sentences, padding='max_length', max_length=42)` |
|
| 49 |
+
| | padding to a multiple of a value | `tokenizer(batch_sentences, padding=True, pad_to_multiple_of=8)` |
|
| 50 |
+
| truncation to max model input length | no padding | `tokenizer(batch_sentences, truncation=True)` or |
|
| 51 |
+
| | | `tokenizer(batch_sentences, truncation=STRATEGY)` |
|
| 52 |
+
| | padding to max sequence in batch | `tokenizer(batch_sentences, padding=True, truncation=True)` or |
|
| 53 |
+
| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY)` |
|
| 54 |
+
| | padding to max model input length | `tokenizer(batch_sentences, padding='max_length', truncation=True)` or |
|
| 55 |
+
| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY)` |
|
| 56 |
+
| | padding to specific length | Not possible |
|
| 57 |
+
| truncation to specific length | no padding | `tokenizer(batch_sentences, truncation=True, max_length=42)` or |
|
| 58 |
+
| | | `tokenizer(batch_sentences, truncation=STRATEGY, max_length=42)` |
|
| 59 |
+
| | padding to max sequence in batch | `tokenizer(batch_sentences, padding=True, truncation=True, max_length=42)` or |
|
| 60 |
+
| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY, max_length=42)` |
|
| 61 |
+
| | padding to max model input length | Not possible |
|
| 62 |
+
| | padding to specific length | `tokenizer(batch_sentences, padding='max_length', truncation=True, max_length=42)` or |
|
| 63 |
+
| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY, max_length=42)` |
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/peft.md
ADDED
|
@@ -0,0 +1,214 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 3 |
+
the License. You may obtain a copy of the License at
|
| 4 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 5 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 6 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 7 |
+
specific language governing permissions and limitations under the License.
|
| 8 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 9 |
+
rendered properly in your Markdown viewer.
|
| 10 |
+
-->
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
# Load adapters with 🤗 PEFT
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
[Parameter-Efficient Fine Tuning (PEFT)](https://huggingface.co/blog/peft) メソッドは、事前学習済みモデルのパラメータをファインチューニング中に凍結し、その上にわずかな訓練可能なパラメータ(アダプター)を追加するアプローチです。アダプターは、タスク固有の情報を学習するために訓練されます。このアプローチは、メモリ使用量が少なく、完全にファインチューニングされたモデルと比較して計算リソースを低く抑えつつ、同等の結果を生成することが示されています。
|
| 18 |
+
|
| 19 |
+
PEFTで訓練されたアダプターは通常、完全なモデルのサイズよりも1桁小さく、共有、保存、読み込むのが便利です。
|
| 20 |
+
|
| 21 |
+
<div class="flex flex-col justify-center">
|
| 22 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/peft/PEFT-hub-screenshot.png"/>
|
| 23 |
+
<figcaption class="text-center">Hubに格納されているOPTForCausalLMモデルのアダプター重みは、モデルの全体サイズの約6MBで、モデル重みの全サイズは約700MBです。</figcaption>
|
| 24 |
+
</div>
|
| 25 |
+
|
| 26 |
+
🤗 PEFTライブラリについて詳しく知りたい場合は、[ドキュメンテーション](https://huggingface.co/docs/peft/index)をご覧ください。
|
| 27 |
+
|
| 28 |
+
## Setup
|
| 29 |
+
|
| 30 |
+
🤗 PEFTをインストールして始めましょう:
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
```bash
|
| 34 |
+
pip install peft
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
新機能を試してみたい場合、ソースからライブラリをインストールすることに興味があるかもしれません:
|
| 38 |
+
|
| 39 |
+
```bash
|
| 40 |
+
pip install git+https://github.com/huggingface/peft.git
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
## Supported PEFT models
|
| 44 |
+
|
| 45 |
+
🤗 Transformersは、いくつかのPEFT(Parameter Efficient Fine-Tuning)メソッドをネイティブにサポートしており、ローカルまたはHubに格納されたアダプターウェイトを簡単に読み込んで実行またはトレーニングできます。以下のメソッドがサポートされています:
|
| 46 |
+
|
| 47 |
+
- [Low Rank Adapters](https://huggingface.co/docs/peft/conceptual_guides/lora)
|
| 48 |
+
- [IA3](https://huggingface.co/docs/peft/conceptual_guides/ia3)
|
| 49 |
+
- [AdaLoRA](https://arxiv.org/abs/2303.10512)
|
| 50 |
+
|
| 51 |
+
他のPEFTメソッドを使用したい場合、プロンプト学習やプロンプト調整などについて詳しく知りたい場合、または🤗 PEFTライブラリ全般については、[ドキュメンテーション](https://huggingface.co/docs/peft/index)を参照してください。
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
## Load a PEFT adapter
|
| 55 |
+
|
| 56 |
+
🤗 TransformersからPEFTアダプターモデルを読み込んで使用するには、Hubリポジトリまたはローカルディレクトリに `adapter_config.json` ファイルとアダプターウェイトが含まれていることを確認してください。次に、`AutoModelFor` クラスを使用してPEFTアダプターモデルを読み込むことができます。たとえば、因果言語モデリング用のPEFTアダプターモデルを読み込むには:
|
| 57 |
+
|
| 58 |
+
1. PEFTモデルのIDを指定します。
|
| 59 |
+
2. それを[`AutoModelForCausalLM`] クラスに渡します。
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
```py
|
| 63 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 64 |
+
|
| 65 |
+
peft_model_id = "ybelkada/opt-350m-lora"
|
| 66 |
+
model = AutoModelForCausalLM.from_pretrained(peft_model_id)
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
<Tip>
|
| 70 |
+
|
| 71 |
+
PEFTアダプターを`AutoModelFor`クラスまたは基本モデルクラス(`OPTForCausalLM`または`LlamaForCausalLM`など)で読み込むことができます。
|
| 72 |
+
|
| 73 |
+
</Tip>
|
| 74 |
+
|
| 75 |
+
また、`load_adapter`メソッドを呼び出すことで、PEFTアダプターを読み込むこともできます:
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
```py
|
| 79 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 80 |
+
|
| 81 |
+
model_id = "facebook/opt-350m"
|
| 82 |
+
peft_model_id = "ybelkada/opt-350m-lora"
|
| 83 |
+
|
| 84 |
+
model = AutoModelForCausalLM.from_pretrained(model_id)
|
| 85 |
+
model.load_adapter(peft_model_id)
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
## Load in 8bit or 4bit
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
`bitsandbytes` 統合は、8ビットおよび4ビットの精度データ型をサポートしており、大規模なモデルを読み込む際にメモリを節約するのに役立ちます(詳細については `bitsandbytes` 統合の[ガイド](./quantization#bitsandbytes-integration)を参照して��ださい)。[`~PreTrainedModel.from_pretrained`] に `load_in_8bit` または `load_in_4bit` パラメータを追加し、`device_map="auto"` を設定してモデルを効果的にハードウェアに分散配置できます:
|
| 92 |
+
|
| 93 |
+
```py
|
| 94 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
|
| 95 |
+
|
| 96 |
+
peft_model_id = "ybelkada/opt-350m-lora"
|
| 97 |
+
model = AutoModelForCausalLM.from_pretrained(peft_model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
## Add a new adapter
|
| 101 |
+
|
| 102 |
+
既存のアダプターを持つモデルに新しいアダプターを追加するために [`~peft.PeftModel.add_adapter`] を使用できます。ただし、新しいアダプターは現在のアダプターと同じタイプである限り、これを行うことができます。たとえば、モデルに既存の LoRA アダプターがアタッチされている場合:
|
| 103 |
+
|
| 104 |
+
|
| 105 |
+
```py
|
| 106 |
+
from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
|
| 107 |
+
from peft import PeftConfig
|
| 108 |
+
|
| 109 |
+
model_id = "facebook/opt-350m"
|
| 110 |
+
model = AutoModelForCausalLM.from_pretrained(model_id)
|
| 111 |
+
|
| 112 |
+
lora_config = LoraConfig(
|
| 113 |
+
target_modules=["q_proj", "k_proj"],
|
| 114 |
+
init_lora_weights=False
|
| 115 |
+
)
|
| 116 |
+
|
| 117 |
+
model.add_adapter(lora_config, adapter_name="adapter_1")
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
新しいアダプタを追加するには:
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
```py
|
| 124 |
+
# attach new adapter with same config
|
| 125 |
+
model.add_adapter(lora_config, adapter_name="adapter_2")
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
[`~peft.PeftModel.set_adapter`] を使用して、どのアダプターを使用するかを設定できます:
|
| 129 |
+
|
| 130 |
+
|
| 131 |
+
```py
|
| 132 |
+
# use adapter_1
|
| 133 |
+
model.set_adapter("adapter_1")
|
| 134 |
+
output = model.generate(**inputs)
|
| 135 |
+
print(tokenizer.decode(output_disabled[0], skip_special_tokens=True))
|
| 136 |
+
|
| 137 |
+
# use adapter_2
|
| 138 |
+
model.set_adapter("adapter_2")
|
| 139 |
+
output_enabled = model.generate(**inputs)
|
| 140 |
+
print(tokenizer.decode(output_enabled[0], skip_special_tokens=True))
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
## Enable and disable adapters
|
| 144 |
+
|
| 145 |
+
モデルにアダプターを追加したら、アダプターモジュールを有効または無効にすることができます。アダプターモジュールを有効にするには、次の手順を実行します:
|
| 146 |
+
|
| 147 |
+
```py
|
| 148 |
+
from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
|
| 149 |
+
from peft import PeftConfig
|
| 150 |
+
|
| 151 |
+
model_id = "facebook/opt-350m"
|
| 152 |
+
adapter_model_id = "ybelkada/opt-350m-lora"
|
| 153 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 154 |
+
text = "Hello"
|
| 155 |
+
inputs = tokenizer(text, return_tensors="pt")
|
| 156 |
+
|
| 157 |
+
model = AutoModelForCausalLM.from_pretrained(model_id)
|
| 158 |
+
peft_config = PeftConfig.from_pretrained(adapter_model_id)
|
| 159 |
+
|
| 160 |
+
# to initiate with random weights
|
| 161 |
+
peft_config.init_lora_weights = False
|
| 162 |
+
|
| 163 |
+
model.add_adapter(peft_config)
|
| 164 |
+
model.enable_adapters()
|
| 165 |
+
output = model.generate(**inputs)
|
| 166 |
+
```
|
| 167 |
+
|
| 168 |
+
アダプターモジュールを無効にするには:
|
| 169 |
+
|
| 170 |
+
```py
|
| 171 |
+
model.disable_adapters()
|
| 172 |
+
output = model.generate(**inputs)
|
| 173 |
+
```
|
| 174 |
+
|
| 175 |
+
## Train a PEFT adapter
|
| 176 |
+
|
| 177 |
+
PEFTアダプターは[`Trainer`]クラスでサポートされており、特定のユースケースに対してアダプターをトレーニングすることができます。数行のコードを追加するだけで済みます。たとえば、LoRAアダプターをトレーニングする場合:
|
| 178 |
+
|
| 179 |
+
<Tip>
|
| 180 |
+
|
| 181 |
+
[`Trainer`]を使用したモデルの微調整に慣れていない場合は、[事前トレーニング済みモデルの微調整](training)チュートリアルをご覧ください。
|
| 182 |
+
|
| 183 |
+
</Tip>
|
| 184 |
+
|
| 185 |
+
1. タスクタイプとハイパーパラメータに対するアダプターの構成を定義します(ハイパーパラメータの詳細については[`~peft.LoraConfig`]を参照してください)。
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
```py
|
| 189 |
+
from peft import LoraConfig
|
| 190 |
+
|
| 191 |
+
peft_config = LoraConfig(
|
| 192 |
+
lora_alpha=16,
|
| 193 |
+
lora_dropout=0.1,
|
| 194 |
+
r=64,
|
| 195 |
+
bias="none",
|
| 196 |
+
task_type="CAUSAL_LM",
|
| 197 |
+
)
|
| 198 |
+
```
|
| 199 |
+
|
| 200 |
+
2. モデルにアダプターを追加する。
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
```py
|
| 204 |
+
model.add_adapter(peft_config)
|
| 205 |
+
```
|
| 206 |
+
|
| 207 |
+
3. これで、モデルを [`Trainer`] に渡すことができます!
|
| 208 |
+
|
| 209 |
+
```py
|
| 210 |
+
trainer = Trainer(model=model, ...)
|
| 211 |
+
trainer.train()
|
| 212 |
+
```
|
| 213 |
+
|
| 214 |
+
保存するトレーニング済みアダプタとそれを読み込むための手順:
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_hardware.md
ADDED
|
@@ -0,0 +1,160 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!---
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
you may not use this file except in compliance with the License.
|
| 6 |
+
You may obtain a copy of the License at
|
| 7 |
+
|
| 8 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
|
| 10 |
+
Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
See the License for the specific language governing permissions and
|
| 14 |
+
limitations under the License.
|
| 15 |
+
|
| 16 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 17 |
+
rendered properly in your Markdown viewer.
|
| 18 |
+
|
| 19 |
+
-->
|
| 20 |
+
|
| 21 |
+
# Custom hardware for training
|
| 22 |
+
|
| 23 |
+
モデルのトレーニングおよび推論に使用するハードウェアは、パフォーマンスに大きな影響を与えることがあります。GPUについて詳しく知りたい場合は、Tim Dettmerの優れた[ブログ記事](https://timdettmers.com/2020/09/07/which-gpu-for-deep-learning/)をチェックしてみてください。
|
| 24 |
+
|
| 25 |
+
GPUセットアップの実用的なアドバイスをいくつか見てみましょう。
|
| 26 |
+
|
| 27 |
+
## GPU
|
| 28 |
+
より大きなモデルをトレーニングする場合、基本的には以下の3つのオプションがあります:
|
| 29 |
+
|
| 30 |
+
- より大きなGPU
|
| 31 |
+
- より多くのGPU
|
| 32 |
+
- より多くのCPUおよびNVMe([DeepSpeed-Infinity](main_classes/deepspeed#nvme-support)によるオフロード)
|
| 33 |
+
|
| 34 |
+
まず、単一のGPUを使用する場合から始めましょう。
|
| 35 |
+
|
| 36 |
+
### Power and Cooling
|
| 37 |
+
|
| 38 |
+
高価なハイエンドGPUを購入した場合、正しい電力供給と十分な冷却を提供することが重要です。
|
| 39 |
+
|
| 40 |
+
**電力**:
|
| 41 |
+
|
| 42 |
+
一部の高級コンシューマGPUカードには、2つまたは3つのPCI-E 8ピン電源ソケットがあります。カードにあるソケットの数だけ、独立した12V PCI-E 8ピンケーブルが接続されていることを確認してください。同じケーブルの一端にある2つの分岐(またはピッグテールケーブルとしても知られています)を使用しないでください。つまり、GPUに2つのソケットがある場合、PSUからカードに向けて2つのPCI-E 8ピンケーブルを使用し、1つのケーブルの端に2つのPCI-E 8ピンコネクタがあるものは使用しないでください!そうしないと、カードからのパフォーマンスを十分に引き出すことができません。
|
| 43 |
+
|
| 44 |
+
各PCI-E 8ピン電源ケーブルは、PSU側の12Vレールに接続する必要があり、最大で150Wの電力を供給できます。
|
| 45 |
+
|
| 46 |
+
一部のカードはPCI-E 12ピンコネクタを使用することがあり、これらは最大で500-600Wの電力を供給できます。
|
| 47 |
+
|
| 48 |
+
低価格帯のカードは6ピンコネクタを使用することがあり、最大で75Wの電力を供給します。
|
| 49 |
+
|
| 50 |
+
さらに、カードが必要とする安定した電圧を提供する高品質な電源ユニット(PSU)を使用する必要があります。
|
| 51 |
+
|
| 52 |
+
もちろん、PSUにはカードを駆動するために十分な未使用の電力が必要です。
|
| 53 |
+
|
| 54 |
+
**冷却**:
|
| 55 |
+
|
| 56 |
+
GPUが過熱すると、スロットリングが開始され、フルパフォーマンスを提供しなくなり、過熱しすぎるとシャットダウンすることさえあります。
|
| 57 |
+
|
| 58 |
+
GPUが重要な負荷の下でどのような温度を目指すべきかを正確に示すことは難しいですが、おそらく+80℃未満であれば良いでしょうが、それより低い方が良いです - おそらく70-75℃が優れた範囲でしょう。スロットリングの開始温度はおそらく84-90℃のあたりからでしょう。スロットリングによるパフォーマンスの低下以外にも、長時間にわたる非常に高い温度はGPUの寿命を短縮する可能性があります。
|
| 59 |
+
|
| 60 |
+
次に、複数のGPUを持つ際に最も重要な側面の一つである接続について詳しく見てみましょう。
|
| 61 |
+
|
| 62 |
+
### Multi-GPU Connectivity
|
| 63 |
+
|
| 64 |
+
複数のGPUを使用する場合、カードの相互接続方法はトータルのトレーニング時間に大きな影響を与える可能性があります。GPUが同じ物理ノードにある場合、次のように実行できます:
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
```bash
|
| 68 |
+
nvidia-smi topo -m
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
もちろん、GPUがどのように相互接続されているかについて説明します。デュアルGPUを搭載し、NVLinkで接続されているマシンでは、おそらく以下のような情報が表示されるでしょう:
|
| 72 |
+
|
| 73 |
+
```
|
| 74 |
+
GPU0 GPU1 CPU Affinity NUMA Affinity
|
| 75 |
+
GPU0 X NV2 0-23 N/A
|
| 76 |
+
GPU1 NV2 X 0-23 N/A
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
別のNVLinkなしのマシンでは、以下のような状況が発生するかもしれません:
|
| 80 |
+
|
| 81 |
+
```
|
| 82 |
+
GPU0 GPU1 CPU Affinity NUMA Affinity
|
| 83 |
+
GPU0 X PHB 0-11 N/A
|
| 84 |
+
GPU1 PHB X 0-11 N/A
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
こちらが伝説です:
|
| 88 |
+
|
| 89 |
+
```
|
| 90 |
+
X = Self
|
| 91 |
+
SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
|
| 92 |
+
NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
|
| 93 |
+
PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
|
| 94 |
+
PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
|
| 95 |
+
PIX = Connection traversing at most a single PCIe bridge
|
| 96 |
+
NV# = Connection traversing a bonded set of # NVLinks
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
最初のレポートである `NV2` では、GPUは2つのNVLinkで接続されており、2番目のレポートである `PHB` では、典型的な消費者向けのPCIe+Bridgeセットアップが行われています。
|
| 100 |
+
|
| 101 |
+
あなたのセットアップでどの種類の接続性があるかを確認してください。これらの接続方法のいくつかはカード間の通信を速くすることができます(例:NVLink)、他のものは遅くすることができます(例:PHB)。
|
| 102 |
+
|
| 103 |
+
使用されるスケーラビリティソリューションの種類に応じて、接続速度は大きな影響を与えることも、小さな影響を与えることもあります。GPUがあまり頻繁に同期する必要がない場合、DDPのように、遅い接続の影響はそれほど重要ではありません。しかし、GPUが頻繁にメッセージを送信する必要がある場合、ZeRO-DPのように、高速の接続がより高速なトレーニングを実現するために非常に重要になります。
|
| 104 |
+
|
| 105 |
+
#### NVlink
|
| 106 |
+
|
| 107 |
+
[NVLink](https://en.wikipedia.org/wiki/NVLink) は、Nvidiaによって開発された有線のシリアルマルチレーンの近距離通信リンクです。
|
| 108 |
+
|
| 109 |
+
各新世代では、より高速な帯域幅が提供されます。たとえば、[Nvidia Ampere GA102 GPU Architecture](https://www.nvidia.com/content/dam/en-zz/Solutions/geforce/ampere/pdf/NVIDIA-ampere-GA102-GPU-Architecture-Whitepaper-V1.pdf) からの引用です。
|
| 110 |
+
|
| 111 |
+
> Third-Generation NVLink®
|
| 112 |
+
> GA102 GPUs utilize NVIDIA’s third-generation NVLink interface, which includes four x4 links,
|
| 113 |
+
> with each link providing 14.0625 GB/sec bandwidth in each direction between two GPUs. Four
|
| 114 |
+
> links provide 56.25 GB/sec bandwidth in each direction, and 112.5 GB/sec total bandwidth
|
| 115 |
+
> between two GPUs. Two RTX 3090 GPUs can be connected together for SLI using NVLink.
|
| 116 |
+
> (Note that 3-Way and 4-Way SLI configurations are not supported.)
|
| 117 |
+
|
| 118 |
+
したがって、`nvidia-smi topo -m` の出力の `NVX` レポートで取得する `X` が高いほど良いです。世代はあなたのGPUアーキテクチャに依存します。
|
| 119 |
+
|
| 120 |
+
小さなサンプルのwikitextを使用したgpt2言語モデルのトレーニングの実行を比較しましょう。
|
| 121 |
+
|
| 122 |
+
結果は次のとおりです:
|
| 123 |
+
|
| 124 |
+
(ここに結果を挿入)
|
| 125 |
+
|
| 126 |
+
上記のテキストの日本語訳を提供しました。Markdownコードとしてフォーマットしました。どんな他の質問があれば、お気軽にお知らせください!
|
| 127 |
+
|
| 128 |
+
| NVlink | Time |
|
| 129 |
+
| ----- | ---: |
|
| 130 |
+
| Y | 101s |
|
| 131 |
+
| N | 131s |
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
NVLinkを使用すると、トレーニングが約23%速く完了することがわかります。2番目のベンチマークでは、`NCCL_P2P_DISABLE=1`を使用して、GPUがNVLinkを使用しないように指示しています。
|
| 135 |
+
|
| 136 |
+
以下は、完全なベンチマークコードと出力です:
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
```bash
|
| 140 |
+
# DDP w/ NVLink
|
| 141 |
+
|
| 142 |
+
rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 torchrun \
|
| 143 |
+
--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
|
| 144 |
+
--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train \
|
| 145 |
+
--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
|
| 146 |
+
|
| 147 |
+
{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
|
| 148 |
+
|
| 149 |
+
# DDP w/o NVLink
|
| 150 |
+
|
| 151 |
+
rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 NCCL_P2P_DISABLE=1 torchrun \
|
| 152 |
+
--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
|
| 153 |
+
--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train
|
| 154 |
+
--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
|
| 155 |
+
|
| 156 |
+
{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
|
| 157 |
+
```
|
| 158 |
+
|
| 159 |
+
Hardware: 2x TITAN RTX 24GB each + NVlink with 2 NVLinks (`NV2` in `nvidia-smi topo -m`)
|
| 160 |
+
Software: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_cpu.md
ADDED
|
@@ -0,0 +1,74 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
# Efficient Inference on CPU
|
| 18 |
+
|
| 19 |
+
このガイドは、CPU上で大規模なモデルの効率的な推論に焦点を当てています。
|
| 20 |
+
|
| 21 |
+
## `BetterTransformer` for faster inference
|
| 22 |
+
|
| 23 |
+
最近、テキスト、画像、および音声モデルのCPU上での高速な推論のために`BetterTransformer`を統合しました。詳細については、この統合に関するドキュメンテーションを[こちら](https://huggingface.co/docs/optimum/bettertransformer/overview)で確認してください。
|
| 24 |
+
|
| 25 |
+
## PyTorch JITモード(TorchScript)
|
| 26 |
+
TorchScriptは、PyTorchコードからシリアライズ可能で最適化可能なモデルを作成する方法です。任意のTorchScriptプログラムは、Python依存性のないプロセスで保存およびロードできます。
|
| 27 |
+
デフォルトのイーガーモードと比較して、PyTorchのjitモードは通常、オペレーターフュージョンなどの最適化手法によりモデル推論のパフォーマンスが向上します。
|
| 28 |
+
|
| 29 |
+
TorchScriptの簡単な紹介については、[PyTorch TorchScriptチュートリアル](https://pytorch.org/tutorials/beginner/Intro_to_TorchScript_tutorial.html#tracing-modules)を参照してください。
|
| 30 |
+
|
| 31 |
+
### JITモードでのIPEXグラフ最適化
|
| 32 |
+
Intel® Extension for PyTorchは、Transformersシリーズモデルのjitモードにさらなる最適化を提供します。Intel® Extension for PyTorchをjitモードで使用することを強くお勧めします。Transformersモデルからよく使用されるオペレーターパターンのいくつかは、既にIntel® Extension for PyTorchでjitモードのフュージョンに対応しています。これらのフュージョンパターン(Multi-head-attentionフュージョン、Concat Linear、Linear+Add、Linear+Gelu、Add+LayerNormフュージョンなど)は有効でパフォーマンスが良いです。フュージョンの利点は、ユーザーに透過的に提供されます。分析によれば、最も人気のある質問応答、テキスト分類、トークン分類のNLPタスクの約70%が、これらのフュージョンパターンを使用してFloat32精度とBFloat16混合精度の両方でパフォーマンスの利点を得ることができます。
|
| 33 |
+
|
| 34 |
+
[IPEXグラフ最適化の詳細情報](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/graph_optimization.html)を確認してください。
|
| 35 |
+
|
| 36 |
+
#### IPEX installation:
|
| 37 |
+
|
| 38 |
+
IPEXのリリースはPyTorchに従っています。[IPEXのインストール方法](https://intel.github.io/intel-extension-for-pytorch/)を確認してください。
|
| 39 |
+
|
| 40 |
+
### Usage of JIT-mode
|
| 41 |
+
Trainerで評価または予測のためにJITモードを有効にするには、ユーザーはTrainerコマンド引数に`jit_mode_eval`を追加する必要があります。
|
| 42 |
+
|
| 43 |
+
<Tip warning={true}>
|
| 44 |
+
|
| 45 |
+
PyTorch >= 1.14.0の場合、jitモードはjit.traceでdict入力がサポートされているため、予測と評価に任意のモデルに利益をもたらす可能性があります。
|
| 46 |
+
|
| 47 |
+
PyTorch < 1.14.0の場合、jitモードはforwardパラメーターの順序がjit.traceのタプル入力の順序と一致するモデルに利益をもたらす可能性があります(質問応答モデルなど)。jit.traceがタプル入力の順序と一致しない場合、テキスト分類モデルなど、jit.traceは失敗し、これをフォールバックさせるために例外でキャッチしています。ログはユーザーに通知するために使用されます。
|
| 48 |
+
|
| 49 |
+
</Tip>
|
| 50 |
+
|
| 51 |
+
[Transformers質問応答の使用例](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)を参考にしてください。
|
| 52 |
+
|
| 53 |
+
- Inference using jit mode on CPU:
|
| 54 |
+
<pre>python run_qa.py \
|
| 55 |
+
--model_name_or_path csarron/bert-base-uncased-squad-v1 \
|
| 56 |
+
--dataset_name squad \
|
| 57 |
+
--do_eval \
|
| 58 |
+
--max_seq_length 384 \
|
| 59 |
+
--doc_stride 128 \
|
| 60 |
+
--output_dir /tmp/ \
|
| 61 |
+
--no_cuda \
|
| 62 |
+
<b>--jit_mode_eval </b></pre>
|
| 63 |
+
|
| 64 |
+
- Inference with IPEX using jit mode on CPU:
|
| 65 |
+
<pre>python run_qa.py \
|
| 66 |
+
--model_name_or_path csarron/bert-base-uncased-squad-v1 \
|
| 67 |
+
--dataset_name squad \
|
| 68 |
+
--do_eval \
|
| 69 |
+
--max_seq_length 384 \
|
| 70 |
+
--doc_stride 128 \
|
| 71 |
+
--output_dir /tmp/ \
|
| 72 |
+
--no_cuda \
|
| 73 |
+
<b>--use_ipex \</b>
|
| 74 |
+
<b>--jit_mode_eval</b></pre>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_gpu_many.md
ADDED
|
@@ -0,0 +1,127 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Efficient Inference on a Multiple GPUs
|
| 17 |
+
|
| 18 |
+
この文書には、複数のGPUで効率的に推論を行う方法に関する情報が含まれています。
|
| 19 |
+
<Tip>
|
| 20 |
+
|
| 21 |
+
注意: 複数のGPUセットアップは、[単一のGPUセクション](./perf_infer_gpu_one)で説明されているほとんどの戦略を使用できます。ただし、より良い使用法のために使用できる簡単なテクニックについても認識しておく必要があります。
|
| 22 |
+
|
| 23 |
+
</Tip>
|
| 24 |
+
|
| 25 |
+
## Flash Attention 2
|
| 26 |
+
|
| 27 |
+
Flash Attention 2の統合は、複数のGPUセットアップでも機能します。詳細については、[単一のGPUセクション](./perf_infer_gpu_one#Flash-Attention-2)の適切なセクションをご覧ください。
|
| 28 |
+
|
| 29 |
+
## BetterTransformer
|
| 30 |
+
|
| 31 |
+
[BetterTransformer](https://huggingface.co/docs/optimum/bettertransformer/overview)は、🤗 TransformersモデルをPyTorchネイティブの高速実行パスを使用するように変換し、その下でFlash Attentionなどの最適化されたカーネルを呼び出します。
|
| 32 |
+
|
| 33 |
+
BetterTransformerは、テキスト、画像、音声モデルの単一GPUおよび複数GPUでの高速推論もサポートしています。
|
| 34 |
+
<Tip>
|
| 35 |
+
|
| 36 |
+
Flash Attentionは、fp16またはbf16 dtypeを使用しているモデルにのみ使用できます。BetterTransformerを使用する前に、モデルを適切なdtypeにキャストしてください。
|
| 37 |
+
|
| 38 |
+
</Tip>
|
| 39 |
+
|
| 40 |
+
### Decoder models
|
| 41 |
+
|
| 42 |
+
テキストモデル、特にデコーダーベースのモデル(GPT、T5、Llamaなど)の場合、BetterTransformer APIはすべての注意操作を[`torch.nn.functional.scaled_dot_product_attention`オペレーター](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention)(SDPA)を使用するように変換します。これはPyTorch 2.0以降でのみ使用可能です。
|
| 43 |
+
|
| 44 |
+
モデルをBetterTransformerに変換するには:
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
from transformers import AutoModelForCausalLM
|
| 48 |
+
|
| 49 |
+
model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m")
|
| 50 |
+
# convert the model to BetterTransformer
|
| 51 |
+
model.to_bettertransformer()
|
| 52 |
+
|
| 53 |
+
# Use it for training or inference
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
SDPAは、ハードウェアや問題のサイズなどの特定の設定で[Flash Attention](https://arxiv.org/abs/2205.14135)カーネルを呼び出すこともできます。Flash Attentionを有効にするか、特定の設定(ハードウェア、問題のサイズ)で利用可能かを確認するには、[`torch.nn.kernel.sdpa_kernel`](https://pytorch.org/docs/stable/generated/torch.nn.attention.sdpa_kernel.html)をコンテキストマネージャとして使用します。
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
```diff
|
| 60 |
+
import torch
|
| 61 |
+
+ from torch.nn.attention import SDPBackend, sdpa_kernel
|
| 62 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 63 |
+
|
| 64 |
+
tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
|
| 65 |
+
model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m").to("cuda")
|
| 66 |
+
# convert the model to BetterTransformer
|
| 67 |
+
model.to_bettertransformer()
|
| 68 |
+
|
| 69 |
+
input_text = "Hello my dog is cute and"
|
| 70 |
+
inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
|
| 71 |
+
|
| 72 |
+
+ with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
|
| 73 |
+
outputs = model.generate(**inputs)
|
| 74 |
+
|
| 75 |
+
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
もしトレースバックで次のようなエラーメッセージが表示された場合:
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
```bash
|
| 82 |
+
RuntimeError: No available kernel. Aborting execution.
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
当日、Flash Attentionのカバレッジが広範囲である可能性があるPyTorch Nightlyバージョンを試すようにお勧めします。
|
| 86 |
+
|
| 87 |
+
```bash
|
| 88 |
+
pip3 install -U --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/cu118
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
[このブログ投稿](https://pytorch.org/blog/out-of-the-box-acceleration/)をチェックして、BetterTransformer + SDPA APIで可能なことについて詳しく学びましょう。
|
| 92 |
+
|
| 93 |
+
### Encoder Models
|
| 94 |
+
|
| 95 |
+
推論中のエンコーダーモデルでは、BetterTransformerはエンコーダーレイヤーのforward呼び出しを、エンコーダーレイヤーの[`torch.nn.TransformerEncoderLayer`](https://pytorch.org/docs/stable/generated/torch.nn.TransformerEncoderLayer.html)の相当するものにディスパッチします。これにより、エンコーダーレイヤーの高速実装が実行されます��
|
| 96 |
+
|
| 97 |
+
`torch.nn.TransformerEncoderLayer`の高速実装はトレーニングをサポートしていないため、代わりに`torch.nn.functional.scaled_dot_product_attention`にディスパッチされます。これにより、ネストされたテンソルを活用しないFlash AttentionまたはMemory-Efficient Attentionの融合カーネルを使用できます。
|
| 98 |
+
|
| 99 |
+
BetterTransformerのパフォーマンスの詳細については、この[ブログ投稿](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)をご覧いただけます。また、エンコーダーモデル用のBetterTransformerについては、この[ブログ](https://pytorch.org/blog/a-better-transformer-for-fast-transformer-encoder-inference/)で詳しく学ぶことができます。
|
| 100 |
+
|
| 101 |
+
|
| 102 |
+
## Advanced usage: mixing FP4 (or Int8) and BetterTransformer
|
| 103 |
+
|
| 104 |
+
モデルの最良のパフォーマンスを得るために、上記で説明した異なる方法を組み合わせることができます。例えば、FP4ミックスプレシジョン推論+Flash Attentionを使用したBetterTransformerを組み合わせることができます。
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
```py
|
| 108 |
+
import torch
|
| 109 |
+
from torch.nn.attention import SDPBackend, sdpa_kernel
|
| 110 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
|
| 111 |
+
|
| 112 |
+
quantization_config = BitsAndBytesConfig(
|
| 113 |
+
load_in_4bit=True,
|
| 114 |
+
bnb_4bit_compute_dtype=torch.float16
|
| 115 |
+
)
|
| 116 |
+
|
| 117 |
+
tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
|
| 118 |
+
model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", quantization_config=quantization_config)
|
| 119 |
+
|
| 120 |
+
input_text = "Hello my dog is cute and"
|
| 121 |
+
inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
|
| 122 |
+
|
| 123 |
+
with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
|
| 124 |
+
outputs = model.generate(**inputs)
|
| 125 |
+
|
| 126 |
+
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
|
| 127 |
+
```
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_gpu_one.md
ADDED
|
@@ -0,0 +1,443 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Efficient Inference on a Single GPU
|
| 17 |
+
|
| 18 |
+
このガイドに加えて、[1つのGPUでのトレーニングガイド](perf_train_gpu_one)と[CPUでの推論ガイド](perf_infer_cpu)に関連する情報があります。
|
| 19 |
+
|
| 20 |
+
## Flash Attention 2
|
| 21 |
+
|
| 22 |
+
<Tip>
|
| 23 |
+
|
| 24 |
+
この機能は実験的であり、将来のバージョンで大幅に変更される可能性があります。たとえば、Flash Attention 2 APIは近い将来`BetterTransformer` APIに移行するかもしれません。
|
| 25 |
+
|
| 26 |
+
</Tip>
|
| 27 |
+
|
| 28 |
+
Flash Attention 2は、トランスフォーマーベースのモデルのトレーニングと推論速度を大幅に高速化できます。Flash Attention 2は、Tri Dao氏によって[公式のFlash Attentionリポジトリ](https://github.com/Dao-AILab/flash-attention)で導入されました。Flash Attentionに関する科学論文は[こちら](https://arxiv.org/abs/2205.14135)で見ることができます。
|
| 29 |
+
|
| 30 |
+
Flash Attention 2を正しくインストールするには、上記のリポジトリに記載されているインストールガイドに従ってください。
|
| 31 |
+
|
| 32 |
+
以下のモデルに対してFlash Attention 2をネイティブサポートしています:
|
| 33 |
+
|
| 34 |
+
- Llama
|
| 35 |
+
- Falcon
|
| 36 |
+
|
| 37 |
+
さらに多くのモデルにFlash Attention 2のサポートを追加することをGitHubで提案することもでき、変更を統合するためにプルリクエストを開くこともできます。サポートされているモデルは、パディングトークンを使用してトレーニングを含む、推論とトレーニングに使用できます(現在の`BetterTransformer` APIではサポートされていない)。
|
| 38 |
+
|
| 39 |
+
<Tip>
|
| 40 |
+
|
| 41 |
+
Flash Attention 2は、モデルのdtypeが`fp16`または`bf16`の場合にのみ使用でき、NVIDIA-GPUデバイスでのみ実行されます。この機能を使用する前に、モデルを適切なdtypeにキャストし、サポートされているデバイスにロードしてください。
|
| 42 |
+
|
| 43 |
+
</Tip>
|
| 44 |
+
|
| 45 |
+
### Quick usage
|
| 46 |
+
|
| 47 |
+
モデルでFlash Attention 2を有効にするには、`from_pretrained`の引数に`attn_implementation="flash_attention_2"`を追加します。
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
```python
|
| 51 |
+
import torch
|
| 52 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, LlamaForCausalLM
|
| 53 |
+
|
| 54 |
+
model_id = "tiiuae/falcon-7b"
|
| 55 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 56 |
+
|
| 57 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 58 |
+
model_id,
|
| 59 |
+
torch_dtype=torch.bfloat16,
|
| 60 |
+
attn_implementation="flash_attention_2",
|
| 61 |
+
)
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
こちらは、生成または微調整のために使用するテキストです。
|
| 65 |
+
|
| 66 |
+
### Expected speedups
|
| 67 |
+
|
| 68 |
+
特に長いシーケンスに対して、微調整と推論の際には、かなりの高速化が期待できます。ただし、Flash Attentionはパディングトークンを使用してアテンションスコアを計算しないため、シーケンスにパディングトークンが含まれる場合、バッチ推論においてアテンションスコアを手動でパッド/アンパッドする必要があり、パディングトークンを含むバッチ生成の大幅な遅延が発生します。
|
| 69 |
+
|
| 70 |
+
これを克服するために、トレーニング中にシーケンスにパディングトークンを使用せずにFlash Attentionを使用する必要があります(たとえば、データセットをパックすることにより、シーケンスを最大シーケンス長に達するまで連結することなど)。ここに[例](https://github.com/huggingface/transformers/blob/main/examples/pytorch/language-modeling/run_clm.py#L516)が提供されています。
|
| 71 |
+
|
| 72 |
+
以下は、パディングトークンのない場合に、シーケンス長が4096の[tiiuae/falcon-7b](https://hf.co/tiiuae/falcon-7b)に対する単純なフォワードパスの予想される高速化です。さまざまなバッチサイズが示されています:
|
| 73 |
+
|
| 74 |
+
<div style="text-align: center">
|
| 75 |
+
<img src="https://huggingface.co/datasets/ybelkada/documentation-images/resolve/main/falcon-7b-inference-large-seqlen.png">
|
| 76 |
+
</div>
|
| 77 |
+
|
| 78 |
+
以下は、パディングトークンのない場合に、シーケンス長が4096の[`meta-llama/Llama-7b-hf`](https://hf.co/meta-llama/Llama-7b-hf)に対する単純なフォワードパスの予想される高速化です。さまざまなバッチサイズが示されています:
|
| 79 |
+
|
| 80 |
+
<div style="text-align: center">
|
| 81 |
+
<img src="https://huggingface.co/datasets/ybelkada/documentation-images/resolve/main/llama-7b-inference-large-seqlen.png">
|
| 82 |
+
</div>
|
| 83 |
+
|
| 84 |
+
パディングトークンを含むシーケンス(パディングトークンを使用してトレーニングまたは生成する)の場合、アテンションスコアを正しく計算するために入力シーケンスをアンパッド/パッドする必要があります。比較的小さいシーケンス長の場合、純粋なフォワードパスではパディングトークンが30%未満しか埋められていないため、これはわずかな高速化をもたらします。
|
| 85 |
+
|
| 86 |
+
<div style="text-align: center">
|
| 87 |
+
<img src="https://huggingface.co/datasets/ybelkada/documentation-images/resolve/main/llama-2-small-seqlen-padding.png">
|
| 88 |
+
</div>
|
| 89 |
+
|
| 90 |
+
しかし、大きなシーケンス長の場合、純粋な推論(トレーニングも含む)には興味深い高速化が得られます。
|
| 91 |
+
|
| 92 |
+
Flash Attentionは、アテンション計算をよりメモリ効率の良いものにし、大きなシーケンス長でのCUDA OOMの問題を回避できるようにします。大きなシーケンス長に対して最大20のメモリ削減をもたらすことがあります。詳細については、[公式のFlash Attentionリポジトリ](https://github.com/Dao-AILab/flash-attention)をご覧ください。
|
| 93 |
+
|
| 94 |
+
<div style="text-align: center">
|
| 95 |
+
<img src="https://huggingface.co/datasets/ybelkada/documentation-images/resolve/main/llama-2-large-seqlen-padding.png">
|
| 96 |
+
</div>
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
### Advanced usage
|
| 100 |
+
|
| 101 |
+
この機能をモデルの最適化に多くの既存の機能と組み合わせることができます。以下にいくつかの例を示します:
|
| 102 |
+
|
| 103 |
+
### Combining Flash Attention 2 and 8-bit models
|
| 104 |
+
|
| 105 |
+
この機能を8ビットの量子化と組み合わせることができます:
|
| 106 |
+
|
| 107 |
+
```python
|
| 108 |
+
import torch
|
| 109 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, LlamaForCausalLM
|
| 110 |
+
|
| 111 |
+
model_id = "tiiuae/falcon-7b"
|
| 112 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 113 |
+
|
| 114 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 115 |
+
model_id,
|
| 116 |
+
load_in_8bit=True,
|
| 117 |
+
attn_implementation="flash_attention_2",
|
| 118 |
+
)
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
### Combining Flash Attention 2 and 4-bit models
|
| 122 |
+
|
| 123 |
+
この機能を 4 ビットの量子化と組み合わせることができます:
|
| 124 |
+
|
| 125 |
+
```python
|
| 126 |
+
import torch
|
| 127 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, LlamaForCausalLM
|
| 128 |
+
|
| 129 |
+
model_id = "tiiuae/falcon-7b"
|
| 130 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 131 |
+
|
| 132 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 133 |
+
model_id,
|
| 134 |
+
load_in_4bit=True,
|
| 135 |
+
attn_implementation="flash_attention_2",
|
| 136 |
+
)
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
### Combining Flash Attention 2 and PEFT
|
| 140 |
+
|
| 141 |
+
この機能を使用して、Flash Attention 2をベースにアダプターをトレーニングする際にPEFTを組み合わせることができます。
|
| 142 |
+
|
| 143 |
+
```python
|
| 144 |
+
import torch
|
| 145 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, LlamaForCausalLM
|
| 146 |
+
from peft import LoraConfig
|
| 147 |
+
|
| 148 |
+
model_id = "tiiuae/falcon-7b"
|
| 149 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 150 |
+
|
| 151 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 152 |
+
model_id,
|
| 153 |
+
load_in_4bit=True,
|
| 154 |
+
attn_implementation="flash_attention_2",
|
| 155 |
+
)
|
| 156 |
+
|
| 157 |
+
lora_config = LoraConfig(
|
| 158 |
+
r=8,
|
| 159 |
+
task_type="CAUSAL_LM"
|
| 160 |
+
)
|
| 161 |
+
|
| 162 |
+
model.add_adapter(lora_config)
|
| 163 |
+
|
| 164 |
+
... # train your model
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
## BetterTransformer
|
| 168 |
+
|
| 169 |
+
[BetterTransformer](https://huggingface.co/docs/optimum/bettertransformer/overview)は、🤗 TransformersモデルをPyTorchネイティブの高速パス実行に変換します。これにより、Flash Attentionなどの最適化されたカーネルが内部で呼び出されます。
|
| 170 |
+
|
| 171 |
+
BetterTransformerは、テキスト、画像、およびオーディオモデルの単一およびマルチGPUでの高速な推論をサポートしています。
|
| 172 |
+
|
| 173 |
+
<Tip>
|
| 174 |
+
|
| 175 |
+
Flash Attentionは、fp16またはbf16のdtypeを使用するモデルにのみ使用できます。BetterTransformerを使用する前に、モデルを適切なdtypeにキャストしてください。
|
| 176 |
+
|
| 177 |
+
</Tip>
|
| 178 |
+
|
| 179 |
+
### Encoder models
|
| 180 |
+
|
| 181 |
+
PyTorchネイティブの[`nn.MultiHeadAttention`](https://pytorch.org/blog/a-better-transformer-for-fast-transformer-encoder-inference/)アテンション高速パス、BetterTransformerと呼ばれるものは、[🤗 Optimumライブラリ](https://huggingface.co/docs/optimum/bettertransformer/overview)の統合を通じてTransformersと一緒に使用できます。
|
| 182 |
+
|
| 183 |
+
PyTorchのアテンション高速パスを使用すると、カーネルフュージョンと[ネストされたテンソル](https://pytorch.org/docs/stable/nested.html)の使用により、推論を高速化できます。詳細なベンチマーク情報は[このブログ記事](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)にあります。
|
| 184 |
+
|
| 185 |
+
[`optimum`](https://github.com/huggingface/optimum)パッケージをインストールした後、推論中にBetter Transformerを使用するには、関連する内部モジュールを呼び出すことで置き換える必要があります[`~PreTrainedModel.to_bettertransformer`]:
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
```python
|
| 189 |
+
model = model.to_bettertransformer()
|
| 190 |
+
```
|
| 191 |
+
|
| 192 |
+
メソッド [`~PreTrainedModel.reverse_bettertransformer`] は、モデルを保存する前に使用すべきで、標準のトランスフォーマーモデリングを使用するためのものです:
|
| 193 |
+
|
| 194 |
+
```python
|
| 195 |
+
model = model.reverse_bettertransformer()
|
| 196 |
+
model.save_pretrained("saved_model")
|
| 197 |
+
```
|
| 198 |
+
|
| 199 |
+
BetterTransformer APIを使ったエンコーダーモデルの可能性について詳しく知るには、[このブログポスト](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)をご覧ください。
|
| 200 |
+
|
| 201 |
+
### Decoder models
|
| 202 |
+
|
| 203 |
+
テキストモデル、特にデコーダーベースのモデル(GPT、T5、Llamaなど)にとって、BetterTransformer APIはすべての注意操作を[`torch.nn.functional.scaled_dot_product_attention`オペレーター](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention)(SDPA)を使用するように変換します。このオペレーターはPyTorch 2.0以降でのみ利用可能です。
|
| 204 |
+
|
| 205 |
+
モデルをBetterTransformerに変換するには、以下の手順を実行してください:
|
| 206 |
+
|
| 207 |
+
```python
|
| 208 |
+
from transformers import AutoModelForCausalLM
|
| 209 |
+
|
| 210 |
+
model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m")
|
| 211 |
+
# convert the model to BetterTransformer
|
| 212 |
+
model.to_bettertransformer()
|
| 213 |
+
|
| 214 |
+
# Use it for training or inference
|
| 215 |
+
```
|
| 216 |
+
|
| 217 |
+
SDPAは、ハードウェアや問題のサイズに応じて[Flash Attention](https://arxiv.org/abs/2205.14135)カーネルを使用することもできます。Flash Attentionを有効にするか、特定の設定(ハードウェア、問題サイズ)で使用可能かどうかを確認するには、[`torch.nn.attention.sdpa_kernel`](https://pytorch.org/docs/stable/generated/torch.nn.attention.sdpa_kernel.html)をコンテキストマネージャとして使用します。
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
```diff
|
| 221 |
+
import torch
|
| 222 |
+
+ from torch.nn.attention import SDPBackend, sdpa_kernel
|
| 223 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 224 |
+
|
| 225 |
+
tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
|
| 226 |
+
model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", torch_dtype=torch.float16).to("cuda")
|
| 227 |
+
# convert the model to BetterTransformer
|
| 228 |
+
model.to_bettertransformer()
|
| 229 |
+
|
| 230 |
+
input_text = "Hello my dog is cute and"
|
| 231 |
+
inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
|
| 232 |
+
|
| 233 |
+
+ with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
|
| 234 |
+
outputs = model.generate(**inputs)
|
| 235 |
+
|
| 236 |
+
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
|
| 237 |
+
```
|
| 238 |
+
|
| 239 |
+
もしトレースバックにバグが表示された場合
|
| 240 |
+
|
| 241 |
+
```bash
|
| 242 |
+
RuntimeError: No available kernel. Aborting execution.
|
| 243 |
+
```
|
| 244 |
+
|
| 245 |
+
Flash Attention の広範なカバレッジを持つかもしれない PyTorch のナイトリーバージョンを試してみることをお勧めします。
|
| 246 |
+
|
| 247 |
+
```bash
|
| 248 |
+
pip3 install -U --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/cu118
|
| 249 |
+
```
|
| 250 |
+
|
| 251 |
+
Or make sure your model is correctly casted in float16 or bfloat16
|
| 252 |
+
|
| 253 |
+
モデルが正しくfloat16またはbfloat16にキャストされていることを確認してください。
|
| 254 |
+
|
| 255 |
+
Have a look at [this detailed blogpost](https://pytorch.org/blog/out-of-the-box-acceleration/) to read more about what is possible to do with `BetterTransformer` + SDPA API.
|
| 256 |
+
|
| 257 |
+
`BetterTransformer` + SDPA APIを使用して何が可能かについて詳しく読むには、[この詳細なブログポスト](https://pytorch.org/blog/out-of-the-box-acceleration/)をご覧ください。
|
| 258 |
+
|
| 259 |
+
## `bitsandbytes` integration for FP4 mixed-precision inference
|
| 260 |
+
|
| 261 |
+
FP4混合精度推論のための`bitsandbytes`統合
|
| 262 |
+
|
| 263 |
+
You can install `bitsandbytes` and benefit from easy model compression on GPUs. Using FP4 quantization you can expect to reduce up to 8x the model size compared to its native full precision version. Check out below how to get started.
|
| 264 |
+
|
| 265 |
+
`bitsandbytes`をインストールし、GPUで簡単なモデルの圧縮を利用できます。FP4量子化を使用すると、ネイティブのフルプレシジョンバージョンと比較してモデルサイズを最大8倍削減できることが期待できます。以下を確認して、どのように始めるかをご覧ください。
|
| 266 |
+
|
| 267 |
+
<Tip>
|
| 268 |
+
|
| 269 |
+
Note that this feature can also be used in a multi GPU setup.
|
| 270 |
+
|
| 271 |
+
この機能は、マルチGPUセットアップでも使用できることに注意してください。
|
| 272 |
+
|
| 273 |
+
</Tip>
|
| 274 |
+
|
| 275 |
+
### Requirements [[requirements-for-fp4-mixedprecision-inference]]
|
| 276 |
+
|
| 277 |
+
- Latest `bitsandbytes` library
|
| 278 |
+
`pip install bitsandbytes>=0.39.0`
|
| 279 |
+
|
| 280 |
+
- Install latest `accelerate` from source
|
| 281 |
+
`pip install git+https://github.com/huggingface/accelerate.git`
|
| 282 |
+
|
| 283 |
+
- Install latest `transformers` from source
|
| 284 |
+
`pip install git+https://github.com/huggingface/transformers.git`
|
| 285 |
+
|
| 286 |
+
|
| 287 |
+
### Running FP4 models - single GPU setup - Quickstart
|
| 288 |
+
|
| 289 |
+
以下のコードを実行することで、簡単に単一のGPUでFP4モデ��を実行できます:
|
| 290 |
+
|
| 291 |
+
|
| 292 |
+
```py
|
| 293 |
+
from transformers import AutoModelForCausalLM
|
| 294 |
+
|
| 295 |
+
model_name = "bigscience/bloom-2b5"
|
| 296 |
+
model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
|
| 297 |
+
```
|
| 298 |
+
|
| 299 |
+
注意: `device_map`はオプションですが、推論時に `device_map = 'auto'` を設定することが推奨されています。これにより、利用可能なリソースに効率的にモデルがディスパッチされます。
|
| 300 |
+
|
| 301 |
+
### Running FP4 models - multi GPU setup
|
| 302 |
+
|
| 303 |
+
混合4ビットモデルを複数のGPUにロードする方法は、単一GPUセットアップと同じです(単一GPUセットアップと同じコマンドです):
|
| 304 |
+
|
| 305 |
+
```py
|
| 306 |
+
model_name = "bigscience/bloom-2b5"
|
| 307 |
+
model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
|
| 308 |
+
```
|
| 309 |
+
|
| 310 |
+
しかし、`accelerate`を使用して、各GPUに割り当てるGPU RAMを制御することができます。以下のように、`max_memory`引数を使用します:
|
| 311 |
+
|
| 312 |
+
|
| 313 |
+
```py
|
| 314 |
+
max_memory_mapping = {0: "600MB", 1: "1GB"}
|
| 315 |
+
model_name = "bigscience/bloom-3b"
|
| 316 |
+
model_4bit = AutoModelForCausalLM.from_pretrained(
|
| 317 |
+
model_name, device_map="auto", load_in_4bit=True, max_memory=max_memory_mapping
|
| 318 |
+
)
|
| 319 |
+
```
|
| 320 |
+
|
| 321 |
+
この例では、最初のGPUは600MBのメモリを使用し、2番目のGPUは1GBを使用します。
|
| 322 |
+
|
| 323 |
+
### Advanced usage
|
| 324 |
+
|
| 325 |
+
このメソッドのさらなる高度な使用法については、[量子化](main_classes/quantization)のドキュメンテーションページをご覧ください。
|
| 326 |
+
|
| 327 |
+
## `bitsandbytes` integration for Int8 mixed-precision matrix decomposition
|
| 328 |
+
|
| 329 |
+
<Tip>
|
| 330 |
+
|
| 331 |
+
この機能は、マルチGPU環境でも使用できます。
|
| 332 |
+
|
| 333 |
+
</Tip>
|
| 334 |
+
|
| 335 |
+
論文[`LLM.int8():スケーラブルなTransformer向けの8ビット行列乗算`](https://arxiv.org/abs/2208.07339)によれば、Hugging Face統合がHub内のすべてのモデルでわずか数行のコードでサポートされています。このメソッドは、半精度(`float16`および`bfloat16`)の重みの場合に`nn.Linear`サイズを2倍、単精度(`float32`)の重みの場合は4倍に縮小し、外れ値に対してほとんど影響を与えません。
|
| 336 |
+
|
| 337 |
+

|
| 338 |
+
|
| 339 |
+
Int8混合精度行列分解は、行列乗算を2つのストリームに分割することによって動作します:(1) システマティックな特徴外れ値ストリームがfp16で行列乗算(0.01%)、(2) int8行列乗算の通常のストリーム(99.9%)。この方法を使用すると、非常に大きなモデルに対して予測の劣化なしにint8推論が可能です。
|
| 340 |
+
このメソッドの詳細については、[論文](https://arxiv.org/abs/2208.07339)または[この統合に関するブログ記事](https://huggingface.co/blog/hf-bitsandbytes-integration)をご確認ください。
|
| 341 |
+
|
| 342 |
+

|
| 343 |
+
|
| 344 |
+
なお、この機能を使用するにはGPUが必要であり、カーネルはGPU専用にコンパイルされている必要があります。この機能を使用する前に、モデルの1/4(またはハーフ精度の重みの場合は1/2)を保存するのに十分なGPUメモリがあることを確認してください。
|
| 345 |
+
このモジュールを使用する際のヘルプに関する詳細は、以下のノートをご覧いただくか、[Google Colabのデモ](#colab-demos)をご覧ください。
|
| 346 |
+
|
| 347 |
+
### Requirements [[requirements-for-int8-mixedprecision-matrix-decomposition]]
|
| 348 |
+
|
| 349 |
+
- `bitsandbytes<0.37.0`を使用する場合、NVIDIA GPUを使用していることを確認し、8ビットテンソルコアをサポートしていることを確認してください(Turing、Ampere、またはそれ以降のアーキテクチャー、例:T4、RTX20s RTX30s、A40-A100など)。`bitsandbytes>=0.37.0`の場合、すべてのGPUがサポートされるはずです。
|
| 350 |
+
- 正しいバージョンの`bitsandbytes`をインストールするには、次のコマンドを実行してください:
|
| 351 |
+
`pip install bitsandbytes>=0.31.5`
|
| 352 |
+
- `accelerate`をインストールします:
|
| 353 |
+
`pip install accelerate>=0.12.0`
|
| 354 |
+
|
| 355 |
+
|
| 356 |
+
### Running mixed-Int8 models - single GPU setup
|
| 357 |
+
|
| 358 |
+
必要なライブラリをインストールした後、ミックス 8 ビットモデルを読み込む方法は次の通りです:
|
| 359 |
+
|
| 360 |
+
```py
|
| 361 |
+
from transformers import AutoModelForCausalLM, BitsAndBytesConfig
|
| 362 |
+
|
| 363 |
+
model_name = "bigscience/bloom-2b5"
|
| 364 |
+
model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
|
| 365 |
+
```
|
| 366 |
+
|
| 367 |
+
以下はシンプルな例です:
|
| 368 |
+
|
| 369 |
+
* `pipeline()` 関数の代わりに、モデルの `generate()` メソッドを使用することをお勧めします。`pipeline()` 関数を使用して推論することは可能ですが、混合8ビットモデルに最適化されておらず、`generate()` メソッドを使用するよりも遅くなります。また、一部のサンプリング戦略(例:ヌクレウスサンプリング)は、`pipeline()` 関数では混合8ビットモデルではサポートされていません。
|
| 370 |
+
* すべての入力をモデルと同じデバイスに配置してください。
|
| 371 |
+
|
| 372 |
+
|
| 373 |
+
```py
|
| 374 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
|
| 375 |
+
|
| 376 |
+
model_name = "bigscience/bloom-2b5"
|
| 377 |
+
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
| 378 |
+
model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
|
| 379 |
+
|
| 380 |
+
prompt = "Hello, my llama is cute"
|
| 381 |
+
inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
|
| 382 |
+
generated_ids = model.generate(**inputs)
|
| 383 |
+
outputs = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
|
| 384 |
+
```
|
| 385 |
+
|
| 386 |
+
### Running mixed-int8 models - multi GPU setup
|
| 387 |
+
|
| 388 |
+
複数のGPUに混合8ビットモデルをロードする方法は、次の通りです(シングルGPUセットアップと同じコマンドです):
|
| 389 |
+
|
| 390 |
+
```py
|
| 391 |
+
model_name = "bigscience/bloom-2b5"
|
| 392 |
+
model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
|
| 393 |
+
```
|
| 394 |
+
|
| 395 |
+
`accelerate`を使用して各GPUに割り当てるGPU RAMを制御する際には、以下のように`max_memory`引数を使用します:
|
| 396 |
+
|
| 397 |
+
|
| 398 |
+
```py
|
| 399 |
+
max_memory_mapping = {0: "1GB", 1: "2GB"}
|
| 400 |
+
model_name = "bigscience/bloom-3b"
|
| 401 |
+
model_8bit = AutoModelForCausalLM.from_pretrained(
|
| 402 |
+
model_name, device_map="auto", load_in_8bit=True, max_memory=max_memory_mapping
|
| 403 |
+
)
|
| 404 |
+
```
|
| 405 |
+
|
| 406 |
+
In this example, the first GPU will use 1GB of memory and the second 2GB.
|
| 407 |
+
|
| 408 |
+
### Colab demos
|
| 409 |
+
|
| 410 |
+
この方法を使用すると、以前のGoogle Colabでは推論できなかったモデルに対して推論を行うことができます。以下は、Google Colabで8ビット量子化を使用してT5-11b(fp32で42GB)を実行するデモのリンクです:
|
| 411 |
+
|
| 412 |
+
[](https://colab.research.google.com/drive/1YORPWx4okIHXnjW7MSAidXN29mPVNT7F?usp=sharing)
|
| 413 |
+
|
| 414 |
+
また、BLOOM-3Bのデモもご覧いただけます:
|
| 415 |
+
|
| 416 |
+
[](https://colab.research.google.com/drive/1qOjXfQIAULfKvZqwCen8-MoWKGdSatZ4?usp=sharing)
|
| 417 |
+
|
| 418 |
+
## Advanced usage: mixing FP4 (or Int8) and BetterTransformer
|
| 419 |
+
|
| 420 |
+
異なる方法を組み合わせて、モデルの最適なパフォーマンスを得ることができます。例えば、BetterTransformerを使用してFP4ミックスプレシジョン推論とフラッシュアテンションを組み合わせることができます。
|
| 421 |
+
|
| 422 |
+
|
| 423 |
+
```py
|
| 424 |
+
import torch
|
| 425 |
+
from torch.nn.attention import SDPBackend, sdpa_kernel
|
| 426 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
|
| 427 |
+
|
| 428 |
+
quantization_config = BitsAndBytesConfig(
|
| 429 |
+
load_in_4bit=True,
|
| 430 |
+
bnb_4bit_compute_dtype=torch.float16
|
| 431 |
+
)
|
| 432 |
+
|
| 433 |
+
tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
|
| 434 |
+
model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", quantization_config=quantization_config)
|
| 435 |
+
|
| 436 |
+
input_text = "Hello my dog is cute and"
|
| 437 |
+
inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
|
| 438 |
+
|
| 439 |
+
with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
|
| 440 |
+
outputs = model.generate(**inputs)
|
| 441 |
+
|
| 442 |
+
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
|
| 443 |
+
```
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_infer_special.md
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Inference on Specialized Hardware
|
| 17 |
+
|
| 18 |
+
こちらのドキュメントは、専用のハードウェアでの推論方法についての情報がまもなく提供されます。その間に、CPUでの推論に関するガイドをご覧いただけます。[the guide for inference on CPUs](perf_infer_cpu).
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_torch_compile.md
ADDED
|
@@ -0,0 +1,359 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Optimize inference using torch.compile()
|
| 17 |
+
|
| 18 |
+
このガイドは、[`torch.compile()`](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) を使用した推論速度の向上に関するベンチマークを提供することを目的としています。これは、[🤗 Transformers のコンピュータビジョンモデル](https://huggingface.co/models?pipeline_tag=image-classification&library=transformers&sort=trending)向けのものです。
|
| 19 |
+
|
| 20 |
+
## Benefits of torch.compile
|
| 21 |
+
|
| 22 |
+
`torch.compile()`の利点
|
| 23 |
+
モデルとGPUによっては、torch.compile()は推論時に最大30%の高速化を実現します。 `torch.compile()`を使用するには、バージョン2.0以上のtorchをインストールするだけです。
|
| 24 |
+
|
| 25 |
+
モデルのコンパイルには時間がかかるため、毎回推論するのではなく、モデルを1度だけコンパイルする場合に役立ちます。
|
| 26 |
+
任意のコンピュータビジョンモデルをコンパイルするには、以下のようにモデルに`torch.compile()`を呼び出します:
|
| 27 |
+
|
| 28 |
+
```diff
|
| 29 |
+
from transformers import AutoModelForImageClassification
|
| 30 |
+
|
| 31 |
+
model = AutoModelForImageClassification.from_pretrained(MODEL_ID).to("cuda")
|
| 32 |
+
+ model = torch.compile(model)
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
`compile()` は、コンパイルに関する異なるモードを備えており、基本的にはコンパイル時間と推論のオーバーヘッドが異なります。`max-autotune` は `reduce-overhead` よりも時間がかかりますが、推論速度が速くなります。デフォルトモードはコンパイルにおいては最速ですが、推論時間においては `reduce-overhead` に比べて効率が良くありません。このガイドでは、デフォルトモードを使用しました。詳細については、[こちら](https://pytorch.org/get-started/pytorch-2.0/#user-experience) を参照してください。
|
| 36 |
+
|
| 37 |
+
`torch` バージョン 2.0.1 で異なるコンピュータビジョンモデル、タスク、ハードウェアの種類、およびバッチサイズを使用して `torch.compile` をベンチマークしました。
|
| 38 |
+
|
| 39 |
+
## Benchmarking code
|
| 40 |
+
|
| 41 |
+
以下に、各タスクのベンチマークコードを示します。推論前にGPUをウォームアップし、毎回同じ画像を使用して300回の推論の平均時間を取得します。
|
| 42 |
+
|
| 43 |
+
### Image Classification with ViT
|
| 44 |
+
|
| 45 |
+
```python
|
| 46 |
+
from PIL import Image
|
| 47 |
+
import requests
|
| 48 |
+
import numpy as np
|
| 49 |
+
from transformers import AutoImageProcessor, AutoModelForImageClassification
|
| 50 |
+
|
| 51 |
+
url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
|
| 52 |
+
image = Image.open(requests.get(url, stream=True).raw)
|
| 53 |
+
|
| 54 |
+
processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
|
| 55 |
+
model = AutoModelForImageClassification.from_pretrained("google/vit-base-patch16-224").to("cuda")
|
| 56 |
+
model = torch.compile(model)
|
| 57 |
+
|
| 58 |
+
processed_input = processor(image, return_tensors='pt').to(device="cuda")
|
| 59 |
+
|
| 60 |
+
with torch.no_grad():
|
| 61 |
+
_ = model(**processed_input)
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
#### Object Detection with DETR
|
| 65 |
+
|
| 66 |
+
```python
|
| 67 |
+
from transformers import AutoImageProcessor, AutoModelForObjectDetection
|
| 68 |
+
|
| 69 |
+
processor = AutoImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
| 70 |
+
model = AutoModelForObjectDetection.from_pretrained("facebook/detr-resnet-50").to("cuda")
|
| 71 |
+
model = torch.compile(model)
|
| 72 |
+
|
| 73 |
+
texts = ["a photo of a cat", "a photo of a dog"]
|
| 74 |
+
inputs = processor(text=texts, images=image, return_tensors="pt").to("cuda")
|
| 75 |
+
|
| 76 |
+
with torch.no_grad():
|
| 77 |
+
_ = model(**inputs)
|
| 78 |
+
```
|
| 79 |
+
|
| 80 |
+
#### Image Segmentation with Segformer
|
| 81 |
+
|
| 82 |
+
```python
|
| 83 |
+
from transformers import SegformerImageProcessor, SegformerForSemanticSegmentation
|
| 84 |
+
|
| 85 |
+
processor = SegformerImageProcessor.from_pretrained("nvidia/segformer-b0-finetuned-ade-512-512")
|
| 86 |
+
model = SegformerForSemanticSegmentation.from_pretrained("nvidia/segformer-b0-finetuned-ade-512-512").to("cuda")
|
| 87 |
+
model = torch.compile(model)
|
| 88 |
+
seg_inputs = processor(images=image, return_tensors="pt").to("cuda")
|
| 89 |
+
|
| 90 |
+
with torch.no_grad():
|
| 91 |
+
_ = model(**seg_inputs)
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
以下は、私たちがベンチマークを行ったモデルのリストです。
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
**Image Classification**
|
| 98 |
+
- [google/vit-base-patch16-224](https://huggingface.co/google/vit-base-patch16-224)
|
| 99 |
+
- [microsoft/beit-base-patch16-224-pt22k-ft22k](https://huggingface.co/microsoft/beit-base-patch16-224-pt22k-ft22k)
|
| 100 |
+
- [facebook/convnext-large-224](https://huggingface.co/facebook/convnext-large-224)
|
| 101 |
+
- [microsoft/resnet-50](https://huggingface.co/)
|
| 102 |
+
|
| 103 |
+
**Image Segmentation**
|
| 104 |
+
- [nvidia/segformer-b0-finetuned-ade-512-512](https://huggingface.co/nvidia/segformer-b0-finetuned-ade-512-512)
|
| 105 |
+
- [facebook/mask2former-swin-tiny-coco-panoptic](https://huggingface.co/facebook/mask2former-swin-tiny-coco-panoptic)
|
| 106 |
+
- [facebook/maskformer-swin-base-ade](https://huggingface.co/facebook/maskformer-swin-base-ade)
|
| 107 |
+
- [google/deeplabv3_mobilenet_v2_1.0_513](https://huggingface.co/google/deeplabv3_mobilenet_v2_1.0_513)
|
| 108 |
+
|
| 109 |
+
**Object Detection**
|
| 110 |
+
- [google/owlvit-base-patch32](https://huggingface.co/google/owlvit-base-patch32)
|
| 111 |
+
- [facebook/detr-resnet-101](https://huggingface.co/facebook/detr-resnet-101)
|
| 112 |
+
- [microsoft/conditional-detr-resnet-50](https://huggingface.co/microsoft/conditional-detr-resnet-50)
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
以下は、`torch.compile()`を使用した場合と使用しない場合の推論時間の可視化と、異なるハードウェアとバッチサイズの各モデルに対するパフォーマンス向上の割合です。
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
<div class="flex">
|
| 119 |
+
<div>
|
| 120 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/torch_compile/a100_batch_comp.png" />
|
| 121 |
+
</div>
|
| 122 |
+
<div>
|
| 123 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/torch_compile/v100_batch_comp.png" />
|
| 124 |
+
</div>
|
| 125 |
+
<div>
|
| 126 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/torch_compile/t4_batch_comp.png" />
|
| 127 |
+
</div>
|
| 128 |
+
</div>
|
| 129 |
+
|
| 130 |
+
<div class="flex">
|
| 131 |
+
<div>
|
| 132 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/torch_compile/A100_1_duration.png" />
|
| 133 |
+
</div>
|
| 134 |
+
<div>
|
| 135 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/torch_compile/A100_1_percentage.png" />
|
| 136 |
+
</div>
|
| 137 |
+
</div>
|
| 138 |
+
|
| 139 |
+
|
| 140 |
+
|
| 141 |
+
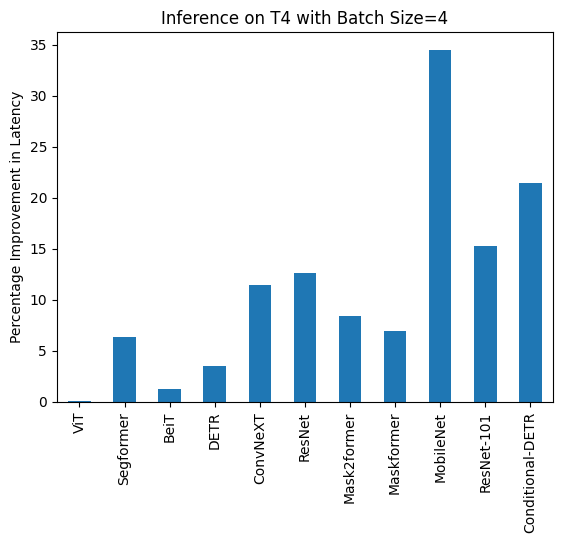
|
| 142 |
+
|
| 143 |
+
下記は、各モデルについて`compile()`を使用した場合と使用しなかった場合の推論時間(ミリ秒単位)です。なお、OwlViTは大きなバッチサイズでの使用時にメモリ不足(OOM)が発生することに注意してください。
|
| 144 |
+
|
| 145 |
+
### A100 (batch size: 1)
|
| 146 |
+
|
| 147 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 148 |
+
|:---:|:---:|:---:|
|
| 149 |
+
| Image Classification/ViT | 9.325 | 7.584 |
|
| 150 |
+
| Image Segmentation/Segformer | 11.759 | 10.500 |
|
| 151 |
+
| Object Detection/OwlViT | 24.978 | 18.420 |
|
| 152 |
+
| Image Classification/BeiT | 11.282 | 8.448 |
|
| 153 |
+
| Object Detection/DETR | 34.619 | 19.040 |
|
| 154 |
+
| Image Classification/ConvNeXT | 10.410 | 10.208 |
|
| 155 |
+
| Image Classification/ResNet | 6.531 | 4.124 |
|
| 156 |
+
| Image Segmentation/Mask2former | 60.188 | 49.117 |
|
| 157 |
+
| Image Segmentation/Maskformer | 75.764 | 59.487 |
|
| 158 |
+
| Image Segmentation/MobileNet | 8.583 | 3.974 |
|
| 159 |
+
| Object Detection/Resnet-101 | 36.276 | 18.197 |
|
| 160 |
+
| Object Detection/Conditional-DETR | 31.219 | 17.993 |
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
### A100 (batch size: 4)
|
| 164 |
+
|
| 165 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 166 |
+
|:---:|:---:|:---:|
|
| 167 |
+
| Image Classification/ViT | 14.832 | 14.499 |
|
| 168 |
+
| Image Segmentation/Segformer | 18.838 | 16.476 |
|
| 169 |
+
| Image Classification/BeiT | 13.205 | 13.048 |
|
| 170 |
+
| Object Detection/DETR | 48.657 | 32.418|
|
| 171 |
+
| Image Classification/ConvNeXT | 22.940 | 21.631 |
|
| 172 |
+
| Image Classification/ResNet | 6.657 | 4.268 |
|
| 173 |
+
| Image Segmentation/Mask2former | 74.277 | 61.781 |
|
| 174 |
+
| Image Segmentation/Maskformer | 180.700 | 159.116 |
|
| 175 |
+
| Image Segmentation/MobileNet | 14.174 | 8.515 |
|
| 176 |
+
| Object Detection/Resnet-101 | 68.101 | 44.998 |
|
| 177 |
+
| Object Detection/Conditional-DETR | 56.470 | 35.552 |
|
| 178 |
+
|
| 179 |
+
### A100 (batch size: 16)
|
| 180 |
+
|
| 181 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 182 |
+
|:---:|:---:|:---:|
|
| 183 |
+
| Image Classification/ViT | 40.944 | 40.010 |
|
| 184 |
+
| Image Segmentation/Segformer | 37.005 | 31.144 |
|
| 185 |
+
| Image Classification/BeiT | 41.854 | 41.048 |
|
| 186 |
+
| Object Detection/DETR | 164.382 | 161.902 |
|
| 187 |
+
| Image Classification/ConvNeXT | 82.258 | 75.561 |
|
| 188 |
+
| Image Classification/ResNet | 7.018 | 5.024 |
|
| 189 |
+
| Image Segmentation/Mask2former | 178.945 | 154.814 |
|
| 190 |
+
| Image Segmentation/Maskformer | 638.570 | 579.826 |
|
| 191 |
+
| Image Segmentation/MobileNet | 51.693 | 30.310 |
|
| 192 |
+
| Object Detection/Resnet-101 | 232.887 | 155.021 |
|
| 193 |
+
| Object Detection/Conditional-DETR | 180.491 | 124.032 |
|
| 194 |
+
|
| 195 |
+
### V100 (batch size: 1)
|
| 196 |
+
|
| 197 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 198 |
+
|:---:|:---:|:---:|
|
| 199 |
+
| Image Classification/ViT | 10.495 | 6.00 |
|
| 200 |
+
| Image Segmentation/Segformer | 13.321 | 5.862 |
|
| 201 |
+
| Object Detection/OwlViT | 25.769 | 22.395 |
|
| 202 |
+
| Image Classification/BeiT | 11.347 | 7.234 |
|
| 203 |
+
| Object Detection/DETR | 33.951 | 19.388 |
|
| 204 |
+
| Image Classification/ConvNeXT | 11.623 | 10.412 |
|
| 205 |
+
| Image Classification/ResNet | 6.484 | 3.820 |
|
| 206 |
+
| Image Segmentation/Mask2former | 64.640 | 49.873 |
|
| 207 |
+
| Image Segmentation/Maskformer | 95.532 | 72.207 |
|
| 208 |
+
| Image Segmentation/MobileNet | 9.217 | 4.753 |
|
| 209 |
+
| Object Detection/Resnet-101 | 52.818 | 28.367 |
|
| 210 |
+
| Object Detection/Conditional-DETR | 39.512 | 20.816 |
|
| 211 |
+
|
| 212 |
+
### V100 (batch size: 4)
|
| 213 |
+
|
| 214 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 215 |
+
|:---:|:---:|:---:|
|
| 216 |
+
| Image Classification/ViT | 15.181 | 14.501 |
|
| 217 |
+
| Image Segmentation/Segformer | 16.787 | 16.188 |
|
| 218 |
+
| Image Classification/BeiT | 15.171 | 14.753 |
|
| 219 |
+
| Object Detection/DETR | 88.529 | 64.195 |
|
| 220 |
+
| Image Classification/ConvNeXT | 29.574 | 27.085 |
|
| 221 |
+
| Image Classification/ResNet | 6.109 | 4.731 |
|
| 222 |
+
| Image Segmentation/Mask2former | 90.402 | 76.926 |
|
| 223 |
+
| Image Segmentation/Maskformer | 234.261 | 205.456 |
|
| 224 |
+
| Image Segmentation/MobileNet | 24.623 | 14.816 |
|
| 225 |
+
| Object Detection/Resnet-101 | 134.672 | 101.304 |
|
| 226 |
+
| Object Detection/Conditional-DETR | 97.464 | 69.739 |
|
| 227 |
+
|
| 228 |
+
### V100 (batch size: 16)
|
| 229 |
+
|
| 230 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 231 |
+
|:---:|:---:|:---:|
|
| 232 |
+
| Image Classification/ViT | 52.209 | 51.633 |
|
| 233 |
+
| Image Segmentation/Segformer | 61.013 | 55.499 |
|
| 234 |
+
| Image Classification/BeiT | 53.938 | 53.581 |
|
| 235 |
+
| Object Detection/DETR | OOM | OOM |
|
| 236 |
+
| Image Classification/ConvNeXT | 109.682 | 100.771 |
|
| 237 |
+
| Image Classification/ResNet | 14.857 | 12.089 |
|
| 238 |
+
| Image Segmentation/Mask2former | 249.605 | 222.801 |
|
| 239 |
+
| Image Segmentation/Maskformer | 831.142 | 743.645 |
|
| 240 |
+
| Image Segmentation/MobileNet | 93.129 | 55.365 |
|
| 241 |
+
| Object Detection/Resnet-101 | 482.425 | 361.843 |
|
| 242 |
+
| Object Detection/Conditional-DETR | 344.661 | 255.298 |
|
| 243 |
+
|
| 244 |
+
### T4 (batch size: 1)
|
| 245 |
+
|
| 246 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 247 |
+
|:---:|:---:|:---:|
|
| 248 |
+
| Image Classification/ViT | 16.520 | 15.786 |
|
| 249 |
+
| Image Segmentation/Segformer | 16.116 | 14.205 |
|
| 250 |
+
| Object Detection/OwlViT | 53.634 | 51.105 |
|
| 251 |
+
| Image Classification/BeiT | 16.464 | 15.710 |
|
| 252 |
+
| Object Detection/DETR | 73.100 | 53.99 |
|
| 253 |
+
| Image Classification/ConvNeXT | 32.932 | 30.845 |
|
| 254 |
+
| Image Classification/ResNet | 6.031 | 4.321 |
|
| 255 |
+
| Image Segmentation/Mask2former | 79.192 | 66.815 |
|
| 256 |
+
| Image Segmentation/Maskformer | 200.026 | 188.268 |
|
| 257 |
+
| Image Segmentation/MobileNet | 18.908 | 11.997 |
|
| 258 |
+
| Object Detection/Resnet-101 | 106.622 | 82.566 |
|
| 259 |
+
| Object Detection/Conditional-DETR | 77.594 | 56.984 |
|
| 260 |
+
|
| 261 |
+
### T4 (batch size: 4)
|
| 262 |
+
|
| 263 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 264 |
+
|:---:|:---:|:---:|
|
| 265 |
+
| Image Classification/ViT | 43.653 | 43.626 |
|
| 266 |
+
| Image Segmentation/Segformer | 45.327 | 42.445 |
|
| 267 |
+
| Image Classification/BeiT | 52.007 | 51.354 |
|
| 268 |
+
| Object Detection/DETR | 277.850 | 268.003 |
|
| 269 |
+
| Image Classification/ConvNeXT | 119.259 | 105.580 |
|
| 270 |
+
| Image Classification/ResNet | 13.039 | 11.388 |
|
| 271 |
+
| Image Segmentation/Mask2former | 201.540 | 184.670 |
|
| 272 |
+
| Image Segmentation/Maskformer | 764.052 | 711.280 |
|
| 273 |
+
| Image Segmentation/MobileNet | 74.289 | 48.677 |
|
| 274 |
+
| Object Detection/Resnet-101 | 421.859 | 357.614 |
|
| 275 |
+
| Object Detection/Conditional-DETR | 289.002 | 226.945 |
|
| 276 |
+
|
| 277 |
+
### T4 (batch size: 16)
|
| 278 |
+
|
| 279 |
+
| **Task/Model** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 280 |
+
|:---:|:---:|:---:|
|
| 281 |
+
| Image Classification/ViT | 163.914 | 160.907 |
|
| 282 |
+
| Image Segmentation/Segformer | 192.412 | 163.620 |
|
| 283 |
+
| Image Classification/BeiT | 188.978 | 187.976 |
|
| 284 |
+
| Object Detection/DETR | OOM | OOM |
|
| 285 |
+
| Image Classification/ConvNeXT | 422.886 | 388.078 |
|
| 286 |
+
| Image Classification/ResNet | 44.114 | 37.604 |
|
| 287 |
+
| Image Segmentation/Mask2former | 756.337 | 695.291 |
|
| 288 |
+
| Image Segmentation/Maskformer | 2842.940 | 2656.88 |
|
| 289 |
+
| Image Segmentation/MobileNet | 299.003 | 201.942 |
|
| 290 |
+
| Object Detection/Resnet-101 | 1619.505 | 1262.758 |
|
| 291 |
+
| Object Detection/Conditional-DETR | 1137.513 | 897.390|
|
| 292 |
+
|
| 293 |
+
## PyTorch Nightly
|
| 294 |
+
また、PyTorchのナイトリーバージョン(2.1.0dev)でのベンチマークを行い、コンパイルされていないモデルとコンパイル済みモデルの両方でレイテンシーの向上を観察しました。ホイールは[こちら](https://download.pytorch.org/whl/nightly/cu118)から入手できます。
|
| 295 |
+
|
| 296 |
+
|
| 297 |
+
### A100
|
| 298 |
+
|
| 299 |
+
| **Task/Model** | **Batch Size** | **torch 2.0 - no compile** | **torch 2.0 -<br> compile** |
|
| 300 |
+
|:---:|:---:|:---:|:---:|
|
| 301 |
+
| Image Classification/BeiT | Unbatched | 12.462 | 6.954 |
|
| 302 |
+
| Image Classification/BeiT | 4 | 14.109 | 12.851 |
|
| 303 |
+
| Image Classification/BeiT | 16 | 42.179 | 42.147 |
|
| 304 |
+
| Object Detection/DETR | Unbatched | 30.484 | 15.221 |
|
| 305 |
+
| Object Detection/DETR | 4 | 46.816 | 30.942 |
|
| 306 |
+
| Object Detection/DETR | 16 | 163.749 | 163.706 |
|
| 307 |
+
|
| 308 |
+
### T4
|
| 309 |
+
|
| 310 |
+
| **Task/Model** | **Batch Size** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 311 |
+
|:---:|:---:|:---:|:---:|
|
| 312 |
+
| Image Classification/BeiT | Unbatched | 14.408 | 14.052 |
|
| 313 |
+
| Image Classification/BeiT | 4 | 47.381 | 46.604 |
|
| 314 |
+
| Image Classification/BeiT | 16 | 42.179 | 42.147 |
|
| 315 |
+
| Object Detection/DETR | Unbatched | 68.382 | 53.481 |
|
| 316 |
+
| Object Detection/DETR | 4 | 269.615 | 204.785 |
|
| 317 |
+
| Object Detection/DETR | 16 | OOM | OOM |
|
| 318 |
+
|
| 319 |
+
### V100
|
| 320 |
+
|
| 321 |
+
| **Task/Model** | **Batch Size** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 322 |
+
|:---:|:---:|:---:|:---:|
|
| 323 |
+
| Image Classification/BeiT | Unbatched | 13.477 | 7.926 |
|
| 324 |
+
| Image Classification/BeiT | 4 | 15.103 | 14.378 |
|
| 325 |
+
| Image Classification/BeiT | 16 | 52.517 | 51.691 |
|
| 326 |
+
| Object Detection/DETR | Unbatched | 28.706 | 19.077 |
|
| 327 |
+
| Object Detection/DETR | 4 | 88.402 | 62.949|
|
| 328 |
+
| Object Detection/DETR | 16 | OOM | OOM |
|
| 329 |
+
|
| 330 |
+
|
| 331 |
+
## Reduce Overhead
|
| 332 |
+
NightlyビルドでA100およびT4向けの `reduce-overhead` コンパイルモードをベンチマークしました。
|
| 333 |
+
|
| 334 |
+
### A100
|
| 335 |
+
|
| 336 |
+
| **Task/Model** | **Batch Size** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 337 |
+
|:---:|:---:|:---:|:---:|
|
| 338 |
+
| Image Classification/ConvNeXT | Unbatched | 11.758 | 7.335 |
|
| 339 |
+
| Image Classification/ConvNeXT | 4 | 23.171 | 21.490 |
|
| 340 |
+
| Image Classification/ResNet | Unbatched | 7.435 | 3.801 |
|
| 341 |
+
| Image Classification/ResNet | 4 | 7.261 | 2.187 |
|
| 342 |
+
| Object Detection/Conditional-DETR | Unbatched | 32.823 | 11.627 |
|
| 343 |
+
| Object Detection/Conditional-DETR | 4 | 50.622 | 33.831 |
|
| 344 |
+
| Image Segmentation/MobileNet | Unbatched | 9.869 | 4.244 |
|
| 345 |
+
| Image Segmentation/MobileNet | 4 | 14.385 | 7.946 |
|
| 346 |
+
|
| 347 |
+
|
| 348 |
+
### T4
|
| 349 |
+
|
| 350 |
+
| **Task/Model** | **Batch Size** | **torch 2.0 - <br>no compile** | **torch 2.0 - <br>compile** |
|
| 351 |
+
|:---:|:---:|:---:|:---:|
|
| 352 |
+
| Image Classification/ConvNeXT | Unbatched | 32.137 | 31.84 |
|
| 353 |
+
| Image Classification/ConvNeXT | 4 | 120.944 | 110.209 |
|
| 354 |
+
| Image Classification/ResNet | Unbatched | 9.761 | 7.698 |
|
| 355 |
+
| Image Classification/ResNet | 4 | 15.215 | 13.871 |
|
| 356 |
+
| Object Detection/Conditional-DETR | Unbatched | 72.150 | 57.660 |
|
| 357 |
+
| Object Detection/Conditional-DETR | 4 | 301.494 | 247.543 |
|
| 358 |
+
| Image Segmentation/MobileNet | Unbatched | 22.266 | 19.339 |
|
| 359 |
+
| Image Segmentation/MobileNet | 4 | 78.311 | 50.983 |
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_cpu.md
ADDED
|
@@ -0,0 +1,67 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Efficient Training on CPU
|
| 17 |
+
|
| 18 |
+
このガイドは、CPU上で大規模なモデルを効率的にトレーニングする方法に焦点を当てています。
|
| 19 |
+
|
| 20 |
+
## Mixed precision with IPEX
|
| 21 |
+
|
| 22 |
+
IPEXはAVX-512以上のCPUに最適化されており、AVX2のみのCPUでも機能的に動作します。そのため、AVX-512以上のIntel CPU世代ではパフォーマンスの向上が期待されますが、AVX2のみのCPU(例:AMD CPUまたは古いIntel CPU)ではIPEXの下でより良いパフォーマンスが得られるかもしれませんが、保証されません。IPEXは、Float32とBFloat16の両方でCPUトレーニングのパフォーマンスを最適化します。以下のセクションでは、BFloat16の使用に重点を置いて説明します。
|
| 23 |
+
|
| 24 |
+
低精度データ型であるBFloat16は、AVX512命令セットを備えた第3世代Xeon® Scalable Processors(別名Cooper Lake)でネイティブサポートされており、さらに高性能なIntel® Advanced Matrix Extensions(Intel® AMX)命令セットを備えた次世代のIntel® Xeon® Scalable Processorsでもサポートされます。CPUバックエンド用の自動混合精度がPyTorch-1.10以降で有効になっています。同時に、Intel® Extension for PyTorchでのCPU用BFloat16の自動混合精度サポートと、オペレーターのBFloat16最適化のサポートが大幅に向上し、一部がPyTorchのメインブランチにアップストリームされています。ユーザーはIPEX Auto Mixed Precisionを使用することで、より優れたパフォーマンスとユーザーエクスペリエンスを得ることができます。
|
| 25 |
+
|
| 26 |
+
詳細な情報については、[Auto Mixed Precision](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/amp.html)を確認してください。
|
| 27 |
+
|
| 28 |
+
### IPEX installation:
|
| 29 |
+
|
| 30 |
+
IPEXのリリースはPyTorchに従っており、pipを使用してインストールできます:
|
| 31 |
+
|
| 32 |
+
| PyTorch Version | IPEX version |
|
| 33 |
+
| :---------------: | :----------: |
|
| 34 |
+
| 1.13 | 1.13.0+cpu |
|
| 35 |
+
| 1.12 | 1.12.300+cpu |
|
| 36 |
+
| 1.11 | 1.11.200+cpu |
|
| 37 |
+
| 1.10 | 1.10.100+cpu |
|
| 38 |
+
|
| 39 |
+
```bash
|
| 40 |
+
pip install intel_extension_for_pytorch==<version_name> -f https://developer.intel.com/ipex-whl-stable-cpu
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
[IPEXのインストール方法](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html)について、さらなるアプローチを確認してください。
|
| 44 |
+
|
| 45 |
+
### Trainerでの使用方法
|
| 46 |
+
TrainerでIPEXの自動混合精度を有効にするには、ユーザーはトレーニングコマンド引数に `use_ipex`、`bf16`、および `no_cuda` を追加する必要があります。
|
| 47 |
+
|
| 48 |
+
[Transformersの質問応答](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)のユースケースを例に説明します。
|
| 49 |
+
|
| 50 |
+
- CPU上でBF16自動混合精度を使用してIPEXでトレーニングを行う場合:
|
| 51 |
+
<pre> python run_qa.py \
|
| 52 |
+
--model_name_or_path google-bert/bert-base-uncased \
|
| 53 |
+
--dataset_name squad \
|
| 54 |
+
--do_train \
|
| 55 |
+
--do_eval \
|
| 56 |
+
--per_device_train_batch_size 12 \
|
| 57 |
+
--learning_rate 3e-5 \
|
| 58 |
+
--num_train_epochs 2 \
|
| 59 |
+
--max_seq_length 384 \
|
| 60 |
+
--doc_stride 128 \
|
| 61 |
+
--output_dir /tmp/debug_squad/ \
|
| 62 |
+
<b>--use_ipex \</b>
|
| 63 |
+
<b>--bf16 --no_cuda</b></pre>
|
| 64 |
+
|
| 65 |
+
### Practice example
|
| 66 |
+
|
| 67 |
+
Blog: [Accelerating PyTorch Transformers with Intel Sapphire Rapids](https://huggingface.co/blog/intel-sapphire-rapids)
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_cpu_many.md
ADDED
|
@@ -0,0 +1,151 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
# Efficient Training on Multiple CPUs
|
| 18 |
+
|
| 19 |
+
1つのCPUでのトレーニングが遅すぎる場合、複数のCPUを使用できます。このガイドは、PyTorchベースのDDPを使用した分散CPUトレーニングに焦点を当てています。
|
| 20 |
+
|
| 21 |
+
## Intel® oneCCL Bindings for PyTorch
|
| 22 |
+
|
| 23 |
+
[Intel® oneCCL](https://github.com/oneapi-src/oneCCL)(集合通信ライブラリ)は、allreduce、allgather、alltoallなどの収集通信を実装した効率的な分散ディープラーニングトレーニング用のライブラリです。oneCCLの詳細については、[oneCCLドキュメント](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)と[oneCCL仕様](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)を参照してください。
|
| 24 |
+
|
| 25 |
+
モジュール`oneccl_bindings_for_pytorch`(バージョン1.12以前は`torch_ccl`)は、PyTorch C10D ProcessGroup APIを実装し、外部のProcessGroupとして動的にロードでき、現在はLinuxプラットフォームでのみ動作します。
|
| 26 |
+
|
| 27 |
+
[torch-ccl](https://github.com/intel/torch-ccl)の詳細情報を確認してください。
|
| 28 |
+
|
| 29 |
+
### Intel® oneCCL Bindings for PyTorch installation:
|
| 30 |
+
|
| 31 |
+
Wheelファイルは、以下のPythonバージョン用に利用可能です:
|
| 32 |
+
|
| 33 |
+
| Extension Version | Python 3.6 | Python 3.7 | Python 3.8 | Python 3.9 | Python 3.10 |
|
| 34 |
+
| :---------------: | :--------: | :--------: | :--------: | :--------: | :---------: |
|
| 35 |
+
| 1.13.0 | | √ | √ | √ | √ |
|
| 36 |
+
| 1.12.100 | | √ | √ | √ | √ |
|
| 37 |
+
| 1.12.0 | | √ | √ | √ | √ |
|
| 38 |
+
| 1.11.0 | | √ | √ | √ | √ |
|
| 39 |
+
| 1.10.0 | √ | √ | √ | √ | |
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install oneccl_bind_pt=={pytorch_version} -f https://developer.intel.com/ipex-whl-stable-cpu
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
where `{pytorch_version}` should be your PyTorch version, for instance 1.13.0.
|
| 46 |
+
Check more approaches for [oneccl_bind_pt installation](https://github.com/intel/torch-ccl).
|
| 47 |
+
Versions of oneCCL and PyTorch must match.
|
| 48 |
+
|
| 49 |
+
<Tip warning={true}>
|
| 50 |
+
|
| 51 |
+
oneccl_bindings_for_pytorch 1.12.0 prebuilt wheel does not work with PyTorch 1.12.1 (it is for PyTorch 1.12.0)
|
| 52 |
+
PyTorch 1.12.1 should work with oneccl_bindings_for_pytorch 1.12.100
|
| 53 |
+
|
| 54 |
+
</Tip>
|
| 55 |
+
|
| 56 |
+
`{pytorch_version}` は、あなたのPyTorchのバージョン(例:1.13.0)に置き換える必要があります。重要なのは、oneCCLとPyTorchのバージョンが一致していることです。[oneccl_bind_ptのインストール](https://github.com/intel/torch-ccl)に関するさらなるアプローチを確認できます。
|
| 57 |
+
|
| 58 |
+
<Tip warning={true}>
|
| 59 |
+
|
| 60 |
+
`oneccl_bindings_for_pytorch`の1.12.0プリビルトホイールはPyTorch 1.12.1と互換性がありません(これはPyTorch 1.12.0用です)。PyTorch 1.12.1を使用する場合は、`oneccl_bindings_for_pytorch`バージョン1.12.100を使用する必要があります。
|
| 61 |
+
|
| 62 |
+
</Tip>
|
| 63 |
+
|
| 64 |
+
## Intel® MPI library
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
この基準ベースのMPI実装を使用して、Intel®アーキテクチャ上で柔軟で効率的、スケーラブルなクラスタメッセージングを提供します。このコンポーネントは、Intel® oneAPI HPC Toolkitの一部です。
|
| 68 |
+
|
| 69 |
+
oneccl_bindings_for_pytorchはMPIツールセットと一緒にインストールされます。使用する前に環境をソース化する必要があります。
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
for Intel® oneCCL >= 1.12.0
|
| 73 |
+
```bash
|
| 74 |
+
oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
|
| 75 |
+
source $oneccl_bindings_for_pytorch_path/env/setvars.sh
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
for Intel® oneCCL whose version < 1.12.0
|
| 79 |
+
```bash
|
| 80 |
+
torch_ccl_path=$(python -c "import torch; import torch_ccl; import os; print(os.path.abspath(os.path.dirname(torch_ccl.__file__)))")
|
| 81 |
+
source $torch_ccl_path/env/setvars.sh
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
#### IPEX installation:
|
| 85 |
+
|
| 86 |
+
IPEXは、Float32およびBFloat16の両方でCPUトレーニングのパフォーマンス最適化を提供します。詳細は[こちらのシングルCPUセクション](./perf_train_cpu)をご参照ください。
|
| 87 |
+
|
| 88 |
+
以下の「トレーナーでの使用」は��Intel® MPIライブラリでmpirunを使用する例を示しています。
|
| 89 |
+
|
| 90 |
+
## Usage in Trainer
|
| 91 |
+
トレーナーでのマルチCPU分散トレーニングを有効にするために、ユーザーはコマンド引数に **`--ddp_backend ccl`** を追加する必要があります。
|
| 92 |
+
|
| 93 |
+
例を見てみましょう。[質問応答の例](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)
|
| 94 |
+
|
| 95 |
+
以下のコマンドは、1つのXeonノードで2つのプロセスを使用してトレーニングを有効にします。1つのプロセスが1つのソケットで実行されます。OMP_NUM_THREADS/CCL_WORKER_COUNT変数は、最適なパフォーマンスを調整するために調整できます。
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
```shell script
|
| 99 |
+
export CCL_WORKER_COUNT=1
|
| 100 |
+
export MASTER_ADDR=127.0.0.1
|
| 101 |
+
mpirun -n 2 -genv OMP_NUM_THREADS=23 \
|
| 102 |
+
python3 run_qa.py \
|
| 103 |
+
--model_name_or_path google-bert/bert-large-uncased \
|
| 104 |
+
--dataset_name squad \
|
| 105 |
+
--do_train \
|
| 106 |
+
--do_eval \
|
| 107 |
+
--per_device_train_batch_size 12 \
|
| 108 |
+
--learning_rate 3e-5 \
|
| 109 |
+
--num_train_epochs 2 \
|
| 110 |
+
--max_seq_length 384 \
|
| 111 |
+
--doc_stride 128 \
|
| 112 |
+
--output_dir /tmp/debug_squad/ \
|
| 113 |
+
--no_cuda \
|
| 114 |
+
--ddp_backend ccl \
|
| 115 |
+
--use_ipex
|
| 116 |
+
```
|
| 117 |
+
|
| 118 |
+
以下のコマンドは、2つのXeonプロセッサ(node0とnode1、node0をメインプロセスとして使用)で合計4つのプロセスを使用してトレーニングを有効にします。ppn(ノードごとのプロセス数)は2に設定され、1つのソケットごとに1つのプロセスが実行されます。最適なパフォーマンスを得るために、OMP_NUM_THREADS/CCL_WORKER_COUNT変数を調整できます。
|
| 119 |
+
|
| 120 |
+
node0では、各ノードのIPアドレスを含む構成ファイルを作成し、その構成ファイルのパスを引数として渡す必要があります。
|
| 121 |
+
|
| 122 |
+
```shell script
|
| 123 |
+
cat hostfile
|
| 124 |
+
xxx.xxx.xxx.xxx #node0 ip
|
| 125 |
+
xxx.xxx.xxx.xxx #node1 ip
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
ノード0で次のコマンドを実行すると、ノード0とノード1で**4DDP**がBF16自動混合精度で有効になります。
|
| 129 |
+
|
| 130 |
+
|
| 131 |
+
```shell script
|
| 132 |
+
export CCL_WORKER_COUNT=1
|
| 133 |
+
export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
|
| 134 |
+
mpirun -f hostfile -n 4 -ppn 2 \
|
| 135 |
+
-genv OMP_NUM_THREADS=23 \
|
| 136 |
+
python3 run_qa.py \
|
| 137 |
+
--model_name_or_path google-bert/bert-large-uncased \
|
| 138 |
+
--dataset_name squad \
|
| 139 |
+
--do_train \
|
| 140 |
+
--do_eval \
|
| 141 |
+
--per_device_train_batch_size 12 \
|
| 142 |
+
--learning_rate 3e-5 \
|
| 143 |
+
--num_train_epochs 2 \
|
| 144 |
+
--max_seq_length 384 \
|
| 145 |
+
--doc_stride 128 \
|
| 146 |
+
--output_dir /tmp/debug_squad/ \
|
| 147 |
+
--no_cuda \
|
| 148 |
+
--ddp_backend ccl \
|
| 149 |
+
--use_ipex \
|
| 150 |
+
--bf16
|
| 151 |
+
```
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_gpu_many.md
ADDED
|
@@ -0,0 +1,529 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Efficient Training on Multiple GPUs
|
| 17 |
+
|
| 18 |
+
単一のGPUでのトレーニングが遅すぎる場合や、モデルの重みが単一のGPUのメモリに収まらない場合、複数のGPUを使用したセットアップが必要となります。単一のGPUから複数のGPUへの切り替えには、ワークロードを分散するためのある種の並列処理が必要です。データ、テンソル、またはパイプラインの並列処理など、さまざまな並列処理技術があります。ただし、すべてに適した一つの解決策は存在せず、最適な設定は使用するハードウェアに依存します。この記事は、おそらく他のフレームワークにも適用される主要な概念に焦点を当てつつ、PyTorchベースの実装に焦点を当てています。
|
| 19 |
+
|
| 20 |
+
<Tip>
|
| 21 |
+
|
| 22 |
+
**注意**: [単一GPUセクション](perf_train_gpu_one) で紹介された多くの戦略(混合精度トレーニングや勾配蓄積など)は一般的であり、モデルのトレーニングに一般的に適用されます。したがって、マルチGPUやCPUトレーニングなどの次のセクションに入る前に、それを確認してください。
|
| 23 |
+
|
| 24 |
+
</Tip>
|
| 25 |
+
|
| 26 |
+
まず、さまざまな1D並列処理技術とその利点および欠点について詳しく説明し、それらを2Dおよび3D並列処理に組み合わせてさらに高速なトレーニングを実現し、より大きなモデルをサポートする方法を検討します。さまざまな他の強力な代替手法も紹介されます。
|
| 27 |
+
|
| 28 |
+
## Concepts
|
| 29 |
+
|
| 30 |
+
以下は、この文書で後で詳しく説明される主要な概念の簡単な説明です。
|
| 31 |
+
|
| 32 |
+
1. **DataParallel (DP)** - 同じセットアップが複数回複製され、各セットアップにデータのスライスが供給されます。処理は並行して行われ、各セットアップはトレーニングステップの最後に同期されます。
|
| 33 |
+
2. **TensorParallel (TP)** - 各テンソルは複数のチャンクに分割され、単一のGPUにテンソル全体が存在するのではなく、テンソルの各シャードが指定されたGPUに存在します。処理中に、各シャードは別々に並行して処理され、異なるGPUで同期され、ステップの最後に結果が同期されます。これは水平並列処理と呼ばれるもので、分割は水平レベルで行われます。
|
| 34 |
+
3. **PipelineParallel (PP)** - モデルは垂直(レイヤーレベル)に複数のGPUに分割され、モデルの単一または複数のレイヤーが単一のGPUに配置されます。各GPUはパイプラインの異なるステージを並行して処理し、バッチの小さなチャンクで作業します。
|
| 35 |
+
4. **Zero Redundancy Optimizer (ZeRO)** - TPといくらか似たようなテンソルのシャーディングを実行しますが、前向きまたは後向きの計算のためにテンソル全体が再構築されるため、モデルを変更する必要はありません。また、GPUメモリが制限されている場合に補償するためのさまざまなオフロード技術をサポートします。
|
| 36 |
+
5. **Sharded DDP** - Sharded DDPは、さまざまなZeRO実装で使用される基本的なZeROコンセプトの別名です。
|
| 37 |
+
|
| 38 |
+
各コンセプトの詳細に深入りする前に、大規模なインフラストラクチャで大規模なモデルをトレーニングする際の大まかな決定プロセスを見てみましょう。
|
| 39 |
+
|
| 40 |
+
## Scalability Strategy
|
| 41 |
+
|
| 42 |
+
**⇨ シングルノード / マルチGPU**
|
| 43 |
+
* モデルが単一のGPUに収まる場合:
|
| 44 |
+
|
| 45 |
+
1. DDP - 分散データ並列
|
| 46 |
+
2. ZeRO - 状況と使用される構成に応じて速いかどうかが異なります
|
| 47 |
+
|
| 48 |
+
* モデルが単一のGPUに収まらない場合:
|
| 49 |
+
|
| 50 |
+
1. PP
|
| 51 |
+
2. ZeRO
|
| 52 |
+
3. TP
|
| 53 |
+
|
| 54 |
+
非常に高速なノード内接続(NVLINKまたはNVSwitchなど)があれば、これらの3つはほぼ同じ速度になるはずで、これらがない場合、PPはTPまたはZeROよりも速くなります。TPの程度も差を生じるかもしれません。特定のセットアップでの勝者を見つけるために実験することが最善です。
|
| 55 |
+
|
| 56 |
+
TPはほとんどの場合、単一ノード内で使用されます。つまり、TPサイズ <= ノードごとのGPU数です。
|
| 57 |
+
|
| 58 |
+
* 最大のレイヤーが単一のGPUに収まらない場合:
|
| 59 |
+
|
| 60 |
+
1. ZeROを使用しない場合 - TPを使用する必要があります。PP単独では収まらないでしょう。
|
| 61 |
+
2. ZeROを使用する場合 - "シングルGPU"のエントリと同じものを参照してください
|
| 62 |
+
|
| 63 |
+
**⇨ マルチノード / マルチGPU**
|
| 64 |
+
|
| 65 |
+
* ノード間の高速接続がある場合:
|
| 66 |
+
|
| 67 |
+
1. ZeRO - モデルへのほとんどの変更が不要です
|
| 68 |
+
2. PP+TP+DP - 通信が少なく、モデルへの大規模な変更が必要です
|
| 69 |
+
|
| 70 |
+
* ノード間の接続が遅く、GPUメモリがまだ不足している場合:
|
| 71 |
+
|
| 72 |
+
1. DP+PP+TP+ZeRO-1
|
| 73 |
+
|
| 74 |
+
## Data Parallelism
|
| 75 |
+
|
| 76 |
+
2つのGPUを持つほとんどのユーザーは、`DataParallel`(DP)と`DistributedDataParallel`(DDP)によって提供されるトレーニング速度の向上をすでに享受しています。これらはほぼ自明に使用できるPyTorchの組み込み機能です。一般的に、すべてのモデルで動作するDDPを使用することをお勧めします。DPは一部のモデルで失敗する可能性があるためです。[PyTorchのドキュメンテーション](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html)自体もDDPの使用を推奨しています。
|
| 77 |
+
|
| 78 |
+
### DP vs DDP
|
| 79 |
+
|
| 80 |
+
`DistributedDataParallel`(DDP)は通常、`DataParallel`(DP)よりも高速ですが、常にそうとは限りません:
|
| 81 |
+
* DPはPythonスレッドベースですが、DDPはマルチプロセスベースです。そのため、GIL(Global Interpreter Lock)などのPythonスレッドの制約がないためです。
|
| 82 |
+
* 一方、GPUカード間の遅い相互接続性は、DDPの場合に実際には遅い結果をもたらす可能性があります。
|
| 83 |
+
|
| 84 |
+
以下は、2つのモード間のGPU間通信の主な違いです:
|
| 85 |
+
|
| 86 |
+
[DDP](https://pytorch.org/docs/master/notes/ddp.html):
|
| 87 |
+
|
| 88 |
+
- 開始時、メインプロセスはモデルをGPU 0から他のGPUに複製します。
|
| 89 |
+
- それから各バッチごとに:
|
| 90 |
+
1. 各GPUは各自のミニバッチのデータを直接消費します。
|
| 91 |
+
2. `backward`中、ローカル勾配が準備できると、それらはすべてのプロセスで平均化されます。
|
| 92 |
+
|
| 93 |
+
[DP](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html):
|
| 94 |
+
|
| 95 |
+
各バッチごとに:
|
| 96 |
+
1. GPU 0はデータバッチを読み取り、それから各GPUにミニバッチを送信します。
|
| 97 |
+
2. GPU 0から各GPUに最新のモデルを複製します。
|
| 98 |
+
3. `forward`を実行し、各GPUからGPU 0に出力を送信し、損失を計算します。
|
| 99 |
+
4. GPU 0からすべてのGPUに損失を分散し、`backward`を実行します。
|
| 100 |
+
5. 各GPUからGPU 0に勾配を送信し、それらを平均化します。
|
| 101 |
+
|
| 102 |
+
DDPはバッチごとに行う通信は勾配の送信のみであり、一方、DPはバッチごとに5つの異なるデータ交換を行います。
|
| 103 |
+
|
| 104 |
+
DPはプロセス内でデータをPythonスレッドを介してコピーしますが、DDPは[torch.distributed](https://pytorch.org/docs/master/distributed.html)を介してデータをコピーします。
|
| 105 |
+
|
| 106 |
+
DPではGPU 0は他のGPUよりもはるかに多くの作業を行うため、GPUの未使用率が高くなります。
|
| 107 |
+
|
| 108 |
+
DDPは複数のマシン間で使用できますが、DPの場合はそうではありません。
|
| 109 |
+
|
| 110 |
+
DPとDDPの他にも違いがありますが、この議論には関係ありません。
|
| 111 |
+
|
| 112 |
+
これら2つのモードを深く理解したい場合、この[記事](https://www.telesens.co/2019/04/04/distributed-data-parallel-training-using-pytorch-on-aws/)を強くお勧めします。素晴らしいダイアグラムを含み、さまざまなハードウェアでの複数のベンチマークとプロファイラの出力を示し、知っておく必要があるすべての微妙なニュアンスを説明しています。
|
| 113 |
+
|
| 114 |
+
実際のベンチマークを見てみましょう:
|
| 115 |
+
|
| 116 |
+
| Type | NVlink | Time |
|
| 117 |
+
| :----- | ----- | ---: |
|
| 118 |
+
| 2:DP | Y | 110s |
|
| 119 |
+
| 2:DDP | Y | 101s |
|
| 120 |
+
| 2:DDP | N | 131s |
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
解析:
|
| 124 |
+
|
| 125 |
+
ここで、DPはNVlinkを使用したDDPに比べて約10%遅く、NVlinkを使用しないDDPに比べて約15%高速であることが示されています。
|
| 126 |
+
|
| 127 |
+
実際の違いは、各GPUが他のGPUと同期する必要があるデータの量に依存します。同期するデータが多いほど、遅いリンクが合計の実行時間を遅くする可能性が高くなります。
|
| 128 |
+
|
| 129 |
+
以下は完全なベンチマークコードと出力です:
|
| 130 |
+
|
| 131 |
+
`NCCL_P2P_DISABLE=1`を使用して、対応するベンチマークでNVLink機能を無効にしました。
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
```bash
|
| 135 |
+
|
| 136 |
+
# DP
|
| 137 |
+
rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
|
| 138 |
+
python examples/pytorch/language-modeling/run_clm.py \
|
| 139 |
+
--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
|
| 140 |
+
--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
|
| 141 |
+
|
| 142 |
+
{'train_runtime': 110.5948, 'train_samples_per_second': 1.808, 'epoch': 0.69}
|
| 143 |
+
|
| 144 |
+
# DDP w/ NVlink
|
| 145 |
+
rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
|
| 146 |
+
torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
|
| 147 |
+
--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
|
| 148 |
+
--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
|
| 149 |
+
|
| 150 |
+
{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
|
| 151 |
+
|
| 152 |
+
# DDP w/o NVlink
|
| 153 |
+
rm -r /tmp/test-clm; NCCL_P2P_DISABLE=1 CUDA_VISIBLE_DEVICES=0,1 \
|
| 154 |
+
torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
|
| 155 |
+
--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
|
| 156 |
+
--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
|
| 157 |
+
|
| 158 |
+
{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
|
| 159 |
+
```
|
| 160 |
+
|
| 161 |
+
ハードウェア: 2x TITAN RTX、各24GB + 2つのNVLink(`nvidia-smi topo -m`で `NV2`)
|
| 162 |
+
|
| 163 |
+
ソフトウェア: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
|
| 164 |
+
|
| 165 |
+
## ZeRO Data Parallelism
|
| 166 |
+
|
| 167 |
+
ZeROパワードデータ並列処理(ZeRO-DP)は、次の[ブログ投稿](https://www.microsoft.com/en-us/research/blog/zero-deepspeed-new-system-optimizations-enable-training-models-with-over-100-billion-parameters/)のダイアグラムで説明されています。
|
| 168 |
+
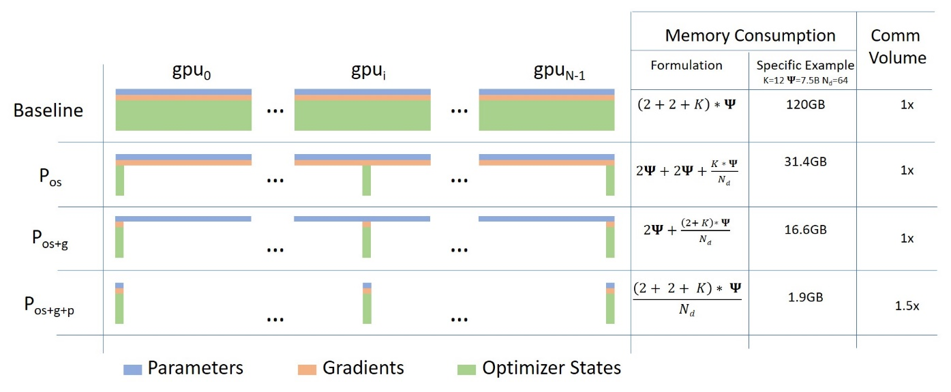
|
| 169 |
+
|
| 170 |
+
これは理解が難しいかもしれませんが、実際にはこの概念は非常にシンプルです。これは通常の`DataParallel`(DP)ですが、完全なモデルパラメータ、勾配、およびオプティマイザの状態を複製する代わりに、各GPUはそれぞれのスライスのみを保存します。そして、実行時に、特定のレイヤーに必要な完全なレイヤーパラメータが必要な場合、すべてのGPUが同期して、お互いに不足している部分を提供します。それがすべてです。
|
| 171 |
+
|
| 172 |
+
3つのレイヤーからなる単純なモデルを考えてみましょう。各レイヤーには3つのパラメータがあります:
|
| 173 |
+
|
| 174 |
+
|
| 175 |
+
```
|
| 176 |
+
La | Lb | Lc
|
| 177 |
+
---|----|---
|
| 178 |
+
a0 | b0 | c0
|
| 179 |
+
a1 | b1 | c1
|
| 180 |
+
a2 | b2 | c2
|
| 181 |
+
```
|
| 182 |
+
|
| 183 |
+
レイヤーLaには、重みa0、a1、およびa2があります。
|
| 184 |
+
|
| 185 |
+
3つのGPUがある場合、Sharded DDP(= Zero-DP)はモデルを3つのGPUに次のように分割します:
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
```
|
| 189 |
+
GPU0:
|
| 190 |
+
La | Lb | Lc
|
| 191 |
+
---|----|---
|
| 192 |
+
a0 | b0 | c0
|
| 193 |
+
|
| 194 |
+
GPU1:
|
| 195 |
+
La | Lb | Lc
|
| 196 |
+
---|----|---
|
| 197 |
+
a1 | b1 | c1
|
| 198 |
+
|
| 199 |
+
GPU2:
|
| 200 |
+
La | Lb | Lc
|
| 201 |
+
---|----|---
|
| 202 |
+
a2 | b2 | c2
|
| 203 |
+
```
|
| 204 |
+
|
| 205 |
+
これは、典型的なディープニューラルネットワーク(DNN)のダイアグラムを想像すると、テンソル並列処理と同様の水平スライスであるようなものです。垂直スライスは、異なるGPUに完全な層グループを配置する方法です。しかし、これは単なる出発点に過ぎません。
|
| 206 |
+
|
| 207 |
+
これから、各GPUは通常のデータ並列処理(DP)と同様に、通常のミニバッチを受け取ります:
|
| 208 |
+
|
| 209 |
+
```
|
| 210 |
+
x0 => GPU0
|
| 211 |
+
x1 => GPU1
|
| 212 |
+
x2 => GPU2
|
| 213 |
+
```
|
| 214 |
+
|
| 215 |
+
最初に、入力データはレイヤーLaに適用されます。
|
| 216 |
+
|
| 217 |
+
GPU0に焦点を当てましょう:x0は、その前向きパスを実行するためにa0、a1、a2のパラメータが必要ですが、GPU0にはa0しかありません。GPU1からa1を、GPU2からa2を受け取り、モデルの各部分をまとめます。
|
| 218 |
+
|
| 219 |
+
同様に、GPU1はミニバッチx1を受け取り、a1しか持っていませんが、a0とa2のパラメータが必要です。これらはGPU0とGPU2から取得します。
|
| 220 |
+
|
| 221 |
+
GPU2もx2を受け取ります。a0とa1はGPU0とGPU1から受け取り、a2とともに完全なテンソルを再構築します。
|
| 222 |
+
|
| 223 |
+
3つのGPUは完全なテンソルを再構築し、前向き計算が行われます。
|
| 224 |
+
|
| 225 |
+
計算が完了すると、不要になったデータは削除されます。計算中だけ使用され、再構築は事前にフェッチを使用して効率的に行われます。
|
| 226 |
+
|
| 227 |
+
そして、このプロセス全体がレイヤーLb、次に前向きでLc、そして逆方向でLc -> Lb -> Laに対して繰り返されます。
|
| 228 |
+
|
| 229 |
+
私にとって、これは効率的なグループでの重みの分散戦略のように聞こえます:
|
| 230 |
+
|
| 231 |
+
1. 人Aはテントを持っています。
|
| 232 |
+
2. 人Bはストーブを持っています。
|
| 233 |
+
3. 人Cは斧を持っています。
|
| 234 |
+
|
| 235 |
+
今、彼らは毎晩持っているものを共有し、他の人から持っていないものをもらい、朝には割り当てられたタイプのギアを詰めて旅を続けます。これがSharded DDP / Zero DPです。
|
| 236 |
+
|
| 237 |
+
この戦略を、各人が独自のテント、ストーブ、斧を持って運ばなければならないシンプルな戦略と比較してみてください。これがPyTorchのDataParallel(DPおよびDDP)です。
|
| 238 |
+
|
| 239 |
+
このトピックの文献を読む際に��以下の類義語に出会うかもしれません:Sharded、Partitioned。
|
| 240 |
+
|
| 241 |
+
ZeROがモデルの重みを分割する方法に注意を払うと、これはテンソルパラレリズムと非常に似ているように見えます。これは後で議論される垂直モデルパラレリズムとは異なり、各レイヤーの重みをパーティション/シャーディングします。
|
| 242 |
+
|
| 243 |
+
Implementations:
|
| 244 |
+
|
| 245 |
+
- [DeepSpeed](https://www.deepspeed.ai/tutorials/zero/) ZeRO-DP stages 1+2+3
|
| 246 |
+
- [`transformers` integration](main_classes/trainer#trainer-integrations)
|
| 247 |
+
|
| 248 |
+
|
| 249 |
+
## Naive Model Parallelism (Vertical) and Pipeline Parallelism
|
| 250 |
+
|
| 251 |
+
ナイーブモデルパラレリズム(MP)は、モデルの層を複数のGPUに分散させる方法です。このメカニズムは比較的単純で、希望する層を`.to()`メソッドを使用して特定のデバイスに切り替えるだけです。これにより、データがこれらの層を通過するたびに、データも層と同じデバイスに切り替えられ、残りの部分は変更されません。
|
| 252 |
+
|
| 253 |
+
私たちはこれを「垂直MP」と呼びます。なぜなら、ほとんどのモデルがどのように描かれるかを思い出すと、層を垂直にスライスするからです。たとえば、以下の図は8層のモデルを示しています:
|
| 254 |
+
|
| 255 |
+
|
| 256 |
+
```
|
| 257 |
+
=================== ===================
|
| 258 |
+
| 0 | 1 | 2 | 3 | | 4 | 5 | 6 | 7 |
|
| 259 |
+
=================== ===================
|
| 260 |
+
gpu0 gpu1
|
| 261 |
+
```
|
| 262 |
+
|
| 263 |
+
我々は、モデルを垂直に2つに分割し、レイヤー0から3をGPU0に配置し、レイヤー4から7をGPU1に配置しました。
|
| 264 |
+
|
| 265 |
+
データがレイヤー0から1、1から2、2から3に移動する間は通常のモデルと同じです。しかし、データがレイヤー3からレイヤー4に移動する必要がある場合、GPU0からGPU1への移動が発生し、通信のオーバーヘッドが発生します。参加しているGPUが同じコンピュートノード(例:同じ物理マシン)にある場合、このコピーは非常に高速ですが、異なるコンピュートノード(例:複数のマシン)にある場合、通信のオーバーヘッドは大幅に増加する可能性があります。
|
| 266 |
+
|
| 267 |
+
その後、レイヤー4から5、6から7までは通常のモデルと同様に動作し、7番目のレイヤーが完了すると、データをしばしばレイヤー0に戻す必要があります(またはラベルを最後のレイヤーに送信します)。これで損失を計算し、オプティマイザが作業を開始できます。
|
| 268 |
+
|
| 269 |
+
問題点:
|
| 270 |
+
- 主な欠点、およびなぜこれを「単純な」MPと呼ぶのかは、1つを除いてすべてのGPUがどんな瞬間でもアイドル状態であることです。したがって、4つのGPUを使用する場合、単純なMPは、1つのGPUのメモリ容量を4倍にするのとほぼ同じであり、ハードウェアの残りを無視します。さらに、データのコピーのオーバーヘッドがあることを忘れてはいけません。したがって、4枚の6GBのカードは、データのコピーのオーバーヘッドがない1枚の24GBのカードと同じサイズを収容できるでしょうが、後者はトレーニングをより迅速に完了します。ただし、たとえば40GBのカードがあり、45GBのモデルを収める必要がある場合、勾配とオプティマイザの状態のためにほとんど収めることができません。
|
| 271 |
+
- 共有の埋め込みは、GPU間でコピーする必要があるかもしれません。
|
| 272 |
+
|
| 273 |
+
パイプライン並列処理(PP)は、ほぼ単純なMPと同じですが、GPUがアイドル状態になる問題を解決し、入力バッチをマイクロバッチに分割し、パイプラインを人工的に作成することにより、異なるGPUが計算プロセスに同時に参加できるようにします。
|
| 274 |
+
|
| 275 |
+
以下は、[GPipe論文](https://ai.googleblog.com/2019/03/introducing-gpipe-open-source-library.html)からの図で、上部には単純なMP、下部にはPPが示されています:
|
| 276 |
+
|
| 277 |
+
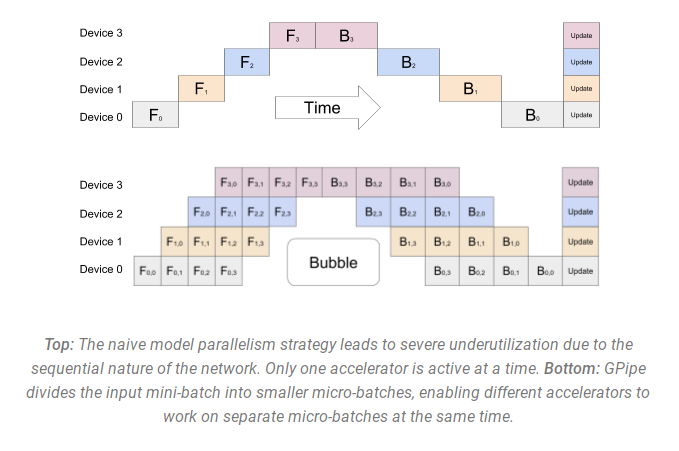
|
| 278 |
+
|
| 279 |
+
この図から、PPがGPUがアイドル状態の領域である「バブル」を少なく持つことがわかります。アイドル状態の部分は「バブル」と呼ばれます。
|
| 280 |
+
|
| 281 |
+
図の両方の部分は、4つのGPUがパイプラインに参加している4の次元の並列性を示しています。つまり、4つのパイプステージF0、F1、F2、F3のフォワードパスがあり、逆順のバックワードパスB3、B2、B1、B0があります。
|
| 282 |
+
|
| 283 |
+
PPは調整する新しいハイパーパラメータを導入します。それは `chunks` で、同じパイプステージを通じて連続して送信されるデータのチャンクの数を定義します。たとえば、下の図では `chunks=4` が表示されています。GPU0はチャンク0、1、2、3(F0,0、F0,1、F0,2、F0,3)で同じフォワードパスを実行し、他のGPUが作業を開始し始めるのを待ってから、GPU0はチャンク3、2、1、0(B0,3、B0,2、B0,1、B0,0)で逆順パスを実行します。
|
| 284 |
+
|
| 285 |
+
注意すべきは、概念的にはこれが勾配蓄積ステップ(GAS)と同じコンセプトであることです。PyTorchは `chunks` を使用し、DeepSpeedは同じハイパーパラメータをGASと呼びます。
|
| 286 |
+
|
| 287 |
+
`chunks` の導入により、PPはマイクロバッチ(MBS)の概念を導入します。DPはグローバルデータバッチサイズをミニバッチに分割します。したがって、DPの次数が4で、グローバルバッチサイズが1024の場合、4つのミニバッチ(それぞれ256)に分割されます(1024/4)。そして、`chunks`(またはGAS)の数が32である場合、マイクロバッチサイズは8になります(256/32)。各パイプラインステージは1つのマイクロバッチで作業します。
|
| 288 |
+
|
| 289 |
+
DP + PPセットアップのグローバルバッチサイズを計算するには、`mbs*chunks*dp_degree`(`8*32*4=1024`)を行います。
|
| 290 |
+
|
| 291 |
+
図に戻りましょう。
|
| 292 |
+
|
| 293 |
+
`chunks=1` であれば、非効率な単純なMPになります。非常に大きな `chunks` 値を使用すると、非常に小さなマイクロバッチサイズになり、効率があまり高くないかもしれません。したがって、GPUの効率的な利用を最大化する値を見つけるために実験する必要があります。これは、バブルのサイズを最小限にすることに対応する、すべての参加GPUにわたる高い並行GPU利用を可能にするためです。
|
| 294 |
+
|
| 295 |
+
2つのソリューショングループがあります。従来のパイプラインAPIソリューションと、ユーザーのモデルを大幅に変更する必要があるより現代的なソリューションです。
|
| 296 |
+
|
| 297 |
+
従来のパイプラインAPIソリューション:
|
| 298 |
+
- PyTorch
|
| 299 |
+
- DeepSpeed
|
| 300 |
+
- Megatron-LM
|
| 301 |
+
|
| 302 |
+
現代的なソリューション:
|
| 303 |
+
- Varuna
|
| 304 |
+
- Sagemaker
|
| 305 |
+
|
| 306 |
+
従来のパイプラインAPIソリューションの問題点:
|
| 307 |
+
- モデルをかなり変更する必要があるため、Pipelineはモジュールの通常のフローを`nn.Sequential`シーケンスに再書き込む必要があり、モデルの設計を変更することが必要です。
|
| 308 |
+
- 現在、Pipeline APIは非常に制限的です。最初のパイプラインステージに渡されるPython変数のセットがある場合、回避策を見つける必要があります。現在、パイプラインインターフェースでは、唯一のテンソルまたはテンソルのタプルを入力と出力として要求しています。これらのテンソルはバッチサイズを最初の次元として持っている必要があります。パイプラインはミニバッチをマイクロバッチに分割します。可能な改善点については、こちらの議論が行われています:https://github.com/pytorch/pytorch/pull/50693
|
| 309 |
+
- パイプステージのレベルでの条件付き制御フローは不可能です。例えば、T5のようなエンコーダーデコーダーモデルは、条件付きエンコーダーステージを処理するために特別な回避策が必要です。
|
| 310 |
+
- 各レイヤーを配置する必要があるため、1つのモデルの出力が他のモデルの入力になるようにします。
|
| 311 |
+
|
| 312 |
+
VarunaとSageMakerとの実験はまだ行っていませんが、彼らの論文によれば、上記で述べた問題のリストを克服し、ユーザーのモデルにははるかに小さな変更しか必要としないと報告されています。
|
| 313 |
+
|
| 314 |
+
実装:
|
| 315 |
+
|
| 316 |
+
- [Pytorch](https://pytorch.org/docs/stable/pipeline.html) (initial support in pytorch-1.8, and progressively getting improved in 1.9 and more so in 1.10). Some [examples](https://github.com/pytorch/pytorch/blob/master/benchmarks/distributed/pipeline/pipe.py)
|
| 317 |
+
- [DeepSpeed](https://www.deepspeed.ai/tutorials/pipeline/)
|
| 318 |
+
- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM) has an internal implementation - no API.
|
| 319 |
+
- [Varuna](https://github.com/microsoft/varuna)
|
| 320 |
+
- [SageMaker](https://arxiv.org/abs/2111.05972) - this is a proprietary solution that can only be used on AWS.
|
| 321 |
+
- [OSLO](https://github.com/tunib-ai/oslo) - この実装は、Hugging Face Transformersに基づいています。
|
| 322 |
+
|
| 323 |
+
🤗 Transformersのステータス: この執筆時点では、いずれのモデルも完全なPP(パイプライン並列処理)をサポートしていません。GPT2モデルとT5モデルは単純なMP(モデル並列処理)サポートを持っています。主な障害は、モデルを`nn.Sequential`に変換できず、すべての入力がテンソルである必要があることです。現在のモデルには、変換を非常に複雑にする多くの機能が含まれており、これらを削除する必要があります。
|
| 324 |
+
|
| 325 |
+
他のアプローチ:
|
| 326 |
+
|
| 327 |
+
DeepSpeed、Varuna、およびSageMakerは、[交互にパイプラインを実行](https://docs.aws.amazon.com/sagemaker/latest/dg/model-parallel-core-features.html)するコンセプトを使用しています。ここでは、バックワードパスを優先させてバブル(アイドル時間)をさらに最小限に抑えます。
|
| 328 |
+
|
| 329 |
+
Varunaは、最適なスケジュールを発見するためにシミュレーションを使用してスケジュールをさらに改善しようとします。
|
| 330 |
+
|
| 331 |
+
OSLOは、`nn.Sequential`の変換なしでTransformersに基づくパイプライン並列処理を実装しています。
|
| 332 |
+
|
| 333 |
+
## Tensor Parallelism
|
| 334 |
+
|
| 335 |
+
テンソル並列処理では、各GPUがテンソルのスライスのみを処理し、全体が必要な操作のためにのみ完全なテンソルを集約します。
|
| 336 |
+
|
| 337 |
+
このセクションでは、[Megatron-LM](https://github.com/NVIDIA/Megatron-LM)論文からのコンセプトと図を使用します:[GPUクラスタでの効率的な大規模言語モデルトレーニング](https://arxiv.org/abs/2104.04473)。
|
| 338 |
+
|
| 339 |
+
どのトランスフォーマの主要な構築要素は、完全に接続された`nn.Linear`に続く非線形アクティベーション`GeLU`です。
|
| 340 |
+
|
| 341 |
+
Megatronの論文の表記法に従って、行列の乗算部分を`Y = GeLU(XA)`と書くことができます。ここで、`X`と`Y`は入力ベクトルと出力ベクトルで、`A`は重み行列です。
|
| 342 |
+
|
| 343 |
+
行列の計算を行列形式で見ると、行列乗算を複数のGPUで分割できる方法が簡単に理解できます:
|
| 344 |
+
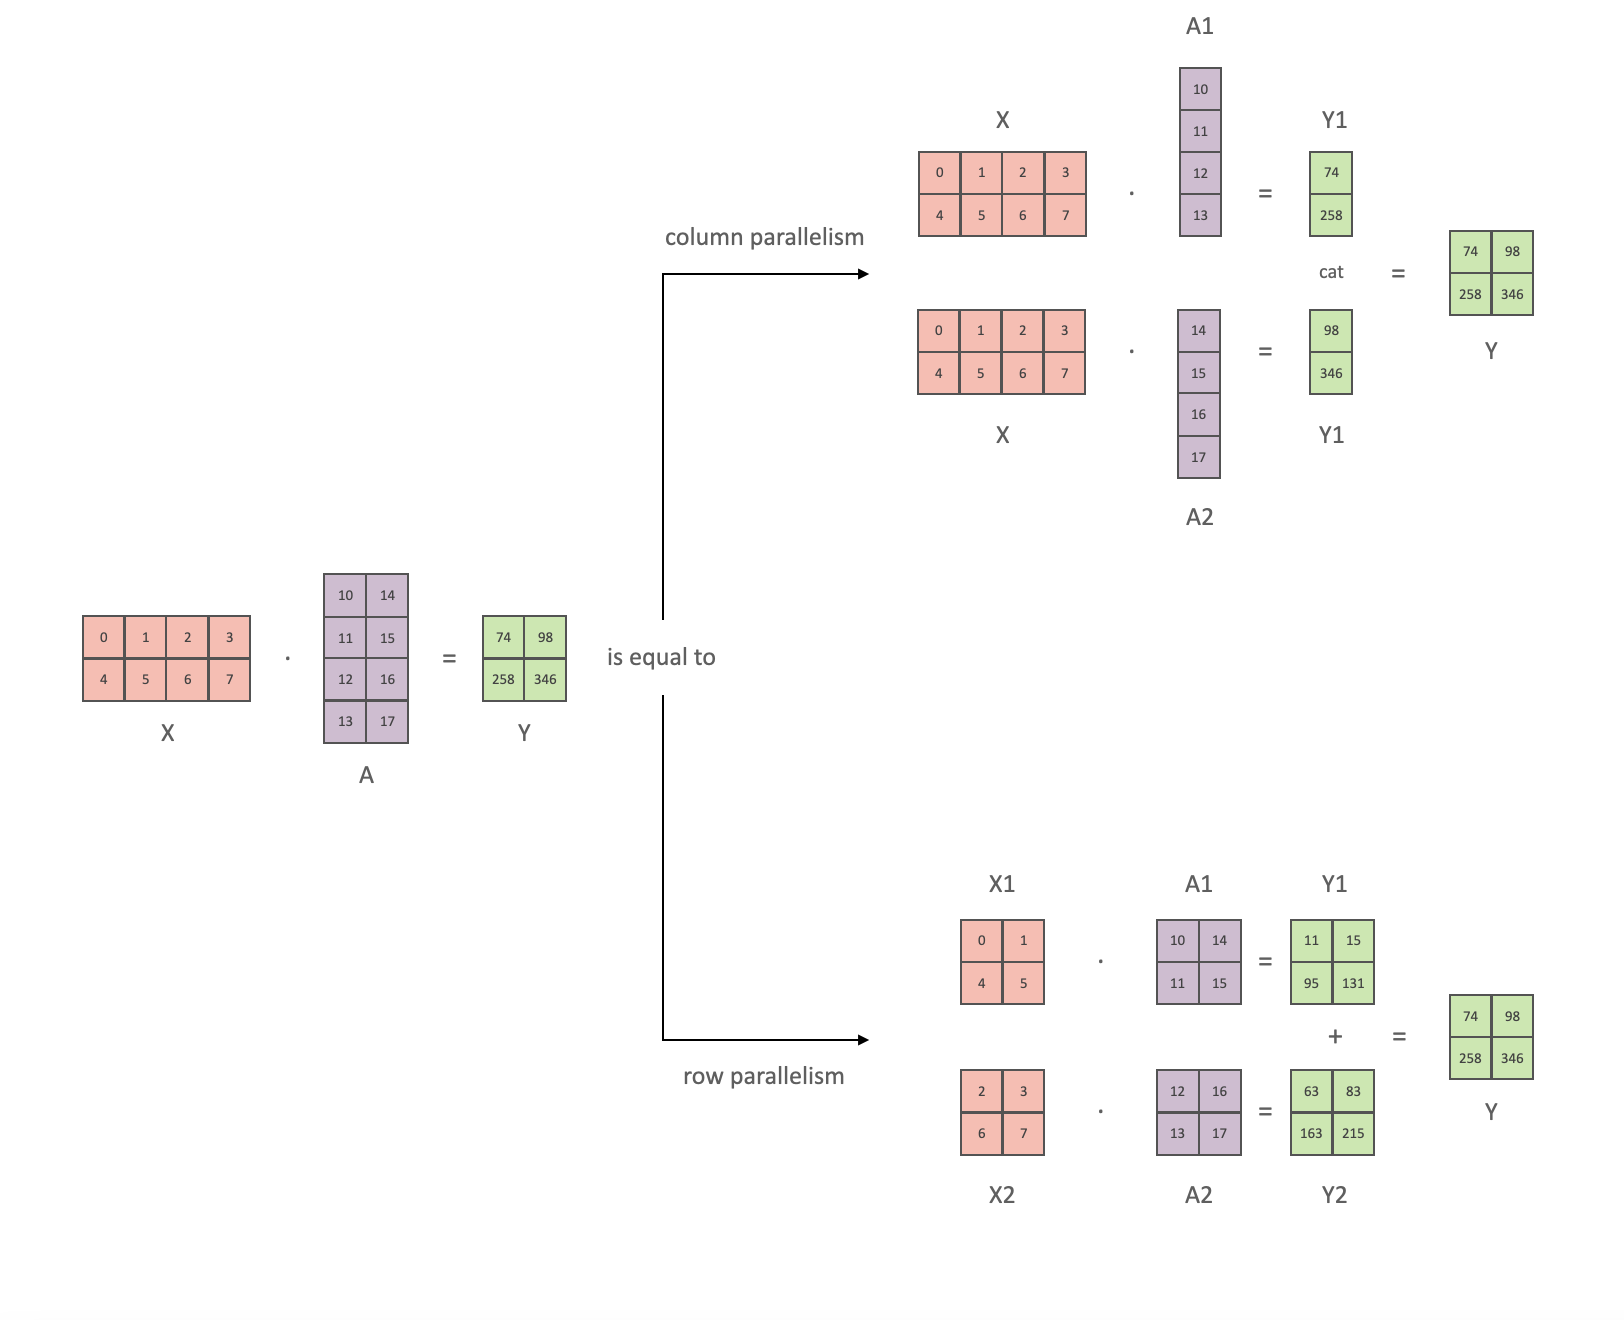
|
| 345 |
+
|
| 346 |
+
重み行列`A`を`N`個のGPUに対して列ごとに分割し、並列で行列乗算`XA_1`から`XA_n`を実行すると、`N`個の出力ベクトル`Y_1、Y_2、...、Y_n`が得られ、それらを独立して`GeLU`に供給できます:
|
| 347 |
+

|
| 348 |
+
|
| 349 |
+
この原理を使用して、最後まで同期が必要ないまま、任意の深さのMLPを更新できます。Megatron-LMの著者はそのための有用なイラストを提供しています:
|
| 350 |
+
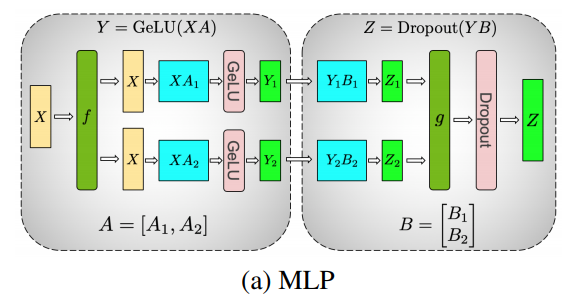
|
| 351 |
+
|
| 352 |
+
マルチヘッドアテンションレイヤーを並列化することはさらに簡単です。それらは既に複数の独立したヘッドを持っているため、本質的に並列です!
|
| 353 |
+
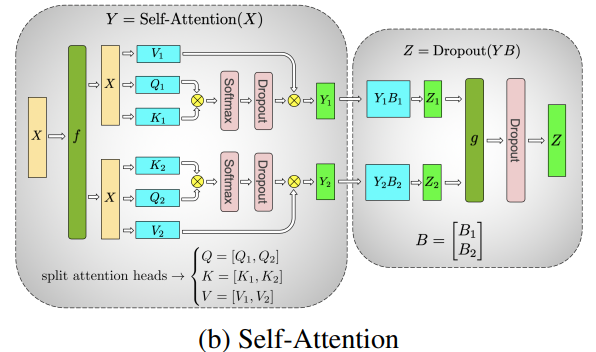
|
| 354 |
+
|
| 355 |
+
特別な考慮事項:TPには非常に高速なネットワークが必要であり、したがって1つのノードを超えてTPを実行しないことがお勧めされません。実際には、1つのノードに4つのGPUがある場合、最大のTP度数は4です。TP度数8が必要な場合は、少なくとも8つのGPUを持つノードを使用する必要があります。
|
| 356 |
+
|
| 357 |
+
このセクションは、元のより詳細な[TPの概要](https://github.com/huggingface/transformers/issues/10321#issuecomment-783543530)に基づいています。
|
| 358 |
+
by [@anton-l](https://github.com/anton-l)。
|
| 359 |
+
|
| 360 |
+
SageMakerは、より効率的な処理のためにTPとDPを組み合わせて使用します。
|
| 361 |
+
|
| 362 |
+
代替名:
|
| 363 |
+
- [DeepSpeed](https://github.com/deepspeedai/DeepSpeed)はこれを「テンソルスライシング」と呼びます。詳細は[DeepSpeedの特徴](https://www.deepspeed.ai/training/#model-parallelism)をご覧ください。
|
| 364 |
+
|
| 365 |
+
実装例:
|
| 366 |
+
- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)には、モデル固有の内部実装があります。
|
| 367 |
+
- [parallelformers](https://github.com/tunib-ai/parallelformers)(現時点では推論のみ)。
|
| 368 |
+
- [SageMaker](https://arxiv.org/abs/2111.05972) - これはAWSでのみ使用できるプロプライエタリなソリューションです。
|
| 369 |
+
- [OSLO](https://github.com/tunib-ai/oslo)には、Transformersに基づいたテンソル並列実装があります。
|
| 370 |
+
|
| 371 |
+
🤗 Transformersの状況:
|
| 372 |
+
- コア: まだコアには実装されていません。
|
| 373 |
+
- ただし、推論が必要な場合、[parallelformers](https://github.com/tunib-ai/parallelformers)はほとんどのモデルに対してサポートを提供します。これがコアに実装されるまで、これを使用できます。そして、トレーニングモードもサポートされることを期待しています。
|
| 374 |
+
- Deepspeed-Inferenceでは、BERT、GPT-2、およびGPT-NeoモデルをCUDAカーネルベースの高速推論モードでサポートしています。詳細は[こちら](https://www.deepspeed.ai/tutorials/inference-tutorial/)をご覧ください。
|
| 375 |
+
|
| 376 |
+
## DP+PP
|
| 377 |
+
|
| 378 |
+
DeepSpeedの[パイプラインチュートリアル](https://www.deepspeed.ai/tutorials/pipeline/)からの次の図は、DPをPPと組み合わせる方法を示しています。
|
| 379 |
+
|
| 380 |
+
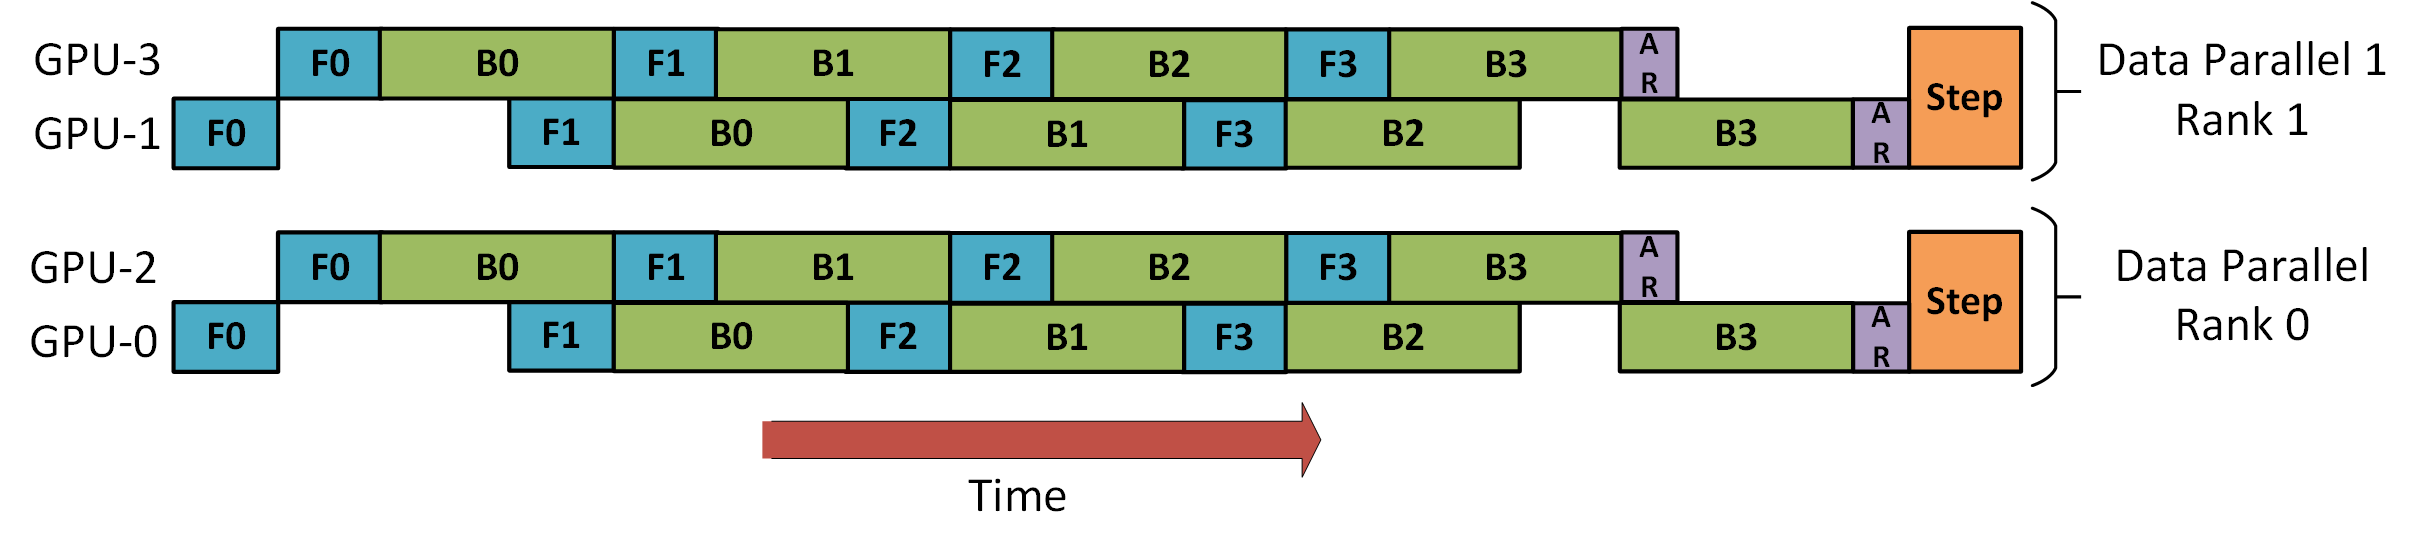
|
| 381 |
+
|
| 382 |
+
ここで重要なのは、DPランク0がGPU2を見えなくし、DPランク1がGPU3を見えなくすることです。DPにとって、存在するのはGPU 0 と 1 のみで、それらの2つのGPUのようにデータを供給します。GPU0はPPを使用してGPU2に一部の負荷を「秘密裏に」オフロードし、GPU1も同様にGPU3を支援に引き入れます。
|
| 383 |
+
|
| 384 |
+
各次元には少なくとも2つのGPUが必要ですので、ここでは少なくとも4つのGPUが必要です。
|
| 385 |
+
|
| 386 |
+
実装例:
|
| 387 |
+
- [DeepSpeed](https://github.com/deepspeedai/DeepSpeed)
|
| 388 |
+
- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
|
| 389 |
+
- [Varuna](https://github.com/microsoft/varuna)
|
| 390 |
+
- [SageMaker](https://arxiv.org/abs/2111.05972)
|
| 391 |
+
- [OSLO](https://github.com/tunib-ai/oslo)
|
| 392 |
+
|
| 393 |
+
🤗 Transformersの状況: まだ実装されていません
|
| 394 |
+
|
| 395 |
+
## DP+PP+TP
|
| 396 |
+
|
| 397 |
+
さらに効率的なトレーニングを行うために、3Dパラレリズムを使用し、PPをTPとDPと組み合わせます。これは次の図で示されています。
|
| 398 |
+
|
| 399 |
+
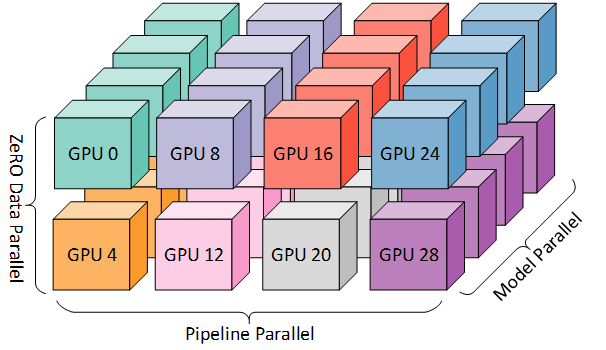
|
| 400 |
+
|
| 401 |
+
この図は[3Dパラレリズム:兆パラメータモデルへのスケーリング](https://www.microsoft.com/en-us/research/blog/deepspeed-extreme-scale-model-training-for-everyone/)というブログ投稿から取得されたもので、おすすめの読み物です。
|
| 402 |
+
|
| 403 |
+
各次元には少なくとも2つのGPUが必要ですので、ここでは少なくとも8つのGPUが必要です。
|
| 404 |
+
|
| 405 |
+
実装例:
|
| 406 |
+
- [DeepSpeed](https://github.com/deepspeedai/DeepSpeed) - DeepSpeedには、さらに効率的なDPであるZeRO-DPと呼ばれるものも含まれています。
|
| 407 |
+
- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
|
| 408 |
+
- [Varuna](https://github.com/microsoft/varuna)
|
| 409 |
+
- [SageMaker](https://arxiv.org/abs/2111.05972)
|
| 410 |
+
- [OSLO](https://github.com/tunib-ai/oslo)
|
| 411 |
+
|
| 412 |
+
🤗 Transformersの状況: まだ実装されていません。PPとTPがないため。
|
| 413 |
+
|
| 414 |
+
## ZeRO DP+PP+TP
|
| 415 |
+
|
| 416 |
+
DeepSpeedの主要な機能の1つはZeROで、これはDPの拡張機能です。これについてはすでに「ZeROデータ並列化」で説明されています。通常、これは単独で動作する機能で、PPやTPは必要ありません。しかし、PPとTPと組み合わせることもできます。
|
| 417 |
+
|
| 418 |
+
ZeRO-DPがPPと組み合わされる場合、通常はZeROステージ1(オプティマイザーシャーディング)のみが有効になります。
|
| 419 |
+
|
| 420 |
+
ZeROステージ2(勾配シャーディング)をパイプライン並列化と組み合わせて使用する理論的な可能性はありますが、性能に悪影響を及ぼします。各マイクロバッチごとに勾配をシャーディングする前に、勾配を集約するための追加のリダクションスキャッター集計が必要で、通信オーバーヘッドが発生する可能性があります。パイプライン並列化の性質上、小さなマイクロバッチが使用され、計算の集中度(マイクロバッチサイズ)をバランスにかけ、パイプラインバブル(マイクロバッチ数)を最小限に抑えることに焦点が当てられています。したがって、これらの通信コストは影響を及ぼすでしょう。
|
| 421 |
+
|
| 422 |
+
さらに、PPには通常よりも少ない層が含まれており、メモリの節約はそれほど大きくありません。PPは既に勾配サイズを「1/PP」に削減するため、勾配シャーディングの節約は純粋なDPよりもはるかに重要ではありません。
|
| 423 |
+
|
| 424 |
+
ZeROステージ3も同様の理由で適していません - より多くのノード間通信が必要です。
|
| 425 |
+
|
| 426 |
+
そして、ZeROを持っているので、もう一つの利点はZeRO-Offloadです。これはステージ1オプティマイザーステートをCPUにオフロードできます。
|
| 427 |
+
|
| 428 |
+
実装例:
|
| 429 |
+
- [Megatron-DeepSpeed](https://github.com/microsoft/Megatron-DeepSpeed)と[BigScienceからのMegatron-Deepspeed](https://github.com/bigscience-workshop/Megatron-DeepSpeed)は、前者のリポジトリのフォークです。
|
| 430 |
+
- [OSLO](https://github.com/tunib-ai/oslo)
|
| 431 |
+
|
| 432 |
+
重要な論文:
|
| 433 |
+
|
| 434 |
+
- [DeepSpeedとMegatronを使用したMegatron-Turing NLG 530Bのトレーニング](https://arxiv.org/abs/2201.11990)
|
| 435 |
+
|
| 436 |
+
🤗 Transformersの状況: まだ実装されていません。PPとTPがないため。
|
| 437 |
+
|
| 438 |
+
|
| 439 |
+
## FlexFlow
|
| 440 |
+
|
| 441 |
+
[FlexFlow](https://github.com/flexflow/FlexFlow)は、わずかに異なるアプローチで並列化の問題を解決します。
|
| 442 |
+
|
| 443 |
+
論文: [Zhihao Jia、Matei Zaharia、Alex Aikenによる "Deep Neural Networksのデータとモデルの並列化を超えて"](https://arxiv.org/abs/1807.05358)
|
| 444 |
+
|
| 445 |
+
FlexFlowは、サンプル-オペレータ-属性-パラメータの4D並列化を行います。
|
| 446 |
+
|
| 447 |
+
1. サンプル = データ並列化(サンプル単位の並列化)
|
| 448 |
+
2. オペレータ = 単一の操作をいくつかのサブ操作に並列化
|
| 449 |
+
3. 属性 = データ並列化(長さ方向の並列化)
|
| 450 |
+
4. パラメータ = モデル並列化(次元に関係なく、水平または垂直)
|
| 451 |
+
|
| 452 |
+
例:
|
| 453 |
+
* サンプル
|
| 454 |
+
|
| 455 |
+
シーケンス長512の10バッチを考えてみましょう。これらをサンプル次元で2つのデバイスに並列化すると、10 x 512が5 x 2 x 512になります。
|
| 456 |
+
|
| 457 |
+
* オペレータ
|
| 458 |
+
|
| 459 |
+
層正規化を行う場合、まずstdを計算し、次にmeanを計算し、データを正規化できます。オペレータの並列化により、stdとmeanを並列に計算できます。したがって、オペレータ次元で2つのデバイス(cuda:0、cuda:1)に並列化すると、最初に入力データを両方のデバイスにコピーし、cuda:0でstdを計算し、cuda:1でmeanを同時に計算します。
|
| 460 |
+
|
| 461 |
+
* 属性
|
| 462 |
+
|
| 463 |
+
10バッチの512長があります。これらを属性次元で2つのデバイスに並列化すると、10 x 512が10 x 2 x 256になります。
|
| 464 |
+
|
| 465 |
+
* パラメータ
|
| 466 |
+
|
| 467 |
+
これはテンソルモデルの並列化または単純な層ごとのモデルの並列化と似ています。
|
| 468 |
+
|
| 469 |
+
このフレームワークの重要性は、(1)GPU/TPU/CPU対(2)RAM/DRAM対(3)高速内部接続/低速外部接続などのリソースを取り、これらすべてをアルゴリズムによって自動的に最適化することです。どの並列化をどこで使用するかをアルゴリズム的に決定します。
|
| 470 |
+
|
| 471 |
+
非常に重要な側面の1つは、FlexFlowは静的で固定のワークロードを持つモデルのために設計されており、動的な動作を持つモデルはイテレーションごとに異なる並列化戦略を好む場合があることです。
|
| 472 |
+
|
| 473 |
+
したがって、このフレームワークの約束は非常に魅力的です。選択したクラスタで30分間のシミュレーションを実行し、この特定の環境を最適に利用するための最良の戦略を提供します。部分を追加/削除/置換すると、それに対して実行して再最適化プランを作成します。その後、トレーニングできます。異なるセットアップには独自の最適化があります。
|
| 474 |
+
|
| 475 |
+
🤗 Transformersの現在の状況: まだ統合されていません。すでに[transformers.utils.fx](https://github.com/huggingface/transformers/blob/master/src/transformers/utils/fx.py)を使用してモデルがFXトレース可能であるため、FlexFlowを動作させるために必要な手順を誰かが見つける必要があります。
|
| 476 |
+
|
| 477 |
+
## Which Strategy To Use When
|
| 478 |
+
|
| 479 |
+
ここでは、どの並列化戦略をいつ使用するかの非常におおまかなアウトラインを示します。各リストの最初が通常よりも速いことが一般的です。
|
| 480 |
+
|
| 481 |
+
**⇨ 単一GPU**
|
| 482 |
+
|
| 483 |
+
* モデルが単一GPUに収まる場合:
|
| 484 |
+
|
| 485 |
+
1. 通常の使用
|
| 486 |
+
|
| 487 |
+
* モデルが単一GPUに収まらない場合:
|
| 488 |
+
|
| 489 |
+
1. ZeRO + CPUをオフロードし、オプションでNVMeをオフロード
|
| 490 |
+
2. 上記に加えて、最大のレイヤーが単一GPUに収まらない場合、[Memory Centric Tiling](https://deepspeed.readthedocs.io/en/latest/zero3.html#memory-centric-tiling)(詳細は以下参照)を有効化
|
| 491 |
+
|
| 492 |
+
* 最大のレイヤーが単一GPUに収まらない場合:
|
| 493 |
+
|
| 494 |
+
1. ZeROを使用しない場合 - TPを有効化する必要があります。なぜなら、PPだけでは収めることができないからです。
|
| 495 |
+
2. ZeROを使用する場合は、上記の「単一GPU」のエントリと同じものを参照してください
|
| 496 |
+
|
| 497 |
+
**⇨ 単一ノード/マルチGPU**
|
| 498 |
+
|
| 499 |
+
* モデルが単一GPUに収まる場合:
|
| 500 |
+
|
| 501 |
+
1. DDP - 分散データ並列
|
| 502 |
+
2. ZeRO - 状況と使用される構成に依存して速いかどうかが異なることがあります
|
| 503 |
+
|
| 504 |
+
* モデルが単一GPUに収まらない場合:
|
| 505 |
+
|
| 506 |
+
1. PP
|
| 507 |
+
2. ZeRO
|
| 508 |
+
3. TP
|
| 509 |
+
|
| 510 |
+
非常に高速なノード内接続がNVLINKまたはNVSwitchである場合、これらのすべてはほとんど同等の性能です。これらがない場合、PPはTPまたはZeROよりも速くなります。TPの度合いも違いを生じるかもしれません。特定のセットアップで勝者を見つけるために実験するのが最善です。
|
| 511 |
+
|
| 512 |
+
TPはほとんど常に単一ノード内で使用されます。つまり、TPサイズ <= ノードあたりのGPUです。
|
| 513 |
+
|
| 514 |
+
* 最大のレイヤーが単一GPUに収まらない場合:
|
| 515 |
+
|
| 516 |
+
1. ZeROを使用しない場合 - TPを使用する必要があります。なぜなら、PPだけでは収めることができないからです。
|
| 517 |
+
2. ZeROを使用する場合は、上記の「単一GPU」のエントリと同じものを参照してください
|
| 518 |
+
|
| 519 |
+
**⇨ マルチノード/マルチGPU**
|
| 520 |
+
|
| 521 |
+
* 高速なノード間接続がある場合:
|
| 522 |
+
|
| 523 |
+
1. ZeRO - モデルへのほとんどの変更が���要です
|
| 524 |
+
2. PP+TP+DP - 通信が少なく、モデルに大規模な変更が必要です
|
| 525 |
+
|
| 526 |
+
* 遅いノード間接続があり、GPUメモリが少ない場合:
|
| 527 |
+
|
| 528 |
+
1. DP+PP+TP+ZeRO-1
|
| 529 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_gpu_one.md
ADDED
|
@@ -0,0 +1,437 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Methods and tools for efficient training on a single GPU
|
| 17 |
+
|
| 18 |
+
このガイドでは、メモリの利用効率を最適化し、トレーニングを高速化することで、モデルのトレーニング効率を向上させるために使用できる実用的なテクニックを紹介します。トレーニング中にGPUがどのように利用されるかを理解したい場合は、最初に「[モデルトレーニングの解剖学](model_memory_anatomy)」のコンセプトガイドを参照してください。このガイドは実用的なテクニックに焦点を当てています。
|
| 19 |
+
|
| 20 |
+
<Tip>
|
| 21 |
+
|
| 22 |
+
複数のGPUを搭載したマシンにアクセスできる場合、これらのアプローチは依然として有効です。さらに、[マルチGPUセクション](perf_train_gpu_many)で説明されている追加の方法を活用できます。
|
| 23 |
+
|
| 24 |
+
</Tip>
|
| 25 |
+
|
| 26 |
+
大規模なモデルをトレーニングする際、同時に考慮すべき2つの側面があります:
|
| 27 |
+
|
| 28 |
+
* データのスループット/トレーニング時間
|
| 29 |
+
* モデルのパフォーマンス
|
| 30 |
+
|
| 31 |
+
スループット(サンプル/秒)を最大化することは、トレーニングコストを低減させます。これは一般的に、GPUをできるだけ効果的に活用し、GPUメモリを限界まで埋めることによって達成されます。希望するバッチサイズがGPUメモリの制限を超える場合、勾配蓄積などのメモリ最適化テクニックが役立ちます。
|
| 32 |
+
|
| 33 |
+
しかし、好みのバッチサイズがメモリに収まる場合、メモリを最適化するテクニックを適用する理由はありません。大きなバッチサイズを使用できるからといって、それを必ずしも使用すべきではありません。ハイパーパラメータの調整の一環として、どのバッチサイズが最良の結果を生み出すかを決定し、リソースを適切に最適化する必要があります。
|
| 34 |
+
|
| 35 |
+
このガイドでカバーされている方法とツールは、トレーニングプロセスに与える影響に基づいて分類できます:
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
| Method/tool | Improves training speed | Optimizes memory utilization |
|
| 39 |
+
|:-----------------------------------------------------------|:------------------------|:-----------------------------|
|
| 40 |
+
| [Batch size choice](#batch-size-choice) | Yes | Yes |
|
| 41 |
+
| [Gradient accumulation](#gradient-accumulation) | No | Yes |
|
| 42 |
+
| [Gradient checkpointing](#gradient-checkpointing) | No | Yes |
|
| 43 |
+
| [Mixed precision training](#mixed-precision-training) | Yes | (No) |
|
| 44 |
+
| [Optimizer choice](#optimizer-choice) | Yes | Yes |
|
| 45 |
+
| [Data preloading](#data-preloading) | Yes | No |
|
| 46 |
+
| [DeepSpeed Zero](#deepspeed-zero) | No | Yes |
|
| 47 |
+
| [torch.compile](#using-torchcompile) | Yes | No |
|
| 48 |
+
|
| 49 |
+
<Tip>
|
| 50 |
+
|
| 51 |
+
**注意**: 小さなモデルと大きなバッチサイズを使用する場合、メモリの節約が行われますが、大きなモデルと小さなバッチサイズを使用する場合、メモリの使用量が増加します。
|
| 52 |
+
|
| 53 |
+
</Tip>
|
| 54 |
+
|
| 55 |
+
これらのテクニックは、[`Trainer`]でモデルをトレーニングしている場合や、純粋なPyTorchループを記述している場合の両方で利用できます。詳細な最適化の設定については、🤗 Accelerateを使用して[これらの最適化を設定できます](#using--accelerate)。
|
| 56 |
+
|
| 57 |
+
これらの方法が十分な利益をもたらさない場合、以下のオプションを検討できます:
|
| 58 |
+
* [効率的なソフトウェアプリビルドを備えたカスタムDockerコンテナの作成](#efficient-software-prebuilds)
|
| 59 |
+
* [Mixture of Experts(MoE)を使用するモデルを検討](#mixture-of-experts)
|
| 60 |
+
* [モデルをBetterTransformerに変換して、PyTorchネイティブのアテンションを活用](#using-pytorch-native-attention)
|
| 61 |
+
|
| 62 |
+
最後に、これらの方法がまだ十分でない場合、A100などのサーバーグレードGPUに切り替えても、さらなる改善が必要かもしれません。これらのアプローチは、マルチGPUセットアップでも有効であり、[マルチGPUセクション](perf_train_gpu_many)で説明されている追加の並列化技術を活用できます。
|
| 63 |
+
|
| 64 |
+
## Batch size choice
|
| 65 |
+
|
| 66 |
+
最適なパフォーマンスを実現するために、適切なバッチサイズを特定することから始めましょう。2^Nのサイズのバッチサイズと入力/出力ニューロン数を使用することが推奨されています。通常、これは8の倍数ですが、使用するハードウェアとモデルのデータ型に依存することがあります。
|
| 67 |
+
|
| 68 |
+
参考までに、NVIDIAの[入力/出力ニューロン数の推奨事項](https://docs.nvidia.com/deeplearning/performance/dl-performance-fully-connected/index.html#input-features)と[バッチサイズ](https://docs.nvidia.com/deeplearning/performance/dl-performance-fully-connected/index.html#batch-size)を確認してください(これらはGEMM(一般的な行列乗算)に関与します)。
|
| 69 |
+
|
| 70 |
+
[Tensor Core要件](https://docs.nvidia.com/deeplearning/performance/dl-performance-matrix-multiplication/index.html#requirements-tc)では、データ型とハードウェアに基づいて乗数が定義されています。たとえば、fp16データ型の場合、64の倍数を使用することが推奨されます(A100 GPUの場合を除く)。
|
| 71 |
+
|
| 72 |
+
小さなパラメータの場合、[次元量子化効果](https://docs.nvidia.com/deeplearning/performance/dl-performance-matrix-multiplication/index.html#dim-quantization)も考慮してください。これはタイリングが行われ、適切な乗数が大幅な高速化をもたらす場合があります。
|
| 73 |
+
|
| 74 |
+
## Gradient Accumulation
|
| 75 |
+
|
| 76 |
+
**勾配蓄積**メソッドは、GPUのメモリ容量の制約によって課せられる制限を超えた効果的なバッチサイズを実現するために、勾配を小さな増分で計算することを目的としています。このアプローチでは、モデルを順方向および逆方向に小さなバッチで反復的に計算し、その過程で勾配を蓄積します。十分な数の勾配が蓄積されたら、モデルの最適化ステップを実行します。勾配蓄積を使用することで、GPUのメモリ容量による制約を超えて**効果的なバッチサイズ**を増やすことができますが、勾配蓄積によって導入される追加の順方向および逆方向の計算はトレーニングプロセスを遅くする可能性があることに注意が必要です。
|
| 77 |
+
|
| 78 |
+
`TrainingArguments`に`gradient_accumulation_steps`引数を追加することで、勾配蓄積を有効にすることができます:
|
| 79 |
+
|
| 80 |
+
```py
|
| 81 |
+
training_args = TrainingArguments(per_device_train_batch_size=1, gradient_accumulation_steps=4, **default_args)
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
上記の例では、効果的なバッチサイズは4になります。
|
| 85 |
+
|
| 86 |
+
また、トレーニングループを完全に制御するために🤗 Accelerateを使用することもできます。🤗 Accelerateの例は、[このガイドの後半にある](#using--accelerate)で見つけることができます。
|
| 87 |
+
|
| 88 |
+
できるだけGPUの使用率を最大限にすることが推奨されていますが、高い勾配蓄積ステップ数はトレーニングの遅延をより顕著にすることがあります。以下の例を考えてみましょう。`per_device_train_batch_size=4`の場合、勾配蓄積を使用しないとGPUの制限に達します。バッチサイズ64でトレーニングしたい場合、`per_device_train_batch_size`を1に設定し、`gradient_accumulation_steps`を64に設定しないでください。代わりに、`per_device_train_batch_size=4`を保持し、`gradient_accumulation_steps=16`を設定します。これにより、同じ効果的なバッチサイズが得られ、利用可能なGPUリソースが効果的に活用されます。
|
| 89 |
+
|
| 90 |
+
詳細な情報については、[RTX-3090用のバッチサイズと勾配蓄積のベンチマーク](https://github.com/huggingface/transformers/issues/14608#issuecomment-1004392537)および[A100用のバッチサイズと勾配蓄積のベンチマーク](https://github.com/huggingface/transformers/issues/15026#issuecomment-1005033957)を参照してください。
|
| 91 |
+
|
| 92 |
+
## Gradient Checkpointing
|
| 93 |
+
|
| 94 |
+
一部の大きなモデルは、バッチサイズを1に設定し、勾配蓄積を使用している場合でもメモリの問題に直面することがあります。これは、メモリストレージが必要な他のコンポーネントも存在するためです。
|
| 95 |
+
|
| 96 |
+
前向きパスからのすべてのアクティベーションを保存して、逆向きパスで勾配を計算すると、かなりのメモリオーバーヘッドが発生します。逆向きパスで必要なときにアクティベーショ���を破棄して再計算する代替アプローチは、計算オーバーヘッドが大幅に増加し、トレーニングプロセスが遅くなります。
|
| 97 |
+
|
| 98 |
+
**勾配チェックポイント**は、これらの2つのアプローチの折衷案を提供し、計算グラフ全体で戦略的に選択されたアクティベーションのみを保存するため、勾配を再計算する必要があるアクティベーションの一部だけを節約します。勾配チェックポイントの詳細については、[この素晴らしい記事](https://medium.com/tensorflow/fitting-larger-networks-into-memory-583e3c758ff9)を参照してください。
|
| 99 |
+
|
| 100 |
+
[`Trainer`]で勾配チェックポイントを有効にするには、[`TrainingArguments`]に対応するフラグを渡します:
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
```py
|
| 104 |
+
training_args = TrainingArguments(
|
| 105 |
+
per_device_train_batch_size=1, gradient_accumulation_steps=4, gradient_checkpointing=True, **default_args
|
| 106 |
+
)
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
代替手段として、🤗 Accelerateを使用することもできます - 🤗 Accelerateの例は[このガイドのさらに後ろにあります](#using--accelerate)。
|
| 110 |
+
|
| 111 |
+
<Tip>
|
| 112 |
+
|
| 113 |
+
勾配チェックポイントを使用することでメモリ効率が向上する場合がありますが、トレーニング速度は約20%遅くなることに注意してください。
|
| 114 |
+
|
| 115 |
+
</Tip>
|
| 116 |
+
|
| 117 |
+
## Mixed precision training
|
| 118 |
+
|
| 119 |
+
**混合精度トレーニング**は、モデルのトレーニングの計算効率を最適化する技術で、特定の変数に対して低精度の数値フォーマットを利用します。従来、ほとんどのモデルは変数を表現し処理するために32ビット浮動小数点精度(fp32またはfloat32)を使用しています。しかし、すべての変数が正確な結果を得るためにこの高精度のレベルを必要としない場合があります。一部の変数の精度を16ビット浮動小数点(fp16またはfloat16)などのより低い数値フォーマットに変更することで、計算を高速化できます。このアプローチでは、一部の計算は半精度で行われ、一部はまだ完全な精度で行われるため、このアプローチは混合精度トレーニングと呼ばれています。
|
| 120 |
+
|
| 121 |
+
最も一般的に混合精度トレーニングは、fp16(float16)データ型を使用して実現されますが、一部のGPUアーキテクチャ(アンペアアーキテクチャなど)ではbf16およびtf32(CUDA内部データ型)データ型も提供されています。これらのデータ型の違いについて詳しく知りたい場合は、[NVIDIAのブログ](https://developer.nvidia.com/blog/accelerating-ai-training-with-tf32-tensor-cores/)を確認してください。
|
| 122 |
+
|
| 123 |
+
### fp16
|
| 124 |
+
|
| 125 |
+
混合精度トレーニングの主な利点は、半精度(fp16)でアクティベーションを保存することから得られます。
|
| 126 |
+
勾配も半精度で計算されますが、最適化ステップでは再び完全精度に変換されるため、ここではメモリは保存されません。
|
| 127 |
+
混合精度トレーニングは計算速度を向上させる一方、特に小さなバッチサイズの場合、より多くのGPUメモリを使用することがあります。
|
| 128 |
+
これは、モデルがGPU上に16ビットおよび32ビット精度の両方で存在するためです(GPU上の元のモデルの1.5倍)。
|
| 129 |
+
|
| 130 |
+
混合精度トレーニングを有効にするには、`fp16`フラグを`True`に設定します:
|
| 131 |
+
|
| 132 |
+
```py
|
| 133 |
+
training_args = TrainingArguments(per_device_train_batch_size=4, fp16=True, **default_args)
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
🤗 Accelerateを使用する場合、🤗 Accelerateの例は[このガイドのさらに後ろにあります](#using--accelerate)。
|
| 137 |
+
|
| 138 |
+
### BF16
|
| 139 |
+
|
| 140 |
+
Ampereまたはそれ以降のハードウェアにアクセスできる場合、混合精度トレーニングと評価にbf16を使用できます。bf16はfp16よりも精度が劣りますが、はるかに大きな動的範囲を持っています。fp16では、持つことができる最大の数は `65535` であり、それを超える数値はオーバーフローを引き起こします。一方、bf16の数値は `3.39e+38` のように大きく、これはfp32とほぼ同じです - どちらも数値範囲に8ビットを使用しているためです。
|
| 141 |
+
|
| 142 |
+
BF16を有効にするには、🤗 Trainerで以下のように設定します:
|
| 143 |
+
|
| 144 |
+
|
| 145 |
+
```python
|
| 146 |
+
training_args = TrainingArguments(bf16=True, **default_args)
|
| 147 |
+
```
|
| 148 |
+
|
| 149 |
+
|
| 150 |
+
### TF32
|
| 151 |
+
|
| 152 |
+
アンペアハードウェアは、tf32という特別なデータ型を使用します。これは、fp32と同じ数値範囲(8ビット)を持っていますが、23ビットの精度ではなく、10ビットの精度(fp16と同じ)を持ち、合計で19ビットしか使用しません。これは通常のfp32トレーニングおよび推論コードを使用し、tf32サポートを有効にすることで、最大3倍のスループットの向上が得られる点で「魔法のよう」です。行う必要があるのは、次のコードを追加するだけです:
|
| 153 |
+
|
| 154 |
+
```python
|
| 155 |
+
import torch
|
| 156 |
+
torch.backends.cuda.matmul.allow_tf32 = True
|
| 157 |
+
torch.backends.cudnn.allow_tf32 = True
|
| 158 |
+
```
|
| 159 |
+
|
| 160 |
+
|
| 161 |
+
使用されているGPUがアンペアシリーズであると仮定し、CUDAは可能な限りtf32を使用するように自動的に切り替えます。
|
| 162 |
+
|
| 163 |
+
[NVIDIAの研究によれば](https://developer.nvidia.com/blog/accelerating-ai-training-with-tf32-tensor-cores/)、ほとんどの機械学習トレーニングワークロードはtf32トレーニングとfp32トレーニングで同じ難解度と収束を示します。すでにfp16またはbf16混合精度を使用している場合、スループットの向上に役立つこともあります。
|
| 164 |
+
|
| 165 |
+
🤗 Trainerでこのモードを有効にすることができます:
|
| 166 |
+
|
| 167 |
+
|
| 168 |
+
```python
|
| 169 |
+
TrainingArguments(tf32=True, **default_args)
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
<Tip>
|
| 173 |
+
|
| 174 |
+
tf32は`tensor.to(dtype=torch.tf32)`を介して直接アクセスできません。これは内部のCUDAデータ型です。tf32データ型を使用するには、`torch>=1.7`が必要です。
|
| 175 |
+
|
| 176 |
+
</Tip>
|
| 177 |
+
|
| 178 |
+
tf32と他の精度に関する詳細な情報については、以下のベンチマークを参照してください:
|
| 179 |
+
[RTX-3090](https://github.com/huggingface/transformers/issues/14608#issuecomment-1004390803)および
|
| 180 |
+
[A100](https://github.com/huggingface/transformers/issues/15026#issuecomment-1004543189)。
|
| 181 |
+
|
| 182 |
+
## Flash Attention 2
|
| 183 |
+
|
| 184 |
+
transformersでFlash Attention 2統合を使用することで、トレーニングのスループットを向上させることができます。Flash Attention 2モジュールを含むモデルの読み込み方法については、[single GPU section](./perf_infer_gpu_one#Flash-Attention-2)の適切なセクションを確認して詳細を学びましょう。
|
| 185 |
+
|
| 186 |
+
## オプティマイザの選択
|
| 187 |
+
|
| 188 |
+
Transformerモデルをトレーニングするために最も一般的に使用されるオプティマイザはAdamまたはAdamW(重み減衰を伴うAdam)です。Adamは前回の勾配の移動平均を保存することで収束を達成しますが、モデルパラメータの数のオーダーの追加メモリフットプリントを追加します。これを解消するために、代替オプティマイザを使用できます。たとえば、[NVIDIA/apex](https://github.com/NVIDIA/apex)がインストールされている場合、`adamw_apex_fused`はすべてのサポートされているAdamWオプティマイザの中で最も高速なトレーニング体験を提供します。
|
| 189 |
+
|
| 190 |
+
[`Trainer`]は、直接使用できるさまざまなオプティマイザを統合しており、`adamw_hf`、`adamw_torch`、`adamw_torch_fused`、`adamw_apex_fused`、`adamw_anyprecision`、`adafactor`、または`adamw_bnb_8bit`が含まれています。サードパーティの実装を介してさらに多くのオプティマイザを追加できます。
|
| 191 |
+
|
| 192 |
+
AdamWオプティマイザの代替手段について詳しく見てみましょう:
|
| 193 |
+
1. [`Trainer`]で使用可能な`adafactor`
|
| 194 |
+
2. Trainerで使用可能な`adamw_bnb_8bit`は、デモンストレーション用に以下でサードパーティの統合が提供されています。
|
| 195 |
+
|
| 196 |
+
比較のため、3Bパラメータモデル(例:「google-t5/t5-3b」)の場合:
|
| 197 |
+
* 標準のAdamWオプティマイザは、各パラメータに8バイトを使用するため、24GBのGPUメモリが必要です(8 * 3 => 24GB)。
|
| 198 |
+
* Adafactorオプティマイザは12GB以上必要です。各パラメータにわずか4バイト以上を使用するため、4 * 3と少し余分になります。
|
| 199 |
+
* 8ビットのBNB量子化オプティマイザは、すべてのオプティマイザの状態が量子化されている場合、わずか6GBしか使用しません。
|
| 200 |
+
|
| 201 |
+
### Adafactor
|
| 202 |
+
|
| 203 |
+
Adafactorは、重み行列の各要素のために前回の平均を保存しません。代わりに、(行ごとと列ごとの平均の合計など)集
|
| 204 |
+
|
| 205 |
+
|
| 206 |
+
```py
|
| 207 |
+
training_args = TrainingArguments(per_device_train_batch_size=4, optim="adafactor", **default_args)
|
| 208 |
+
```
|
| 209 |
+
|
| 210 |
+
|
| 211 |
+
他のアプローチ(勾配蓄積、勾配チェックポイント、混合精度トレーニング)と組み合わせることで、スループットを維持しながら最大3倍の向上が見られることがあります!ただし、前述のように、Adafactorの収束性はAdamよりも悪いことがあります。
|
| 212 |
+
|
| 213 |
+
### 8ビット Adam
|
| 214 |
+
|
| 215 |
+
Adafactorのようにオプティマイザの状態を集約する代わりに、8ビットのAdamは完全な状態を保持し、それを量子化します。量子化とは、状態を低い精度で保存し、最適化のためだけに非量子化することを意味します。これは混合精度トレーニングの背後にあるアイデアと似ています。
|
| 216 |
+
|
| 217 |
+
`adamw_bnb_8bit`を使用するには、単に[`TrainingArguments`]で`optim="adamw_bnb_8bit"`を設定するだけです:
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
```py
|
| 221 |
+
training_args = TrainingArguments(per_device_train_batch_size=4, optim="adamw_bnb_8bit", **default_args)
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
ただし、デモンストレーション目的で8ビットオプティマイザをサードパーティの実装を使用することもできます。これを統合する方法を確認するためです。
|
| 225 |
+
|
| 226 |
+
まず、8ビットAdamオプティマイザを実装した`bitsandbytes`ライブラリをインストールするために、GitHub [リポジトリ](https://github.com/TimDettmers/bitsandbytes)内のインストールガイドに従ってください。
|
| 227 |
+
|
| 228 |
+
次に、オプティマイザを初期化する必要があります。これには2つのステップが含まれます:
|
| 229 |
+
* まず、モデルのパラメータを2つのグループに分けます - 重み減衰を適用するべきグループと、適用すべきでないグループです。通常、バイアスとレイヤー正規化パラメータは重み減衰されません。
|
| 230 |
+
* 次に、以前に使用したAdamWオプティマイザと同じパラメータを使用するために、いくつかの引数の調整を行います。
|
| 231 |
+
|
| 232 |
+
|
| 233 |
+
```py
|
| 234 |
+
import bitsandbytes as bnb
|
| 235 |
+
from torch import nn
|
| 236 |
+
from transformers.trainer_pt_utils import get_parameter_names
|
| 237 |
+
|
| 238 |
+
training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
|
| 239 |
+
|
| 240 |
+
decay_parameters = get_parameter_names(model, [nn.LayerNorm], ["bias", "layernorm", "rmsnorm"])
|
| 241 |
+
optimizer_grouped_parameters = [
|
| 242 |
+
{
|
| 243 |
+
"params": [p for n, p in model.named_parameters() if n in decay_parameters],
|
| 244 |
+
"weight_decay": training_args.weight_decay,
|
| 245 |
+
},
|
| 246 |
+
{
|
| 247 |
+
"params": [p for n, p in model.named_parameters() if n not in decay_parameters],
|
| 248 |
+
"weight_decay": 0.0,
|
| 249 |
+
},
|
| 250 |
+
]
|
| 251 |
+
|
| 252 |
+
optimizer_kwargs = {
|
| 253 |
+
"betas": (training_args.adam_beta1, training_args.adam_beta2),
|
| 254 |
+
"eps": training_args.adam_epsilon,
|
| 255 |
+
}
|
| 256 |
+
optimizer_kwargs["lr"] = training_args.learning_rate
|
| 257 |
+
adam_bnb_optim = bnb.optim.Adam8bit(
|
| 258 |
+
optimizer_grouped_parameters,
|
| 259 |
+
betas=(training_args.adam_beta1, training_args.adam_beta2),
|
| 260 |
+
eps=training_args.adam_epsilon,
|
| 261 |
+
lr=training_args.learning_rate,
|
| 262 |
+
)
|
| 263 |
+
```
|
| 264 |
+
|
| 265 |
+
最後に、カスタムオプティマイザを`Trainer`に引数として渡します:
|
| 266 |
+
|
| 267 |
+
|
| 268 |
+
```py
|
| 269 |
+
trainer = Trainer(model=model, args=training_args, train_dataset=ds, optimizers=(adam_bnb_optim, None))
|
| 270 |
+
```
|
| 271 |
+
|
| 272 |
+
他のアプローチ(勾配蓄積、勾配チェックポイント、混合精度トレーニング)と組み合わせることで、Adafactorの使用と同等以上の3倍のメモリ改善およびわずかに高いスループットを期待できます。
|
| 273 |
+
|
| 274 |
+
### multi_tensor
|
| 275 |
+
|
| 276 |
+
pytorch-nightlyは、多くの小さな特徴テンソルがある状況のオプティマイザを大幅に高速化するはずの`torch.optim._multi_tensor`を導入しました。これは最終的にはデフォルトになるはずですが、それを早く試してみたい場合は、このGitHub [issue](https://github.com/huggingface/transformers/issues/9965)をご覧ください。
|
| 277 |
+
|
| 278 |
+
## データの事前読み込み
|
| 279 |
+
|
| 280 |
+
優れたトレーニング速度に到達するための重要な要件の1つは、GPUが処理できる最大速度でデータを供給できる能力です。デフォルトではすべてがメインプロセスで行われ、データをディスクから十分速く読み取ることができない場合、GPUのアンダーユーティリゼーションを引き起こすボトルネックが発生する可能性があります。ボトルネックを減らすために、以下の引数を設定します:
|
| 281 |
+
|
| 282 |
+
- `DataLoader(pin_memory=True, ...)` - データをCPUのピンメモリに事前読み込みし、通常、CPUからGPUメモリへの転送がはるかに高速化されます。
|
| 283 |
+
- `DataLoader(num_workers=4, ...)` - データをより速く事前読み込みするために複数のワーカーを生成します。トレーニング中にGPUの利用状況の統計情報を確認し、100%から遠い場合、ワーカーの数を増やす実験を行ってください。もちろん、問題は他の場所にあるかもしれませんので、多くのワーカーが必ずしも性能向上につながるわけではありません。
|
| 284 |
+
|
| 285 |
+
[`Trainer`]を使用する場合、対応する[`TrainingArguments`]は`dataloader_pin_memory`(デフォルトでは`True`)および`dataloader_num_workers`(デフォルトは`0`)です。
|
| 286 |
+
|
| 287 |
+
## DeepSpeed ZeRO
|
| 288 |
+
|
| 289 |
+
DeepSpeedは、🤗 Transformersと🤗 Accelerateと統合されたオープンソースのディープラーニング最適化ライブラリです。
|
| 290 |
+
大規模なディープラーニングトレーニングの効率とスケーラビリティを向上させるために設計されたさまざまな機能と最適化を提供します。
|
| 291 |
+
|
| 292 |
+
モデルが単一のGPUに収まり、小さなバッチサイズを収めるスペースがある場合、DeepSpeedを使用する必要はありません。それはむしろ遅くなります。ただし、モデルが単一のGPUに収まらない場合、または小さなバッチを収めることができない場合、DeepSpeed ZeRO + CPU OffloadまたはNVMe Offloadを利用できます。この場合、[ライブラリを別途インストール](main_classes/deepspeed#installation)し、設定ファイルを作成し、DeepSpeedを起動するためのガイドをフォローする必要があります:
|
| 293 |
+
|
| 294 |
+
* [`Trainer`]とのDeepSpeed統合の詳細ガイドについては、[該当するドキュメンテーション](main_classes/deepspeed)を確認してください。特に、[単一GPU用のデプロイメント](main_classes/deepspeed#deployment-with-one-gpu)に関するセクションです。DeepSpeedをノートブックで使用するにはいくつかの調整が必要ですので、[該当するガイド](main_classes/deepspeed#deployment-in-notebooks)もご覧ください。
|
| 295 |
+
* 🤗 Accelerateを使用する場合は、[🤗 Accelerate DeepSpeedガイド](https://huggingface.co/docs/accelerate/en/usage_guides/deepspeed)を参照してください。
|
| 296 |
+
|
| 297 |
+
## torch.compileの使用
|
| 298 |
+
|
| 299 |
+
PyTorch 2.0は新しいコンパイル関数を導入しました。これは既存のPyTorchコードを変更する必要はありませんが、1行のコードを追加することでコードを最適化できます:`model = torch.compile(model)`。
|
| 300 |
+
|
| 301 |
+
[`Trainer`]を使用する場合、[`TrainingArguments`]内の`torch_compile`オプションを渡すだけです:
|
| 302 |
+
|
| 303 |
+
|
| 304 |
+
```python
|
| 305 |
+
training_args = TrainingArguments(torch_compile=True, **default_args)
|
| 306 |
+
```
|
| 307 |
+
|
| 308 |
+
`torch.compile`は、既存のPyTorchプログラムからグラフを自動的に作成するためにPythonのフレーム評価APIを使用します。グラフをキャプチャした後、異なるバックエンドを展開して最適化されたエンジンに変換できます。
|
| 309 |
+
詳細およびベンチマークについては、[PyTorchドキュメント](https://pytorch.org/get-started/pytorch-2.0/)を参照してください。
|
| 310 |
+
|
| 311 |
+
`torch.compile`には、オプションの依存関係を持つ成長中のバックエンドのリストがあり、`torchdynamo.list_backends()`を呼び出して確認できます。最も一般的に使用される一部のバックエンドは次のとおりです。
|
| 312 |
+
|
| 313 |
+
**デバッグ用バックエンド**:
|
| 314 |
+
* `dynamo.optimize("eager")` - 抽出されたGraphModuleを実行するためにPyTorchを使用します。これはTorchDynamoの問題をデバッグする際に非常に役立ちます。
|
| 315 |
+
* `dynamo.optimize("aot_eager")` - コンパイラーを使用しないAotAutogradを使用してAotAutogradの抽出されたフォワードおよびバックワードグラフに対して単にPyTorch eagerを使用します。これはデバッグに役立ち、高速化は期待できません。
|
| 316 |
+
|
| 317 |
+
**トレーニングおよび推論バックエンド**:
|
| 318 |
+
* `dynamo.optimize("inductor")` - TorchInductorバックエンドを使用し、AotAutogradおよびcudagraphsを活用してコード生成されたTritonカーネルを使用します [詳細はこちら](https://dev-discuss.pytorch.org/t/torchinductor-a-pytorch-native-compiler-with-define-by-run-ir-and-symbolic-shapes/747)
|
| 319 |
+
* `dynamo.optimize("nvfuser")` - nvFuser with TorchScriptを使用します。 [詳細はこちら](https://dev-discuss.pytorch.org/t/tracing-with-primitives-update-1-nvfuser-and-its-primitives/593)
|
| 320 |
+
* `dynamo.optimize("aot_nvfuser")` - nvFuser with AotAutogradを使用します。 [詳細はこちら](https://dev-discuss.pytorch.org/t/tracing-with-primitives-update-1-nvfuser-and-its-primitives/593)
|
| 321 |
+
* `dynamo.optimize("aot_cudagraphs")` - AotAutogradを使用してcudagraphsを使用します。 [詳細はこちら](https://github.com/pytorch/torchdynamo/pull/757)
|
| 322 |
+
|
| 323 |
+
**推論専用バックエンド**:
|
| 324 |
+
* `dynamo.optimize("ofi")` - Torchscriptの`optimize_for_inference`を使用します。 [詳細はこちら](https://pytorch.org/docs/stable/generated/torch.jit.optimize_for_inference.html)
|
| 325 |
+
* `dynamo.optimize("fx2trt")` - Nvidia TensorRTを使用した推論の最適化にNvidia TensorRTを使用します。 [詳細はこちら](https://pytorch.org/TensorRT/tutorials/getting_started_with_fx_path.html)
|
| 326 |
+
* `dynamo.optimize("onnxrt")` - CPU/GPUでの推論にONNX Runtimeを使用します。 [詳細はこちら](https://onnxruntime.ai/)
|
| 327 |
+
* `dynamo.optimize("ipex")` - CPUでの推論にIPEXを使用します。 [詳細はこちら](https://github.com/intel/intel-extension-for-pytorch)
|
| 328 |
+
|
| 329 |
+
🤗 Transformersを使用した`torch.compile`の使用例については、この[ブログ記事](https://www.philschmid.de/getting-started-pytorch-2-0-transformers)をご覧ください。
|
| 330 |
+
|
| 331 |
+
## Using 🤗 Accelerate
|
| 332 |
+
|
| 333 |
+
[🤗 Accelerate](https://huggingface.co/docs/accelerate/index)を使用すると、上記の方法を使用しながらトレーニングループを完全に制御でき、基本的には純粋なPyTorchでループを書くことができます。
|
| 334 |
+
|
| 335 |
+
次に、[`TrainingArguments`]内で方法を組み合わせた場合を想
|
| 336 |
+
|
| 337 |
+
```py
|
| 338 |
+
training_args = TrainingArguments(
|
| 339 |
+
per_device_train_batch_size=1,
|
| 340 |
+
gradient_accumulation_steps=4,
|
| 341 |
+
gradient_checkpointing=True,
|
| 342 |
+
fp16=True,
|
| 343 |
+
**default_args,
|
| 344 |
+
)
|
| 345 |
+
```
|
| 346 |
+
|
| 347 |
+
🤗 Accelerateを使用した完全なトレーニングループの例は、ほんの数行のコードです:
|
| 348 |
+
|
| 349 |
+
```py
|
| 350 |
+
from accelerate import Accelerator
|
| 351 |
+
from torch.utils.data.dataloader import DataLoader
|
| 352 |
+
|
| 353 |
+
dataloader = DataLoader(ds, batch_size=training_args.per_device_train_batch_size)
|
| 354 |
+
|
| 355 |
+
if training_args.gradient_checkpointing:
|
| 356 |
+
model.gradient_checkpointing_enable()
|
| 357 |
+
|
| 358 |
+
accelerator = Accelerator(fp16=training_args.fp16)
|
| 359 |
+
model, optimizer, dataloader = accelerator.prepare(model, adam_bnb_optim, dataloader)
|
| 360 |
+
|
| 361 |
+
model.train()
|
| 362 |
+
for step, batch in enumerate(dataloader, start=1):
|
| 363 |
+
loss = model(**batch).loss
|
| 364 |
+
loss = loss / training_args.gradient_accumulation_steps
|
| 365 |
+
accelerator.backward(loss)
|
| 366 |
+
if step % training_args.gradient_accumulation_steps == 0:
|
| 367 |
+
optimizer.step()
|
| 368 |
+
optimizer.zero_grad()
|
| 369 |
+
```
|
| 370 |
+
|
| 371 |
+
まず、データセットを[`DataLoader`](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)でラップします。
|
| 372 |
+
次に、モデルの[`~PreTrainedModel.gradient_checkpointing_enable`]メソッドを呼び出すことで勾配チェックポイントを有効にできます。
|
| 373 |
+
[`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator)を初期化する際に、混合精度トレーニングを使用するかどうかを[`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare)の呼び出しで指定し、複数のGPUを使用する場合、`prepare`の間にデータローダーもワーカー間で分散されます。同じ[8ビットオプティマイザ](#8-bit-adam)を前の例から使用します。
|
| 374 |
+
|
| 375 |
+
最後に、主要なトレーニングループを追加できます。`backward`の呼び出しは🤗 Accelerateによって処理されることに注意してください。また、勾配の蓄積がどのように機能するかも確認できます。損失を正規化しているため、蓄積の最後に平均を得て、十分なステップがあると最適化が実行されます。
|
| 376 |
+
|
| 377 |
+
これらの最適化技術を🤗 Accelerateを使用して実装するのは、わずかなコード行で行うことができ、トレーニングループの柔軟性が向上します。すべての機能の詳細については、[Accelerateのドキュメント](https://huggingface.co/docs/accelerate/index)を参照してください。
|
| 378 |
+
|
| 379 |
+
## Efficient Software Prebuilds
|
| 380 |
+
|
| 381 |
+
PyTorchの[pipとcondaビルド](https://pytorch.org/get-started/locally/#start-locally)は、PyTorchを実行するのに十分なcudaツールキットで事前にビルドされていますが、cuda拡張をビルドする必要がある場合には不十分です。
|
| 382 |
+
|
| 383 |
+
時折、追加の努力が必要な場合があります。たとえば、事前にコンパイルされていない`apex`などのライブラリを使用している場合です。また、システム全体で適切なcudaツールキットをインストールする方法を見つけることが難しい場合もあります。
|
| 384 |
+
これらのシナリオに対処するために、PyTorchとNVIDIAはcuda拡張がすでに事前にビルドされているNGC dockerコンテナの新しいバージョンをリリースしました。プログラムをインストールするだけで、そのまま実行できます。
|
| 385 |
+
|
| 386 |
+
このアプローチは、PyTorchのソースを調整したり、新しいカスタマイズされたビルドを作成したりしたい場合にも役立ちます。
|
| 387 |
+
欲しいdockerイメージバージョンを見つけるには、まず[PyTorchのリリースノート](https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/)から始め、最新の月次リリースのいずれかを選択します。希望のリリースのリリースノートに移動し、環境のコンポーネントが必要なものと一致していることを確認します(NVIDIA Driverの要件も含む!)、その文書の一番上に行き、対応するNGCページに移動します。なぜかわからない場合は、[すべてのPyTorch NGCイメージのインデックス](https://ngc.nvidia.com/catalog/containers/nvidia:pytorch)です。
|
| 388 |
+
|
| 389 |
+
次に、dockerイメージをダウンロードして展開する手順に従います。
|
| 390 |
+
|
| 391 |
+
## Mixture of Experts
|
| 392 |
+
|
| 393 |
+
最近の論文によれば、Transformerモデルに専門家の混合(MoE)を統合することで、トレーニング速度が4〜5倍向上し、推論も高速化されることが報告されています。
|
| 394 |
+
|
| 395 |
+
より多くのパラメータがより良いパフォーマンスにつながることがわかっているため、この技術はトレーニングコストを増やすことなくパラメータの数を桁違いに増やすことを可能にします。
|
| 396 |
+
|
| 397 |
+
このアプローチでは、他のFFN層の代わりにMoE層が配置され、各専門家をトークンの位置に応じてバランスよくトレーニングするゲート関数で構成��れます。
|
| 398 |
+
|
| 399 |
+
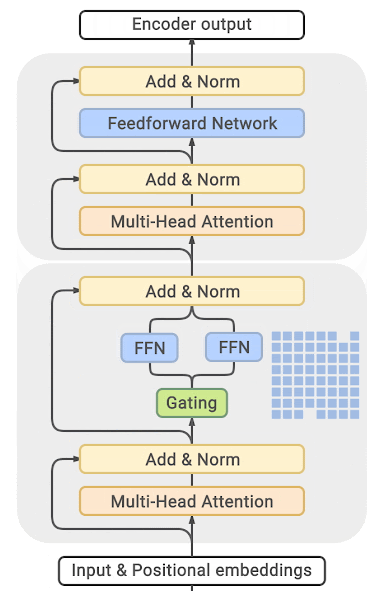
|
| 400 |
+
|
| 401 |
+
(出典: [GLAM](https://ai.googleblog.com/2021/12/more-efficient-in-context-learning-with.html))
|
| 402 |
+
|
| 403 |
+
このアプローチの主な欠点は、GPUメモリをほぼ桁違いに多く必要とすることです。メモリ要件がはるかに大きいことがそのまま反映されます。より高いメモリ要件を克服する方法については、さまざまな蒸留およびアプローチが提案されています。
|
| 404 |
+
|
| 405 |
+
ただし、直接のトレードオフがあります。数人の専門家を使用してベースモデルを2〜3倍小さくすることで、5倍小さなモデルにし、トレーニング速度を適度に向上させ、メモリ要件を適度に増やすことができます。
|
| 406 |
+
|
| 407 |
+
関連するほとんどの論文および実装はTensorflow/TPUを中心に構築されています。
|
| 408 |
+
|
| 409 |
+
- [GShard: Conditional Computation and Automatic Shardingを活用した巨大モデルのスケーリング](https://arxiv.org/abs/2006.16668)
|
| 410 |
+
- [Switch Transformers: シンプルで効率的なスパース性を備えたトリリオンパラメータモデルへのスケーリング](https://arxiv.org/abs/2101.03961)
|
| 411 |
+
- [GLaM: Generalist Language Model (GLaM)](https://ai.googleblog.com/2021/12/more-efficient-in-context-learning-with.html)
|
| 412 |
+
|
| 413 |
+
PytorchにはDeepSpeedが構築したものもあります: [DeepSpeed-MoE: Advancing Mixture-of-Experts Inference and Training to Power Next-Generation AI Scale](https://arxiv.org/abs/2201.05596)、[Mixture of Experts](https://www.deepspeed.ai/tutorials/mixture-of-experts/) - ブログ記事: [1](https://www.microsoft.com/en-us/research/blog/deepspeed-powers-8x-larger-moe-model-training-with-high-performance/)、[2](https://www.microsoft.com/en-us/research/publication/scalable-and-efficient-moe-training-for-multitask-multilingual-models/)、大規模なTransformerベースの自然言語生成モデルの具体的な展開については、[ブログ記事](https://www.deepspeed.ai/2021/12/09/deepspeed-moe-nlg.html)、[Megatron-Deepspeedブランチ](https://github.com/microsoft/Megatron-DeepSpeed/tree/moe-training)を参照してください。
|
| 414 |
+
|
| 415 |
+
|
| 416 |
+
## PyTorchネイティブアテンションとFlash Attentionの使用
|
| 417 |
+
|
| 418 |
+
PyTorch 2.0では、ネイティブの[`torch.nn.functional.scaled_dot_product_attention`](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html)(SDPA)がリリースされ、[メモリ効率の高いアテンション](https://arxiv.org/abs/2112.05682)や[フラッシュアテンション](https://arxiv.org/abs/2205.14135)などの融合されたGPUカーネルの使用を可能にします。
|
| 419 |
+
|
| 420 |
+
[`optimum`](https://github.com/huggingface/optimum)パッケージをインストールした後、関連する内部モジュールを置き換えて、PyTorchのネイティブアテンションを使用できます。以下のように設定します:
|
| 421 |
+
|
| 422 |
+
|
| 423 |
+
```python
|
| 424 |
+
model = model.to_bettertransformer()
|
| 425 |
+
```
|
| 426 |
+
|
| 427 |
+
変換後、通常通りモデルをトレーニングしてください。
|
| 428 |
+
|
| 429 |
+
<Tip warning={true}>
|
| 430 |
+
|
| 431 |
+
PyTorchネイティブの`scaled_dot_product_attention`演算子は、`attention_mask`が提供されていない場合にのみFlash Attentionにディスパッチできます。
|
| 432 |
+
|
| 433 |
+
デフォルトでは、トレーニングモードでBetterTransformer統合はマスクサポートを削除し、バッチトレーニングにパディングマスクが必要ないトレーニングにしか使用できません。これは、例えばマスク言語モデリングや因果言語モデリングのような、バッチトレーニングにパディングマスクが不要なトレーニングの場合に該当します。BetterTransformerはパディングマスクが必要なタスクに対するモデルの微調整には適していません。
|
| 434 |
+
|
| 435 |
+
</Tip>
|
| 436 |
+
|
| 437 |
+
SDPAを使用したアクセラレーションとメモリの節約について詳しく知りたい場合は、この[ブログ記事](https://pytorch.org/blog/out-of-the-box-acceleration/)をチェックしてください。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_special.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Training on Specialized Hardware
|
| 17 |
+
|
| 18 |
+
<Tip>
|
| 19 |
+
|
| 20 |
+
注意: [単一GPUセクション](perf_train_gpu_one)で紹介されたほとんどの戦略(混合精度トレーニングや勾配蓄積など)および[マルチGPUセクション](perf_train_gpu_many)は一般的なトレーニングモデルに適用される汎用的なものですので、このセクションに入る前にそれを確認してください。
|
| 21 |
+
|
| 22 |
+
</Tip>
|
| 23 |
+
|
| 24 |
+
このドキュメントは、専用ハードウェアでトレーニングする方法に関する情報を近日中に追加予定です。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_tpu.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Training on TPUs
|
| 17 |
+
|
| 18 |
+
<Tip>
|
| 19 |
+
|
| 20 |
+
注意: [シングルGPUセクション](perf_train_gpu_one)で紹介されているほとんどの戦略(混合精度トレーニングや勾配蓄積など)および[マルチGPUセクション](perf_train_gpu_many)は一般的なモデルのトレーニングに適用できますので、このセクションに入る前にそれを確認してください。
|
| 21 |
+
|
| 22 |
+
</Tip>
|
| 23 |
+
|
| 24 |
+
このドキュメントは、TPUでのトレーニング方法に関する情報をまもなく追加いたします。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perf_train_tpu_tf.md
ADDED
|
@@ -0,0 +1,168 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
|
| 11 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 12 |
+
rendered properly in your Markdown viewer.
|
| 13 |
+
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# Training on TPU with TensorFlow
|
| 17 |
+
|
| 18 |
+
<Tip>
|
| 19 |
+
|
| 20 |
+
詳細な説明が不要で、単にTPUのコードサンプルを入手してトレーニングを開始したい場合は、[私たちのTPUの例のノートブックをチェックしてください!](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)
|
| 21 |
+
|
| 22 |
+
</Tip>
|
| 23 |
+
|
| 24 |
+
### What is a TPU?
|
| 25 |
+
|
| 26 |
+
TPUは**Tensor Processing Unit(テンソル処理ユニット)**の略です。これらはGoogleが設計したハードウェアで、ニューラルネットワーク内のテンソル計算を大幅に高速化するために使用されます。これはGPUのようなものです。ネットワークのトレーニングと推論の両方に使用できます。一般的にはGoogleのクラウドサービスを介してアクセスされますが、Google ColabとKaggle Kernelsを通じても無料で小規模のTPUに直接アクセスできます。
|
| 27 |
+
|
| 28 |
+
[🤗 TransformersのすべてのTensorFlowモデルはKerasモデルです](https://huggingface.co/blog/tensorflow-philosophy)ので、この文書のほとんどの方法は一般的にKerasモデル用のTPUトレーニングに適用できます!ただし、TransformersとDatasetsのHuggingFaceエコシステム(hug-o-system?)に固有のポイントもいくつかあり、それについては適用するときにそれを示します。
|
| 29 |
+
|
| 30 |
+
### What kinds of TPU are available?
|
| 31 |
+
|
| 32 |
+
新しいユーザーは、さまざまなTPUとそのアクセス方法に関する幅広い情報によく混乱します。理解するための最初の重要な違いは、**TPUノード**と**TPU VM**の違いです。
|
| 33 |
+
|
| 34 |
+
**TPUノード**を使用すると、事実上リモートのTPUに間接的にアクセスします。別個のVMが必要で、ネットワークとデータパイプラインを初期化し、それらをリモートノードに転送します。Google ColabでTPUを使用すると、**TPUノード**スタイルでアクセスしています。
|
| 35 |
+
|
| 36 |
+
TPUノードを使用すると、それに慣れていない人々にはかなり予期しない動作が発生することがあります!特に、TPUはPythonコードを実行しているマシンと物理的に異なるシステムに配置されているため、データはローカルマシンにローカルで格納されているデータパイプラインが完全に失敗します。代わりに、データはGoogle Cloud Storageに格納する必要があります。ここでデータパイプラインはリモートのTPUノードで実行されている場合でも、データにアクセスできます。
|
| 37 |
+
|
| 38 |
+
<Tip>
|
| 39 |
+
|
| 40 |
+
すべてのデータを`np.ndarray`または`tf.Tensor`としてメモリに収めることができる場合、ColabまたはTPUノードを使用している場合でも、データをGoogle Cloud Storageにアップロードせずに`fit()`でトレーニングできます。
|
| 41 |
+
|
| 42 |
+
</Tip>
|
| 43 |
+
|
| 44 |
+
<Tip>
|
| 45 |
+
|
| 46 |
+
**🤗 Hugging Face固有のヒント🤗:** TFコードの例でよく見るであろう`Dataset.to_tf_dataset()`とその高レベルのラッパーである`model.prepare_tf_dataset()`は、TPUノードで失敗します。これは、`tf.data.Dataset`を作成しているにもかかわらず、それが「純粋な」`tf.data`パイプラインではなく、`tf.numpy_function`または`Dataset.from_generator()`を使用して基盤となるHuggingFace `Dataset`からデータをストリームで読み込むことからです。このHuggingFace `Dataset`はローカルディスク上のデータをバックアップしており、リモートTPUノードが読み取ることができないためです。
|
| 47 |
+
|
| 48 |
+
</Tip>
|
| 49 |
+
|
| 50 |
+
TPUにアクセスする第二の方法は、**TPU VM**を介してです。TPU VMを使用する場合、TPUが接続されているマシンに直接接続します。これはGPU VMでトレーニングを行うのと同様です。TPU VMは一般的にデータパイプラインに関しては特に作業がしやすく、上記のすべての警告はTPU VMには適用されません!
|
| 51 |
+
|
| 52 |
+
これは主観的な文書ですので、こちらの意見です:**可能な限りTPUノードの使用を避けてください。** TPU VMよりも混乱しやすく、デバッグが難しいです。将来的にはサポートされなくなる可能性もあります - Googleの最新のTPUであるTPUv4は、TPU VMとしてのみアクセスできるため、TPUノードは将来的には「レガシー」のアクセス方法になる可能性が高いです。ただし、無料でTPUにアクセスできるのはColabとKaggle Kernelsの場合があります。その場合、どうしても使用しなければならない場合の取り扱い方法を説明しようとします!詳細は[TPUの例のノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)で詳細な説明を確認してください。
|
| 53 |
+
|
| 54 |
+
### What sizes of TPU are available?
|
| 55 |
+
|
| 56 |
+
単一のTPU(v2-8/v3-8/v4-8)は8つのレプリカを実行します。TPUは数百から数千のレプリカを同時に実行できる**ポッド**に存在します。単一のTPUよりも多くのTPUを使用するが、ポッド全体ではない場合(たとえばv3-32)、TPUフリートは**ポッドスライス**として参照されます。
|
| 57 |
+
|
| 58 |
+
Colabを介して無料のTPUにアクセスする場合、通常は単一のv2-8 TPUが提供されます。
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
### I keep hearing about this XLA thing. What’s XLA, and how does it relate to TPUs?
|
| 62 |
+
|
| 63 |
+
XLAは、TensorFlowとJAXの両方で使用される最適化コンパイラです。JAXでは唯一のコンパイラであり、TensorFlowではオプションですが(しかしTPUでは必須です!)、Kerasモデルをトレーニングする際に`model.compile()`に引数`jit_compile=True`を渡すことで最も簡単に有効にできます。エラーが発生せず、パフォーマンスが良好であれば、それはTPUに移行する準備が整った良い兆候です!
|
| 64 |
+
|
| 65 |
+
TPU上でのデバッグは一般的にCPU/GPUよりも少し難しいため、TPUで試す前にまずCPU/GPUでXLAを使用してコードを実行することをお勧めします。もちろん、長時間トレーニングする必要はありません。モデルとデータパイプラインが期待通りに動作するかを確認するための数ステップだけです。
|
| 66 |
+
|
| 67 |
+
<Tip>
|
| 68 |
+
|
| 69 |
+
XLAコンパイルされたコードは通常高速です。したがって、TPUで実行する予定がない場合でも、`jit_compile=True`を追加することでパフォーマンスを向上させることができます。ただし、以下のXLA互換性に関する注意事項に注意してください!
|
| 70 |
+
|
| 71 |
+
</Tip>
|
| 72 |
+
|
| 73 |
+
<Tip warning={true}>
|
| 74 |
+
|
| 75 |
+
**苦い経験から生まれたヒント:** `jit_compile=True`を使用することは、CPU/GPUコードがXLA互換であることを確認し、速度を向上させる良い方法ですが、実際にTPUでコードを実行する際には多くの問題を引き起こす可能性があります。 XLAコンパイルはTPU上で暗黙的に行われるため、実際にコードをTPUで実行する前にその行を削除することを忘れないでください!
|
| 76 |
+
|
| 77 |
+
</Tip>
|
| 78 |
+
|
| 79 |
+
### How do I make my model XLA compatible?
|
| 80 |
+
|
| 81 |
+
多くの場合、コードはすでにXLA互換かもしれません!ただし、XLAでは動作する通常のTensorFlowでも動作しないいくつかの要素があります。以下に、3つの主要なルールにまとめています:
|
| 82 |
+
|
| 83 |
+
<Tip>
|
| 84 |
+
|
| 85 |
+
**🤗 HuggingFace固有のヒント🤗:** TensorFlowモデルと損失関数をXLA互換に書き直すために多くの努力を払っています。通常、モデルと損失関数はデフォルトでルール#1と#2に従っているため、`transformers`モデルを使用している場合はこれらをスキップできます。ただし、独自のモデルと損失関数を記述する場合は、これらのルールを忘れないでください!
|
| 86 |
+
|
| 87 |
+
</Tip>
|
| 88 |
+
|
| 89 |
+
#### XLA Rule #1: Your code cannot have “data-dependent conditionals”
|
| 90 |
+
|
| 91 |
+
これは、任意の`if`ステートメントが`tf.Tensor`内の値に依存していない必要があることを意味します。例えば、次のコードブロックはXLAでコンパイルできません!
|
| 92 |
+
|
| 93 |
+
```python
|
| 94 |
+
if tf.reduce_sum(tensor) > 10:
|
| 95 |
+
tensor = tensor / 2.0
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
これは最初は非常に制限的に思えるかもしれませんが、ほとんどのニューラルネットコードはこれを行う必要はありません。通常、この制約を回避するために`tf.cond`を使用するか(ドキュメントはこちらを参照)、条件を削除して代わりに指示変数を使用したりすることができます。次のように:
|
| 99 |
+
|
| 100 |
+
```python
|
| 101 |
+
sum_over_10 = tf.cast(tf.reduce_sum(tensor) > 10, tf.float32)
|
| 102 |
+
tensor = tensor / (1.0 + sum_over_10)
|
| 103 |
+
```
|
| 104 |
+
|
| 105 |
+
このコードは、上記のコードとまったく同じ効果を持っていますが、条件を回避することで、XLAで問題なくコンパイルできることを確認します!
|
| 106 |
+
|
| 107 |
+
#### XLA Rule #2: Your code cannot have “data-dependent shapes”
|
| 108 |
+
|
| 109 |
+
これは、コード内のすべての `tf.Tensor` オブジェクトの形状が、その値に依存しないことを意味します。たとえば、`tf.unique` 関数はXLAでコン���イルできないので、このルールに違反します。なぜなら、これは入力 `Tensor` の一意の値の各インスタンスを含む `tensor` を返すためです。この出力の形状は、入力 `Tensor` の重複具合によって異なるため、XLAはそれを処理しないことになります!
|
| 110 |
+
|
| 111 |
+
一般的に、ほとんどのニューラルネットワークコードはデフォルトでルール#2に従います。ただし、いくつかの一般的なケースでは問題が発生することがあります。非常に一般的なケースの1つは、**ラベルマスキング**を使用する場合です。ラベルを無視して損失を計算する場所を示すために、ラベルを負の値に設定する方法です。NumPyまたはPyTorchのラベルマスキングをサポートする損失関数を見ると、次のような[ブールインデックス](https://numpy.org/doc/stable/user/basics.indexing.html#boolean-array-indexing)を使用したコードがよく見られます:
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
```python
|
| 115 |
+
label_mask = labels >= 0
|
| 116 |
+
masked_outputs = outputs[label_mask]
|
| 117 |
+
masked_labels = labels[label_mask]
|
| 118 |
+
loss = compute_loss(masked_outputs, masked_labels)
|
| 119 |
+
mean_loss = torch.mean(loss)
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
このコードはNumPyやPyTorchでは完全に機能しますが、XLAでは動作しません!なぜなら、`masked_outputs`と`masked_labels`の形状はマスクされた位置の数に依存するため、これは**データ依存の形状**になります。ただし、ルール#1と同様に、このコードを書き直して、データ依存の形状なしでまったく同じ出力を生成できることがあります。
|
| 123 |
+
|
| 124 |
+
|
| 125 |
+
```python
|
| 126 |
+
label_mask = tf.cast(labels >= 0, tf.float32)
|
| 127 |
+
loss = compute_loss(outputs, labels)
|
| 128 |
+
loss = loss * label_mask # Set negative label positions to 0
|
| 129 |
+
mean_loss = tf.reduce_sum(loss) / tf.reduce_sum(label_mask)
|
| 130 |
+
```
|
| 131 |
+
|
| 132 |
+
|
| 133 |
+
ここでは、データ依存の形状を避けるために、各位置で損失を計算してから、平均を計算する際に分子と分母の両方でマスクされた位置をゼロ化する方法を紹介します。これにより、最初のアプローチとまったく同じ結果が得られますが、XLA互換性を維持します。注意点として、ルール#1と同じトリックを使用します - `tf.bool`を`tf.float32`に変換して指標変数として使用します。これは非常に便利なトリックですので、自分のコードをXLAに変換する必要がある場合には覚えておいてください!
|
| 134 |
+
|
| 135 |
+
#### XLA Rule #3: XLA will need to recompile your model for every different input shape it sees
|
| 136 |
+
|
| 137 |
+
これは重要なルールです。これはつまり、入力形状が非常に変動的な場合、XLA はモデルを何度も再コンパイルする必要があるため、大きなパフォーマンスの問題が発生する可能性があるということです。これは NLP モデルで一般的に発生し、トークナイズ後の入力テキストの長さが異なる場合があります。他のモダリティでは、静的な形状が一般的であり、このルールはほとんど問題になりません。
|
| 138 |
+
|
| 139 |
+
ルール#3を回避する方法は何でしょうか?鍵は「パディング」です - すべての入力を同じ長さにパディングし、次に「attention_mask」を使用することで、可変形状と同じ結果を得ることができますが、XLA の問題は発生しません。ただし、過度のパディングも深刻な遅延を引き起こす可能性があります - データセット全体で最大の長さにすべてのサンプルをパディングすると、多くの計算とメモリを無駄にする可能性があります!
|
| 140 |
+
|
| 141 |
+
この問題には完璧な解決策はありませんが、いくつかのトリックを試すことができます。非常に便利なトリックの1つは、**バッチのサンプルを32または64トークンの倍数までパディングする**ことです。これにより、トークン数がわずかに増加するだけで、すべての入力形状が32または64の倍数である必要があるため、一意の入力形状の数が大幅に減少します。一意の入力形状が少ないと、XLA の再コンパイルが少なくなります!
|
| 142 |
+
|
| 143 |
+
<Tip>
|
| 144 |
+
|
| 145 |
+
**🤗 HuggingFace に関する具体的なヒント🤗:** 弊社のトークナイザーとデータコレクターには、ここで役立つメソッドがあります。トークナイザーを呼び出す際に `padding="max_length"` または `padding="longest"` を使用して、パディングされたデータを出力するように設定できます。トークナイザーとデータコレクターには、一意の入力形状の数を減らすのに役立つ `pad_to_multiple_of` 引数もあります!
|
| 146 |
+
|
| 147 |
+
</Tip>
|
| 148 |
+
|
| 149 |
+
### How do I actually train my model on TPU?
|
| 150 |
+
|
| 151 |
+
一度トレーニングが XLA 互換性があることを確認し、(TPU Node/Colab を使用する場合は)データセッ���が適切に準備されている場合、TPU 上で実行することは驚くほど簡単です!コードを変更する必要があるのは、いくつかの行を追加して TPU を初期化し、モデルとデータセットが `TPUStrategy` スコープ内で作成されるようにすることだけです。これを実際に見るには、[TPU のサンプルノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)をご覧ください!
|
| 152 |
+
|
| 153 |
+
### Summary
|
| 154 |
+
|
| 155 |
+
ここでは多くの情報が提供されましたので、TPU でモデルをトレーニングする際に以下のチェックリストを使用できます:
|
| 156 |
+
|
| 157 |
+
- コードが XLA の三つのルールに従っていることを確認します。
|
| 158 |
+
- CPU/GPU で `jit_compile=True` を使用してモデルをコンパイルし、XLA でトレーニングできることを確認します。
|
| 159 |
+
- データセットをメモリに読み込むか、TPU 互換のデータセット読み込みアプローチを使用します([ノートブックを参照](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb))。
|
| 160 |
+
- コードを Colab(アクセラレータを「TPU」に設定)または Google Cloud の TPU VM に移行します。
|
| 161 |
+
- TPU 初期化コードを追加します([ノートブックを参照](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb))。
|
| 162 |
+
- `TPUStrategy` を作成し、データセットの読み込みとモデルの作成が `strategy.scope()` 内で行われることを確認します([ノートブックを参照](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb))。
|
| 163 |
+
- TPU に移行する際に `jit_compile=True` を外すのを忘れないでください!
|
| 164 |
+
- 🙏🙏🙏🥺🥺🥺
|
| 165 |
+
- `model.fit()` を呼び出します。
|
| 166 |
+
- おめでとうございます!
|
| 167 |
+
|
| 168 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/performance.md
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!---
|
| 2 |
+
Copyright 2021 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
you may not use this file except in compliance with the License.
|
| 6 |
+
You may obtain a copy of the License at
|
| 7 |
+
|
| 8 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
|
| 10 |
+
Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
See the License for the specific language governing permissions and
|
| 14 |
+
limitations under the License.
|
| 15 |
+
|
| 16 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 17 |
+
rendered properly in your Markdown viewer.
|
| 18 |
+
|
| 19 |
+
-->
|
| 20 |
+
|
| 21 |
+
# Performance and Scalability
|
| 22 |
+
|
| 23 |
+
大規模なトランスフォーマーモデルのトレーニングおよび本番環境への展開はさまざまな課題を提起します。
|
| 24 |
+
トレーニング中には、モデルが利用可能なGPUメモリよりも多くを必要としたり、トレーニング速度が遅かったりする可能性があります。
|
| 25 |
+
デプロイフェーズでは、モデルが本番環境で必要なスループットを処理するのに苦労することがあります。
|
| 26 |
+
|
| 27 |
+
このドキュメンテーションは、これらの課題を克服し、ユースケースに最適な設定を見つけるのに役立つことを目的としています。
|
| 28 |
+
ガイドはトレーニングと推論のセクションに分かれており、それぞれ異なる課題と解決策が存在します。
|
| 29 |
+
各セクション内には、トレーニング用のシングルGPU対マルチGPU、推論用のCPU対GPUなど、異なるハードウェア構成用の別々のガイドが用意されています。
|
| 30 |
+
|
| 31 |
+
このドキュメントを出発点として、シナリオに合った方法に進むための情報源としてご利用ください。
|
| 32 |
+
|
| 33 |
+
## Training
|
| 34 |
+
|
| 35 |
+
大規模なトランスフォーマーモデルを効率的にトレーニングするには、GPUやTPUなどのアクセラレータが必要です。
|
| 36 |
+
最も一般的なケースは、シングルGPUがある場合です。シングルGPUでのトレーニング効率を最適化するための一般的なアプローチを学ぶには、以下を参照してください。
|
| 37 |
+
|
| 38 |
+
* [シングルGPUでの効率的なトレーニングのための方法とツール](perf_train_gpu_one): GPUメモリの効果的な利用、トレーニングの高速化などを支援する共通のアプローチを学ぶためにここから始めてください。
|
| 39 |
+
* [マルチGPUトレーニングセクション](perf_train_gpu_many): マルチGPU環境に適用されるデータ、テンソル、パイプライン並列性など、さらなる最適化方法について詳細に学びます。
|
| 40 |
+
* [CPUトレーニングセクション](perf_train_cpu): CPU上での混合精度トレーニングについて学びます。
|
| 41 |
+
* [複数CPUでの効率的なトレーニング](perf_train_cpu_many): 分散CPUトレーニングについて学びます。
|
| 42 |
+
* [TensorFlowでTPUを使用したトレーニング](perf_train_tpu_tf): TPUに慣れていない場合は、TPUでのトレーニングとXLAの使用についてのセクションを参照してください。
|
| 43 |
+
* [トレーニングのためのカスタムハードウェア](perf_hardware): 独自のディープラーニング環境を構築する際のヒントやトリックを見つけます。
|
| 44 |
+
* [Trainer APIを使用したハイパーパラメーター検索](hpo_train)
|
| 45 |
+
|
| 46 |
+
## Inference
|
| 47 |
+
|
| 48 |
+
本番環境で大規模なモデルを効率的に推論することは、それらをトレーニングすることと同じくらい難しいことがあります。
|
| 49 |
+
以下のセクションでは、CPUおよびシングル/マルチGPU環境で推論を実行する手順について説明します。
|
| 50 |
+
|
| 51 |
+
* [シングルCPUでの推論](perf_infer_cpu)
|
| 52 |
+
* [シングルGPUでの推論](perf_infer_gpu_one)
|
| 53 |
+
* [マルチGPU推論](perf_infer_gpu_many)
|
| 54 |
+
* [TensorFlowモデルのXLA統合](tf_xla)
|
| 55 |
+
|
| 56 |
+
## Training and inference
|
| 57 |
+
|
| 58 |
+
モデルをトレーニングするか、それを使用して推論を実行するかに関係なく適用されるテクニック、ヒント、トリックがここにあります。
|
| 59 |
+
|
| 60 |
+
* [大規模モデルのインスタンス化](big_models)
|
| 61 |
+
* [パフォーマンスの問題のトラブルシューティング](debugging)
|
| 62 |
+
|
| 63 |
+
## Contribute
|
| 64 |
+
|
| 65 |
+
このドキュメントはまだ完全ではなく、さらに追加する必要がある項目がたくさんあります。
|
| 66 |
+
追加や訂正が必要な場合は、遠慮せずにPRをオープンするか、詳細を議論するためにIssueを開始してください。
|
| 67 |
+
|
| 68 |
+
AがBよりも優れているという貢献を行う際には、再現可能なベンチマークやその情報の出典へのリンクを含めてみてください(あなた自身の情報である場合を除く)。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/perplexity.md
ADDED
|
@@ -0,0 +1,116 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Perplexity of fixed-length models
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
パープレキシティ(PPL)は言語モデルの評価に最も一般的な指標の1つです。深入りする前に、この指標は特に古典的な言語モデル(時にはオートレグレッシブまたは因果言語モデルとも呼ばれる)に適用され、BERTなどのマスクされた言語モデルには適していないことに注意すべきです(モデルの概要を参照してください[モデルの概要](model_summary))。
|
| 22 |
+
|
| 23 |
+
パープレキシティは、シーケンスの指数平均負の対数尤度として定義されます。トークン化されたシーケンス \\(X = (x_0, x_1, \dots, x_t)\\) がある場合、\\(X\\) のパープレキシティは次のように表されます。
|
| 24 |
+
|
| 25 |
+
$$\text{PPL}(X) = \exp \left\{ {-\frac{1}{t}\sum_i^t \log p_\theta (x_i|x_{<i}) } \right\}$$
|
| 26 |
+
|
| 27 |
+
ここで、\\(\log p_\theta (x_i|x_{<i})\\) はモデルによる前のトークン \\(x_{<i}\\) に対する第iトークンの対数尤度です。直感的には、これはモデルがコーパス内の指定されたトークンの集合に対して一様に予測する能力の評価と考えることができます。重要なのは、これによってトークン化手法がモデルのパープレキシティに直接影響を与えるため、異なるモデルを比較する際には常に考慮すべきであるということです。
|
| 28 |
+
|
| 29 |
+
これはまた、データとモデルの予測との間の交差エントロピーの指数化と同等です。パープレキシティおよびビット・パー・キャラクター(BPC)とデータ圧縮との関係についての詳細な情報については、この[素晴らしい The Gradient のブログ記事](https://thegradient.pub/understanding-evaluation-metrics-for-language-models/)を参照してください。
|
| 30 |
+
|
| 31 |
+
## Calculating PPL with fixed-length models
|
| 32 |
+
|
| 33 |
+
モデルのコンテキストサイズに制約がない場合、モデルのパープレキシティを評価するためには、シーケンスを自己回帰的に因子分解し、各ステップで前のサブシーケンスに条件を付けることで計算します。以下に示すように。
|
| 34 |
+
|
| 35 |
+
<img width="600" alt="完全なコンテキスト長のシーケンスの分解" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/ppl_full.gif"/>
|
| 36 |
+
|
| 37 |
+
しかし、通常、近似モデルを使用する場合、モデルが処理できるトークン数に制約があります。例えば、最大の[GPT-2](model_doc/gpt2)のバージョンは1024トークンの固定長を持っているため、1024よりも大きい \\(t\\) に対して \\(p_\theta(x_t|x_{<t})\\) を直接計算することはできません。
|
| 38 |
+
|
| 39 |
+
代わりに、通常、シーケンスはモデルの最大入力サイズに等しいサブシーケンスに分割されます。モデルの最大入力サイズが \\(k\\) の場合、トークン \\(x_t\\) の尤度を近似するには、完全なコンテキストではなく、それを先行する \\(k-1\\) トークンにのみ条件を付けることがあります。シーケンスのモデルのパープレキシティを評価する際、誘惑的ですが非効率な方法は、シーケンスを分割し、各セグメントの分解対数尤度を独立に合算することです。
|
| 40 |
+
|
| 41 |
+
<img width="600" alt="利用可能な完全なコンテキストを活用しない非最適なPPL" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/ppl_chunked.gif"/>
|
| 42 |
+
|
| 43 |
+
これは各セグメントのパープレキシティが1回のフォワードパスで計算できるため、計算が迅速ですが、通常、モデルはほとんどの予測ステップでコンテキストが少ないため、完全に因子分解されたパープレキシティの悪い近似となり、通常、より高い(悪い)PPLを返します。
|
| 44 |
+
|
| 45 |
+
代わりに、固定長モデルのPPLはスライディングウィンドウ戦略を用いて評価するべきです。これには、モデルが各予測ステップでより多くのコンテキストを持つように、コンテキストウィンドウを繰り返しスライドさせるという方法が含ま���ます。
|
| 46 |
+
|
| 47 |
+
<img width="600" alt="Sliding window PPL taking advantage of all available context" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/ppl_sliding.gif"/>
|
| 48 |
+
|
| 49 |
+
これはシーケンスの確率のより正確な分解に近いものであり、通常はより有利なスコアを生成します。欠点は、コーパス内の各トークンに対して別個の前方パスが必要です。実用的な妥協案は、1トークンずつスライドする代わりに、より大きなストライドでコンテキストを移動するストライド型のスライディングウィンドウを使用することです。これにより、計算がはるかに高速に進行できる一方で、モデルには各ステップで予測を行うための大きなコンテキストが提供されます。
|
| 50 |
+
|
| 51 |
+
## Example: Calculating perplexity with GPT-2 in 🤗 Transformers
|
| 52 |
+
|
| 53 |
+
GPT-2を使用してこのプロセスをデモンストレーションしてみましょう。
|
| 54 |
+
|
| 55 |
+
```python
|
| 56 |
+
from transformers import GPT2LMHeadModel, GPT2TokenizerFast
|
| 57 |
+
|
| 58 |
+
device = "cuda"
|
| 59 |
+
model_id = "openai-community/gpt2-large"
|
| 60 |
+
model = GPT2LMHeadModel.from_pretrained(model_id).to(device)
|
| 61 |
+
tokenizer = GPT2TokenizerFast.from_pretrained(model_id)
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
WikiText-2データセットを読み込み、異なるスライディングウィンドウ戦略を使用してパープレキシティを評価します。このデータセットは小規模で、セット全体に対して単一のフォワードパスを実行するだけなので、データセット全体をメモリに読み込んでエンコードするだけで十分です。
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
```python
|
| 68 |
+
from datasets import load_dataset
|
| 69 |
+
|
| 70 |
+
test = load_dataset("wikitext", "wikitext-2-raw-v1", split="test")
|
| 71 |
+
encodings = tokenizer("\n\n".join(test["text"]), return_tensors="pt")
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
🤗 Transformersを使用すると、単純に`input_ids`をモデルの`labels`として渡すことで、各トークンの平均負の対数尤度が損失として返されます。しかし、スライディングウィンドウのアプローチでは、各イテレーションでモデルに渡すトークンにオーバーラップがあります。私たちは、コンテキストとして扱っているトークンの対数尤度を損失に含めたくありません。そのため、これらの対象を `-100` に設定して無視されるようにします。以下は、ストライドを `512` とした場合の例です。これにより、モデルは任意のトークンの条件付けの尤度を計算する際に、少なくともコンテキストとして 512 トークンを持つことになります(512 個の前のトークンが利用可能である場合)。
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
import torch
|
| 79 |
+
from tqdm import tqdm
|
| 80 |
+
|
| 81 |
+
max_length = model.config.n_positions
|
| 82 |
+
stride = 512
|
| 83 |
+
seq_len = encodings.input_ids.size(1)
|
| 84 |
+
|
| 85 |
+
nlls = []
|
| 86 |
+
prev_end_loc = 0
|
| 87 |
+
for begin_loc in tqdm(range(0, seq_len, stride)):
|
| 88 |
+
end_loc = min(begin_loc + max_length, seq_len)
|
| 89 |
+
trg_len = end_loc - prev_end_loc # may be different from stride on last loop
|
| 90 |
+
input_ids = encodings.input_ids[:, begin_loc:end_loc].to(device)
|
| 91 |
+
target_ids = input_ids.clone()
|
| 92 |
+
target_ids[:, :-trg_len] = -100
|
| 93 |
+
|
| 94 |
+
with torch.no_grad():
|
| 95 |
+
outputs = model(input_ids, labels=target_ids)
|
| 96 |
+
|
| 97 |
+
# loss is calculated using CrossEntropyLoss which averages over valid labels
|
| 98 |
+
# N.B. the model only calculates loss over trg_len - 1 labels, because it internally shifts the labels
|
| 99 |
+
# to the left by 1.
|
| 100 |
+
neg_log_likelihood = outputs.loss
|
| 101 |
+
|
| 102 |
+
nlls.append(neg_log_likelihood)
|
| 103 |
+
|
| 104 |
+
prev_end_loc = end_loc
|
| 105 |
+
if end_loc == seq_len:
|
| 106 |
+
break
|
| 107 |
+
|
| 108 |
+
ppl = torch.exp(torch.stack(nlls).mean())
|
| 109 |
+
```
|
| 110 |
+
|
| 111 |
+
ストライド長が最大入力長と同じ場合、上述の最適でないスライディングウィンドウ戦略と同等です。ストライドが小さいほど、モデルは各予測を行う際により多くのコンテキストを持つため、通常、報告される困難度(perplexity)が向上します。
|
| 112 |
+
|
| 113 |
+
上記のコードを `stride = 1024` で実行すると、オーバーラップがない状態で、結果の困難度(perplexity)は `19.44` になります。これは GPT-2 の論文に報告された `19.93` とほぼ同等です。一方、`stride = 512` を使用し、このようにストライディングウィンドウ戦略を採用すると、困難度(perplexity)が `16.45` に向上します。これはより好意的なスコアだけでなく、シーケンスの尤度の真の自己回帰分解により近い方法で計算されています。
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/philosophy.md
ADDED
|
@@ -0,0 +1,67 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Philosophy
|
| 18 |
+
|
| 19 |
+
🤗 Transformersは、次のような目的で構築された意見を持つライブラリです:
|
| 20 |
+
|
| 21 |
+
- 大規模なTransformersモデルを使用、研究、または拡張したい機械学習研究者および教育者。
|
| 22 |
+
- これらのモデルを微調整したり、本番環境で提供したり、またはその両方を行いたい実務家。
|
| 23 |
+
- 与えられた機械学習タスクを解決するために、事前トレーニングされたモデルをダウンロードして使用したいエンジニア。
|
| 24 |
+
|
| 25 |
+
このライブラリは、2つの強力な目標を持って設計されました:
|
| 26 |
+
|
| 27 |
+
1. できるだけ簡単かつ高速に使用できるようにすること:
|
| 28 |
+
|
| 29 |
+
- ユーザー向けの抽象化を限りなく少なくし、実際、ほとんどの場合、抽象化はありません。
|
| 30 |
+
各モデルを使用するために必要な3つの標準クラスだけが存在します:[構成](main_classes/configuration)、
|
| 31 |
+
[モデル](main_classes/model)、および前処理クラス(NLP用の[トークナイザ](main_classes/tokenizer)、ビジョン用の[イメージプロセッサ](main_classes/image_processor)、
|
| 32 |
+
オーディオ用の[特徴抽出器](main_classes/feature_extractor)、およびマルチモーダル入力用の[プロセッサ](main_classes/processors))。
|
| 33 |
+
- これらのクラスは、共通の`from_pretrained()`メソッドを使用して、事前トレーニング済みのインスタンスから簡単かつ統一された方法で初期化できます。このメソッドは、事前トレーニング済みのチェックポイントから関連するクラスのインスタンスと関連データ(構成のハイパーパラメータ、トークナイザの語彙、モデルの重み)をダウンロード(必要な場合はキャッシュ)して読み込みます。これらの基本クラスの上に、ライブラリは2つのAPIを提供しています:[パイプライン]は、特定のタスクでモデルをすばやく推論に使用するためのものであり、[`Trainer`]はPyTorchモデルを迅速にトレーニングまたは微調整するためのものです(すべてのTensorFlowモデルは`Keras.fit`と互換性があります)。
|
| 34 |
+
- その結果、このライブラリはニューラルネットワークのモジュラーツールボックスではありません。ライブラリを拡張または構築したい場合は、通常のPython、PyTorch、TensorFlow、Kerasモジュールを使用し、ライブラリの基本クラスから継承してモデルの読み込みと保存などの機能を再利用するだけです。モデルのコーディング哲学について詳しく知りたい場合は、[Repeat Yourself](https://huggingface.co/blog/transformers-design-philosophy)ブログ投稿をチェックしてみてください。
|
| 35 |
+
|
| 36 |
+
2. オリジナルのモデルにできるだけ近い性能を持つ最新のモデルを提供すること:
|
| 37 |
+
|
| 38 |
+
- 各アーキテクチャに対して、公式な著者から提供された結果を再現する少なくとも1つの例を提供します。
|
| 39 |
+
- コードは通常、可能な限り元のコードベースに近いものであり、これはPyTorchコードがTensorFlowコードに変換されることから生じ、逆もまた然りです。
|
| 40 |
+
|
| 41 |
+
その他のいくつかの目標:
|
| 42 |
+
|
| 43 |
+
- モデルの内部をできるだけ一貫して公開すること:
|
| 44 |
+
|
| 45 |
+
- フルな隠れ状態と注意の重みにアクセスできる単一のAPIを提供します。
|
| 46 |
+
- 前処理クラスと基本モデルのAPIは標準化され、簡単にモデル間を切り替えることができます。
|
| 47 |
+
|
| 48 |
+
- これらのモデルの微調整と調査のための有望なツールを主観的に選定すること:
|
| 49 |
+
|
| 50 |
+
- 語彙と埋め込みに新しいトークンを追加するための簡単で一貫した方法。
|
| 51 |
+
- Transformerヘッドをマスクおよびプルーンするための簡単な方法。
|
| 52 |
+
|
| 53 |
+
- PyTorch、TensorFlow 2.0、およびFlaxの間を簡単に切り替えて、1つのフレームワークでトレーニングし、別のフレームワークで推論を行うことを可能にすること。
|
| 54 |
+
|
| 55 |
+
## Main concepts
|
| 56 |
+
|
| 57 |
+
このライブラリは、���モデルについて次の3つのタイプのクラスを中心に構築されています:
|
| 58 |
+
|
| 59 |
+
- **モデルクラス**は、ライブラリで提供される事前トレーニング済みの重みと互換性のあるPyTorchモデル([torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module))、Kerasモデル([tf.keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model))またはJAX/Flaxモデル([flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html))を使用できます。
|
| 60 |
+
- **構成クラス**は、モデルを構築するために必要なハイパーパラメータを格納します(層の数や隠れ層のサイズなど)。これらを自分でインスタンス化する必要はありません。特に、変更を加えずに事前トレーニング済みモデルを使用している場合、モデルを作成すると自動的に構成がインスタンス化されるようになります(これはモデルの一部です)。
|
| 61 |
+
- **前処理クラス**は、生データをモデルが受け入れる形式に変換します。[トークナイザ](main_classes/tokenizer)は各モデルの語彙を保存し、文字列をトークン埋め込みのインデックスのリストにエンコードおよびデコードするためのメソッドを提供します。[イメージプロセッサ](main_classes/image_processor)はビジョン入力を前処理し、[特徴抽出器](main_classes/feature_extractor)はオーディオ入力を前処理し、[プロセッサ](main_classes/processors)はマルチモーダル入力を処理します。
|
| 62 |
+
|
| 63 |
+
これらのすべてのクラスは、事前トレーニング済みのインスタンスからインスタンス化し、ローカルに保存し、Hubで共有することができる3つのメソッドを使用しています:
|
| 64 |
+
|
| 65 |
+
- `from_pretrained()`は、ライブラリ自体によって提供される([モデルハブ](https://huggingface.co/models)でサポートされているモデルがあります)か、ユーザーによってローカルに保存された(またはサーバーに保存された)事前トレーニング済みバージョンからモデル、構成、前処理クラスをインスタンス化するためのメソッドです。
|
| 66 |
+
- `save_pretrained()`は、モデル、構成、前処理クラスをローカルに保存し、`from_pretrained()`を使用して再読み込みできるようにします。
|
| 67 |
+
- `push_to_hub()`は、モデル、構成、前処理クラスをHubに共有し、誰でも簡単にアクセスできるようにします。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_tutorial.md
ADDED
|
@@ -0,0 +1,295 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 5 |
+
the License. You may obtain a copy of the License at
|
| 6 |
+
|
| 7 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
|
| 9 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 10 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 11 |
+
specific language governing permissions and limitations under the License.
|
| 12 |
+
|
| 13 |
+
⚠️ このファイルはMarkdown形式ですが、当社のdoc-builder(MDXに似た構文)を含むため、Markdownビューアで正しく表示されないことがあります。
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Pipelines for inference
|
| 18 |
+
|
| 19 |
+
[`pipeline`]を使用することで、[Hub](https://huggingface.co/models)からの任意のモデルを言語、コンピュータビジョン、音声、およびマルチモーダルタスクの推論に簡単に使用できます。
|
| 20 |
+
特定のモダリティに関する経験がない場合や、モデルの背後にあるコードに精通していない場合でも、[`pipeline`]を使用して推論できます!
|
| 21 |
+
このチュートリアルでは、次のことを学びます:
|
| 22 |
+
|
| 23 |
+
- 推論のための[`pipeline`]の使用方法。
|
| 24 |
+
- 特定のトークナイザやモデルの使用方法。
|
| 25 |
+
- オーディオ、ビジョン、マルチモーダルタスクのための[`pipeline`]の使用方法。
|
| 26 |
+
|
| 27 |
+
<Tip>
|
| 28 |
+
|
| 29 |
+
サポートされているタスクと利用可能なパラメータの完全な一覧については、[`pipeline`]のドキュメンテーションをご覧ください。
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
## Pipeline usage
|
| 34 |
+
|
| 35 |
+
各タスクには関連する[`pipeline`]がありますが、タスク固有の[`pipeline`]を使用する代わりに、すべてのタスク固有のパイプラインを含む一般的な[`pipeline`]の抽象化を使用すると、より簡単です。[`pipeline`]は自動的にデフォルトのモデルと、タスクの推論が可能な前処理クラスを読み込みます。
|
| 36 |
+
|
| 37 |
+
1. [`pipeline`]を作成し、推論タスクを指定して始めます:
|
| 38 |
+
|
| 39 |
+
```py
|
| 40 |
+
>>> from transformers import pipeline
|
| 41 |
+
|
| 42 |
+
>>> generator = pipeline(task="automatic-speech-recognition")
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
2. [`pipeline`]に入力テキストを渡します:
|
| 46 |
+
|
| 47 |
+
```python
|
| 48 |
+
>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
|
| 49 |
+
{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
チェックアウトできなかったか? [Hubの最もダウンロードされた自動音声認識モデル](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=downloads) のいくつかを見て、より良い転写を得ることができるかどうかを確認してみてください。
|
| 53 |
+
[openai/whisper-large](https://huggingface.co/openai/whisper-large) を試してみましょう:
|
| 54 |
+
|
| 55 |
+
```python
|
| 56 |
+
>>> generator = pipeline(model="openai/whisper-large")
|
| 57 |
+
>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
|
| 58 |
+
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
この結果はより正確に見えますね!
|
| 62 |
+
異なる言語、専門分野に特化したモデル、その他のモデルについては、Hubをチェックすることを強くお勧めします。
|
| 63 |
+
Hubでは、ブラウザから直接モデルの結果をチェックして、他のモデルよりも適しているか、特殊なケースをよりよく処理できるかを確認できます。
|
| 64 |
+
そして、あなたのユースケースに適したモデルが見つからない場合、いつでも[トレーニング](training)を開始できます!
|
| 65 |
+
|
| 66 |
+
複数の入力がある場合、入力をリストとして渡すことができます:
|
| 67 |
+
|
| 68 |
+
```py
|
| 69 |
+
generator(
|
| 70 |
+
[
|
| 71 |
+
"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
|
| 72 |
+
"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
|
| 73 |
+
]
|
| 74 |
+
)
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
データセット全体を繰り返し処理したり、ウェブサーバーで推論に使用したい場合は、専用の部分をチェックしてください。
|
| 78 |
+
|
| 79 |
+
[データセットでパイプラインを使用する](#using-pipeline-in-a-dataset)
|
| 80 |
+
|
| 81 |
+
[ウェブサーバーでパイプラインを使用する](./pipeline_webserver)
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
## パラメータ
|
| 86 |
+
|
| 87 |
+
[`pipeline`]は多くのパラメータをサポートしており、一部はタスク固有であり、一部はすべてのパイプラインに共通です。
|
| 88 |
+
一般的には、どこでもパラメータを指定できます:
|
| 89 |
+
|
| 90 |
+
```py
|
| 91 |
+
generator = pipeline(model="openai/whisper-large", my_parameter=1)
|
| 92 |
+
out = generator(...) # これは `my_parameter=1` を使用します。
|
| 93 |
+
out = generator(..., my_parameter=2) # これは上書きして `my_parameter=2` を使用します。
|
| 94 |
+
out = generator(...) # これは再び `my_parameter=1` を使用します。
|
| 95 |
+
```
|
| 96 |
+
|
| 97 |
+
3つの重要なものを確認しましょう:
|
| 98 |
+
|
| 99 |
+
### Device
|
| 100 |
+
|
| 101 |
+
`device=n` を使用すると、パイプラインはモデルを指定したデバイスに自動的に配置します。
|
| 102 |
+
これは、PyTorchまたはTensorflowを使用しているかどうかに関係なく機能します。
|
| 103 |
+
|
| 104 |
+
```py
|
| 105 |
+
generator = pipeline(model="openai/whisper-large", device=0)
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
もしモデルが単一のGPUには大きすぎる場合、`device_map="auto"`を設定して、🤗 [Accelerate](https://huggingface.co/docs/accelerate) にモデルの重みをどのようにロードし、保存するかを自動的に決定させることができます。
|
| 109 |
+
|
| 110 |
+
```python
|
| 111 |
+
#!pip install accelerate
|
| 112 |
+
generator = pipeline(model="openai/whisper-large", device_map="auto")
|
| 113 |
+
```
|
| 114 |
+
|
| 115 |
+
注意: `device_map="auto"` が渡された場合、`pipeline` をインスタンス化する際に `device=device` 引数を追加する必要はありません。そうしないと、予期しない動作に遭遇する可能性があります!
|
| 116 |
+
|
| 117 |
+
### Batch size
|
| 118 |
+
|
| 119 |
+
デフォルトでは、パイプラインは詳細について[こちら](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching)で説明されている理由から、推論をバッチ処理しません。その理由は、バッチ処理が必ずしも速くないためであり、実際にはいくつかのケースでかなり遅くなることがあるからです。
|
| 120 |
+
|
| 121 |
+
ただし、あなたのユースケースで機能する場合は、次のように使用できます:
|
| 122 |
+
|
| 123 |
+
```py
|
| 124 |
+
generator = pipeline(model="openai/whisper-large", device=0, batch_size=2)
|
| 125 |
+
audio_filenames = [f"audio_{i}.flac" for i in range(10)]
|
| 126 |
+
texts = generator(audio_filenames)
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
これにより、パイプラインは提供された10個のオーディオファイルでパイプラインを実行しますが、
|
| 130 |
+
モデルにはバッチ処理がより効果的であるGPU上にあり、バッチ処理を行うための追加のコードは必要ありません。
|
| 131 |
+
出力は常にバッチ処理なしで受け取ったものと一致するはずです。これは単にパイプラインからより高速な処理を得るための方法として提供されています。
|
| 132 |
+
|
| 133 |
+
パイプラインは、バッチ処理のいくつかの複雑さを軽減することもできます。なぜなら、一部のパイプラインでは、
|
| 134 |
+
モデルで処理するために1つのアイテム(長いオーディオファイルのようなもの)を複数の部分に分割する必要がある場合があるからです。
|
| 135 |
+
パイプラインはこれをあなたのために実行します。[*チャンクバッチ処理*](./main_classes/pipelines#pipeline-chunk-batching)として知られるものを実行します。
|
| 136 |
+
|
| 137 |
+
### Task specific parameters
|
| 138 |
+
|
| 139 |
+
すべてのタスクは、タスク固有のパラメータを提供し、追加の柔軟性とオプションを提供して、作業をスムーズに進めるのに役立ちます。
|
| 140 |
+
たとえば、[`transformers.AutomaticSpeechRecognitionPipeline.__call__`]メソッドには、ビデオの字幕作成に有用な`return_timestamps`パラメータがあります。
|
| 141 |
+
|
| 142 |
+
```py
|
| 143 |
+
>>> # Not using whisper, as it cannot provide timestamps.
|
| 144 |
+
>>> generator = pipeline(model="facebook/wav2vec2-large-960h-lv60-self", return_timestamps="word")
|
| 145 |
+
>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
|
| 146 |
+
{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP AND LIVE OUT THE TRUE MEANING OF ITS CREED', 'chunks': [{'text': 'I', 'timestamp': (1.22, 1.24)}, {'text': 'HAVE', 'timestamp': (1.42, 1.58)}, {'text': 'A', 'timestamp': (1.66, 1.68)}, {'text': 'DREAM', 'timestamp': (1.76, 2.14)}, {'text': 'BUT', 'timestamp': (3.68, 3.8)}, {'text': 'ONE', 'timestamp': (3.94, 4.06)}, {'text': 'DAY', 'timestamp': (4.16, 4.3)}, {'text': 'THIS', 'timestamp': (6.36, 6.54)}, {'text': 'NATION', 'timestamp': (6.68, 7.1)}, {'text': 'WILL', 'timestamp': (7.32, 7.56)}, {'text': 'RISE', 'timestamp': (7.8, 8.26)}, {'text': 'UP', 'timestamp': (8.38, 8.48)}, {'text': 'AND', 'timestamp': (10.08, 10.18)}, {'text': 'LIVE', 'timestamp': (10.26, 10.48)}, {'text': 'OUT', 'timestamp': (10.58, 10.7)}, {'text': 'THE', 'timestamp': (10.82, 10.9)}, {'text': 'TRUE', 'timestamp': (10.98, 11.18)}, {'text': 'MEANING', 'timestamp': (11.26, 11.58)}, {'text': 'OF', 'timestamp': (11.66, 11.7)}, {'text': 'ITS', 'timestamp': (11.76, 11.88)}, {'text': 'CREED', 'timestamp': (12.0, 12.38)}]}
|
| 147 |
+
```
|
| 148 |
+
|
| 149 |
+
モデルは、テキストを推測し、文の中で各単語がいつ発音されたかを出力しました。
|
| 150 |
+
|
| 151 |
+
各タスクごとに利用可能な多くのパラメータがありますので、何を調整できるかを確認するために各タスクのAPIリファレンスを確認してください!
|
| 152 |
+
たとえば、[`~transformers.AutomaticSpeechRecognitionPipeline`]には、モデル単体では処理できない非常に長いオーディオファイル(たとえば、映画全体や1時間のビデオの字幕付��など)で役立つ`chunk_length_s`パラメータがあります。
|
| 153 |
+
|
| 154 |
+
<!--役立つパラメータが見つからない場合は、[リクエスト](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)してください!-->
|
| 155 |
+
|
| 156 |
+
役立つパラメータが見つからない場合は、[リクエスト](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)してください!
|
| 157 |
+
|
| 158 |
+
## Using pipeline in a dataset
|
| 159 |
+
|
| 160 |
+
パイプラインは大規模なデータセット上で推論を実行することもできます。これを行う最も簡単な方法は、イテレータを使用することです:
|
| 161 |
+
|
| 162 |
+
```py
|
| 163 |
+
def data():
|
| 164 |
+
for i in range(1000):
|
| 165 |
+
yield f"My example {i}"
|
| 166 |
+
|
| 167 |
+
|
| 168 |
+
pipe = pipeline(model="openai-community/gpt2", device=0)
|
| 169 |
+
generated_characters = 0
|
| 170 |
+
for out in pipe(data()):
|
| 171 |
+
generated_characters += len(out[0]["generated_text"])
|
| 172 |
+
```
|
| 173 |
+
|
| 174 |
+
イテレーター `data()` は各結果を生成し、パイプラインは自動的に入力が反復可能であることを認識し、データを取得し続けながらGPU上で処理を行います(これは[DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)を内部で使用しています)。
|
| 175 |
+
これは、データセット全体にメモリを割り当てる必要がなく、GPUにできるだけ速くデータを供給できるため重要です。
|
| 176 |
+
|
| 177 |
+
バッチ処理は処理を高速化できる可能性があるため、ここで`batch_size`パラメータを調整して試すことが役立つかもしれません。
|
| 178 |
+
|
| 179 |
+
データセットを反復処理する最も簡単な方法は、🤗 [Datasets](https://github.com/huggingface/datasets/)からデータセットを読み込むことです:
|
| 180 |
+
|
| 181 |
+
```py
|
| 182 |
+
# KeyDataset is a util that will just output the item we're interested in.
|
| 183 |
+
from transformers.pipelines.pt_utils import KeyDataset
|
| 184 |
+
from datasets import load_dataset
|
| 185 |
+
|
| 186 |
+
pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
|
| 187 |
+
dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
|
| 188 |
+
|
| 189 |
+
for out in pipe(KeyDataset(dataset, "audio")):
|
| 190 |
+
print(out)
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
## Using pipelines for a webserver
|
| 194 |
+
|
| 195 |
+
<Tip>
|
| 196 |
+
推論エンジンを作成することは複雑なトピックで、独自のページが必要です。
|
| 197 |
+
</Tip>
|
| 198 |
+
|
| 199 |
+
[リンク](./pipeline_webserver)
|
| 200 |
+
|
| 201 |
+
## Vision pipeline
|
| 202 |
+
|
| 203 |
+
ビジョンタスク用の[`pipeline`]を使用する方法はほぼ同じです。
|
| 204 |
+
|
| 205 |
+
タスクを指定し、画像をクラシファイアに渡します。画像はリンク、ローカルパス、またはBase64エンコードされた画像であることができます。例えば、以下の画像はどの種類の猫ですか?
|
| 206 |
+
|
| 207 |
+
|
| 208 |
+
|
| 209 |
+
```py
|
| 210 |
+
>>> from transformers import pipeline
|
| 211 |
+
|
| 212 |
+
>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
|
| 213 |
+
>>> preds = vision_classifier(
|
| 214 |
+
... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
|
| 215 |
+
... )
|
| 216 |
+
>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
|
| 217 |
+
>>> preds
|
| 218 |
+
[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
|
| 219 |
+
```
|
| 220 |
+
|
| 221 |
+
## Text pipeline
|
| 222 |
+
|
| 223 |
+
[`pipeline`]を使用することは、NLPタスクに対してほぼ同じです。
|
| 224 |
+
|
| 225 |
+
```py
|
| 226 |
+
>>> from transformers import pipeline
|
| 227 |
+
|
| 228 |
+
>>> # This model is a `zero-shot-classification` model.
|
| 229 |
+
>>> # It will classify text, except you are free to choose any label you might imagine
|
| 230 |
+
>>> classifier = pipeline(model="facebook/bart-large-mnli")
|
| 231 |
+
>>> classifier(
|
| 232 |
+
... "I have a problem with my iphone that needs to be resolved asap!!",
|
| 233 |
+
... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
|
| 234 |
+
... )
|
| 235 |
+
{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
|
| 236 |
+
```
|
| 237 |
+
|
| 238 |
+
## Multimodal pipeline
|
| 239 |
+
|
| 240 |
+
[`pipeline`]は、1つ以上のモダリティをサポートしています。たとえば、視覚的な質問応答(VQA)タスクはテキストと画像を組み合わせています。
|
| 241 |
+
好きな画像リンクと画像に関する質問を自由に使ってください。画像はURLまたは画像のローカルパスで指定できます。
|
| 242 |
+
|
| 243 |
+
例えば、この[請求書画像](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png)を使用する場合:
|
| 244 |
+
|
| 245 |
+
```py
|
| 246 |
+
>>> from transformers import pipeline
|
| 247 |
+
|
| 248 |
+
>>> vqa = pipeline(model="impira/layoutlm-document-qa")
|
| 249 |
+
>>> output = vqa(
|
| 250 |
+
... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
|
| 251 |
+
... question="What is the invoice number?",
|
| 252 |
+
... )
|
| 253 |
+
>>> output[0]["score"] = round(output[0]["score"], 3)
|
| 254 |
+
>>> output
|
| 255 |
+
[{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
|
| 256 |
+
```
|
| 257 |
+
|
| 258 |
+
<Tip>
|
| 259 |
+
|
| 260 |
+
上記の例を実行するには、🤗 Transformersに加えて [`pytesseract`](https://pypi.org/project/pytesseract/) がインストールされている必要があります。
|
| 261 |
+
|
| 262 |
+
```bash
|
| 263 |
+
sudo apt install -y tesseract-ocr
|
| 264 |
+
pip install pytesseract
|
| 265 |
+
```
|
| 266 |
+
|
| 267 |
+
</Tip>
|
| 268 |
+
|
| 269 |
+
## Using `pipeline` on large models with 🤗 `accelerate`:
|
| 270 |
+
|
| 271 |
+
まず、`accelerate` を`pip install accelerate` でインストールしていることを確認してください。
|
| 272 |
+
|
| 273 |
+
次に、`device_map="auto"` を使用してモデルをロードします。この例では `facebook/opt-1.3b` を使用します。
|
| 274 |
+
|
| 275 |
+
```python
|
| 276 |
+
# pip install accelerate
|
| 277 |
+
import torch
|
| 278 |
+
from transformers import pipeline
|
| 279 |
+
|
| 280 |
+
pipe = pipeline(model="facebook/opt-1.3b", torch_dtype=torch.bfloat16, device_map="auto")
|
| 281 |
+
output = pipe("これは素晴らしい例です!", do_sample=True, top_p=0.95)
|
| 282 |
+
```
|
| 283 |
+
|
| 284 |
+
もし `bitsandbytes` をインストールし、`load_in_8bit=True` 引数を追加すれば、8ビットで読み込まれたモデルを渡すこともできます。
|
| 285 |
+
|
| 286 |
+
```py
|
| 287 |
+
# pip install accelerate bitsandbytes
|
| 288 |
+
import torch
|
| 289 |
+
from transformers import pipeline
|
| 290 |
+
|
| 291 |
+
pipe = pipeline(model="facebook/opt-1.3b", device_map="auto", model_kwargs={"load_in_8bit": True})
|
| 292 |
+
output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
注意: BLOOMなどの大規模モデルのロードをサポートするHugging Faceモデルのいずれかで、チェックポイントを置き換えることができます!
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_webserver.md
ADDED
|
@@ -0,0 +1,132 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 2 |
+
rendered properly in your Markdown viewer.
|
| 3 |
+
-->
|
| 4 |
+
|
| 5 |
+
# Webサーバー用のパイプラインの使用
|
| 6 |
+
|
| 7 |
+
<Tip>
|
| 8 |
+
推論エンジンの作成は複雑なトピックであり、"最適な"ソリューションはおそらく問題の領域に依存するでしょう。CPUまたはGPUを使用していますか?最低のレイテンシ、最高のスループット、多くのモデルのサポート、または特定のモデルの高度な最適化を望んでいますか?
|
| 9 |
+
このトピックに取り組むための多くの方法があり、私たちが紹介するのは、おそらく最適なソリューションではないかもしれないが、始めるための良いデフォルトです。
|
| 10 |
+
</Tip>
|
| 11 |
+
|
| 12 |
+
重要なことは、Webサーバーはリクエストを待機し、受信したように扱うシステムであるため、[データセット](pipeline_tutorial#using-pipelines-on-a-dataset)のように、イテレータを使用できることです。
|
| 13 |
+
|
| 14 |
+
通常、Webサーバーは並列処理(マルチスレッド、非同期など)されて、さまざまなリクエストを同時に処理します。一方、パイプライン(および主にその基礎となるモデル)は並列処理にはあまり適していません。それらは多くのRAMを使用するため、実行中に利用可能なリソースをすべて提供するか、計算集約型のジョブである場合に最適です。
|
| 15 |
+
|
| 16 |
+
Webサーバーは受信と送信の軽い負荷を処理し、実際の作業を1つのスレッドで処理するようにします。この例では`starlette`を使用します。実際のフレームワークはあまり重要ではありませんが、別のフレームワークを使用している場合は、同じ効果を得るためにコードを調整または変更する必要があるかもしれません。
|
| 17 |
+
|
| 18 |
+
`server.py`を作成してください:
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
```py
|
| 22 |
+
from starlette.applications import Starlette
|
| 23 |
+
from starlette.responses import JSONResponse
|
| 24 |
+
from starlette.routing import Route
|
| 25 |
+
from transformers import pipeline
|
| 26 |
+
import asyncio
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
async def homepage(request):
|
| 30 |
+
payload = await request.body()
|
| 31 |
+
string = payload.decode("utf-8")
|
| 32 |
+
response_q = asyncio.Queue()
|
| 33 |
+
await request.app.model_queue.put((string, response_q))
|
| 34 |
+
output = await response_q.get()
|
| 35 |
+
return JSONResponse(output)
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
async def server_loop(q):
|
| 39 |
+
pipe = pipeline(model="google-bert/bert-base-uncased")
|
| 40 |
+
while True:
|
| 41 |
+
(string, response_q) = await q.get()
|
| 42 |
+
out = pipe(string)
|
| 43 |
+
await response_q.put(out)
|
| 44 |
+
|
| 45 |
+
|
| 46 |
+
app = Starlette(
|
| 47 |
+
routes=[
|
| 48 |
+
Route("/", homepage, methods=["POST"]),
|
| 49 |
+
],
|
| 50 |
+
)
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
@app.on_event("startup")
|
| 54 |
+
async def startup_event():
|
| 55 |
+
q = asyncio.Queue()
|
| 56 |
+
app.model_queue = q
|
| 57 |
+
asyncio.create_task(server_loop(q))
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
ここから始めることができます:
|
| 61 |
+
```bash
|
| 62 |
+
uvicorn server:app
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
そして、次のようにクエリできます:
|
| 66 |
+
```bash
|
| 67 |
+
curl -X POST -d "test [MASK]" http://localhost:8000/
|
| 68 |
+
#[{"score":0.7742936015129089,"token":1012,"token_str":".","sequence":"test."},...]
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
そして、これでウェブサーバーを作成する方法の良いアイデアを持っています!
|
| 74 |
+
|
| 75 |
+
本当に重要なのは、モデルを**一度だけ**ロードすることです。これにより、ウェブサーバー上にモデルのコピーがないため、不必要なRAMが使用されなくなります。
|
| 76 |
+
その後、キューイングメカニズムを使用して、動的バッチ処理を行うなど、いくつかのアイテムを蓄積してから推論を行うなど、高度な処理を行うことができます:
|
| 77 |
+
|
| 78 |
+
<Tip warning={true}>
|
| 79 |
+
|
| 80 |
+
以下のコードサンプルは、可読性のために擬似コードのように書かれています。システムリソースに合理的かどうかを確認せずに実行しないでください!
|
| 81 |
+
|
| 82 |
+
</Tip>
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
```py
|
| 86 |
+
(string, rq) = await q.get()
|
| 87 |
+
strings = []
|
| 88 |
+
queues = []
|
| 89 |
+
while True:
|
| 90 |
+
try:
|
| 91 |
+
(string, rq) = await asyncio.wait_for(q.get(), timeout=0.001) # 1ms
|
| 92 |
+
except asyncio.exceptions.TimeoutError:
|
| 93 |
+
break
|
| 94 |
+
strings.append(string)
|
| 95 |
+
queues.append(rq)
|
| 96 |
+
strings
|
| 97 |
+
outs = pipe(strings, batch_size=len(strings))
|
| 98 |
+
for rq, out in zip(queues, outs):
|
| 99 |
+
await rq.put(out)
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
まず第一に、通常はあまり良いアイデアではないバッチサイズの制限がありません。次に、タイムアウトはキューの取得ごとにリセットされるため、推論を実行する前に1ms以上待つ可能性があります(最初のリクエストの遅延に1ms分遅れが生じます)。
|
| 103 |
+
|
| 104 |
+
1msの締め切りを1回だけ持つのが良いでしょう。
|
| 105 |
+
|
| 106 |
+
これは、キューに何もない場合でも常に1ms待機しますが、キューに何もない場合に推論を開始したい場合は適していないかもしれません。ただし、バッ���処理が本当に重要な場合には意味があるかもしれません。再度、1つの最適な解決策は存在しません。
|
| 107 |
+
|
| 108 |
+
## Few things you might want to consider
|
| 109 |
+
|
| 110 |
+
### Error checking
|
| 111 |
+
|
| 112 |
+
本番環境では多くの問題が発生する可能性があります:メモリ不足、スペース不足、モデルの読み込みが失敗するかもしれません、クエリが誤っているかもしれません、クエリが正しい場合でもモデルの構成エラーのために実行に失敗するかもしれませんなど。
|
| 113 |
+
|
| 114 |
+
一般的には、サーバーがエラーをユーザーに出力すると良いため、これらのエラーを表示するための多くの`try..except`ステートメントを追加することは良いアイデアです。ただし、セキュリティコンテキストに応じてこれらのエラーをすべて表示することはセキュリティリスクになる可能性があることに注意してください。
|
| 115 |
+
|
| 116 |
+
### Circuit breaking
|
| 117 |
+
|
| 118 |
+
Webサーバーは通常、過負荷時に正しいエラーを返す方が良いです。クエリを無期限に待つ代わりに適切なエラーを返します。長時間待つ代わりに503エラーを返すか、長時間待ってから504エラーを返すかです。
|
| 119 |
+
|
| 120 |
+
提案されたコードでは単一のキューがあるため、キューサイズを見ることは、Webサーバーが負荷に耐える前にエラーを返すための基本的な方法です。
|
| 121 |
+
|
| 122 |
+
### Blocking the main thread
|
| 123 |
+
|
| 124 |
+
現在、PyTorchは非同期を認識していないため、計算はメインスレッドをブロックします。つまり、PyTorchが独自のスレッド/プロセスで実行されるようにすると良いでしょう。提案されたコードは、スレッドと非同期とキューがうまく連携しないため、これは行われていませんが、最終的には同じことを行います。
|
| 125 |
+
|
| 126 |
+
これは、単一のアイテムの推論が長い場合(>1秒)に重要です。この場合、推論中にすべてのクエリが1秒待たなければならないことを意味します。
|
| 127 |
+
|
| 128 |
+
### Dynamic batching
|
| 129 |
+
|
| 130 |
+
一般的に、バッチ処理は1回のアイテムを1回渡すよりも改善されることは必ずしもありません(詳細は[バッチ処理の詳細](./main_classes/pipelines#pipeline-batching)を参照)。しかし、正しい設定で使用すると非常に効果的です。APIではデフォルトで動的バッチ処理は行われません(遅延の機会が多すぎます)。しかし、非常に大規模なモデルであるBLOOM推論の場合、動的バッチ処理は**重要**です。これにより、すべてのユーザーにとってまともなエクスペリエンスを提供できます。
|
| 131 |
+
|
| 132 |
+
以上が、提供されたテキストのMarkdown形式の翻訳です。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pr_checks.md
ADDED
|
@@ -0,0 +1,208 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!---
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
you may not use this file except in compliance with the License.
|
| 6 |
+
You may obtain a copy of the License at
|
| 7 |
+
|
| 8 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
|
| 10 |
+
Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
See the License for the specific language governing permissions and
|
| 14 |
+
limitations under the License.
|
| 15 |
+
|
| 16 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 17 |
+
rendered properly in your Markdown viewer.
|
| 18 |
+
|
| 19 |
+
-->
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
# Checks on a Pull Request
|
| 23 |
+
|
| 24 |
+
🤗 Transformersリポジトリでプルリクエストを開くと、追加しているパッチが既存のものを壊していないことを確認するために、かなりの数のチェックが実行されます。これらのチェックには、次の4つのタイプがあります:
|
| 25 |
+
- 通常のテスト
|
| 26 |
+
- ドキュメンテーションのビルド
|
| 27 |
+
- コードとドキュメンテーションのスタイル
|
| 28 |
+
- リポジトリ全体の一貫性
|
| 29 |
+
|
| 30 |
+
このドキュメントでは、これらのさまざまなチェックとその背後にある理由、そしてそれらのいずれかがあなたのプルリクエストで失敗した場合のローカルでのデバッグ方法について説明します。
|
| 31 |
+
|
| 32 |
+
なお、理想的には、開発者用のインストールが必要です:
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
```bash
|
| 36 |
+
pip install transformers[dev]
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
または編集可能なインストールの場合:
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
```bash
|
| 43 |
+
pip install -e .[dev]
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
トランスフォーマーズのリポジトリ内で作業しています。トランスフォーマーズのオプションの依存関係の数が増えたため、すべてを取得できない可能性があります。開発用インストールが失敗した場合、作業しているディープラーニングフレームワーク(PyTorch、TensorFlow、および/またはFlax)をインストールし、次の手順を実行してください。
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
```bash
|
| 50 |
+
pip install transformers[quality]
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
または編集可能なインストールの場合:
|
| 54 |
+
|
| 55 |
+
```bash
|
| 56 |
+
pip install -e .[quality]
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
## Tests
|
| 60 |
+
|
| 61 |
+
`ci/circleci: run_tests_` で始まるすべてのジョブは、Transformersのテストスイートの一部を実行します。これらのジョブは、特定の環境でライブラリの一部に焦点を当てて実行されます。たとえば、`ci/circleci: run_tests_pipelines_tf` は、TensorFlowのみがインストールされた環境でパイプラインのテストを実行します。
|
| 62 |
+
|
| 63 |
+
テストスイートの一部のみが実行されるように注意してください。テストスイートは、変更前と変更後のPRのライブラリの違いを決定し、その違いに影響を受けるテストを選択するためのユーティリティが実行されます。このユーティリティは、ローカルで以下のコマンドを実行して実行できます:
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
```bash
|
| 67 |
+
python utils/tests_fetcher.py
|
| 68 |
+
```
|
| 69 |
+
|
| 70 |
+
1. リポジトリのルートからスクリプトを実行します。これは次のステップを実行します:
|
| 71 |
+
|
| 72 |
+
1. 差分内の各ファイルをチェックし、変更がコード内にあるか、コメントやドキュメンテーション文字列のみにあるかを確認します。実際のコード変更があるファイルのみを保持します。
|
| 73 |
+
|
| 74 |
+
2. 内部のマップを構築します。このマップは、ライブラリのソースコードの各ファイルが再帰的に影響を与えるすべてのファイルを提供します。モジュールAがモジュールBに影響を与えるとは、モジュールBがモジュールAをインポートする場合を指します。再帰的な影響を得るには、モジュールAからモジュールBへのモジュールのチェーンが必要で、各モジュールは前のモジュールをインポートする必要があります。
|
| 75 |
+
|
| 76 |
+
3. このマップをステップ1で収集したファイルに適用します。これにより、PRに影響を受けるモデルファイルのリストが得られます。
|
| 77 |
+
|
| 78 |
+
4. これらのファイルをそれに対応するテストファイルにマップし、実行するテストのリストを取得します。
|
| 79 |
+
|
| 80 |
+
2. スクリプトをローカルで実行する場合、ステップ1、3、および4の結果が表示され、実行するテストがわかります。スクリプトはまた、`test_list.txt` という名前のファイルを作成します。このファイルには実行するテストのリストが含まれており、次のコマンドでローカルで実行できます:
|
| 81 |
+
|
| 82 |
+
```bash
|
| 83 |
+
python -m pytest -n 8 --dist=loadfile -rA -s $(cat test_list.txt)
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
## Documentation build
|
| 87 |
+
|
| 88 |
+
`build_pr_documentation` ジョブは、ドキュメンテーションのビルドを行い、あなたのPRがマージされた後にすべてが正常に表示されることを確認します。ボットがプレビューのドキュメンテーションへのリンクをPRに追加します。PRに対する変更は、プレビューに自動的に反映されます。ドキュメンテーションのビルドに失敗した場合、失敗したジョブの隣にある「詳細」をクリックして、何が問題になっているかを確認できます。多くの場合、問題は`toctree`内のファイルが不足しているなど、単純なものです。
|
| 89 |
+
|
| 90 |
+
ドキュメンテーションをローカルでビルドまたはプレビューしたい場合は、[docsフォルダ内の`README.md`](https://github.com/huggingface/transformers/tree/main/docs)をご覧ください。
|
| 91 |
+
|
| 92 |
+
## Code and documentation style
|
| 93 |
+
|
| 94 |
+
すべてのソースファイル、例、テストには、`black`と`ruff`を使用してコードのフォーマットが適用されます。また、ドックストリングと`rst`ファイルのフォーマット、Transformersの`__init__.py`ファイルで実行される遅延インポートの順序についてもカスタムツールが存在します(`utils/style_doc.py`と`utils/custom_init_isort.py`)。これらすべては、以下を実行することで起動できます。
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
```bash
|
| 98 |
+
make style
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
CIは、`ci/circleci: check_code_quality` チェック内でこれらのチェックが適用されていることを確認します。また、`ruff` を実行し、未定義の変数や使用されていない変数がある場合にエラーを報告します。このチェックをローカルで実行するには、以下のコマンドを使用してください。
|
| 102 |
+
|
| 103 |
+
|
| 104 |
+
```bash
|
| 105 |
+
make quality
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
時間がかかることがあります。したがって、現在のブランチで変更したファイルのみで同じことを実行するには、次のコマンドを実行します。
|
| 109 |
+
|
| 110 |
+
|
| 111 |
+
```bash
|
| 112 |
+
make fixup
|
| 113 |
+
```
|
| 114 |
+
|
| 115 |
+
この最後のコマンドは、リポジトリの整合性のためのすべての追加のチェックも実行します。それらを詳しく見てみましょう。
|
| 116 |
+
|
| 117 |
+
## Repository consistency
|
| 118 |
+
|
| 119 |
+
これには、あなたのPRがリポジトリを適切な状態に保ったままであることを確認するためのすべてのテストが含まれており、ci/`circleci: check_repository_consistency` チェックによって実行されます。ローカルでこのチェックを実行するには、以下を実行します。
|
| 120 |
+
|
| 121 |
+
```bash
|
| 122 |
+
make repo-consistency
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
これを確認します:
|
| 126 |
+
|
| 127 |
+
- `utils/check_repo.py` によって実行される、init に追加されたすべてのオブジェクトが文書化されています。
|
| 128 |
+
- `utils/check_inits.py` によって実行される、すべての `__init__.py` ファイルがその2つのセクションで同じ内容を持っています。
|
| 129 |
+
- `utils/check_copies.py` によって実行される、他のモジュールからのコピーとして識別されたすべてのコードが元のコードと一致しています。
|
| 130 |
+
- `utils/check_config_docstrings.py` によって実行される、すべての設定クラスには少なくとも1つの有効なチェックポイントがドキュメント文字列に記載されています。
|
| 131 |
+
- `utils/check_config_attributes.py` によって実行される、すべての設定クラスには、対応するモデリングファイルで使用されている属性のみが含まれています。
|
| 132 |
+
- `utils/check_copies.py` によって実行される、README とドキュメントのインデックスの翻訳が、メインのREADME と同じモデルリストを持っています。
|
| 133 |
+
- `utils/check_table.py` によって実行される、ドキュメンテーションの自動生成テーブルが最新であることを確認します。
|
| 134 |
+
- `utils/check_dummies.py` によって実行される、すべてのオブジェクトが利用可能であり、オプションの依存関係がすべてインストールされていなくても問題ありません。
|
| 135 |
+
|
| 136 |
+
このチェックが失敗する場合、最初の2つの項目は手動で修正する必要があり、最後の4つはコマンドを実行して自動的に修正できます。
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
```bash
|
| 140 |
+
make fix-copies
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
追加のチェックポイントは、新しいモデルを追加するPull Request(PR)に関連しています。主に次の点を確認します:
|
| 144 |
+
|
| 145 |
+
- すべての追加されたモデルは、Auto-mapping(`utils/check_repo.py`で実行)に含まれています。
|
| 146 |
+
<!-- TODO Sylvain、共通のテストが実装されていることを確認するチェックを追加してください。-->
|
| 147 |
+
- すべてのモデルが適切にテストされています(`utils/check_repo.py`で実行)。
|
| 148 |
+
|
| 149 |
+
<!-- TODO Sylvain、以下を追加してください
|
| 150 |
+
- すべてのモデルがメインのREADMEおよびメインのドキュメント内に追加されています。
|
| 151 |
+
- 使用されているすべてのチェックポイントが実際にHubに存在しています
|
| 152 |
+
-->
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
### Check copies
|
| 156 |
+
|
| 157 |
+
Transformersライブラリは、モデルコードに関して非常に意見があるため、各モデルは他のモデルに依存せずに完全に1つのファイルに実装する必要があります。したがって、特定のモデルのコードのコピーが元のコードと一貫しているかどうかを確認する仕組みを追加しました。これにより、バグ修正がある場合、他の影響を受けるモデルをすべて確認し、変更を伝達するかコピーを破棄するかを選択できます。
|
| 158 |
+
|
| 159 |
+
<Tip>
|
| 160 |
+
|
| 161 |
+
ファイルが別のファイルの完全なコピーである場合、それを`utils/check_copies.py`の`FULL_COPIES`定数に登録する必要があります。
|
| 162 |
+
|
| 163 |
+
</Tip>
|
| 164 |
+
|
| 165 |
+
この仕組みは、`# Copied from xxx`という形式のコメントに依存しています。`xxx`は、コピーされているクラスまたは関数の完全なパスを含む必要があります。例えば、`RobertaSelfOutput`は`BertSelfOutput`クラスの直接のコピーですので、[こちら](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L289)にコメントがあります。
|
| 166 |
+
|
| 167 |
+
|
| 168 |
+
```py
|
| 169 |
+
# Copied from transformers.models.bert.modeling_bert.BertSelfOutput
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
注意点として、これをクラス全体に適用する代わりに、コピー元の関連メソッドに適用できます。たとえば、[こちら](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L598)では、`RobertaPreTrainedModel._init_weights` が `BertPreTrainedModel` からコピーされており、以下のコメントがあります:
|
| 173 |
+
|
| 174 |
+
|
| 175 |
+
```py
|
| 176 |
+
# Copied from transformers.models.bert.modeling_bert.BertAttention with Bert->Roberta
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
注:矢印の周りにはスペースが含まれていてはいけません(もちろん、そのスペースが置換パターンの一部である場合を除きます)。
|
| 180 |
+
|
| 181 |
+
カンマで区切られた複数のパターンを追加できます。例えば、ここでは `CamemberForMaskedLM` は `RobertaForMaskedLM` の直接のコピーで、2つの置換があります: `Roberta` から `Camembert` へ、そして `ROBERTA` から `CAMEMBERT` へと置換されます。[こちら](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/camembert/modeling_camembert.py#L929)で、この作業はコメント付きで行われています。
|
| 182 |
+
|
| 183 |
+
|
| 184 |
+
```py
|
| 185 |
+
# Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM with Roberta->Camembert, ROBERTA->CAMEMBERT
|
| 186 |
+
```
|
| 187 |
+
|
| 188 |
+
|
| 189 |
+
もし順序が重要な場合(以前の置換と競合する可能性があるため)、置換は左から右に実行されます。
|
| 190 |
+
|
| 191 |
+
<Tip>
|
| 192 |
+
|
| 193 |
+
もし置換がフォーマットを変更する場合(たとえば、短い名前を非常に長い名前に置き換える場合など)、自動フォーマッタを適用した後にコピーが確認されます。
|
| 194 |
+
|
| 195 |
+
</Tip>
|
| 196 |
+
|
| 197 |
+
パターンが同じ置換の異なるケース(大文字と小文字のバリアントがある)の場合、オプションとして `all-casing` を追加するだけの別の方法もあります。[こちら](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/mobilebert/modeling_mobilebert.py#L1237)は、`MobileBertForSequenceClassification` 内の例で、コメントがついています。
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
```py
|
| 201 |
+
# Copied from transformers.models.bert.modeling_bert.BertForSequenceClassification with Bert->MobileBert all-casing
|
| 202 |
+
```
|
| 203 |
+
|
| 204 |
+
この場合、コードは「BertForSequenceClassification」からコピーされ、次のように置換されます:
|
| 205 |
+
- `Bert` を `MobileBert` に置き換える(例:`init`で `MobileBertModel` を使用する場合)
|
| 206 |
+
- `bert` を `mobilebert` に置き換える(例:`self.mobilebert` を定義する場合)
|
| 207 |
+
- `BERT` を `MOBILEBERT` に置き換える(定数 `MOBILEBERT_INPUTS_DOCSTRING` 内で)
|
| 208 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/preprocessing.md
ADDED
|
@@ -0,0 +1,533 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 5 |
+
the License. You may obtain a copy of the License at
|
| 6 |
+
|
| 7 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
|
| 9 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 10 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 11 |
+
specific language governing permissions and limitations under the License.
|
| 12 |
+
|
| 13 |
+
⚠️ このファイルはMarkdown形式ですが、特定のMDXに類似したドキュメントビルダーの構文を含んでおり、
|
| 14 |
+
Markdownビューアーで正しく表示されないことがあります。
|
| 15 |
+
|
| 16 |
+
-->
|
| 17 |
+
|
| 18 |
+
# Preprocess
|
| 19 |
+
|
| 20 |
+
[[open-in-colab]]
|
| 21 |
+
|
| 22 |
+
データセットでモデルをトレーニングする前に、それをモデルの期待する入力形式に前処理する必要があります。
|
| 23 |
+
データがテキスト、画像、またはオーディオであるかどうかにかかわらず、それらはテンソルのバッチに変換して組み立てる必要があります。
|
| 24 |
+
🤗 Transformersは、データをモデル用に準備するのに役立つ前処理クラスのセットを提供しています。
|
| 25 |
+
このチュートリアルでは、次のことを学びます:
|
| 26 |
+
|
| 27 |
+
* テキストの場合、[Tokenizer](./main_classes/tokenizer)を使用してテキストをトークンのシーケンスに変換し、トークンの数値表現を作成し、それらをテンソルに組み立てる方法。
|
| 28 |
+
* 音声とオーディオの場合、[Feature extractor](./main_classes/feature_extractor)を使用してオーディオ波形から連続的な特徴を抽出し、それらをテンソルに変換する方法。
|
| 29 |
+
* 画像入力の場合、[ImageProcessor](./main_classes/image)を使用して画像をテンソルに変換する方法。
|
| 30 |
+
* マルチモーダル入力の場合、[Processor](./main_classes/processors)を使用してトークナイザと特徴抽出器または画像プロセッサを組み合わせる方法。
|
| 31 |
+
|
| 32 |
+
<Tip>
|
| 33 |
+
|
| 34 |
+
`AutoProcessor`は常に動作し、使用するモデルに適切なクラスを自動的に選択します。
|
| 35 |
+
トークナイザ、画像プロセッサ、特徴抽出器、またはプロセッサを使用しているかにかかわらず、動作します。
|
| 36 |
+
|
| 37 |
+
</Tip>
|
| 38 |
+
|
| 39 |
+
始める前に、🤗 Datasetsをインストールして、いくつかのデータセットを試すことができるようにしてください:
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install datasets
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
## Natural Language Processing
|
| 46 |
+
|
| 47 |
+
<Youtube id="Yffk5aydLzg"/>
|
| 48 |
+
|
| 49 |
+
テキストデータの前処理に使用する主要なツールは、[トークナイザ](main_classes/tokenizer)です。トークナイザは、一連のルールに従ってテキストを*トークン*に分割します。トークンは数値に変換され、その後テンソルに変換され、モデルの入力となります。モデルが必要とする追加の入力は、トークナイザによって追加されます。
|
| 50 |
+
|
| 51 |
+
<Tip>
|
| 52 |
+
|
| 53 |
+
事前学習済みモデルを使用する予定の場合、関連する事前学習済みトークナイザを使用することが重要です。これにより、テキストが事前学習コーパスと同じ方法で分割され、事前学習中に通常*ボキャブ*として参照される対応するトークンインデックスを使用します。
|
| 54 |
+
|
| 55 |
+
</Tip>
|
| 56 |
+
|
| 57 |
+
[`AutoTokenizer.from_pretrained`]メソッドを使用して事前学習済みトークナイザをロードして、開始しましょう。これにより、モデルが事前学習された*ボキャブ*がダウンロードされます:
|
| 58 |
+
|
| 59 |
+
```python
|
| 60 |
+
>>> from transformers import AutoTokenizer
|
| 61 |
+
|
| 62 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
次に、テキストをトークナイザに渡します:
|
| 66 |
+
|
| 67 |
+
```py
|
| 68 |
+
>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
|
| 69 |
+
>>> print(encoded_input)
|
| 70 |
+
{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
|
| 71 |
+
'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 72 |
+
'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
トークナイザは、重要な3つの項目を持つ辞書を返します:
|
| 76 |
+
|
| 77 |
+
* [input_ids](glossary#input-ids) は文中の各トークンに対応するインデックスです。
|
| 78 |
+
* [attention_mask](glossary#attention-mask) はトークンがアテンションを受ける必要があるかどうかを示します。
|
| 79 |
+
* [token_type_ids](glossary#token-type-ids) は複数のシーケンスがある場合、トークンがどのシーケンスに属しているかを識別します。
|
| 80 |
+
|
| 81 |
+
`input_ids` をデコードして入力を返します:
|
| 82 |
+
|
| 83 |
+
```python
|
| 84 |
+
>>> tokenizer.decode(encoded_input["input_ids"])
|
| 85 |
+
'[CLS] 魔法使いの事に干渉するな、彼らは微妙で怒りっぽい。 [SEP]'
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
如何にお分かりいただけるかと思いますが、トークナイザはこの文章に2つの特別なトークン、`CLS`(クラシファイア)と`SEP`(セパレータ)を追加しました。
|
| 89 |
+
すべてのモデルが特別なトークンを必要とするわけではありませんが、必要な場合、トークナイザは自動的にそれらを追加します。
|
| 90 |
+
|
| 91 |
+
複数の文章を前処理する場合、トークナイザにリストとして渡してください:
|
| 92 |
+
|
| 93 |
+
```py
|
| 94 |
+
>>> batch_sentences = [
|
| 95 |
+
... "But what about second breakfast?",
|
| 96 |
+
... "Don't think he knows about second breakfast, Pip.",
|
| 97 |
+
... "What about elevensies?",
|
| 98 |
+
... ]
|
| 99 |
+
>>> encoded_inputs = tokenizer(batch_sentences)
|
| 100 |
+
>>> print(encoded_inputs)
|
| 101 |
+
{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
|
| 102 |
+
[101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
|
| 103 |
+
[101, 1327, 1164, 5450, 23434, 136, 102]],
|
| 104 |
+
'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
|
| 105 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 106 |
+
[0, 0, 0, 0, 0, 0, 0]],
|
| 107 |
+
'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
|
| 108 |
+
[1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
|
| 109 |
+
[1, 1, 1, 1, 1, 1, 1]]}
|
| 110 |
+
```
|
| 111 |
+
|
| 112 |
+
### Pad
|
| 113 |
+
|
| 114 |
+
文章は常に同じ長さではないことがあり、これはテンソル(モデルの入力)が均一な形状を持つ必要があるため問題となります。
|
| 115 |
+
パディングは、短い文に特別な「パディングトークン」を追加して、テンソルを長いシーケンスに合わせるための戦略です。
|
| 116 |
+
|
| 117 |
+
バッチ内の短いシーケンスを最長のシーケンスに合わせるために、`padding`パラメータを`True`に設定します:
|
| 118 |
+
|
| 119 |
+
```py
|
| 120 |
+
>>> batch_sentences = [
|
| 121 |
+
... "But what about second breakfast?",
|
| 122 |
+
... "Don't think he knows about second breakfast, Pip.",
|
| 123 |
+
... "What about elevensies?",
|
| 124 |
+
... ]
|
| 125 |
+
>>> encoded_input = tokenizer(batch_sentences, padding=True)
|
| 126 |
+
>>> print(encoded_input)
|
| 127 |
+
{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
|
| 128 |
+
[101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
|
| 129 |
+
[101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
|
| 130 |
+
'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 131 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 132 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
|
| 133 |
+
'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
|
| 134 |
+
[1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
|
| 135 |
+
[1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
|
| 136 |
+
```
|
| 137 |
+
|
| 138 |
+
1番目と3番目の文は、短いために`0`でパディングされています。
|
| 139 |
+
|
| 140 |
+
### Truncation
|
| 141 |
+
|
| 142 |
+
逆のスペクトルでは、時折、モデルが処理するのに長すぎるシーケンスがあるかもしれません。この場合、シーケンスを短縮する必要があります。
|
| 143 |
+
|
| 144 |
+
モデルが受け入れる最大の長さにシーケンスを切り詰めるには、`truncation`パラメータを`True`に設定します:
|
| 145 |
+
|
| 146 |
+
```py
|
| 147 |
+
>>> batch_sentences = [
|
| 148 |
+
... "But what about second breakfast?",
|
| 149 |
+
... "Don't think he knows about second breakfast, Pip.",
|
| 150 |
+
... "What about elevensies?",
|
| 151 |
+
... ]
|
| 152 |
+
>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
|
| 153 |
+
>>> print(encoded_input)
|
| 154 |
+
{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
|
| 155 |
+
[101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
|
| 156 |
+
[101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
|
| 157 |
+
'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 158 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 159 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
|
| 160 |
+
'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
|
| 161 |
+
[1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
|
| 162 |
+
[1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
|
| 163 |
+
```
|
| 164 |
+
|
| 165 |
+
<Tip>
|
| 166 |
+
|
| 167 |
+
異なるパディングと切り詰めの引数について詳しくは、[パディングと切り詰め](./pad_truncation)のコンセプトガイドをご覧ください。
|
| 168 |
+
|
| 169 |
+
</Tip>
|
| 170 |
+
|
| 171 |
+
### Build tensors
|
| 172 |
+
|
| 173 |
+
最後に、トークナイザがモデルに供給される実際のテンソルを返すように設定します。
|
| 174 |
+
|
| 175 |
+
`return_tensors`パラメータを`pt`(PyTorch用)または`tf`(TensorFlow用)に設定します:
|
| 176 |
+
|
| 177 |
+
<frameworkcontent>
|
| 178 |
+
<pt>
|
| 179 |
+
|
| 180 |
+
```py
|
| 181 |
+
>>> batch_sentences = [
|
| 182 |
+
... "But what about second breakfast?",
|
| 183 |
+
... "Don't think he knows about second breakfast, Pip.",
|
| 184 |
+
... "What about elevensies?",
|
| 185 |
+
... ]
|
| 186 |
+
>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="pt")
|
| 187 |
+
>>> print(encoded_input)
|
| 188 |
+
{'input_ids': tensor([[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
|
| 189 |
+
[101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
|
| 190 |
+
[101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]]),
|
| 191 |
+
'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 192 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 193 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]]),
|
| 194 |
+
'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
|
| 195 |
+
[1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
|
| 196 |
+
[1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]])}
|
| 197 |
+
```
|
| 198 |
+
</pt>
|
| 199 |
+
<tf>
|
| 200 |
+
```py
|
| 201 |
+
>>> batch_sentences = [
|
| 202 |
+
... "But what about second breakfast?",
|
| 203 |
+
... "Don't think he knows about second breakfast, Pip.",
|
| 204 |
+
... "What about elevensies?",
|
| 205 |
+
... ]
|
| 206 |
+
>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="tf")
|
| 207 |
+
>>> print(encoded_input)
|
| 208 |
+
{'input_ids': <tf.Tensor: shape=(2, 9), dtype=int32, numpy=
|
| 209 |
+
array([[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
|
| 210 |
+
[101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
|
| 211 |
+
[101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
|
| 212 |
+
dtype=int32)>,
|
| 213 |
+
'token_type_ids': <tf.Tensor: shape=(2, 9), dtype=int32, numpy=
|
| 214 |
+
array([[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 215 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 216 |
+
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]], dtype=int32)>,
|
| 217 |
+
'attention_mask': <tf.Tensor: shape=(2, 9), dtype=int32, numpy=
|
| 218 |
+
array([[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
|
| 219 |
+
[1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
|
| 220 |
+
[1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]], dtype=int32)>}
|
| 221 |
+
```
|
| 222 |
+
</tf>
|
| 223 |
+
</frameworkcontent>
|
| 224 |
+
|
| 225 |
+
## Audio
|
| 226 |
+
|
| 227 |
+
オーディオタスクの場合、データセットをモデル用に準備するために[特徴抽出器](main_classes/feature_extractor)が必要です。
|
| 228 |
+
特徴抽出器は生のオーディオデータから特徴を抽出し、それらをテンソルに変換するために設計されています。
|
| 229 |
+
|
| 230 |
+
[PolyAI/minds14](https://huggingface.co/datasets/PolyAI/minds14)データセットをロードして(データセットのロード方法の詳細については🤗 [Datasetsチュートリアル](https://huggingface.co/docs/datasets/load_hub)を参照)、
|
| 231 |
+
オーディオデータセットで特徴抽出器をどのように使用できるかを確認してみましょう:
|
| 232 |
+
|
| 233 |
+
```python
|
| 234 |
+
>>> from datasets import load_dataset, Audio
|
| 235 |
+
|
| 236 |
+
>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
|
| 237 |
+
```
|
| 238 |
+
|
| 239 |
+
アクセスして`audio`列の最初の要素を確認します。`audio`列を呼び出すと、自動的にオーディオファイルが読み込まれ、リサンプリングされます:
|
| 240 |
+
|
| 241 |
+
```py
|
| 242 |
+
>>> dataset[0]["audio"]
|
| 243 |
+
{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
|
| 244 |
+
0. , 0. ], dtype=float32),
|
| 245 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
|
| 246 |
+
'sampling_rate': 8000}
|
| 247 |
+
```
|
| 248 |
+
|
| 249 |
+
これにより、3つのアイテムが返されます:
|
| 250 |
+
|
| 251 |
+
* `array` は読み込まれた音声信号で、1Dの配列として読み込まれます。必要に応じてリサンプリングされることもあります。
|
| 252 |
+
* `path` は音声ファイルの場所を指します。
|
| 253 |
+
* `sampling_rate` は音声信号内のデータポイントが1秒間にいくつ測定されるかを示します。
|
| 254 |
+
|
| 255 |
+
このチュートリアルでは、[Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base)モデルを使用します。
|
| 256 |
+
モデルカードを確認すると、Wav2Vec2が16kHzのサンプリングされた音声オーディオで事前学習されていることがわかります。
|
| 257 |
+
モデルの事前学習に使用されたデータセットのサンプリングレートと、あなたのオーディオデータのサンプリングレートが一致することが重要です。
|
| 258 |
+
データのサンプリングレートが異なる場合、データをリサンプリングする必要があります。
|
| 259 |
+
|
| 260 |
+
1. 🤗 Datasetsの [`~datasets.Dataset.cast_column`] メソッドを使用して、サンプリングレートを16kHzにアップサンプリングします:
|
| 261 |
+
|
| 262 |
+
```py
|
| 263 |
+
>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16_000))
|
| 264 |
+
```
|
| 265 |
+
|
| 266 |
+
2. 再び `audio` 列を呼び出してオーディオファイルをリサンプルします:
|
| 267 |
+
|
| 268 |
+
```py
|
| 269 |
+
>>> dataset[0]["audio"]
|
| 270 |
+
{'array': array([ 2.3443763e-05, 2.1729663e-04, 2.2145823e-04, ...,
|
| 271 |
+
3.8356509e-05, -7.3497440e-06, -2.1754686e-05], dtype=float32),
|
| 272 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
|
| 273 |
+
'sampling_rate': 16000}
|
| 274 |
+
```
|
| 275 |
+
|
| 276 |
+
次に、入力を正規化しパディングするために特徴抽出器をロードします。テキストデータをパディングする場合、短いシーケンスには `0` が追加されます。同じ考え方がオーディオデータにも適用されます。特徴抽出器は `array` に `0` を追加します(これは無音として解釈されます)。
|
| 277 |
+
|
| 278 |
+
[`AutoFeatureExtractor.from_pretrained`]を使用して特徴抽出器をロードします:
|
| 279 |
+
|
| 280 |
+
```python
|
| 281 |
+
>>> from transformers import AutoFeatureExtractor
|
| 282 |
+
|
| 283 |
+
>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
|
| 284 |
+
```
|
| 285 |
+
|
| 286 |
+
オーディオ `array` を特徴抽出器に渡します。特徴抽出器で発生する可能性のある無音エラーをより良くデバッグするために、特徴抽出器に `sampling_rate` 引数を追加することをお勧めします。
|
| 287 |
+
|
| 288 |
+
```python
|
| 289 |
+
>>> audio_input = [dataset[0]["audio"]["array"]]
|
| 290 |
+
>>> feature_extractor(audio_input, sampling_rate=16000)
|
| 291 |
+
{'input_values': [array([ 3.8106556e-04, 2.7506407e-03, 2.8015103e-03, ...,
|
| 292 |
+
5.6335266e-04, 4.6588284e-06, -1.7142107e-04], dtype=float32)]}
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
同様に、トークナイザと同様に、バッチ内の可変シーケンスを処理するためにパディングまたは切り詰めを適用できます。次に、これらの2つのオーディオサンプルのシーケンス長を確認してみましょう:
|
| 296 |
+
|
| 297 |
+
```python
|
| 298 |
+
>>> dataset[0]["audio"]["array"].shape
|
| 299 |
+
(173398,)
|
| 300 |
+
|
| 301 |
+
>>> dataset[1]["audio"]["array"].shape
|
| 302 |
+
(106496,)
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
この関数は、データセットを前処理してオーディオサンプルの長さを同じにするためのものです。最大サンプル長を指定し、特徴抽出器はシーケンスをそれに合わせてパディングまたは切り詰めます。
|
| 306 |
+
|
| 307 |
+
```py
|
| 308 |
+
>>> def preprocess_function(examples):
|
| 309 |
+
... audio_arrays = [x["array"] for x in examples["audio"]]
|
| 310 |
+
... inputs = feature_extractor(
|
| 311 |
+
... audio_arrays,
|
| 312 |
+
... sampling_rate=16000,
|
| 313 |
+
... padding=True,
|
| 314 |
+
... max_length=100000,
|
| 315 |
+
... truncation=True,
|
| 316 |
+
... )
|
| 317 |
+
... return inputs
|
| 318 |
+
```
|
| 319 |
+
|
| 320 |
+
`preprocess_function`をデータセットの最初の数例に適用します:
|
| 321 |
+
|
| 322 |
+
```python
|
| 323 |
+
>>> processed_dataset = preprocess_function(dataset[:5])
|
| 324 |
+
```
|
| 325 |
+
|
| 326 |
+
サンプルの長さは現在同じで、指定された最大長と一致しています。これで処理されたデータセットをモデルに渡すことができます!
|
| 327 |
+
|
| 328 |
+
```py
|
| 329 |
+
>>> processed_dataset["input_values"][0].shape
|
| 330 |
+
(100000,)
|
| 331 |
+
|
| 332 |
+
>>> processed_dataset["input_values"][1].shape
|
| 333 |
+
(100000,)
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
## Computer Vision
|
| 337 |
+
|
| 338 |
+
コンピュータビジョンタスクでは、モデル用にデータセットを準備するための[画像プロセッサ](main_classes/image_processor)が必要です。
|
| 339 |
+
画像の前処理には、画像をモデルが期待する入力形式に変換するためのいくつかのステップが含まれています。これらのステップには、リサイズ、正規化、カラーチャネルの補正、および画像をテンソルに変換するなどが含まれます。
|
| 340 |
+
|
| 341 |
+
<Tip>
|
| 342 |
+
|
| 343 |
+
画像の前処理は、通常、画像の増強の形式に従います。画像の前処理と画像の増強の両方は画像データを変換しますが、異なる目的があります:
|
| 344 |
+
|
| 345 |
+
* 画像の増強は、過学習を防ぎ、モデルの堅牢性を向上させるのに役立つ方法で画像を変更します。データを増強する方法は無限で、明るさや色の調整、クロップ、回転、リサイズ、ズームなど、様々な方法があります。ただし、増強操作によって画像の意味が変わらないように注意する必要があります。
|
| 346 |
+
* 画像の前処理は、画像がモデルの期待する入力形式と一致することを保証します。コンピュータビジョンモデルをファインチューニングする場合、画像はモデルが最初にトレーニングされたときとまったく同じ方法で前処理する必要があります。
|
| 347 |
+
|
| 348 |
+
画像の増強には任意のライブラリを使用できます。画像の前処理には、モデルに関連付けられた`ImageProcessor`を使用します。
|
| 349 |
+
|
| 350 |
+
</Tip>
|
| 351 |
+
|
| 352 |
+
コンピュータビジョンのデータセットで画像プロセッサを使用する方法を示すために、[food101](https://huggingface.co/datasets/food101)データセットをロードします(データセットのロード方法の詳細については🤗[Datasetsチュートリアル](https://huggingface.co/docs/datasets/load_hub)を参照):
|
| 353 |
+
|
| 354 |
+
<Tip>
|
| 355 |
+
|
| 356 |
+
データセットがかなり大きいため、🤗 Datasetsの`split`パラメータを使用してトレーニングデータの小さなサンプルのみをロードします!
|
| 357 |
+
|
| 358 |
+
</Tip>
|
| 359 |
+
|
| 360 |
+
```python
|
| 361 |
+
>>> from datasets import load_dataset
|
| 362 |
+
|
| 363 |
+
>>> dataset = load_dataset("food101", split="train[:100]")
|
| 364 |
+
```
|
| 365 |
+
|
| 366 |
+
次に、🤗 Datasetsの [`Image`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=image#datasets.Image) 機能で画像を見てみましょう:
|
| 367 |
+
|
| 368 |
+
```python
|
| 369 |
+
>>> dataset[0]["image"]
|
| 370 |
+
```
|
| 371 |
+
|
| 372 |
+
<div class="flex justify-center">
|
| 373 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/vision-preprocess-tutorial.png"/>
|
| 374 |
+
</div>
|
| 375 |
+
|
| 376 |
+
AutoImageProcessorを[`AutoImageProcessor.from_pretrained`]を使用してロードします:
|
| 377 |
+
|
| 378 |
+
```py
|
| 379 |
+
>>> from transformers import AutoImageProcessor
|
| 380 |
+
|
| 381 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
|
| 382 |
+
```
|
| 383 |
+
|
| 384 |
+
1. まず、画像の拡張を追加しましょう。好きなライブラリを使用できますが、このチュートリアルではtorchvisionの[`transforms`](https://pytorch.org/vision/stable/transforms.html)モジュールを使用します。別のデータ拡張ライブラリを使用したい場合は、[Albumentations](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification_albumentations.ipynb)または[Kornia notebooks](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification_kornia.ipynb)で詳細を学ぶことができます。
|
| 385 |
+
|
| 386 |
+
ここでは、[`Compose`](https://pytorch.org/vision/master/generated/torchvision.transforms.Compose.html)を使用していくつかの変換を連鎖させます - [`RandomResizedCrop`](https://pytorch.org/vision/main/generated/torchvision.transforms.RandomResizedCrop.html)と[`ColorJitter`](https://pytorch.org/vision/main/generated/torchvision.transforms.ColorJitter.html)。
|
| 387 |
+
サイズの変更に関しては、`image_processor`から画像サイズの要件を取得できます。
|
| 388 |
+
一部のモデルでは、正確な高さと幅が必要ですが、他のモデルでは`shortest_edge`のみが定義されています。
|
| 389 |
+
|
| 390 |
+
```py
|
| 391 |
+
>>> from torchvision.transforms import RandomResizedCrop, ColorJitter, Compose
|
| 392 |
+
|
| 393 |
+
>>> size = (
|
| 394 |
+
... image_processor.size["shortest_edge"]
|
| 395 |
+
... if "shortest_edge" in image_processor.size
|
| 396 |
+
... else (image_processor.size["height"], image_processor.size["width"])
|
| 397 |
+
... )
|
| 398 |
+
|
| 399 |
+
>>> _transforms = Compose([RandomResizedCrop(size), ColorJitter(brightness=0.5, hue=0.5)])
|
| 400 |
+
```
|
| 401 |
+
|
| 402 |
+
2. モデルは[`pixel_values`](model_doc/visionencoderdecoder#transformers.VisionEncoderDecoderModel.forward.pixel_values)を入力として受け取ります。
|
| 403 |
+
`ImageProcessor`は画像の正規化と適切なテンソルの生成を処理できます。
|
| 404 |
+
一連の画像に対する画像拡張と画像前処理を組み合わせ、`pixel_values`を生成する関数を作成します:
|
| 405 |
+
|
| 406 |
+
```python
|
| 407 |
+
>>> def transforms(examples):
|
| 408 |
+
... images = [_transforms(img.convert("RGB")) for img in examples["image"]]
|
| 409 |
+
... examples["pixel_values"] = image_processor(images, do_resize=False, return_tensors="pt")["pixel_values"]
|
| 410 |
+
... return examples
|
| 411 |
+
```
|
| 412 |
+
|
| 413 |
+
<Tip>
|
| 414 |
+
|
| 415 |
+
上記の例では、画像のサイズ変更を既に画像増強変換で行っているため、`do_resize=False`を設定しました。
|
| 416 |
+
適切な `image_processor` からの `size` 属性を活用しています。画像増強中に画像のサイズ変更を行わない場合は、このパラメータを省略してください。
|
| 417 |
+
デフォルトでは、`ImageProcessor` がサイズ変更を処理します。
|
| 418 |
+
|
| 419 |
+
画像を増強変換の一部として正規化したい場合は、`image_processor.image_mean` と `image_processor.image_std` の値を使用してください。
|
| 420 |
+
</Tip>
|
| 421 |
+
|
| 422 |
+
3. 次に、🤗 Datasetsの[`set_transform`](https://huggingface.co/docs/datasets/process#format-transform)を使用して、変換をリアルタイムで適用します:
|
| 423 |
+
|
| 424 |
+
```python
|
| 425 |
+
>>> dataset.set_transform(transforms)
|
| 426 |
+
```
|
| 427 |
+
|
| 428 |
+
4. 画像にアクセスすると、画像プロセッサが `pixel_values` を追加したことがわかります。これで処理済みのデータセットをモデルに渡すことができます!
|
| 429 |
+
|
| 430 |
+
```python
|
| 431 |
+
>>> dataset[0].keys()
|
| 432 |
+
```
|
| 433 |
+
|
| 434 |
+
以下は、変換が適用された後の画像の外観です。 画像はランダムに切り抜かれ、その色の特性も異なります。
|
| 435 |
+
|
| 436 |
+
```py
|
| 437 |
+
>>> import numpy as np
|
| 438 |
+
>>> import matplotlib.pyplot as plt
|
| 439 |
+
|
| 440 |
+
>>> img = dataset[0]["pixel_values"]
|
| 441 |
+
>>> plt.imshow(img.permute(1, 2, 0))
|
| 442 |
+
```
|
| 443 |
+
|
| 444 |
+
<div class="flex justify-center">
|
| 445 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/preprocessed_image.png"/>
|
| 446 |
+
</div>
|
| 447 |
+
|
| 448 |
+
<Tip>
|
| 449 |
+
|
| 450 |
+
オブジェクト検出、意味セグメンテーション、インスタンスセグメンテーション、およびパノプティックセグメンテーションなどのタスクの場合、`ImageProcessor`は
|
| 451 |
+
ポスト処理メソッドを提供します。これらのメソッドは、モデルの生の出力を境界ボックスやセグメンテーションマップなどの意味のある予測に変換します。
|
| 452 |
+
|
| 453 |
+
</Tip>
|
| 454 |
+
|
| 455 |
+
### Pad
|
| 456 |
+
|
| 457 |
+
一部の場合、たとえば、[DETR](./model_doc/detr)をファインチューニングする場合、モデルはトレーニング時にスケールの変更を適用します。
|
| 458 |
+
これにより���バッチ内の画像のサイズが異なる場合があります。[`DetrImageProcessor`]から[`DetrImageProcessor.pad`]を使用し、
|
| 459 |
+
カスタムの`collate_fn`を定義して画像を一緒にバッチ処理できます。
|
| 460 |
+
|
| 461 |
+
```py
|
| 462 |
+
>>> def collate_fn(batch):
|
| 463 |
+
... pixel_values = [item["pixel_values"] for item in batch]
|
| 464 |
+
... encoding = image_processor.pad(pixel_values, return_tensors="pt")
|
| 465 |
+
... labels = [item["labels"] for item in batch]
|
| 466 |
+
... batch = {}
|
| 467 |
+
... batch["pixel_values"] = encoding["pixel_values"]
|
| 468 |
+
... batch["pixel_mask"] = encoding["pixel_mask"]
|
| 469 |
+
... batch["labels"] = labels
|
| 470 |
+
... return batch
|
| 471 |
+
```
|
| 472 |
+
|
| 473 |
+
## Multi Modal
|
| 474 |
+
|
| 475 |
+
マルチモーダル入力を使用するタスクの場合、モデル用にデータセットを準備するための[プロセッサ](main_classes/processors)が必要です。プロセッサは、トークナイザや特徴量抽出器などの2つの処理オブジェクトを結合します。
|
| 476 |
+
|
| 477 |
+
自動音声認識(ASR)のためのプロセッサの使用方法を示すために、[LJ Speech](https://huggingface.co/datasets/lj_speech)データセットをロードします(データセットのロード方法の詳細については🤗 [Datasets チュートリアル](https://huggingface.co/docs/datasets/load_hub)を参照):
|
| 478 |
+
|
| 479 |
+
```python
|
| 480 |
+
>>> from datasets import load_dataset
|
| 481 |
+
|
| 482 |
+
>>> lj_speech = load_dataset("lj_speech", split="train")
|
| 483 |
+
```
|
| 484 |
+
|
| 485 |
+
ASR(自動音声認識)の場合、主に `audio` と `text` に焦点を当てているため、他の列を削除できます:
|
| 486 |
+
|
| 487 |
+
```python
|
| 488 |
+
>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
|
| 489 |
+
```
|
| 490 |
+
|
| 491 |
+
次に、`audio`と`text`の列を見てみましょう:
|
| 492 |
+
|
| 493 |
+
```python
|
| 494 |
+
>>> lj_speech[0]["audio"]
|
| 495 |
+
{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
|
| 496 |
+
7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
|
| 497 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
|
| 498 |
+
'sampling_rate': 22050}
|
| 499 |
+
|
| 500 |
+
>>> lj_speech[0]["text"]
|
| 501 |
+
'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
|
| 502 |
+
```
|
| 503 |
+
|
| 504 |
+
常に、オーディオデータセットのサンプリングレートを、モデルの事前学習に使用されたデータセットのサンプリングレートと一致させるように[リサンプル](preprocessing#audio)する必要があります!
|
| 505 |
+
|
| 506 |
+
```py
|
| 507 |
+
>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
|
| 508 |
+
```
|
| 509 |
+
|
| 510 |
+
プロセッサを [`AutoProcessor.from_pretrained`] を使用してロードします:
|
| 511 |
+
|
| 512 |
+
```py
|
| 513 |
+
>>> from transformers import AutoProcessor
|
| 514 |
+
|
| 515 |
+
>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
|
| 516 |
+
```
|
| 517 |
+
|
| 518 |
+
1. `array`内に含まれるオーディオデータを`input_values`に処理し、`text`を`labels`にトークン化する関数を作成します:
|
| 519 |
+
|
| 520 |
+
```py
|
| 521 |
+
>>> def prepare_dataset(example):
|
| 522 |
+
... audio = example["audio"]
|
| 523 |
+
|
| 524 |
+
... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
|
| 525 |
+
|
| 526 |
+
... return example
|
| 527 |
+
```
|
| 528 |
+
|
| 529 |
+
2. サンプルに`prepare_dataset`関数を適用します:
|
| 530 |
+
|
| 531 |
+
```py
|
| 532 |
+
>>> prepare_dataset(lj_speech[0])
|
| 533 |
+
```
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/quicktour.md
ADDED
|
@@ -0,0 +1,588 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--
|
| 2 |
+
Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 5 |
+
the License. You may obtain a copy of the License at
|
| 6 |
+
|
| 7 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
|
| 9 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 10 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 11 |
+
specific language governing permissions and limitations under the License.
|
| 12 |
+
|
| 13 |
+
⚠️ このファイルはMarkdown形式ですが、Hugging Faceのドキュメントビルダー向けに特定の構文を含んでいるため、
|
| 14 |
+
通常のMarkdownビューアーで正しく表示されないことに注意してください。
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Quick tour
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
🤗 Transformersを使い始めましょう! 開発者であろうと、日常的なユーザーであろうと、このクイックツアーは
|
| 22 |
+
初めて始めるのを支援し、[`pipeline`]を使った推論方法、[AutoClass](./model_doc/auto)で事前学習済みモデルとプリプロセッサをロードする方法、
|
| 23 |
+
そしてPyTorchまたはTensorFlowで素早くモデルをトレーニングする方法を示します。 初心者の場合、ここで紹介されたコンセプトの詳細な説明を提供する
|
| 24 |
+
チュートリアルまたは[コース](https://huggingface.co/course/chapter1/1)を次に参照することをお勧めします。
|
| 25 |
+
|
| 26 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください:
|
| 27 |
+
|
| 28 |
+
```bash
|
| 29 |
+
!pip install transformers datasets evaluate accelerate
|
| 30 |
+
```
|
| 31 |
+
|
| 32 |
+
あなたはまた、好きな機械学習フレームワークをインストールする必要があります:
|
| 33 |
+
|
| 34 |
+
<frameworkcontent>
|
| 35 |
+
<pt>
|
| 36 |
+
|
| 37 |
+
```bash
|
| 38 |
+
pip install torch
|
| 39 |
+
```
|
| 40 |
+
</pt>
|
| 41 |
+
<tf>
|
| 42 |
+
|
| 43 |
+
```bash
|
| 44 |
+
pip install tensorflow
|
| 45 |
+
```
|
| 46 |
+
</tf>
|
| 47 |
+
</frameworkcontent>
|
| 48 |
+
|
| 49 |
+
## Pipeline
|
| 50 |
+
|
| 51 |
+
<Youtube id="tiZFewofSLM"/>
|
| 52 |
+
|
| 53 |
+
[`pipeline`] は、事前学習済みモデルを推論に最も簡単で高速な方法です。
|
| 54 |
+
[`pipeline`] を使用することで、さまざまなモダリティにわたる多くのタスクに対して即座に使用できます。
|
| 55 |
+
いくつかのタスクは以下の表に示されています:
|
| 56 |
+
|
| 57 |
+
<Tip>
|
| 58 |
+
|
| 59 |
+
使用可能なタスクの完全な一覧については、[pipeline API リファレンス](./main_classes/pipelines)を確認してください。
|
| 60 |
+
|
| 61 |
+
</Tip>
|
| 62 |
+
|
| 63 |
+
| **タスク** | **説明** | **モダリティ** | **パイプライン識別子** |
|
| 64 |
+
|------------------------------|--------------------------------------------------------------------------------------------------------------|-----------------|-----------------------------------------------|
|
| 65 |
+
| テキスト分類 | テキストのシーケンスにラベルを割り当てる | NLP | pipeline(task="sentiment-analysis") |
|
| 66 |
+
| テキスト生成 | プロンプトを指定してテキストを生成する | NLP | pipeline(task="text-generation") |
|
| 67 |
+
| 要約 | テキストまたはドキュメントの要約を生成する | NLP | pipeline(task="summarization") |
|
| 68 |
+
| 画像分類 | 画像にラベルを割り当てる | コンピュータビジョン | pipeline(task="image-classification") |
|
| 69 |
+
| 画像セグメンテーション | 画像の各個別のピクセルにラベルを割り当てる(セマンティック、パノプティック、およびインスタンスセグメンテーションをサポート) | コンピュータビジョン | pipeline(task="image-segmentation") |
|
| 70 |
+
| オブジェクト検出 | 画像内のオブジェクトの境界ボックスとクラスを予測する | コンピュータビジョン | pipeline(task="object-detection") |
|
| 71 |
+
| オーディオ分類 | オーディオデータにラベルを割り当てる | オーディオ | pipeline(task="audio-classification") |
|
| 72 |
+
| 自動音声認識 | 音声をテキストに変換する | オーディオ | pipeline(task="automatic-speech-recognition") |
|
| 73 |
+
| ビジュアルクエスチョン応答 | 画像と質問が与えられた場合に、画像に関���る質問に回答する | マルチモーダル | pipeline(task="vqa") |
|
| 74 |
+
| ドキュメントクエスチョン応答 | ドキュメントと質問が与えられた場合に、ドキュメントに関する質問に回答する | マルチモーダル | pipeline(task="document-question-answering") |
|
| 75 |
+
| 画像キャプショニング | 与えられた画像にキャプションを生成する | マルチモーダル | pipeline(task="image-to-text") |
|
| 76 |
+
|
| 77 |
+
まず、[`pipeline`] のインスタンスを作成し、使用したいタスクを指定します。
|
| 78 |
+
このガイドでは、センチメント分析のために [`pipeline`] を使用する例を示します:
|
| 79 |
+
|
| 80 |
+
```python
|
| 81 |
+
>>> from transformers import pipeline
|
| 82 |
+
|
| 83 |
+
>>> classifier = pipeline("sentiment-analysis")
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
[`pipeline`]は、感情分析のためのデフォルトの[事前学習済みモデル](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english)とトークナイザをダウンロードしてキャッシュし、使用できるようになります。
|
| 87 |
+
これで、`classifier`を対象のテキストに使用できます:
|
| 88 |
+
|
| 89 |
+
```python
|
| 90 |
+
>>> classifier("私たちは🤗 Transformersライブラリをお見せできてとても嬉しいです。")
|
| 91 |
+
[{'label': 'POSITIVE', 'score': 0.9998}]
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
複数の入力がある場合は、[`pipeline`]に入力をリストとして渡して、辞書のリストを返します:
|
| 95 |
+
|
| 96 |
+
```py
|
| 97 |
+
>>> results = classifier(["🤗 Transformersライブラリをご紹介できて非常に嬉しいです。", "嫌いにならないでほしいです。"])
|
| 98 |
+
>>> for result in results:
|
| 99 |
+
... print(f"label: {result['label']}, スコア: {round(result['score'], 4)}")
|
| 100 |
+
label: POSITIVE, スコア: 0.9998
|
| 101 |
+
label: NEGATIVE, スコア: 0.5309
|
| 102 |
+
```
|
| 103 |
+
|
| 104 |
+
[`pipeline`]は、任意のタスクに対してデータセット全体を繰り返し処理することもできます。この例では、自動音声認識をタスクとして選びましょう:
|
| 105 |
+
|
| 106 |
+
```python
|
| 107 |
+
>>> import torch
|
| 108 |
+
>>> from transformers import pipeline
|
| 109 |
+
|
| 110 |
+
>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
オーディオデータセットをロードします(詳細については🤗 Datasets [クイックスタート](https://huggingface.co/docs/datasets/quickstart#audio)を参照してください)。
|
| 114 |
+
たとえば、[MInDS-14](https://huggingface.co/datasets/PolyAI/minds14)データセットをロードします:
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
>>> from datasets import load_dataset, Audio
|
| 118 |
+
|
| 119 |
+
>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
データセットのサンプリングレートが[`facebook/wav2vec2-base-960h`](https://huggingface.co/facebook/wav2vec2-base-960h)がトレーニングされたサンプリングレートと一致することを確認してください:
|
| 123 |
+
|
| 124 |
+
```py
|
| 125 |
+
>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
"audio"列を呼び出すと、オーディオファイルは自動的にロードされ、リサンプリングされます。最初の4つのサンプルから生の波形配列を抽出し、それをパイプラインにリストとして渡します。
|
| 129 |
+
|
| 130 |
+
```py
|
| 131 |
+
>>> result = speech_recognizer(dataset[:4]["audio"])
|
| 132 |
+
>>> print([d["text"] for d in result])
|
| 133 |
+
['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HELL T WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AN I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I FURN A JOINA COUT']
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
大規模なデータセットで、入力が大きい場合(音声や画像など)、すべての入力をメモリに読み込む代わりに、リストではなくジェネレータを渡すことがお勧めです。詳細については[パイプラインAPIリファレンス](./main_classes/pipelines)を参照してください。
|
| 137 |
+
|
| 138 |
+
### Use another model and tokenizer in the pipeline
|
| 139 |
+
|
| 140 |
+
[`pipeline`]は[Hub](https://huggingface.co/models)からの任意のモデルを収容でき、他のユースケースに[`pipeline`]を適応させることが容易です。たとえば、フランス語のテキストを処理できるモデルが必要な場合、Hubのタグを使用して適切なモデルをフィルタリングできます。トップのフィルタリングされた結果は、フランス語のテキストに使用できる感情分析用に調整された多言語の[BERTモデル](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment)を返します:
|
| 141 |
+
|
| 142 |
+
```py
|
| 143 |
+
>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
|
| 144 |
+
```
|
| 145 |
+
|
| 146 |
+
<frameworkcontent>
|
| 147 |
+
<pt>
|
| 148 |
+
[`AutoModelForSequenceClassification`]と[`AutoTokenizer`]を使用して事前学習済みモデルとそれに関連するトークナイザをロードします(次のセクションで`AutoClass`について詳しく説明します):
|
| 149 |
+
|
| 150 |
+
```python
|
| 151 |
+
>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
|
| 152 |
+
|
| 153 |
+
>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
|
| 154 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
|
| 155 |
+
```
|
| 156 |
+
|
| 157 |
+
</pt>
|
| 158 |
+
<tf>
|
| 159 |
+
以下のコードは、[`TFAutoModelForSequenceClassification`]および[`AutoTokenizer`]を使用して、事前学習済みモデルとその関連するトークナイザをロードする方法を示しています(`TFAutoClass`については次のセクションで詳しく説明します):
|
| 160 |
+
|
| 161 |
+
```python
|
| 162 |
+
>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
|
| 163 |
+
|
| 164 |
+
>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
|
| 165 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
|
| 166 |
+
```
|
| 167 |
+
</tf>
|
| 168 |
+
</frameworkcontent>
|
| 169 |
+
|
| 170 |
+
指定したモデルとトークナイザを[`pipeline`]に設定し、今度はフランス語のテキストに`classifier`を適用できます:
|
| 171 |
+
|
| 172 |
+
```py
|
| 173 |
+
>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
|
| 174 |
+
>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
|
| 175 |
+
[{'label': '5 stars', 'score': 0.7273}]
|
| 176 |
+
```
|
| 177 |
+
|
| 178 |
+
もし、あなたのユースケースに適したモデルが見つからない場合、事前学習済みモデルをあなたのデータでファインチューニングする必要があります。
|
| 179 |
+
ファインチューニングの方法については、[ファインチューニングのチュートリアル](./training)をご覧ください。
|
| 180 |
+
最後に、ファインチューニングした事前学習済みモデルを共有し、コミュニティと共有ハブで共有することを検討してください。これにより、機械学習を民主化する手助けができます! 🤗
|
| 181 |
+
|
| 182 |
+
## AutoClass
|
| 183 |
+
|
| 184 |
+
<Youtube id="AhChOFRegn4"/>
|
| 185 |
+
|
| 186 |
+
[`AutoModelForSequenceClassification`] および [`AutoTokenizer`] クラスは、上記で使用した [`pipeline`] を駆動するために協力して動作します。
|
| 187 |
+
[AutoClass](./model_doc/auto) は、事前学習済みモデルのアーキテクチャをその名前またはパスから自動的に取得するショートカットです。
|
| 188 |
+
適切な `AutoClass` を選択し、それに関連する前処理クラスを選択するだけで済みます。
|
| 189 |
+
|
| 190 |
+
前のセクションからの例に戻り、`AutoClass` を使用して [`pipeline`] の結果を再現する方法を見てみましょう。
|
| 191 |
+
|
| 192 |
+
### AutoTokenizer
|
| 193 |
+
|
| 194 |
+
トークナイザはテキストをモデルの入力として使用できる数値の配列に前処理する役割を果たします。
|
| 195 |
+
トークナイゼーションプロセスには、単語をどのように分割するかや、単語をどのレベルで分割するかといった多くのルールがあります
|
| 196 |
+
(トークナイゼーションについての詳細は [トークナイザサマリー](./tokenizer_summary) をご覧ください)。
|
| 197 |
+
最も重要なことは、モデルが事前学習済みになったときと同じトークナイゼーションルールを使用するために、同じモデル名でトークナイザをインスタンス化する必要があることです。
|
| 198 |
+
|
| 199 |
+
[`AutoTokenizer`] を使用してトークナイザをロードします:
|
| 200 |
+
|
| 201 |
+
```python
|
| 202 |
+
>>> from transformers import AutoTokenizer
|
| 203 |
+
|
| 204 |
+
>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
|
| 205 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
|
| 206 |
+
```
|
| 207 |
+
|
| 208 |
+
Pass your text to the tokenizer:
|
| 209 |
+
|
| 210 |
+
```python
|
| 211 |
+
>>> encoding = tokenizer("私たちは🤗 Transformersライブラリをお見せできてとても嬉しいです。")
|
| 212 |
+
>>> print(encoding)
|
| 213 |
+
{'input_ids': [101, 11312, 10320, 12495, 19308, 10114, 11391, 10855, 10103, 100, 58263, 13299, 119, 102],
|
| 214 |
+
'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 215 |
+
'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
|
| 216 |
+
```
|
| 217 |
+
|
| 218 |
+
トークナイザは、次の情報を含む辞書を返します:
|
| 219 |
+
|
| 220 |
+
- [input_ids](./glossary#input-ids): トークンの数値表現。
|
| 221 |
+
- [attention_mask](.glossary#attention-mask): どのトークンにアテンションを向けるかを示します。
|
| 222 |
+
|
| 223 |
+
トークナイザはまた、入力のリストを受け入れ、一様な長さのバッチを返すためにテキストをパディングおよび切り詰めることができます。
|
| 224 |
+
|
| 225 |
+
<frameworkcontent>
|
| 226 |
+
<pt>
|
| 227 |
+
|
| 228 |
+
```py
|
| 229 |
+
>>> pt_batch = tokenizer(
|
| 230 |
+
... ["🤗 Transformersライブラリをお見せできて非常に嬉しいです。", "嫌いではないことを願っています。"],
|
| 231 |
+
... padding=True,
|
| 232 |
+
... truncation=True,
|
| 233 |
+
... max_length=512,
|
| 234 |
+
... return_tensors="pt",
|
| 235 |
+
... )
|
| 236 |
+
```
|
| 237 |
+
</pt>
|
| 238 |
+
<tf>
|
| 239 |
+
|
| 240 |
+
```py
|
| 241 |
+
>>> tf_batch = tokenizer(
|
| 242 |
+
... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
|
| 243 |
+
... padding=True,
|
| 244 |
+
... truncation=True,
|
| 245 |
+
... max_length=512,
|
| 246 |
+
... return_tensors="tf",
|
| 247 |
+
... )
|
| 248 |
+
```
|
| 249 |
+
</tf>
|
| 250 |
+
</frameworkcontent>
|
| 251 |
+
|
| 252 |
+
<Tip>
|
| 253 |
+
|
| 254 |
+
[前処理](./preprocessing)チュートリアルをご覧いただき、トークナイゼーションの詳細や、[`AutoImageProcessor`]、[`AutoFeatureExtractor`]、[`AutoProcessor`]を使用して画像、オーディオ、およびマルチモーダル入力を前処理する方法について詳しく説明されているページもご覧ください。
|
| 255 |
+
|
| 256 |
+
</Tip>
|
| 257 |
+
|
| 258 |
+
### AutoModel
|
| 259 |
+
|
| 260 |
+
<frameworkcontent>
|
| 261 |
+
<pt>
|
| 262 |
+
🤗 Transformersは事前学習済みインスタンスを簡単に統一的にロードする方法を提供します。
|
| 263 |
+
これは、[`AutoTokenizer`]をロードするのと同じように[`AutoModel`]をロードできることを意味します。
|
| 264 |
+
タスクに適した[`AutoModel`]を選択する以外の違いはありません。
|
| 265 |
+
テキスト(またはシーケンス)分類の場合、[`AutoModelForSequenceClassification`]をロードする必要があります:
|
| 266 |
+
|
| 267 |
+
```py
|
| 268 |
+
>>> from transformers import AutoModelForSequenceClassification
|
| 269 |
+
|
| 270 |
+
>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
|
| 271 |
+
>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
|
| 272 |
+
```
|
| 273 |
+
|
| 274 |
+
<Tip>
|
| 275 |
+
|
| 276 |
+
[`AutoModel`]クラスでサポートされているタスクに関する詳細については、[タスクの概要](./task_summary)を参照してください。
|
| 277 |
+
|
| 278 |
+
</Tip>
|
| 279 |
+
|
| 280 |
+
今、前処理済みのバッチを直接モデルに渡します。辞書を展開するだけで、`**`を追加する必要があります:
|
| 281 |
+
|
| 282 |
+
```python
|
| 283 |
+
>>> pt_outputs = pt_model(**pt_batch)
|
| 284 |
+
```
|
| 285 |
+
|
| 286 |
+
モデルは、`logits`属性に最終的なアクティベーションを出力します。 `logits`にsoftmax関数を適用して確率を取得します:
|
| 287 |
+
|
| 288 |
+
```py
|
| 289 |
+
>>> from torch import nn
|
| 290 |
+
|
| 291 |
+
>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
|
| 292 |
+
>>> print(pt_predictions)
|
| 293 |
+
tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
|
| 294 |
+
[0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=<SoftmaxBackward0>)
|
| 295 |
+
```
|
| 296 |
+
|
| 297 |
+
</pt>
|
| 298 |
+
<tf>
|
| 299 |
+
🤗 Transformersは事前学習済みインスタンスをロードするためのシンプルで統一された方法を提供します。
|
| 300 |
+
これは、[`TFAutoModel`]を[`AutoTokenizer`]をロードするのと同じようにロードできることを意味します。
|
| 301 |
+
唯一の違いは、タスクに適した[`TFAutoModel`]を選択することです。
|
| 302 |
+
テキスト(またはシーケンス)分類の場合、[`TFAutoModelForSequenceClassification`]をロードする必要があります:
|
| 303 |
+
|
| 304 |
+
```py
|
| 305 |
+
>>> from transformers import TFAutoModelForSequenceClassification
|
| 306 |
+
|
| 307 |
+
>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
|
| 308 |
+
>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
|
| 309 |
+
```
|
| 310 |
+
|
| 311 |
+
<Tip>
|
| 312 |
+
|
| 313 |
+
詳細については、[`AutoModel`]クラスでサポートされているタスクに関する情報は、[タスクの概要](./task_summary)を参照してください。
|
| 314 |
+
|
| 315 |
+
</Tip>
|
| 316 |
+
|
| 317 |
+
次に、前処理済みのバッチを直接モデルに渡します。テンソルをそのまま渡すことができます:
|
| 318 |
+
|
| 319 |
+
```python
|
| 320 |
+
>>> tf_outputs = tf_model(tf_batch)
|
| 321 |
+
```
|
| 322 |
+
|
| 323 |
+
モデルは`logits`属性に最終的なアクティベーションを出力します。`logits`にソフトマックス関数を適用して確率を取得します:
|
| 324 |
+
|
| 325 |
+
```python
|
| 326 |
+
>>> import tensorflow as tf
|
| 327 |
+
|
| 328 |
+
>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
|
| 329 |
+
>>> tf_predictions # doctest: +IGNORE_RESULT
|
| 330 |
+
```
|
| 331 |
+
|
| 332 |
+
</tf>
|
| 333 |
+
</frameworkcontent>
|
| 334 |
+
|
| 335 |
+
<Tip>
|
| 336 |
+
|
| 337 |
+
🤗 Transformersのすべてのモデル(PyTorchまたはTensorFlow)は、最終的な活性化関数(softmaxなど)*前*のテンソルを出力します。
|
| 338 |
+
最終的な活性化関数は、しばしば損失と結合されているためです。モデルの出力は特別なデータクラスであり、その属性はIDEで自動補完されます。
|
| 339 |
+
モデルの出力は、タプルまたは辞書のように動作します(整数、スライス、または文字列でインデックスを付けることができます)。
|
| 340 |
+
この場合、Noneである属性は無視されます。
|
| 341 |
+
|
| 342 |
+
</Tip>
|
| 343 |
+
|
| 344 |
+
### Save a Model
|
| 345 |
+
|
| 346 |
+
<frameworkcontent>
|
| 347 |
+
<pt>
|
| 348 |
+
モデルをファインチューニングしたら、[`PreTrainedModel.save_pretrained`]を使用してトークナイザと共に保存できます:
|
| 349 |
+
|
| 350 |
+
```py
|
| 351 |
+
>>> pt_save_directory = "./pt_save_pretrained"
|
| 352 |
+
>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
|
| 353 |
+
>>> pt_model.save_pretrained(pt_save_directory)
|
| 354 |
+
```
|
| 355 |
+
|
| 356 |
+
再びモデルを使用する準備ができたら、[`PreTrainedModel.from_pretrained`]を使用して再度ロードします:
|
| 357 |
+
|
| 358 |
+
```py
|
| 359 |
+
>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
|
| 360 |
+
```
|
| 361 |
+
|
| 362 |
+
</pt>
|
| 363 |
+
<tf>
|
| 364 |
+
モデルをファインチューニングし���ら、そのトークナイザを使用してモデルを保存できます。[`TFPreTrainedModel.save_pretrained`]を使用します:
|
| 365 |
+
|
| 366 |
+
```py
|
| 367 |
+
>>> tf_save_directory = "./tf_save_pretrained"
|
| 368 |
+
>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
|
| 369 |
+
>>> tf_model.save_pretrained(tf_save_directory)
|
| 370 |
+
```
|
| 371 |
+
|
| 372 |
+
モデルを再度使用する準備ができたら、[`TFPreTrainedModel.from_pretrained`]を使用して再度ロードします:
|
| 373 |
+
|
| 374 |
+
```py
|
| 375 |
+
>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
|
| 376 |
+
```
|
| 377 |
+
|
| 378 |
+
</tf>
|
| 379 |
+
</frameworkcontent>
|
| 380 |
+
|
| 381 |
+
🤗 Transformersの特に素晴らしい機能の一つは、モデルを保存し、それをPyTorchモデルまたはTensorFlowモデルとして再ロードできることです。 `from_pt`または`from_tf`パラメータを使用してモデルをフレームワーク間で変換できます:
|
| 382 |
+
|
| 383 |
+
<frameworkcontent>
|
| 384 |
+
<pt>
|
| 385 |
+
|
| 386 |
+
```py
|
| 387 |
+
>>> from transformers import AutoModel
|
| 388 |
+
|
| 389 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
|
| 390 |
+
>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
|
| 391 |
+
```
|
| 392 |
+
|
| 393 |
+
</pt>
|
| 394 |
+
<tf>
|
| 395 |
+
|
| 396 |
+
```py
|
| 397 |
+
>>> from transformers import TFAutoModel
|
| 398 |
+
|
| 399 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
|
| 400 |
+
>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
|
| 401 |
+
```
|
| 402 |
+
</tf>
|
| 403 |
+
</frameworkcontent>
|
| 404 |
+
|
| 405 |
+
## Custom model builds
|
| 406 |
+
|
| 407 |
+
モデルを構築方法を変更するには、モデルの設定クラスを変更できます。設定はモデルの属性を指定します。例えば、隠れ層の数やアテンションヘッドの数などがこれに含まれます。カスタム設定クラスからモデルを初期化する際には、ゼロから始めます。モデルの属性はランダムに初期化され、有意義な結果を得るためにモデルをトレーニングする必要があります。
|
| 408 |
+
|
| 409 |
+
最初に[`AutoConfig`]をインポートし、変更したい事前学習済みモデルをロードします。[`AutoConfig.from_pretrained`]内で、変更したい属性(例:アテンションヘッドの数)を指定できます:
|
| 410 |
+
|
| 411 |
+
```python
|
| 412 |
+
>>> from transformers import AutoConfig
|
| 413 |
+
|
| 414 |
+
>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
|
| 415 |
+
```
|
| 416 |
+
|
| 417 |
+
<frameworkcontent>
|
| 418 |
+
<pt>
|
| 419 |
+
[`AutoModel.from_config`]を使用してカスタム設定からモデルを作成します:
|
| 420 |
+
|
| 421 |
+
```python
|
| 422 |
+
>>> from transformers import AutoModel
|
| 423 |
+
|
| 424 |
+
>>> my_model = AutoModel.from_config(my_config)
|
| 425 |
+
```
|
| 426 |
+
|
| 427 |
+
</pt>
|
| 428 |
+
<tf>
|
| 429 |
+
カスタム構成からモデルを作成するには、[`TFAutoModel.from_config`]を使用します:
|
| 430 |
+
|
| 431 |
+
```py
|
| 432 |
+
>>> from transformers import TFAutoModel
|
| 433 |
+
|
| 434 |
+
>>> my_model = TFAutoModel.from_config(my_config)
|
| 435 |
+
```
|
| 436 |
+
|
| 437 |
+
</tf>
|
| 438 |
+
</frameworkcontent>
|
| 439 |
+
|
| 440 |
+
[カスタムアーキテクチャを作成](./create_a_model)ガイドを参照して、カスタム構成の詳細情報を確認してください。
|
| 441 |
+
|
| 442 |
+
## Trainer - PyTorch向けの最適化されたトレーニングループ
|
| 443 |
+
|
| 444 |
+
すべてのモデルは標準の[`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)であるため、通常のトレーニングループで使用できます。
|
| 445 |
+
独自のトレーニングループを作成できますが、🤗 TransformersはPyTorch向けに[`Trainer`]クラスを提供しており、基本的なトレーニングループに加えて、
|
| 446 |
+
分散トレーニング、混合精度などの機能の追加を行っています。
|
| 447 |
+
|
| 448 |
+
タスクに応じて、通常は[`Trainer`]に以下のパラメータを渡します:
|
| 449 |
+
|
| 450 |
+
1. [`PreTrainedModel`]または[`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)から始めます:
|
| 451 |
+
|
| 452 |
+
```py
|
| 453 |
+
>>> from transformers import AutoModelForSequenceClassification
|
| 454 |
+
|
| 455 |
+
>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
|
| 456 |
+
```
|
| 457 |
+
|
| 458 |
+
2. [`TrainingArguments`]には、変更できるモデルのハイパーパラメータが含まれており、学習率、バッチサイズ、トレーニングエポック数などが変更できます。指定しない場合、デフォルト値が使用されます:
|
| 459 |
+
|
| 460 |
+
```py
|
| 461 |
+
>>> from transformers import TrainingArguments
|
| 462 |
+
|
| 463 |
+
>>> training_args = TrainingArguments(
|
| 464 |
+
... output_dir="path/to/save/folder/",
|
| 465 |
+
... learning_rate=2e-5,
|
| 466 |
+
... per_device_train_batch_size=8,
|
| 467 |
+
... per_device_eval_batch_size=8,
|
| 468 |
+
... num_train_epochs=2,
|
| 469 |
+
... )
|
| 470 |
+
```
|
| 471 |
+
|
| 472 |
+
3. トークナイザ、画像プロセッサ、特徴量抽出器、またはプロセッサのような前処理クラスをロードします:
|
| 473 |
+
|
| 474 |
+
```py
|
| 475 |
+
>>> from transformers import AutoTokenizer
|
| 476 |
+
|
| 477 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
|
| 478 |
+
```
|
| 479 |
+
|
| 480 |
+
4. データセットをロードする:
|
| 481 |
+
|
| 482 |
+
```py
|
| 483 |
+
>>> from datasets import load_dataset
|
| 484 |
+
|
| 485 |
+
>>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
|
| 486 |
+
```
|
| 487 |
+
|
| 488 |
+
5. データセットをトークン化するための関数を作成します:
|
| 489 |
+
|
| 490 |
+
```python
|
| 491 |
+
>>> def tokenize_dataset(dataset):
|
| 492 |
+
... return tokenizer(dataset["text"])
|
| 493 |
+
```
|
| 494 |
+
|
| 495 |
+
その後、[`~datasets.Dataset.map`]を使用してデータセット全体に適用します:
|
| 496 |
+
|
| 497 |
+
```python
|
| 498 |
+
>>> dataset = dataset.map(tokenize_dataset, batched=True)
|
| 499 |
+
```
|
| 500 |
+
|
| 501 |
+
6. データセットからの例のバッチを作成するための [`DataCollatorWithPadding`]:
|
| 502 |
+
|
| 503 |
+
```py
|
| 504 |
+
>>> from transformers import DataCollatorWithPadding
|
| 505 |
+
|
| 506 |
+
>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
|
| 507 |
+
```
|
| 508 |
+
|
| 509 |
+
次に、これらのクラスを[`Trainer`]にまとめます:
|
| 510 |
+
|
| 511 |
+
```python
|
| 512 |
+
>>> from transformers import Trainer
|
| 513 |
+
|
| 514 |
+
>>> trainer = Trainer(
|
| 515 |
+
... model=model,
|
| 516 |
+
... args=training_args,
|
| 517 |
+
... train_dataset=dataset["train"],
|
| 518 |
+
... eval_dataset=dataset["test"],
|
| 519 |
+
... processing_class=tokenizer,
|
| 520 |
+
... data_collator=data_collator,
|
| 521 |
+
... ) # doctest: +SKIP
|
| 522 |
+
```
|
| 523 |
+
|
| 524 |
+
訓練を開始する準備ができたら、[`~Trainer.train`]を呼び出してトレーニングを開始します:
|
| 525 |
+
|
| 526 |
+
```py
|
| 527 |
+
>>> trainer.train() # doctest: +SKIP
|
| 528 |
+
```
|
| 529 |
+
|
| 530 |
+
<Tip>
|
| 531 |
+
|
| 532 |
+
翻訳や要約など、シーケンス間モデルを使用するタスクには、代わりに[`Seq2SeqTrainer`]と[`Seq2SeqTrainingArguments`]クラスを使用してください。
|
| 533 |
+
|
| 534 |
+
</Tip>
|
| 535 |
+
|
| 536 |
+
[`Trainer`]内のメソッドをサブクラス化することで、トレーニングループの動作をカスタマイズできます。これにより、損失関数、オプティマイザ、スケジューラなどの機能をカスタマイズできます。サブクラス化できるメソッドの一覧については、[`Trainer`]リファレンスをご覧ください。
|
| 537 |
+
|
| 538 |
+
トレーニングループをカスタマイズする別の方法は、[Callbacks](./main_classes/callback)を使用することです。コールバックを使用して他のライブラリと統合し、トレーニングループを監視して進捗状況を報告したり、トレーニングを早期に停止したりできます。コールバックはトレーニングループ自体には何も変更を加えません。損失関数などのカスタマイズを行う場合は、[`Trainer`]をサブクラス化する必要があります。
|
| 539 |
+
|
| 540 |
+
## Train with TensorFlow
|
| 541 |
+
|
| 542 |
+
すべてのモデルは標準の[`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)であるため、[Keras](https://keras.io/) APIを使用してTensorFlowでトレーニングできます。
|
| 543 |
+
🤗 Transformersは、データセットを`tf.data.Dataset`として簡単にロードできるようにする[`~TFPreTrainedModel.prepare_tf_dataset`]メソッドを提供しており、Kerasの[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)および[`fit`](https://keras.io/api/models/model_training_apis/#fit-method)メソッドを使用してトレーニングをすぐに開始できます。
|
| 544 |
+
|
| 545 |
+
1. [`TFPreTrainedModel`]または[`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)から始めます:
|
| 546 |
+
|
| 547 |
+
```py
|
| 548 |
+
>>> from transformers import TFAutoModelForSequenceClassification
|
| 549 |
+
|
| 550 |
+
>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
|
| 551 |
+
```
|
| 552 |
+
|
| 553 |
+
2. トークナイザ、画像プロセッサ、特徴量抽出器、またはプロセッサのような前処理クラスをロードします:
|
| 554 |
+
|
| 555 |
+
```py
|
| 556 |
+
>>> from transformers import AutoTokenizer
|
| 557 |
+
|
| 558 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
|
| 559 |
+
```
|
| 560 |
+
|
| 561 |
+
3. データセットをトークナイズするための関数を作成します:
|
| 562 |
+
|
| 563 |
+
```python
|
| 564 |
+
>>> def tokenize_dataset(dataset):
|
| 565 |
+
... return tokenizer(dataset["text"]) # doctest: +SKIP
|
| 566 |
+
```
|
| 567 |
+
|
| 568 |
+
4. [`~datasets.Dataset.map`]を使用してデータセット全体にトークナイザを適用し、データセットとトークナイザを[`~TFPreTrainedModel.prepare_tf_dataset`]に渡します。バッチサイズを変更し、データセットをシャッフルすることもできます。
|
| 569 |
+
|
| 570 |
+
```python
|
| 571 |
+
>>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
|
| 572 |
+
>>> tf_dataset = model.prepare_tf_dataset(
|
| 573 |
+
... dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
|
| 574 |
+
... ) # doctest: +SKIP
|
| 575 |
+
```
|
| 576 |
+
|
| 577 |
+
5. 準備ができたら、`compile`と`fit`を呼び出してトレーニングを開始できます。 Transformersモデルはすべてデフォルトのタスクに関連する損失関数を持っているため、指定しない限り、損失関数を指定する必要はありません。
|
| 578 |
+
|
| 579 |
+
```python
|
| 580 |
+
>>> from tensorflow.keras.optimizers import Adam
|
| 581 |
+
|
| 582 |
+
>>> model.compile(optimizer=Adam(3e-5)) # 損失関数の引数は不要です!
|
| 583 |
+
>>> model.fit(tf
|
| 584 |
+
```
|
| 585 |
+
|
| 586 |
+
## What's next?
|
| 587 |
+
|
| 588 |
+
🤗 Transformersのクイックツアーを完了したら、ガイドをチェックして、カスタムモデルの作成、タスクのためのファインチューニング、スクリプトを使用���たモデルのトレーニングなど、より具体的なことを学ぶことができます。🤗 Transformersのコアコンセプトについてもっと詳しく知りたい場合は、コンセプチュアルガイドを読んでみてください!
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/run_scripts.md
ADDED
|
@@ -0,0 +1,370 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Train with a script
|
| 18 |
+
|
| 19 |
+
🤗 Transformersの[notebooks](./notebooks/README)と一緒に、[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch)、[TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow)、または[JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax)を使用してモデルをトレーニングする方法を示すサンプルスクリプトもあります。
|
| 20 |
+
|
| 21 |
+
また、私たちの[研究プロジェクト](https://github.com/huggingface/transformers/tree/main/examples/research_projects)や[レガシーの例](https://github.com/huggingface/transformers/tree/main/examples/legacy)で使用したスクリプトも見つかります。これらのスクリプトは現在メンテナンスされておらず、おそらく最新バージョンのライブラリと互換性がない特定の🤗 Transformersのバージョンが必要です。
|
| 22 |
+
|
| 23 |
+
サンプルスクリプトはすべての問題でそのまま動作することは期待されておらず、解決しようとしている問題にスクリプトを適応させる必要があるかもしれません。この点をサポートするために、ほとんどのスクリプトはデータがどのように前処理されているかを完全に公開し、必要に応じて編集できるようにしています。
|
| 24 |
+
|
| 25 |
+
サンプルスクリプトで実装したい機能がある場合は、[フォーラム](https://discuss.huggingface.co/)か[イシュートラッカー](https://github.com/huggingface/transformers/issues)で議論してからプルリクエストを提出してください。バグ修正は歓迎しますが、読みやすさのコストで機能を追加するプルリクエストはほとんどマージされない可能性が高いです。
|
| 26 |
+
|
| 27 |
+
このガイドでは、[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization)と[TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization)で実行するサマリゼーショントレーニングスクリプトの実行方法を示します。すべての例は、明示的に指定されていない限り、両方のフレームワークともに動作することが期待されています。
|
| 28 |
+
|
| 29 |
+
## Setup
|
| 30 |
+
|
| 31 |
+
最新バージョンのサンプルスクリプトを正常に実行するには、新しい仮想環境に🤗 Transformersをソースからインストールする必要があります:
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
```bash
|
| 35 |
+
git clone https://github.com/huggingface/transformers
|
| 36 |
+
cd transformers
|
| 37 |
+
pip install .
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
以前のスクリプトのバージョンについては、以下のトグルをクリックしてください:
|
| 41 |
+
|
| 42 |
+
<details>
|
| 43 |
+
<summary>以前の🤗 Transformersのバージョンに関する例</summary>
|
| 44 |
+
<ul>
|
| 45 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v4.5.1/examples">v4.5.1</a></li>
|
| 46 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v4.4.2/examples">v4.4.2</a></li>
|
| 47 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v4.3.3/examples">v4.3.3</a></li>
|
| 48 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v4.2.2/examples">v4.2.2</a></li>
|
| 49 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v4.1.1/examples">v4.1.1</a></li>
|
| 50 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v4.0.1/examples">v4.0.1</a></li>
|
| 51 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v3.5.1/examples">v3.5.1</a></li>
|
| 52 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v3.4.0/examples">v3.4.0</a></li>
|
| 53 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v3.3.1/examples">v3.3.1</a></li>
|
| 54 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v3.2.0/examples">v3.2.0</a></li>
|
| 55 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v3.1.0/examples">v3.1.0</a></li>
|
| 56 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v3.0.2/examples">v3.0.2</a></li>
|
| 57 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.11.0/examples">v2.11.0</a></li>
|
| 58 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.10.0/examples">v2.10.0</a></li>
|
| 59 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.9.1/examples">v2.9.1</a></li>
|
| 60 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.8.0/examples">v2.8.0</a></li>
|
| 61 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.7.0/examples">v2.7.0</a></li>
|
| 62 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.6.0/examples">v2.6.0</a></li>
|
| 63 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.5.1/examples">v2.5.1</a></li>
|
| 64 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.4.0/examples">v2.4.0</a></li>
|
| 65 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.3.0/examples">v2.3.0</a></li>
|
| 66 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.2.0/examples">v2.2.0</a></li>
|
| 67 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.1.0/examples">v2.1.1</a></li>
|
| 68 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v2.0.0/examples">v2.0.0</a></li>
|
| 69 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v1.2.0/examples">v1.2.0</a></li>
|
| 70 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v1.1.0/examples">v1.1.0</a></li>
|
| 71 |
+
<li><a href="https://github.com/huggingface/transformers/tree/v1.0.0/examples">v1.0.0</a></li>
|
| 72 |
+
</ul>
|
| 73 |
+
</details>
|
| 74 |
+
|
| 75 |
+
次に、現在の🤗 Transformersのクローンを特定のバージョンに切り替えてください。たとえば、v3.5.1などです。
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
```bash
|
| 79 |
+
git checkout tags/v3.5.1
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
適切なライブラリバージョンを設定したら、任意の例のフォルダに移動し、例固有の要件をインストールします:
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
```bash
|
| 88 |
+
pip install -r requirements.txt
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
## Run a script
|
| 92 |
+
|
| 93 |
+
<frameworkcontent>
|
| 94 |
+
<pt>
|
| 95 |
+
この例のスクリプトは、🤗 [Datasets](https://huggingface.co/docs/datasets/) ライブラリからデータセットをダウンロードし、前処理を行います。次に、[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) を使用して要約をサポートするアーキテクチャ上でデータセットをファインチューニングします。以下の例では、[CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) データセット上で [T5-small](https://huggingface.co/google-t5/t5-small) をファインチューニングする方法が示されています。T5 モデルは、そのトレーニング方法に起因して追加の `source_prefix` 引数が必要です。このプロンプトにより、T5 はこれが要約タスクであることを知ることができます。
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
```bash
|
| 99 |
+
python examples/pytorch/summarization/run_summarization.py \
|
| 100 |
+
--model_name_or_path google-t5/t5-small \
|
| 101 |
+
--do_train \
|
| 102 |
+
--do_eval \
|
| 103 |
+
--dataset_name cnn_dailymail \
|
| 104 |
+
--dataset_config "3.0.0" \
|
| 105 |
+
--source_prefix "summarize: " \
|
| 106 |
+
--output_dir /tmp/tst-summarization \
|
| 107 |
+
--per_device_train_batch_size=4 \
|
| 108 |
+
--per_device_eval_batch_size=4 \
|
| 109 |
+
--overwrite_output_dir \
|
| 110 |
+
--predict_with_generate
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
</pt>
|
| 114 |
+
<tf>
|
| 115 |
+
この例のスクリプトは、🤗 [Datasets](https://huggingface.co/docs/datasets/) ライブラリからデータセットをダウンロードして前処理します。その後、スクリプトは要約をサポートするアーキテクチャ上で Keras を使用してデータセットをファインチューニングします。以下の例では、[T5-small](https://huggingface.co/google-t5/t5-small) を [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) データセットでファインチューニングする方法を示しています。T5 モデルは、そのトレーニング方法に起因して追加の `source_prefix` 引数が必要です。このプロンプトは、T5 にこれが要約タスクであることを知らせます。
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
```bash
|
| 119 |
+
python examples/tensorflow/summarization/run_summarization.py \
|
| 120 |
+
--model_name_or_path google-t5/t5-small \
|
| 121 |
+
--dataset_name cnn_dailymail \
|
| 122 |
+
--dataset_config "3.0.0" \
|
| 123 |
+
--output_dir /tmp/tst-summarization \
|
| 124 |
+
--per_device_train_batch_size 8 \
|
| 125 |
+
--per_device_eval_batch_size 16 \
|
| 126 |
+
--num_train_epochs 3 \
|
| 127 |
+
--do_train \
|
| 128 |
+
--do_eval
|
| 129 |
+
```
|
| 130 |
+
</tf>
|
| 131 |
+
</frameworkcontent>
|
| 132 |
+
|
| 133 |
+
## Distributed training and mixed precision
|
| 134 |
+
|
| 135 |
+
[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer)は、分散トレーニングと混合精度をサポートしています。つまり、この機能をスクリプトで使用することができます。これらの機能を有効にするには、次の手順を実行します。
|
| 136 |
+
|
| 137 |
+
- `fp16`引数を追加して混合精度を有効にします。
|
| 138 |
+
- `nproc_per_node`引数で使用するGPUの数を設定します。
|
| 139 |
+
|
| 140 |
+
以下は提供されたBashコードです。このコードの日本語訳をMarkdown形式で記載します。
|
| 141 |
+
|
| 142 |
+
```bash
|
| 143 |
+
torchrun \
|
| 144 |
+
--nproc_per_node 8 pytorch/summarization/run_summarization.py \
|
| 145 |
+
--fp16 \
|
| 146 |
+
--model_name_or_path google-t5/t5-small \
|
| 147 |
+
--do_train \
|
| 148 |
+
--do_eval \
|
| 149 |
+
--dataset_name cnn_dailymail \
|
| 150 |
+
--dataset_config "3.0.0" \
|
| 151 |
+
--source_prefix "summarize: " \
|
| 152 |
+
--output_dir /tmp/tst-summarization \
|
| 153 |
+
--per_device_train_batch_size=4 \
|
| 154 |
+
--per_device_eval_batch_size=4 \
|
| 155 |
+
--overwrite_output_dir \
|
| 156 |
+
--predict_with_generate
|
| 157 |
+
```
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
TensorFlowスクリプトは、分散トレーニングに[`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy)を使用し、トレーニングスクリプトに追加の引数を追加する必要はありません。TensorFlowスクリプトは、デフォルトで複数のGPUが利用可能な場合にそれらを使用します。
|
| 161 |
+
|
| 162 |
+
## Run a script on a TPU
|
| 163 |
+
|
| 164 |
+
<frameworkcontent>
|
| 165 |
+
<pt>
|
| 166 |
+
Tensor Processing Units (TPUs)は、パフォーマンスを加速させるために特別に設計されています。PyTorchは、[XLA](https://www.tensorflow.org/xla)ディープラーニングコンパイラを使用してTPUsをサポートしており、詳細については[こちら](https://github.com/pytorch/xla/blob/master/README.md)をご覧ください。TPUを使用するには、`xla_spawn.py`スクリプトを起動し、`num_cores`引数を使用して使用するTPUコアの数を設定します。
|
| 167 |
+
```bash
|
| 168 |
+
python xla_spawn.py --num_cores 8 \
|
| 169 |
+
summarization/run_summarization.py \
|
| 170 |
+
--model_name_or_path google-t5/t5-small \
|
| 171 |
+
--do_train \
|
| 172 |
+
--do_eval \
|
| 173 |
+
--dataset_name cnn_dailymail \
|
| 174 |
+
--dataset_config "3.0.0" \
|
| 175 |
+
--source_prefix "summarize: " \
|
| 176 |
+
--output_dir /tmp/tst-summarization \
|
| 177 |
+
--per_device_train_batch_size=4 \
|
| 178 |
+
--per_device_eval_batch_size=4 \
|
| 179 |
+
--overwrite_output_dir \
|
| 180 |
+
--predict_with_generate
|
| 181 |
+
```
|
| 182 |
+
</pt>
|
| 183 |
+
<tf>
|
| 184 |
+
もちろん、Tensor Processing Units(TPUs)は性能を高速化するために特別に設計されています。TensorFlowスクリプトは、TPUsでトレーニングするために[`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy)を利用します。TPUを使用するには、TPUリソースの名前を`tpu`引数に渡します。
|
| 185 |
+
|
| 186 |
+
```bash
|
| 187 |
+
python run_summarization.py \
|
| 188 |
+
--tpu name_of_tpu_resource \
|
| 189 |
+
--model_name_or_path google-t5/t5-small \
|
| 190 |
+
--dataset_name cnn_dailymail \
|
| 191 |
+
--dataset_config "3.0.0" \
|
| 192 |
+
--output_dir /tmp/tst-summarization \
|
| 193 |
+
--per_device_train_batch_size 8 \
|
| 194 |
+
--per_device_eval_batch_size 16 \
|
| 195 |
+
--num_train_epochs 3 \
|
| 196 |
+
--do_train \
|
| 197 |
+
--do_eval
|
| 198 |
+
```
|
| 199 |
+
</tf>
|
| 200 |
+
</frameworkcontent>
|
| 201 |
+
|
| 202 |
+
## Run a script with 🤗 Accelerate
|
| 203 |
+
|
| 204 |
+
🤗 [Accelerate](https://huggingface.co/docs/accelerate)は、PyTorch専用のライブラリで、CPUのみ、複数のGPU、TPUなど、さまざまなセットアップでモデルをトレーニングするための統一された方法を提供します。PyTorchのトレーニングループを完全に可視化しながら実行できます。まだインストールしていない場合は、🤗 Accelerateをインストールしてください:
|
| 205 |
+
|
| 206 |
+
> 注意:Accelerateは急速に開発が進行しているため、スクリプトを実行するにはaccelerateのgitバージョンをインストールする必要があります
|
| 207 |
+
```bash
|
| 208 |
+
pip install git+https://github.com/huggingface/accelerate
|
| 209 |
+
```
|
| 210 |
+
|
| 211 |
+
代わりに、`run_summarization_no_trainer.py` スクリプトを使用する必要があります。 🤗 Accelerate がサポートするスクリプトには、フォルダ内に `task_no_trainer.py` ファイルが含まれています。まず、次のコマンドを実行して設定ファイルを作成し、保存します:
|
| 212 |
+
|
| 213 |
+
```bash
|
| 214 |
+
accelerate config
|
| 215 |
+
```
|
| 216 |
+
|
| 217 |
+
テストを行い、設定が正しく構成されているか確認してください:
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
```bash
|
| 221 |
+
accelerate test
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
Now you are ready to launch the training:
|
| 225 |
+
|
| 226 |
+
|
| 227 |
+
```bash
|
| 228 |
+
accelerate launch run_summarization_no_trainer.py \
|
| 229 |
+
--model_name_or_path google-t5/t5-small \
|
| 230 |
+
--dataset_name cnn_dailymail \
|
| 231 |
+
--dataset_config "3.0.0" \
|
| 232 |
+
--source_prefix "summarize: " \
|
| 233 |
+
--output_dir ~/tmp/tst-summarization
|
| 234 |
+
```
|
| 235 |
+
|
| 236 |
+
## Use a custom dataset
|
| 237 |
+
|
| 238 |
+
要約スクリプトは、CSVまたはJSON Lineファイルであれば、カスタムデータセットをサポートしています。独自のデータセットを使用する場合、いくつかの追加の引数を指定する必要があります。
|
| 239 |
+
|
| 240 |
+
- `train_file`および`validation_file`は、トレーニングとバリデーションのファイルへのパスを指定します。
|
| 241 |
+
- `text_column`は要約するための入力テキストです。
|
| 242 |
+
- `summary_column`は出力する対象テキストです。
|
| 243 |
+
|
| 244 |
+
カスタムデータセットを使用した要約スクリプトは、以下のようになります:
|
| 245 |
+
|
| 246 |
+
```bash
|
| 247 |
+
python examples/pytorch/summarization/run_summarization.py \
|
| 248 |
+
--model_name_or_path google-t5/t5-small \
|
| 249 |
+
--do_train \
|
| 250 |
+
--do_eval \
|
| 251 |
+
--train_file path_to_csv_or_jsonlines_file \
|
| 252 |
+
--validation_file path_to_csv_or_jsonlines_file \
|
| 253 |
+
--text_column text_column_name \
|
| 254 |
+
--summary_column summary_column_name \
|
| 255 |
+
--source_prefix "summarize: " \
|
| 256 |
+
--output_dir /tmp/tst-summarization \
|
| 257 |
+
--overwrite_output_dir \
|
| 258 |
+
--per_device_train_batch_size=4 \
|
| 259 |
+
--per_device_eval_batch_size=4 \
|
| 260 |
+
--predict_with_generate
|
| 261 |
+
```
|
| 262 |
+
|
| 263 |
+
## Test a script
|
| 264 |
+
|
| 265 |
+
すべてが予想通りに動作することを確認するために、データセット全体を処理する前に、データセットの一部の例でスクリプトを実行することは良いアイデアです。以下の引数を使用して、データセットを最大サンプル数に切り詰めます:
|
| 266 |
+
|
| 267 |
+
- `max_train_samples`
|
| 268 |
+
- `max_eval_samples`
|
| 269 |
+
- `max_predict_samples`
|
| 270 |
+
|
| 271 |
+
```bash
|
| 272 |
+
python examples/pytorch/summarization/run_summarization.py \
|
| 273 |
+
--model_name_or_path google-t5/t5-small \
|
| 274 |
+
--max_train_samples 50 \
|
| 275 |
+
--max_eval_samples 50 \
|
| 276 |
+
--max_predict_samples 50 \
|
| 277 |
+
--do_train \
|
| 278 |
+
--do_eval \
|
| 279 |
+
--dataset_name cnn_dailymail \
|
| 280 |
+
--dataset_config "3.0.0" \
|
| 281 |
+
--source_prefix "summarize: " \
|
| 282 |
+
--output_dir /tmp/tst-summarization \
|
| 283 |
+
--per_device_train_batch_size=4 \
|
| 284 |
+
--per_device_eval_batch_size=4 \
|
| 285 |
+
--overwrite_output_dir \
|
| 286 |
+
--predict_with_generate
|
| 287 |
+
```
|
| 288 |
+
|
| 289 |
+
一部の例のスクリプトは、`max_predict_samples`引数をサポートしていないことがあります。この引数がサポートされているかどうかがわからない場合は、`-h`引数を追加して確認してください。
|
| 290 |
+
|
| 291 |
+
```bash
|
| 292 |
+
examples/pytorch/summarization/run_summarization.py -h
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
## Resume training from checkpoint
|
| 296 |
+
|
| 297 |
+
以前のチェックポイントからトレーニングを再開するための役立つオプションもあります。これにより、トレーニングが中断された場合でも、最初からやり直すことなく、中断したところから再開できます。チェックポイントからトレーニングを再開するための2つの方法があります。
|
| 298 |
+
|
| 299 |
+
最初の方法は、`output_dir previous_output_dir` 引数を使用して、`output_dir` に保存された最新のチェックポイントからトレーニングを再開する方法です。この場合、`overwrite_output_dir` を削除する必要があります:
|
| 300 |
+
|
| 301 |
+
```bash
|
| 302 |
+
python examples/pytorch/summarization/run_summarization.py
|
| 303 |
+
--model_name_or_path google-t5/t5-small \
|
| 304 |
+
--do_train \
|
| 305 |
+
--do_eval \
|
| 306 |
+
--dataset_name cnn_dailymail \
|
| 307 |
+
--dataset_config "3.0.0" \
|
| 308 |
+
--source_prefix "summarize: " \
|
| 309 |
+
--output_dir /tmp/tst-summarization \
|
| 310 |
+
--per_device_train_batch_size=4 \
|
| 311 |
+
--per_device_eval_batch_size=4 \
|
| 312 |
+
--output_dir previous_output_dir \
|
| 313 |
+
--predict_with_generate
|
| 314 |
+
```
|
| 315 |
+
|
| 316 |
+
2番目の方法では、`resume_from_checkpoint path_to_specific_checkpoint` 引数を使用して、特定のチェックポイントフォルダからトレーニングを再開します。
|
| 317 |
+
|
| 318 |
+
|
| 319 |
+
```bash
|
| 320 |
+
python examples/pytorch/summarization/run_summarization.py
|
| 321 |
+
--model_name_or_path google-t5/t5-small \
|
| 322 |
+
--do_train \
|
| 323 |
+
--do_eval \
|
| 324 |
+
--dataset_name cnn_dailymail \
|
| 325 |
+
--dataset_config "3.0.0" \
|
| 326 |
+
--source_prefix "summarize: " \
|
| 327 |
+
--output_dir /tmp/tst-summarization \
|
| 328 |
+
--per_device_train_batch_size=4 \
|
| 329 |
+
--per_device_eval_batch_size=4 \
|
| 330 |
+
--overwrite_output_dir \
|
| 331 |
+
--resume_from_checkpoint path_to_specific_checkpoint \
|
| 332 |
+
--predict_with_generate
|
| 333 |
+
```
|
| 334 |
+
|
| 335 |
+
## Share your model
|
| 336 |
+
|
| 337 |
+
すべてのスクリプトは、最終的なモデルを [Model Hub](https://huggingface.co/models) にアップロードできます。開始する前に Hugging Face にログインしていることを確認してください。
|
| 338 |
+
|
| 339 |
+
```bash
|
| 340 |
+
huggingface-cli login
|
| 341 |
+
```
|
| 342 |
+
|
| 343 |
+
次に、スクリプトに `push_to_hub` 引数を追加します。この引数は、Hugging Face のユーザー名と `output_dir` で指定したフォルダ名でリポジトリを作成します。
|
| 344 |
+
|
| 345 |
+
特定の名前をリポジトリに付けるには、`push_to_hub_model_id` 引数を使用して追加します。このリポジトリは自動的にあなたの名前空間の下にリストされます。
|
| 346 |
+
|
| 347 |
+
以下の例は、特定のリポジトリ名でモデルをアップロードする方法を示しています:
|
| 348 |
+
|
| 349 |
+
|
| 350 |
+
|
| 351 |
+
```bash
|
| 352 |
+
python examples/pytorch/summarization/run_summarization.py
|
| 353 |
+
--model_name_or_path google-t5/t5-small \
|
| 354 |
+
--do_train \
|
| 355 |
+
--do_eval \
|
| 356 |
+
--dataset_name cnn_dailymail \
|
| 357 |
+
--dataset_config "3.0.0" \
|
| 358 |
+
--source_prefix "summarize: " \
|
| 359 |
+
--push_to_hub \
|
| 360 |
+
--push_to_hub_model_id finetuned-t5-cnn_dailymail \
|
| 361 |
+
--output_dir /tmp/tst-summarization \
|
| 362 |
+
--per_device_train_batch_size=4 \
|
| 363 |
+
--per_device_eval_batch_size=4 \
|
| 364 |
+
--overwrite_output_dir \
|
| 365 |
+
--predict_with_generate
|
| 366 |
+
```
|
| 367 |
+
|
| 368 |
+
|
| 369 |
+
|
| 370 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/serialization.md
ADDED
|
@@ -0,0 +1,191 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Export to ONNX
|
| 18 |
+
|
| 19 |
+
🤗 Transformersモデルを本番環境に展開する際には、モデルを特殊なランタイムおよびハードウェアで読み込み、実行できるように、モデルをシリアライズされた形式にエクスポートすることが必要であるか、その恩恵を受けることができることがあります。
|
| 20 |
+
|
| 21 |
+
🤗 Optimumは、Transformersの拡張機能であり、PyTorchまたはTensorFlowからモデルをONNXやTFLiteなどのシリアライズされた形式にエクスポートすることを可能にする「exporters」モジュールを提供しています。また、🤗 Optimumは、最大の効率でターゲットハードウェアでモデルをトレーニングおよび実行するためのパフォーマンス最適化ツールも提供しています。
|
| 22 |
+
|
| 23 |
+
このガイドでは、🤗 Transformersモデルを🤗 Optimumを使用してONNXにエクスポートする方法を示しており、モデルをTFLiteにエクスポートする方法については[Export to TFLiteページ](tflite)を参照してください。
|
| 24 |
+
|
| 25 |
+
## Export to ONNX
|
| 26 |
+
|
| 27 |
+
[ONNX(Open Neural Network eXchange)](http://onnx.ai)は、PyTorchおよびTensorFlowを含むさまざまなフレームワークで深層学習モデルを表現するための共通の一連の演算子とファイル形式を定義するオープンスタンダードです。モデルがONNX形式にエクスポートされると、これらの演算子はニューラルネットワークを介するデータの流れを表す計算グラフ(一般的には「中間表現」と呼ばれる)を構築するために使用されます。
|
| 28 |
+
|
| 29 |
+
標準化された演算子とデータ型を備えたグラフを公開することで、ONNXはフレームワーク間の切り替えを容易にします。たとえば、PyTorchでトレーニングされたモデルはONNX形式にエクスポートし、それをTensorFlowでインポートすることができます(逆も同様です)。
|
| 30 |
+
|
| 31 |
+
ONNX形式にエクスポートされたモデルは、以下のように使用できます:
|
| 32 |
+
- [グラフ最適化](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/optimization)や[量子化](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/quantization)などのテクニックを使用して推論のために最適化。
|
| 33 |
+
- [`ORTModelForXXX`クラス](https://huggingface.co/docs/optimum/onnxruntime/package_reference/modeling_ort)を介してONNX Runtimeで実行し、🤗 Transformersでおなじみの`AutoModel` APIに従います。
|
| 34 |
+
- [最適化された推論パイプライン](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/pipelines)を介して実行し、🤗 Transformersの[`pipeline`]関数と同じAPIを持っています。
|
| 35 |
+
|
| 36 |
+
🤗 Optimumは、設定オブジェクトを活用してONNXエクスポートをサポートしており、これらの設定オブジェクトは多くのモデルアーキテクチャ用に事前に作成されており、他のアーキテクチャにも簡単に拡張できるように設計されています。
|
| 37 |
+
|
| 38 |
+
事前に作成された設定のリストについては、[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/exporters/onnx/overview)を参照してください。
|
| 39 |
+
|
| 40 |
+
🤗 TransformersモデルをONNXにエクスポートする方法は2つあります。以下では両方の方法を示します:
|
| 41 |
+
|
| 42 |
+
- export with 🤗 Optimum via CLI.
|
| 43 |
+
- export with 🤗 Optimum with `optimum.onnxruntime`.
|
| 44 |
+
|
| 45 |
+
### Exporting a 🤗 Transformers model to ONNX with CLI
|
| 46 |
+
|
| 47 |
+
🤗 TransformersモデルをONNXにエクスポートするには、まず追加の依存関係をインストールしてください:
|
| 48 |
+
|
| 49 |
+
```bash
|
| 50 |
+
pip install optimum[exporters]
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
すべての利用可能な引数を確認するには、[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli)を参照してください。または、コマンドラインでヘルプを表示することもできます:
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
```bash
|
| 57 |
+
optimum-cli export onnx --help
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
🤗 Hubからモデルのチェックポイントをエクスポートするには、例えば `distilbert/distilbert-base-uncased-distilled-squad` を使いたい場合、以下のコマンドを実行してください:
|
| 61 |
+
|
| 62 |
+
```bash
|
| 63 |
+
optimum-cli export onnx --model distilbert/distilbert-base-uncased-distilled-squad distilbert_base_uncased_squad_onnx/
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
進行状況を示し、結果の `model.onnx` が保存される場所を表示するログは、以下のように表示されるはずです:
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
Validating ONNX model distilbert_base_uncased_squad_onnx/model.onnx...
|
| 71 |
+
-[✓] ONNX model output names match reference model (start_logits, end_logits)
|
| 72 |
+
- Validating ONNX Model output "start_logits":
|
| 73 |
+
-[✓] (2, 16) matches (2, 16)
|
| 74 |
+
-[✓] all values close (atol: 0.0001)
|
| 75 |
+
- Validating ONNX Model output "end_logits":
|
| 76 |
+
-[✓] (2, 16) matches (2, 16)
|
| 77 |
+
-[✓] all values close (atol: 0.0001)
|
| 78 |
+
The ONNX export succeeded and the exported model was saved at: distilbert_base_uncased_squad_onnx
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
上記の例は🤗 Hubからのチェックポイントのエクスポートを示しています。ローカルモデルをエクスポートする場合、まずモデルの重みとトークナイザのファイルを同じディレクトリ(`local_path`)に保存してください。CLIを使用する場合、🤗 Hubのチェックポイント名の代わりに`model`引数に`local_path`を渡し、`--task`引数を指定してください。[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/exporters/task_manager)でサポートされているタスクのリストを確認できます。`task`引数が指定されていない場合、タスク固有のヘッドを持たないモデルアーキテクチャがデフォルトで選択されます。
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
```bash
|
| 85 |
+
optimum-cli export onnx --model local_path --task question-answering distilbert_base_uncased_squad_onnx/
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
エクスポートされた `model.onnx` ファイルは、ONNX標準をサポートする[多くのアクセラレータ](https://onnx.ai/supported-tools.html#deployModel)の1つで実行できます。たとえば、[ONNX Runtime](https://onnxruntime.ai/)を使用してモデルを読み込み、実行する方法は以下の通りです:
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
```python
|
| 92 |
+
>>> from transformers import AutoTokenizer
|
| 93 |
+
>>> from optimum.onnxruntime import ORTModelForQuestionAnswering
|
| 94 |
+
|
| 95 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert_base_uncased_squad_onnx")
|
| 96 |
+
>>> model = ORTModelForQuestionAnswering.from_pretrained("distilbert_base_uncased_squad_onnx")
|
| 97 |
+
>>> inputs = tokenizer("What am I using?", "Using DistilBERT with ONNX Runtime!", return_tensors="pt")
|
| 98 |
+
>>> outputs = model(**inputs)
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
🤗 HubからTensorFlowのチェックポイントをエクスポートするプロセスは、同様です。例えば、[Keras organization](https://huggingface.co/keras-io)から純粋なTensorFlowのチェックポイントをエクスポートする方法は以下の通りです:
|
| 102 |
+
|
| 103 |
+
|
| 104 |
+
```bash
|
| 105 |
+
optimum-cli export onnx --model keras-io/transformers-qa distilbert_base_cased_squad_onnx/
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
### Exporting a 🤗 Transformers model to ONNX with `optimum.onnxruntime`
|
| 109 |
+
|
| 110 |
+
CLIの代わりに、🤗 TransformersモデルをONNXにプログラム的にエクスポートすることもできます。以下のように行います:
|
| 111 |
+
|
| 112 |
+
```python
|
| 113 |
+
>>> from optimum.onnxruntime import ORTModelForSequenceClassification
|
| 114 |
+
>>> from transformers import AutoTokenizer
|
| 115 |
+
|
| 116 |
+
>>> model_checkpoint = "distilbert_base_uncased_squad"
|
| 117 |
+
>>> save_directory = "onnx/"
|
| 118 |
+
|
| 119 |
+
>>> # Load a model from transformers and export it to ONNX
|
| 120 |
+
>>> ort_model = ORTModelForSequenceClassification.from_pretrained(model_checkpoint, export=True)
|
| 121 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(model_checkpoint)
|
| 122 |
+
|
| 123 |
+
>>> # Save the onnx model and tokenizer
|
| 124 |
+
>>> ort_model.save_pretrained(save_directory)
|
| 125 |
+
>>> tokenizer.save_pretrained(save_directory)
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
### Exporting a model for an unsupported architecture
|
| 129 |
+
|
| 130 |
+
現在エクスポートできないモデルをサポートするために貢献したい場合、まず[`optimum.exporters.onnx`](https://huggingface.co/docs/optimum/exporters/onnx/overview)でサポートされているかどうかを確認し、サポートされていない場合は[🤗 Optimumに貢献](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/contribute)してください。
|
| 131 |
+
|
| 132 |
+
### Exporting a model with `transformers.onnx`
|
| 133 |
+
|
| 134 |
+
<Tip warning={true}>
|
| 135 |
+
|
| 136 |
+
`transformers.onnx`はもはやメンテナンスされていないため、モデルを上記で説明したように🤗 Optimumでエクスポートしてください。このセクションは将来のバージョンで削除されます。
|
| 137 |
+
|
| 138 |
+
</Tip>
|
| 139 |
+
|
| 140 |
+
🤗 TransformersモデルをONNXにエクスポートするには、追加の依存関係をインストールしてください:
|
| 141 |
+
|
| 142 |
+
|
| 143 |
+
```bash
|
| 144 |
+
pip install transformers[onnx]
|
| 145 |
+
```
|
| 146 |
+
|
| 147 |
+
`transformers.onnx`パッケージをPythonモジュールとして使用して、事前に用意された設定を使用してチェックポイントをエクスポートする方法は以下の通りです:
|
| 148 |
+
|
| 149 |
+
```bash
|
| 150 |
+
python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
|
| 151 |
+
```
|
| 152 |
+
|
| 153 |
+
この方法は、`--model`引数で定義されたチェックポイントのONNXグラフをエクスポートします。🤗 Hubのいずれかのチェックポイントまたはローカルに保存されたチェックポイントを渡すことができます。エクスポートされた`model.onnx`ファイルは、ONNX標準をサポートする多くのアクセラレータで実行できます。例えば、ONNX Runtimeを使用してモデルを読み込んで実行する方法は以下の通りです:
|
| 154 |
+
|
| 155 |
+
|
| 156 |
+
```python
|
| 157 |
+
>>> from transformers import AutoTokenizer
|
| 158 |
+
>>> from onnxruntime import InferenceSession
|
| 159 |
+
|
| 160 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
|
| 161 |
+
>>> session = InferenceSession("onnx/model.onnx")
|
| 162 |
+
>>> # ONNX Runtime expects NumPy arrays as input
|
| 163 |
+
>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
|
| 164 |
+
>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
必要な出力名(例: `["last_hidden_state"]`)は、各モデルのONNX構成を確認することで取得できます。例えば、DistilBERTの場合、次のようになります:
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
```python
|
| 171 |
+
>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
|
| 172 |
+
|
| 173 |
+
>>> config = DistilBertConfig()
|
| 174 |
+
>>> onnx_config = DistilBertOnnxConfig(config)
|
| 175 |
+
>>> print(list(onnx_config.outputs.keys()))
|
| 176 |
+
["last_hidden_state"]
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
ハブから純粋なTensorFlowのチェックポイントをプログラム的にエクスポートするプロセスは、以下のように同様です:
|
| 180 |
+
|
| 181 |
+
```bash
|
| 182 |
+
python -m transformers.onnx --model=keras-io/transformers-qa onnx/
|
| 183 |
+
```
|
| 184 |
+
|
| 185 |
+
ローカルに保存されたモデルをエクスポートする場合、モデルの重みとトークナイザのファイルを同じディレクトリに保存してください(例: `local-pt-checkpoint`)。その後、`transformers.onnx`パッケージの `--model`引数を希望するディレクトリに向けて設定して、ONNXにエクスポートします:
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
```bash
|
| 189 |
+
python -m transformers.onnx --model=local-pt-checkpoint onnx/
|
| 190 |
+
```
|
| 191 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/task_summary.md
ADDED
|
@@ -0,0 +1,355 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# What 🤗 Transformers can do
|
| 18 |
+
|
| 19 |
+
🤗 Transformersは、自然言語処理(NLP)、コンピュータビジョン、音声処理などの最新の事前学習済みモデルのライブラリです。このライブラリには、Transformerモデルだけでなく、コンピュータビジョンタスク向けのモダンな畳み込みニューラルネットワークなど、Transformer以外のモデルも含まれています。現代のスマートフォン、アプリ、テレビなど、最も人気のある消費者製品の多くには、深層学習技術が使用されています。スマートフォンで撮影した写真から背景オブジェクトを削除したいですか?これはパノプティック・セグメンテーション(まだ何を意味するかわからなくても心配しないでください、以下のセクションで説明します!)のタスクの一例です。
|
| 20 |
+
|
| 21 |
+
このページでは、🤗 Transformersライブラリを使用して、たった3行のコードで解決できるさまざまな音声および音声、コンピュータビジョン、NLPタスクの概要を提供します!
|
| 22 |
+
|
| 23 |
+
## Audio
|
| 24 |
+
|
| 25 |
+
音声と音声処理のタスクは、他のモダリティとは少し異なります。なぜなら、入力としての生の音声波形は連続的な信号であるからです。テキストとは異なり、生の音声波形は文章を単語に分割できるようにきれいに分割できません。これを解決するために、通常、生の音声信号は定期的な間隔でサンプリングされます。間隔内でより多くのサンプルを取ると、サンプリングレートが高くなり、音声はより元の音声ソースに近づきます。
|
| 26 |
+
|
| 27 |
+
以前のアプローチでは、音声を前処理してそれから有用な特徴を抽出しました。しかし、現在では、生の音声波形を特徴エンコーダに直接フィードし、音声表現を抽出することから始めることが一般的です。これにより、前処理ステップが簡素化され、モデルは最も重要な特徴を学習できます。
|
| 28 |
+
|
| 29 |
+
### Audio classification
|
| 30 |
+
|
| 31 |
+
音声分類は、事前に定義されたクラスのセットから音声データにラベルを付けるタスクです。これは多くの具体的なアプリケーションを含む広範なカテゴリであり、いくつかの例は次のとおりです:
|
| 32 |
+
|
| 33 |
+
- 音響シーン分類:音声にシーンラベルを付ける(「オフィス」、「ビーチ」、「スタジアム」)
|
| 34 |
+
- 音響イベント検出:音声に音声イベントラベルを付ける(「車のクラクション」、「クジラの呼び声」、「ガラスの破裂」)
|
| 35 |
+
- タギング:複数の音を含む音声にラベルを付ける(鳥の鳴き声、会議でのスピーカー識別)
|
| 36 |
+
- 音楽分類:音楽にジャンルラベルを付ける(「メタル」、「ヒップホップ」、「カントリー」)
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
```py
|
| 40 |
+
>>> from transformers import pipeline
|
| 41 |
+
|
| 42 |
+
>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
|
| 43 |
+
>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
|
| 44 |
+
>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
|
| 45 |
+
>>> preds
|
| 46 |
+
[{'score': 0.4532, 'label': 'hap'},
|
| 47 |
+
{'score': 0.3622, 'label': 'sad'},
|
| 48 |
+
{'score': 0.0943, 'label': 'neu'},
|
| 49 |
+
{'score': 0.0903, 'label': 'ang'}]
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
### Automatic speech recognition
|
| 53 |
+
|
| 54 |
+
自動音声認識(ASR)は音声をテキストに変換します。これは、人間のコミュニケーションの自然な形式である音声の一部として、部分的にそのような一般的なオーディオタスクの一つです。今日、ASRシステムはスピーカー、スマートフォン、自動車などの「スマート」テクノロジープロダクトに組み込まれています。私たちは仮想アシスタントに音楽を再生してもらったり、リマインダーを設定してもらったり、天気を教えてもらったりできます。
|
| 55 |
+
|
| 56 |
+
しかし、Transformerアーキテクチャが助けた主要な課題の一つは、低リソース言語におけるものです。大量の��声データで事前トレーニングし、低リソース言語でラベル付き音声データをわずか1時間だけでファインチューニングすることでも、以前のASRシステムと比較して高品質な結果を得ることができます。以前のASRシステムは100倍以上のラベル付きデータでトレーニングされていましたが、Transformerアーキテクチャはこの問題に貢献しました。
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
```py
|
| 60 |
+
>>> from transformers import pipeline
|
| 61 |
+
|
| 62 |
+
>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
|
| 63 |
+
>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
|
| 64 |
+
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
## Computer vision
|
| 69 |
+
|
| 70 |
+
最初で初めて成功したコンピュータビジョンのタスクの一つは、[畳み込みニューラルネットワーク(CNN)](glossary#convolution)を使用して郵便番号の画像を認識することでした。画像はピクセルから構成され、各ピクセルには数値があります。これにより、画像をピクセル値の行列として簡単に表現できます。特定のピクセル値の組み合わせは、画像の色を記述します。
|
| 71 |
+
|
| 72 |
+
コンピュータビジョンのタスクを解決する一般的な方法は次の2つです:
|
| 73 |
+
|
| 74 |
+
1. 畳み込みを使用して、低レベルの特徴から高レベルの抽象的な情報まで、画像の階層的な特徴を学習する。
|
| 75 |
+
2. 画像をパッチに分割し、各画像パッチが画像全体とどのように関連しているかを徐々に学習するためにTransformerを使用する。CNNが好むボトムアップアプローチとは異なり、これはぼんやりとした画像から始めて徐々に焦点を合わせるようなものです。
|
| 76 |
+
|
| 77 |
+
### Image classification
|
| 78 |
+
|
| 79 |
+
画像分類は、事前に定義されたクラスのセットから画像全体にラベルを付けます。多くの分類タスクと同様に、画像分類には多くの実用的な用途があり、その一部は次のとおりです:
|
| 80 |
+
|
| 81 |
+
* 医療:疾患の検出や患者の健康の監視に使用するために医療画像にラベルを付ける
|
| 82 |
+
* 環境:森林伐採の監視、野生地の管理情報、または山火事の検出に使用するために衛星画像にラベルを付ける
|
| 83 |
+
* 農業:作物の健康を監視するための作物の画像や、土地利用の監視のための衛星画像にラベルを付ける
|
| 84 |
+
* 生態学:野生動物の個体数を監視したり、絶滅危惧種を追跡するために動植物の種の画像にラベルを付ける
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
```py
|
| 88 |
+
>>> from transformers import pipeline
|
| 89 |
+
|
| 90 |
+
>>> classifier = pipeline(task="image-classification")
|
| 91 |
+
>>> preds = classifier(
|
| 92 |
+
... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
|
| 93 |
+
... )
|
| 94 |
+
>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
|
| 95 |
+
>>> print(*preds, sep="\n")
|
| 96 |
+
{'score': 0.4335, 'label': 'lynx, catamount'}
|
| 97 |
+
{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
|
| 98 |
+
{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
|
| 99 |
+
{'score': 0.0239, 'label': 'Egyptian cat'}
|
| 100 |
+
{'score': 0.0229, 'label': 'tiger cat'}
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
### Object detection
|
| 104 |
+
|
| 105 |
+
画像分類とは異なり、オブジェクト検出は画像内の複数のオブジェクトを識別し、オブジェクトの位置を画像内で定義する境界ボックスによって特定します。オブジェクト検出の例には次のような用途があります:
|
| 106 |
+
|
| 107 |
+
* 自動運転車:他の車両、歩行者、信号機などの日常の交通オブジェクトを検出
|
| 108 |
+
* リモートセンシング:災害モニタリング、都市計画、天候予測
|
| 109 |
+
* 欠陥検出:建物のクラックや構造上の損傷、製造上の欠陥を検出
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
```py
|
| 113 |
+
>>> from transformers import pipeline
|
| 114 |
+
|
| 115 |
+
>>> detector = pipeline(task="object-detection")
|
| 116 |
+
>>> preds = detector(
|
| 117 |
+
... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
|
| 118 |
+
... )
|
| 119 |
+
>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
|
| 120 |
+
>>> preds
|
| 121 |
+
[{'score': 0.9865,
|
| 122 |
+
'label': 'cat',
|
| 123 |
+
'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
### Image segmentation
|
| 127 |
+
|
| 128 |
+
画像セグメンテーションは、画像内のすべてのピクセルをクラスに割り当てるピクセルレベルのタスクです。これはオブジェクト検出とは異なり、オブジェクトをラベル付けし、予測するために境界ボックスを使用する代わりに、セグメンテーションはより詳細になります。セグメンテーションはピクセルレベルでオブジェクトを検出できます。画像セグメンテーションにはいくつかのタイプがあります:
|
| 129 |
+
|
| 130 |
+
* インスタン��セグメンテーション:オブジェクトのクラスをラベル付けするだけでなく、オブジェクトの個別のインスタンス("犬-1"、"犬-2")もラベル付けします。
|
| 131 |
+
* パノプティックセグメンテーション:セマンティックセグメンテーションとインスタンスセグメンテーションの組み合わせ。セマンティッククラスごとに各ピクセルにラベルを付け、オブジェクトの個別のインスタンスもラベル付けします。
|
| 132 |
+
|
| 133 |
+
セグメンテーションタスクは、自動運転車にとって、周囲の世界のピクセルレベルのマップを作成し、歩行者や他の車両を安全に回避できるようにするのに役立ちます。また、医療画像では、タスクの細かい粒度が異常な細胞や臓器の特徴を識別するのに役立ちます。画像セグメンテーションは、eコマースで衣類を仮想的に試着したり、カメラを通じて実世界にオブジェクトを重ねて拡張現実の体験を作成したりするためにも使用できます。
|
| 134 |
+
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
```py
|
| 138 |
+
>>> from transformers import pipeline
|
| 139 |
+
|
| 140 |
+
>>> segmenter = pipeline(task="image-segmentation")
|
| 141 |
+
>>> preds = segmenter(
|
| 142 |
+
... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
|
| 143 |
+
... )
|
| 144 |
+
>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
|
| 145 |
+
>>> print(*preds, sep="\n")
|
| 146 |
+
{'score': 0.9879, 'label': 'LABEL_184'}
|
| 147 |
+
{'score': 0.9973, 'label': 'snow'}
|
| 148 |
+
{'score': 0.9972, 'label': 'cat'}
|
| 149 |
+
```
|
| 150 |
+
|
| 151 |
+
### Depth estimation
|
| 152 |
+
|
| 153 |
+
深度推定は、画像内の各ピクセルがカメラからの距離を予測します。このコンピュータビジョンタスクは、特にシーンの理解と再構築に重要です。たとえば、自動運転車では、歩行者、交通標識、他の車などの物体がどれだけ遠いかを理解し、障害物や衝突を回避するために必要です。深度情報はまた、2D画像から3D表現を構築し、生物学的構造や建物の高品質な3D表現を作成するのに役立ちます。
|
| 154 |
+
|
| 155 |
+
深度推定には次の2つのアプローチがあります:
|
| 156 |
+
|
| 157 |
+
* ステレオ:深度は、わずかに異なる角度からの同じ画像の2つの画像を比較して推定されます。
|
| 158 |
+
* モノキュラー:深度は単一の画像から推定されます。
|
| 159 |
+
|
| 160 |
+
|
| 161 |
+
```py
|
| 162 |
+
>>> from transformers import pipeline
|
| 163 |
+
|
| 164 |
+
>>> depth_estimator = pipeline(task="depth-estimation")
|
| 165 |
+
>>> preds = depth_estimator(
|
| 166 |
+
... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
|
| 167 |
+
... )
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
## Natural language processing
|
| 172 |
+
|
| 173 |
+
NLPタスクは、テキストが私たちにとって自然なコミュニケーション手段であるため、最も一般的なタスクの一つです。モデルが認識するための形式にテキストを変換するには、トークン化が必要です。これは、テキストのシーケンスを単語やサブワード(トークン)に分割し、それらのトークンを数字に変換することを意味します。その結果、テキストのシーケンスを数字のシーケンスとして表現し、一度数字のシーケンスがあれば、さまざまなNLPタスクを解決するためにモデルに入力できます!
|
| 174 |
+
|
| 175 |
+
### Text classification
|
| 176 |
+
|
| 177 |
+
どんなモダリティの分類タスクと同様に、テキスト分類は事前に定義されたクラスのセットからテキストのシーケンス(文レベル、段落、またはドキュメントであることがあります)にラベルを付けます。テキスト分類には多くの実用的な用途があり、その一部は次のとおりです:
|
| 178 |
+
|
| 179 |
+
* 感情分析:`positive`や`negative`のような極性に従ってテキストにラベルを付け、政治、金融、マーケティングなどの分野での意思決定をサポートします。
|
| 180 |
+
* コンテンツ分類:テキストをトピックに従ってラベル付けし、ニュースやソーシャルメディアのフィード内の情報を整理し、フィルタリングするのに役立ちます(`天気`、`スポーツ`、`金融`など)。
|
| 181 |
+
|
| 182 |
+
|
| 183 |
+
```py
|
| 184 |
+
>>> from transformers import pipeline
|
| 185 |
+
|
| 186 |
+
>>> classifier = pipeline(task="sentiment-analysis")
|
| 187 |
+
>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
|
| 188 |
+
>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
|
| 189 |
+
>>> preds
|
| 190 |
+
[{'score': 0.9991, 'label': 'POSITIVE'}]
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
### Token classification
|
| 194 |
+
|
| 195 |
+
どんなNLPタスクでも、テキストはテキストのシーケンスを個々の単語やサブワードに分割して前処理されます。これらは[トークン](/glossary#token)として知られています。トークン分類は、事前に定義されたクラスのセットから各トークンにラベルを割り当てます。
|
| 196 |
+
|
| 197 |
+
トークン分類の一般的なタイプは次の2つです:
|
| 198 |
+
|
| 199 |
+
* 固有���現認識(NER):組織、人物、場所、日付などのエンティティのカテゴリに従ってトークンにラベルを付けます。NERは特にバイオメディカル環境で人気であり、遺伝子、タンパク質、薬物名などをラベル付けできます。
|
| 200 |
+
* 品詞タグ付け(POS):名詞、動詞、形容詞などの品詞に従ってトークンにラベルを付けます。POSは、翻訳システムが同じ単語が文法的にどのように異なるかを理解するのに役立ちます(名詞としての「銀行」と動詞としての「銀行」など)。
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
```py
|
| 204 |
+
>>> from transformers import pipeline
|
| 205 |
+
|
| 206 |
+
>>> classifier = pipeline(task="ner")
|
| 207 |
+
>>> preds = classifier("Hugging Face is a French company based in New York City.")
|
| 208 |
+
>>> preds = [
|
| 209 |
+
... {
|
| 210 |
+
... "entity": pred["entity"],
|
| 211 |
+
... "score": round(pred["score"], 4),
|
| 212 |
+
... "index": pred["index"],
|
| 213 |
+
... "word": pred["word"],
|
| 214 |
+
... "start": pred["start"],
|
| 215 |
+
... "end": pred["end"],
|
| 216 |
+
... }
|
| 217 |
+
... for pred in preds
|
| 218 |
+
... ]
|
| 219 |
+
>>> print(*preds, sep="\n")
|
| 220 |
+
{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
|
| 221 |
+
{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
|
| 222 |
+
{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
|
| 223 |
+
{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
|
| 224 |
+
{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
|
| 225 |
+
{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
|
| 226 |
+
{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
|
| 227 |
+
```
|
| 228 |
+
|
| 229 |
+
### Question answering
|
| 230 |
+
|
| 231 |
+
質問応答は、コンテキスト(オープンドメイン)を含む場合と含まない場合(クローズドドメイン)がある場合もある、別のトークンレベルのタスクで、質問に対する回答を返します。このタスクは、仮想アシスタントにレストランが営業しているかどうかのような質問をするときに発生します。また、顧客や技術サポートを提供し、検索エンジンがあなたが求めている関連情報を取得するのにも役立ちます。
|
| 232 |
+
|
| 233 |
+
質問応答の一般的なタイプは次の2つです:
|
| 234 |
+
|
| 235 |
+
* 抽出型:質問と一部のコンテキストが与えられた場合、モデルがコンテキストから抽出する必要のあるテキストのスパンが回答となります。
|
| 236 |
+
* 抽象的:質問と一部のコンテキストが与えられた場合、回答はコンテキストから生成されます。このアプローチは、[`QuestionAnsweringPipeline`]ではなく[`Text2TextGenerationPipeline`]で処理されます。
|
| 237 |
+
|
| 238 |
+
|
| 239 |
+
```py
|
| 240 |
+
>>> from transformers import pipeline
|
| 241 |
+
|
| 242 |
+
>>> question_answerer = pipeline(task="question-answering")
|
| 243 |
+
>>> preds = question_answerer(
|
| 244 |
+
... question="What is the name of the repository?",
|
| 245 |
+
... context="The name of the repository is huggingface/transformers",
|
| 246 |
+
... )
|
| 247 |
+
>>> print(
|
| 248 |
+
... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
|
| 249 |
+
... )
|
| 250 |
+
score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
|
| 251 |
+
```
|
| 252 |
+
|
| 253 |
+
### Summarization
|
| 254 |
+
|
| 255 |
+
要約は、長いテキストから短いバージョンを作成し、元の文書の意味の大部分を保ちながら試みるタスクです。要約はシーケンスからシーケンスへのタスクであり、入力よりも短いテキストシーケンスを出力します。要約を行うことで、読者が主要なポイントを迅速に理解できるようにするのに役立つ長文書がたくさんあります。法案、法的および財務文書、特許、科学論文など、読者の時間を節約し読書の支援となる文書の例があります。
|
| 256 |
+
|
| 257 |
+
質問応答と同様に、要約には2つのタイプがあります:
|
| 258 |
+
|
| 259 |
+
* 抽出的要約:元のテキストから最も重要な文を識別して抽出します。
|
| 260 |
+
* 抽象的要約:元のテキストからターゲットの要約(入力文書に含まれていない新しい単語を含むことがあります)を生成します。[`SummarizationPipeline`]は抽象的なアプローチを使用しています。
|
| 261 |
+
|
| 262 |
+
|
| 263 |
+
```py
|
| 264 |
+
>>> from transformers import pipeline
|
| 265 |
+
|
| 266 |
+
>>> summarizer = pipeline(task="summarization")
|
| 267 |
+
>>> summarizer(
|
| 268 |
+
... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
|
| 269 |
+
... )
|
| 270 |
+
[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
|
| 271 |
+
```
|
| 272 |
+
|
| 273 |
+
### Translation
|
| 274 |
+
|
| 275 |
+
翻訳は、ある言語のテキストシーケンスを別の言語に変換する作業です。これは異なるバックグラウンドを持つ人々がコミュニケーションをとるのに役立ち、広範な観客にコンテンツを翻訳して伝えるのに役立ち、新しい言語を学ぶのを支援する学習ツールにもなります。要約と共に、翻訳はシーケンス間のタスクであり、モデルは入力シーケンスを受け取り、ターゲットの出力シーケンスを返します。
|
| 276 |
+
|
| 277 |
+
初期の翻訳モデルは主に単一言語でしたが、最近では多言語モデルに対する関心が高まり、多くの言語対で翻訳できるような多言語モデルに注目が集まっています。
|
| 278 |
+
|
| 279 |
+
|
| 280 |
+
```py
|
| 281 |
+
>>> from transformers import pipeline
|
| 282 |
+
|
| 283 |
+
>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
|
| 284 |
+
>>> translator = pipeline(task="translation", model="google-t5/t5-small")
|
| 285 |
+
>>> translator(text)
|
| 286 |
+
[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
|
| 287 |
+
```
|
| 288 |
+
|
| 289 |
+
### 言語モデリング
|
| 290 |
+
|
| 291 |
+
言語モデリングは、テキストのシーケンス内の単語を予測するタスクです。事前学習された言語モデルは、多くの他のダウンストリームタスクに対してファインチューニングできるため、非常に人気のあるNLPタスクとなっています。最近では、ゼロショットまたはフューショット学習を実証する大規模な言語モデル(LLM)に大きな関心が寄せられています。これは、モデルが明示的にトレーニングされていないタスクを解決できることを意味します!言語モデルは、流暢で説得力のあるテキストを生成するために使用できますが、テキストが常に正確であるわけではないため、注意が必要です。
|
| 292 |
+
|
| 293 |
+
言語モデリングには2つのタイプがあります:
|
| 294 |
+
|
| 295 |
+
* 因果的:モデルの目標は、シーケンス内の次のトークンを予測することであり、将来のトークンはマスクされます。
|
| 296 |
+
|
| 297 |
+
```py
|
| 298 |
+
>>> from transformers import pipeline
|
| 299 |
+
|
| 300 |
+
>>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
|
| 301 |
+
>>> generator = pipeline(task="text-generation")
|
| 302 |
+
>>> generator(prompt) # doctest: +SKIP
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
* マスクされた:モデルの目的は、シーケンス内のトークン全体にアクセスしながら、シーケンス内のマスクされたトークンを予測することです。
|
| 306 |
+
|
| 307 |
+
```py
|
| 308 |
+
>>> text = "Hugging Face is a community-based open-source <mask> for machine learning."
|
| 309 |
+
>>> fill_mask = pipeline(task="fill-mask")
|
| 310 |
+
>>> preds = fill_mask(text, top_k=1)
|
| 311 |
+
>>> preds = [
|
| 312 |
+
... {
|
| 313 |
+
... "score": round(pred["score"], 4),
|
| 314 |
+
... "token": pred["token"],
|
| 315 |
+
... "token_str": pred["token_str"],
|
| 316 |
+
... "sequence": pred["sequence"],
|
| 317 |
+
... }
|
| 318 |
+
... for pred in preds
|
| 319 |
+
... ]
|
| 320 |
+
>>> preds
|
| 321 |
+
[{'score': 0.2236,
|
| 322 |
+
'token': 1761,
|
| 323 |
+
'token_str': ' platform',
|
| 324 |
+
'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
|
| 325 |
+
```
|
| 326 |
+
|
| 327 |
+
## Multimodal
|
| 328 |
+
|
| 329 |
+
マルチモーダルタスクは、特定の問題を解決するために複数のデータモダリティ(テキスト、画像、音声、ビデオ)を処理するためにモデルを必要とします。画像キャプショニングは、モデルが入力として画像を受け取り、画像を説明するテキストのシーケンスまたは画像のいくつかの特性を出力するマルチモーダルタスクの例です。
|
| 330 |
+
|
| 331 |
+
マルチモーダルモデルは異なるデータタイプまたはモダリティで作業しますが、内部的には前処理ステップがモデルにすべてのデータタイプを埋め込み(データに関する意味のある情報を保持するベクトルまたは数字のリスト)に変換するのを支援します。画像キャプショニングのようなタスクでは、モデルは画像の埋め込みとテキストの埋め込みの間の関係を学習します。
|
| 332 |
+
|
| 333 |
+
### Document question answering
|
| 334 |
+
|
| 335 |
+
ドキュメント質問応答は、ドキュメントからの自然言語の質問に答えるタスクです。テキストを入力とするトークンレベルの質問応答タスクとは異なり、ドキュメント質問応答はドキュメントの画像とそのドキュメントに関する質問を受け取り、答えを返します。ドキ��メント質問応答は構造化されたドキュメントを解析し、それから重要な情報を抽出するために使用できます。以下の例では、レシートから合計金額とお釣りを抽出することができます。
|
| 336 |
+
|
| 337 |
+
|
| 338 |
+
```py
|
| 339 |
+
>>> from transformers import pipeline
|
| 340 |
+
>>> from PIL import Image
|
| 341 |
+
>>> import requests
|
| 342 |
+
|
| 343 |
+
>>> url = "https://huggingface.co/datasets/hf-internal-testing/example-documents/resolve/main/jpeg_images/2.jpg"
|
| 344 |
+
>>> image = Image.open(requests.get(url, stream=True).raw)
|
| 345 |
+
|
| 346 |
+
>>> doc_question_answerer = pipeline("document-question-answering", model="magorshunov/layoutlm-invoices")
|
| 347 |
+
>>> preds = doc_question_answerer(
|
| 348 |
+
... question="What is the total amount?",
|
| 349 |
+
... image=image,
|
| 350 |
+
... )
|
| 351 |
+
>>> preds
|
| 352 |
+
[{'score': 0.8531, 'answer': '17,000', 'start': 4, 'end': 4}]
|
| 353 |
+
```
|
| 354 |
+
|
| 355 |
+
このページが各モダリティのタスクの種類とそれぞれの重要性についての追加の背景情報を提供できたことを願っています。次の [セクション](tasks_explained) では、🤗 トランスフォーマーがこれらのタスクを解決するために **どのように** 動作するかを学びます。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/asr.md
ADDED
|
@@ -0,0 +1,375 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Automatic speech recognition
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="TksaY_FDgnk"/>
|
| 22 |
+
|
| 23 |
+
自動音声認識 (ASR) は音声信号をテキストに変換し、一連の音声入力をテキスト出力にマッピングします。 Siri や Alexa などの仮想アシスタントは ASR モデルを使用してユーザーを日常的に支援しており、ライブキャプションや会議中のメモ取りなど、他にも便利なユーザー向けアプリケーションが数多くあります。
|
| 24 |
+
|
| 25 |
+
このガイドでは、次の方法を説明します。
|
| 26 |
+
|
| 27 |
+
1. [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) データセットの [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base) を微調整して、音声をテキストに書き起こします。
|
| 28 |
+
2. 微調整したモデルを推論に使用します。
|
| 29 |
+
|
| 30 |
+
<Tip>
|
| 31 |
+
|
| 32 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/automatic-speech-recognition) を確認することをお勧めします。
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 37 |
+
|
| 38 |
+
```bash
|
| 39 |
+
pip install transformers datasets evaluate jiwer
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 43 |
+
|
| 44 |
+
```py
|
| 45 |
+
>>> from huggingface_hub import notebook_login
|
| 46 |
+
|
| 47 |
+
>>> notebook_login()
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
## Load MInDS-14 dataset
|
| 51 |
+
|
| 52 |
+
まず、🤗 データセット ライブラリから [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) データセットの小さいサブセットをロードします。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
>>> from datasets import load_dataset, Audio
|
| 56 |
+
|
| 57 |
+
>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
[`~Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
|
| 61 |
+
|
| 62 |
+
```py
|
| 63 |
+
>>> minds = minds.train_test_split(test_size=0.2)
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
次に、データセットを見てみましょう。
|
| 67 |
+
|
| 68 |
+
```py
|
| 69 |
+
>>> minds
|
| 70 |
+
DatasetDict({
|
| 71 |
+
train: Dataset({
|
| 72 |
+
features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
|
| 73 |
+
num_rows: 16
|
| 74 |
+
})
|
| 75 |
+
test: Dataset({
|
| 76 |
+
features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
|
| 77 |
+
num_rows: 4
|
| 78 |
+
})
|
| 79 |
+
})
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
データセットには`lang_id`や`english_transcription`などの多くの有用な情報が含まれていますが、このガイドでは「`audio`」と「`transciption`」に焦点を当てます。 [`~datasets.Dataset.remove_columns`] メソッドを使用して他の列を削除します。
|
| 83 |
+
|
| 84 |
+
```py
|
| 85 |
+
>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
もう一度例を見てみましょう。
|
| 89 |
+
|
| 90 |
+
```py
|
| 91 |
+
>>> minds["train"][0]
|
| 92 |
+
{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
|
| 93 |
+
0.00024414, 0.00024414], dtype=float32),
|
| 94 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
|
| 95 |
+
'sampling_rate': 8000},
|
| 96 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
|
| 97 |
+
'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
次の 2 つのフィールドがあります。
|
| 101 |
+
|
| 102 |
+
- `audio`: 音声ファイルをロードしてリサンプリングするために呼び出す必要がある音声信号の 1 次元の `array`。
|
| 103 |
+
- `transcription`: ターゲットテキスト。
|
| 104 |
+
|
| 105 |
+
## Preprocess
|
| 106 |
+
|
| 107 |
+
次のステップでは、Wav2Vec2 プロセッサをロ���ドしてオーディオ信号を処理します。
|
| 108 |
+
|
| 109 |
+
```py
|
| 110 |
+
>>> from transformers import AutoProcessor
|
| 111 |
+
|
| 112 |
+
>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
|
| 113 |
+
```
|
| 114 |
+
|
| 115 |
+
MInDS-14 データセットのサンプリング レートは 8000kHz です (この情報は [データセット カード](https://huggingface.co/datasets/PolyAI/minds14) で確認できます)。つまり、データセットを再サンプリングする必要があります。事前トレーニングされた Wav2Vec2 モデルを使用するには、16000kHz に設定します。
|
| 116 |
+
|
| 117 |
+
```py
|
| 118 |
+
>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
|
| 119 |
+
>>> minds["train"][0]
|
| 120 |
+
{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
|
| 121 |
+
2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
|
| 122 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
|
| 123 |
+
'sampling_rate': 16000},
|
| 124 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
|
| 125 |
+
'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
上の `transcription` でわかるように、テキストには大文字と小文字が混在しています。 Wav2Vec2 トークナイザーは大文字のみでトレーニングされるため、テキストがトークナイザーの語彙と一致することを確認する必要があります。
|
| 129 |
+
|
| 130 |
+
```py
|
| 131 |
+
>>> def uppercase(example):
|
| 132 |
+
... return {"transcription": example["transcription"].upper()}
|
| 133 |
+
|
| 134 |
+
|
| 135 |
+
>>> minds = minds.map(uppercase)
|
| 136 |
+
```
|
| 137 |
+
|
| 138 |
+
次に、次の前処理関数を作成します。
|
| 139 |
+
|
| 140 |
+
1. `audio`列を呼び出して、オーディオ ファイルをロードしてリサンプリングします。
|
| 141 |
+
2. オーディオ ファイルから `input_values` を抽出し、プロセッサを使用して `transcription` 列をトークン化します。
|
| 142 |
+
|
| 143 |
+
```py
|
| 144 |
+
>>> def prepare_dataset(batch):
|
| 145 |
+
... audio = batch["audio"]
|
| 146 |
+
... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
|
| 147 |
+
... batch["input_length"] = len(batch["input_values"][0])
|
| 148 |
+
... return batch
|
| 149 |
+
```
|
| 150 |
+
|
| 151 |
+
データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] 関数を使用します。 `num_proc` パラメータを使用してプロセスの数を増やすことで、`map` を高速化できます。 [`~datasets.Dataset.remove_columns`] メソッドを使用して、不要な列を削除します。
|
| 152 |
+
|
| 153 |
+
```py
|
| 154 |
+
>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
|
| 155 |
+
```
|
| 156 |
+
|
| 157 |
+
🤗 Transformers には ASR 用のデータ照合器がないため、[`DataCollatorWithPadding`] を調整してサンプルのバッチを作成する必要があります。また、テキストとラベルが (データセット全体ではなく) バッチ内の最も長い要素の長さに合わせて動的に埋め込まれ、均一な長さになります。 `padding=True` を設定すると、`tokenizer` 関数でテキストを埋め込むことができますが、動的な埋め込みの方が効率的です。
|
| 158 |
+
|
| 159 |
+
他のデータ照合器とは異なり、この特定のデータ照合器は、`input_values`と `labels`」に異なるパディング方法を適用する必要があります。
|
| 160 |
+
|
| 161 |
+
```py
|
| 162 |
+
>>> import torch
|
| 163 |
+
|
| 164 |
+
>>> from dataclasses import dataclass, field
|
| 165 |
+
>>> from typing import Any, Dict, List, Optional, Union
|
| 166 |
+
|
| 167 |
+
|
| 168 |
+
>>> @dataclass
|
| 169 |
+
... class DataCollatorCTCWithPadding:
|
| 170 |
+
... processor: AutoProcessor
|
| 171 |
+
... padding: Union[bool, str] = "longest"
|
| 172 |
+
|
| 173 |
+
... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
|
| 174 |
+
... # split inputs and labels since they have to be of different lengths and need
|
| 175 |
+
... # different padding methods
|
| 176 |
+
... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
|
| 177 |
+
... label_features = [{"input_ids": feature["labels"]} for feature in features]
|
| 178 |
+
|
| 179 |
+
... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
|
| 180 |
+
|
| 181 |
+
... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
|
| 182 |
+
|
| 183 |
+
... # replace padding with -100 to ignore loss correctly
|
| 184 |
+
... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
|
| 185 |
+
|
| 186 |
+
... batch["labels"] = labels
|
| 187 |
+
|
| 188 |
+
... return batch
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
次に、`DataCollatorForCTCWithPadding` をインスタンス化します。
|
| 192 |
+
|
| 193 |
+
```py
|
| 194 |
+
>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
## Evaluate
|
| 198 |
+
|
| 199 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[単語エラー率](https://huggingface.co/spaces/evaluate-metric/wer) (WER) メトリクスを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照して、メトリクスをロードして計算する方法の詳細を確認してください)。
|
| 200 |
+
|
| 201 |
+
```py
|
| 202 |
+
>>> import evaluate
|
| 203 |
+
|
| 204 |
+
>>> wer = evaluate.load("wer")
|
| 205 |
+
```
|
| 206 |
+
|
| 207 |
+
次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して WER を計算する関数を作成します。
|
| 208 |
+
|
| 209 |
+
```py
|
| 210 |
+
>>> import numpy as np
|
| 211 |
+
|
| 212 |
+
|
| 213 |
+
>>> def compute_metrics(pred):
|
| 214 |
+
... pred_logits = pred.predictions
|
| 215 |
+
... pred_ids = np.argmax(pred_logits, axis=-1)
|
| 216 |
+
|
| 217 |
+
... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
|
| 218 |
+
|
| 219 |
+
... pred_str = processor.batch_decode(pred_ids)
|
| 220 |
+
... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
|
| 221 |
+
|
| 222 |
+
... wer = wer.compute(predictions=pred_str, references=label_str)
|
| 223 |
+
|
| 224 |
+
... return {"wer": wer}
|
| 225 |
+
```
|
| 226 |
+
|
| 227 |
+
これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
|
| 228 |
+
|
| 229 |
+
## Train
|
| 230 |
+
|
| 231 |
+
<frameworkcontent>
|
| 232 |
+
<pt>
|
| 233 |
+
<Tip>
|
| 234 |
+
|
| 235 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 236 |
+
|
| 237 |
+
</Tip>
|
| 238 |
+
|
| 239 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForCTC`] で Wav2Vec2 をロードします。 `ctc_loss_reduction` パラメータで適用する削減を指定します。多くの場合、デフォルトの合計ではなく平均を使用する方が適切です。
|
| 240 |
+
|
| 241 |
+
```py
|
| 242 |
+
>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
|
| 243 |
+
|
| 244 |
+
>>> model = AutoModelForCTC.from_pretrained(
|
| 245 |
+
... "facebook/wav2vec2-base",
|
| 246 |
+
... ctc_loss_reduction="mean",
|
| 247 |
+
... pad_token_id=processor.tokenizer.pad_token_id,
|
| 248 |
+
... )
|
| 249 |
+
```
|
| 250 |
+
|
| 251 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 252 |
+
|
| 253 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`トレーナー`] は WER を評価し、トレーニング チェックポイントを保存します。
|
| 254 |
+
2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
|
| 255 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 256 |
+
|
| 257 |
+
```py
|
| 258 |
+
>>> training_args = TrainingArguments(
|
| 259 |
+
... output_dir="my_awesome_asr_mind_model",
|
| 260 |
+
... per_device_train_batch_size=8,
|
| 261 |
+
... gradient_accumulation_steps=2,
|
| 262 |
+
... learning_rate=1e-5,
|
| 263 |
+
... warmup_steps=500,
|
| 264 |
+
... max_steps=2000,
|
| 265 |
+
... gradient_checkpointing=True,
|
| 266 |
+
... fp16=True,
|
| 267 |
+
... group_by_length=True,
|
| 268 |
+
... eval_strategy="steps",
|
| 269 |
+
... per_device_eval_batch_size=8,
|
| 270 |
+
... save_steps=1000,
|
| 271 |
+
... eval_steps=1000,
|
| 272 |
+
... logging_steps=25,
|
| 273 |
+
... load_best_model_at_end=True,
|
| 274 |
+
... metric_for_best_model="wer",
|
| 275 |
+
... greater_is_better=False,
|
| 276 |
+
... push_to_hub=True,
|
| 277 |
+
... )
|
| 278 |
+
|
| 279 |
+
>>> trainer = Trainer(
|
| 280 |
+
... model=model,
|
| 281 |
+
... args=training_args,
|
| 282 |
+
... train_dataset=encoded_minds["train"],
|
| 283 |
+
... eval_dataset=encoded_minds["test"],
|
| 284 |
+
... processing_class=processor,
|
| 285 |
+
... data_collator=data_collator,
|
| 286 |
+
... compute_metrics=compute_metrics,
|
| 287 |
+
... )
|
| 288 |
+
|
| 289 |
+
>>> trainer.train()
|
| 290 |
+
```
|
| 291 |
+
|
| 292 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 293 |
+
|
| 294 |
+
```py
|
| 295 |
+
>>> trainer.push_to_hub()
|
| 296 |
+
```
|
| 297 |
+
|
| 298 |
+
</pt>
|
| 299 |
+
</frameworkcontent>
|
| 300 |
+
|
| 301 |
+
<Tip>
|
| 302 |
+
|
| 303 |
+
自動音声認識用にモデルを微調整する方法のより詳細な例については、英語 ASR および英語のこのブログ [投稿](https://huggingface.co/blog/fine-tune-wav2vec2-english) を参照してください。多言語 ASR については、この [投稿](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2) を参照してください。
|
| 304 |
+
|
| 305 |
+
</Tip>
|
| 306 |
+
|
| 307 |
+
## Inference
|
| 308 |
+
|
| 309 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 310 |
+
|
| 311 |
+
推論を実行したい音声ファイルをロードします。必要に応じて、オーディオ ファイルのサンプリング レートをモデルのサンプリング レートと一致するようにリサンプリングすることを忘れないでください。
|
| 312 |
+
|
| 313 |
+
```py
|
| 314 |
+
>>> from datasets import load_dataset, Audio
|
| 315 |
+
|
| 316 |
+
>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
|
| 317 |
+
>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
|
| 318 |
+
>>> sampling_rate = dataset.features["audio"].sampling_rate
|
| 319 |
+
>>> audio_file = dataset[0]["audio"]["path"]
|
| 320 |
+
```
|
| 321 |
+
|
| 322 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して自動音声認識用の`pipeline`をインスタンス化し、オーディオ ファイルをそれに渡します。
|
| 323 |
+
|
| 324 |
+
```py
|
| 325 |
+
>>> from transformers import pipeline
|
| 326 |
+
|
| 327 |
+
>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
|
| 328 |
+
>>> transcriber(audio_file)
|
| 329 |
+
{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
|
| 330 |
+
```
|
| 331 |
+
|
| 332 |
+
<Tip>
|
| 333 |
+
|
| 334 |
+
転写はまあまあですが、もっと良くなる可能性があります。さらに良い結果を得るには、より多くの例でモデルを微調整してみてください。
|
| 335 |
+
|
| 336 |
+
</Tip>
|
| 337 |
+
|
| 338 |
+
必要に応じて、「パイプライン」の結果を手動で複製することもできます。
|
| 339 |
+
|
| 340 |
+
<frameworkcontent>
|
| 341 |
+
<pt>
|
| 342 |
+
|
| 343 |
+
プロセッサをロードしてオーディオ ファイルと文字起こしを前処理し、`input`を PyTorch テンソルとして返します。
|
| 344 |
+
|
| 345 |
+
```py
|
| 346 |
+
>>> from transformers import AutoProcessor
|
| 347 |
+
|
| 348 |
+
>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
|
| 349 |
+
>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
|
| 350 |
+
```
|
| 351 |
+
|
| 352 |
+
Pass your inputs to the model and return the logits:
|
| 353 |
+
|
| 354 |
+
```py
|
| 355 |
+
>>> from transformers import AutoModelForCTC
|
| 356 |
+
|
| 357 |
+
>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
|
| 358 |
+
>>> with torch.no_grad():
|
| 359 |
+
... logits = model(**inputs).logits
|
| 360 |
+
```
|
| 361 |
+
|
| 362 |
+
最も高い確率で予測された `input_ids` を取得し、プロセッサを使用して予測された `input_ids` をデコードしてテキストに戻します。
|
| 363 |
+
|
| 364 |
+
|
| 365 |
+
```py
|
| 366 |
+
>>> import torch
|
| 367 |
+
|
| 368 |
+
>>> predicted_ids = torch.argmax(logits, dim=-1)
|
| 369 |
+
>>> transcription = processor.batch_decode(predicted_ids)
|
| 370 |
+
>>> transcription
|
| 371 |
+
['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
|
| 372 |
+
```
|
| 373 |
+
|
| 374 |
+
</pt>
|
| 375 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/audio_classification.md
ADDED
|
@@ -0,0 +1,323 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Audio classification
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="KWwzcmG98Ds"/>
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
音声分類では、テキストと同様に、入力データから出力されたクラス ラベルを割り当てます。唯一の違いは、テキスト入力の代わりに生のオーディオ波形があることです。音声分類の実際的な応用例には、話者の意図、言語分類、さらには音による動物の種類の識別などがあります。
|
| 25 |
+
|
| 26 |
+
このガイドでは、次の方法を説明します。
|
| 27 |
+
|
| 28 |
+
1. [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) データセットで [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base) を微調整して話者の意図を分類します。
|
| 29 |
+
2. 微調整したモデルを推論に使用します。
|
| 30 |
+
|
| 31 |
+
<Tip>
|
| 32 |
+
|
| 33 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/audio-classification) を確認することをお勧めします。
|
| 34 |
+
|
| 35 |
+
</Tip>
|
| 36 |
+
|
| 37 |
+
```bash
|
| 38 |
+
pip install transformers datasets evaluate
|
| 39 |
+
```
|
| 40 |
+
|
| 41 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 42 |
+
|
| 43 |
+
```py
|
| 44 |
+
>>> from huggingface_hub import notebook_login
|
| 45 |
+
|
| 46 |
+
>>> notebook_login()
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
## Load MInDS-14 dataset
|
| 50 |
+
|
| 51 |
+
まず、🤗 データセット ライブラリから MInDS-14 データセットをロードします。
|
| 52 |
+
|
| 53 |
+
```py
|
| 54 |
+
>>> from datasets import load_dataset, Audio
|
| 55 |
+
|
| 56 |
+
>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train")
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` をより小さなトレインとテスト セットに分割します。これにより、完全なデータセットにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
|
| 60 |
+
|
| 61 |
+
```py
|
| 62 |
+
>>> minds = minds.train_test_split(test_size=0.2)
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
次に、データセットを見てみましょう。
|
| 66 |
+
|
| 67 |
+
```py
|
| 68 |
+
>>> minds
|
| 69 |
+
DatasetDict({
|
| 70 |
+
train: Dataset({
|
| 71 |
+
features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
|
| 72 |
+
num_rows: 450
|
| 73 |
+
})
|
| 74 |
+
test: Dataset({
|
| 75 |
+
features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
|
| 76 |
+
num_rows: 113
|
| 77 |
+
})
|
| 78 |
+
})
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
データセットには`lang_id`や`english_transcription`などの多くの有用な情報が含まれていますが、このガイドでは`audio`と`intent_class`に焦点を当てます。 [`~datasets.Dataset.remove_columns`] メソッドを使用して他の列を削除します。
|
| 83 |
+
|
| 84 |
+
```py
|
| 85 |
+
>>> minds = minds.remove_columns(["path", "transcription", "english_transcription", "lang_id"])
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
ここで例を見てみましょう。
|
| 89 |
+
|
| 90 |
+
```py
|
| 91 |
+
>>> minds["train"][0]
|
| 92 |
+
{'audio': {'array': array([ 0. , 0. , 0. , ..., -0.00048828,
|
| 93 |
+
-0.00024414, -0.00024414], dtype=float32),
|
| 94 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
|
| 95 |
+
'sampling_rate': 8000},
|
| 96 |
+
'intent_class': 2}
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
次の 2 つのフィールドがあります。
|
| 100 |
+
|
| 101 |
+
- `audio`: 音声ファイルをロードしてリサンプリングするために呼び出す必要がある音声信号の 1 次元の `array`。
|
| 102 |
+
- `intent_class`: スピーカーのインテントのクラス ID を表します。
|
| 103 |
+
|
| 104 |
+
モデルがラベル ID からラベル名を取得しやすくするために、ラベル名を整数に、またはその逆にマップする辞書を作成します。
|
| 105 |
+
|
| 106 |
+
```py
|
| 107 |
+
>>> labels = minds["train"].features["intent_class"].names
|
| 108 |
+
>>> label2id, id2label = dict(), dict()
|
| 109 |
+
>>> for i, label in enumerate(labels):
|
| 110 |
+
... label2id[label] = str(i)
|
| 111 |
+
... id2label[str(i)] = label
|
| 112 |
+
```
|
| 113 |
+
|
| 114 |
+
これで、ラベル ID をラベル名に変換できるようになりました。
|
| 115 |
+
|
| 116 |
+
```py
|
| 117 |
+
>>> id2label[str(2)]
|
| 118 |
+
'app_error'
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
## Preprocess
|
| 122 |
+
|
| 123 |
+
次のステップでは、Wav2Vec2 特徴抽出プログラムをロードして���ーディオ信号を処理します。
|
| 124 |
+
|
| 125 |
+
```py
|
| 126 |
+
>>> from transformers import AutoFeatureExtractor
|
| 127 |
+
|
| 128 |
+
>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
|
| 129 |
+
```
|
| 130 |
+
|
| 131 |
+
MInDS-14 データセットのサンプリング レートは 8khz です (この情報は [データセット カード](https://huggingface.co/datasets/PolyAI/minds14) で確認できます)。つまり、データセットを再サンプリングする必要があります。事前トレーニングされた Wav2Vec2 モデルを使用するには、16kHz に設定します。
|
| 132 |
+
|
| 133 |
+
```py
|
| 134 |
+
>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
|
| 135 |
+
>>> minds["train"][0]
|
| 136 |
+
{'audio': {'array': array([ 2.2098757e-05, 4.6582241e-05, -2.2803260e-05, ...,
|
| 137 |
+
-2.8419291e-04, -2.3305941e-04, -1.1425107e-04], dtype=float32),
|
| 138 |
+
'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
|
| 139 |
+
'sampling_rate': 16000},
|
| 140 |
+
'intent_class': 2}
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
次に、次の前処理関数を作成します。
|
| 144 |
+
|
| 145 |
+
1. `audio`列を呼び出してロードし、必要に応じてオーディオ ファイルをリサンプリングします。
|
| 146 |
+
2. オーディオ ファイルのサンプリング レートが、モデルが事前トレーニングされたオーディオ データのサンプリング レートと一致するかどうかを確認します。この情報は、Wav2Vec2 [モデル カード](https://huggingface.co/facebook/wav2vec2-base) で見つけることができます。
|
| 147 |
+
3. 入力の最大長を設定して、長い入力を切り捨てずにバッチ処理します。
|
| 148 |
+
|
| 149 |
+
```py
|
| 150 |
+
>>> def preprocess_function(examples):
|
| 151 |
+
... audio_arrays = [x["array"] for x in examples["audio"]]
|
| 152 |
+
... inputs = feature_extractor(
|
| 153 |
+
... audio_arrays, sampling_rate=feature_extractor.sampling_rate, max_length=16000, truncation=True
|
| 154 |
+
... )
|
| 155 |
+
... return inputs
|
| 156 |
+
```
|
| 157 |
+
|
| 158 |
+
データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] 関数を使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` を高速化できます。不要な列を削除し、`intent_class` の名前を `label` に変更します。これはモデルが期待する名前であるためです。
|
| 159 |
+
|
| 160 |
+
```py
|
| 161 |
+
>>> encoded_minds = minds.map(preprocess_function, remove_columns="audio", batched=True)
|
| 162 |
+
>>> encoded_minds = encoded_minds.rename_column("intent_class", "label")
|
| 163 |
+
```
|
| 164 |
+
## Evaluate
|
| 165 |
+
|
| 166 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) メトリクスを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) メトリクスの読み込みと計算方法の詳細については、次を参照してください。
|
| 167 |
+
|
| 168 |
+
```py
|
| 169 |
+
>>> import evaluate
|
| 170 |
+
|
| 171 |
+
>>> accuracy = evaluate.load("accuracy")
|
| 172 |
+
```
|
| 173 |
+
|
| 174 |
+
次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して精度を計算する関数を作成します。
|
| 175 |
+
|
| 176 |
+
```py
|
| 177 |
+
>>> import numpy as np
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
>>> def compute_metrics(eval_pred):
|
| 181 |
+
... predictions = np.argmax(eval_pred.predictions, axis=1)
|
| 182 |
+
... return accuracy.compute(predictions=predictions, references=eval_pred.label_ids)
|
| 183 |
+
```
|
| 184 |
+
|
| 185 |
+
これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
|
| 186 |
+
|
| 187 |
+
## Train
|
| 188 |
+
|
| 189 |
+
<frameworkcontent>
|
| 190 |
+
<pt>
|
| 191 |
+
<Tip>
|
| 192 |
+
|
| 193 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 194 |
+
|
| 195 |
+
</Tip>
|
| 196 |
+
|
| 197 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForAudioClassification`] を使用して、予期されるラベルの数とラベル マッピングを使用して Wav2Vec2 を読み込みます。
|
| 198 |
+
|
| 199 |
+
```py
|
| 200 |
+
>>> from transformers import AutoModelForAudioClassification, TrainingArguments, Trainer
|
| 201 |
+
|
| 202 |
+
>>> num_labels = len(id2label)
|
| 203 |
+
>>> model = AutoModelForAudioClassification.from_pretrained(
|
| 204 |
+
... "facebook/wav2vec2-base", num_labels=num_labels, label2id=label2id, id2label=id2label
|
| 205 |
+
... )
|
| 206 |
+
```
|
| 207 |
+
|
| 208 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 209 |
+
|
| 210 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`トレーナー`] は精度を評価し、トレーニング チェックポイントを保存します。
|
| 211 |
+
2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
|
| 212 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 213 |
+
|
| 214 |
+
```py
|
| 215 |
+
>>> training_args = TrainingArguments(
|
| 216 |
+
... output_dir="my_awesome_mind_model",
|
| 217 |
+
... eval_strategy="epoch",
|
| 218 |
+
... save_strategy="epoch",
|
| 219 |
+
... learning_rate=3e-5,
|
| 220 |
+
... per_device_train_batch_size=32,
|
| 221 |
+
... gradient_accumulation_steps=4,
|
| 222 |
+
... per_device_eval_batch_size=32,
|
| 223 |
+
... num_train_epochs=10,
|
| 224 |
+
... warmup_ratio=0.1,
|
| 225 |
+
... logging_steps=10,
|
| 226 |
+
... load_best_model_at_end=True,
|
| 227 |
+
... metric_for_best_model="accuracy",
|
| 228 |
+
... push_to_hub=True,
|
| 229 |
+
... )
|
| 230 |
+
|
| 231 |
+
>>> trainer = Trainer(
|
| 232 |
+
... model=model,
|
| 233 |
+
... args=training_args,
|
| 234 |
+
... train_dataset=encoded_minds["train"],
|
| 235 |
+
... eval_dataset=encoded_minds["test"],
|
| 236 |
+
... processing_class=feature_extractor,
|
| 237 |
+
... compute_metrics=compute_metrics,
|
| 238 |
+
... )
|
| 239 |
+
|
| 240 |
+
>>> trainer.train()
|
| 241 |
+
```
|
| 242 |
+
|
| 243 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 244 |
+
|
| 245 |
+
```py
|
| 246 |
+
>>> trainer.push_to_hub()
|
| 247 |
+
```
|
| 248 |
+
</pt>
|
| 249 |
+
</frameworkcontent>
|
| 250 |
+
|
| 251 |
+
<Tip>
|
| 252 |
+
|
| 253 |
+
音声分類用のモデルを微調整する方法の詳細な例については、対応する [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb).
|
| 254 |
+
|
| 255 |
+
</Tip>
|
| 256 |
+
|
| 257 |
+
## Inference
|
| 258 |
+
|
| 259 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 260 |
+
|
| 261 |
+
推論を実行したい音声ファイルをロードします。必要に応じて、オーディオ ファイルのサンプリング レートをモデルのサンプリング レートと一致するようにリサンプリングすることを忘れないでください。
|
| 262 |
+
|
| 263 |
+
```py
|
| 264 |
+
>>> from datasets import load_dataset, Audio
|
| 265 |
+
|
| 266 |
+
>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
|
| 267 |
+
>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
|
| 268 |
+
>>> sampling_rate = dataset.features["audio"].sampling_rate
|
| 269 |
+
>>> audio_file = dataset[0]["audio"]["path"]
|
| 270 |
+
```
|
| 271 |
+
|
| 272 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して音声分類用の`pipeline`をインスタンス化し、それに音声ファイルを渡します。
|
| 273 |
+
|
| 274 |
+
```py
|
| 275 |
+
>>> from transformers import pipeline
|
| 276 |
+
|
| 277 |
+
>>> classifier = pipeline("audio-classification", model="stevhliu/my_awesome_minds_model")
|
| 278 |
+
>>> classifier(audio_file)
|
| 279 |
+
[
|
| 280 |
+
{'score': 0.09766869246959686, 'label': 'cash_deposit'},
|
| 281 |
+
{'score': 0.07998877018690109, 'label': 'app_error'},
|
| 282 |
+
{'score': 0.0781070664525032, 'label': 'joint_account'},
|
| 283 |
+
{'score': 0.07667109370231628, 'label': 'pay_bill'},
|
| 284 |
+
{'score': 0.0755252093076706, 'label': 'balance'}
|
| 285 |
+
]
|
| 286 |
+
```
|
| 287 |
+
|
| 288 |
+
必要に応じて、`pipeline` の結果を手動で複製することもできます。
|
| 289 |
+
|
| 290 |
+
<frameworkcontent>
|
| 291 |
+
<pt>
|
| 292 |
+
|
| 293 |
+
特徴抽出器をロードしてオーディオ ファイルを前処理し、`input`を PyTorch テンソルとして返します。
|
| 294 |
+
|
| 295 |
+
```py
|
| 296 |
+
>>> from transformers import AutoFeatureExtractor
|
| 297 |
+
|
| 298 |
+
>>> feature_extractor = AutoFeatureExtractor.from_pretrained("stevhliu/my_awesome_minds_model")
|
| 299 |
+
>>> inputs = feature_extractor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
|
| 300 |
+
```
|
| 301 |
+
|
| 302 |
+
入力をモデルに渡し、ロジットを返します。
|
| 303 |
+
|
| 304 |
+
```py
|
| 305 |
+
>>> from transformers import AutoModelForAudioClassification
|
| 306 |
+
|
| 307 |
+
>>> model = AutoModelForAudioClassification.from_pretrained("stevhliu/my_awesome_minds_model")
|
| 308 |
+
>>> with torch.no_grad():
|
| 309 |
+
... logits = model(**inputs).logits
|
| 310 |
+
```
|
| 311 |
+
|
| 312 |
+
最も高い確率でクラスを取得し、モデルの `id2label` マッピングを使用してそれをラベルに変換します。
|
| 313 |
+
|
| 314 |
+
```py
|
| 315 |
+
>>> import torch
|
| 316 |
+
|
| 317 |
+
>>> predicted_class_ids = torch.argmax(logits).item()
|
| 318 |
+
>>> predicted_label = model.config.id2label[predicted_class_ids]
|
| 319 |
+
>>> predicted_label
|
| 320 |
+
'cash_deposit'
|
| 321 |
+
```
|
| 322 |
+
</pt>
|
| 323 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/document_question_answering.md
ADDED
|
@@ -0,0 +1,495 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Document Question Answering
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
文書による質問応答は、文書による視覚的な質問応答とも呼ばれ、以下を提供するタスクです。
|
| 22 |
+
ドキュメント画像に関する質問への回答。このタスクをサポートするモデルへの入力は通常、画像と画像の組み合わせです。
|
| 23 |
+
質問があり、出力は自然言語で表現された回答です。これらのモデルは、以下を含む複数のモダリティを利用します。
|
| 24 |
+
テキスト、単語の位置 (境界ボックス)、および画像自体。
|
| 25 |
+
|
| 26 |
+
このガイドでは、次の方法を説明します。
|
| 27 |
+
|
| 28 |
+
- [DocVQA データセット](https://huggingface.co/datasets/nielsr/docvqa_1200_examples_donut) の [LayoutLMv2](../model_doc/layoutlmv2) を微調整します。
|
| 29 |
+
- 微調整されたモデルを推論に使用します。
|
| 30 |
+
|
| 31 |
+
<Tip>
|
| 32 |
+
|
| 33 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/image-to-text) を確認することをお勧めします。
|
| 34 |
+
|
| 35 |
+
</Tip>
|
| 36 |
+
|
| 37 |
+
LayoutLMv2 は、最後の非表示のヘッダーの上に質問応答ヘッドを追加することで、ドキュメントの質問応答タスクを解決します。
|
| 38 |
+
トークンの状態を調べて、トークンの開始トークンと終了トークンの位置を予測します。
|
| 39 |
+
答え。言い換えれば、問題は抽出的質問応答として扱われます。つまり、コンテキストを考慮して、どの部分を抽出するかということです。
|
| 40 |
+
の情報が質問に答えます。コンテキストは OCR エンジンの出力から取得されます。ここでは Google の Tesseract です。
|
| 41 |
+
|
| 42 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。 LayoutLMv2 は detectron2、torchvision、tesseract に依存します。
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
pip install -q transformers datasets
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
```bash
|
| 49 |
+
pip install 'git+https://github.com/facebookresearch/detectron2.git'
|
| 50 |
+
pip install torchvision
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
```bash
|
| 54 |
+
sudo apt install tesseract-ocr
|
| 55 |
+
pip install -q pytesseract
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
すべての依存関係をインストールしたら、ランタイムを再起動します。
|
| 59 |
+
|
| 60 |
+
モデルをコミュニティと共有することをお勧めします。 Hugging Face アカウントにログインして、🤗 ハブにアップロードします。
|
| 61 |
+
プロンプトが表示されたら、トークンを入力してログインします。
|
| 62 |
+
|
| 63 |
+
```py
|
| 64 |
+
>>> from huggingface_hub import notebook_login
|
| 65 |
+
|
| 66 |
+
>>> notebook_login()
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
いくつかのグローバル変数を定義しましょう。
|
| 70 |
+
|
| 71 |
+
```py
|
| 72 |
+
>>> model_checkpoint = "microsoft/layoutlmv2-base-uncased"
|
| 73 |
+
>>> batch_size = 4
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
## Load the data
|
| 77 |
+
|
| 78 |
+
このガイドでは、🤗 Hub にある前処理された DocVQA の小さなサンプルを使用します。フルに使いたい場合は、
|
| 79 |
+
DocVQA データセットは、[DocVQA ホームページ](https://rrc.cvc.uab.es/?ch=17) で登録してダウンロードできます。そうすれば、
|
| 80 |
+
このガイドを進めて、[🤗 データセットにファイルをロードする方法](https://huggingface.co/docs/datasets/loading#local-and-remote-files) を確認してください。
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
```py
|
| 84 |
+
>>> from datasets import load_dataset
|
| 85 |
+
|
| 86 |
+
>>> dataset = load_dataset("nielsr/docvqa_1200_examples")
|
| 87 |
+
>>> dataset
|
| 88 |
+
DatasetDict({
|
| 89 |
+
train: Dataset({
|
| 90 |
+
features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
|
| 91 |
+
num_rows: 1000
|
| 92 |
+
})
|
| 93 |
+
test: Dataset({
|
| 94 |
+
features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
|
| 95 |
+
num_rows: 200
|
| 96 |
+
})
|
| 97 |
+
})
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
ご覧のとおり、データセットはすでにトレーニング セットとテスト セットに分割されています。理解するためにランダムな例を見てみましょう
|
| 101 |
+
機能を備えた自分自身。
|
| 102 |
+
|
| 103 |
+
```py
|
| 104 |
+
>>> dataset["train"].features
|
| 105 |
+
```
|
| 106 |
+
|
| 107 |
+
個々のフィールドが表す内容は次のとおりです。
|
| 108 |
+
* `id`: サンプルのID
|
| 109 |
+
* `image`: ドキュメント画像を含む PIL.Image.Image オブジェクト
|
| 110 |
+
* `query`: 質問文字列 - いくつかの言語での自然言語に���る質問
|
| 111 |
+
* `answers`: ヒューマン アノテーターによって提供された正解のリスト
|
| 112 |
+
* `words` と `bounding_boxes`: OCR の結果。ここでは使用しません。
|
| 113 |
+
* `answer`: 別のモデルと一致する答え。ここでは使用しません。
|
| 114 |
+
|
| 115 |
+
英語の質問だけを残し、別のモデルによる予測が含まれていると思われる`answer`機能を削除しましょう。
|
| 116 |
+
また、アノテーターによって提供されたセットから最初の回答を取得します。あるいは、ランダムにサンプリングすることもできます。
|
| 117 |
+
|
| 118 |
+
```py
|
| 119 |
+
>>> updated_dataset = dataset.map(lambda example: {"question": example["query"]["en"]}, remove_columns=["query"])
|
| 120 |
+
>>> updated_dataset = updated_dataset.map(
|
| 121 |
+
... lambda example: {"answer": example["answers"][0]}, remove_columns=["answer", "answers"]
|
| 122 |
+
... )
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
このガイドで使用する LayoutLMv2 チェックポイントは、`max_position_embeddings = 512` でトレーニングされていることに注意してください (
|
| 126 |
+
この情報は、[チェックポイントの `config.json` ファイル](https://huggingface.co/microsoft/layoutlmv2-base-uncased/blob/main/config.json#L18)) で見つけてください。
|
| 127 |
+
例を省略することもできますが、答えが大きな文書の最後にあり、結局省略されてしまうという状況を避けるために、
|
| 128 |
+
ここでは、埋め込みが 512 を超える可能性があるいくつかの例を削除します。
|
| 129 |
+
データセット内のほとんどのドキュメントが長い場合は、スライディング ウィンドウ戦略を実装できます。詳細については、[このノートブック](https://github.com/huggingface/notebooks/blob/main/examples/question_answering.ipynb) を確認してください。 。
|
| 130 |
+
|
| 131 |
+
```py
|
| 132 |
+
>>> updated_dataset = updated_dataset.filter(lambda x: len(x["words"]) + len(x["question"].split()) < 512)
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
この時点で、このデータセットから OCR 機能も削除しましょう。これらは、異なるデータを微調整するための OCR の結果です。
|
| 136 |
+
モデル。これらは入力要件と一致しないため、使用したい場合はさらに処理が必要になります。
|
| 137 |
+
このガイドで使用するモデルの。代わりに、OCR と OCR の両方の元のデータに対して [`LayoutLMv2Processor`] を使用できます。
|
| 138 |
+
トークン化。このようにして、モデルの予想される入力と一致する入力を取得します。画像を手動で加工したい場合は、
|
| 139 |
+
モデルがどのような入力形式を想定しているかを知るには、[`LayoutLMv2` モデルのドキュメント](../model_doc/layoutlmv2) を確認してください。
|
| 140 |
+
|
| 141 |
+
```py
|
| 142 |
+
>>> updated_dataset = updated_dataset.remove_columns("words")
|
| 143 |
+
>>> updated_dataset = updated_dataset.remove_columns("bounding_boxes")
|
| 144 |
+
```
|
| 145 |
+
|
| 146 |
+
最後に、画像サンプルを確認しないとデータ探索は完了しません。
|
| 147 |
+
|
| 148 |
+
|
| 149 |
+
```py
|
| 150 |
+
>>> updated_dataset["train"][11]["image"]
|
| 151 |
+
```
|
| 152 |
+
|
| 153 |
+
<div class="flex justify-center">
|
| 154 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/docvqa_example.jpg" alt="DocVQA Image Example"/>
|
| 155 |
+
</div>
|
| 156 |
+
|
| 157 |
+
## Preprocess the data
|
| 158 |
+
|
| 159 |
+
文書の質問に答えるタスクはマルチモーダル タスクであるため、各モダリティからの入力が確実に行われるようにする必要があります。
|
| 160 |
+
モデルの期待に従って前処理されます。まず、[`LayoutLMv2Processor`] をロードします。これは、画像データを処理できる画像プロセッサとテキスト データをエンコードできるトークナイザーを内部で組み合わせています。
|
| 161 |
+
|
| 162 |
+
```py
|
| 163 |
+
>>> from transformers import AutoProcessor
|
| 164 |
+
|
| 165 |
+
>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
|
| 166 |
+
```
|
| 167 |
+
|
| 168 |
+
### Preprocessing document images
|
| 169 |
+
|
| 170 |
+
まず、プロセッサからの `image_processor` を利用して、モデルのドキュメント画像を準備しましょう。
|
| 171 |
+
デフォルトでは、画像プロセッサは画像のサイズを 224x224 に変更し、カラー チャネルの順序が正しいことを確認します。
|
| 172 |
+
tesseract を使用して OCR を適用し、単語と正規化された境界ボックスを取得します。このチュートリアルでは、これらのデフォルトはすべて、まさに必要なものです。
|
| 173 |
+
デフォルトの画像処理を画像のバッチに適用し、OCR の結果を返す関数を作成します。
|
| 174 |
+
|
| 175 |
+
```py
|
| 176 |
+
>>> image_processor = processor.image_processor
|
| 177 |
+
|
| 178 |
+
|
| 179 |
+
>>> def get_ocr_words_and_boxes(examples):
|
| 180 |
+
... images = [image.convert("RGB") for image in examples["image"]]
|
| 181 |
+
... encoded_inputs = image_processor(images)
|
| 182 |
+
|
| 183 |
+
... examples["image"] = encoded_inputs.pixel_values
|
| 184 |
+
... examples["words"] = encoded_inputs.words
|
| 185 |
+
... examples["boxes"] = encoded_inputs.boxes
|
| 186 |
+
|
| 187 |
+
... return examples
|
| 188 |
+
```
|
| 189 |
+
|
| 190 |
+
この前処理をデータセット全体に高速に適用するには、[`~datasets.Dataset.map`] ���使用します。
|
| 191 |
+
|
| 192 |
+
```py
|
| 193 |
+
>>> dataset_with_ocr = updated_dataset.map(get_ocr_words_and_boxes, batched=True, batch_size=2)
|
| 194 |
+
```
|
| 195 |
+
|
| 196 |
+
### Preprocessing text data
|
| 197 |
+
|
| 198 |
+
画像に OCR を適用したら、データセットのテキスト部分をエンコードしてモデル用に準備する必要があります。
|
| 199 |
+
これには、前のステップで取得した単語とボックスをトークンレベルの `input_ids`、`attention_mask`、
|
| 200 |
+
`token_type_ids`と`bbox`。テキストを前処理するには、プロセッサからの`Tokenizer`が必要になります。
|
| 201 |
+
|
| 202 |
+
```py
|
| 203 |
+
>>> tokenizer = processor.tokenizer
|
| 204 |
+
```
|
| 205 |
+
|
| 206 |
+
前述の前処理に加えて、モデルのラベルを追加する必要もあります。 `xxxForQuestionAnswering` モデルの場合
|
| 207 |
+
🤗 Transformers では、ラベルは `start_positions` と `end_positions` で構成され、どのトークンがその位置にあるかを示します。
|
| 208 |
+
開始点と、どのトークンが回答の最後にあるか。
|
| 209 |
+
|
| 210 |
+
それから始めましょう。より大きなリスト (単語リスト) 内のサブリスト (単語に分割された回答) を検索できるヘルパー関数を定義します。
|
| 211 |
+
|
| 212 |
+
この関数は、`words_list` と `answer_list` という 2 つのリストを入力として受け取ります。次に、`words_list`を反復処理してチェックします。
|
| 213 |
+
`words_list` (words_list[i]) 内の現在の単語が、answer_list (answer_list[0]) の最初の単語と等しいかどうか、および
|
| 214 |
+
現在の単語から始まり、`answer_list` と同じ長さの `words_list` のサブリストは、`to answer_list` と等しくなります。
|
| 215 |
+
この条件が true の場合、一致が見つかったことを意味し、関数は一致とその開始インデックス (idx) を記録します。
|
| 216 |
+
とその終了インデックス (idx + len(answer_list) - 1)。複数の一致が見つかった場合、関数は最初のもののみを返します。
|
| 217 |
+
一致するものが見つからない場合、関数は (`None`、0、および 0) を返します。
|
| 218 |
+
|
| 219 |
+
```py
|
| 220 |
+
>>> def subfinder(words_list, answer_list):
|
| 221 |
+
... matches = []
|
| 222 |
+
... start_indices = []
|
| 223 |
+
... end_indices = []
|
| 224 |
+
... for idx, i in enumerate(range(len(words_list))):
|
| 225 |
+
... if words_list[i] == answer_list[0] and words_list[i : i + len(answer_list)] == answer_list:
|
| 226 |
+
... matches.append(answer_list)
|
| 227 |
+
... start_indices.append(idx)
|
| 228 |
+
... end_indices.append(idx + len(answer_list) - 1)
|
| 229 |
+
... if matches:
|
| 230 |
+
... return matches[0], start_indices[0], end_indices[0]
|
| 231 |
+
... else:
|
| 232 |
+
... return None, 0, 0
|
| 233 |
+
```
|
| 234 |
+
|
| 235 |
+
この関数が答えの位置を見つける方法を説明するために、例で使用してみましょう。
|
| 236 |
+
|
| 237 |
+
```py
|
| 238 |
+
>>> example = dataset_with_ocr["train"][1]
|
| 239 |
+
>>> words = [word.lower() for word in example["words"]]
|
| 240 |
+
>>> match, word_idx_start, word_idx_end = subfinder(words, example["answer"].lower().split())
|
| 241 |
+
>>> print("Question: ", example["question"])
|
| 242 |
+
>>> print("Words:", words)
|
| 243 |
+
>>> print("Answer: ", example["answer"])
|
| 244 |
+
>>> print("start_index", word_idx_start)
|
| 245 |
+
>>> print("end_index", word_idx_end)
|
| 246 |
+
Question: Who is in cc in this letter?
|
| 247 |
+
Words: ['wie', 'baw', 'brown', '&', 'williamson', 'tobacco', 'corporation', 'research', '&', 'development', 'internal', 'correspondence', 'to:', 'r.', 'h.', 'honeycutt', 'ce:', 't.f.', 'riehl', 'from:', '.', 'c.j.', 'cook', 'date:', 'may', '8,', '1995', 'subject:', 'review', 'of', 'existing', 'brainstorming', 'ideas/483', 'the', 'major', 'function', 'of', 'the', 'product', 'innovation', 'graup', 'is', 'to', 'develop', 'marketable', 'nove!', 'products', 'that', 'would', 'be', 'profitable', 'to', 'manufacture', 'and', 'sell.', 'novel', 'is', 'defined', 'as:', 'of', 'a', 'new', 'kind,', 'or', 'different', 'from', 'anything', 'seen', 'or', 'known', 'before.', 'innovation', 'is', 'defined', 'as:', 'something', 'new', 'or', 'different', 'introduced;', 'act', 'of', 'innovating;', 'introduction', 'of', 'new', 'things', 'or', 'methods.', 'the', 'products', 'may', 'incorporate', 'the', 'latest', 'technologies,', 'materials', 'and', 'know-how', 'available', 'to', 'give', 'then', 'a', 'unique', 'taste', 'or', 'look.', 'the', 'first', 'task', 'of', 'the', 'product', 'innovation', 'group', 'was', 'to', 'assemble,', 'review', 'and', 'categorize', 'a', 'list', 'of', 'existing', 'brainstorming', 'ideas.', 'ideas', 'were', 'grouped', 'into', 'two', 'major', 'categories', 'labeled', 'appearance', 'and', 'taste/aroma.', 'these', 'categories', 'are', 'used', 'for', 'novel', 'products', 'that', 'may', 'differ', 'from', 'a', 'visual', 'and/or', 'taste/aroma', 'point', 'of', 'view', 'compared', 'to', 'canventional', 'cigarettes.', 'other', 'categories', 'include', 'a', 'combination', 'of', 'the', 'above,', 'filters,', 'packaging', 'and', 'brand', 'extensions.', 'appearance', 'this', 'category', 'is', 'used', 'for', 'novel', 'cigarette', 'constructions', 'that', 'yield', 'visually', 'different', 'products', 'with', 'minimal', 'changes', 'in', 'smoke', 'chemistry', 'two', 'cigarettes', 'in', 'cne.', 'emulti-plug', 'te', 'build', 'yaur', 'awn', 'cigarette.', 'eswitchable', 'menthol', 'or', 'non', 'menthol', 'cigarette.', '*cigarettes', 'with', 'interspaced', 'perforations', 'to', 'enable', 'smoker', 'to', 'separate', 'unburned', 'section', 'for', 'future', 'smoking.', '«short', 'cigarette,', 'tobacco', 'section', '30', 'mm.', '«extremely', 'fast', 'buming', 'cigarette.', '«novel', 'cigarette', 'constructions', 'that', 'permit', 'a', 'significant', 'reduction', 'iretobacco', 'weight', 'while', 'maintaining', 'smoking', 'mechanics', 'and', 'visual', 'characteristics.', 'higher', 'basis', 'weight', 'paper:', 'potential', 'reduction', 'in', 'tobacco', 'weight.', '«more', 'rigid', 'tobacco', 'column;', 'stiffing', 'agent', 'for', 'tobacco;', 'e.g.', 'starch', '*colored', 'tow', 'and', 'cigarette', 'papers;', 'seasonal', 'promotions,', 'e.g.', 'pastel', 'colored', 'cigarettes', 'for', 'easter', 'or', 'in', 'an', 'ebony', 'and', 'ivory', 'brand', 'containing', 'a', 'mixture', 'of', 'all', 'black', '(black', 'paper', 'and', 'tow)', 'and', 'ail', 'white', 'cigarettes.', '499150498']
|
| 248 |
+
Answer: T.F. Riehl
|
| 249 |
+
start_index 17
|
| 250 |
+
end_index 18
|
| 251 |
+
```
|
| 252 |
+
|
| 253 |
+
ただし、サンプルがエンコードされると、次のようになります。
|
| 254 |
+
|
| 255 |
+
```py
|
| 256 |
+
>>> encoding = tokenizer(example["question"], example["words"], example["boxes"])
|
| 257 |
+
>>> tokenizer.decode(encoding["input_ids"])
|
| 258 |
+
[CLS] who is in cc in this letter? [SEP] wie baw brown & williamson tobacco corporation research & development ...
|
| 259 |
+
```
|
| 260 |
+
|
| 261 |
+
エンコードされた入力内で答えの位置を見つける必要があります。
|
| 262 |
+
* `token_type_ids` は、どのトークンが質問の一部であり、どのトークンが文書の単語の一部であるかを示します。
|
| 263 |
+
* `tokenizer.cls_token_id` は、入力の先頭で特別なトークンを見つけるのに役立ちます。
|
| 264 |
+
* `word_ids` は、元の `words` で見つかった回答を、完全にエンコードされた入力内の同じ回答と照合して判断するのに役立ちます。
|
| 265 |
+
エンコードされた入力内の応答の開始/終了位置。
|
| 266 |
+
|
| 267 |
+
これを念頭に置いて、データセット内のサンプルのバッチをエンコードする関数を作成しましょう。
|
| 268 |
+
|
| 269 |
+
|
| 270 |
+
```py
|
| 271 |
+
>>> def encode_dataset(examples, max_length=512):
|
| 272 |
+
... questions = examples["question"]
|
| 273 |
+
... words = examples["words"]
|
| 274 |
+
... boxes = examples["boxes"]
|
| 275 |
+
... answers = examples["answer"]
|
| 276 |
+
|
| 277 |
+
... # encode the batch of examples and initialize the start_positions and end_positions
|
| 278 |
+
... encoding = tokenizer(questions, words, boxes, max_length=max_length, padding="max_length", truncation=True)
|
| 279 |
+
... start_positions = []
|
| 280 |
+
... end_positions = []
|
| 281 |
+
|
| 282 |
+
... # loop through the examples in the batch
|
| 283 |
+
... for i in range(len(questions)):
|
| 284 |
+
... cls_index = encoding["input_ids"][i].index(tokenizer.cls_token_id)
|
| 285 |
+
|
| 286 |
+
... # find the position of the answer in example's words
|
| 287 |
+
... words_example = [word.lower() for word in words[i]]
|
| 288 |
+
... answer = answers[i]
|
| 289 |
+
... match, word_idx_start, word_idx_end = subfinder(words_example, answer.lower().split())
|
| 290 |
+
|
| 291 |
+
... if match:
|
| 292 |
+
... # if match is found, use `token_type_ids` to find where words start in the encoding
|
| 293 |
+
... token_type_ids = encoding["token_type_ids"][i]
|
| 294 |
+
... token_start_index = 0
|
| 295 |
+
... while token_type_ids[token_start_index] != 1:
|
| 296 |
+
... token_start_index += 1
|
| 297 |
+
|
| 298 |
+
... token_end_index = len(encoding["input_ids"][i]) - 1
|
| 299 |
+
... while token_type_ids[token_end_index] != 1:
|
| 300 |
+
... token_end_index -= 1
|
| 301 |
+
|
| 302 |
+
... word_ids = encoding.word_ids(i)[token_start_index : token_end_index + 1]
|
| 303 |
+
... start_position = cls_index
|
| 304 |
+
... end_position = cls_index
|
| 305 |
+
|
| 306 |
+
... # loop over word_ids and increase `token_start_index` until it matches the answer position in words
|
| 307 |
+
... # once it matches, save the `token_start_index` as the `start_position` of the answer in the encoding
|
| 308 |
+
... for id in word_ids:
|
| 309 |
+
... if id == word_idx_start:
|
| 310 |
+
... start_position = token_start_index
|
| 311 |
+
... else:
|
| 312 |
+
... token_start_index += 1
|
| 313 |
+
|
| 314 |
+
... # similarly loop over `word_ids` starting from the end to find the `end_position` of the answer
|
| 315 |
+
... for id in word_ids[::-1]:
|
| 316 |
+
... if id == word_idx_end:
|
| 317 |
+
... end_position = token_end_index
|
| 318 |
+
... else:
|
| 319 |
+
... token_end_index -= 1
|
| 320 |
+
|
| 321 |
+
... start_positions.append(start_position)
|
| 322 |
+
... end_positions.append(end_position)
|
| 323 |
+
|
| 324 |
+
... else:
|
| 325 |
+
... start_positions.append(cls_index)
|
| 326 |
+
... end_positions.append(cls_index)
|
| 327 |
+
|
| 328 |
+
... encoding["image"] = examples["image"]
|
| 329 |
+
... encoding["start_positions"] = start_positions
|
| 330 |
+
... encoding["end_positions"] = end_positions
|
| 331 |
+
|
| 332 |
+
... return encoding
|
| 333 |
+
```
|
| 334 |
+
|
| 335 |
+
この前処理関数が完成したので���データセット全体をエンコードできます。
|
| 336 |
+
|
| 337 |
+
```py
|
| 338 |
+
>>> encoded_train_dataset = dataset_with_ocr["train"].map(
|
| 339 |
+
... encode_dataset, batched=True, batch_size=2, remove_columns=dataset_with_ocr["train"].column_names
|
| 340 |
+
... )
|
| 341 |
+
>>> encoded_test_dataset = dataset_with_ocr["test"].map(
|
| 342 |
+
... encode_dataset, batched=True, batch_size=2, remove_columns=dataset_with_ocr["test"].column_names
|
| 343 |
+
... )
|
| 344 |
+
```
|
| 345 |
+
|
| 346 |
+
エンコードされたデータセットの特徴がどのようなものかを確認してみましょう。
|
| 347 |
+
|
| 348 |
+
```py
|
| 349 |
+
>>> encoded_train_dataset.features
|
| 350 |
+
{'image': Sequence(feature=Sequence(feature=Sequence(feature=Value(dtype='uint8', id=None), length=-1, id=None), length=-1, id=None), length=-1, id=None),
|
| 351 |
+
'input_ids': Sequence(feature=Value(dtype='int32', id=None), length=-1, id=None),
|
| 352 |
+
'token_type_ids': Sequence(feature=Value(dtype='int8', id=None), length=-1, id=None),
|
| 353 |
+
'attention_mask': Sequence(feature=Value(dtype='int8', id=None), length=-1, id=None),
|
| 354 |
+
'bbox': Sequence(feature=Sequence(feature=Value(dtype='int64', id=None), length=-1, id=None), length=-1, id=None),
|
| 355 |
+
'start_positions': Value(dtype='int64', id=None),
|
| 356 |
+
'end_positions': Value(dtype='int64', id=None)}
|
| 357 |
+
```
|
| 358 |
+
|
| 359 |
+
## Evaluation
|
| 360 |
+
|
| 361 |
+
文書の質問回答の評価には、大量の後処理が必要です。過剰摂取を避けるために
|
| 362 |
+
現時点では、このガイドでは評価ステップを省略しています。 [`Trainer`] はトレーニング中に評価損失を計算するため、
|
| 363 |
+
モデルのパフォーマンスについてまったくわからないわけではありません。抽出的質問応答は通常、F1/完全一致を使用して評価されます。
|
| 364 |
+
自分で実装したい場合は、[質問応答の章](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing) を確認してください。
|
| 365 |
+
インスピレーションを得るためにハグフェイスコースの。
|
| 366 |
+
|
| 367 |
+
## Train
|
| 368 |
+
|
| 369 |
+
おめでとう!このガイドの最も難しい部分を無事にナビゲートできたので、独自のモデルをトレーニングする準備が整いました。
|
| 370 |
+
トレーニングには次の手順が含まれます。
|
| 371 |
+
* 前処理と同じチェックポイントを使用して、[`AutoModelForDocumentQuestionAnswering`] でモデルを読み込みます。
|
| 372 |
+
* [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。
|
| 373 |
+
* サンプルをバッチ処理する関数を定義します。ここでは [`DefaultDataCollator`] が適切に機能します。
|
| 374 |
+
* モデル、データセット、データ照合器とともにトレーニング引数を [`Trainer`] に渡します。
|
| 375 |
+
* [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 376 |
+
|
| 377 |
+
```py
|
| 378 |
+
>>> from transformers import AutoModelForDocumentQuestionAnswering
|
| 379 |
+
|
| 380 |
+
>>> model = AutoModelForDocumentQuestionAnswering.from_pretrained(model_checkpoint)
|
| 381 |
+
```
|
| 382 |
+
|
| 383 |
+
[`TrainingArguments`] で、`output_dir` を使用してモデルの保存場所を指定し、必要に応じてハイパーパラメーターを構成します。
|
| 384 |
+
モデルをコミュニティと共有したい場合は、`push_to_hub`を`True`に設定します (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
|
| 385 |
+
この場合、`output_dir`はモデルのチェックポイントがプッシュされるリポジトリの名前にもなります。
|
| 386 |
+
|
| 387 |
+
```py
|
| 388 |
+
>>> from transformers import TrainingArguments
|
| 389 |
+
|
| 390 |
+
>>> # REPLACE THIS WITH YOUR REPO ID
|
| 391 |
+
>>> repo_id = "MariaK/layoutlmv2-base-uncased_finetuned_docvqa"
|
| 392 |
+
|
| 393 |
+
>>> training_args = TrainingArguments(
|
| 394 |
+
... output_dir=repo_id,
|
| 395 |
+
... per_device_train_batch_size=4,
|
| 396 |
+
... num_train_epochs=20,
|
| 397 |
+
... save_steps=200,
|
| 398 |
+
... logging_steps=50,
|
| 399 |
+
... eval_strategy="steps",
|
| 400 |
+
... learning_rate=5e-5,
|
| 401 |
+
... save_total_limit=2,
|
| 402 |
+
... remove_unused_columns=False,
|
| 403 |
+
... push_to_hub=True,
|
| 404 |
+
... )
|
| 405 |
+
```
|
| 406 |
+
|
| 407 |
+
サンプルをまとめてバッチ処理するための単純なデータ照合器を定義します。
|
| 408 |
+
|
| 409 |
+
```py
|
| 410 |
+
>>> from transformers import DefaultDataCollator
|
| 411 |
+
|
| 412 |
+
>>> data_collator = DefaultDataCollator()
|
| 413 |
+
```
|
| 414 |
+
|
| 415 |
+
最後に、すべてをまとめて、[`~Trainer.train`] を呼び出します。
|
| 416 |
+
|
| 417 |
+
```py
|
| 418 |
+
>>> from transformers import Trainer
|
| 419 |
+
|
| 420 |
+
>>> trainer = Trainer(
|
| 421 |
+
... model=model,
|
| 422 |
+
... args=training_args,
|
| 423 |
+
... data_collator=data_collator,
|
| 424 |
+
... train_dataset=encoded_train_dataset,
|
| 425 |
+
... eval_dataset=encoded_test_dataset,
|
| 426 |
+
... processing_class=processor,
|
| 427 |
+
... )
|
| 428 |
+
|
| 429 |
+
>>> trainer.train()
|
| 430 |
+
```
|
| 431 |
+
|
| 432 |
+
最終モデルを 🤗 Hub に追加するには、モデル カードを作成し、`push_to_hub` を呼び出します。
|
| 433 |
+
|
| 434 |
+
```py
|
| 435 |
+
>>> trainer.create_model_card()
|
| 436 |
+
>>> trainer.push_to_hub()
|
| 437 |
+
```
|
| 438 |
+
|
| 439 |
+
## Inference
|
| 440 |
+
|
| 441 |
+
LayoutLMv2 モデルを微調整し、🤗 ハブにアップロードしたので、それを推論に使用できます。もっとも単純な
|
| 442 |
+
推論用に微調整されたモデルを試す方法は、それを [`Pipeline`] で使用することです。
|
| 443 |
+
|
| 444 |
+
例を挙げてみましょう:
|
| 445 |
+
```py
|
| 446 |
+
>>> example = dataset["test"][2]
|
| 447 |
+
>>> question = example["query"]["en"]
|
| 448 |
+
>>> image = example["image"]
|
| 449 |
+
>>> print(question)
|
| 450 |
+
>>> print(example["answers"])
|
| 451 |
+
'Who is ‘presiding’ TRRF GENERAL SESSION (PART 1)?'
|
| 452 |
+
['TRRF Vice President', 'lee a. waller']
|
| 453 |
+
```
|
| 454 |
+
|
| 455 |
+
次に、パイプラインをインスタンス化します。
|
| 456 |
+
モデルを使用して質問への回答を文書化し、画像と質問の組み合わせをモデルに渡します。
|
| 457 |
+
|
| 458 |
+
```py
|
| 459 |
+
>>> from transformers import pipeline
|
| 460 |
+
|
| 461 |
+
>>> qa_pipeline = pipeline("document-question-answering", model="MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
|
| 462 |
+
>>> qa_pipeline(image, question)
|
| 463 |
+
[{'score': 0.9949808120727539,
|
| 464 |
+
'answer': 'Lee A. Waller',
|
| 465 |
+
'start': 55,
|
| 466 |
+
'end': 57}]
|
| 467 |
+
```
|
| 468 |
+
|
| 469 |
+
必要に応じて、パイプラインの結果を手動で複製することもできます。
|
| 470 |
+
1. 画像と質問を取得し、モデルのプロセッサを使用してモデル用に準備します。
|
| 471 |
+
2. モデルを通じて結果または前処理を転送します。
|
| 472 |
+
3. モデルは`start_logits`と`end_logits`を返します。これらは、どのトークンが応答の先頭にあるのかを示し、
|
| 473 |
+
どのトークンが回答の最後にありますか。どちらも形状 (batch_size、sequence_length) を持ちます。
|
| 474 |
+
4. `start_logits` と `end_logits` の両方の最後の次元で argmax を取得し、予測される `start_idx` と `end_idx` を取得します。
|
| 475 |
+
5. トークナイザーを使用して回答をデコードします。
|
| 476 |
+
|
| 477 |
+
```py
|
| 478 |
+
>>> import torch
|
| 479 |
+
>>> from transformers import AutoProcessor
|
| 480 |
+
>>> from transformers import AutoModelForDocumentQuestionAnswering
|
| 481 |
+
|
| 482 |
+
>>> processor = AutoProcessor.from_pretrained("MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
|
| 483 |
+
>>> model = AutoModelForDocumentQuestionAnswering.from_pretrained("MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
|
| 484 |
+
|
| 485 |
+
>>> with torch.no_grad():
|
| 486 |
+
... encoding = processor(image.convert("RGB"), question, return_tensors="pt")
|
| 487 |
+
... outputs = model(**encoding)
|
| 488 |
+
... start_logits = outputs.start_logits
|
| 489 |
+
... end_logits = outputs.end_logits
|
| 490 |
+
... predicted_start_idx = start_logits.argmax(-1).item()
|
| 491 |
+
... predicted_end_idx = end_logits.argmax(-1).item()
|
| 492 |
+
|
| 493 |
+
>>> processor.tokenizer.decode(encoding.input_ids.squeeze()[predicted_start_idx : predicted_end_idx + 1])
|
| 494 |
+
'lee a. waller'
|
| 495 |
+
```
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/idefics.md
ADDED
|
@@ -0,0 +1,430 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
# Image tasks with IDEFICS
|
| 19 |
+
|
| 20 |
+
[[open-in-colab]]
|
| 21 |
+
|
| 22 |
+
個別のタスクは特殊なモデルを微調整することで対処できますが、別のアプローチも可能です。
|
| 23 |
+
最近登場して人気を博しているのは、微調整を行わずにさまざまなタスクに大規模なモデルを使用することです。
|
| 24 |
+
たとえば、大規模な言語モデルは、要約、翻訳、分類などの NLP タスクを処理できます。
|
| 25 |
+
このアプローチは、テキストなどの単一のモダリティに限定されなくなりました。このガイドでは、次のような方法を説明します。
|
| 26 |
+
IDEFICS と呼ばれる大規模なマルチモーダル モデルを使用して、画像とテキストのタスクを解決します。
|
| 27 |
+
|
| 28 |
+
[IDEFICS](../model_doc/idefics) は、[Flamingo](https://huggingface.co/papers/2204.14198) に基づくオープンアクセスのビジョンおよび言語モデルです。
|
| 29 |
+
DeepMind によって最初に開発された最先端の視覚言語モデル。モデルは任意の画像シーケンスを受け入れます
|
| 30 |
+
テキストを入力し、出力として一貫したテキストを生成します。画像に関する質問に答えたり、視覚的なコンテンツについて説明したり、
|
| 31 |
+
複数のイメージに基づいたストーリーを作成するなど。 IDEFICS には 2 つのバリエーションがあります - [800 億パラメータ](https://huggingface.co/HuggingFaceM4/idefics-80b)
|
| 32 |
+
および [90 億のパラメータ](https://huggingface.co/HuggingFaceM4/idefics-9b)、どちらも 🤗 Hub で入手できます。各バリエーションについて、細かく調整された指示も見つけることができます。
|
| 33 |
+
会話のユースケースに適応したモデルのバージョン。
|
| 34 |
+
|
| 35 |
+
このモデルは非常に多用途で、幅広い画像タスクやマルチモーダル タスクに使用できます。しかし、
|
| 36 |
+
大規模なモデルであるということは、大量の計算リソースとインフラストラクチャが必要であることを意味します。それはあなた次第です
|
| 37 |
+
このアプローチは、個別のタスクごとに特化したモデルを微調整するよりも、ユースケースに適しています。
|
| 38 |
+
|
| 39 |
+
このガイドでは、次の方法を学習します。
|
| 40 |
+
- [IDEFICS をロード](#loading-the-model) および [モデルの量子化バージョンをロード](#quantized-model)
|
| 41 |
+
- IDEFICS を次の目的で使用します。
|
| 42 |
+
- [画像キャプション](#image-captioning)
|
| 43 |
+
- [プロンプト画像キャプション](#prompted-image-captioning)
|
| 44 |
+
- [Few-shot プロンプト](#few-shot-prompting)
|
| 45 |
+
- [ビジュアル質問回答](#visual-question-answering)
|
| 46 |
+
- [画像分類](#image-classification)
|
| 47 |
+
- [画像ガイド付きテキスト生成](#image-guided-text-generation)
|
| 48 |
+
- [バッチモードで推論を実行する](#running-inference-in-batch-mode)
|
| 49 |
+
- [会話用に IDEFICS 命令を実行](#idefics-instruct-for-conversational-use)
|
| 50 |
+
|
| 51 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 52 |
+
|
| 53 |
+
```bash
|
| 54 |
+
pip install -q bitsandbytes sentencepiece accelerate transformers
|
| 55 |
+
```
|
| 56 |
+
|
| 57 |
+
<Tip>
|
| 58 |
+
量子化されていないバージョンのモデル チェックポイントを使用して次の例を実行するには、少なくとも 20GB の GPU メモリが必要です。
|
| 59 |
+
</Tip>
|
| 60 |
+
|
| 61 |
+
## Loading the model
|
| 62 |
+
|
| 63 |
+
まずはモデルの 90 億個のパラメーターのチェックポイントをロードしましょう。
|
| 64 |
+
|
| 65 |
+
```py
|
| 66 |
+
>>> checkpoint = "HuggingFaceM4/idefics-9b"
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
他の Transformers モデルと同様に、プロセッサとモデル自体をチェックポイントからロードする必要があります。
|
| 70 |
+
IDEFICS プロセッサは、[`LlamaTokenizer`] と IDEFICS 画像プロセッサを単一のプロセッサにラップして処理します。
|
| 71 |
+
モデルのテキストと画像の入力を準備します。
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
```py
|
| 75 |
+
>>> import torch
|
| 76 |
+
|
| 77 |
+
>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
|
| 78 |
+
|
| 79 |
+
>>> processor = AutoProcessor.from_pretrained(checkpoint)
|
| 80 |
+
|
| 81 |
+
>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
`device_map`を`auto`に設定すると、モデルの重みを最も最適化された状態でロードおよび保存する方法が自動的に決定されます。
|
| 85 |
+
既存のデバイスを考慮した方法。
|
| 86 |
+
|
| 87 |
+
### Quantized model
|
| 88 |
+
|
| 89 |
+
ハイメモリ GPU の可用性が問題となる場合は、モデルの量子化されたバージョンをロードできます。モデルと
|
| 90 |
+
プロセッサを 4 ビット精度で使用する場合、`BitsAndBytesConfig`を`from_pretrained`メソッドに渡すと、モデルが圧縮されます。
|
| 91 |
+
ロード中にその場で。
|
| 92 |
+
|
| 93 |
+
|
| 94 |
+
```py
|
| 95 |
+
>>> import torch
|
| 96 |
+
>>> from transformers import IdeficsForVisionText2Text, AutoProcessor, BitsAndBytesConfig
|
| 97 |
+
|
| 98 |
+
>>> quantization_config = BitsAndBytesConfig(
|
| 99 |
+
... load_in_4bit=True,
|
| 100 |
+
... bnb_4bit_compute_dtype=torch.float16,
|
| 101 |
+
... )
|
| 102 |
+
|
| 103 |
+
>>> processor = AutoProcessor.from_pretrained(checkpoint)
|
| 104 |
+
|
| 105 |
+
>>> model = IdeficsForVisionText2Text.from_pretrained(
|
| 106 |
+
... checkpoint,
|
| 107 |
+
... quantization_config=quantization_config,
|
| 108 |
+
... device_map="auto"
|
| 109 |
+
... )
|
| 110 |
+
```
|
| 111 |
+
|
| 112 |
+
提案された方法のいずれかでモデルをロードしたので、IDEFICS を使用できるタスクの探索に進みましょう。
|
| 113 |
+
|
| 114 |
+
## Image captioning
|
| 115 |
+
|
| 116 |
+
画像のキャプション付けは、特定の画像のキャプションを予測するタスクです。一般的な用途は視覚障害者を支援することです
|
| 117 |
+
人々はさまざまな状況をナビゲートします。たとえば、オンラインで画像コンテンツを探索します。
|
| 118 |
+
|
| 119 |
+
タスクを説明するには、キャプションを付ける画像を取得します。例:
|
| 120 |
+
|
| 121 |
+
<div class="flex justify-center">
|
| 122 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-im-captioning.jpg" alt="Image of a puppy in a flower bed"/>
|
| 123 |
+
</div>
|
| 124 |
+
|
| 125 |
+
写真提供:[Hendo Wang](https://unsplash.com/@hendoo)
|
| 126 |
+
|
| 127 |
+
IDEFICS はテキストと画像のプロンプトを受け入れます。ただし、画像にキャプションを付けるには、テキスト プロンプトをユーザーに提供する必要はありません。
|
| 128 |
+
モデル、前処理された入力画像のみ。テキスト プロンプトがない場合、モデルはテキストの生成を開始します。
|
| 129 |
+
BOS (Beginning-of-sequence) トークンによりキャプションが作成されます。
|
| 130 |
+
|
| 131 |
+
モデルへの画像入力として、画像オブジェクト (`PIL.Image`) または画像を取得できる URL のいずれかを使用できます。
|
| 132 |
+
|
| 133 |
+
```py
|
| 134 |
+
>>> prompt = [
|
| 135 |
+
... "https://images.unsplash.com/photo-1583160247711-2191776b4b91?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3542&q=80",
|
| 136 |
+
... ]
|
| 137 |
+
|
| 138 |
+
>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
|
| 139 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 140 |
+
|
| 141 |
+
>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
|
| 142 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 143 |
+
>>> print(generated_text[0])
|
| 144 |
+
A puppy in a flower bed
|
| 145 |
+
```
|
| 146 |
+
|
| 147 |
+
<Tip>
|
| 148 |
+
|
| 149 |
+
増加時に発生するエラーを避けるために、`generate`の呼び出しに`bad_words_ids`を含めることをお勧めします。
|
| 150 |
+
`max_new_tokens`: モデルは、新しい `<image>` または `<fake_token_around_image>` トークンを生成する必要があります。
|
| 151 |
+
モデルによって画像が生成されていません。
|
| 152 |
+
このガイドのようにオンザフライで設定することも、[テキスト生成戦略](../generation_strategies) ガイドで説明されているように `GenerationConfig` に保存することもできます。
|
| 153 |
+
</Tip>
|
| 154 |
+
|
| 155 |
+
## Prompted image captioning
|
| 156 |
+
|
| 157 |
+
テキスト プロンプトを提供することで画像キャプションを拡張でき、モデルは画像を指定して続行します。持っていきましょう
|
| 158 |
+
別の図で説明します。
|
| 159 |
+
|
| 160 |
+
<div class="flex justify-center">
|
| 161 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-prompted-im-captioning.jpg" alt="Image of the Eiffel Tower at night"/>
|
| 162 |
+
</div>
|
| 163 |
+
|
| 164 |
+
写真提供:[Denys Nevozhai](https://unsplash.com/@dnevozhai)。
|
| 165 |
+
|
| 166 |
+
テキストおよび画像のプロンプトを単一のリストとしてモデルのプロセッサに渡し、適切な入力を作成できます。
|
| 167 |
+
|
| 168 |
+
```py
|
| 169 |
+
>>> prompt = [
|
| 170 |
+
... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
|
| 171 |
+
... "This is an image of ",
|
| 172 |
+
... ]
|
| 173 |
+
|
| 174 |
+
>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
|
| 175 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 176 |
+
|
| 177 |
+
>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
|
| 178 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 179 |
+
>>> print(generated_text[0])
|
| 180 |
+
This is an image of the Eiffel Tower in Paris, France.
|
| 181 |
+
```
|
| 182 |
+
|
| 183 |
+
## Few-shot prompting
|
| 184 |
+
|
| 185 |
+
IDEFICS はゼロショットで優れた結果を示しますが、タスクによっては特定の形式のキャプションが必要になる場合や、キャプションが付属する場合があります。
|
| 186 |
+
タスクの複雑さを増大させるその他の制限または要件。少数のショットのプロンプトを使用して、コンテキスト内の学習を有効にすることができます。
|
| 187 |
+
プロンプトに例を指定することで、指定された例の形式を模倣した結果を生成するようにモデルを操作できます。
|
| 188 |
+
|
| 189 |
+
前のエッフェル塔の画像をモデルの例として使用し、モデルにデモンストレーションするプロンプトを作成してみましょう。
|
| 190 |
+
画像内のオブジェクトが何であるかを知ることに加えて、それに関する興味深い情報も取得したいと考えています。
|
| 191 |
+
次に、自由の女神の画像に対して同じ応答形式を取得できるかどうかを見てみましょう。
|
| 192 |
+
|
| 193 |
+
<div class="flex justify-center">
|
| 194 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg" alt="Image of the Statue of Liberty"/>
|
| 195 |
+
</div>
|
| 196 |
+
|
| 197 |
+
写真提供:[Juan Mayobre](https://unsplash.com/@jmayobres)。
|
| 198 |
+
|
| 199 |
+
```py
|
| 200 |
+
>>> prompt = ["User:",
|
| 201 |
+
... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
|
| 202 |
+
... "Describe this image.\nAssistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.\n",
|
| 203 |
+
... "User:",
|
| 204 |
+
... "https://images.unsplash.com/photo-1524099163253-32b7f0256868?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3387&q=80",
|
| 205 |
+
... "Describe this image.\nAssistant:"
|
| 206 |
+
... ]
|
| 207 |
+
|
| 208 |
+
>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
|
| 209 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 210 |
+
|
| 211 |
+
>>> generated_ids = model.generate(**inputs, max_new_tokens=30, bad_words_ids=bad_words_ids)
|
| 212 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 213 |
+
>>> print(generated_text[0])
|
| 214 |
+
User: Describe this image.
|
| 215 |
+
Assistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.
|
| 216 |
+
User: Describe this image.
|
| 217 |
+
Assistant: An image of the Statue of Liberty. Fun fact: the Statue of Liberty is 151 feet tall.
|
| 218 |
+
```
|
| 219 |
+
|
| 220 |
+
モデルは 1 つの例 (つまり、1 ショット) だけからタスクの実行方法を学習していることに注目してください。より複雑なタスクの場合は、
|
| 221 |
+
より多くの例 (3 ショット、5 ショットなど) を自由に試してみてください。
|
| 222 |
+
|
| 223 |
+
## Visual question answering
|
| 224 |
+
|
| 225 |
+
Visual Question Answering (VQA) は、画像に基づいて自由形式の質問に答えるタスクです。画像に似ている
|
| 226 |
+
キャプションは、アクセシビリティ アプリケーションだけでなく、教育 (視覚資料についての推論) にも使用できます。
|
| 227 |
+
サービス(画像を基にした商品に関する質問)、画像検索など。
|
| 228 |
+
|
| 229 |
+
このタスク用に新しい画像を取得しましょう。
|
| 230 |
+
|
| 231 |
+
<div class="flex justify-center">
|
| 232 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-vqa.jpg" alt="Image of a couple having a picnic"/>
|
| 233 |
+
</div>
|
| 234 |
+
|
| 235 |
+
写真提供 [Jarritos Mexican Soda](https://unsplash.com/@jarritos).
|
| 236 |
+
|
| 237 |
+
適切な指示をプロンプトすることで、モデルを画像キャプションから視覚的な質問への応答に導くことができます。
|
| 238 |
+
|
| 239 |
+
```py
|
| 240 |
+
>>> prompt = [
|
| 241 |
+
... "Instruction: Provide an answer to the question. Use the image to answer.\n",
|
| 242 |
+
... "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
|
| 243 |
+
... "Question: Where are these people and what's the weather like? Answer:"
|
| 244 |
+
... ]
|
| 245 |
+
|
| 246 |
+
>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
|
| 247 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 248 |
+
|
| 249 |
+
>>> generated_ids = model.generate(**inputs, max_new_tokens=20, bad_words_ids=bad_words_ids)
|
| 250 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 251 |
+
>>> print(generated_text[0])
|
| 252 |
+
Instruction: Provide an answer to the question. Use the image to answer.
|
| 253 |
+
Question: Where are these people and what's the weather like? Answer: They're in a park in New York City, and it's a beautiful day.
|
| 254 |
+
```
|
| 255 |
+
|
| 256 |
+
## Image classification
|
| 257 |
+
|
| 258 |
+
IDEFICS は、次のデータを含むデータについて明示的にトレーニングしなくても、画像をさまざまなカテゴリに分類できます。
|
| 259 |
+
これらの特定のカテゴリからのラベル付きの例。カテゴリのリストを指定し、その画像とテキストを使用して理解する
|
| 260 |
+
機能を利用すると、モデルは画像がどのカテゴリに属する可能性が高いかを推測できます。
|
| 261 |
+
|
| 262 |
+
たとえば、次のような野菜スタンドの画像があるとします。
|
| 263 |
+
|
| 264 |
+
<div class="flex justify-center">
|
| 265 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-classification.jpg" alt="Image of a vegetable stand"/>
|
| 266 |
+
</div>
|
| 267 |
+
|
| 268 |
+
写真提供:[Peter Wendt](https://unsplash.com/@peterwendt)。
|
| 269 |
+
|
| 270 |
+
画像を次のいずれかのカテゴリに分類するようにモデルに指示できます。
|
| 271 |
+
|
| 272 |
+
```py
|
| 273 |
+
>>> categories = ['animals','vegetables', 'city landscape', 'cars', 'office']
|
| 274 |
+
>>> prompt = [f"Instruction: Classify the following image into a single category from the following list: {categories}.\n",
|
| 275 |
+
... "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
|
| 276 |
+
... "Category: "
|
| 277 |
+
... ]
|
| 278 |
+
|
| 279 |
+
>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
|
| 280 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 281 |
+
|
| 282 |
+
>>> generated_ids = model.generate(**inputs, max_new_tokens=6, bad_words_ids=bad_words_ids)
|
| 283 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 284 |
+
>>> print(generated_text[0])
|
| 285 |
+
Instruction: Classify the following image into a single category from the following list: ['animals', 'vegetables', 'city landscape', 'cars', 'office'].
|
| 286 |
+
Category: Vegetables
|
| 287 |
+
```
|
| 288 |
+
|
| 289 |
+
上の例では、画像を 1 つのカテゴリに分類するようにモデルに指示していますが、ランク分類を行うようにモデルに指示することもできます。
|
| 290 |
+
|
| 291 |
+
## Image-guided text generation
|
| 292 |
+
|
| 293 |
+
よりクリエイティブなアプリケーションの場合は、画像ガイド付きテキスト生成を使用して、画像に基づいてテキストを生成できます。これは可能です
|
| 294 |
+
製品、広告、シーンの説明などを作成するのに役立ちます。
|
| 295 |
+
|
| 296 |
+
IDEFICS に、赤いドアの単純な画像に基づいてストーリーを書くように促してみましょう。
|
| 297 |
+
|
| 298 |
+
<div class="flex justify-center">
|
| 299 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-story-generation.jpg" alt="Image of a red door with a pumpkin on the steps"/>
|
| 300 |
+
</div>
|
| 301 |
+
|
| 302 |
+
写真提供:[Craig Tidball](https://unsplash.com/@devonshiremedia)。
|
| 303 |
+
|
| 304 |
+
```py
|
| 305 |
+
>>> prompt = ["Instruction: Use the image to write a story. \n",
|
| 306 |
+
... "https://images.unsplash.com/photo-1517086822157-2b0358e7684a?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=2203&q=80",
|
| 307 |
+
... "Story: \n"]
|
| 308 |
+
|
| 309 |
+
>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
|
| 310 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 311 |
+
|
| 312 |
+
>>> generated_ids = model.generate(**inputs, num_beams=2, max_new_tokens=200, bad_words_ids=bad_words_ids)
|
| 313 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 314 |
+
>>> print(generated_text[0])
|
| 315 |
+
Instruction: Use the image to write a story.
|
| 316 |
+
Story:
|
| 317 |
+
Once upon a time, there was a little girl who lived in a house with a red door. She loved her red door. It was the prettiest door in the whole world.
|
| 318 |
+
|
| 319 |
+
One day, the little girl was playing in her yard when she noticed a man standing on her doorstep. He was wearing a long black coat and a top hat.
|
| 320 |
+
|
| 321 |
+
The little girl ran inside and told her mother about the man.
|
| 322 |
+
|
| 323 |
+
Her mother said, “Don’t worry, honey. He’s just a friendly ghost.”
|
| 324 |
+
|
| 325 |
+
The little girl wasn’t sure if she believed her mother, but she went outside anyway.
|
| 326 |
+
|
| 327 |
+
When she got to the door, the man was gone.
|
| 328 |
+
|
| 329 |
+
The next day, the little girl was playing in her yard again when she noticed the man standing on her doorstep.
|
| 330 |
+
|
| 331 |
+
He was wearing a long black coat and a top hat.
|
| 332 |
+
|
| 333 |
+
The little girl ran
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
IDEFICS は玄関先にあるカボチャに気づき、幽霊に関する不気味なハロウィーンの話をしたようです。
|
| 337 |
+
|
| 338 |
+
<Tip>
|
| 339 |
+
|
| 340 |
+
このような長い出力の場合、テキスト生成戦略を微調整すると大きなメリットが得られます。これは役に立ちます
|
| 341 |
+
生成される出力の品質が大幅に向上します。 [テキスト生成戦略](../generation_strategies) を確認してください。
|
| 342 |
+
詳しく知ることができ。
|
| 343 |
+
|
| 344 |
+
</Tip>
|
| 345 |
+
|
| 346 |
+
## Running inference in batch mode
|
| 347 |
+
|
| 348 |
+
これまでのすべてのセクションでは、IDEFICS を 1 つの例として説明しました。非常に似た方法で、推論を実行できます。
|
| 349 |
+
プロンプトのリストを渡すことにより、サンプルのバッチを取得します。
|
| 350 |
+
|
| 351 |
+
```py
|
| 352 |
+
>>> prompts = [
|
| 353 |
+
... [ "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
|
| 354 |
+
... "This is an image of ",
|
| 355 |
+
... ],
|
| 356 |
+
... [ "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
|
| 357 |
+
... "This is an image of ",
|
| 358 |
+
... ],
|
| 359 |
+
... [ "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
|
| 360 |
+
... "This is an image of ",
|
| 361 |
+
... ],
|
| 362 |
+
... ]
|
| 363 |
+
|
| 364 |
+
>>> inputs = processor(prompts, return_tensors="pt").to("cuda")
|
| 365 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 366 |
+
|
| 367 |
+
>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
|
| 368 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 369 |
+
>>> for i,t in enumerate(generated_text):
|
| 370 |
+
... print(f"{i}:\n{t}\n")
|
| 371 |
+
0:
|
| 372 |
+
This is an image of the Eiffel Tower in Paris, France.
|
| 373 |
+
|
| 374 |
+
1:
|
| 375 |
+
This is an image of a couple on a picnic blanket.
|
| 376 |
+
|
| 377 |
+
2:
|
| 378 |
+
This is an image of a vegetable stand.
|
| 379 |
+
```
|
| 380 |
+
|
| 381 |
+
## IDEFICS instruct for conversational use
|
| 382 |
+
|
| 383 |
+
会話型のユースケースの場合は、🤗 ハブでモデルの微調整された指示されたバージョンを見つけることができます。
|
| 384 |
+
`HuggingFaceM4/idefics-80b-instruct` および `HuggingFaceM4/idefics-9b-instruct`。
|
| 385 |
+
|
| 386 |
+
これらのチェックポイントは、教師ありモデルと命令モデルを組み合わせたそれぞれの基本モデルを微調整した結果です。
|
| 387 |
+
データセットを微調整することで、ダウンストリームのパフォーマンスを向上させながら、会話設定でモデルをより使いやすくします。
|
| 388 |
+
|
| 389 |
+
会話での使用とプロンプトは、基本モデルの使用と非常に似ています。
|
| 390 |
+
|
| 391 |
+
```py
|
| 392 |
+
>>> import torch
|
| 393 |
+
>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
|
| 394 |
+
|
| 395 |
+
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
|
| 396 |
+
|
| 397 |
+
>>> checkpoint = "HuggingFaceM4/idefics-9b-instruct"
|
| 398 |
+
>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16).to(device)
|
| 399 |
+
>>> processor = AutoProcessor.from_pretrained(checkpoint)
|
| 400 |
+
|
| 401 |
+
>>> prompts = [
|
| 402 |
+
... [
|
| 403 |
+
... "User: What is in this image?",
|
| 404 |
+
... "https://upload.wikimedia.org/wikipedia/commons/8/86/Id%C3%A9fix.JPG",
|
| 405 |
+
... "<end_of_utterance>",
|
| 406 |
+
|
| 407 |
+
... "\nAssistant: This picture depicts Idefix, the dog of Obelix in Asterix and Obelix. Idefix is running on the ground.<end_of_utterance>",
|
| 408 |
+
|
| 409 |
+
... "\nUser:",
|
| 410 |
+
... "https://static.wikia.nocookie.net/asterix/images/2/25/R22b.gif/revision/latest?cb=20110815073052",
|
| 411 |
+
... "And who is that?<end_of_utterance>",
|
| 412 |
+
|
| 413 |
+
... "\nAssistant:",
|
| 414 |
+
... ],
|
| 415 |
+
... ]
|
| 416 |
+
|
| 417 |
+
>>> # --batched mode
|
| 418 |
+
>>> inputs = processor(prompts, add_end_of_utterance_token=False, return_tensors="pt").to(device)
|
| 419 |
+
>>> # --single sample mode
|
| 420 |
+
>>> # inputs = processor(prompts[0], return_tensors="pt").to(device)
|
| 421 |
+
|
| 422 |
+
>>> # Generation args
|
| 423 |
+
>>> exit_condition = processor.tokenizer("<end_of_utterance>", add_special_tokens=False).input_ids
|
| 424 |
+
>>> bad_words_ids = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids
|
| 425 |
+
|
| 426 |
+
>>> generated_ids = model.generate(**inputs, eos_token_id=exit_condition, bad_words_ids=bad_words_ids, max_length=100)
|
| 427 |
+
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
|
| 428 |
+
>>> for i, t in enumerate(generated_text):
|
| 429 |
+
... print(f"{i}:\n{t}\n")
|
| 430 |
+
```
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_captioning.md
ADDED
|
@@ -0,0 +1,276 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Image captioning
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
画像のキャプション付けは、特定の画像のキャプションを予測するタスクです。一般的な現実世界のアプリケーションには次のものがあります。
|
| 22 |
+
視覚障害者がさまざまな状況を乗り越えられるよう支援します。したがって、画像のキャプション
|
| 23 |
+
画像を説明することで人々のコンテンツへのアクセシビリティを向上させるのに役立ちます。
|
| 24 |
+
|
| 25 |
+
このガイドでは、次の方法を説明します。
|
| 26 |
+
|
| 27 |
+
* 画像キャプション モデルを微調整します。
|
| 28 |
+
* 微調整されたモデルを推論に使用します。
|
| 29 |
+
|
| 30 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 31 |
+
|
| 32 |
+
```bash
|
| 33 |
+
pip install transformers datasets evaluate -q
|
| 34 |
+
pip install jiwer -q
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
```python
|
| 41 |
+
from huggingface_hub import notebook_login
|
| 42 |
+
|
| 43 |
+
notebook_login()
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
## Load the Pokémon BLIP captions dataset
|
| 47 |
+
|
| 48 |
+
🤗 データセット ライブラリを使用して、{image-caption} ペアで構成されるデータセットを読み込みます。独自の画像キャプション データセットを作成するには
|
| 49 |
+
PyTorch では、[このノートブック](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb) を参照できます。
|
| 50 |
+
|
| 51 |
+
```py
|
| 52 |
+
ds = load_dataset("lambdalabs/pokemon-blip-captions")
|
| 53 |
+
ds
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
```bash
|
| 57 |
+
DatasetDict({
|
| 58 |
+
train: Dataset({
|
| 59 |
+
features: ['image', 'text'],
|
| 60 |
+
num_rows: 833
|
| 61 |
+
})
|
| 62 |
+
})
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
データセットには `image`と`text`の 2 つの機能があります。
|
| 66 |
+
|
| 67 |
+
<Tip>
|
| 68 |
+
|
| 69 |
+
多くの画像キャプション データセットには、画像ごとに複数のキャプションが含まれています。このような場合、一般的な戦略は、トレーニング中に利用可能なキャプションの中からランダムにキャプションをサンプリングすることです。
|
| 70 |
+
|
| 71 |
+
</Tip>
|
| 72 |
+
|
| 73 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットのトレイン スプリットをトレイン セットとテスト セットに分割します。
|
| 74 |
+
|
| 75 |
+
```python
|
| 76 |
+
ds = ds["train"].train_test_split(test_size=0.1)
|
| 77 |
+
train_ds = ds["train"]
|
| 78 |
+
test_ds = ds["test"]
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
トレーニング セットからのいくつかのサンプルを視覚化してみましょう。
|
| 82 |
+
|
| 83 |
+
```python
|
| 84 |
+
from textwrap import wrap
|
| 85 |
+
import matplotlib.pyplot as plt
|
| 86 |
+
import numpy as np
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
def plot_images(images, captions):
|
| 90 |
+
plt.figure(figsize=(20, 20))
|
| 91 |
+
for i in range(len(images)):
|
| 92 |
+
ax = plt.subplot(1, len(images), i + 1)
|
| 93 |
+
caption = captions[i]
|
| 94 |
+
caption = "\n".join(wrap(caption, 12))
|
| 95 |
+
plt.title(caption)
|
| 96 |
+
plt.imshow(images[i])
|
| 97 |
+
plt.axis("off")
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
|
| 101 |
+
sample_captions = [train_ds[i]["text"] for i in range(5)]
|
| 102 |
+
plot_images(sample_images_to_visualize, sample_captions)
|
| 103 |
+
```
|
| 104 |
+
|
| 105 |
+
<div class="flex justify-center">
|
| 106 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/sample_training_images_image_cap.png" alt="Sample training images"/>
|
| 107 |
+
</div>
|
| 108 |
+
|
| 109 |
+
## Preprocess the dataset
|
| 110 |
+
|
| 111 |
+
データセットには 2 つのモダリティ (画像とテキスト) があるため、前処理パイプラインは画像とキャプションを前処理します。
|
| 112 |
+
|
| 113 |
+
これを行うには、微調整しようとしているモデルに関連付けられたプロセッサ クラスをロードします。
|
| 114 |
+
|
| 115 |
+
```python
|
| 116 |
+
from transformers import AutoProcessor
|
| 117 |
+
|
| 118 |
+
checkpoint = "microsoft/git-base"
|
| 119 |
+
processor = AutoProcessor.from_pretrained(checkpoint)
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
プロセッサは内部で画像を前処理し (サイズ変更やピクセル スケーリングを含む)、キャプションをトークン化します。
|
| 124 |
+
|
| 125 |
+
```python
|
| 126 |
+
def transforms(example_batch):
|
| 127 |
+
images = [x for x in example_batch["image"]]
|
| 128 |
+
captions = [x for x in example_batch["text"]]
|
| 129 |
+
inputs = processor(images=images, text=captions, padding="max_length")
|
| 130 |
+
inputs.update({"labels": inputs["input_ids"]})
|
| 131 |
+
return inputs
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
train_ds.set_transform(transforms)
|
| 135 |
+
test_ds.set_transform(transforms)
|
| 136 |
+
```
|
| 137 |
+
|
| 138 |
+
データセットの準備ができたら、微調整用にモデルをセットアップできます。
|
| 139 |
+
|
| 140 |
+
## Load a base model
|
| 141 |
+
|
| 142 |
+
["microsoft/git-base"](https://huggingface.co/microsoft/git-base) を [`AutoModelForCausalLM`](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModelForCausalLM) オブジェクト。
|
| 143 |
+
|
| 144 |
+
```python
|
| 145 |
+
from transformers import AutoModelForCausalLM
|
| 146 |
+
|
| 147 |
+
model = AutoModelForCausalLM.from_pretrained(checkpoint)
|
| 148 |
+
```
|
| 149 |
+
|
| 150 |
+
```python
|
| 151 |
+
from transformers import AutoModelForCausalLM
|
| 152 |
+
|
| 153 |
+
model = AutoModelForCausalLM.from_pretrained(checkpoint)
|
| 154 |
+
```
|
| 155 |
+
## Evaluate
|
| 156 |
+
|
| 157 |
+
画像キャプション モデルは通常、[Rouge Score](https://huggingface.co/spaces/evaluate-metric/rouge) または [Word Error Rate](https://huggingface.co/spaces/evaluate-metric/) で評価されます。そうだった)。このガイドでは、Word Error Rate (WER) を使用します。
|
| 158 |
+
|
| 159 |
+
これを行うには 🤗 Evaluate ライブラリを使用します。 WER の潜在的な制限やその他の問題点については、[このガイド](https://huggingface.co/spaces/evaluate-metric/wer) を参照してください。
|
| 160 |
+
|
| 161 |
+
```python
|
| 162 |
+
from evaluate import load
|
| 163 |
+
import torch
|
| 164 |
+
|
| 165 |
+
wer = load("wer")
|
| 166 |
+
|
| 167 |
+
|
| 168 |
+
def compute_metrics(eval_pred):
|
| 169 |
+
logits, labels = eval_pred
|
| 170 |
+
predicted = logits.argmax(-1)
|
| 171 |
+
decoded_labels = processor.batch_decode(labels, skip_special_tokens=True)
|
| 172 |
+
decoded_predictions = processor.batch_decode(predicted, skip_special_tokens=True)
|
| 173 |
+
wer_score = wer.compute(predictions=decoded_predictions, references=decoded_labels)
|
| 174 |
+
return {"wer_score": wer_score}
|
| 175 |
+
```
|
| 176 |
+
|
| 177 |
+
## Train!
|
| 178 |
+
|
| 179 |
+
これで、モデルの微調整を開始する準備が整いました。これには 🤗 [`Trainer`] を使用します。
|
| 180 |
+
|
| 181 |
+
まず、[`TrainingArguments`] を使用してトレーニング引数を定義します。
|
| 182 |
+
|
| 183 |
+
```python
|
| 184 |
+
from transformers import TrainingArguments, Trainer
|
| 185 |
+
|
| 186 |
+
model_name = checkpoint.split("/")[1]
|
| 187 |
+
|
| 188 |
+
training_args = TrainingArguments(
|
| 189 |
+
output_dir=f"{model_name}-pokemon",
|
| 190 |
+
learning_rate=5e-5,
|
| 191 |
+
num_train_epochs=50,
|
| 192 |
+
fp16=True,
|
| 193 |
+
per_device_train_batch_size=32,
|
| 194 |
+
per_device_eval_batch_size=32,
|
| 195 |
+
gradient_accumulation_steps=2,
|
| 196 |
+
save_total_limit=3,
|
| 197 |
+
eval_strategy="steps",
|
| 198 |
+
eval_steps=50,
|
| 199 |
+
save_strategy="steps",
|
| 200 |
+
save_steps=50,
|
| 201 |
+
logging_steps=50,
|
| 202 |
+
remove_unused_columns=False,
|
| 203 |
+
push_to_hub=True,
|
| 204 |
+
label_names=["labels"],
|
| 205 |
+
load_best_model_at_end=True,
|
| 206 |
+
)
|
| 207 |
+
```
|
| 208 |
+
|
| 209 |
+
Trainer 次に、次に、データセットとモデルと一緒に 🤗 に渡します。
|
| 210 |
+
|
| 211 |
+
```python
|
| 212 |
+
trainer = Trainer(
|
| 213 |
+
model=model,
|
| 214 |
+
args=training_args,
|
| 215 |
+
train_dataset=train_ds,
|
| 216 |
+
eval_dataset=test_ds,
|
| 217 |
+
compute_metrics=compute_metrics,
|
| 218 |
+
)
|
| 219 |
+
```
|
| 220 |
+
|
| 221 |
+
トレーニングを開始するには、[`Trainer`] オブジェクトの [`~Trainer.train`] を呼び出すだけです。
|
| 222 |
+
|
| 223 |
+
```python
|
| 224 |
+
trainer.train()
|
| 225 |
+
```
|
| 226 |
+
|
| 227 |
+
トレーニングが進むにつれて、トレーニングの損失がスムーズに減少することがわかります。
|
| 228 |
+
|
| 229 |
+
トレーニングが完了したら、 [`~Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 230 |
+
|
| 231 |
+
```python
|
| 232 |
+
trainer.push_to_hub()
|
| 233 |
+
```
|
| 234 |
+
|
| 235 |
+
## Inference
|
| 236 |
+
|
| 237 |
+
`test_ds` からサンプル画像を取得してモデルをテストします。
|
| 238 |
+
|
| 239 |
+
```python
|
| 240 |
+
from PIL import Image
|
| 241 |
+
import requests
|
| 242 |
+
|
| 243 |
+
url = "https://huggingface.co/datasets/sayakpaul/sample-datasets/resolve/main/pokemon.png"
|
| 244 |
+
image = Image.open(requests.get(url, stream=True).raw)
|
| 245 |
+
image
|
| 246 |
+
```
|
| 247 |
+
|
| 248 |
+
<div class="flex justify-center">
|
| 249 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/test_image_image_cap.png" alt="Test image"/>
|
| 250 |
+
</div>
|
| 251 |
+
|
| 252 |
+
モデル用の画像を準備します。
|
| 253 |
+
|
| 254 |
+
```python
|
| 255 |
+
device = "cuda" if torch.cuda.is_available() else "cpu"
|
| 256 |
+
|
| 257 |
+
inputs = processor(images=image, return_tensors="pt").to(device)
|
| 258 |
+
pixel_values = inputs.pixel_values
|
| 259 |
+
```
|
| 260 |
+
|
| 261 |
+
[`generate`] を呼び出して予測をデコードします。
|
| 262 |
+
|
| 263 |
+
```python
|
| 264 |
+
generated_ids = model.generate(pixel_values=pixel_values, max_length=50)
|
| 265 |
+
generated_caption = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
| 266 |
+
print(generated_caption)
|
| 267 |
+
```
|
| 268 |
+
```bash
|
| 269 |
+
a drawing of a pink and blue pokemon
|
| 270 |
+
```
|
| 271 |
+
|
| 272 |
+
微調整されたモデルにより、非常に優れたキャプションが生成されたようです。
|
| 273 |
+
|
| 274 |
+
|
| 275 |
+
|
| 276 |
+
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_classification.md
ADDED
|
@@ -0,0 +1,553 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
# Image classification
|
| 19 |
+
|
| 20 |
+
[[open-in-colab]]
|
| 21 |
+
|
| 22 |
+
<Youtube id="tjAIM7BOYhw"/>
|
| 23 |
+
|
| 24 |
+
画像分類では、画像にラベルまたはクラスを割り当てます。テキストや音声の分類とは異なり、入力は
|
| 25 |
+
画像を構成するピクセル値。損傷の検出など、画像分類には多くの用途があります
|
| 26 |
+
自然災害の後、作物の健康状態を監視したり、病気の兆候がないか医療画像をスクリーニングしたりするのに役立ちます。
|
| 27 |
+
|
| 28 |
+
このガイドでは、次の方法を説明します。
|
| 29 |
+
|
| 30 |
+
1. [Food-101](https://huggingface.co/datasets/food101) データセットの [ViT](model_doc/vit) を微調整して、画像内の食品を分類します。
|
| 31 |
+
2. 微調整したモデルを推論に使用します。
|
| 32 |
+
|
| 33 |
+
<Tip>
|
| 34 |
+
|
| 35 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/image-classification) を確認することをお勧めします。
|
| 36 |
+
|
| 37 |
+
</Tip>
|
| 38 |
+
|
| 39 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install transformers datasets evaluate
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
Hugging Face アカウントにログインして、モデルをアップロードしてコミュニティと共有することをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 46 |
+
|
| 47 |
+
```py
|
| 48 |
+
>>> from huggingface_hub import notebook_login
|
| 49 |
+
|
| 50 |
+
>>> notebook_login()
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
## Load Food-101 dataset
|
| 54 |
+
|
| 55 |
+
Datasets、🤗 データセット ライブラリから Food-101 データセットの小さいサブセットを読み込みます。これにより、次の機会が得られます
|
| 56 |
+
完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認してください。
|
| 57 |
+
|
| 58 |
+
```py
|
| 59 |
+
>>> from datasets import load_dataset
|
| 60 |
+
|
| 61 |
+
>>> food = load_dataset("food101", split="train[:5000]")
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
```py
|
| 68 |
+
>>> food = food.train_test_split(test_size=0.2)
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
次に、例を見てみましょう。
|
| 72 |
+
|
| 73 |
+
```py
|
| 74 |
+
>>> food["train"][0]
|
| 75 |
+
{'image': <PIL.JpegImagePlugin.JpegImageFile image mode=RGB size=512x512 at 0x7F52AFC8AC50>,
|
| 76 |
+
'label': 79}
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
データセット内の各例には 2 つのフィールドがあります。
|
| 80 |
+
|
| 81 |
+
- `image`: 食品の PIL 画像
|
| 82 |
+
- `label`: 食品のラベルクラス
|
| 83 |
+
|
| 84 |
+
モデルがラベル ID からラベル名を取得しやすくするために、ラベル名をマップする辞書を作成します。
|
| 85 |
+
整数への変換、またはその逆:
|
| 86 |
+
|
| 87 |
+
```py
|
| 88 |
+
>>> labels = food["train"].features["label"].names
|
| 89 |
+
>>> label2id, id2label = dict(), dict()
|
| 90 |
+
>>> for i, label in enumerate(labels):
|
| 91 |
+
... label2id[label] = str(i)
|
| 92 |
+
... id2label[str(i)] = label
|
| 93 |
+
```
|
| 94 |
+
|
| 95 |
+
これで、ラベル ID をラベル名に変換できるようになりました。
|
| 96 |
+
|
| 97 |
+
```py
|
| 98 |
+
>>> id2label[str(79)]
|
| 99 |
+
'prime_rib'
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
## Preprocess
|
| 103 |
+
|
| 104 |
+
次のステップでは、ViT 画像プロセッサをロードして画像をテンソルに処理します。
|
| 105 |
+
|
| 106 |
+
```py
|
| 107 |
+
>>> from transformers import AutoImageProcessor
|
| 108 |
+
|
| 109 |
+
>>> checkpoint = "google/vit-base-patch16-224-in21k"
|
| 110 |
+
>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
<frameworkcontent>
|
| 115 |
+
<pt>
|
| 116 |
+
|
| 117 |
+
いくつかの画像変換を画像に適用して、モデルの過学習に対する堅牢性を高めます。ここでは torchvision の [`transforms`](https://pytorch.org/vision/stable/transforms.html) モジュールを使用しますが、任意の画像ライブラリを使用することもできます。
|
| 118 |
+
|
| 119 |
+
画像のランダムな部分をトリミングし、サイズを変更し、画像の平均と標準偏差で正規化します。
|
| 120 |
+
|
| 121 |
+
|
| 122 |
+
```py
|
| 123 |
+
>>> from torchvision.transforms import RandomResizedCrop, Compose, Normalize, ToTensor
|
| 124 |
+
|
| 125 |
+
>>> normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
|
| 126 |
+
>>> size = (
|
| 127 |
+
... image_processor.size["shortest_edge"]
|
| 128 |
+
... if "shortest_edge" in image_processor.size
|
| 129 |
+
... else (image_processor.size["height"], image_processor.size["width"])
|
| 130 |
+
... )
|
| 131 |
+
>>> _transforms = Compose([RandomResizedCrop(size), ToTensor(), normalize])
|
| 132 |
+
```
|
| 133 |
+
|
| 134 |
+
次に、変換を適用し、画像の `pixel_values` (モデルへの入力) を返す前処理関数を作成します。
|
| 135 |
+
|
| 136 |
+
```py
|
| 137 |
+
>>> def transforms(examples):
|
| 138 |
+
... examples["pixel_values"] = [_transforms(img.convert("RGB")) for img in examples["image"]]
|
| 139 |
+
... del examples["image"]
|
| 140 |
+
... return examples
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.with_transform`] メソッドを使用します。変換は、データセットの要素を読み込むときにオンザフライで適用されます。
|
| 144 |
+
|
| 145 |
+
```py
|
| 146 |
+
>>> food = food.with_transform(transforms)
|
| 147 |
+
```
|
| 148 |
+
|
| 149 |
+
次に、[`DefaultDataCollator`] を使用してサンプルのバッチを作成します。 🤗 Transformers の他のデータ照合器とは異なり、`DefaultDataCollator` はパディングなどの追加の前処理を適用しません。
|
| 150 |
+
|
| 151 |
+
```py
|
| 152 |
+
>>> from transformers import DefaultDataCollator
|
| 153 |
+
|
| 154 |
+
>>> data_collator = DefaultDataCollator()
|
| 155 |
+
```
|
| 156 |
+
</pt>
|
| 157 |
+
</frameworkcontent>
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
<frameworkcontent>
|
| 161 |
+
<tf>
|
| 162 |
+
|
| 163 |
+
過剰適合を回避し、モデルをより堅牢にするために、データセットのトレーニング部分にデータ拡張を追加します。
|
| 164 |
+
ここでは、Keras 前処理レイヤーを使用してトレーニング データの変換 (データ拡張を含む) を定義します。
|
| 165 |
+
検証データの変換 (中央のトリミング、サイズ変更、正規化のみ)。 `tf.image` または
|
| 166 |
+
他のライブラリでも構いません。
|
| 167 |
+
|
| 168 |
+
|
| 169 |
+
```py
|
| 170 |
+
>>> from tensorflow import keras
|
| 171 |
+
>>> from tensorflow.keras import layers
|
| 172 |
+
|
| 173 |
+
>>> size = (image_processor.size["height"], image_processor.size["width"])
|
| 174 |
+
|
| 175 |
+
>>> train_data_augmentation = keras.Sequential(
|
| 176 |
+
... [
|
| 177 |
+
... layers.RandomCrop(size[0], size[1]),
|
| 178 |
+
... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
|
| 179 |
+
... layers.RandomFlip("horizontal"),
|
| 180 |
+
... layers.RandomRotation(factor=0.02),
|
| 181 |
+
... layers.RandomZoom(height_factor=0.2, width_factor=0.2),
|
| 182 |
+
... ],
|
| 183 |
+
... name="train_data_augmentation",
|
| 184 |
+
... )
|
| 185 |
+
|
| 186 |
+
>>> val_data_augmentation = keras.Sequential(
|
| 187 |
+
... [
|
| 188 |
+
... layers.CenterCrop(size[0], size[1]),
|
| 189 |
+
... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
|
| 190 |
+
... ],
|
| 191 |
+
... name="val_data_augmentation",
|
| 192 |
+
... )
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
次に、一度に 1 つの画像ではなく、画像のバッチに適切な変換を適用する関数を作成します。
|
| 196 |
+
|
| 197 |
+
```py
|
| 198 |
+
>>> import numpy as np
|
| 199 |
+
>>> import tensorflow as tf
|
| 200 |
+
>>> from PIL import Image
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
>>> def convert_to_tf_tensor(image: Image):
|
| 204 |
+
... np_image = np.array(image)
|
| 205 |
+
... tf_image = tf.convert_to_tensor(np_image)
|
| 206 |
+
... # `expand_dims()` is used to add a batch dimension since
|
| 207 |
+
... # the TF augmentation layers operates on batched inputs.
|
| 208 |
+
... return tf.expand_dims(tf_image, 0)
|
| 209 |
+
|
| 210 |
+
|
| 211 |
+
>>> def preprocess_train(example_batch):
|
| 212 |
+
... """Apply train_transforms across a batch."""
|
| 213 |
+
... images = [
|
| 214 |
+
... train_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
|
| 215 |
+
... ]
|
| 216 |
+
... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
|
| 217 |
+
... return example_batch
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
... def preprocess_val(example_batch):
|
| 221 |
+
... """Apply val_transforms across a batch."""
|
| 222 |
+
... images = [
|
| 223 |
+
... val_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
|
| 224 |
+
... ]
|
| 225 |
+
... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
|
| 226 |
+
... return example_batch
|
| 227 |
+
```
|
| 228 |
+
|
| 229 |
+
🤗 データセット [`~datasets.Dataset.set_transform`] を使用して、その場で変換を適用します。
|
| 230 |
+
|
| 231 |
+
```py
|
| 232 |
+
food["train"].set_transform(preprocess_train)
|
| 233 |
+
food["test"].set_transform(preprocess_val)
|
| 234 |
+
```
|
| 235 |
+
|
| 236 |
+
最後の前処理ステップとして、`DefaultDataCollator`を使用してサンプルのバッチを作成します。 🤗 Transformers の他のデータ照合機能とは異なり、
|
| 237 |
+
`DefaultDataCollator` は、パディングなどの追加の前処理を適用しません。
|
| 238 |
+
|
| 239 |
+
```py
|
| 240 |
+
>>> from transformers import DefaultDataCollator
|
| 241 |
+
|
| 242 |
+
>>> data_collator = DefaultDataCollator(return_tensors="tf")
|
| 243 |
+
```
|
| 244 |
+
</tf>
|
| 245 |
+
</frameworkcontent>
|
| 246 |
+
|
| 247 |
+
## Evaluate
|
| 248 |
+
|
| 249 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。すぐにロードできます
|
| 250 |
+
🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用した評価方法。このタスクでは、ロードします
|
| 251 |
+
[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 指標 (詳細については、🤗 評価 [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してくださいメトリクスをロードして計算する方法):
|
| 252 |
+
|
| 253 |
+
```py
|
| 254 |
+
>>> import evaluate
|
| 255 |
+
|
| 256 |
+
>>> accuracy = evaluate.load("accuracy")
|
| 257 |
+
```
|
| 258 |
+
|
| 259 |
+
��に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して精度を計算する関数を作成します。
|
| 260 |
+
|
| 261 |
+
```py
|
| 262 |
+
>>> import numpy as np
|
| 263 |
+
|
| 264 |
+
|
| 265 |
+
>>> def compute_metrics(eval_pred):
|
| 266 |
+
... predictions, labels = eval_pred
|
| 267 |
+
... predictions = np.argmax(predictions, axis=1)
|
| 268 |
+
... return accuracy.compute(predictions=predictions, references=labels)
|
| 269 |
+
```
|
| 270 |
+
|
| 271 |
+
これで `compute_metrics`関数の準備が整いました。トレーニングを設定するときにこの関数に戻ります。
|
| 272 |
+
|
| 273 |
+
## Train
|
| 274 |
+
|
| 275 |
+
<frameworkcontent>
|
| 276 |
+
<pt>
|
| 277 |
+
<Tip>
|
| 278 |
+
|
| 279 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 280 |
+
|
| 281 |
+
</Tip>
|
| 282 |
+
|
| 283 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForImageClassification`] を使用して ViT をロードします。ラベルの数と予想されるラベルの数、およびラベル マッピングを指定します。
|
| 284 |
+
|
| 285 |
+
```py
|
| 286 |
+
>>> from transformers import AutoModelForImageClassification, TrainingArguments, Trainer
|
| 287 |
+
|
| 288 |
+
>>> model = AutoModelForImageClassification.from_pretrained(
|
| 289 |
+
... checkpoint,
|
| 290 |
+
... num_labels=len(labels),
|
| 291 |
+
... id2label=id2label,
|
| 292 |
+
... label2id=label2id,
|
| 293 |
+
... )
|
| 294 |
+
```
|
| 295 |
+
|
| 296 |
+
この時点で残っているステップは 3 つだけです。
|
| 297 |
+
|
| 298 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。 `image` 列が削除されるため、未使用の列を削除しないことが重要です。 `image` 列がないと、`pixel_values` を作成できません。この動作を防ぐには、`remove_unused_columns=False`を設定してください。他に必要なパラメータは、モデルの保存場所を指定する `output_dir` だけです。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は精度を評価し、トレーニング チェックポイントを保存します。
|
| 299 |
+
2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
|
| 300 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 301 |
+
|
| 302 |
+
```py
|
| 303 |
+
>>> training_args = TrainingArguments(
|
| 304 |
+
... output_dir="my_awesome_food_model",
|
| 305 |
+
... remove_unused_columns=False,
|
| 306 |
+
... eval_strategy="epoch",
|
| 307 |
+
... save_strategy="epoch",
|
| 308 |
+
... learning_rate=5e-5,
|
| 309 |
+
... per_device_train_batch_size=16,
|
| 310 |
+
... gradient_accumulation_steps=4,
|
| 311 |
+
... per_device_eval_batch_size=16,
|
| 312 |
+
... num_train_epochs=3,
|
| 313 |
+
... warmup_ratio=0.1,
|
| 314 |
+
... logging_steps=10,
|
| 315 |
+
... load_best_model_at_end=True,
|
| 316 |
+
... metric_for_best_model="accuracy",
|
| 317 |
+
... push_to_hub=True,
|
| 318 |
+
... )
|
| 319 |
+
|
| 320 |
+
>>> trainer = Trainer(
|
| 321 |
+
... model=model,
|
| 322 |
+
... args=training_args,
|
| 323 |
+
... data_collator=data_collator,
|
| 324 |
+
... train_dataset=food["train"],
|
| 325 |
+
... eval_dataset=food["test"],
|
| 326 |
+
... processing_class=image_processor,
|
| 327 |
+
... compute_metrics=compute_metrics,
|
| 328 |
+
... )
|
| 329 |
+
|
| 330 |
+
>>> trainer.train()
|
| 331 |
+
```
|
| 332 |
+
|
| 333 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 334 |
+
|
| 335 |
+
```py
|
| 336 |
+
>>> trainer.push_to_hub()
|
| 337 |
+
```
|
| 338 |
+
</pt>
|
| 339 |
+
</frameworkcontent>
|
| 340 |
+
|
| 341 |
+
<frameworkcontent>
|
| 342 |
+
<tf>
|
| 343 |
+
|
| 344 |
+
<Tip>
|
| 345 |
+
|
| 346 |
+
|
| 347 |
+
Keras を使用したモデルの微調整に慣れていない場合は、まず [基本チュートリアル](./training#train-a-tensorflow-model-with-keras) を確認してください。
|
| 348 |
+
|
| 349 |
+
</Tip>
|
| 350 |
+
|
| 351 |
+
|
| 352 |
+
TensorFlow でモデルを微調整するには、次の手順に従います。
|
| 353 |
+
1. トレーニングのハイパーパラメータを定義し、オプティマイザーと学習率スケジュールを設定します。
|
| 354 |
+
2. 事前トレーニングされたモデルをインスタンス化します。
|
| 355 |
+
3. 🤗 データセットを `tf.data.Dataset` に変換します。
|
| 356 |
+
4. モデルをコンパイルします。
|
| 357 |
+
5. コールバックを追加し、`fit()` メソッドを使用してトレーニングを実行します。
|
| 358 |
+
6. モデルを 🤗 Hub にアップロードしてコミュニティと共有します。
|
| 359 |
+
|
| 360 |
+
まず、ハイパーパラメーター、オプティマイザー、学習率スケジュールを定義します。
|
| 361 |
+
|
| 362 |
+
```py
|
| 363 |
+
>>> from transformers import create_optimizer
|
| 364 |
+
|
| 365 |
+
>>> batch_size = 16
|
| 366 |
+
>>> num_epochs = 5
|
| 367 |
+
>>> num_train_steps = len(food["train"]) * num_epochs
|
| 368 |
+
>>> learning_rate = 3e-5
|
| 369 |
+
>>> weight_decay_rate = 0.01
|
| 370 |
+
|
| 371 |
+
>>> optimizer, lr_schedule = create_optimizer(
|
| 372 |
+
... init_lr=learning_rate,
|
| 373 |
+
... num_train_steps=num_train_steps,
|
| 374 |
+
... weight_decay_rate=weight_decay_rate,
|
| 375 |
+
... num_warmup_steps=0,
|
| 376 |
+
... )
|
| 377 |
+
```
|
| 378 |
+
|
| 379 |
+
次に、ラベル マッピングとともに [`TFAutoModelForImageClassification`] を使用して ViT を読み込みます。
|
| 380 |
+
|
| 381 |
+
```py
|
| 382 |
+
>>> from transformers import TFAutoModelForImageClassification
|
| 383 |
+
|
| 384 |
+
>>> model = TFAutoModelForImageClassification.from_pretrained(
|
| 385 |
+
... checkpoint,
|
| 386 |
+
... id2label=id2label,
|
| 387 |
+
... label2id=label2id,
|
| 388 |
+
... )
|
| 389 |
+
```
|
| 390 |
+
|
| 391 |
+
Convert your datasets to the `tf.data.Dataset` format using the [`~datasets.Dataset.to_tf_dataset`] and your `data_collator`:
|
| 392 |
+
|
| 393 |
+
```py
|
| 394 |
+
>>> # converting our train dataset to tf.data.Dataset
|
| 395 |
+
>>> tf_train_dataset = food["train"].to_tf_dataset(
|
| 396 |
+
... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
|
| 397 |
+
... )
|
| 398 |
+
|
| 399 |
+
>>> # converting our test dataset to tf.data.Dataset
|
| 400 |
+
>>> tf_eval_dataset = food["test"].to_tf_dataset(
|
| 401 |
+
... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
|
| 402 |
+
... )
|
| 403 |
+
```
|
| 404 |
+
|
| 405 |
+
`compile()` を使用してトレーニング用にモデルを設定します。
|
| 406 |
+
|
| 407 |
+
```py
|
| 408 |
+
>>> from tensorflow.keras.losses import SparseCategoricalCrossentropy
|
| 409 |
+
|
| 410 |
+
>>> loss = tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True)
|
| 411 |
+
>>> model.compile(optimizer=optimizer, loss=loss)
|
| 412 |
+
```
|
| 413 |
+
|
| 414 |
+
予測から精度を計算し、モデルを 🤗 ハブにプッシュするには、[Keras callbacks](../main_classes/keras_callbacks) を使用します。
|
| 415 |
+
`compute_metrics` 関数を [KerasMetricCallback](../main_classes/keras_callbacks#transformers.KerasMetricCallback) に渡します。
|
| 416 |
+
[PushToHubCallback](../main_classes/keras_callbacks#transformers.PushToHubCallback) を使用してモデルをアップロードします。
|
| 417 |
+
|
| 418 |
+
```py
|
| 419 |
+
>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
|
| 420 |
+
|
| 421 |
+
>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_eval_dataset)
|
| 422 |
+
>>> push_to_hub_callback = PushToHubCallback(
|
| 423 |
+
... output_dir="food_classifier",
|
| 424 |
+
... tokenizer=image_processor,
|
| 425 |
+
... save_strategy="no",
|
| 426 |
+
... )
|
| 427 |
+
>>> callbacks = [metric_callback, push_to_hub_callback]
|
| 428 |
+
```
|
| 429 |
+
|
| 430 |
+
ついに、モデルをトレーニングする準備が整いました。トレーニングおよび検証データセット、エポック数、
|
| 431 |
+
モデルを微調整するためのコールバック:
|
| 432 |
+
|
| 433 |
+
```py
|
| 434 |
+
>>> model.fit(tf_train_dataset, validation_data=tf_eval_dataset, epochs=num_epochs, callbacks=callbacks)
|
| 435 |
+
Epoch 1/5
|
| 436 |
+
250/250 [==============================] - 313s 1s/step - loss: 2.5623 - val_loss: 1.4161 - accuracy: 0.9290
|
| 437 |
+
Epoch 2/5
|
| 438 |
+
250/250 [==============================] - 265s 1s/step - loss: 0.9181 - val_loss: 0.6808 - accuracy: 0.9690
|
| 439 |
+
Epoch 3/5
|
| 440 |
+
250/250 [==============================] - 252s 1s/step - loss: 0.3910 - val_loss: 0.4303 - accuracy: 0.9820
|
| 441 |
+
Epoch 4/5
|
| 442 |
+
250/250 [==============================] - 251s 1s/step - loss: 0.2028 - val_loss: 0.3191 - accuracy: 0.9900
|
| 443 |
+
Epoch 5/5
|
| 444 |
+
250/250 [==============================] - 238s 949ms/step - loss: 0.1232 - val_loss: 0.3259 - accuracy: 0.9890
|
| 445 |
+
```
|
| 446 |
+
|
| 447 |
+
おめでとう!モデルを微調整し、🤗 Hub で共有しました。これで推論に使用できるようになりました。
|
| 448 |
+
</tf>
|
| 449 |
+
</frameworkcontent>
|
| 450 |
+
|
| 451 |
+
|
| 452 |
+
<Tip>
|
| 453 |
+
|
| 454 |
+
画像分類用のモデルを微調整する方法の詳細な例については、対応する [PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)
|
| 455 |
+
|
| 456 |
+
</Tip>
|
| 457 |
+
|
| 458 |
+
## Inference
|
| 459 |
+
|
| 460 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 461 |
+
|
| 462 |
+
推論を実行したい画像を読み込みます。
|
| 463 |
+
|
| 464 |
+
```py
|
| 465 |
+
>>> ds = load_dataset("food101", split="validation[:10]")
|
| 466 |
+
>>> image = ds["image"][0]
|
| 467 |
+
```
|
| 468 |
+
|
| 469 |
+
<div class="flex justify-center">
|
| 470 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/beignets-task-guide.png" alt="image of beignets"/>
|
| 471 |
+
</div>
|
| 472 |
+
|
| 473 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して画像分類用の`pipeline`をインスタンス化し、それに画像を渡します。
|
| 474 |
+
|
| 475 |
+
```py
|
| 476 |
+
>>> from transformers import pipeline
|
| 477 |
+
|
| 478 |
+
>>> classifier = pipeline("image-classification", model="my_awesome_food_model")
|
| 479 |
+
>>> classifier(image)
|
| 480 |
+
[{'score': 0.31856709718704224, 'label': 'beignets'},
|
| 481 |
+
{'score': 0.015232225880026817, 'label': 'bruschetta'},
|
| 482 |
+
{'score': 0.01519392803311348, 'label': 'chicken_wings'},
|
| 483 |
+
{'score': 0.013022331520915031, 'label': 'pork_chop'},
|
| 484 |
+
{'score': 0.012728818692266941, 'label': 'prime_rib'}]
|
| 485 |
+
```
|
| 486 |
+
|
| 487 |
+
必要に応じて、`pipeline`の結果を手動で複製することもできます。
|
| 488 |
+
|
| 489 |
+
<frameworkcontent>
|
| 490 |
+
<pt>
|
| 491 |
+
|
| 492 |
+
画像プロセッサをロードして画像を前処理し、`input`を PyTorch テンソルとして返します。
|
| 493 |
+
|
| 494 |
+
```py
|
| 495 |
+
>>> from transformers import AutoImageProcessor
|
| 496 |
+
>>> import torch
|
| 497 |
+
|
| 498 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("my_awesome_food_model")
|
| 499 |
+
>>> inputs = image_processor(image, return_tensors="pt")
|
| 500 |
+
```
|
| 501 |
+
|
| 502 |
+
入力をモデルに渡し、ロジットを返します。
|
| 503 |
+
|
| 504 |
+
```py
|
| 505 |
+
>>> from transformers import AutoModelForImageClassification
|
| 506 |
+
|
| 507 |
+
>>> model = AutoModelForImageClassification.from_pretrained("my_awesome_food_model")
|
| 508 |
+
>>> with torch.no_grad():
|
| 509 |
+
... logits = model(**inputs).logits
|
| 510 |
+
```
|
| 511 |
+
|
| 512 |
+
最も高い確率で予測されたラベルを取得し、モデルの `id2label` マッピングを使用してラベルに変換します。
|
| 513 |
+
|
| 514 |
+
```py
|
| 515 |
+
>>> predicted_label = logits.argmax(-1).item()
|
| 516 |
+
>>> model.config.id2label[predicted_label]
|
| 517 |
+
'beignets'
|
| 518 |
+
```
|
| 519 |
+
</pt>
|
| 520 |
+
</frameworkcontent>
|
| 521 |
+
|
| 522 |
+
<frameworkcontent>
|
| 523 |
+
<tf>
|
| 524 |
+
|
| 525 |
+
画像プロセッサをロードして画像を前処理し、`input`を TensorFlow テンソルとして返します。
|
| 526 |
+
|
| 527 |
+
```py
|
| 528 |
+
>>> from transformers import AutoImageProcessor
|
| 529 |
+
|
| 530 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/food_classifier")
|
| 531 |
+
>>> inputs = image_processor(image, return_tensors="tf")
|
| 532 |
+
```
|
| 533 |
+
|
| 534 |
+
入力をモデルに渡し、ロジットを返します。
|
| 535 |
+
|
| 536 |
+
```py
|
| 537 |
+
>>> from transformers import TFAutoModelForImageClassification
|
| 538 |
+
|
| 539 |
+
>>> model = TFAutoModelForImageClassification.from_pretrained("MariaK/food_classifier")
|
| 540 |
+
>>> logits = model(**inputs).logits
|
| 541 |
+
```
|
| 542 |
+
|
| 543 |
+
最も高い確率で予測されたラベルを取得し、モデルの `id2label` マッピングを使用してラベルに変換します。
|
| 544 |
+
|
| 545 |
+
|
| 546 |
+
```py
|
| 547 |
+
>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
|
| 548 |
+
>>> model.config.id2label[predicted_class_id]
|
| 549 |
+
'beignets'
|
| 550 |
+
```
|
| 551 |
+
|
| 552 |
+
</tf>
|
| 553 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_to_image.md
ADDED
|
@@ -0,0 +1,135 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Image-to-Image Task Guide
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
Image-to-Image タスクは、アプリケーションが画像を受信し、別の画像を出力するタスクです。これには、画像強化 (超解像度、低光量強化、ディレインなど)、画像修復などを含むさまざまなサブタスクがあります。
|
| 22 |
+
|
| 23 |
+
このガイドでは、次の方法を説明します。
|
| 24 |
+
- 超解像度タスクに画像間のパイプラインを使用します。
|
| 25 |
+
- パイプラインを使用せずに、同じタスクに対してイメージ間モデルを実行します。
|
| 26 |
+
|
| 27 |
+
このガイドがリリースされた時点では、`image-to-image`パイプラインは超解像度タスクのみをサポートしていることに注意してください。
|
| 28 |
+
|
| 29 |
+
必要なライブラリをインストールすることから始めましょう。
|
| 30 |
+
|
| 31 |
+
```bash
|
| 32 |
+
pip install transformers
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
[Swin2SR モデル](https://huggingface.co/caidas/swin2SR-lightweight-x2-64) を使用してパイプラインを初期化できるようになりました。次に、イメージを使用してパイプラインを呼び出すことで、パイプラインを推論できます。現時点では、[Swin2SR モデル](https://huggingface.co/models?sort=trending&search=swin2sr) のみがこのパイプラインでサポートされています。
|
| 36 |
+
|
| 37 |
+
```python
|
| 38 |
+
from transformers import pipeline
|
| 39 |
+
|
| 40 |
+
device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
|
| 41 |
+
pipe = pipeline(task="image-to-image", model="caidas/swin2SR-lightweight-x2-64", device=device)
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
では、画像を読み込みましょう。
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
from PIL import Image
|
| 48 |
+
import requests
|
| 49 |
+
|
| 50 |
+
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat.jpg"
|
| 51 |
+
image = Image.open(requests.get(url, stream=True).raw)
|
| 52 |
+
|
| 53 |
+
print(image.size)
|
| 54 |
+
```
|
| 55 |
+
```bash
|
| 56 |
+
# (532, 432)
|
| 57 |
+
```
|
| 58 |
+
<div class="flex justify-center">
|
| 59 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat.jpg" alt="Photo of a cat"/>
|
| 60 |
+
</div>
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
これで、パイプラインを使用して推論を実行できるようになりました。猫の画像の拡大バージョンを取得します。
|
| 64 |
+
|
| 65 |
+
```python
|
| 66 |
+
upscaled = pipe(image)
|
| 67 |
+
print(upscaled.size)
|
| 68 |
+
```
|
| 69 |
+
```bash
|
| 70 |
+
# (1072, 880)
|
| 71 |
+
```
|
| 72 |
+
|
| 73 |
+
パイプラインを使用せずに自分で推論を実行したい場合は、トランスフォーマーの `Swin2SRForImageSuperResolution` クラスと `Swin2SRImageProcessor` クラスを使用できます。これには同じモデルのチェックポイントを使用します。モデルとプロセッサを初期化しましょう。
|
| 74 |
+
|
| 75 |
+
```python
|
| 76 |
+
from transformers import Swin2SRForImageSuperResolution, Swin2SRImageProcessor
|
| 77 |
+
|
| 78 |
+
model = Swin2SRForImageSuperResolution.from_pretrained("caidas/swin2SR-lightweight-x2-64").to(device)
|
| 79 |
+
processor = Swin2SRImageProcessor("caidas/swin2SR-lightweight-x2-64")
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
`pipeline`」は、自分で行う必要がある前処理と後処理のステップを抽象化するので、画像を前処理しましょう。画像をプロセッサに渡してから、ピクセル値を GPU に移動します。
|
| 83 |
+
|
| 84 |
+
```python
|
| 85 |
+
pixel_values = processor(image, return_tensors="pt").pixel_values
|
| 86 |
+
print(pixel_values.shape)
|
| 87 |
+
|
| 88 |
+
pixel_values = pixel_values.to(device)
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
これで、ピクセル値をモデルに渡すことで画像を推測できるようになりました。
|
| 92 |
+
|
| 93 |
+
```python
|
| 94 |
+
import torch
|
| 95 |
+
|
| 96 |
+
with torch.no_grad():
|
| 97 |
+
outputs = model(pixel_values)
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
出力は、以下のような `ImageSuperResolutionOutput` タイプのオブジェクトです 👇
|
| 101 |
+
|
| 102 |
+
```
|
| 103 |
+
(loss=None, reconstruction=tensor([[[[0.8270, 0.8269, 0.8275, ..., 0.7463, 0.7446, 0.7453],
|
| 104 |
+
[0.8287, 0.8278, 0.8283, ..., 0.7451, 0.7448, 0.7457],
|
| 105 |
+
[0.8280, 0.8273, 0.8269, ..., 0.7447, 0.7446, 0.7452],
|
| 106 |
+
...,
|
| 107 |
+
[0.5923, 0.5933, 0.5924, ..., 0.0697, 0.0695, 0.0706],
|
| 108 |
+
[0.5926, 0.5932, 0.5926, ..., 0.0673, 0.0687, 0.0705],
|
| 109 |
+
[0.5927, 0.5914, 0.5922, ..., 0.0664, 0.0694, 0.0718]]]],
|
| 110 |
+
device='cuda:0'), hidden_states=None, attentions=None)
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
`reconstruction`を取得し、それを視覚化するために後処理する必要があります。どのように見えるか見てみましょう。
|
| 114 |
+
|
| 115 |
+
```python
|
| 116 |
+
outputs.reconstruction.data.shape
|
| 117 |
+
# torch.Size([1, 3, 880, 1072])
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
出力を圧縮して軸 0 を削除し、値をクリップしてから、それを numpy float に変換する必要があります。次に、軸を [1072, 880] の形状になるように配置し、最後に出力を範囲 [0, 255] に戻します。
|
| 121 |
+
|
| 122 |
+
```python
|
| 123 |
+
import numpy as np
|
| 124 |
+
|
| 125 |
+
# squeeze, take to CPU and clip the values
|
| 126 |
+
output = outputs.reconstruction.data.squeeze().cpu().clamp_(0, 1).numpy()
|
| 127 |
+
# rearrange the axes
|
| 128 |
+
output = np.moveaxis(output, source=0, destination=-1)
|
| 129 |
+
# bring values back to pixel values range
|
| 130 |
+
output = (output * 255.0).round().astype(np.uint8)
|
| 131 |
+
Image.fromarray(output)
|
| 132 |
+
```
|
| 133 |
+
<div class="flex justify-center">
|
| 134 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat_upscaled.png" alt="Upscaled photo of a cat"/>
|
| 135 |
+
</div>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/knowledge_distillation_for_image_classification.md
ADDED
|
@@ -0,0 +1,188 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
# Knowledge Distillation for Computer Vision
|
| 17 |
+
|
| 18 |
+
[[open-in-colab]]
|
| 19 |
+
|
| 20 |
+
知識の蒸留は、より大規模で複雑なモデル (教師) からより小規模で単純なモデル (生徒) に知識を伝達するために使用される手法です。あるモデルから別のモデルに知識を抽出するには、特定のタスク (この場合は画像分類) でトレーニングされた事前トレーニング済み教師モデルを取得し、画像分類でトレーニングされる生徒モデルをランダムに初期化します。次に、学生モデルをトレーニングして、その出力と教師の出力の差を最小限に抑え、動作を模倣します。これは [Distilling the Knowledge in a Neural Network by Hinton et al](https://arxiv.org/abs/1503.02531) で最初に導入されました。このガイドでは、タスク固有の知識の蒸留を行います。これには [Beans データセット](https://huggingface.co/datasets/beans) を使用します。
|
| 21 |
+
|
| 22 |
+
このガイドでは、[微調整された ViT モデル](https://huggingface.co/merve/vit-mobilenet-beans-224) (教師モデル) を抽出して [MobileNet](https://huggingface.co/google/mobilenet_v2_1.4_224) (学生モデル) 🤗 Transformers の [Trainer API](https://huggingface.co/docs/transformers/en/main_classes/trainer#trainer) を使用します。
|
| 23 |
+
|
| 24 |
+
蒸留とプロセスの評価に必要なライブラリをインストールしましょう。
|
| 25 |
+
|
| 26 |
+
```bash
|
| 27 |
+
pip install transformers datasets accelerate tensorboard evaluate --upgrade
|
| 28 |
+
```
|
| 29 |
+
|
| 30 |
+
この例では、教師モデルとして`merve/beans-vit-224`モデルを使用しています。これは、Bean データセットに基づいて微調整された`google/vit-base-patch16-224-in21k`に基づく画像分類モデルです。このモデルをランダムに初期化された MobileNetV2 に抽出します。
|
| 31 |
+
|
| 32 |
+
次に、データセットをロードします。
|
| 33 |
+
|
| 34 |
+
```python
|
| 35 |
+
from datasets import load_dataset
|
| 36 |
+
|
| 37 |
+
dataset = load_dataset("beans")
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
この場合、同じ解像度で同じ出力が返されるため、どちらのモデルの画像プロセッサも使用できます。 `dataset`の`map()`メソッドを使用して、データセットのすべての分割に前処理を適用します。
|
| 41 |
+
|
| 42 |
+
```python
|
| 43 |
+
from transformers import AutoImageProcessor
|
| 44 |
+
teacher_processor = AutoImageProcessor.from_pretrained("merve/beans-vit-224")
|
| 45 |
+
|
| 46 |
+
def process(examples):
|
| 47 |
+
processed_inputs = teacher_processor(examples["image"])
|
| 48 |
+
return processed_inputs
|
| 49 |
+
|
| 50 |
+
processed_datasets = dataset.map(process, batched=True)
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
基本的に、我々は生徒モデル(ランダムに初期化されたMobileNet)が教師モデル(微調整されたビジョン変換器)を模倣することを望む。これを実現するために、まず教師と生徒からロジット出力を得る。次に、それぞれのソフトターゲットの重要度を制御するパラメータ`temperature`で分割する。`lambda`と呼ばれるパラメータは蒸留ロスの重要度を量る。この例では、`temperature=5`、`lambda=0.5`とする。生徒と教師の間の発散を計算するために、Kullback-Leibler発散損失を使用します。2つのデータPとQが与えられたとき、KLダイバージェンスはQを使ってPを表現するためにどれだけの余分な情報が必要かを説明します。もし2つが同じであれば、QからPを説明するために必要な他の情報はないので、それらのKLダイバージェンスはゼロになります。
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
```python
|
| 57 |
+
from transformers import TrainingArguments, Trainer
|
| 58 |
+
import torch
|
| 59 |
+
import torch.nn as nn
|
| 60 |
+
import torch.nn.functional as F
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
class ImageDistilTrainer(Trainer):
|
| 64 |
+
def __init__(self, *args, teacher_model=None, **kwargs):
|
| 65 |
+
super().__init__(*args, **kwargs)
|
| 66 |
+
self.teacher = teacher_model
|
| 67 |
+
self.student = student_model
|
| 68 |
+
self.loss_function = nn.KLDivLoss(reduction="batchmean")
|
| 69 |
+
device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
|
| 70 |
+
self.teacher.to(device)
|
| 71 |
+
self.teacher.eval()
|
| 72 |
+
self.temperature = temperature
|
| 73 |
+
self.lambda_param = lambda_param
|
| 74 |
+
|
| 75 |
+
def compute_loss(self, student, inputs, return_outputs=False):
|
| 76 |
+
student_output = self.student(**inputs)
|
| 77 |
+
|
| 78 |
+
with torch.no_grad():
|
| 79 |
+
teacher_output = self.teacher(**inputs)
|
| 80 |
+
|
| 81 |
+
# Compute soft targets for teacher and student
|
| 82 |
+
soft_teacher = F.softmax(teacher_output.logits / self.temperature, dim=-1)
|
| 83 |
+
soft_student = F.log_softmax(student_output.logits / self.temperature, dim=-1)
|
| 84 |
+
|
| 85 |
+
# Compute the loss
|
| 86 |
+
distillation_loss = self.loss_function(soft_student, soft_teacher) * (self.temperature ** 2)
|
| 87 |
+
|
| 88 |
+
# Compute the true label loss
|
| 89 |
+
student_target_loss = student_output.loss
|
| 90 |
+
|
| 91 |
+
# Calculate final loss
|
| 92 |
+
loss = (1. - self.lambda_param) * student_target_loss + self.lambda_param * distillation_loss
|
| 93 |
+
return (loss, student_output) if return_outputs else loss
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
次に、Hugging Face Hub にログインして、`trainer`を通じてモデルを Hugging Face Hub にプッシュできるようにします。
|
| 97 |
+
|
| 98 |
+
```python
|
| 99 |
+
from huggingface_hub import notebook_login
|
| 100 |
+
|
| 101 |
+
notebook_login()
|
| 102 |
+
```
|
| 103 |
+
|
| 104 |
+
教師モデルと生徒モデルである`TrainingArguments`を設定しましょう。
|
| 105 |
+
|
| 106 |
+
```python
|
| 107 |
+
from transformers import AutoModelForImageClassification, MobileNetV2Config, MobileNetV2ForImageClassification
|
| 108 |
+
|
| 109 |
+
training_args = TrainingArguments(
|
| 110 |
+
output_dir="my-awesome-model",
|
| 111 |
+
num_train_epochs=30,
|
| 112 |
+
fp16=True,
|
| 113 |
+
logging_dir=f"{repo_name}/logs",
|
| 114 |
+
logging_strategy="epoch",
|
| 115 |
+
eval_strategy="epoch",
|
| 116 |
+
save_strategy="epoch",
|
| 117 |
+
load_best_model_at_end=True,
|
| 118 |
+
metric_for_best_model="accuracy",
|
| 119 |
+
report_to="tensorboard",
|
| 120 |
+
push_to_hub=True,
|
| 121 |
+
hub_strategy="every_save",
|
| 122 |
+
hub_model_id=repo_name,
|
| 123 |
+
)
|
| 124 |
+
|
| 125 |
+
num_labels = len(processed_datasets["train"].features["labels"].names)
|
| 126 |
+
|
| 127 |
+
# initialize models
|
| 128 |
+
teacher_model = AutoModelForImageClassification.from_pretrained(
|
| 129 |
+
"merve/beans-vit-224",
|
| 130 |
+
num_labels=num_labels,
|
| 131 |
+
ignore_mismatched_sizes=True
|
| 132 |
+
)
|
| 133 |
+
|
| 134 |
+
# training MobileNetV2 from scratch
|
| 135 |
+
student_config = MobileNetV2Config()
|
| 136 |
+
student_config.num_labels = num_labels
|
| 137 |
+
student_model = MobileNetV2ForImageClassification(student_config)
|
| 138 |
+
```
|
| 139 |
+
|
| 140 |
+
`compute_metrics` 関数を使用して、テスト セットでモデルを評価できます。この関数は、トレーニング プロセス中にモデルの`accuracy`と`f1`を計算するために使用されます。
|
| 141 |
+
|
| 142 |
+
```python
|
| 143 |
+
import evaluate
|
| 144 |
+
import numpy as np
|
| 145 |
+
|
| 146 |
+
accuracy = evaluate.load("accuracy")
|
| 147 |
+
|
| 148 |
+
def compute_metrics(eval_pred):
|
| 149 |
+
predictions, labels = eval_pred
|
| 150 |
+
acc = accuracy.compute(references=labels, predictions=np.argmax(predictions, axis=1))
|
| 151 |
+
return {"accuracy": acc["accuracy"]}
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
定義したトレーニング引数を使用して`Trainer`を初期化しましょう。データ照合装置も初期化します。
|
| 155 |
+
|
| 156 |
+
|
| 157 |
+
```python
|
| 158 |
+
from transformers import DefaultDataCollator
|
| 159 |
+
|
| 160 |
+
data_collator = DefaultDataCollator()
|
| 161 |
+
trainer = ImageDistilTrainer(
|
| 162 |
+
student_model=student_model,
|
| 163 |
+
teacher_model=teacher_model,
|
| 164 |
+
training_args=training_args,
|
| 165 |
+
train_dataset=processed_datasets["train"],
|
| 166 |
+
eval_dataset=processed_datasets["validation"],
|
| 167 |
+
data_collator=data_collator,
|
| 168 |
+
processing_class=teacher_extractor,
|
| 169 |
+
compute_metrics=compute_metrics,
|
| 170 |
+
temperature=5,
|
| 171 |
+
lambda_param=0.5
|
| 172 |
+
)
|
| 173 |
+
```
|
| 174 |
+
|
| 175 |
+
これでモデルをトレーニングできるようになりました。
|
| 176 |
+
|
| 177 |
+
```python
|
| 178 |
+
trainer.train()
|
| 179 |
+
```
|
| 180 |
+
|
| 181 |
+
テスト セットでモデルを評価できます。
|
| 182 |
+
|
| 183 |
+
|
| 184 |
+
```python
|
| 185 |
+
trainer.evaluate(processed_datasets["test"])
|
| 186 |
+
```
|
| 187 |
+
|
| 188 |
+
テスト セットでは、モデルの精度は 72% に達します。蒸留効率の健全性チェックを行うために、同じハイパーパラメータを使用して Bean データセットで MobileNet を最初からトレーニングし、テスト セットで 63% の精度を観察しました。読者の皆様には、さまざまな事前トレーニング済み教師モデル、学生アーキテクチャ、蒸留パラメータを試していただき、その結果を報告していただくようお勧めします。抽出されたモデルのトレーニング ログとチェックポイントは [このリポジトリ](https://huggingface.co/merve/vit-mobilenet-beans-224) にあり、最初からトレーニングされた MobileNetV2 はこの [リポジトリ](https://huggingface.co/merve/resnet-mobilenet-beans-5)。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/language_modeling.md
ADDED
|
@@ -0,0 +1,437 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Causal language modeling
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
[[open-in-colab]]
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
言語モデリングには、因果的モデリングとマスクされた言語モデリングの 2 つのタイプがあります。このガイドでは、因果関係のある言語モデリングについて説明します。
|
| 24 |
+
因果言語モデルはテキスト生成によく使用されます。これらのモデルは、次のようなクリエイティブなアプリケーションに使用できます。
|
| 25 |
+
独自のテキスト アドベンチャーを選択するか、Copilot や CodeParrot などのインテリジェントなコーディング アシスタントを選択します。
|
| 26 |
+
|
| 27 |
+
<Youtube id="Vpjb1lu0MDk"/>
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
因果言語モデリングは、一連のトークン内の次のトークンを予測します。モデルは、次のトークンにのみ対応できます。
|
| 31 |
+
左。これは、モデルが将来のトークンを認識できないことを意味します。 GPT-2 は因果的言語モデルの一例です。
|
| 32 |
+
|
| 33 |
+
このガイドでは、次の方法を説明します。
|
| 34 |
+
|
| 35 |
+
1. [ELI5](https:/) の [r/askscience](https://www.reddit.com/r/askscience/) サブセットで [DistilGPT2](https://huggingface.co/distilbert/distilgpt2) を微調整します。 /huggingface.co/datasets/eli5) データセット。
|
| 36 |
+
2. 微調整したモデルを推論に使用します。
|
| 37 |
+
|
| 38 |
+
<Tip>
|
| 39 |
+
|
| 40 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/text-generation) を確認することをお勧めします。u
|
| 41 |
+
|
| 42 |
+
</Tip>
|
| 43 |
+
|
| 44 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 45 |
+
|
| 46 |
+
```bash
|
| 47 |
+
pip install transformers datasets evaluate
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 51 |
+
|
| 52 |
+
```py
|
| 53 |
+
>>> from huggingface_hub import notebook_login
|
| 54 |
+
|
| 55 |
+
>>> notebook_login()
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
## Load ELI5 dataset
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
まず、ELI5 データセットの r/askscience サブセットの小さいサブセットを 🤗 データセット ライブラリからロードします。
|
| 62 |
+
これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
|
| 63 |
+
|
| 64 |
+
```py
|
| 65 |
+
>>> from datasets import load_dataset
|
| 66 |
+
|
| 67 |
+
>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
|
| 68 |
+
```
|
| 69 |
+
|
| 70 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train_asks` をトレイン セットとテスト セットに分割します。
|
| 71 |
+
|
| 72 |
+
```py
|
| 73 |
+
>>> eli5 = eli5.train_test_split(test_size=0.2)
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
次に、例を見てみましょう。
|
| 77 |
+
|
| 78 |
+
```py
|
| 79 |
+
>>> eli5["train"][0]
|
| 80 |
+
{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
|
| 81 |
+
'score': [6, 3],
|
| 82 |
+
'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
|
| 83 |
+
"Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
|
| 84 |
+
'answers_urls': {'url': []},
|
| 85 |
+
'document': '',
|
| 86 |
+
'q_id': 'nyxfp',
|
| 87 |
+
'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
|
| 88 |
+
'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
|
| 89 |
+
'subreddit': 'askscience',
|
| 90 |
+
'title': 'Few questions about this space walk photograph.',
|
| 91 |
+
'title_urls': {'url': []}}
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
これは多くのことのように見えるかもしれませんが、実際に関心があるのは`text`フィールドだけです。言語モデリングの優れている点
|
| 95 |
+
タスクでは、次の単語がラベル * であるため、ラベル (教師なしタスクとも呼ばれます) は必要ありません。
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
## Preprocess
|
| 99 |
+
|
| 100 |
+
<Youtube id="ma1TrR7gE7I"/>
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
次のステップは、`text`サブフィールドを処理するために DistilGPT2 トークナイザーをロードすることです。
|
| 104 |
+
|
| 105 |
+
```py
|
| 106 |
+
>>> from transformers import AutoTokenizer
|
| 107 |
+
|
| 108 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
|
| 109 |
+
```
|
| 110 |
+
|
| 111 |
+
上の例からわかるように、`text`フィールドは実際には`answers`内にネストされています。つまり、次のことが必要になります。
|
| 112 |
+
[` flatten`](https://huggingface.co/docs/datasets/process.html#flatten) メソッドを使用して、ネストされた構造から `text` サブフィールドを抽出します。
|
| 113 |
+
|
| 114 |
+
```py
|
| 115 |
+
>>> eli5 = eli5.flatten()
|
| 116 |
+
>>> eli5["train"][0]
|
| 117 |
+
{'answers.a_id': ['c3d1aib', 'c3d4lya'],
|
| 118 |
+
'answers.score': [6, 3],
|
| 119 |
+
'answers.text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
|
| 120 |
+
"Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"],
|
| 121 |
+
'answers_urls.url': [],
|
| 122 |
+
'document': '',
|
| 123 |
+
'q_id': 'nyxfp',
|
| 124 |
+
'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
|
| 125 |
+
'selftext_urls.url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg'],
|
| 126 |
+
'subreddit': 'askscience',
|
| 127 |
+
'title': 'Few questions about this space walk photograph.',
|
| 128 |
+
'title_urls.url': []}
|
| 129 |
+
```
|
| 130 |
+
|
| 131 |
+
`answers`接頭辞で示されるように、各サブフィールドは個別の列になり、`text`フィールドはリストになりました。その代わり
|
| 132 |
+
各文を個別にトークン化する場合は、リストを文字列に変換して、それらをまとめてトークン化できるようにします。
|
| 133 |
+
|
| 134 |
+
以下は、各例の文字列のリストを結合し、結果をトークン化する最初の前処理関数です。
|
| 135 |
+
|
| 136 |
+
```py
|
| 137 |
+
>>> def preprocess_function(examples):
|
| 138 |
+
... return tokenizer([" ".join(x) for x in examples["answers.text"]])
|
| 139 |
+
```
|
| 140 |
+
|
| 141 |
+
この前処理関数をデータセット全体に適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `map` 関数を高速化するには、`batched=True` を設定してデータセットの複数の要素を一度に処理し、`num_proc` でプロセスの数を増やします。不要な列を削除します。
|
| 142 |
+
|
| 143 |
+
```py
|
| 144 |
+
>>> tokenized_eli5 = eli5.map(
|
| 145 |
+
... preprocess_function,
|
| 146 |
+
... batched=True,
|
| 147 |
+
... num_proc=4,
|
| 148 |
+
... remove_columns=eli5["train"].column_names,
|
| 149 |
+
... )
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
このデータセットにはトークン シーケンスが含まれていますが、その一部はモデルの最大入力長よりも長くなります。
|
| 153 |
+
|
| 154 |
+
2 番目の前処理関数を使用して、
|
| 155 |
+
- すべてのシーケンスを連結します
|
| 156 |
+
- 連結されたシーケンスを`block_size`で定義された短いチャンクに分割します。これは、最大入力長より短く、GPU RAM に十分な長さである必要があります。
|
| 157 |
+
|
| 158 |
+
```py
|
| 159 |
+
>>> block_size = 128
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
>>> def group_texts(examples):
|
| 163 |
+
... # Concatenate all texts.
|
| 164 |
+
... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
| 165 |
+
... total_length = len(concatenated_examples[list(examples.keys())[0]])
|
| 166 |
+
... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
| 167 |
+
... # customize this part to your needs.
|
| 168 |
+
... if total_length >= block_size:
|
| 169 |
+
... total_length = (total_length // block_size) * block_size
|
| 170 |
+
... # Split by chunks of block_size.
|
| 171 |
+
... result = {
|
| 172 |
+
... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
| 173 |
+
... for k, t in concatenated_examples.items()
|
| 174 |
+
... }
|
| 175 |
+
... result["labels"] = result["input_ids"].copy()
|
| 176 |
+
... return result
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
Apply the `group_texts` function over the entire dataset:
|
| 180 |
+
|
| 181 |
+
```py
|
| 182 |
+
>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
|
| 183 |
+
```
|
| 184 |
+
|
| 185 |
+
次に、[`DataCollatorForLanguageModeling`] を使用してサンプルのバッチを作成します。 *動的にパディング*する方が効率的です。
|
| 186 |
+
データセット全体を最大長までパディングするのではなく、照合中にバッチ内の文を最長の長さにします。
|
| 187 |
+
|
| 188 |
+
<frameworkcontent>
|
| 189 |
+
<pt>
|
| 190 |
+
|
| 191 |
+
シーケンス終了トークンをパディング トークンとして使用し、`mlm=False` を設定します。これは、入力を 1 要素分右にシフトしたラベルとして使用します。
|
| 192 |
+
|
| 193 |
+
```py
|
| 194 |
+
>>> from transformers import DataCollatorForLanguageModeling
|
| 195 |
+
|
| 196 |
+
>>> tokenizer.pad_token = tokenizer.eos_token
|
| 197 |
+
>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
|
| 198 |
+
```
|
| 199 |
+
|
| 200 |
+
</pt>
|
| 201 |
+
<tf>
|
| 202 |
+
シーケンス終了トークンをパディング トークンとして使用し、`mlm=False` を設定します。これは、入力を 1 要素分右にシフトしたラベルとして使用します。
|
| 203 |
+
|
| 204 |
+
```py
|
| 205 |
+
>>> from transformers import DataCollatorForLanguageModeling
|
| 206 |
+
|
| 207 |
+
>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
|
| 208 |
+
```
|
| 209 |
+
|
| 210 |
+
</tf>
|
| 211 |
+
</frameworkcontent>
|
| 212 |
+
|
| 213 |
+
|
| 214 |
+
## Train
|
| 215 |
+
|
| 216 |
+
<frameworkcontent>
|
| 217 |
+
<pt>
|
| 218 |
+
<Tip>
|
| 219 |
+
|
| 220 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[基本チュートリアル](../training#train-with-pytorch-trainer) を参照してください。
|
| 221 |
+
|
| 222 |
+
</Tip>
|
| 223 |
+
|
| 224 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForCausalLM`] を使用して DistilGPT2 をロードします。
|
| 225 |
+
|
| 226 |
+
|
| 227 |
+
```py
|
| 228 |
+
>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
|
| 229 |
+
|
| 230 |
+
>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
|
| 231 |
+
```
|
| 232 |
+
|
| 233 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 234 |
+
|
| 235 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
|
| 236 |
+
2. トレーニング引数をモデル、データセット、データ照合器とともに [`Trainer`] に渡します。
|
| 237 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 238 |
+
|
| 239 |
+
```py
|
| 240 |
+
>>> training_args = TrainingArguments(
|
| 241 |
+
... output_dir="my_awesome_eli5_clm-model",
|
| 242 |
+
... eval_strategy="epoch",
|
| 243 |
+
... learning_rate=2e-5,
|
| 244 |
+
... weight_decay=0.01,
|
| 245 |
+
... push_to_hub=True,
|
| 246 |
+
... )
|
| 247 |
+
|
| 248 |
+
>>> trainer = Trainer(
|
| 249 |
+
... model=model,
|
| 250 |
+
... args=training_args,
|
| 251 |
+
... train_dataset=lm_dataset["train"],
|
| 252 |
+
... eval_dataset=lm_dataset["test"],
|
| 253 |
+
... data_collator=data_collator,
|
| 254 |
+
... )
|
| 255 |
+
|
| 256 |
+
>>> trainer.train()
|
| 257 |
+
```
|
| 258 |
+
|
| 259 |
+
トレーニングが完了したら、 [`~transformers.Trainer.evaluate`] メソッドを使用してモデルを評価し、その複雑さを取得します。
|
| 260 |
+
|
| 261 |
+
```py
|
| 262 |
+
>>> import math
|
| 263 |
+
|
| 264 |
+
>>> eval_results = trainer.evaluate()
|
| 265 |
+
>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
|
| 266 |
+
Perplexity: 49.61
|
| 267 |
+
```
|
| 268 |
+
|
| 269 |
+
次に、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 270 |
+
|
| 271 |
+
```py
|
| 272 |
+
>>> trainer.push_to_hub()
|
| 273 |
+
```
|
| 274 |
+
</pt>
|
| 275 |
+
<tf>
|
| 276 |
+
<Tip>
|
| 277 |
+
|
| 278 |
+
Keras を使用したモデルの微調整に慣れていない場合は、[基本チュートリアル](../training#train-a-tensorflow-model-with-keras) をご覧ください。
|
| 279 |
+
|
| 280 |
+
</Tip>
|
| 281 |
+
TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
|
| 282 |
+
|
| 283 |
+
```py
|
| 284 |
+
>>> from transformers import create_optimizer, AdamWeightDecay
|
| 285 |
+
|
| 286 |
+
>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
|
| 287 |
+
```
|
| 288 |
+
|
| 289 |
+
次に、[`TFAutoModelForCausalLM`] を使用して DistilGPT2 をロードできます。
|
| 290 |
+
|
| 291 |
+
```py
|
| 292 |
+
>>> from transformers import TFAutoModelForCausalLM
|
| 293 |
+
|
| 294 |
+
>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
|
| 295 |
+
```
|
| 296 |
+
|
| 297 |
+
[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 298 |
+
|
| 299 |
+
```py
|
| 300 |
+
>>> tf_train_set = model.prepare_tf_dataset(
|
| 301 |
+
... lm_dataset["train"],
|
| 302 |
+
... shuffle=True,
|
| 303 |
+
... batch_size=16,
|
| 304 |
+
... collate_fn=data_collator,
|
| 305 |
+
... )
|
| 306 |
+
|
| 307 |
+
>>> tf_test_set = model.prepare_tf_dataset(
|
| 308 |
+
... lm_dataset["test"],
|
| 309 |
+
... shuffle=False,
|
| 310 |
+
... batch_size=16,
|
| 311 |
+
... collate_fn=data_collator,
|
| 312 |
+
... )
|
| 313 |
+
```
|
| 314 |
+
|
| 315 |
+
[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
|
| 316 |
+
|
| 317 |
+
```py
|
| 318 |
+
>>> import tensorflow as tf
|
| 319 |
+
|
| 320 |
+
>>> model.compile(optimizer=optimizer) # No loss argument!
|
| 321 |
+
```
|
| 322 |
+
|
| 323 |
+
これは、モデルとトークナイザーを [`~transformers.PushToHubCallback`] でプッシュする場所を指定することで実行できます。
|
| 324 |
+
|
| 325 |
+
|
| 326 |
+
|
| 327 |
+
```py
|
| 328 |
+
>>> from transformers.keras_callbacks import PushToHubCallback
|
| 329 |
+
|
| 330 |
+
>>> callback = PushToHubCallback(
|
| 331 |
+
... output_dir="my_awesome_eli5_clm-model",
|
| 332 |
+
... tokenizer=tokenizer,
|
| 333 |
+
... )
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
|
| 337 |
+
|
| 338 |
+
|
| 339 |
+
|
| 340 |
+
```py
|
| 341 |
+
>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
|
| 342 |
+
```
|
| 343 |
+
|
| 344 |
+
トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
|
| 345 |
+
|
| 346 |
+
</tf>
|
| 347 |
+
</frameworkcontent>
|
| 348 |
+
|
| 349 |
+
<Tip>
|
| 350 |
+
|
| 351 |
+
因果言語モデリング用にモデルを微調整する方法のより詳細な例については、対応するドキュメントを参照してください。
|
| 352 |
+
[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
|
| 353 |
+
または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)。
|
| 354 |
+
|
| 355 |
+
</Tip>
|
| 356 |
+
|
| 357 |
+
## Inference
|
| 358 |
+
|
| 359 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 360 |
+
|
| 361 |
+
テキストを生成するプロンプトを考え出します。
|
| 362 |
+
|
| 363 |
+
```py
|
| 364 |
+
>>> prompt = "Somatic hypermutation allows the immune system to"
|
| 365 |
+
```
|
| 366 |
+
|
| 367 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用してテキスト生成用の`pipeline`をインスタンス化し、それにテキストを渡します。
|
| 368 |
+
|
| 369 |
+
|
| 370 |
+
```py
|
| 371 |
+
>>> from transformers import pipeline
|
| 372 |
+
|
| 373 |
+
>>> generator = pipeline("text-generation", model="my_awesome_eli5_clm-model")
|
| 374 |
+
>>> generator(prompt)
|
| 375 |
+
[{'generated_text': "Somatic hypermutation allows the immune system to be able to effectively reverse the damage caused by an infection.\n\n\nThe damage caused by an infection is caused by the immune system's ability to perform its own self-correcting tasks."}]
|
| 376 |
+
```
|
| 377 |
+
|
| 378 |
+
<frameworkcontent>
|
| 379 |
+
<pt>
|
| 380 |
+
|
| 381 |
+
|
| 382 |
+
テキストをトークン化し、「input_ids」を PyTorch テンソルとして返します。
|
| 383 |
+
|
| 384 |
+
```py
|
| 385 |
+
>>> from transformers import AutoTokenizer
|
| 386 |
+
|
| 387 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
|
| 388 |
+
>>> inputs = tokenizer(prompt, return_tensors="pt").input_ids
|
| 389 |
+
```
|
| 390 |
+
|
| 391 |
+
[`~generation.GenerationMixin.generate`] メソッドを使用してテキストを生成します。
|
| 392 |
+
さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[テキスト生成戦略](../generation_strategies) ページを参照してください。
|
| 393 |
+
|
| 394 |
+
```py
|
| 395 |
+
>>> from transformers import AutoModelForCausalLM
|
| 396 |
+
|
| 397 |
+
>>> model = AutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
|
| 398 |
+
>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
|
| 399 |
+
```
|
| 400 |
+
|
| 401 |
+
生成されたトークン ID をデコードしてテキストに戻します。
|
| 402 |
+
|
| 403 |
+
```py
|
| 404 |
+
>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
|
| 405 |
+
["Somatic hypermutation allows the immune system to react to drugs with the ability to adapt to a different environmental situation. In other words, a system of 'hypermutation' can help the immune system to adapt to a different environmental situation or in some cases even a single life. In contrast, researchers at the University of Massachusetts-Boston have found that 'hypermutation' is much stronger in mice than in humans but can be found in humans, and that it's not completely unknown to the immune system. A study on how the immune system"]
|
| 406 |
+
```
|
| 407 |
+
|
| 408 |
+
</pt>
|
| 409 |
+
<tf>
|
| 410 |
+
|
| 411 |
+
テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。
|
| 412 |
+
|
| 413 |
+
```py
|
| 414 |
+
>>> from transformers import AutoTokenizer
|
| 415 |
+
|
| 416 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
|
| 417 |
+
>>> inputs = tokenizer(prompt, return_tensors="tf").input_ids
|
| 418 |
+
```
|
| 419 |
+
|
| 420 |
+
[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[テキスト生成戦略](../generation_strategies) ページを参照してください。
|
| 421 |
+
|
| 422 |
+
```py
|
| 423 |
+
>>> from transformers import TFAutoModelForCausalLM
|
| 424 |
+
|
| 425 |
+
>>> model = TFAutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
|
| 426 |
+
>>> outputs = model.generate(input_ids=inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
|
| 427 |
+
```
|
| 428 |
+
|
| 429 |
+
生成されたトークン ID をデコードしてテキストに戻します。
|
| 430 |
+
|
| 431 |
+
```py
|
| 432 |
+
>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
|
| 433 |
+
['Somatic hypermutation allows the immune system to detect the presence of other viruses as they become more prevalent. Therefore, researchers have identified a high proportion of human viruses. The proportion of virus-associated viruses in our study increases with age. Therefore, we propose a simple algorithm to detect the presence of these new viruses in our samples as a sign of improved immunity. A first study based on this algorithm, which will be published in Science on Friday, aims to show that this finding could translate into the development of a better vaccine that is more effective for']
|
| 434 |
+
```
|
| 435 |
+
|
| 436 |
+
</tf>
|
| 437 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/masked_language_modeling.md
ADDED
|
@@ -0,0 +1,449 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Masked language modeling
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="mqElG5QJWUg"/>
|
| 22 |
+
|
| 23 |
+
マスクされた言語モデリングはシーケンス内のマスクされたトークンを予測し、モデルはトークンを双方向に処理できます。これ
|
| 24 |
+
これは、モデルが左右のトークンに完全にアクセスできることを意味します。マスクされた言語モデリングは、次のようなタスクに最適です。
|
| 25 |
+
シーケンス全体の文脈をよく理解する必要があります。 BERT はマスクされた言語モデルの一例です。
|
| 26 |
+
|
| 27 |
+
このガイドでは、次の方法を説明します。
|
| 28 |
+
|
| 29 |
+
1. [ELI5](https://huggingface.co/distilbert/distilroberta-base) の [r/askscience](https://www.reddit.com/r/askscience/) サブセットで [DistilRoBERTa](https://huggingface.co/distilbert/distilroberta-base) を微調整します。 ://huggingface.co/datasets/eli5) データセット。
|
| 30 |
+
2. 微調整したモデルを推論に使用します。
|
| 31 |
+
|
| 32 |
+
<Tip>
|
| 33 |
+
|
| 34 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/fill-mask) を確認することをお勧めします。
|
| 35 |
+
|
| 36 |
+
</Tip>
|
| 37 |
+
|
| 38 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 39 |
+
|
| 40 |
+
```bash
|
| 41 |
+
pip install transformers datasets evaluate
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 45 |
+
|
| 46 |
+
```py
|
| 47 |
+
>>> from huggingface_hub import notebook_login
|
| 48 |
+
|
| 49 |
+
>>> notebook_login()
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
## Load ELI5 dataset
|
| 53 |
+
|
| 54 |
+
まず、ELI5 データセットの r/askscience サブセットの小さいサブセットを 🤗 データセット ライブラリからロードします。これで
|
| 55 |
+
データセット全体のトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が与えられます。
|
| 56 |
+
|
| 57 |
+
```py
|
| 58 |
+
>>> from datasets import load_dataset
|
| 59 |
+
|
| 60 |
+
>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train_asks` をトレイン セットとテスト セットに分割します。
|
| 64 |
+
|
| 65 |
+
```py
|
| 66 |
+
>>> eli5 = eli5.train_test_split(test_size=0.2)
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
次に、例を見てみましょう。
|
| 70 |
+
|
| 71 |
+
```py
|
| 72 |
+
>>> eli5["train"][0]
|
| 73 |
+
{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
|
| 74 |
+
'score': [6, 3],
|
| 75 |
+
'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
|
| 76 |
+
"Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
|
| 77 |
+
'answers_urls': {'url': []},
|
| 78 |
+
'document': '',
|
| 79 |
+
'q_id': 'nyxfp',
|
| 80 |
+
'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
|
| 81 |
+
'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
|
| 82 |
+
'subreddit': 'askscience',
|
| 83 |
+
'title': 'Few questions about this space walk photograph.',
|
| 84 |
+
'title_urls': {'url': []}}
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
これは多くのことのように見えるかもしれませんが、実際に関心があるのは`text`フィールドだけです。言語モデリング タスクの優れた点は、次の単語がラベル * であるため、ラベル (教師なしタスクとも���ばれます) が必要ないことです。
|
| 88 |
+
|
| 89 |
+
## Preprocess
|
| 90 |
+
|
| 91 |
+
<Youtube id="8PmhEIXhBvI"/>
|
| 92 |
+
|
| 93 |
+
マスクされた言語モデリングの場合、次のステップは、`text`サブフィールドを処理するために DistilRoBERTa トークナイザーをロードすることです。
|
| 94 |
+
|
| 95 |
+
```py
|
| 96 |
+
>>> from transformers import AutoTokenizer
|
| 97 |
+
|
| 98 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilroberta-base")
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
上の例からわかるように、`text`フィールドは実際には`answers`内にネストされています。これは、次のことを行う必要があることを意味します
|
| 102 |
+
[` flatten`](https://huggingface.co/docs/datasets/process.html#flatten) メソッドを使用して、ネストされた構造から `text` サブフィールドを抽出します。
|
| 103 |
+
|
| 104 |
+
```py
|
| 105 |
+
>>> eli5 = eli5.flatten()
|
| 106 |
+
>>> eli5["train"][0]
|
| 107 |
+
{'answers.a_id': ['c3d1aib', 'c3d4lya'],
|
| 108 |
+
'answers.score': [6, 3],
|
| 109 |
+
'answers.text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
|
| 110 |
+
"Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"],
|
| 111 |
+
'answers_urls.url': [],
|
| 112 |
+
'document': '',
|
| 113 |
+
'q_id': 'nyxfp',
|
| 114 |
+
'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
|
| 115 |
+
'selftext_urls.url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg'],
|
| 116 |
+
'subreddit': 'askscience',
|
| 117 |
+
'title': 'Few questions about this space walk photograph.',
|
| 118 |
+
'title_urls.url': []}
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
`answers`接頭辞で示されるように、各サブフィールドは個別の列になり、`text`フィールドはリストになりました。その代わり
|
| 122 |
+
各文を個別にトークン化する場合は、リストを文字列に変換して、それらをまとめてトークン化できるようにします。
|
| 123 |
+
|
| 124 |
+
以下は、各例の文字列のリストを結合し、結果をトークン化する最初の前処理関数です。
|
| 125 |
+
|
| 126 |
+
```py
|
| 127 |
+
>>> def preprocess_function(examples):
|
| 128 |
+
... return tokenizer([" ".join(x) for x in examples["answers.text"]])
|
| 129 |
+
```
|
| 130 |
+
|
| 131 |
+
この前処理関数をデータセット全体に適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `map` 関数を高速化するには、`batched=True` を設定してデータセットの複数の要素を一度に処理し、`num_proc` でプロセスの数を増やします。不要な列を削除します。
|
| 132 |
+
|
| 133 |
+
```py
|
| 134 |
+
>>> tokenized_eli5 = eli5.map(
|
| 135 |
+
... preprocess_function,
|
| 136 |
+
... batched=True,
|
| 137 |
+
... num_proc=4,
|
| 138 |
+
... remove_columns=eli5["train"].column_names,
|
| 139 |
+
... )
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
このデータセットにはトークン シーケンスが含まれていますが、その一部はモデルの最大入力長よりも長くなります。
|
| 143 |
+
|
| 144 |
+
2 番目の前処理関数を使用して、
|
| 145 |
+
- すべてのシーケンスを連結します
|
| 146 |
+
- 連結されたシーケンスを`block_size`で定義された短いチャンクに分割します。これは、最大入力長より短く、GPU RAM に十分な長さである必要があります。
|
| 147 |
+
|
| 148 |
+
```py
|
| 149 |
+
>>> block_size = 128
|
| 150 |
+
|
| 151 |
+
|
| 152 |
+
>>> def group_texts(examples):
|
| 153 |
+
... # Concatenate all texts.
|
| 154 |
+
... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
| 155 |
+
... total_length = len(concatenated_examples[list(examples.keys())[0]])
|
| 156 |
+
... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
| 157 |
+
... # customize this part to your needs.
|
| 158 |
+
... if total_length >= block_size:
|
| 159 |
+
... total_length = (total_length // block_size) * block_size
|
| 160 |
+
... # Split by chunks of block_size.
|
| 161 |
+
... result = {
|
| 162 |
+
... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
| 163 |
+
... for k, t in concatenated_examples.items()
|
| 164 |
+
... }
|
| 165 |
+
... return result
|
| 166 |
+
```
|
| 167 |
+
|
| 168 |
+
データセット全体に`group_texts`関数を適用します。
|
| 169 |
+
|
| 170 |
+
```py
|
| 171 |
+
>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
|
| 172 |
+
```
|
| 173 |
+
|
| 174 |
+
次に、[`DataCollatorForLanguageModeling`] を使用してサンプルのバッチを作成します。データセット全体を最大長までパディングするのではなく、照合中にバッチ内の最長の長さまで文を *動的にパディング* する方が効率的です。
|
| 175 |
+
|
| 176 |
+
<frameworkcontent>
|
| 177 |
+
<pt>
|
| 178 |
+
|
| 179 |
+
シーケンス終了トークンをパディング トークンとして使用し、データを反復するたびにランダムにトークンをマスクするために `mlm_probability` を指定します。
|
| 180 |
+
|
| 181 |
+
```py
|
| 182 |
+
>>> from transformers import DataCollatorForLanguageModeling
|
| 183 |
+
|
| 184 |
+
>>> tokenizer.pad_token = tokenizer.eos_token
|
| 185 |
+
>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
|
| 186 |
+
```
|
| 187 |
+
</pt>
|
| 188 |
+
<tf>
|
| 189 |
+
|
| 190 |
+
シーケンス終了トークンをパディング トークンとして使用し、データを反復するたびにランダムにトークンをマスクするために `mlm_probability` を指定します。
|
| 191 |
+
|
| 192 |
+
|
| 193 |
+
```py
|
| 194 |
+
>>> from transformers import DataCollatorForLanguageModeling
|
| 195 |
+
|
| 196 |
+
>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15, return_tensors="tf")
|
| 197 |
+
```
|
| 198 |
+
</tf>
|
| 199 |
+
</frameworkcontent>
|
| 200 |
+
|
| 201 |
+
## Train
|
| 202 |
+
|
| 203 |
+
<frameworkcontent>
|
| 204 |
+
<pt>
|
| 205 |
+
<Tip>
|
| 206 |
+
|
| 207 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 208 |
+
|
| 209 |
+
</Tip>
|
| 210 |
+
|
| 211 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForMaskedLM`] を使用して DistilRoBERTa をロードします。
|
| 212 |
+
|
| 213 |
+
```py
|
| 214 |
+
>>> from transformers import AutoModelForMaskedLM
|
| 215 |
+
|
| 216 |
+
>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
|
| 217 |
+
```
|
| 218 |
+
|
| 219 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 220 |
+
|
| 221 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
|
| 222 |
+
2. トレーニング引数をモデル、データセット、データ照合器とともに [`Trainer`] に渡します。
|
| 223 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 224 |
+
|
| 225 |
+
```py
|
| 226 |
+
>>> training_args = TrainingArguments(
|
| 227 |
+
... output_dir="my_awesome_eli5_mlm_model",
|
| 228 |
+
... eval_strategy="epoch",
|
| 229 |
+
... learning_rate=2e-5,
|
| 230 |
+
... num_train_epochs=3,
|
| 231 |
+
... weight_decay=0.01,
|
| 232 |
+
... push_to_hub=True,
|
| 233 |
+
... )
|
| 234 |
+
|
| 235 |
+
>>> trainer = Trainer(
|
| 236 |
+
... model=model,
|
| 237 |
+
... args=training_args,
|
| 238 |
+
... train_dataset=lm_dataset["train"],
|
| 239 |
+
... eval_dataset=lm_dataset["test"],
|
| 240 |
+
... data_collator=data_collator,
|
| 241 |
+
... )
|
| 242 |
+
|
| 243 |
+
>>> trainer.train()
|
| 244 |
+
```
|
| 245 |
+
|
| 246 |
+
トレーニングが完了したら、 [`~transformers.Trainer.evaluate`] メソッドを使用してモデルを評価し、その複雑さを取得します。
|
| 247 |
+
|
| 248 |
+
|
| 249 |
+
```py
|
| 250 |
+
>>> import math
|
| 251 |
+
|
| 252 |
+
>>> eval_results = trainer.evaluate()
|
| 253 |
+
>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
|
| 254 |
+
Perplexity: 8.76
|
| 255 |
+
```
|
| 256 |
+
|
| 257 |
+
次に、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 258 |
+
|
| 259 |
+
```py
|
| 260 |
+
>>> trainer.push_to_hub()
|
| 261 |
+
```
|
| 262 |
+
|
| 263 |
+
</pt>
|
| 264 |
+
<tf>
|
| 265 |
+
<Tip>
|
| 266 |
+
|
| 267 |
+
Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
|
| 268 |
+
|
| 269 |
+
</Tip>
|
| 270 |
+
|
| 271 |
+
TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
|
| 272 |
+
|
| 273 |
+
```py
|
| 274 |
+
>>> from transformers import create_optimizer, AdamWeightDecay
|
| 275 |
+
|
| 276 |
+
>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
|
| 277 |
+
```
|
| 278 |
+
|
| 279 |
+
次に、[`TFAutoModelForMaskedLM`] を使用して DistilRoBERTa をロードできます。
|
| 280 |
+
|
| 281 |
+
```py
|
| 282 |
+
>>> from transformers import TFAutoModelForMaskedLM
|
| 283 |
+
|
| 284 |
+
>>> model = TFAutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
|
| 285 |
+
```
|
| 286 |
+
|
| 287 |
+
[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 288 |
+
|
| 289 |
+
```py
|
| 290 |
+
>>> tf_train_set = model.prepare_tf_dataset(
|
| 291 |
+
... lm_dataset["train"],
|
| 292 |
+
... shuffle=True,
|
| 293 |
+
... batch_size=16,
|
| 294 |
+
... collate_fn=data_collator,
|
| 295 |
+
... )
|
| 296 |
+
|
| 297 |
+
>>> tf_test_set = model.prepare_tf_dataset(
|
| 298 |
+
... lm_dataset["test"],
|
| 299 |
+
... shuffle=False,
|
| 300 |
+
... batch_size=16,
|
| 301 |
+
... collate_fn=data_collator,
|
| 302 |
+
... )
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
|
| 306 |
+
|
| 307 |
+
|
| 308 |
+
```py
|
| 309 |
+
>>> import tensorflow as tf
|
| 310 |
+
|
| 311 |
+
>>> model.compile(optimizer=optimizer) # No loss argument!
|
| 312 |
+
```
|
| 313 |
+
|
| 314 |
+
This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
|
| 315 |
+
|
| 316 |
+
```py
|
| 317 |
+
>>> from transformers.keras_callbacks import PushToHubCallback
|
| 318 |
+
|
| 319 |
+
>>> callback = PushToHubCallback(
|
| 320 |
+
... output_dir="my_awesome_eli5_mlm_model",
|
| 321 |
+
... tokenizer=tokenizer,
|
| 322 |
+
... )
|
| 323 |
+
```
|
| 324 |
+
|
| 325 |
+
ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
|
| 326 |
+
|
| 327 |
+
|
| 328 |
+
|
| 329 |
+
```py
|
| 330 |
+
>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
|
| 331 |
+
```
|
| 332 |
+
|
| 333 |
+
トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
|
| 334 |
+
|
| 335 |
+
</tf>
|
| 336 |
+
</frameworkcontent>
|
| 337 |
+
|
| 338 |
+
<Tip>
|
| 339 |
+
|
| 340 |
+
マスクされた言語モデリング用にモデルを微調整する方法のより詳細な例については、対応するドキュメントを参照してください。
|
| 341 |
+
[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
|
| 342 |
+
または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)。
|
| 343 |
+
|
| 344 |
+
</Tip>
|
| 345 |
+
|
| 346 |
+
## Inference
|
| 347 |
+
|
| 348 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 349 |
+
|
| 350 |
+
モデルに空白を埋めるテキストを考え出し、特別な `<mask>` トークンを使用して空白を示します。
|
| 351 |
+
|
| 352 |
+
```py
|
| 353 |
+
>>> text = "The Milky Way is a <mask> galaxy."
|
| 354 |
+
```
|
| 355 |
+
|
| 356 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用してフィルマスクの`pipeline`をインスタンス化し、テキストをそれに渡します。必要に応じて、`top_k`パラメータを使用して、返す予測の数を指定できます。
|
| 357 |
+
|
| 358 |
+
```py
|
| 359 |
+
>>> from transformers import pipeline
|
| 360 |
+
|
| 361 |
+
>>> mask_filler = pipeline("fill-mask", "stevhliu/my_awesome_eli5_mlm_model")
|
| 362 |
+
>>> mask_filler(text, top_k=3)
|
| 363 |
+
[{'score': 0.5150994658470154,
|
| 364 |
+
'token': 21300,
|
| 365 |
+
'token_str': ' spiral',
|
| 366 |
+
'sequence': 'The Milky Way is a spiral galaxy.'},
|
| 367 |
+
{'score': 0.07087188959121704,
|
| 368 |
+
'token': 2232,
|
| 369 |
+
'token_str': ' massive',
|
| 370 |
+
'sequence': 'The Milky Way is a massive galaxy.'},
|
| 371 |
+
{'score': 0.06434620916843414,
|
| 372 |
+
'token': 650,
|
| 373 |
+
'token_str': ' small',
|
| 374 |
+
'sequence': 'The Milky Way is a small galaxy.'}]
|
| 375 |
+
```
|
| 376 |
+
|
| 377 |
+
<frameworkcontent>
|
| 378 |
+
<pt>
|
| 379 |
+
|
| 380 |
+
テキストをトークン化し、`input_ids`を PyTorch テンソルとして返します。 `<mask>` トークンの位置も指定する必要があります。
|
| 381 |
+
|
| 382 |
+
```py
|
| 383 |
+
>>> from transformers import AutoTokenizer
|
| 384 |
+
|
| 385 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
|
| 386 |
+
>>> inputs = tokenizer(text, return_tensors="pt")
|
| 387 |
+
>>> mask_token_index = torch.where(inputs["input_ids"] == tokenizer.mask_token_id)[1]
|
| 388 |
+
```
|
| 389 |
+
|
| 390 |
+
入力をモデルに渡し、マスクされたトークンの`logits`を返します。
|
| 391 |
+
|
| 392 |
+
```py
|
| 393 |
+
>>> from transformers import AutoModelForMaskedLM
|
| 394 |
+
|
| 395 |
+
>>> model = AutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
|
| 396 |
+
>>> logits = model(**inputs).logits
|
| 397 |
+
>>> mask_token_logits = logits[0, mask_token_index, :]
|
| 398 |
+
```
|
| 399 |
+
|
| 400 |
+
次に、マスクされた 3 つのトークンを最も高い確率で返し、出力します。
|
| 401 |
+
|
| 402 |
+
```py
|
| 403 |
+
>>> top_3_tokens = torch.topk(mask_token_logits, 3, dim=1).indices[0].tolist()
|
| 404 |
+
|
| 405 |
+
>>> for token in top_3_tokens:
|
| 406 |
+
... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
|
| 407 |
+
The Milky Way is a spiral galaxy.
|
| 408 |
+
The Milky Way is a massive galaxy.
|
| 409 |
+
The Milky Way is a small galaxy.
|
| 410 |
+
```
|
| 411 |
+
|
| 412 |
+
</pt>
|
| 413 |
+
<tf>
|
| 414 |
+
|
| 415 |
+
テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。 `<mask>` トークンの位置も指定する必要があります。
|
| 416 |
+
|
| 417 |
+
```py
|
| 418 |
+
>>> from transformers import AutoTokenizer
|
| 419 |
+
|
| 420 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
|
| 421 |
+
>>> inputs = tokenizer(text, return_tensors="tf")
|
| 422 |
+
>>> mask_token_index = tf.where(inputs["input_ids"] == tokenizer.mask_token_id)[0, 1]
|
| 423 |
+
```
|
| 424 |
+
|
| 425 |
+
入力をモデルに渡し、マスクされたトークンの`logits`を返します。
|
| 426 |
+
|
| 427 |
+
|
| 428 |
+
```py
|
| 429 |
+
>>> from transformers import TFAutoModelForMaskedLM
|
| 430 |
+
|
| 431 |
+
>>> model = TFAutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
|
| 432 |
+
>>> logits = model(**inputs).logits
|
| 433 |
+
>>> mask_token_logits = logits[0, mask_token_index, :]
|
| 434 |
+
```
|
| 435 |
+
|
| 436 |
+
次に、マスクされた 3 つのトークンを最も高い確率で返し、出力します。
|
| 437 |
+
|
| 438 |
+
|
| 439 |
+
```py
|
| 440 |
+
>>> top_3_tokens = tf.math.top_k(mask_token_logits, 3).indices.numpy()
|
| 441 |
+
|
| 442 |
+
>>> for token in top_3_tokens:
|
| 443 |
+
... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
|
| 444 |
+
The Milky Way is a spiral galaxy.
|
| 445 |
+
The Milky Way is a massive galaxy.
|
| 446 |
+
The Milky Way is a small galaxy.
|
| 447 |
+
```
|
| 448 |
+
</tf>
|
| 449 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/monocular_depth_estimation.md
ADDED
|
@@ -0,0 +1,149 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Monocular depth estimation
|
| 18 |
+
|
| 19 |
+
単眼奥行き推定は、シーンの奥行き情報を画像から予測することを含むコンピューター ビジョン タスクです。
|
| 20 |
+
単一の画像。言い換えれば、シーン内のオブジェクトの距離を距離から推定するプロセスです。
|
| 21 |
+
単一カメラの視点。
|
| 22 |
+
|
| 23 |
+
単眼奥行き推定には、3D 再構築、拡張現実、自動運転、
|
| 24 |
+
そしてロボット工学。モデルがオブジェクト間の複雑な関係を理解する必要があるため、これは困難な作業です。
|
| 25 |
+
シーンとそれに対応する深度情報(照明条件などの要因の影響を受ける可能性があります)
|
| 26 |
+
オクルージョンとテクスチャ。
|
| 27 |
+
|
| 28 |
+
<Tip>
|
| 29 |
+
|
| 30 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/depth-estimation) を確認することをお勧めします。
|
| 31 |
+
|
| 32 |
+
</Tip>
|
| 33 |
+
|
| 34 |
+
このガイドでは、次の方法を学びます。
|
| 35 |
+
|
| 36 |
+
* 深度推定パイプラインを作成する
|
| 37 |
+
* 手動で深度推定推論を実行します
|
| 38 |
+
|
| 39 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install -q transformers
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
## Depth estimation pipeline
|
| 46 |
+
|
| 47 |
+
深度推定をサポートするモデルで推論を試す最も簡単な方法は、対応する [`pipeline`] を使用することです。
|
| 48 |
+
[Hugging Face Hub のチェックポイント](https://huggingface.co/models?pipeline_tag=Depth-estimation&sort=downloads) からパイプラインをインスタンス化します。
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
```py
|
| 52 |
+
>>> from transformers import pipeline
|
| 53 |
+
|
| 54 |
+
>>> checkpoint = "vinvino02/glpn-nyu"
|
| 55 |
+
>>> depth_estimator = pipeline("depth-estimation", model=checkpoint)
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
次に、分析する画像を選択します。
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
>>> from PIL import Image
|
| 62 |
+
>>> import requests
|
| 63 |
+
|
| 64 |
+
>>> url = "https://unsplash.com/photos/HwBAsSbPBDU/download?ixid=MnwxMjA3fDB8MXxzZWFyY2h8MzR8fGNhciUyMGluJTIwdGhlJTIwc3RyZWV0fGVufDB8MHx8fDE2Nzg5MDEwODg&force=true&w=640"
|
| 65 |
+
>>> image = Image.open(requests.get(url, stream=True).raw)
|
| 66 |
+
>>> image
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
<div class="flex justify-center">
|
| 70 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/depth-estimation-example.jpg" alt="Photo of a busy street"/>
|
| 71 |
+
</div>
|
| 72 |
+
|
| 73 |
+
画像をパイプラインに渡します。
|
| 74 |
+
|
| 75 |
+
```py
|
| 76 |
+
>>> predictions = depth_estimator(image)
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
パイプラインは 2 つのエントリを含む辞書を返します。最初のものは`predicted_ Depth`と呼ばれ、次の値を持つテンソルです。
|
| 80 |
+
深さは各ピクセルのメートル単位で表されます。
|
| 81 |
+
2 番目の`depth`は、深度推定結果を視覚化する PIL 画像です。
|
| 82 |
+
|
| 83 |
+
視覚化された結果を見てみましょう。
|
| 84 |
+
|
| 85 |
+
```py
|
| 86 |
+
>>> predictions["depth"]
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
<div class="flex justify-center">
|
| 90 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/depth-visualization.png" alt="Depth estimation visualization"/>
|
| 91 |
+
</div>
|
| 92 |
+
|
| 93 |
+
## Depth estimation inference by hand
|
| 94 |
+
|
| 95 |
+
深度推定パイプラインの使用方法を理解したので、同じ結果を手動で複製する方法を見てみましょう。
|
| 96 |
+
|
| 97 |
+
まず、[Hugging Face Hub のチェックポイント](https://huggingface.co/models?pipeline_tag=Depth-estimation&sort=downloads) からモデルと関連プロセッサをロードします。
|
| 98 |
+
ここでは、前と同じチェックポイントを使用します。
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
```py
|
| 102 |
+
>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
|
| 103 |
+
|
| 104 |
+
>>> checkpoint = "vinvino02/glpn-nyu"
|
| 105 |
+
|
| 106 |
+
>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
|
| 107 |
+
>>> model = AutoModelForDepthEstimation.from_pretrained(checkpoint)
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
必要な画像変換を処理する`image_processor`を使用して、モデルの画像入力を準備します。
|
| 111 |
+
サイズ変更や正規化など:
|
| 112 |
+
|
| 113 |
+
```py
|
| 114 |
+
>>> pixel_values = image_processor(image, return_tensors="pt").pixel_values
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
準備された入力をモデルに渡します。
|
| 118 |
+
|
| 119 |
+
```py
|
| 120 |
+
>>> import torch
|
| 121 |
+
|
| 122 |
+
>>> with torch.no_grad():
|
| 123 |
+
... outputs = model(pixel_values)
|
| 124 |
+
... predicted_depth = outputs.predicted_depth
|
| 125 |
+
```
|
| 126 |
+
|
| 127 |
+
結果を視覚化します。
|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
```py
|
| 131 |
+
>>> import numpy as np
|
| 132 |
+
|
| 133 |
+
>>> # interpolate to original size
|
| 134 |
+
>>> prediction = torch.nn.functional.interpolate(
|
| 135 |
+
... predicted_depth.unsqueeze(1),
|
| 136 |
+
... size=image.size[::-1],
|
| 137 |
+
... mode="bicubic",
|
| 138 |
+
... align_corners=False,
|
| 139 |
+
... ).squeeze()
|
| 140 |
+
>>> output = prediction.numpy()
|
| 141 |
+
|
| 142 |
+
>>> formatted = (output * 255 / np.max(output)).astype("uint8")
|
| 143 |
+
>>> depth = Image.fromarray(formatted)
|
| 144 |
+
>>> depth
|
| 145 |
+
```
|
| 146 |
+
|
| 147 |
+
<div class="flex justify-center">
|
| 148 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/depth-visualization.png" alt="Depth estimation visualization"/>
|
| 149 |
+
</div>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/multiple_choice.md
ADDED
|
@@ -0,0 +1,374 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Multiple choice
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
多肢選択タスクは質問応答に似ていますが、いくつかの候補の回答がコンテキストとともに提供され、正しい回答を選択するようにモデルがトレーニングされる点が異なります。
|
| 22 |
+
|
| 23 |
+
このガイドでは、次の方法を説明します。
|
| 24 |
+
|
| 25 |
+
1. [SWAG](https://huggingface.co/datasets/swag) データセットの「通常」構成で [BERT](https://huggingface.co/google-bert/bert-base-uncased) を微調整して、最適なデータセットを選択します複数の選択肢と何らかのコンテキストを考慮して回答します。
|
| 26 |
+
2. 微調整したモデルを推論に使用します。
|
| 27 |
+
|
| 28 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
pip install transformers datasets evaluate
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 35 |
+
|
| 36 |
+
```py
|
| 37 |
+
>>> from huggingface_hub import notebook_login
|
| 38 |
+
|
| 39 |
+
>>> notebook_login()
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
## Load SWAG dataset
|
| 43 |
+
|
| 44 |
+
まず、🤗 データセット ライブラリから SWAG データセットの「通常」構成をロードします。
|
| 45 |
+
|
| 46 |
+
```py
|
| 47 |
+
>>> from datasets import load_dataset
|
| 48 |
+
|
| 49 |
+
>>> swag = load_dataset("swag", "regular")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
次に、例を見てみましょう。
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
>>> swag["train"][0]
|
| 56 |
+
{'ending0': 'passes by walking down the street playing their instruments.',
|
| 57 |
+
'ending1': 'has heard approaching them.',
|
| 58 |
+
'ending2': "arrives and they're outside dancing and asleep.",
|
| 59 |
+
'ending3': 'turns the lead singer watches the performance.',
|
| 60 |
+
'fold-ind': '3416',
|
| 61 |
+
'gold-source': 'gold',
|
| 62 |
+
'label': 0,
|
| 63 |
+
'sent1': 'Members of the procession walk down the street holding small horn brass instruments.',
|
| 64 |
+
'sent2': 'A drum line',
|
| 65 |
+
'startphrase': 'Members of the procession walk down the street holding small horn brass instruments. A drum line',
|
| 66 |
+
'video-id': 'anetv_jkn6uvmqwh4'}
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
ここにはたくさんのフィールドがあるように見えますが、実際は非常に簡単です。
|
| 70 |
+
|
| 71 |
+
- `sent1` と `sent2`: これらのフィールドは文の始まりを示し、この 2 つを組み合わせると `startphrase` フィールドが得られます。
|
| 72 |
+
- `ending`: 文の終わり方として考えられる終わり方を示唆しますが、正しいのは 1 つだけです。
|
| 73 |
+
- `label`: 正しい文の終わりを識別します。
|
| 74 |
+
|
| 75 |
+
## Preprocess
|
| 76 |
+
|
| 77 |
+
次のステップでは、BERT トークナイザーをロードして、文の始まりと 4 つの可能な終わりを処理します。
|
| 78 |
+
|
| 79 |
+
```py
|
| 80 |
+
>>> from transformers import AutoTokenizer
|
| 81 |
+
|
| 82 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
作成する前処理関数は次のことを行う必要があります。
|
| 86 |
+
|
| 87 |
+
1. `sent1` フィールドのコピーを 4 つ作成し、それぞれを `sent2` と組み合わせて文の始まりを再現します。
|
| 88 |
+
2. `sent2` を 4 つの可能な文末尾のそれぞれと組み合わせます。
|
| 89 |
+
3. これら 2 つのリストをトークン化できるようにフラット化し、その後、各例に対応する `input_ids`、`attention_mask`、および `labels` フィールドが含まれるように非フラット化します。
|
| 90 |
+
|
| 91 |
+
```py
|
| 92 |
+
>>> ending_names = ["ending0", "ending1", "ending2", "ending3"]
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
>>> def preprocess_function(examples):
|
| 96 |
+
... first_sentences = [[context] * 4 for context in examples["sent1"]]
|
| 97 |
+
... question_headers = examples["sent2"]
|
| 98 |
+
... second_sentences = [
|
| 99 |
+
... [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
|
| 100 |
+
... ]
|
| 101 |
+
|
| 102 |
+
... first_sentences = sum(first_sentences, [])
|
| 103 |
+
... second_sentences = sum(second_sentences, [])
|
| 104 |
+
|
| 105 |
+
... tokenized_examples = tokenizer(first_sentences, second_sentences, truncation=True)
|
| 106 |
+
... return {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` 関数を高速化できます。
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
```py
|
| 113 |
+
tokenized_swag = swag.map(preprocess_function, batched=True)
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
[`DataCollatorForMultipleChoice`] は、すべてのモデル入力を平坦化し、パディングを適用して、結果を非平坦化します。
|
| 117 |
+
```py
|
| 118 |
+
>>> from transformers import DataCollatorForMultipleChoice
|
| 119 |
+
>>> collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
## Evaluate
|
| 123 |
+
|
| 124 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) メトリクスを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスの読み込みと計算方法の詳細については、次を参照してください)。
|
| 125 |
+
|
| 126 |
+
```py
|
| 127 |
+
>>> import evaluate
|
| 128 |
+
|
| 129 |
+
>>> accuracy = evaluate.load("accuracy")
|
| 130 |
+
```
|
| 131 |
+
|
| 132 |
+
次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して精度を計算する関数を作成します。
|
| 133 |
+
|
| 134 |
+
```py
|
| 135 |
+
>>> import numpy as np
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
>>> def compute_metrics(eval_pred):
|
| 139 |
+
... predictions, labels = eval_pred
|
| 140 |
+
... predictions = np.argmax(predictions, axis=1)
|
| 141 |
+
... return accuracy.compute(predictions=predictions, references=labels)
|
| 142 |
+
```
|
| 143 |
+
|
| 144 |
+
これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
|
| 145 |
+
|
| 146 |
+
## Train
|
| 147 |
+
|
| 148 |
+
<frameworkcontent>
|
| 149 |
+
<pt>
|
| 150 |
+
<Tip>
|
| 151 |
+
|
| 152 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 153 |
+
|
| 154 |
+
</Tip>
|
| 155 |
+
|
| 156 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForMultipleChoice`] を使用して BERT をロードします。
|
| 157 |
+
|
| 158 |
+
```py
|
| 159 |
+
>>> from transformers import AutoModelForMultipleChoice, TrainingArguments, Trainer
|
| 160 |
+
|
| 161 |
+
>>> model = AutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
|
| 162 |
+
```
|
| 163 |
+
|
| 164 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 165 |
+
|
| 166 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は精度を評価し、トレーニング チェックポイントを保存します。
|
| 167 |
+
2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
|
| 168 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 169 |
+
|
| 170 |
+
```py
|
| 171 |
+
>>> training_args = TrainingArguments(
|
| 172 |
+
... output_dir="my_awesome_swag_model",
|
| 173 |
+
... eval_strategy="epoch",
|
| 174 |
+
... save_strategy="epoch",
|
| 175 |
+
... load_best_model_at_end=True,
|
| 176 |
+
... learning_rate=5e-5,
|
| 177 |
+
... per_device_train_batch_size=16,
|
| 178 |
+
... per_device_eval_batch_size=16,
|
| 179 |
+
... num_train_epochs=3,
|
| 180 |
+
... weight_decay=0.01,
|
| 181 |
+
... push_to_hub=True,
|
| 182 |
+
... )
|
| 183 |
+
|
| 184 |
+
>>> trainer = Trainer(
|
| 185 |
+
... model=model,
|
| 186 |
+
... args=training_args,
|
| 187 |
+
... train_dataset=tokenized_swag["train"],
|
| 188 |
+
... eval_dataset=tokenized_swag["validation"],
|
| 189 |
+
... processing_class=tokenizer,
|
| 190 |
+
... data_collator=collator,
|
| 191 |
+
... compute_metrics=compute_metrics,
|
| 192 |
+
... )
|
| 193 |
+
|
| 194 |
+
>>> trainer.train()
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できますように。
|
| 198 |
+
|
| 199 |
+
```py
|
| 200 |
+
>>> trainer.push_to_hub()
|
| 201 |
+
```
|
| 202 |
+
</pt>
|
| 203 |
+
<tf>
|
| 204 |
+
<Tip>
|
| 205 |
+
|
| 206 |
+
Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
|
| 207 |
+
|
| 208 |
+
</Tip>
|
| 209 |
+
TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
|
| 210 |
+
|
| 211 |
+
```py
|
| 212 |
+
>>> from transformers import create_optimizer
|
| 213 |
+
|
| 214 |
+
>>> batch_size = 16
|
| 215 |
+
>>> num_train_epochs = 2
|
| 216 |
+
>>> total_train_steps = (len(tokenized_swag["train"]) // batch_size) * num_train_epochs
|
| 217 |
+
>>> optimizer, schedule = create_optimizer(init_lr=5e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
|
| 218 |
+
```
|
| 219 |
+
|
| 220 |
+
次に、[`TFAutoModelForMultipleChoice`] を使用して BERT をロードできます。
|
| 221 |
+
|
| 222 |
+
```py
|
| 223 |
+
>>> from transformers import TFAutoModelForMultipleChoice
|
| 224 |
+
|
| 225 |
+
>>> model = TFAutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
|
| 226 |
+
```
|
| 227 |
+
|
| 228 |
+
[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 229 |
+
|
| 230 |
+
```py
|
| 231 |
+
>>> data_collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
|
| 232 |
+
>>> tf_train_set = model.prepare_tf_dataset(
|
| 233 |
+
... tokenized_swag["train"],
|
| 234 |
+
... shuffle=True,
|
| 235 |
+
... batch_size=batch_size,
|
| 236 |
+
... collate_fn=data_collator,
|
| 237 |
+
... )
|
| 238 |
+
|
| 239 |
+
>>> tf_validation_set = model.prepare_tf_dataset(
|
| 240 |
+
... tokenized_swag["validation"],
|
| 241 |
+
... shuffle=False,
|
| 242 |
+
... batch_size=batch_size,
|
| 243 |
+
... collate_fn=data_collator,
|
| 244 |
+
... )
|
| 245 |
+
```
|
| 246 |
+
|
| 247 |
+
[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
|
| 248 |
+
|
| 249 |
+
```py
|
| 250 |
+
>>> model.compile(optimizer=optimizer) # No loss argument!
|
| 251 |
+
```
|
| 252 |
+
|
| 253 |
+
トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から精度を計算することと、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
|
| 254 |
+
|
| 255 |
+
`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
|
| 256 |
+
|
| 257 |
+
```py
|
| 258 |
+
>>> from transformers.keras_callbacks import KerasMetricCallback
|
| 259 |
+
|
| 260 |
+
>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
|
| 261 |
+
```
|
| 262 |
+
|
| 263 |
+
[`~transformers.PushToHubCallback`] でモデルとトークナイザーをプッシュする場所を指定します。
|
| 264 |
+
|
| 265 |
+
```py
|
| 266 |
+
>>> from transformers.keras_callbacks import PushToHubCallback
|
| 267 |
+
|
| 268 |
+
>>> push_to_hub_callback = PushToHubCallback(
|
| 269 |
+
... output_dir="my_awesome_model",
|
| 270 |
+
... tokenizer=tokenizer,
|
| 271 |
+
... )
|
| 272 |
+
```
|
| 273 |
+
|
| 274 |
+
次に、コールバックをまとめてバンドルします。
|
| 275 |
+
|
| 276 |
+
```py
|
| 277 |
+
>>> callbacks = [metric_callback, push_to_hub_callback]
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
|
| 281 |
+
|
| 282 |
+
```py
|
| 283 |
+
>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=2, callbacks=callbacks)
|
| 284 |
+
```
|
| 285 |
+
|
| 286 |
+
トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
|
| 287 |
+
|
| 288 |
+
</tf>
|
| 289 |
+
</frameworkcontent>
|
| 290 |
+
|
| 291 |
+
|
| 292 |
+
<Tip>
|
| 293 |
+
|
| 294 |
+
複数選択用にモデルを微調整する方法の詳細な例については、対応するセクションを参照してください。
|
| 295 |
+
[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
|
| 296 |
+
または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb)。
|
| 297 |
+
|
| 298 |
+
</Tip>
|
| 299 |
+
|
| 300 |
+
|
| 301 |
+
# Inference
|
| 302 |
+
|
| 303 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 304 |
+
|
| 305 |
+
いくつかのテキストと 2 つの回答候補を考えてください。
|
| 306 |
+
|
| 307 |
+
```py
|
| 308 |
+
>>> prompt = "France has a bread law, Le Décret Pain, with strict rules on what is allowed in a traditional baguette."
|
| 309 |
+
>>> candidate1 = "The law does not apply to croissants and brioche."
|
| 310 |
+
>>> candidate2 = "The law applies to baguettes."
|
| 311 |
+
```
|
| 312 |
+
|
| 313 |
+
<frameworkcontent>
|
| 314 |
+
<pt>
|
| 315 |
+
|
| 316 |
+
各プロンプトと回答候補のペアをトークン化し、PyTorch テンソルを返します。いくつかの`lables`も作成する必要があります。
|
| 317 |
+
|
| 318 |
+
```py
|
| 319 |
+
>>> from transformers import AutoTokenizer
|
| 320 |
+
|
| 321 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
|
| 322 |
+
>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="pt", padding=True)
|
| 323 |
+
>>> labels = torch.tensor(0).unsqueeze(0)
|
| 324 |
+
```
|
| 325 |
+
|
| 326 |
+
入力とラベルをモデルに渡し、`logits`を返します。
|
| 327 |
+
|
| 328 |
+
```py
|
| 329 |
+
>>> from transformers import AutoModelForMultipleChoice
|
| 330 |
+
|
| 331 |
+
>>> model = AutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
|
| 332 |
+
>>> outputs = model(**{k: v.unsqueeze(0) for k, v in inputs.items()}, labels=labels)
|
| 333 |
+
>>> logits = outputs.logits
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
最も高い確率でクラスを取得します。
|
| 337 |
+
|
| 338 |
+
```py
|
| 339 |
+
>>> predicted_class = logits.argmax().item()
|
| 340 |
+
>>> predicted_class
|
| 341 |
+
'0'
|
| 342 |
+
```
|
| 343 |
+
</pt>
|
| 344 |
+
<tf>
|
| 345 |
+
|
| 346 |
+
各プロンプトと回答候補のペアをトークン化し、TensorFlow テンソルを返します。
|
| 347 |
+
|
| 348 |
+
```py
|
| 349 |
+
>>> from transformers import AutoTokenizer
|
| 350 |
+
|
| 351 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
|
| 352 |
+
>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="tf", padding=True)
|
| 353 |
+
```
|
| 354 |
+
|
| 355 |
+
入力をモデルに渡し、`logits`を返します。
|
| 356 |
+
|
| 357 |
+
```py
|
| 358 |
+
>>> from transformers import TFAutoModelForMultipleChoice
|
| 359 |
+
|
| 360 |
+
>>> model = TFAutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
|
| 361 |
+
>>> inputs = {k: tf.expand_dims(v, 0) for k, v in inputs.items()}
|
| 362 |
+
>>> outputs = model(inputs)
|
| 363 |
+
>>> logits = outputs.logits
|
| 364 |
+
```
|
| 365 |
+
|
| 366 |
+
最も高い確率でクラスを取得します。
|
| 367 |
+
|
| 368 |
+
```py
|
| 369 |
+
>>> predicted_class = int(tf.math.argmax(logits, axis=-1)[0])
|
| 370 |
+
>>> predicted_class
|
| 371 |
+
'0'
|
| 372 |
+
```
|
| 373 |
+
</tf>
|
| 374 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/object_detection.md
ADDED
|
@@ -0,0 +1,598 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Object detection
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
オブジェクト検出は、画像内のインスタンス (人間、建物、車など) を検出するコンピューター ビジョン タスクです。物体検出モデルは画像を入力および出力として受け取ります
|
| 22 |
+
検出されたオブジェクトの境界ボックスと関連するラベルの座標。画像には複数のオブジェクトを含めることができます。
|
| 23 |
+
それぞれに独自の境界ボックスとラベルがあり (例: 車と建物を持つことができます)、各オブジェクトは
|
| 24 |
+
画像のさまざまな部分に存在する必要があります (たとえば、画像には複数の車が含まれている可能性があります)。
|
| 25 |
+
このタスクは、歩行者、道路標識、信号機などを検出するために自動運転で一般的に使用されます。
|
| 26 |
+
他のアプリケーションには、画像内のオブジェクトのカウント、画像検索などが含まれます。
|
| 27 |
+
|
| 28 |
+
このガイドでは、次の方法を学習します。
|
| 29 |
+
|
| 30 |
+
1. Finetune [DETR](https://huggingface.co/docs/transformers/model_doc/detr)、畳み込みアルゴリズムを組み合わせたモデル
|
| 31 |
+
[CPPE-5](https://huggingface.co/datasets/cppe-5) 上のエンコーダー/デコーダー トランスフォーマーを備えたバックボーン
|
| 32 |
+
データセット。
|
| 33 |
+
2. 微調整したモデルを推論に使用します。
|
| 34 |
+
|
| 35 |
+
<Tip>
|
| 36 |
+
|
| 37 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/object-detection) を確認することをお勧めします。
|
| 38 |
+
|
| 39 |
+
</Tip>
|
| 40 |
+
|
| 41 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
pip install -q datasets transformers evaluate timm albumentations
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
🤗 データセットを使用して Hugging Face Hub からデータセットをロードし、🤗 トランスフォーマーを使用してモデルをトレーニングします。
|
| 49 |
+
データを増強するための`albumentations`。 `timm` は現在、DETR モデルの畳み込みバックボーンをロードするために必要です。
|
| 50 |
+
|
| 51 |
+
モデルをコミュニティと共有することをお勧めします。 Hugging Face アカウントにログインして、ハブにアップロードします。
|
| 52 |
+
プロンプトが表示されたら、トークンを入力してログインします。
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
>>> from huggingface_hub import notebook_login
|
| 56 |
+
|
| 57 |
+
>>> notebook_login()
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
## Load the CPPE-5 dataset
|
| 61 |
+
|
| 62 |
+
[CPPE-5 データセット](https://huggingface.co/datasets/cppe-5) には、次の画像が含まれています。
|
| 63 |
+
新型コロナウイルス感染症のパンデミックにおける医療用個人保護具 (PPE) を識別する注釈。
|
| 64 |
+
|
| 65 |
+
データセットをロードすることから始めます。
|
| 66 |
+
|
| 67 |
+
```py
|
| 68 |
+
>>> from datasets import load_dataset
|
| 69 |
+
|
| 70 |
+
>>> cppe5 = load_dataset("cppe-5")
|
| 71 |
+
>>> cppe5
|
| 72 |
+
DatasetDict({
|
| 73 |
+
train: Dataset({
|
| 74 |
+
features: ['image_id', 'image', 'width', 'height', 'objects'],
|
| 75 |
+
num_rows: 1000
|
| 76 |
+
})
|
| 77 |
+
test: Dataset({
|
| 78 |
+
features: ['image_id', 'image', 'width', 'height', 'objects'],
|
| 79 |
+
num_rows: 29
|
| 80 |
+
})
|
| 81 |
+
})
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
このデータセットには、1000 枚の画像を含むトレーニング セットと 29 枚の画像を含むテスト セットがすでに付属していることがわかります。
|
| 85 |
+
|
| 86 |
+
データに慣れるために、例がどのようなものかを調べてください。
|
| 87 |
+
|
| 88 |
+
```py
|
| 89 |
+
>>> cppe5["train"][0]
|
| 90 |
+
{'image_id': 15,
|
| 91 |
+
'image': <PIL.JpegImagePlugin.JpegImageFile image mode=RGB size=943x663 at 0x7F9EC9E77C10>,
|
| 92 |
+
'width': 943,
|
| 93 |
+
'height': 663,
|
| 94 |
+
'objects': {'id': [114, 115, 116, 117],
|
| 95 |
+
'area': [3796, 1596, 152768, 81002],
|
| 96 |
+
'bbox': [[302.0, 109.0, 73.0, 52.0],
|
| 97 |
+
[810.0, 100.0, 57.0, 28.0],
|
| 98 |
+
[160.0, 31.0, 248.0, 616.0],
|
| 99 |
+
[741.0, 68.0, 202.0, 401.0]],
|
| 100 |
+
'category': [4, 4, 0, 0]}}
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
データセット内の例には次のフィールドがあります。
|
| 104 |
+
- `image_id`: サンプルの画像ID
|
| 105 |
+
- `image`: 画像を含む `PIL.Image.Image` オブジェクト
|
| 106 |
+
- `width`: 画像の幅
|
| 107 |
+
- `height`: 画像の高さ
|
| 108 |
+
- `objects`: 画像内のオブジェクトの境界ボックスのメタデータを含む辞書:
|
| 109 |
+
- `id`: アノテーションID
|
| 110 |
+
- `area`: 境界ボックスの領域
|
| 111 |
+
- `bbox`: オブジェクトの境界ボックス ([COCO 形式](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco) )
|
| 112 |
+
- `category`: オブジェクトのカテゴリー。可能な値には、`Coverall (0)`、`Face_Shield (1)`、`Gloves (2)`、`Goggles (3)`、および `Mask (4)` が含まれます。
|
| 113 |
+
|
| 114 |
+
`bbox`フィールドが COCO 形式に従っていることに気づくかもしれません。これは DETR モデルが予期する形式です。
|
| 115 |
+
ただし、「オブジェクト」内のフィールドのグループ化は、DETR が必要とする注釈形式とは異なります。あなたはするであろう
|
| 116 |
+
このデータをトレーニングに使用する前に、いくつかの前処理変換を適用する必要があります。
|
| 117 |
+
|
| 118 |
+
データをさらに深く理解するには、データセット内の例を視覚化します。
|
| 119 |
+
|
| 120 |
+
```py
|
| 121 |
+
>>> import numpy as np
|
| 122 |
+
>>> import os
|
| 123 |
+
>>> from PIL import Image, ImageDraw
|
| 124 |
+
|
| 125 |
+
>>> image = cppe5["train"][0]["image"]
|
| 126 |
+
>>> annotations = cppe5["train"][0]["objects"]
|
| 127 |
+
>>> draw = ImageDraw.Draw(image)
|
| 128 |
+
|
| 129 |
+
>>> categories = cppe5["train"].features["objects"].feature["category"].names
|
| 130 |
+
|
| 131 |
+
>>> id2label = {index: x for index, x in enumerate(categories, start=0)}
|
| 132 |
+
>>> label2id = {v: k for k, v in id2label.items()}
|
| 133 |
+
|
| 134 |
+
>>> for i in range(len(annotations["id"])):
|
| 135 |
+
... box = annotations["bbox"][i]
|
| 136 |
+
... class_idx = annotations["category"][i]
|
| 137 |
+
... x, y, w, h = tuple(box)
|
| 138 |
+
... draw.rectangle((x, y, x + w, y + h), outline="red", width=1)
|
| 139 |
+
... draw.text((x, y), id2label[class_idx], fill="white")
|
| 140 |
+
|
| 141 |
+
>>> image
|
| 142 |
+
```
|
| 143 |
+
|
| 144 |
+
<div class="flex justify-center">
|
| 145 |
+
<img src="https://i.imgur.com/TdaqPJO.png" alt="CPPE-5 Image Example"/>
|
| 146 |
+
</div>
|
| 147 |
+
|
| 148 |
+
関連付けられたラベルを使用して境界ボックスを視覚化するには、データセットのメタデータからラベルを取得します。
|
| 149 |
+
`category`フィールド。
|
| 150 |
+
また、ラベル ID をラベル クラスにマッピングする辞書 (`id2label`) やその逆 (`label2id`) を作成することもできます。
|
| 151 |
+
これらは、後でモデルをセットアップするときに使用できます。これらのマップを含めると、共有した場合に他の人がモデルを再利用できるようになります。
|
| 152 |
+
ハグフェイスハブに取り付けます。
|
| 153 |
+
|
| 154 |
+
データに慣れるための最後のステップとして、潜在的な問題がないかデータを調査します。データセットに関する一般的な問題の 1 つは、
|
| 155 |
+
オブジェクト検出は、画像の端を越えて「伸びる」境界ボックスです。このような「暴走」境界ボックスは、
|
| 156 |
+
トレーニング中にエラーが発生するため、この段階で対処する必要があります。このデータセットには、この問題に関する例がいくつかあります。
|
| 157 |
+
このガイドでは内容をわかりやすくするために、これらの画像をデータから削除します。
|
| 158 |
+
|
| 159 |
+
```py
|
| 160 |
+
>>> remove_idx = [590, 821, 822, 875, 876, 878, 879]
|
| 161 |
+
>>> keep = [i for i in range(len(cppe5["train"])) if i not in remove_idx]
|
| 162 |
+
>>> cppe5["train"] = cppe5["train"].select(keep)
|
| 163 |
+
```
|
| 164 |
+
|
| 165 |
+
## Preprocess the data
|
| 166 |
+
|
| 167 |
+
モデルを微調整するには、事前トレーニングされたモデルに使用されるアプローチと正確に一致するように、使用する予定のデータを前処理する必要があります。
|
| 168 |
+
[`AutoImageProcessor`] は、画像データを処理して `pixel_values`、`pixel_mask`、および
|
| 169 |
+
DETR モデルをトレーニングできる「ラベル」。画像プロセッサには、心配する必要のないいくつかの属性があります。
|
| 170 |
+
|
| 171 |
+
- `image_mean = [0.485, 0.456, 0.406 ]`
|
| 172 |
+
- `image_std = [0.229, 0.224, 0.225]`
|
| 173 |
+
|
| 174 |
+
これらは、モデルの事前トレーニング中に画像を正規化するために使用される平均と標準偏差です。これらの価値観は非常に重要です
|
| 175 |
+
事前にトレーニングされた画像モデルを推論または微調整するときに複製します。
|
| 176 |
+
|
| 177 |
+
微調整するモデルと同じチェックポイントからイメージ プロセッサをインスタンス化します。
|
| 178 |
+
|
| 179 |
+
```py
|
| 180 |
+
>>> from transformers import AutoImageProcessor
|
| 181 |
+
|
| 182 |
+
>>> checkpoint = "facebook/detr-resnet-50"
|
| 183 |
+
>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
|
| 184 |
+
```
|
| 185 |
+
|
| 186 |
+
画像を`image_processor`に渡す前に、2 つの前処理変換をデータセットに適用します。
|
| 187 |
+
- 画像の拡張
|
| 188 |
+
- DETR の期待に応えるための注釈の再フォーマット
|
| 189 |
+
|
| 190 |
+
まず、モデルがトレーニング データにオーバーフィットしないようにするために、任意のデータ拡張ライブラリを使用して画像拡張を適用できます。ここでは[Albumentations](https://albumentations.ai/docs/)を使用します...
|
| 191 |
+
このライブラリは、変換が画像に影響を与え���それに応じて境界ボックスを更新することを保証します。
|
| 192 |
+
🤗 データセット ライブラリのドキュメントには、詳細な [物体検出用に画像を拡張する方法に関するガイド](https://huggingface.co/docs/datasets/object_detection) が記載されています。
|
| 193 |
+
例としてまったく同じデータセットを使用しています。ここでも同じアプローチを適用し、各画像のサイズを (480, 480) に変更します。
|
| 194 |
+
水平に反転して明るくします。
|
| 195 |
+
|
| 196 |
+
```py
|
| 197 |
+
>>> import albumentations
|
| 198 |
+
>>> import numpy as np
|
| 199 |
+
>>> import torch
|
| 200 |
+
|
| 201 |
+
>>> transform = albumentations.Compose(
|
| 202 |
+
... [
|
| 203 |
+
... albumentations.Resize(480, 480),
|
| 204 |
+
... albumentations.HorizontalFlip(p=1.0),
|
| 205 |
+
... albumentations.RandomBrightnessContrast(p=1.0),
|
| 206 |
+
... ],
|
| 207 |
+
... bbox_params=albumentations.BboxParams(format="coco", label_fields=["category"]),
|
| 208 |
+
... )
|
| 209 |
+
```
|
| 210 |
+
|
| 211 |
+
`image_processor` は、注釈が次の形式であることを期待します: `{'image_id': int, 'annotations': List[Dict]}`,
|
| 212 |
+
ここで、各辞書は COCO オブジェクトの注釈です。 1 つの例として、注釈を再フォーマットする関数を追加してみましょう。
|
| 213 |
+
|
| 214 |
+
```py
|
| 215 |
+
>>> def formatted_anns(image_id, category, area, bbox):
|
| 216 |
+
... annotations = []
|
| 217 |
+
... for i in range(0, len(category)):
|
| 218 |
+
... new_ann = {
|
| 219 |
+
... "image_id": image_id,
|
| 220 |
+
... "category_id": category[i],
|
| 221 |
+
... "isCrowd": 0,
|
| 222 |
+
... "area": area[i],
|
| 223 |
+
... "bbox": list(bbox[i]),
|
| 224 |
+
... }
|
| 225 |
+
... annotations.append(new_ann)
|
| 226 |
+
|
| 227 |
+
... return annotations
|
| 228 |
+
```
|
| 229 |
+
|
| 230 |
+
これで、画像と注釈の変換を組み合わせてサンプルのバッチで使用できるようになりました。
|
| 231 |
+
|
| 232 |
+
```py
|
| 233 |
+
>>> # transforming a batch
|
| 234 |
+
>>> def transform_aug_ann(examples):
|
| 235 |
+
... image_ids = examples["image_id"]
|
| 236 |
+
... images, bboxes, area, categories = [], [], [], []
|
| 237 |
+
... for image, objects in zip(examples["image"], examples["objects"]):
|
| 238 |
+
... image = np.array(image.convert("RGB"))[:, :, ::-1]
|
| 239 |
+
... out = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
|
| 240 |
+
|
| 241 |
+
... area.append(objects["area"])
|
| 242 |
+
... images.append(out["image"])
|
| 243 |
+
... bboxes.append(out["bboxes"])
|
| 244 |
+
... categories.append(out["category"])
|
| 245 |
+
|
| 246 |
+
... targets = [
|
| 247 |
+
... {"image_id": id_, "annotations": formatted_anns(id_, cat_, ar_, box_)}
|
| 248 |
+
... for id_, cat_, ar_, box_ in zip(image_ids, categories, area, bboxes)
|
| 249 |
+
... ]
|
| 250 |
+
|
| 251 |
+
... return image_processor(images=images, annotations=targets, return_tensors="pt")
|
| 252 |
+
```
|
| 253 |
+
|
| 254 |
+
🤗 Datasets [`~datasets.Dataset.with_transform`] メソッドを使用して、この前処理関数をデータセット全体に適用します。この方法が適用されるのは、
|
| 255 |
+
データセットの要素を読み込むときに、その場で変換します。
|
| 256 |
+
|
| 257 |
+
この時点で、データセットの例が変換後にどのようになるかを確認できます。テンソルが表示されるはずです
|
| 258 |
+
`pixel_values`、テンソルと `pixel_mask`、および `labels` を使用します。
|
| 259 |
+
|
| 260 |
+
```py
|
| 261 |
+
>>> cppe5["train"] = cppe5["train"].with_transform(transform_aug_ann)
|
| 262 |
+
>>> cppe5["train"][15]
|
| 263 |
+
{'pixel_values': tensor([[[ 0.9132, 0.9132, 0.9132, ..., -1.9809, -1.9809, -1.9809],
|
| 264 |
+
[ 0.9132, 0.9132, 0.9132, ..., -1.9809, -1.9809, -1.9809],
|
| 265 |
+
[ 0.9132, 0.9132, 0.9132, ..., -1.9638, -1.9638, -1.9638],
|
| 266 |
+
...,
|
| 267 |
+
[-1.5699, -1.5699, -1.5699, ..., -1.9980, -1.9980, -1.9980],
|
| 268 |
+
[-1.5528, -1.5528, -1.5528, ..., -1.9980, -1.9809, -1.9809],
|
| 269 |
+
[-1.5528, -1.5528, -1.5528, ..., -1.9980, -1.9809, -1.9809]],
|
| 270 |
+
|
| 271 |
+
[[ 1.3081, 1.3081, 1.3081, ..., -1.8431, -1.8431, -1.8431],
|
| 272 |
+
[ 1.3081, 1.3081, 1.3081, ..., -1.8431, -1.8431, -1.8431],
|
| 273 |
+
[ 1.3081, 1.3081, 1.3081, ..., -1.8256, -1.8256, -1.8256],
|
| 274 |
+
...,
|
| 275 |
+
[-1.3179, -1.3179, -1.3179, ..., -1.8606, -1.8606, -1.8606],
|
| 276 |
+
[-1.3004, -1.3004, -1.3004, ..., -1.8606, -1.8431, -1.8431],
|
| 277 |
+
[-1.3004, -1.3004, -1.3004, ..., -1.8606, -1.8431, -1.8431]],
|
| 278 |
+
|
| 279 |
+
[[ 1.4200, 1.4200, 1.4200, ..., -1.6476, -1.6476, -1.6476],
|
| 280 |
+
[ 1.4200, 1.4200, 1.4200, ..., -1.6476, -1.6476, -1.6476],
|
| 281 |
+
[ 1.4200, 1.4200, 1.4200, ..., -1.6302, -1.6302, -1.6302],
|
| 282 |
+
...,
|
| 283 |
+
[-1.0201, -1.0201, -1.0201, ..., -1.5604, -1.5604, -1.5604],
|
| 284 |
+
[-1.0027, -1.0027, -1.0027, ..., -1.5604, -1.5430, -1.5430],
|
| 285 |
+
[-1.0027, -1.0027, -1.0027, ..., -1.5604, -1.5430, -1.5430]]]),
|
| 286 |
+
'pixel_mask': tensor([[1, 1, 1, ..., 1, 1, 1],
|
| 287 |
+
[1, 1, 1, ..., 1, 1, 1],
|
| 288 |
+
[1, 1, 1, ..., 1, 1, 1],
|
| 289 |
+
...,
|
| 290 |
+
[1, 1, 1, ..., 1, 1, 1],
|
| 291 |
+
[1, 1, 1, ..., 1, 1, 1],
|
| 292 |
+
[1, 1, 1, ..., 1, 1, 1]]),
|
| 293 |
+
'labels': {'size': tensor([800, 800]), 'image_id': tensor([756]), 'class_labels': tensor([4]), 'boxes': tensor([[0.7340, 0.6986, 0.3414, 0.5944]]), 'area': tensor([519544.4375]), 'iscrowd': tensor([0]), 'orig_size': tensor([480, 480])}}
|
| 294 |
+
```
|
| 295 |
+
|
| 296 |
+
個々の画像を正常に拡張し、それらの注釈を準備しました。ただし、前処理はそうではありません。
|
| 297 |
+
まだ完成しています。最後のステップでは、画像をバッチ処理するためのカスタム `collate_fn` を作成します。
|
| 298 |
+
画像 (現在は `pixel_values`) をバッチ内の最大の画像にパディングし、対応する `pixel_mask` を作成します
|
| 299 |
+
どのピクセルが実数 (1) で、どのピクセルがパディング (0) であるかを示します。
|
| 300 |
+
|
| 301 |
+
|
| 302 |
+
```py
|
| 303 |
+
>>> def collate_fn(batch):
|
| 304 |
+
... pixel_values = [item["pixel_values"] for item in batch]
|
| 305 |
+
... encoding = image_processor.pad(pixel_values, return_tensors="pt")
|
| 306 |
+
... labels = [item["labels"] for item in batch]
|
| 307 |
+
... batch = {}
|
| 308 |
+
... batch["pixel_values"] = encoding["pixel_values"]
|
| 309 |
+
... batch["pixel_mask"] = encoding["pixel_mask"]
|
| 310 |
+
... batch["labels"] = labels
|
| 311 |
+
... return batch
|
| 312 |
+
```
|
| 313 |
+
|
| 314 |
+
## Training the DETR model
|
| 315 |
+
|
| 316 |
+
前のセクションで重労働のほとんどを完了したので、モデルをトレーニングする準備が整いました。
|
| 317 |
+
このデータセット内の画像は、サイズを変更した後でも依然として非常に大きいです。これは、このモデルを微調整すると、
|
| 318 |
+
少なくとも 1 つの GPU が必要です。
|
| 319 |
+
|
| 320 |
+
トレーニングには次の手順が含まれます。
|
| 321 |
+
1. 前処理と同じチェックポイントを使用して、[`AutoModelForObjectDetection`] でモデルを読み込みます。
|
| 322 |
+
2. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。
|
| 323 |
+
3. トレーニング引数をモデル、データセット、画像プロセッサ、データ照合器とともに [`Trainer`] に渡します。
|
| 324 |
+
4. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 325 |
+
|
| 326 |
+
前処理に使用したのと同じチェックポイントからモデルをロードするときは、必ず`label2id`を渡してください。
|
| 327 |
+
および `id2label` マップは、以前にデータセットのメタデータから作成したものです。さらに、`ignore_mismatched_sizes=True`を指定して、既存の分類頭部を新しい分類頭部に置き換えます。
|
| 328 |
+
|
| 329 |
+
```py
|
| 330 |
+
>>> from transformers import AutoModelForObjectDetection
|
| 331 |
+
|
| 332 |
+
>>> model = AutoModelForObjectDetection.from_pretrained(
|
| 333 |
+
... checkpoint,
|
| 334 |
+
... id2label=id2label,
|
| 335 |
+
... label2id=label2id,
|
| 336 |
+
... ignore_mismatched_sizes=True,
|
| 337 |
+
... )
|
| 338 |
+
```
|
| 339 |
+
|
| 340 |
+
[`TrainingArguments`] で、`output_dir` を使用してモデルの保存場所を指定し、必要に応じてハイパーパラメーターを構成します。
|
| 341 |
+
画像列が削除されるため、未使用の列を削除しないことが重要です。画像列がないと、
|
| 342 |
+
`pixel_values` を作成できません。このため、`remove_unused_columns`を`False`に設定します。
|
| 343 |
+
ハブにプッシュしてモデルを共有したい場合は、`push_to_hub` を `True` に設定します (Hugging にサインインする必要があります)
|
| 344 |
+
顔に向かってモデルをアップロードします)。
|
| 345 |
+
|
| 346 |
+
```py
|
| 347 |
+
>>> from transformers import TrainingArguments
|
| 348 |
+
|
| 349 |
+
>>> training_args = TrainingArguments(
|
| 350 |
+
... output_dir="detr-resnet-50_finetuned_cppe5",
|
| 351 |
+
... per_device_train_batch_size=8,
|
| 352 |
+
... num_train_epochs=10,
|
| 353 |
+
... fp16=True,
|
| 354 |
+
... save_steps=200,
|
| 355 |
+
... logging_steps=50,
|
| 356 |
+
... learning_rate=1e-5,
|
| 357 |
+
... weight_decay=1e-4,
|
| 358 |
+
... save_total_limit=2,
|
| 359 |
+
... remove_unused_columns=False,
|
| 360 |
+
... push_to_hub=True,
|
| 361 |
+
... )
|
| 362 |
+
```
|
| 363 |
+
|
| 364 |
+
最後に、すべてをまとめて、[`~transformers.Trainer.train`] を呼び出します。
|
| 365 |
+
|
| 366 |
+
```py
|
| 367 |
+
>>> from transformers import Trainer
|
| 368 |
+
|
| 369 |
+
>>> trainer = Trainer(
|
| 370 |
+
... model=model,
|
| 371 |
+
... args=training_args,
|
| 372 |
+
... data_collator=collate_fn,
|
| 373 |
+
... train_dataset=cppe5["train"],
|
| 374 |
+
... processing_class=image_processor,
|
| 375 |
+
... )
|
| 376 |
+
|
| 377 |
+
>>> trainer.train()
|
| 378 |
+
```
|
| 379 |
+
|
| 380 |
+
`training_args`で`push_to_hub`を`True`に設定した場合、トレーニング チェックポイントは
|
| 381 |
+
ハグフェイスハブ。トレーニングが完了したら、[`~transformers.Trainer.push_to_hub`] メソッドを呼び出して、最終モデルもハブにプッシュします。
|
| 382 |
+
|
| 383 |
+
```py
|
| 384 |
+
>>> trainer.push_to_hub()
|
| 385 |
+
```
|
| 386 |
+
|
| 387 |
+
## Evaluate
|
| 388 |
+
|
| 389 |
+
物体検出モデルは通常、一連の <a href="https://cocodataset.org/#detection-eval">COCO スタイルの指標</a>を使用して評価されます。
|
| 390 |
+
既存のメトリクス実装のいずれかを使用できますが、ここでは`torchvision`のメトリクス実装を使用して最終的なメトリクスを評価します。
|
| 391 |
+
ハブにプッシュしたモデル。
|
| 392 |
+
|
| 393 |
+
`torchvision`エバリュエーターを使用するには、グラウンド トゥルース COCO データセットを準備する必要があります。 COCO データセットを構築するための API
|
| 394 |
+
データを特定の形式で保存する必要があるため、最初に画像と注釈をディスクに保存する必要があります。と同じように
|
| 395 |
+
トレーニング用にデータを準備するとき、`cppe5["test"]` からの注釈をフォーマットする必要があります。ただし、画像
|
| 396 |
+
そのままでいるべきです。
|
| 397 |
+
|
| 398 |
+
評価ステップには少し作業が必要ですが、大きく 3 つのステップに分けることができます。
|
| 399 |
+
まず、`cppe5["test"]` セットを準備します。注釈をフォーマットし、データをディスクに保存します。
|
| 400 |
+
|
| 401 |
+
|
| 402 |
+
```py
|
| 403 |
+
>>> import json
|
| 404 |
+
|
| 405 |
+
|
| 406 |
+
>>> # format annotations the same as for training, no need for data augmentation
|
| 407 |
+
>>> def val_formatted_anns(image_id, objects):
|
| 408 |
+
... annotations = []
|
| 409 |
+
... for i in range(0, len(objects["id"])):
|
| 410 |
+
... new_ann = {
|
| 411 |
+
... "id": objects["id"][i],
|
| 412 |
+
... "category_id": objects["category"][i],
|
| 413 |
+
... "iscrowd": 0,
|
| 414 |
+
... "image_id": image_id,
|
| 415 |
+
... "area": objects["area"][i],
|
| 416 |
+
... "bbox": objects["bbox"][i],
|
| 417 |
+
... }
|
| 418 |
+
... annotations.append(new_ann)
|
| 419 |
+
|
| 420 |
+
... return annotations
|
| 421 |
+
|
| 422 |
+
|
| 423 |
+
>>> # Save images and annotations into the files torchvision.datasets.CocoDetection expects
|
| 424 |
+
>>> def save_cppe5_annotation_file_images(cppe5):
|
| 425 |
+
... output_json = {}
|
| 426 |
+
... path_output_cppe5 = f"{os.getcwd()}/cppe5/"
|
| 427 |
+
|
| 428 |
+
... if not os.path.exists(path_output_cppe5):
|
| 429 |
+
... os.makedirs(path_output_cppe5)
|
| 430 |
+
|
| 431 |
+
... path_anno = os.path.join(path_output_cppe5, "cppe5_ann.json")
|
| 432 |
+
... categories_json = [{"supercategory": "none", "id": id, "name": id2label[id]} for id in id2label]
|
| 433 |
+
... output_json["images"] = []
|
| 434 |
+
... output_json["annotations"] = []
|
| 435 |
+
... for example in cppe5:
|
| 436 |
+
... ann = val_formatted_anns(example["image_id"], example["objects"])
|
| 437 |
+
... output_json["images"].append(
|
| 438 |
+
... {
|
| 439 |
+
... "id": example["image_id"],
|
| 440 |
+
... "width": example["image"].width,
|
| 441 |
+
... "height": example["image"].height,
|
| 442 |
+
... "file_name": f"{example['image_id']}.png",
|
| 443 |
+
... }
|
| 444 |
+
... )
|
| 445 |
+
... output_json["annotations"].extend(ann)
|
| 446 |
+
... output_json["categories"] = categories_json
|
| 447 |
+
|
| 448 |
+
... with open(path_anno, "w") as file:
|
| 449 |
+
... json.dump(output_json, file, ensure_ascii=False, indent=4)
|
| 450 |
+
|
| 451 |
+
... for im, img_id in zip(cppe5["image"], cppe5["image_id"]):
|
| 452 |
+
... path_img = os.path.join(path_output_cppe5, f"{img_id}.png")
|
| 453 |
+
... im.save(path_img)
|
| 454 |
+
|
| 455 |
+
... return path_output_cppe5, path_anno
|
| 456 |
+
```
|
| 457 |
+
|
| 458 |
+
次に、`cocoevaluator`で利用できる`CocoDetection`クラスのインスタンスを用意します。
|
| 459 |
+
|
| 460 |
+
|
| 461 |
+
```py
|
| 462 |
+
>>> import torchvision
|
| 463 |
+
|
| 464 |
+
|
| 465 |
+
>>> class CocoDetection(torchvision.datasets.CocoDetection):
|
| 466 |
+
... def __init__(self, img_folder, image_processor, ann_file):
|
| 467 |
+
... super().__init__(img_folder, ann_file)
|
| 468 |
+
... self.image_processor = image_processor
|
| 469 |
+
|
| 470 |
+
... def __getitem__(self, idx):
|
| 471 |
+
... # read in PIL image and target in COCO format
|
| 472 |
+
... img, target = super(CocoDetection, self).__getitem__(idx)
|
| 473 |
+
|
| 474 |
+
... # preprocess image and target: converting target to DETR format,
|
| 475 |
+
... # resizing + normalization of both image and target)
|
| 476 |
+
... image_id = self.ids[idx]
|
| 477 |
+
... target = {"image_id": image_id, "annotations": target}
|
| 478 |
+
... encoding = self.image_processor(images=img, annotations=target, return_tensors="pt")
|
| 479 |
+
... pixel_values = encoding["pixel_values"].squeeze() # remove batch dimension
|
| 480 |
+
... target = encoding["labels"][0] # remove batch dimension
|
| 481 |
+
|
| 482 |
+
... return {"pixel_values": pixel_values, "labels": target}
|
| 483 |
+
|
| 484 |
+
|
| 485 |
+
>>> im_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
|
| 486 |
+
|
| 487 |
+
>>> path_output_cppe5, path_anno = save_cppe5_annotation_file_images(cppe5["test"])
|
| 488 |
+
>>> test_ds_coco_format = CocoDetection(path_output_cppe5, im_processor, path_anno)
|
| 489 |
+
```
|
| 490 |
+
|
| 491 |
+
最後に、メトリクスをロードして評価を実行します。
|
| 492 |
+
|
| 493 |
+
```py
|
| 494 |
+
>>> import evaluate
|
| 495 |
+
>>> from tqdm import tqdm
|
| 496 |
+
|
| 497 |
+
>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
|
| 498 |
+
>>> module = evaluate.load("ybelkada/cocoevaluate", coco=test_ds_coco_format.coco)
|
| 499 |
+
>>> val_dataloader = torch.utils.data.DataLoader(
|
| 500 |
+
... test_ds_coco_format, batch_size=8, shuffle=False, num_workers=4, collate_fn=collate_fn
|
| 501 |
+
... )
|
| 502 |
+
|
| 503 |
+
>>> with torch.no_grad():
|
| 504 |
+
... for idx, batch in enumerate(tqdm(val_dataloader)):
|
| 505 |
+
... pixel_values = batch["pixel_values"]
|
| 506 |
+
... pixel_mask = batch["pixel_mask"]
|
| 507 |
+
|
| 508 |
+
... labels = [
|
| 509 |
+
... {k: v for k, v in t.items()} for t in batch["labels"]
|
| 510 |
+
... ] # these are in DETR format, resized + normalized
|
| 511 |
+
|
| 512 |
+
... # forward pass
|
| 513 |
+
... outputs = model(pixel_values=pixel_values, pixel_mask=pixel_mask)
|
| 514 |
+
|
| 515 |
+
... orig_target_sizes = torch.stack([target["orig_size"] for target in labels], dim=0)
|
| 516 |
+
... results = im_processor.post_process(outputs, orig_target_sizes) # convert outputs of model to Pascal VOC format (xmin, ymin, xmax, ymax)
|
| 517 |
+
|
| 518 |
+
... module.add(prediction=results, reference=labels)
|
| 519 |
+
... del batch
|
| 520 |
+
|
| 521 |
+
>>> results = module.compute()
|
| 522 |
+
>>> print(results)
|
| 523 |
+
Accumulating evaluation results...
|
| 524 |
+
DONE (t=0.08s).
|
| 525 |
+
IoU metric: bbox
|
| 526 |
+
Average Precision (AP) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.352
|
| 527 |
+
Average Precision (AP) @[ IoU=0.50 | area= all | maxDets=100 ] = 0.681
|
| 528 |
+
Average Precision (AP) @[ IoU=0.75 | area= all | maxDets=100 ] = 0.292
|
| 529 |
+
Average Precision (AP) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.168
|
| 530 |
+
Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.208
|
| 531 |
+
Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.429
|
| 532 |
+
Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 1 ] = 0.274
|
| 533 |
+
Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 10 ] = 0.484
|
| 534 |
+
Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.501
|
| 535 |
+
Average Recall (AR) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.191
|
| 536 |
+
Average Recall (AR) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.323
|
| 537 |
+
Average Recall (AR) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.590
|
| 538 |
+
```
|
| 539 |
+
|
| 540 |
+
これらの結果は、[`~transformers.TrainingArguments`] のハイパーパラメータを調整することでさらに改善できます。試してごらん!
|
| 541 |
+
|
| 542 |
+
## Inference
|
| 543 |
+
|
| 544 |
+
DETR モデルを微調整して評価し、Hugging Face Hub にアップロードしたので、それを推論に使用できます。
|
| 545 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。パイプラインをインスタンス化する
|
| 546 |
+
モデルを使用してオブジェクトを検出し、それに画像を渡します。
|
| 547 |
+
|
| 548 |
+
|
| 549 |
+
```py
|
| 550 |
+
>>> from transformers import pipeline
|
| 551 |
+
>>> import requests
|
| 552 |
+
|
| 553 |
+
>>> url = "https://i.imgur.com/2lnWoly.jpg"
|
| 554 |
+
>>> image = Image.open(requests.get(url, stream=True).raw)
|
| 555 |
+
|
| 556 |
+
>>> obj_detector = pipeline("object-detection", model="devonho/detr-resnet-50_finetuned_cppe5")
|
| 557 |
+
>>> obj_detector(image)
|
| 558 |
+
```
|
| 559 |
+
|
| 560 |
+
必要に応じて、パイプラインの結果を手動で複製することもできます。
|
| 561 |
+
|
| 562 |
+
```py
|
| 563 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
|
| 564 |
+
>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
|
| 565 |
+
|
| 566 |
+
>>> with torch.no_grad():
|
| 567 |
+
... inputs = image_processor(images=image, return_tensors="pt")
|
| 568 |
+
... outputs = model(**inputs)
|
| 569 |
+
... target_sizes = torch.tensor([image.size[::-1]])
|
| 570 |
+
... results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[0]
|
| 571 |
+
|
| 572 |
+
>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
|
| 573 |
+
... box = [round(i, 2) for i in box.tolist()]
|
| 574 |
+
... print(
|
| 575 |
+
... f"Detected {model.config.id2label[label.item()]} with confidence "
|
| 576 |
+
... f"{round(score.item(), 3)} at location {box}"
|
| 577 |
+
... )
|
| 578 |
+
Detected Coverall with confidence 0.566 at location [1215.32, 147.38, 4401.81, 3227.08]
|
| 579 |
+
Detected Mask with confidence 0.584 at location [2449.06, 823.19, 3256.43, 1413.9]
|
| 580 |
+
```
|
| 581 |
+
|
| 582 |
+
結果をプロットしてみましょう:
|
| 583 |
+
|
| 584 |
+
```py
|
| 585 |
+
>>> draw = ImageDraw.Draw(image)
|
| 586 |
+
|
| 587 |
+
>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
|
| 588 |
+
... box = [round(i, 2) for i in box.tolist()]
|
| 589 |
+
... x, y, x2, y2 = tuple(box)
|
| 590 |
+
... draw.rectangle((x, y, x2, y2), outline="red", width=1)
|
| 591 |
+
... draw.text((x, y), model.config.id2label[label.item()], fill="white")
|
| 592 |
+
|
| 593 |
+
>>> image
|
| 594 |
+
```
|
| 595 |
+
|
| 596 |
+
<div class="flex justify-center">
|
| 597 |
+
<img src="https://i.imgur.com/4QZnf9A.png" alt="Object detection result on a new image"/>
|
| 598 |
+
</div>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/prompting.md
ADDED
|
@@ -0,0 +1,438 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
# LLM prompting guide
|
| 19 |
+
|
| 20 |
+
[[open-in-colab]]
|
| 21 |
+
|
| 22 |
+
Falcon、LLaMA などの大規模言語モデルは、事前にトレーニングされたトランスフォーマー モデルであり、最初は予測するようにトレーニングされています。
|
| 23 |
+
入力テキストが与えられた場合の次のトークン。通常、数十億のパラメータがあり、何兆ものパラメータでトレーニングされています。
|
| 24 |
+
長期間のトークン。その結果、これらのモデルは非常に強力で多用途になり、次のようなことが可能になります。
|
| 25 |
+
自然言語プロンプトでモデルに指示することで、すぐに複数の NLP タスクを解決できます。
|
| 26 |
+
|
| 27 |
+
最適な出力を保証するためにこのようなプロンプトを設計することは、多くの場合「プロンプト エンジニアリング」と呼ばれます。プロンプトエンジニアリングとは、
|
| 28 |
+
かなりの量の実験を必要とする反復プロセス。自然言語ははるかに柔軟で表現力豊かです
|
| 29 |
+
ただし、プログラミング言語よりもあいまいさが生じる可能性があります。同時に、自然言語によるプロンプト
|
| 30 |
+
変化にはかなり敏感です。プロンプトにわずかな変更を加えただけでも、出力が大幅に異なる場合があります。
|
| 31 |
+
|
| 32 |
+
すべてのケースに適合するプロンプトを作成するための正確なレシピはありませんが、研究者はいくつかの最良のレシピを考案しました。
|
| 33 |
+
最適な結果をより一貫して達成するのに役立つ実践。
|
| 34 |
+
|
| 35 |
+
このガイドでは、より優れた LLM プロンプトを作成し、さまざまな NLP タスクを解決するのに役立つプロンプト エンジニアリングのベスト プラクティスについて説明します。
|
| 36 |
+
次のことを学びます:
|
| 37 |
+
|
| 38 |
+
- [プロンプトの基本](#basics-of-prompting)
|
| 39 |
+
- [LLM プロンプトのベスト プラクティス](#best-practices-of-llm-prompting)
|
| 40 |
+
- [高度なプロンプト テクニック: 数回のプロンプトと思考の連鎖](#advanced-prompting-techniques)
|
| 41 |
+
- [プロンプトを表示する代わりに微調整する場合](#prompting-vs-fine-tuning)
|
| 42 |
+
|
| 43 |
+
<Tip>
|
| 44 |
+
|
| 45 |
+
迅速なエンジニアリングは、LLM 出力最適化プロセスの一部にすぎません。もう 1 つの重要な要素は、
|
| 46 |
+
最適なテキスト生成戦略。 LLM が生成時に後続の各トークンを選択する方法をカスタマイズできます。
|
| 47 |
+
トレーニング可能なパラメータを一切変更せずにテキストを作成します。テキスト生成パラメータを微調整することで、
|
| 48 |
+
生成されたテキストに繰り返しが含まれているため、より一貫性があり人間らしい響きになります。
|
| 49 |
+
テキスト生成戦略とパラメーターはこのガイドの範囲外ですが、これらのトピックについて詳しくは、次のトピックを参照してください。
|
| 50 |
+
次のガイド:
|
| 51 |
+
|
| 52 |
+
* [LLM による生成](../llm_tutorial)
|
| 53 |
+
* [テキスト生成戦略](../generation_strategies)
|
| 54 |
+
|
| 55 |
+
</Tip>
|
| 56 |
+
|
| 57 |
+
## Basics of prompting
|
| 58 |
+
|
| 59 |
+
### Types of models
|
| 60 |
+
|
| 61 |
+
最新の LLM の大部分は、デコーダ専用のトランスフォーマーです。例としては、[LLaMA](../model_doc/llama)、
|
| 62 |
+
[Llama2](../model_doc/llama2)、[Falcon](../model_doc/falcon)、[GPT2](../model_doc/gpt2)。ただし、遭遇する可能性があります
|
| 63 |
+
エンコーダ デコーダ トランスフォーマ LLM も同様です。たとえば、[Flan-T5](../model_doc/flan-t5) や [BART](../model_doc/bart) です。
|
| 64 |
+
|
| 65 |
+
エンコーダ デコーダ スタイルのモデルは通常、出力が入力に**大きく**依存する生成タスクで使用されます。
|
| 66 |
+
たとえば、翻訳と要約です。デコーダ専用モデルは、他のすべてのタイプの生成タスクに使用されます。
|
| 67 |
+
|
| 68 |
+
パイプラインを使用して LLM でテキストを生成する場合、使用している LLM のタイプを知ることが重要です。
|
| 69 |
+
異なるパイプラインを使用します。
|
| 70 |
+
|
| 71 |
+
`text-generation`パイプラインを使用してデコーダのみのモデルで推論を実行します。
|
| 72 |
+
|
| 73 |
+
```python
|
| 74 |
+
>>> from transformers import pipeline
|
| 75 |
+
>>> import torch
|
| 76 |
+
|
| 77 |
+
>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
|
| 78 |
+
|
| 79 |
+
>>> generator = pipeline('text-generation', model = 'openai-community/gpt2')
|
| 80 |
+
>>> prompt = "Hello, I'm a language model"
|
| 81 |
+
|
| 82 |
+
>>> generator(prompt, max_length = 30)
|
| 83 |
+
[{'generated_text': "Hello, I'm a language model expert, so I'm a big believer in the concept that I know very well and then I try to look into"}]
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
エンコーダー/デコーダーを使用して推論を実行するには、`text2text-generation` パイプラインを使用します。
|
| 87 |
+
|
| 88 |
+
```python
|
| 89 |
+
>>> text2text_generator = pipeline("text2text-generation", model = 'google/flan-t5-base')
|
| 90 |
+
>>> prompt = "Translate from English to French: I'm very happy to see you"
|
| 91 |
+
|
| 92 |
+
>>> text2text_generator(prompt)
|
| 93 |
+
[{'generated_text': 'Je suis très heureuse de vous rencontrer.'}]
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
### Base vs instruct/chat models
|
| 97 |
+
|
| 98 |
+
🤗 Hub で利用できる最近の LLM チェックポイントのほとんどには、base と instruct (または chat) の 2 つのバージョンがあります。例えば、
|
| 99 |
+
[`tiiuae/falcon-7b`](https://huggingface.co/tiiuae/falcon-7b) および [`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b) -指示する)。
|
| 100 |
+
|
| 101 |
+
基本モデルは、最初のプロンプトが与えられたときにテキストを完成させるのには優れていますが、NLP タスクには理想的ではありません。
|
| 102 |
+
指示に従う必要がある場合、または会話で使用する場合に使用します。ここで、指示 (チャット) バージョンが登場します。
|
| 103 |
+
これらのチェックポイントは、命令と会話データに基づいて事前トレーニングされたベース バージョンをさらに微調整した結果です。
|
| 104 |
+
この追加の微調整により、多くの NLP タスクにとってより適切な選択肢になります。
|
| 105 |
+
|
| 106 |
+
[`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct) で使用できるいくつかの簡単なプロンプトを示してみましょう。
|
| 107 |
+
いくつかの一般的な NLP タスクを解決します。
|
| 108 |
+
|
| 109 |
+
### NLP tasks
|
| 110 |
+
|
| 111 |
+
まず、環境をセットアップしましょう。
|
| 112 |
+
|
| 113 |
+
```bash
|
| 114 |
+
pip install -q transformers accelerate
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
次に、適切なパイプライン (`text_generation`) を使用してモデルをロードしましょう。
|
| 118 |
+
|
| 119 |
+
```python
|
| 120 |
+
>>> from transformers import pipeline, AutoTokenizer
|
| 121 |
+
>>> import torch
|
| 122 |
+
|
| 123 |
+
>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
|
| 124 |
+
>>> model = "tiiuae/falcon-7b-instruct"
|
| 125 |
+
|
| 126 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(model)
|
| 127 |
+
>>> pipe = pipeline(
|
| 128 |
+
... "text-generation",
|
| 129 |
+
... model=model,
|
| 130 |
+
... tokenizer=tokenizer,
|
| 131 |
+
... torch_dtype=torch.bfloat16,
|
| 132 |
+
... device_map="auto",
|
| 133 |
+
... )
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
<Tip>
|
| 137 |
+
|
| 138 |
+
Falcon モデルは `bfloat16` データ型を使用してトレーニングされたため、同じものを使用することをお勧めします。これには、最近の
|
| 139 |
+
CUDA のバージョンに準拠しており、最新のカードで最適に動作します。
|
| 140 |
+
|
| 141 |
+
</Tip>
|
| 142 |
+
|
| 143 |
+
パイプライン経由でモデルをロードしたので、プロンプトを使用して NLP タスクを解決する方法を見てみましょう。
|
| 144 |
+
|
| 145 |
+
#### Text classification
|
| 146 |
+
|
| 147 |
+
テキスト分類の最も一般的な形式の 1 つはセンチメント分析であり、「ポジティブ」、「ネガティブ」、「ネガティブ」などのラベルを割り当てます。
|
| 148 |
+
または、一連のテキストに対して「中立」です。与えられたテキスト (映画レビュー) を分類するようにモデルに指示するプロンプトを作成してみましょう。
|
| 149 |
+
まず指示を与え、次に分類するテキストを指定します。そのままにしておくのではなく、
|
| 150 |
+
応答の先頭にも追加します - `"Sentiment: "`:
|
| 151 |
+
|
| 152 |
+
```python
|
| 153 |
+
>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
|
| 154 |
+
>>> prompt = """Classify the text into neutral, negative or positive.
|
| 155 |
+
... Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
|
| 156 |
+
... Sentiment:
|
| 157 |
+
... """
|
| 158 |
+
|
| 159 |
+
>>> sequences = pipe(
|
| 160 |
+
... prompt,
|
| 161 |
+
... max_new_tokens=10,
|
| 162 |
+
... )
|
| 163 |
+
|
| 164 |
+
>>> for seq in sequences:
|
| 165 |
+
... print(f"Result: {seq['generated_text']}")
|
| 166 |
+
Result: Classify the text into neutral, negative or positive.
|
| 167 |
+
Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
|
| 168 |
+
Sentiment:
|
| 169 |
+
Positive
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
その結果、出力には、手順で提供したリストの分類ラベルが含まれており、それは正しいラベルです。
|
| 173 |
+
|
| 174 |
+
<Tip>
|
| 175 |
+
|
| 176 |
+
プロンプトに加えて、`max_new_tokens`パラメータを渡していることに気づくかもしれません。トークンの数を制御します。
|
| 177 |
+
モデルが生成します。これは、学習できる多くのテキスト生成パラメーターの 1 つです。
|
| 178 |
+
[��キスト生成戦略](../generation_strategies) ガイドを参照してください。
|
| 179 |
+
|
| 180 |
+
</Tip>
|
| 181 |
+
|
| 182 |
+
#### Named Entity Recognition
|
| 183 |
+
|
| 184 |
+
固有表現認識 (NER) は、テキスト内の人物、場所、組織などの固有表現を検索するタスクです。
|
| 185 |
+
プロンプトの指示を変更して、LLM にこのタスクを実行させましょう。ここでは`return_full_text = False`も設定しましょう
|
| 186 |
+
出力にプロンプトが含まれないようにします。
|
| 187 |
+
|
| 188 |
+
```python
|
| 189 |
+
>>> torch.manual_seed(1) # doctest: +IGNORE_RESULT
|
| 190 |
+
>>> prompt = """Return a list of named entities in the text.
|
| 191 |
+
... Text: The Golden State Warriors are an American professional basketball team based in San Francisco.
|
| 192 |
+
... Named entities:
|
| 193 |
+
... """
|
| 194 |
+
|
| 195 |
+
>>> sequences = pipe(
|
| 196 |
+
... prompt,
|
| 197 |
+
... max_new_tokens=15,
|
| 198 |
+
... return_full_text = False,
|
| 199 |
+
... )
|
| 200 |
+
|
| 201 |
+
>>> for seq in sequences:
|
| 202 |
+
... print(f"{seq['generated_text']}")
|
| 203 |
+
- Golden State Warriors
|
| 204 |
+
- San Francisco
|
| 205 |
+
```
|
| 206 |
+
|
| 207 |
+
ご覧のとおり、モデルは指定されたテキストから 2 つの名前付きエンティティを正しく識別しました。
|
| 208 |
+
|
| 209 |
+
#### Translation
|
| 210 |
+
|
| 211 |
+
LLM が実行できるもう 1 つのタスクは翻訳です。このタスクにはエンコーダー/デコーダー モデルを使用することを選択できますが、ここでは
|
| 212 |
+
例を簡単にするために、きちんとした仕事をする Falcon-7b-instruct を使い続けます。もう一度、方法は次のとおりです
|
| 213 |
+
テキストの一部を英語からイタリア語に翻訳するようにモデルに指示する基本的なプロンプトを作成できます。
|
| 214 |
+
|
| 215 |
+
```python
|
| 216 |
+
>>> torch.manual_seed(2) # doctest: +IGNORE_RESULT
|
| 217 |
+
>>> prompt = """Translate the English text to Italian.
|
| 218 |
+
... Text: Sometimes, I've believed as many as six impossible things before breakfast.
|
| 219 |
+
... Translation:
|
| 220 |
+
... """
|
| 221 |
+
|
| 222 |
+
>>> sequences = pipe(
|
| 223 |
+
... prompt,
|
| 224 |
+
... max_new_tokens=20,
|
| 225 |
+
... do_sample=True,
|
| 226 |
+
... top_k=10,
|
| 227 |
+
... return_full_text = False,
|
| 228 |
+
... )
|
| 229 |
+
|
| 230 |
+
>>> for seq in sequences:
|
| 231 |
+
... print(f"{seq['generated_text']}")
|
| 232 |
+
A volte, ho creduto a sei impossibili cose prima di colazione.
|
| 233 |
+
```
|
| 234 |
+
|
| 235 |
+
ここでは、出力生成時にモデルがもう少し柔軟になるように `do_sample=True` と `top_k=10` を追加しました。
|
| 236 |
+
|
| 237 |
+
#### Text summarization
|
| 238 |
+
|
| 239 |
+
翻訳と同様に、テキストの要約も、出力が入力に**大きく**依存する生成タスクです。
|
| 240 |
+
エンコーダ/デコーダ モデルの方が良い選択になる可能性があります。ただし、デコーダ スタイルのモデルもこのタスクに使用できます。
|
| 241 |
+
以前は、プロンプトの先頭に指示を配置していました。ただし、プロンプトの最後で、
|
| 242 |
+
指示を与えるのに適した場所でもあります。通常、命令はどちらかの端に配置することをお勧めします。
|
| 243 |
+
|
| 244 |
+
```python
|
| 245 |
+
>>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
|
| 246 |
+
>>> prompt = """Permaculture is a design process mimicking the diversity, functionality and resilience of natural ecosystems. The principles and practices are drawn from traditional ecological knowledge of indigenous cultures combined with modern scientific understanding and technological innovations. Permaculture design provides a framework helping individuals and communities develop innovative, creative and effective strategies for meeting basic needs while preparing for and mitigating the projected impacts of climate change.
|
| 247 |
+
... Write a summary of the above text.
|
| 248 |
+
... Summary:
|
| 249 |
+
... """
|
| 250 |
+
|
| 251 |
+
>>> sequences = pipe(
|
| 252 |
+
... prompt,
|
| 253 |
+
... max_new_tokens=30,
|
| 254 |
+
... do_sample=True,
|
| 255 |
+
... top_k=10,
|
| 256 |
+
... return_full_text = False,
|
| 257 |
+
... )
|
| 258 |
+
|
| 259 |
+
>>> for seq in sequences:
|
| 260 |
+
... print(f"{seq['generated_text']}")
|
| 261 |
+
Permaculture is an ecological design mimicking natural ecosystems to meet basic needs and prepare for climate change. It is based on traditional knowledge and scientific understanding.
|
| 262 |
+
```
|
| 263 |
+
|
| 264 |
+
#### Question answering
|
| 265 |
+
|
| 266 |
+
質問応答タスクの場合、プロンプトを次の論理コンポーネントに構造化できます: 指示、コンテキスト、質問、
|
| 267 |
+
先頭の単語またはフレーズ (`"Answer:"`) を使用して、モデルを操作して答えの生成を開始します。
|
| 268 |
+
|
| 269 |
+
|
| 270 |
+
```python
|
| 271 |
+
>>> torch.manual_seed(4) # doctest: +IGNORE_RESULT
|
| 272 |
+
>>> prompt = """Answer the question using the context below.
|
| 273 |
+
... Context: Gazpacho is a cold soup and drink made of raw, blended vegetables. Most gazpacho includes stale bread, tomato, cucumbers, onion, bell peppers, garlic, olive oil, wine vinegar, water, and salt. Northern recipes often include cumin and/or pimentón (smoked sweet paprika). Traditionally, gazpacho was made by pounding the vegetables in a mortar with a pestle; this more laborious method is still sometimes used as it helps keep the gazpacho cool and avoids the foam and silky consistency of smoothie versions made in blenders or food processors.
|
| 274 |
+
... Question: What modern tool is used to make gazpacho?
|
| 275 |
+
... Answer:
|
| 276 |
+
... """
|
| 277 |
+
|
| 278 |
+
>>> sequences = pipe(
|
| 279 |
+
... prompt,
|
| 280 |
+
... max_new_tokens=10,
|
| 281 |
+
... do_sample=True,
|
| 282 |
+
... top_k=10,
|
| 283 |
+
... return_full_text = False,
|
| 284 |
+
... )
|
| 285 |
+
|
| 286 |
+
>>> for seq in sequences:
|
| 287 |
+
... print(f"Result: {seq['generated_text']}")
|
| 288 |
+
Result: Modern tools are used, such as immersion blenders
|
| 289 |
+
```
|
| 290 |
+
|
| 291 |
+
#### Reasoning
|
| 292 |
+
|
| 293 |
+
LLM にとって推論は最も困難なタスクの 1 つであり、良い結果を達成するには、多くの場合、次のような高度なプロンプト テクニックを適用する必要があります。
|
| 294 |
+
[Chain-of-thought](#chain-of-thought)。
|
| 295 |
+
|
| 296 |
+
基本的なプロンプトを使用して、単純な算術タスクに関するモデル推論を作成できるかどうか試してみましょう。
|
| 297 |
+
|
| 298 |
+
```python
|
| 299 |
+
>>> torch.manual_seed(5) # doctest: +IGNORE_RESULT
|
| 300 |
+
>>> prompt = """There are 5 groups of students in the class. Each group has 4 students. How many students are there in the class?"""
|
| 301 |
+
|
| 302 |
+
>>> sequences = pipe(
|
| 303 |
+
... prompt,
|
| 304 |
+
... max_new_tokens=30,
|
| 305 |
+
... do_sample=True,
|
| 306 |
+
... top_k=10,
|
| 307 |
+
... return_full_text = False,
|
| 308 |
+
... )
|
| 309 |
+
|
| 310 |
+
>>> for seq in sequences:
|
| 311 |
+
... print(f"Result: {seq['generated_text']}")
|
| 312 |
+
Result:
|
| 313 |
+
There are a total of 5 groups, so there are 5 x 4=20 students in the class.
|
| 314 |
+
```
|
| 315 |
+
|
| 316 |
+
正しい!もう少し複雑さを増やして、基本的なプロンプトで問題を解決できるかどうかを確認してみましょう。
|
| 317 |
+
|
| 318 |
+
```python
|
| 319 |
+
>>> torch.manual_seed(6) # doctest: +IGNORE_RESULT
|
| 320 |
+
>>> prompt = """I baked 15 muffins. I ate 2 muffins and gave 5 muffins to a neighbor. My partner then bought 6 more muffins and ate 2. How many muffins do we now have?"""
|
| 321 |
+
|
| 322 |
+
>>> sequences = pipe(
|
| 323 |
+
... prompt,
|
| 324 |
+
... max_new_tokens=10,
|
| 325 |
+
... do_sample=True,
|
| 326 |
+
... top_k=10,
|
| 327 |
+
... return_full_text = False,
|
| 328 |
+
... )
|
| 329 |
+
|
| 330 |
+
>>> for seq in sequences:
|
| 331 |
+
... print(f"Result: {seq['generated_text']}")
|
| 332 |
+
Result:
|
| 333 |
+
The total number of muffins now is 21
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
これは間違った答えです。12 である必要があります。この場合、プロンプトが基本的すぎるか、選択内容が原因である可能性があります。
|
| 337 |
+
結局のところ、Falcon の最小バージョンを選択しました。あらゆるサイズのモデルでは推論が困難ですが、より大きなモデルでは
|
| 338 |
+
モデルのパフォーマンスが向上する可能性があります。
|
| 339 |
+
|
| 340 |
+
## Best practices of LLM prompting
|
| 341 |
+
|
| 342 |
+
ガイドのこのセクションでは、プロンプトの結果を改善する傾向にあるベスト プラクティスのリストをまとめました。
|
| 343 |
+
|
| 344 |
+
* 使用するモデルを選択する場合は、最新かつ最も機能的なモデルの方がパフォーマンスが向上する可能性があります。
|
| 345 |
+
* シンプルで短いプロンプトから始めて、そこから繰り返します。
|
| 346 |
+
* 指示はプロンプトの最初または最後に入力してください。大規模なコンテキストを扱う場合、モデルはさまざまな最適化を適用して、アテンションの複雑さが二次的に拡大するのを防ぎます。これにより、モデルはプロンプトの途中よりも最初または最後に注意を払うようになります。
|
| 347 |
+
* 指示と、それが適用されるテキストを明確に区別してください。これについては、次のセクションで詳しく説明します。
|
| 348 |
+
* タスクと望ましい結果 (その形式、長さ、スタイル、言語など) について具体的かつ説明的にします。
|
| 349 |
+
* 曖昧な説明や指示は避けてください。
|
| 350 |
+
*「何をしてはいけないか」という指示ではなく、「何をすべきか」という指示を優先します。
|
| 351 |
+
* 最初の単語を書いて (またはモデルの最初の文を始めて)、出力を正しい方向に「導き」ます。
|
| 352 |
+
* [Few-shot prompting](#few-shot-prompting) や [Chain-of-thought](#chain-of-thought) などの高度なテクニックを使用します。
|
| 353 |
+
* さまざまなモデルでプロンプトをテストして、その堅牢性を評価します。
|
| 354 |
+
* プロンプトのバージョンを確認し、パフォーマンスを追跡します。
|
| 355 |
+
|
| 356 |
+
## Advanced prompting techniques
|
| 357 |
+
|
| 358 |
+
### Few-shot prompting
|
| 359 |
+
|
| 360 |
+
上記のセクションの基本的なプロンプトは、「ゼロショット」プロンプトの例です。つまり、モデルにはすでに与えられています。
|
| 361 |
+
指示とコンテキストはありますが、解決策を含む例はありません。通常、命令データセットに基づいて微調整された LLM
|
| 362 |
+
このような「ゼロショット」タスクでも優れたパフォーマンスを発揮します。ただし、タスクがより複雑であったり微妙な点があったりする場合があります。
|
| 363 |
+
出力には、命令だけではモデルが理解できないいくつかの要件があります。この場合、次のことができます。
|
| 364 |
+
少数ショット プロンプトと呼ばれるテクニックを試してください。
|
| 365 |
+
|
| 366 |
+
少数ショット プロンプトでは、モデルにパフォーマンスを向上させるためのより多くのコンテキストを提供するプロンプト内の例が提供されます。
|
| 367 |
+
例では、例のパターンに従って出力を生成するようにモデルを条件付けします。
|
| 368 |
+
|
| 369 |
+
以下に例を示します。
|
| 370 |
+
|
| 371 |
+
```python
|
| 372 |
+
>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
|
| 373 |
+
>>> prompt = """Text: The first human went into space and orbited the Earth on April 12, 1961.
|
| 374 |
+
... Date: 04/12/1961
|
| 375 |
+
... Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
|
| 376 |
+
... Date:"""
|
| 377 |
+
|
| 378 |
+
>>> sequences = pipe(
|
| 379 |
+
... prompt,
|
| 380 |
+
... max_new_tokens=8,
|
| 381 |
+
... do_sample=True,
|
| 382 |
+
... top_k=10,
|
| 383 |
+
... )
|
| 384 |
+
|
| 385 |
+
>>> for seq in sequences:
|
| 386 |
+
... print(f"Result: {seq['generated_text']}")
|
| 387 |
+
Result: Text: The first human went into space and orbited the Earth on April 12, 1961.
|
| 388 |
+
Date: 04/12/1961
|
| 389 |
+
Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
|
| 390 |
+
Date: 09/28/1960
|
| 391 |
+
```
|
| 392 |
+
|
| 393 |
+
上記のコード スニペットでは、モデルへの目的の出力を示すために 1 つの例を使用しました。したがって、これは、
|
| 394 |
+
「ワンショット」プロンプト。ただし、タスクの複雑さに応じて、複数の例を使用する必要がある場合があります。
|
| 395 |
+
|
| 396 |
+
数回のプロンプト手法の制限:
|
| 397 |
+
- LLM は例のパターンを理解できますが、これらの手法は複雑な推論タスクではうまく機能しません。
|
| 398 |
+
- 少数ショットのプロンプトでは、長いプロンプトを作成する必要があります。大量のトークンを含むプロンプトでは、計算量と待ち時間が増加する可能性があります。プロンプトの長さにも制限があります。
|
| 399 |
+
- 多くの例を与えると、モデルが学習するつもりのなかったパターンを学習することがあります。 3番目の映画レビューはいつも否定的だということ。
|
| 400 |
+
|
| 401 |
+
### Chain-of-thought
|
| 402 |
+
|
| 403 |
+
思考連鎖 (CoT) プロンプトは、モデルを微調整して中間推論ステップを生成し、改善する手法です。
|
| 404 |
+
複雑な推論タスクの結果。
|
| 405 |
+
|
| 406 |
+
モデルを操作して推論ステップを生成するには、2 つの方法があります。
|
| 407 |
+
- 質問に対する詳細な回答を含む例を示し、問題に対処する方法をモデルに示すことで、数回のプロンプトを表示します。
|
| 408 |
+
- 「ステップごとに考えてみましょう」または「深呼吸して、問題をステップごとに解決してください」などのフレーズを追加してモデルに推論を指示します。
|
| 409 |
+
|
| 410 |
+
[推論セクション](#reasoning) のマフィンの例に CoT テクニックを適用し、より大きなモデルを使用すると、
|
| 411 |
+
[HuggingChat](https://huggingface.co/chat/)で遊べる(`tiiuae/falcon-180B-chat`)など、
|
| 412 |
+
推論結果は大幅に改善されます。
|
| 413 |
+
|
| 414 |
+
```text
|
| 415 |
+
Let's go through this step-by-step:
|
| 416 |
+
1. You start with 15 muffins.
|
| 417 |
+
2. You eat 2 muffins, leaving you with 13 muffins.
|
| 418 |
+
3. You give 5 muffins to your neighbor, leaving you with 8 muffins.
|
| 419 |
+
4. Your partner buys 6 more muffins, bringing the total number of muffins to 14.
|
| 420 |
+
5. Your partner eats 2 muffins, leaving you with 12 muffins.
|
| 421 |
+
Therefore, you now have 12 muffins.
|
| 422 |
+
```
|
| 423 |
+
|
| 424 |
+
## Prompting vs fine-tuning
|
| 425 |
+
|
| 426 |
+
プロンプトを最適化することで優れた結果を達成できますが、モデルを微調整するかどうかについてはまだ思案するかもしれません。
|
| 427 |
+
あなたの場合にはもっとうまくいくでしょう。より小規模なモデルを微調整することが好ましいオプションである場合のいくつかのシナリオを次に示します。
|
| 428 |
+
|
| 429 |
+
- ドメインが LLM が事前にトレーニングされたものと大きく異なっており、広範なプロンプト最適化では十分な結果が得られませんでした。
|
| 430 |
+
- モデルが低リソース言語で適切に動作する必要があります。
|
| 431 |
+
- 厳格な規制の下にある機密データでモデルをトレーニングする必要があります。
|
| 432 |
+
- コスト、プライバシー、インフラストラクチャ、またはその他の制限により、小規模なモデルを使用する必要があります。
|
| 433 |
+
|
| 434 |
+
上記のすべての例で、十分な大きさのファイルをすでに持っているか、簡単に入手できるかを確認する必要があります。
|
| 435 |
+
ドメイン固有のデータセットを合理的なコストでモデルを微調整できます。十分な時間とリソースも必要になります
|
| 436 |
+
モデルを微調整します。
|
| 437 |
+
|
| 438 |
+
上記の例が当てはまらない場合は、プロンプトを最適化する方が有益であることがわかります。
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/question_answering.md
ADDED
|
@@ -0,0 +1,438 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Question answering
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="ajPx5LwJD-I"/>
|
| 22 |
+
|
| 23 |
+
質問応答タスクは、質問に対して回答を返します。 Alexa、Siri、Google などの仮想アシスタントに天気を尋ねたことがあるなら、質問応答モデルを使用したことがあるはずです。質問応答タスクには一般的に 2 つのタイプがあります。
|
| 24 |
+
|
| 25 |
+
- 抽出: 与えられたコンテキストから回答を抽出します。
|
| 26 |
+
- 抽象的: 質問に正しく答えるコンテキストから回答を生成します。
|
| 27 |
+
|
| 28 |
+
このガイドでは、次の方法を説明します。
|
| 29 |
+
|
| 30 |
+
1. 抽出的質問応答用に [SQuAD](https://huggingface.co/datasets/squad) データセット上の [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) を微調整します。
|
| 31 |
+
2. 微調整したモデルを推論に使用します。
|
| 32 |
+
|
| 33 |
+
<Tip>
|
| 34 |
+
|
| 35 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/question-answering) を確認することをお勧めします。
|
| 36 |
+
|
| 37 |
+
</Tip>
|
| 38 |
+
|
| 39 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install transformers datasets evaluate
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 46 |
+
|
| 47 |
+
```py
|
| 48 |
+
>>> from huggingface_hub import notebook_login
|
| 49 |
+
|
| 50 |
+
>>> notebook_login()
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
## Load SQuAD dataset
|
| 54 |
+
|
| 55 |
+
まず、🤗 データセット ライブラリから SQuAD データセットの小さいサブセットを読み込みます。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
```py
|
| 59 |
+
>>> from datasets import load_dataset
|
| 60 |
+
|
| 61 |
+
>>> squad = load_dataset("squad", split="train[:5000]")
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
|
| 65 |
+
|
| 66 |
+
```py
|
| 67 |
+
>>> squad = squad.train_test_split(test_size=0.2)
|
| 68 |
+
```
|
| 69 |
+
|
| 70 |
+
次に、例を見てみましょう。
|
| 71 |
+
|
| 72 |
+
```py
|
| 73 |
+
>>> squad["train"][0]
|
| 74 |
+
{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
|
| 75 |
+
'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
|
| 76 |
+
'id': '5733be284776f41900661182',
|
| 77 |
+
'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
|
| 78 |
+
'title': 'University_of_Notre_Dame'
|
| 79 |
+
}
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
ここにはいくつかの重要なフィールドがあります。
|
| 83 |
+
|
| 84 |
+
- `answers`: 回答トークンと回答テキストの開始位置。
|
| 85 |
+
- `context`: モデルが答えを抽出するために必要な背景情報。
|
| 86 |
+
- `question`: モデルが答える必要がある質問。
|
| 87 |
+
|
| 88 |
+
## Preprocess
|
| 89 |
+
|
| 90 |
+
<Youtube id="qgaM0weJHpA"/>
|
| 91 |
+
|
| 92 |
+
次のステップでは、DistilBERT トークナイザーをロードして`question`フィールドと`context`フィールドを処理します。
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
```py
|
| 96 |
+
>>> from transformers import AutoTokenizer
|
| 97 |
+
|
| 98 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
質問応答タスクに特有の、注意すべき前処理手順がいくつかあります。
|
| 102 |
+
|
| 103 |
+
1. データセット内の一部の例には、モデルの最大入力長を超える非常に長い「コンテキスト」が含まれる場合があります。より長���シーケンスを処理するには、`truncation="only_second"` を設定して `context` のみを切り捨てます。
|
| 104 |
+
2. 次に、設定によって、回答の開始位置と終了位置を元の `context`にマッピングします。
|
| 105 |
+
「`return_offset_mapping=True`」。
|
| 106 |
+
3. マッピングが手元にあるので、答えの開始トークンと終了トークンを見つけることができます。 [`~tokenizers.Encoding.sequence_ids`] メソッドを使用して、
|
| 107 |
+
オフセットのどの部分が`question`に対応し、どの部分が`context`に対応するかを見つけます。
|
| 108 |
+
|
| 109 |
+
以下に、`answer`の開始トークンと終了トークンを切り詰めて`context`にマッピングする関数を作成する方法を示します。
|
| 110 |
+
|
| 111 |
+
```py
|
| 112 |
+
>>> def preprocess_function(examples):
|
| 113 |
+
... questions = [q.strip() for q in examples["question"]]
|
| 114 |
+
... inputs = tokenizer(
|
| 115 |
+
... questions,
|
| 116 |
+
... examples["context"],
|
| 117 |
+
... max_length=384,
|
| 118 |
+
... truncation="only_second",
|
| 119 |
+
... return_offsets_mapping=True,
|
| 120 |
+
... padding="max_length",
|
| 121 |
+
... )
|
| 122 |
+
|
| 123 |
+
... offset_mapping = inputs.pop("offset_mapping")
|
| 124 |
+
... answers = examples["answers"]
|
| 125 |
+
... start_positions = []
|
| 126 |
+
... end_positions = []
|
| 127 |
+
|
| 128 |
+
... for i, offset in enumerate(offset_mapping):
|
| 129 |
+
... answer = answers[i]
|
| 130 |
+
... start_char = answer["answer_start"][0]
|
| 131 |
+
... end_char = answer["answer_start"][0] + len(answer["text"][0])
|
| 132 |
+
... sequence_ids = inputs.sequence_ids(i)
|
| 133 |
+
|
| 134 |
+
... # Find the start and end of the context
|
| 135 |
+
... idx = 0
|
| 136 |
+
... while sequence_ids[idx] != 1:
|
| 137 |
+
... idx += 1
|
| 138 |
+
... context_start = idx
|
| 139 |
+
... while sequence_ids[idx] == 1:
|
| 140 |
+
... idx += 1
|
| 141 |
+
... context_end = idx - 1
|
| 142 |
+
|
| 143 |
+
... # If the answer is not fully inside the context, label it (0, 0)
|
| 144 |
+
... if offset[context_start][0] > end_char or offset[context_end][1] < start_char:
|
| 145 |
+
... start_positions.append(0)
|
| 146 |
+
... end_positions.append(0)
|
| 147 |
+
... else:
|
| 148 |
+
... # Otherwise it's the start and end token positions
|
| 149 |
+
... idx = context_start
|
| 150 |
+
... while idx <= context_end and offset[idx][0] <= start_char:
|
| 151 |
+
... idx += 1
|
| 152 |
+
... start_positions.append(idx - 1)
|
| 153 |
+
|
| 154 |
+
... idx = context_end
|
| 155 |
+
... while idx >= context_start and offset[idx][1] >= end_char:
|
| 156 |
+
... idx -= 1
|
| 157 |
+
... end_positions.append(idx + 1)
|
| 158 |
+
|
| 159 |
+
... inputs["start_positions"] = start_positions
|
| 160 |
+
... inputs["end_positions"] = end_positions
|
| 161 |
+
... return inputs
|
| 162 |
+
```
|
| 163 |
+
|
| 164 |
+
データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] 関数を使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` 関数を高速化できます。不要な列を削除します。
|
| 165 |
+
|
| 166 |
+
```py
|
| 167 |
+
>>> tokenized_squad = squad.map(preprocess_function, batched=True, remove_columns=squad["train"].column_names)
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
次に、[`DefaultDataCollator`] を使用してサンプルのバッチを作成します。 🤗 Transformers の他のデータ照合器とは異なり、[`DefaultDataCollator`] はパディングなどの追加の前処理を適用しません。
|
| 171 |
+
|
| 172 |
+
<frameworkcontent>
|
| 173 |
+
<pt>
|
| 174 |
+
```py
|
| 175 |
+
>>> from transformers import DefaultDataCollator
|
| 176 |
+
|
| 177 |
+
>>> data_collator = DefaultDataCollator()
|
| 178 |
+
```
|
| 179 |
+
</pt>
|
| 180 |
+
<tf>
|
| 181 |
+
```py
|
| 182 |
+
>>> from transformers import DefaultDataCollator
|
| 183 |
+
|
| 184 |
+
>>> data_collator = DefaultDataCollator(return_tensors="tf")
|
| 185 |
+
```
|
| 186 |
+
</tf>
|
| 187 |
+
</frameworkcontent>
|
| 188 |
+
|
| 189 |
+
## Train
|
| 190 |
+
|
| 191 |
+
<frameworkcontent>
|
| 192 |
+
<pt>
|
| 193 |
+
<Tip>
|
| 194 |
+
|
| 195 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 196 |
+
|
| 197 |
+
</Tip>
|
| 198 |
+
|
| 199 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForQuestionAnswering`] を使用して DitilBERT をロードします。
|
| 200 |
+
|
| 201 |
+
```py
|
| 202 |
+
>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
|
| 203 |
+
|
| 204 |
+
>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
|
| 205 |
+
```
|
| 206 |
+
|
| 207 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 208 |
+
|
| 209 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
|
| 210 |
+
2. トレーニング引数をモデル、データセット、トークナイザー、データ照合器とともに [`Trainer`] に渡します。
|
| 211 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 212 |
+
|
| 213 |
+
```py
|
| 214 |
+
>>> training_args = TrainingArguments(
|
| 215 |
+
... output_dir="my_awesome_qa_model",
|
| 216 |
+
... eval_strategy="epoch",
|
| 217 |
+
... learning_rate=2e-5,
|
| 218 |
+
... per_device_train_batch_size=16,
|
| 219 |
+
... per_device_eval_batch_size=16,
|
| 220 |
+
... num_train_epochs=3,
|
| 221 |
+
... weight_decay=0.01,
|
| 222 |
+
... push_to_hub=True,
|
| 223 |
+
... )
|
| 224 |
+
|
| 225 |
+
>>> trainer = Trainer(
|
| 226 |
+
... model=model,
|
| 227 |
+
... args=training_args,
|
| 228 |
+
... train_dataset=tokenized_squad["train"],
|
| 229 |
+
... eval_dataset=tokenized_squad["test"],
|
| 230 |
+
... processing_class=tokenizer,
|
| 231 |
+
... data_collator=data_collator,
|
| 232 |
+
... )
|
| 233 |
+
|
| 234 |
+
>>> trainer.train()
|
| 235 |
+
```
|
| 236 |
+
|
| 237 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 238 |
+
|
| 239 |
+
|
| 240 |
+
```py
|
| 241 |
+
>>> trainer.push_to_hub()
|
| 242 |
+
```
|
| 243 |
+
</pt>
|
| 244 |
+
<tf>
|
| 245 |
+
<Tip>
|
| 246 |
+
|
| 247 |
+
Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
|
| 248 |
+
|
| 249 |
+
</Tip>
|
| 250 |
+
|
| 251 |
+
</ヒント>
|
| 252 |
+
TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
|
| 253 |
+
|
| 254 |
+
```py
|
| 255 |
+
>>> from transformers import create_optimizer
|
| 256 |
+
|
| 257 |
+
>>> batch_size = 16
|
| 258 |
+
>>> num_epochs = 2
|
| 259 |
+
>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
|
| 260 |
+
>>> optimizer, schedule = create_optimizer(
|
| 261 |
+
... init_lr=2e-5,
|
| 262 |
+
... num_warmup_steps=0,
|
| 263 |
+
... num_train_steps=total_train_steps,
|
| 264 |
+
... )
|
| 265 |
+
```
|
| 266 |
+
|
| 267 |
+
次に、[`TFAutoModelForQuestionAnswering`] を使用して DistilBERT をロードできます。
|
| 268 |
+
|
| 269 |
+
```py
|
| 270 |
+
>>> from transformers import TFAutoModelForQuestionAnswering
|
| 271 |
+
|
| 272 |
+
>>> model = TFAutoModelForQuestionAnswering("distilbert/distilbert-base-uncased")
|
| 273 |
+
```
|
| 274 |
+
|
| 275 |
+
[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 276 |
+
|
| 277 |
+
```py
|
| 278 |
+
>>> tf_train_set = model.prepare_tf_dataset(
|
| 279 |
+
... tokenized_squad["train"],
|
| 280 |
+
... shuffle=True,
|
| 281 |
+
... batch_size=16,
|
| 282 |
+
... collate_fn=data_collator,
|
| 283 |
+
... )
|
| 284 |
+
|
| 285 |
+
>>> tf_validation_set = model.prepare_tf_dataset(
|
| 286 |
+
... tokenized_squad["test"],
|
| 287 |
+
... shuffle=False,
|
| 288 |
+
... batch_size=16,
|
| 289 |
+
... collate_fn=data_collator,
|
| 290 |
+
... )
|
| 291 |
+
```
|
| 292 |
+
|
| 293 |
+
[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。
|
| 294 |
+
|
| 295 |
+
```py
|
| 296 |
+
>>> import tensorflow as tf
|
| 297 |
+
|
| 298 |
+
>>> model.compile(optimizer=optimizer)
|
| 299 |
+
```
|
| 300 |
+
|
| 301 |
+
トレーニングを開始する前に最後にセットアップすることは、モデルをハブにプッシュする方法を提供することです。これは、モデルとトークナイザーを [`~transformers.PushToHubCallback`] でプッシュする場所を指定することで実行できます。
|
| 302 |
+
|
| 303 |
+
```py
|
| 304 |
+
>>> from transformers.keras_callbacks import PushToHubCallback
|
| 305 |
+
|
| 306 |
+
>>> callback = PushToHubCallback(
|
| 307 |
+
... output_dir="my_awesome_qa_model",
|
| 308 |
+
... tokenizer=tokenizer,
|
| 309 |
+
... )
|
| 310 |
+
```
|
| 311 |
+
|
| 312 |
+
ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
|
| 313 |
+
|
| 314 |
+
```py
|
| 315 |
+
>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=[callback])
|
| 316 |
+
```
|
| 317 |
+
|
| 318 |
+
トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
|
| 319 |
+
</tf>
|
| 320 |
+
</frameworkcontent>
|
| 321 |
+
|
| 322 |
+
<Tip>
|
| 323 |
+
|
| 324 |
+
質問応答用のモデルを微調整する方法の詳細な例については、対応するドキュメントを参照してください。
|
| 325 |
+
[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)
|
| 326 |
+
または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb)。
|
| 327 |
+
|
| 328 |
+
</Tip>
|
| 329 |
+
|
| 330 |
+
## Evaluate
|
| 331 |
+
|
| 332 |
+
質問応答の評価には、大量の後処理が必要です。時間がかかりすぎないように、このガイドでは評価ステップを省略しています。 [`Trainer`] はトレーニング中に評価損失を計算するため、モデルのパフォーマンスについて完全に分からないわけではありません。
|
| 333 |
+
|
| 334 |
+
もっと時間があり、質問応答用のモデルを評価する方法に興味がある場合は、[質問応答](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing) の章を参照してください。 🤗ハグフェイスコースから!
|
| 335 |
+
|
| 336 |
+
## Inference
|
| 337 |
+
|
| 338 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 339 |
+
|
| 340 |
+
質問と、モデルに予測させたいコンテキストを考え出します。
|
| 341 |
+
|
| 342 |
+
```py
|
| 343 |
+
>>> question = "How many programming languages does BLOOM support?"
|
| 344 |
+
>>> context = "BLOOM has 176 billion parameters and can generate text in 46 languages natural languages and 13 programming languages."
|
| 345 |
+
```
|
| 346 |
+
|
| 347 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して質問応答用の`pipeline`をインスタンス化し、それにテキストを渡します。
|
| 348 |
+
|
| 349 |
+
```py
|
| 350 |
+
>>> from transformers import pipeline
|
| 351 |
+
|
| 352 |
+
>>> question_answerer = pipeline("question-answering", model="my_awesome_qa_model")
|
| 353 |
+
>>> question_answerer(question=question, context=context)
|
| 354 |
+
{'score': 0.2058267742395401,
|
| 355 |
+
'start': 10,
|
| 356 |
+
'end': 95,
|
| 357 |
+
'answer': '176 billion parameters and can generate text in 46 languages natural languages and 13'}
|
| 358 |
+
```
|
| 359 |
+
|
| 360 |
+
必要に応じて、`pipeline`の結果を手動で複製することもできます。
|
| 361 |
+
|
| 362 |
+
<frameworkcontent>
|
| 363 |
+
<pt>
|
| 364 |
+
|
| 365 |
+
テキストをトークン化して PyTorch テンソルを返します。
|
| 366 |
+
|
| 367 |
+
```py
|
| 368 |
+
>>> from transformers import AutoTokenizer
|
| 369 |
+
|
| 370 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
|
| 371 |
+
>>> inputs = tokenizer(question, context, return_tensors="pt")
|
| 372 |
+
```
|
| 373 |
+
|
| 374 |
+
入力をモデルに渡し、`logits`を返します。
|
| 375 |
+
|
| 376 |
+
|
| 377 |
+
```py
|
| 378 |
+
>>> import torch
|
| 379 |
+
>>> from transformers import AutoModelForQuestionAnswering
|
| 380 |
+
|
| 381 |
+
>>> model = AutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
|
| 382 |
+
>>> with torch.no_grad():
|
| 383 |
+
... outputs = model(**inputs)
|
| 384 |
+
```
|
| 385 |
+
|
| 386 |
+
モデル出力から開始位置と終了位置の最も高い確率を取得します。
|
| 387 |
+
|
| 388 |
+
```py
|
| 389 |
+
>>> answer_start_index = outputs.start_logits.argmax()
|
| 390 |
+
>>> answer_end_index = outputs.end_logits.argmax()
|
| 391 |
+
```
|
| 392 |
+
|
| 393 |
+
予測されたトークンをデコードして答えを取得します。
|
| 394 |
+
|
| 395 |
+
```py
|
| 396 |
+
>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
|
| 397 |
+
>>> tokenizer.decode(predict_answer_tokens)
|
| 398 |
+
'176 billion parameters and can generate text in 46 languages natural languages and 13'
|
| 399 |
+
```
|
| 400 |
+
</pt>
|
| 401 |
+
<tf>
|
| 402 |
+
|
| 403 |
+
テキストをトークン化し、TensorFlow テンソルを返します。
|
| 404 |
+
|
| 405 |
+
```py
|
| 406 |
+
>>> from transformers import AutoTokenizer
|
| 407 |
+
|
| 408 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
|
| 409 |
+
>>> inputs = tokenizer(question, text, return_tensors="tf")
|
| 410 |
+
```
|
| 411 |
+
|
| 412 |
+
入力をモデルに渡し、`logits`を返します。
|
| 413 |
+
|
| 414 |
+
|
| 415 |
+
```py
|
| 416 |
+
>>> from transformers import TFAutoModelForQuestionAnswering
|
| 417 |
+
|
| 418 |
+
>>> model = TFAutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
|
| 419 |
+
>>> outputs = model(**inputs)
|
| 420 |
+
```
|
| 421 |
+
|
| 422 |
+
モデル出力から開始位置と終了位置の最も高い確率を取得します。
|
| 423 |
+
|
| 424 |
+
```py
|
| 425 |
+
>>> answer_start_index = int(tf.math.argmax(outputs.start_logits, axis=-1)[0])
|
| 426 |
+
>>> answer_end_index = int(tf.math.argmax(outputs.end_logits, axis=-1)[0])
|
| 427 |
+
```
|
| 428 |
+
|
| 429 |
+
予測されたトークンをデコードして答えを取得します。
|
| 430 |
+
|
| 431 |
+
```py
|
| 432 |
+
>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
|
| 433 |
+
>>> tokenizer.decode(predict_answer_tokens)
|
| 434 |
+
'176 billion parameters and can generate text in 46 languages natural languages and 13'
|
| 435 |
+
```
|
| 436 |
+
|
| 437 |
+
</tf>
|
| 438 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/semantic_segmentation.md
ADDED
|
@@ -0,0 +1,600 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Semantic segmentation
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="dKE8SIt9C-w"/>
|
| 22 |
+
|
| 23 |
+
セマンティック セグメンテーションでは、画像の個々のピクセルにラベルまたはクラスを割り当てます。セグメンテーションにはいくつかのタイプがありますが、セマンティック セグメンテーションの場合、同じオブジェクトの一意のインスタンス間の区別は行われません。両方のオブジェクトに同じラベルが付けられます (たとえば、`car-1`と`car-2`の代わりに`car`)。セマンティック セグメンテーションの一般的な現実世界のアプリケーションには、歩行者や重要な交通情報を識別するための自動運転車のトレーニング、医療画像内の細胞と異常の識別、衛星画像からの環境変化の監視などが含まれます。
|
| 24 |
+
|
| 25 |
+
このガイドでは、次の方法を説明します。
|
| 26 |
+
|
| 27 |
+
1. [SceneParse150](https://huggingface.co/datasets/scene_parse_150) データセットの [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer#segformer) を微調整します。
|
| 28 |
+
2. 微調整したモデルを推論に使用します。
|
| 29 |
+
|
| 30 |
+
<Tip>
|
| 31 |
+
|
| 32 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/image-segmentation) を確認することをお勧めします。
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 37 |
+
|
| 38 |
+
```bash
|
| 39 |
+
pip install -q datasets transformers evaluate
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 43 |
+
|
| 44 |
+
```py
|
| 45 |
+
>>> from huggingface_hub import notebook_login
|
| 46 |
+
|
| 47 |
+
>>> notebook_login()
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
## Load SceneParse150 dataset
|
| 51 |
+
|
| 52 |
+
まず、SceneParse150 データセットの小さいサブセットを 🤗 データセット ライブラリから読み込みます。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
>>> from datasets import load_dataset
|
| 56 |
+
|
| 57 |
+
>>> ds = load_dataset("scene_parse_150", split="train[:50]")
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
```py
|
| 64 |
+
>>> ds = ds.train_test_split(test_size=0.2)
|
| 65 |
+
>>> train_ds = ds["train"]
|
| 66 |
+
>>> test_ds = ds["test"]
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
次に、例を見てみましょう。
|
| 70 |
+
|
| 71 |
+
```py
|
| 72 |
+
>>> train_ds[0]
|
| 73 |
+
{'image': <PIL.JpegImagePlugin.JpegImageFile image mode=RGB size=512x683 at 0x7F9B0C201F90>,
|
| 74 |
+
'annotation': <PIL.PngImagePlugin.PngImageFile image mode=L size=512x683 at 0x7F9B0C201DD0>,
|
| 75 |
+
'scene_category': 368}
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
- `image`: シーンの PIL イメージ。
|
| 79 |
+
- `annotation`: セグメンテーション マップの PIL イメージ。モデルのターゲットでもあります。
|
| 80 |
+
- `scene_category`: "kitchen"や"office"などの画像シーンを説明するカテゴリ ID。このガイドでは、`image`と`annotation`のみが必要になります。どちらも PIL イメージです。
|
| 81 |
+
|
| 82 |
+
また、ラベル ID をラベル クラスにマップする辞書を作成することもできます。これは、後でモデルを設定するときに役立ちます。ハブからマッピングをダウンロードし、`id2label` および `label2id` ディクショナリを作成します。
|
| 83 |
+
|
| 84 |
+
```py
|
| 85 |
+
>>> import json
|
| 86 |
+
>>> from pathlib import Path
|
| 87 |
+
>>> from huggingface_hub import hf_hub_download
|
| 88 |
+
|
| 89 |
+
>>> repo_id = "huggingface/label-files"
|
| 90 |
+
>>> filename = "ade20k-id2label.json"
|
| 91 |
+
>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
|
| 92 |
+
>>> id2label = {int(k): v for k, v in id2label.items()}
|
| 93 |
+
>>> label2id = {v: k for k, v in id2label.items()}
|
| 94 |
+
>>> num_labels = len(id2label)
|
| 95 |
+
```
|
| 96 |
+
|
| 97 |
+
## Preprocess
|
| 98 |
+
|
| 99 |
+
次のステップでは、SegFormer 画像プロセッサをロードして、モデルの画像���注釈を準備します。このデータセットのような一部のデータセットは、バックグラウンド クラスとしてゼロインデックスを使用します。ただし、実際には背景クラスは 150 個のクラスに含まれていないため、`do_reduce_labels=True`を設定してすべてのラベルから 1 つを引く必要があります。ゼロインデックスは `255` に置き換えられるため、SegFormer の損失関数によって無視されます。
|
| 100 |
+
|
| 101 |
+
```py
|
| 102 |
+
>>> from transformers import AutoImageProcessor
|
| 103 |
+
|
| 104 |
+
>>> checkpoint = "nvidia/mit-b0"
|
| 105 |
+
>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
<frameworkcontent>
|
| 109 |
+
<pt>
|
| 110 |
+
|
| 111 |
+
モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。このガイドでは、[torchvision](https://pytorch.org/vision/stable/index.html) の [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html) 関数を使用します。 ) を使用して画像の色のプロパティをランダムに変更しますが、任意の画像ライブラリを使用することもできます。
|
| 112 |
+
|
| 113 |
+
```py
|
| 114 |
+
>>> from torchvision.transforms import ColorJitter
|
| 115 |
+
|
| 116 |
+
>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
|
| 117 |
+
```
|
| 118 |
+
|
| 119 |
+
次に、モデルの画像と注釈を準備するための 2 つの前処理関数を作成します。これらの関数は、画像を`pixel_values`に変換し、注釈を`labels`に変換します。トレーニング セットの場合、画像を画像プロセッサに提供する前に `jitter` が適用されます。テスト セットの場合、テスト中にデータ拡張が適用されないため、画像プロセッサは`images`を切り取って正規化し、`ラベル`のみを切り取ります。
|
| 120 |
+
|
| 121 |
+
```py
|
| 122 |
+
>>> def train_transforms(example_batch):
|
| 123 |
+
... images = [jitter(x) for x in example_batch["image"]]
|
| 124 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 125 |
+
... inputs = image_processor(images, labels)
|
| 126 |
+
... return inputs
|
| 127 |
+
|
| 128 |
+
|
| 129 |
+
>>> def val_transforms(example_batch):
|
| 130 |
+
... images = [x for x in example_batch["image"]]
|
| 131 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 132 |
+
... inputs = image_processor(images, labels)
|
| 133 |
+
... return inputs
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
データセット全体に`jitter`を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
|
| 137 |
+
|
| 138 |
+
```py
|
| 139 |
+
>>> train_ds.set_transform(train_transforms)
|
| 140 |
+
>>> test_ds.set_transform(val_transforms)
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
</pt>
|
| 144 |
+
</frameworkcontent>
|
| 145 |
+
|
| 146 |
+
<frameworkcontent>
|
| 147 |
+
<tf>
|
| 148 |
+
|
| 149 |
+
モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。
|
| 150 |
+
このガイドでは、[`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image) を使用して画像の色のプロパティをランダムに変更しますが、任意のプロパティを使用することもできます。画像
|
| 151 |
+
好きな図書館。
|
| 152 |
+
2 つの別々の変換関数を定義します。
|
| 153 |
+
- 画像拡張を含むトレーニング データ変換
|
| 154 |
+
- 🤗 Transformers のコンピューター ビジョン モデルはチャネル優先のレイアウトを想定しているため、画像を転置するだけの検証データ変換
|
| 155 |
+
|
| 156 |
+
```py
|
| 157 |
+
>>> import tensorflow as tf
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
>>> def aug_transforms(image):
|
| 161 |
+
... image = tf.keras.utils.img_to_array(image)
|
| 162 |
+
... image = tf.image.random_brightness(image, 0.25)
|
| 163 |
+
... image = tf.image.random_contrast(image, 0.5, 2.0)
|
| 164 |
+
... image = tf.image.random_saturation(image, 0.75, 1.25)
|
| 165 |
+
... image = tf.image.random_hue(image, 0.1)
|
| 166 |
+
... image = tf.transpose(image, (2, 0, 1))
|
| 167 |
+
... return image
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
>>> def transforms(image):
|
| 171 |
+
... image = tf.keras.utils.img_to_array(image)
|
| 172 |
+
... image = tf.transpose(image, (2, 0, 1))
|
| 173 |
+
... return image
|
| 174 |
+
```
|
| 175 |
+
|
| 176 |
+
次に、モデルの画像と注釈のバッチを準備する 2 つの前処理関数を作成します。これらの機能が適用されます
|
| 177 |
+
画像変換を行い、以前にロードされた `image_processor` を使用して画像を `pixel_values` に変換し、
|
| 178 |
+
`labels`への注釈。 `ImageProcessor` は、画像のサイズ変更と正規化も処理します。
|
| 179 |
+
|
| 180 |
+
```py
|
| 181 |
+
>>> def train_transforms(example_batch):
|
| 182 |
+
... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
|
| 183 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 184 |
+
... inputs = image_processor(images, labels)
|
| 185 |
+
... return inputs
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
>>> def val_transforms(example_batch):
|
| 189 |
+
... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
|
| 190 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 191 |
+
... inputs = image_processor(images, labels)
|
| 192 |
+
... return inputs
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
データセット全体に前処理変換を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。
|
| 196 |
+
変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
|
| 197 |
+
|
| 198 |
+
```py
|
| 199 |
+
>>> train_ds.set_transform(train_transforms)
|
| 200 |
+
>>> test_ds.set_transform(val_transforms)
|
| 201 |
+
```
|
| 202 |
+
</tf>
|
| 203 |
+
</frameworkcontent>
|
| 204 |
+
|
| 205 |
+
## Evaluate
|
| 206 |
+
|
| 207 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[Mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) メトリックをロードします (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照して、メトリクスをロードして計算する方法の詳細を確認してください)。
|
| 208 |
+
|
| 209 |
+
```py
|
| 210 |
+
>>> import evaluate
|
| 211 |
+
|
| 212 |
+
>>> metric = evaluate.load("mean_iou")
|
| 213 |
+
```
|
| 214 |
+
|
| 215 |
+
次に、メトリクスを [`~evaluate.EvaluationModule.compute`] する関数を作成します。予測を次のように変換する必要があります
|
| 216 |
+
最初にロジットを作成し、次に [`~evaluate.EvaluationModule.compute`] を呼び出す前にラベルのサイズに一致するように再形成します。
|
| 217 |
+
|
| 218 |
+
<frameworkcontent>
|
| 219 |
+
<pt>
|
| 220 |
+
|
| 221 |
+
```py
|
| 222 |
+
>>> import numpy as np
|
| 223 |
+
>>> import torch
|
| 224 |
+
>>> from torch import nn
|
| 225 |
+
|
| 226 |
+
>>> def compute_metrics(eval_pred):
|
| 227 |
+
... with torch.no_grad():
|
| 228 |
+
... logits, labels = eval_pred
|
| 229 |
+
... logits_tensor = torch.from_numpy(logits)
|
| 230 |
+
... logits_tensor = nn.functional.interpolate(
|
| 231 |
+
... logits_tensor,
|
| 232 |
+
... size=labels.shape[-2:],
|
| 233 |
+
... mode="bilinear",
|
| 234 |
+
... align_corners=False,
|
| 235 |
+
... ).argmax(dim=1)
|
| 236 |
+
|
| 237 |
+
... pred_labels = logits_tensor.detach().cpu().numpy()
|
| 238 |
+
... metrics = metric.compute(
|
| 239 |
+
... predictions=pred_labels,
|
| 240 |
+
... references=labels,
|
| 241 |
+
... num_labels=num_labels,
|
| 242 |
+
... ignore_index=255,
|
| 243 |
+
... reduce_labels=False,
|
| 244 |
+
... )
|
| 245 |
+
... for key, value in metrics.items():
|
| 246 |
+
... if type(value) is np.ndarray:
|
| 247 |
+
... metrics[key] = value.tolist()
|
| 248 |
+
... return metrics
|
| 249 |
+
```
|
| 250 |
+
|
| 251 |
+
</pt>
|
| 252 |
+
</frameworkcontent>
|
| 253 |
+
|
| 254 |
+
|
| 255 |
+
<frameworkcontent>
|
| 256 |
+
<tf>
|
| 257 |
+
|
| 258 |
+
```py
|
| 259 |
+
>>> def compute_metrics(eval_pred):
|
| 260 |
+
... logits, labels = eval_pred
|
| 261 |
+
... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
|
| 262 |
+
... logits_resized = tf.image.resize(
|
| 263 |
+
... logits,
|
| 264 |
+
... size=tf.shape(labels)[1:],
|
| 265 |
+
... method="bilinear",
|
| 266 |
+
... )
|
| 267 |
+
|
| 268 |
+
... pred_labels = tf.argmax(logits_resized, axis=-1)
|
| 269 |
+
... metrics = metric.compute(
|
| 270 |
+
... predictions=pred_labels,
|
| 271 |
+
... references=labels,
|
| 272 |
+
... num_labels=num_labels,
|
| 273 |
+
... ignore_index=-1,
|
| 274 |
+
... reduce_labels=image_processor.do_reduce_labels,
|
| 275 |
+
... )
|
| 276 |
+
|
| 277 |
+
... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
|
| 278 |
+
... per_category_iou = metrics.pop("per_category_iou").tolist()
|
| 279 |
+
|
| 280 |
+
... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
|
| 281 |
+
... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
|
| 282 |
+
... return {"val_" + k: v for k, v in metrics.items()}
|
| 283 |
+
```
|
| 284 |
+
|
| 285 |
+
</tf>
|
| 286 |
+
</frameworkcontent>
|
| 287 |
+
|
| 288 |
+
これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
|
| 289 |
+
|
| 290 |
+
## Train
|
| 291 |
+
<frameworkcontent>
|
| 292 |
+
<pt>
|
| 293 |
+
<Tip>
|
| 294 |
+
|
| 295 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#finetune-with-trainer) の基本的なチュートリアルをご覧ください。
|
| 296 |
+
|
| 297 |
+
</Tip>
|
| 298 |
+
|
| 299 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、ラベル ID とラベル クラス間のマッピングをモデルに渡します。
|
| 300 |
+
|
| 301 |
+
```py
|
| 302 |
+
>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
|
| 303 |
+
|
| 304 |
+
>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
|
| 305 |
+
```
|
| 306 |
+
|
| 307 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 308 |
+
|
| 309 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。 `image` 列が削除されるため、未使用の列を削除しないことが重要です。 `image` 列がないと、`pixel_values` を作成できません。この動作を防ぐには、`remove_unused_columns=False`を設定してください。他に必要なパラメータは、モデルの保存場所を指定する `output_dir` だけです。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は IoU メトリックを評価し、トレーニング チェックポイントを保存します。
|
| 310 |
+
2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
|
| 311 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 312 |
+
|
| 313 |
+
```py
|
| 314 |
+
>>> training_args = TrainingArguments(
|
| 315 |
+
... output_dir="segformer-b0-scene-parse-150",
|
| 316 |
+
... learning_rate=6e-5,
|
| 317 |
+
... num_train_epochs=50,
|
| 318 |
+
... per_device_train_batch_size=2,
|
| 319 |
+
... per_device_eval_batch_size=2,
|
| 320 |
+
... save_total_limit=3,
|
| 321 |
+
... eval_strategy="steps",
|
| 322 |
+
... save_strategy="steps",
|
| 323 |
+
... save_steps=20,
|
| 324 |
+
... eval_steps=20,
|
| 325 |
+
... logging_steps=1,
|
| 326 |
+
... eval_accumulation_steps=5,
|
| 327 |
+
... remove_unused_columns=False,
|
| 328 |
+
... push_to_hub=True,
|
| 329 |
+
... )
|
| 330 |
+
|
| 331 |
+
>>> trainer = Trainer(
|
| 332 |
+
... model=model,
|
| 333 |
+
... args=training_args,
|
| 334 |
+
... train_dataset=train_ds,
|
| 335 |
+
... eval_dataset=test_ds,
|
| 336 |
+
... compute_metrics=compute_metrics,
|
| 337 |
+
... )
|
| 338 |
+
|
| 339 |
+
>>> trainer.train()
|
| 340 |
+
```
|
| 341 |
+
|
| 342 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 343 |
+
|
| 344 |
+
```py
|
| 345 |
+
>>> trainer.push_to_hub()
|
| 346 |
+
```
|
| 347 |
+
</pt>
|
| 348 |
+
</frameworkcontent>
|
| 349 |
+
|
| 350 |
+
<frameworkcontent>
|
| 351 |
+
<tf>
|
| 352 |
+
<Tip>
|
| 353 |
+
|
| 354 |
+
Keras を使用したモデルの微調整に慣れていない場合は、まず [基本チュートリアル](./training#train-a-tensorflow-model-with-keras) を確認してください。
|
| 355 |
+
|
| 356 |
+
</Tip>
|
| 357 |
+
|
| 358 |
+
TensorFlow でモデルを微調整するには、次の手順に従います。
|
| 359 |
+
1. トレーニングのハイパーパラメータを定義し、オプティマイザーと学習率スケジュールを設定します。
|
| 360 |
+
2. 事前トレーニングされたモデルをインスタンス化します。
|
| 361 |
+
3. 🤗 データセットを `tf.data.Dataset` に変換します。
|
| 362 |
+
4. モデルをコンパイルします。
|
| 363 |
+
5. コールバックを追加してメトリクスを計算し、モデルを 🤗 Hub にアップロードします
|
| 364 |
+
6. `fit()` メソッドを使用してトレーニングを実行します。
|
| 365 |
+
|
| 366 |
+
まず、ハイパーパラメーター、オプティマイザー、学習率スケジュールを定義します。
|
| 367 |
+
|
| 368 |
+
```py
|
| 369 |
+
>>> from transformers import create_optimizer
|
| 370 |
+
|
| 371 |
+
>>> batch_size = 2
|
| 372 |
+
>>> num_epochs = 50
|
| 373 |
+
>>> num_train_steps = len(train_ds) * num_epochs
|
| 374 |
+
>>> learning_rate = 6e-5
|
| 375 |
+
>>> weight_decay_rate = 0.01
|
| 376 |
+
|
| 377 |
+
>>> optimizer, lr_schedule = create_optimizer(
|
| 378 |
+
... init_lr=learning_rate,
|
| 379 |
+
... num_train_steps=num_train_steps,
|
| 380 |
+
... weight_decay_rate=weight_decay_rate,
|
| 381 |
+
... num_warmup_steps=0,
|
| 382 |
+
... )
|
| 383 |
+
```
|
| 384 |
+
|
| 385 |
+
次に、ラベル マッピングとともに [`TFAutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、それをコンパイルします。
|
| 386 |
+
オプティマイザ。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
|
| 387 |
+
|
| 388 |
+
```py
|
| 389 |
+
>>> from transformers import TFAutoModelForSemanticSegmentation
|
| 390 |
+
|
| 391 |
+
>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
|
| 392 |
+
... checkpoint,
|
| 393 |
+
... id2label=id2label,
|
| 394 |
+
... label2id=label2id,
|
| 395 |
+
... )
|
| 396 |
+
>>> model.compile(optimizer=optimizer) # No loss argument!
|
| 397 |
+
```
|
| 398 |
+
|
| 399 |
+
[`~datasets.Dataset.to_tf_dataset`] と [`DefaultDataCollator`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 400 |
+
|
| 401 |
+
```py
|
| 402 |
+
>>> from transformers import DefaultDataCollator
|
| 403 |
+
|
| 404 |
+
>>> data_collator = DefaultDataCollator(return_tensors="tf")
|
| 405 |
+
|
| 406 |
+
>>> tf_train_dataset = train_ds.to_tf_dataset(
|
| 407 |
+
... columns=["pixel_values", "label"],
|
| 408 |
+
... shuffle=True,
|
| 409 |
+
... batch_size=batch_size,
|
| 410 |
+
... collate_fn=data_collator,
|
| 411 |
+
... )
|
| 412 |
+
|
| 413 |
+
>>> tf_eval_dataset = test_ds.to_tf_dataset(
|
| 414 |
+
... columns=["pixel_values", "label"],
|
| 415 |
+
... shuffle=True,
|
| 416 |
+
... batch_size=batch_size,
|
| 417 |
+
... collate_fn=data_collator,
|
| 418 |
+
... )
|
| 419 |
+
```
|
| 420 |
+
|
| 421 |
+
予測から精度を計算し、モデルを 🤗 ハブにプッシュするには、[Keras callbacks](../main_classes/keras_callbacks) を使用します。
|
| 422 |
+
`compute_metrics` 関数を [`KerasMetricCallback`] に渡します。
|
| 423 |
+
そして [`PushToHubCallback`] を使用してモデルをアップロードします。
|
| 424 |
+
|
| 425 |
+
```py
|
| 426 |
+
>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
|
| 427 |
+
|
| 428 |
+
>>> metric_callback = KerasMetricCallback(
|
| 429 |
+
... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
|
| 430 |
+
... )
|
| 431 |
+
|
| 432 |
+
>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", tokenizer=image_processor)
|
| 433 |
+
|
| 434 |
+
>>> callbacks = [metric_callback, push_to_hub_callback]
|
| 435 |
+
```
|
| 436 |
+
|
| 437 |
+
ついに、モデルをトレーニングする準備が整いました。トレーニングおよび検証データセット、エポック数、
|
| 438 |
+
モデルを微調整するためのコールバック:
|
| 439 |
+
|
| 440 |
+
|
| 441 |
+
```py
|
| 442 |
+
>>> model.fit(
|
| 443 |
+
... tf_train_dataset,
|
| 444 |
+
... validation_data=tf_eval_dataset,
|
| 445 |
+
... callbacks=callbacks,
|
| 446 |
+
... epochs=num_epochs,
|
| 447 |
+
... )
|
| 448 |
+
```
|
| 449 |
+
|
| 450 |
+
おめでとう!モデルを微調整し、🤗 Hub で共有しました。これで推論に使用できるようになりました。
|
| 451 |
+
</tf>
|
| 452 |
+
</frameworkcontent>
|
| 453 |
+
|
| 454 |
+
## Inference
|
| 455 |
+
|
| 456 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 457 |
+
|
| 458 |
+
推論のために画像をロードします。
|
| 459 |
+
|
| 460 |
+
```py
|
| 461 |
+
>>> image = ds[0]["image"]
|
| 462 |
+
>>> image
|
| 463 |
+
```
|
| 464 |
+
|
| 465 |
+
<div class="flex justify-center">
|
| 466 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/semantic-seg-image.png" alt="Image of bedroom"/>
|
| 467 |
+
</div>
|
| 468 |
+
|
| 469 |
+
<frameworkcontent>
|
| 470 |
+
<pt>
|
| 471 |
+
|
| 472 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して画像セグメンテーション用の `pipeline`をインスタンス化し、それに画像を渡します。
|
| 473 |
+
|
| 474 |
+
```py
|
| 475 |
+
>>> from transformers import pipeline
|
| 476 |
+
|
| 477 |
+
>>> segmenter = pipeline("image-segmentation", model="my_awesome_seg_model")
|
| 478 |
+
>>> segmenter(image)
|
| 479 |
+
[{'score': None,
|
| 480 |
+
'label': 'wall',
|
| 481 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062690>},
|
| 482 |
+
{'score': None,
|
| 483 |
+
'label': 'sky',
|
| 484 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062A50>},
|
| 485 |
+
{'score': None,
|
| 486 |
+
'label': 'floor',
|
| 487 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062B50>},
|
| 488 |
+
{'score': None,
|
| 489 |
+
'label': 'ceiling',
|
| 490 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062A10>},
|
| 491 |
+
{'score': None,
|
| 492 |
+
'label': 'bed ',
|
| 493 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062E90>},
|
| 494 |
+
{'score': None,
|
| 495 |
+
'label': 'windowpane',
|
| 496 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062390>},
|
| 497 |
+
{'score': None,
|
| 498 |
+
'label': 'cabinet',
|
| 499 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062550>},
|
| 500 |
+
{'score': None,
|
| 501 |
+
'label': 'chair',
|
| 502 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062D90>},
|
| 503 |
+
{'score': None,
|
| 504 |
+
'label': 'armchair',
|
| 505 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062E10>}]
|
| 506 |
+
```
|
| 507 |
+
|
| 508 |
+
必要に応じて、`pipeline`の結果を手動で複製することもできます。画像を画像プロセッサで処理し、`pixel_values` を GPU に配置します。
|
| 509 |
+
|
| 510 |
+
```py
|
| 511 |
+
>>> device = torch.device("cuda" if torch.cuda.is_available() else "cpu") # use GPU if available, otherwise use a CPU
|
| 512 |
+
>>> encoding = image_processor(image, return_tensors="pt")
|
| 513 |
+
>>> pixel_values = encoding.pixel_values.to(device)
|
| 514 |
+
```
|
| 515 |
+
|
| 516 |
+
入力をモデルに渡し、`logits`を返します。
|
| 517 |
+
|
| 518 |
+
|
| 519 |
+
```py
|
| 520 |
+
>>> outputs = model(pixel_values=pixel_values)
|
| 521 |
+
>>> logits = outputs.logits.cpu()
|
| 522 |
+
```
|
| 523 |
+
|
| 524 |
+
次に、ロジットを元の画像サイズに再スケールします。
|
| 525 |
+
|
| 526 |
+
```py
|
| 527 |
+
>>> upsampled_logits = nn.functional.interpolate(
|
| 528 |
+
... logits,
|
| 529 |
+
... size=image.size[::-1],
|
| 530 |
+
... mode="bilinear",
|
| 531 |
+
... align_corners=False,
|
| 532 |
+
... )
|
| 533 |
+
|
| 534 |
+
>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
|
| 535 |
+
```
|
| 536 |
+
|
| 537 |
+
</pt>
|
| 538 |
+
</frameworkcontent>
|
| 539 |
+
|
| 540 |
+
<frameworkcontent>
|
| 541 |
+
<tf>
|
| 542 |
+
|
| 543 |
+
画像プロセッサをロードして画像を前処理し、入力を TensorFlow テンソルとして返します。
|
| 544 |
+
|
| 545 |
+
```py
|
| 546 |
+
>>> from transformers import AutoImageProcessor
|
| 547 |
+
|
| 548 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
|
| 549 |
+
>>> inputs = image_processor(image, return_tensors="tf")
|
| 550 |
+
```
|
| 551 |
+
|
| 552 |
+
入力をモデルに渡し、`logits`を返します。
|
| 553 |
+
|
| 554 |
+
```py
|
| 555 |
+
>>> from transformers import TFAutoModelForSemanticSegmentation
|
| 556 |
+
|
| 557 |
+
>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
|
| 558 |
+
>>> logits = model(**inputs).logits
|
| 559 |
+
```
|
| 560 |
+
|
| 561 |
+
次に、ロジットを元の画像サイズに再スケールし、クラス次元に argmax を適用します。
|
| 562 |
+
|
| 563 |
+
```py
|
| 564 |
+
>>> logits = tf.transpose(logits, [0, 2, 3, 1])
|
| 565 |
+
|
| 566 |
+
>>> upsampled_logits = tf.image.resize(
|
| 567 |
+
... logits,
|
| 568 |
+
... # We reverse the shape of `image` because `image.size` returns width and height.
|
| 569 |
+
... image.size[::-1],
|
| 570 |
+
... )
|
| 571 |
+
|
| 572 |
+
>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
|
| 573 |
+
```
|
| 574 |
+
|
| 575 |
+
</tf>
|
| 576 |
+
</frameworkcontent>
|
| 577 |
+
|
| 578 |
+
結果を視覚化するには、[データセット カラー パレット](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51) を、それぞれをマップする `ade_palette()` としてロードします。クラスを RGB 値に変換します。次に、画像と予測されたセグメンテーション マップを組み合わせてプロットできます。
|
| 579 |
+
|
| 580 |
+
```py
|
| 581 |
+
>>> import matplotlib.pyplot as plt
|
| 582 |
+
>>> import numpy as np
|
| 583 |
+
|
| 584 |
+
>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
|
| 585 |
+
>>> palette = np.array(ade_palette())
|
| 586 |
+
>>> for label, color in enumerate(palette):
|
| 587 |
+
... color_seg[pred_seg == label, :] = color
|
| 588 |
+
>>> color_seg = color_seg[..., ::-1] # convert to BGR
|
| 589 |
+
|
| 590 |
+
>>> img = np.array(image) * 0.5 + color_seg * 0.5 # plot the image with the segmentation map
|
| 591 |
+
>>> img = img.astype(np.uint8)
|
| 592 |
+
|
| 593 |
+
>>> plt.figure(figsize=(15, 10))
|
| 594 |
+
>>> plt.imshow(img)
|
| 595 |
+
>>> plt.show()
|
| 596 |
+
```
|
| 597 |
+
|
| 598 |
+
<div class="flex justify-center">
|
| 599 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/semantic-seg-preds.png" alt="Image of bedroom overlaid with segmentation map"/>
|
| 600 |
+
</div>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/sequence_classification.md
ADDED
|
@@ -0,0 +1,604 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Sequence classification
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="dKE8SIt9C-w"/>
|
| 22 |
+
|
| 23 |
+
セマンティック セグメンテーションでは、画像の個々のピクセルにラベルまたはクラスを割り当てます。セグメンテーションにはいくつかのタイプがありますが、セマンティック セグメンテーションの場合、同じオブジェクトの一意のインスタンス間の区別は行われません。両方のオブジェクトに同じラベルが付けられます (たとえば、「car-1」と「car-2」の代わりに「car」)。セマンティック セグメンテーションの一般的な現実世界のアプリケーションには、歩行者や重要な交通情報を識別するための自動運転車のトレーニング、医療画像内の細胞と異常の識別、衛星画像からの環境変化の監視などが含まれます。
|
| 24 |
+
|
| 25 |
+
このガイドでは、次の方法を説明します。
|
| 26 |
+
|
| 27 |
+
1. [SceneParse150](https://huggingface.co/datasets/scene_parse_150) データセットの [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer#segformer) を微調整します。
|
| 28 |
+
2. 微調整したモデルを推論に使用します。
|
| 29 |
+
|
| 30 |
+
<Tip>
|
| 31 |
+
|
| 32 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/text-classification) を確認することをお勧めします。
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 37 |
+
|
| 38 |
+
```bash
|
| 39 |
+
pip install -q datasets transformers evaluate
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 43 |
+
|
| 44 |
+
```py
|
| 45 |
+
>>> from huggingface_hub import notebook_login
|
| 46 |
+
|
| 47 |
+
>>> notebook_login()
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
## Load SceneParse150 dataset
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
まず、SceneParse150 データセットの小さいサブセットを 🤗 データセット ライブラリから読み込みます。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
|
| 54 |
+
|
| 55 |
+
```py
|
| 56 |
+
>>> from datasets import load_dataset
|
| 57 |
+
|
| 58 |
+
>>> ds = load_dataset("scene_parse_150", split="train[:50]")
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
|
| 62 |
+
|
| 63 |
+
```py
|
| 64 |
+
>>> ds = ds.train_test_split(test_size=0.2)
|
| 65 |
+
>>> train_ds = ds["train"]
|
| 66 |
+
>>> test_ds = ds["test"]
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
次に、例を見てみましょう。
|
| 70 |
+
|
| 71 |
+
```py
|
| 72 |
+
>>> train_ds[0]
|
| 73 |
+
{'image': <PIL.JpegImagePlugin.JpegImageFile image mode=RGB size=512x683 at 0x7F9B0C201F90>,
|
| 74 |
+
'annotation': <PIL.PngImagePlugin.PngImageFile image mode=L size=512x683 at 0x7F9B0C201DD0>,
|
| 75 |
+
'scene_category': 368}
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
- `image`: シーンの PIL イメージ。
|
| 79 |
+
- `annotation`: セグメンテーション マップの PIL イメージ。モデルのターゲットでもあります。
|
| 80 |
+
- `scene_category`: 「キッチン」や「オフィス」などの画像シーンを説明するカテゴリ ID。このガイドでは、「image」と「annotation」のみが必要になります。どちらも PIL イメージです。
|
| 81 |
+
|
| 82 |
+
また、ラベル ID をラベル クラスにマップする辞書を作成することもできます。これは、後でモデルを設定するときに役立ちます。ハブからマッピングをダウンロードし、`id2label` および `label2id` ディクショナリを作成します。
|
| 83 |
+
|
| 84 |
+
```py
|
| 85 |
+
>>> import json
|
| 86 |
+
>>> from pathlib import Path
|
| 87 |
+
>>> from huggingface_hub import hf_hub_download
|
| 88 |
+
|
| 89 |
+
>>> repo_id = "huggingface/label-files"
|
| 90 |
+
>>> filename = "ade20k-id2label.json"
|
| 91 |
+
>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
|
| 92 |
+
>>> id2label = {int(k): v for k, v in id2label.items()}
|
| 93 |
+
>>> label2id = {v: k for k, v in id2label.items()}
|
| 94 |
+
>>> num_labels = len(id2label)
|
| 95 |
+
```
|
| 96 |
+
|
| 97 |
+
## Preprocess
|
| 98 |
+
|
| 99 |
+
次のステップでは、SegFormer 画像プロセッ���をロードして、モデルの画像と注釈を準備します。このデータセットのような一部のデータセットは、バックグラウンド クラスとしてゼロインデックスを使用します。ただし、実際には背景クラスは 150 個のクラスに含まれていないため、`do_reduce_labels=True`を設定してすべてのラベルから 1 つを引く必要があります。ゼロインデックスは `255` に置き換えられるため、SegFormer の損失関数によって無視されます。
|
| 100 |
+
|
| 101 |
+
```py
|
| 102 |
+
>>> from transformers import AutoImageProcessor
|
| 103 |
+
|
| 104 |
+
>>> checkpoint = "nvidia/mit-b0"
|
| 105 |
+
>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
<frameworkcontent>
|
| 109 |
+
<pt>
|
| 110 |
+
|
| 111 |
+
モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。このガイドでは、[torchvision](https://pytorch.org) の [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html) 関数を使用します。 /vision/stable/index.html) を使用して画像の色のプロパティをランダムに変更しますが、任意の画像ライブラリを使用することもできます。
|
| 112 |
+
|
| 113 |
+
```py
|
| 114 |
+
>>> from torchvision.transforms import ColorJitter
|
| 115 |
+
|
| 116 |
+
>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
|
| 117 |
+
```
|
| 118 |
+
|
| 119 |
+
次に、モデルの画像と注釈を準備するための 2 つの前処理関数を作成します。これらの関数は、画像を`pixel_values`に変換し、注釈を`labels`に変換します。トレーニング セットの場合、画像を画像プロセッサに提供する前に`jitter`が適用されます。テスト セットの場合、テスト中にデータ拡張が適用されないため、画像プロセッサは`images`を切り取って正規化し、`labels` のみを切り取ります。
|
| 120 |
+
|
| 121 |
+
```py
|
| 122 |
+
>>> def train_transforms(example_batch):
|
| 123 |
+
... images = [jitter(x) for x in example_batch["image"]]
|
| 124 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 125 |
+
... inputs = image_processor(images, labels)
|
| 126 |
+
... return inputs
|
| 127 |
+
|
| 128 |
+
|
| 129 |
+
>>> def val_transforms(example_batch):
|
| 130 |
+
... images = [x for x in example_batch["image"]]
|
| 131 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 132 |
+
... inputs = image_processor(images, labels)
|
| 133 |
+
... return inputs
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
データセット全体に`jitter`を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
|
| 137 |
+
|
| 138 |
+
```py
|
| 139 |
+
>>> train_ds.set_transform(train_transforms)
|
| 140 |
+
>>> test_ds.set_transform(val_transforms)
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
</pt>
|
| 144 |
+
</frameworkcontent>
|
| 145 |
+
|
| 146 |
+
<frameworkcontent>
|
| 147 |
+
<tf>
|
| 148 |
+
|
| 149 |
+
モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。
|
| 150 |
+
このガイドでは、[`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image) を使用して画像の色のプロパティをランダムに変更しますが、任意のプロパティを使用することもできます。画像
|
| 151 |
+
好きな図書館。
|
| 152 |
+
2 つの別々の変換関数を定義します。
|
| 153 |
+
- 画像拡張を含むトレーニング データ変換
|
| 154 |
+
- 🤗 Transformers のコンピューター ビジョン モデルはチャネル優先のレイアウトを想定しているため、画像を転置するだけの検証データ変換
|
| 155 |
+
|
| 156 |
+
```py
|
| 157 |
+
>>> import tensorflow as tf
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
>>> def aug_transforms(image):
|
| 161 |
+
... image = tf.keras.utils.img_to_array(image)
|
| 162 |
+
... image = tf.image.random_brightness(image, 0.25)
|
| 163 |
+
... image = tf.image.random_contrast(image, 0.5, 2.0)
|
| 164 |
+
... image = tf.image.random_saturation(image, 0.75, 1.25)
|
| 165 |
+
... image = tf.image.random_hue(image, 0.1)
|
| 166 |
+
... image = tf.transpose(image, (2, 0, 1))
|
| 167 |
+
... return image
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
>>> def transforms(image):
|
| 171 |
+
... image = tf.keras.utils.img_to_array(image)
|
| 172 |
+
... image = tf.transpose(image, (2, 0, 1))
|
| 173 |
+
... return image
|
| 174 |
+
```
|
| 175 |
+
|
| 176 |
+
次に、モデルの画像と注釈のバッチを準備する 2 つの前処理関数を作成します。これらの機能が適用されます
|
| 177 |
+
画像変換を行い、以前にロードされた `image_processor` を使用して画像を `pixel_values` に変換し、
|
| 178 |
+
`labels`への注釈。 `ImageProcessor` は、画像のサイズ変更と正規化も処理します。
|
| 179 |
+
|
| 180 |
+
```py
|
| 181 |
+
>>> def train_transforms(example_batch):
|
| 182 |
+
... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
|
| 183 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 184 |
+
... inputs = image_processor(images, labels)
|
| 185 |
+
... return inputs
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
>>> def val_transforms(example_batch):
|
| 189 |
+
... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
|
| 190 |
+
... labels = [x for x in example_batch["annotation"]]
|
| 191 |
+
... inputs = image_processor(images, labels)
|
| 192 |
+
... return inputs
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
データセット全体に前処理変換を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。
|
| 196 |
+
変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
|
| 197 |
+
|
| 198 |
+
```py
|
| 199 |
+
>>> train_ds.set_transform(train_transforms)
|
| 200 |
+
>>> test_ds.set_transform(val_transforms)
|
| 201 |
+
```
|
| 202 |
+
</tf>
|
| 203 |
+
</frameworkcontent>
|
| 204 |
+
|
| 205 |
+
## Evaluate
|
| 206 |
+
|
| 207 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[Mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) メトリックをロードします (🤗 Evaluate [クイック ツアー](https://huggingface.co) を参照してください) /docs/evaluate/a_quick_tour) を参照して、メトリクスをロードして計算する方法の詳細を確認してください)。
|
| 208 |
+
|
| 209 |
+
```py
|
| 210 |
+
>>> import evaluate
|
| 211 |
+
|
| 212 |
+
>>> metric = evaluate.load("mean_iou")
|
| 213 |
+
```
|
| 214 |
+
|
| 215 |
+
次に、メトリクスを [`~evaluate.EvaluationModule.compute`] する関数を作成します。予測を次のように変換する必要があります
|
| 216 |
+
最初にロジットを作成し、次に [`~evaluate.EvaluationModule.compute`] を呼び出す前にラベルのサイズに一致するように再形成します。
|
| 217 |
+
|
| 218 |
+
<frameworkcontent>
|
| 219 |
+
<pt>
|
| 220 |
+
|
| 221 |
+
```py
|
| 222 |
+
>>> import numpy as np
|
| 223 |
+
>>> import torch
|
| 224 |
+
>>> from torch import nn
|
| 225 |
+
|
| 226 |
+
>>> def compute_metrics(eval_pred):
|
| 227 |
+
... with torch.no_grad():
|
| 228 |
+
... logits, labels = eval_pred
|
| 229 |
+
... logits_tensor = torch.from_numpy(logits)
|
| 230 |
+
... logits_tensor = nn.functional.interpolate(
|
| 231 |
+
... logits_tensor,
|
| 232 |
+
... size=labels.shape[-2:],
|
| 233 |
+
... mode="bilinear",
|
| 234 |
+
... align_corners=False,
|
| 235 |
+
... ).argmax(dim=1)
|
| 236 |
+
|
| 237 |
+
... pred_labels = logits_tensor.detach().cpu().numpy()
|
| 238 |
+
... metrics = metric.compute(
|
| 239 |
+
... predictions=pred_labels,
|
| 240 |
+
... references=labels,
|
| 241 |
+
... num_labels=num_labels,
|
| 242 |
+
... ignore_index=255,
|
| 243 |
+
... reduce_labels=False,
|
| 244 |
+
... )
|
| 245 |
+
... for key, value in metrics.items():
|
| 246 |
+
... if type(value) is np.ndarray:
|
| 247 |
+
... metrics[key] = value.tolist()
|
| 248 |
+
... return metrics
|
| 249 |
+
```
|
| 250 |
+
|
| 251 |
+
</pt>
|
| 252 |
+
</frameworkcontent>
|
| 253 |
+
|
| 254 |
+
|
| 255 |
+
<frameworkcontent>
|
| 256 |
+
<tf>
|
| 257 |
+
|
| 258 |
+
```py
|
| 259 |
+
>>> def compute_metrics(eval_pred):
|
| 260 |
+
... logits, labels = eval_pred
|
| 261 |
+
... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
|
| 262 |
+
... logits_resized = tf.image.resize(
|
| 263 |
+
... logits,
|
| 264 |
+
... size=tf.shape(labels)[1:],
|
| 265 |
+
... method="bilinear",
|
| 266 |
+
... )
|
| 267 |
+
|
| 268 |
+
... pred_labels = tf.argmax(logits_resized, axis=-1)
|
| 269 |
+
... metrics = metric.compute(
|
| 270 |
+
... predictions=pred_labels,
|
| 271 |
+
... references=labels,
|
| 272 |
+
... num_labels=num_labels,
|
| 273 |
+
... ignore_index=-1,
|
| 274 |
+
... reduce_labels=image_processor.do_reduce_labels,
|
| 275 |
+
... )
|
| 276 |
+
|
| 277 |
+
... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
|
| 278 |
+
... per_category_iou = metrics.pop("per_category_iou").tolist()
|
| 279 |
+
|
| 280 |
+
... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
|
| 281 |
+
... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
|
| 282 |
+
... return {"val_" + k: v for k, v in metrics.items()}
|
| 283 |
+
```
|
| 284 |
+
|
| 285 |
+
</tf>
|
| 286 |
+
</frameworkcontent>
|
| 287 |
+
|
| 288 |
+
これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
|
| 289 |
+
|
| 290 |
+
## Train
|
| 291 |
+
<frameworkcontent>
|
| 292 |
+
<pt>
|
| 293 |
+
<Tip>
|
| 294 |
+
|
| 295 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#finetune-with-trainer) の基本的なチュートリアルをご覧ください。
|
| 296 |
+
|
| 297 |
+
|
| 298 |
+
</Tip>
|
| 299 |
+
|
| 300 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、ラベル ID とラベル クラス間のマッピングをモデルに渡します。
|
| 301 |
+
|
| 302 |
+
```py
|
| 303 |
+
>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
|
| 304 |
+
|
| 305 |
+
>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
|
| 306 |
+
```
|
| 307 |
+
|
| 308 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 309 |
+
|
| 310 |
+
1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。 `image` 列が削除されるため、未使用の列を削除しないことが重要です。 `image` 列がないと、`pixel_values` を作成できません。この動作を防ぐには、`remove_unused_columns=False`を設定してください。他に必要なパラメータは、モデルの保存場所を指定する `output_dir` だけです。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は IoU メトリックを評価し、トレーニング チェックポイントを保存します。
|
| 311 |
+
2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
|
| 312 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 313 |
+
|
| 314 |
+
|
| 315 |
+
```py
|
| 316 |
+
>>> training_args = TrainingArguments(
|
| 317 |
+
... output_dir="segformer-b0-scene-parse-150",
|
| 318 |
+
... learning_rate=6e-5,
|
| 319 |
+
... num_train_epochs=50,
|
| 320 |
+
... per_device_train_batch_size=2,
|
| 321 |
+
... per_device_eval_batch_size=2,
|
| 322 |
+
... save_total_limit=3,
|
| 323 |
+
... eval_strategy="steps",
|
| 324 |
+
... save_strategy="steps",
|
| 325 |
+
... save_steps=20,
|
| 326 |
+
... eval_steps=20,
|
| 327 |
+
... logging_steps=1,
|
| 328 |
+
... eval_accumulation_steps=5,
|
| 329 |
+
... remove_unused_columns=False,
|
| 330 |
+
... push_to_hub=True,
|
| 331 |
+
... )
|
| 332 |
+
|
| 333 |
+
>>> trainer = Trainer(
|
| 334 |
+
... model=model,
|
| 335 |
+
... args=training_args,
|
| 336 |
+
... train_dataset=train_ds,
|
| 337 |
+
... eval_dataset=test_ds,
|
| 338 |
+
... compute_metrics=compute_metrics,
|
| 339 |
+
... )
|
| 340 |
+
|
| 341 |
+
>>> trainer.train()
|
| 342 |
+
```
|
| 343 |
+
|
| 344 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 345 |
+
|
| 346 |
+
```py
|
| 347 |
+
>>> trainer.push_to_hub()
|
| 348 |
+
```
|
| 349 |
+
</pt>
|
| 350 |
+
</frameworkcontent>
|
| 351 |
+
|
| 352 |
+
<frameworkcontent>
|
| 353 |
+
<tf>
|
| 354 |
+
<Tip>
|
| 355 |
+
|
| 356 |
+
Keras を使用したモデルの微調整に慣れていない場合は、まず [基本チュートリアル](./training#train-a-tensorflow-model-with-keras) を確認してください。
|
| 357 |
+
|
| 358 |
+
</Tip>
|
| 359 |
+
|
| 360 |
+
TensorFlow でモデルを微調整するには、次の手順に従います。
|
| 361 |
+
1. トレーニングのハイパーパラメータを定義し、オプティマイザーと学習率スケジュールを設定します。
|
| 362 |
+
2. 事前トレーニングされたモデルをインスタンス化します。
|
| 363 |
+
3. 🤗 データセットを `tf.data.Dataset` に変換します。
|
| 364 |
+
4. モデルをコンパイルします。
|
| 365 |
+
5. コールバックを追加してメトリクスを計算し、モデルを 🤗 Hub にアップロードします
|
| 366 |
+
6. `fit()` メソッドを使用してトレーニングを実行します。
|
| 367 |
+
|
| 368 |
+
まず、ハイパーパラメーター、オプティマイザー、学習率スケジュールを定義します。
|
| 369 |
+
|
| 370 |
+
|
| 371 |
+
```py
|
| 372 |
+
>>> from transformers import create_optimizer
|
| 373 |
+
|
| 374 |
+
>>> batch_size = 2
|
| 375 |
+
>>> num_epochs = 50
|
| 376 |
+
>>> num_train_steps = len(train_ds) * num_epochs
|
| 377 |
+
>>> learning_rate = 6e-5
|
| 378 |
+
>>> weight_decay_rate = 0.01
|
| 379 |
+
|
| 380 |
+
>>> optimizer, lr_schedule = create_optimizer(
|
| 381 |
+
... init_lr=learning_rate,
|
| 382 |
+
... num_train_steps=num_train_steps,
|
| 383 |
+
... weight_decay_rate=weight_decay_rate,
|
| 384 |
+
... num_warmup_steps=0,
|
| 385 |
+
... )
|
| 386 |
+
```
|
| 387 |
+
|
| 388 |
+
次に、ラベル マッピングとともに [`TFAutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、それをコンパイルします。
|
| 389 |
+
オプティマイザ。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
|
| 390 |
+
|
| 391 |
+
```py
|
| 392 |
+
>>> from transformers import TFAutoModelForSemanticSegmentation
|
| 393 |
+
|
| 394 |
+
>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
|
| 395 |
+
... checkpoint,
|
| 396 |
+
... id2label=id2label,
|
| 397 |
+
... label2id=label2id,
|
| 398 |
+
... )
|
| 399 |
+
>>> model.compile(optimizer=optimizer) # No loss argument!
|
| 400 |
+
```
|
| 401 |
+
|
| 402 |
+
[`~datasets.Dataset.to_tf_dataset`] と [`DefaultDataCollator`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 403 |
+
|
| 404 |
+
```py
|
| 405 |
+
>>> from transformers import DefaultDataCollator
|
| 406 |
+
|
| 407 |
+
>>> data_collator = DefaultDataCollator(return_tensors="tf")
|
| 408 |
+
|
| 409 |
+
>>> tf_train_dataset = train_ds.to_tf_dataset(
|
| 410 |
+
... columns=["pixel_values", "label"],
|
| 411 |
+
... shuffle=True,
|
| 412 |
+
... batch_size=batch_size,
|
| 413 |
+
... collate_fn=data_collator,
|
| 414 |
+
... )
|
| 415 |
+
|
| 416 |
+
>>> tf_eval_dataset = test_ds.to_tf_dataset(
|
| 417 |
+
... columns=["pixel_values", "label"],
|
| 418 |
+
... shuffle=True,
|
| 419 |
+
... batch_size=batch_size,
|
| 420 |
+
... collate_fn=data_collator,
|
| 421 |
+
... )
|
| 422 |
+
```
|
| 423 |
+
|
| 424 |
+
予測から精度を計算し、モデルを 🤗 ハブにプッシュするには、[Keras callbacks](../main_classes/keras_callbacks) を使用します。
|
| 425 |
+
`compute_metrics` 関数を [`KerasMetricCallback`] に渡します。
|
| 426 |
+
そして [`PushToHubCallback`] を使用してモデルをアップロードします。
|
| 427 |
+
|
| 428 |
+
```py
|
| 429 |
+
>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
|
| 430 |
+
|
| 431 |
+
>>> metric_callback = KerasMetricCallback(
|
| 432 |
+
... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
|
| 433 |
+
... )
|
| 434 |
+
|
| 435 |
+
>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", image_processor=image_processor)
|
| 436 |
+
|
| 437 |
+
>>> callbacks = [metric_callback, push_to_hub_callback]
|
| 438 |
+
```
|
| 439 |
+
|
| 440 |
+
ついに、モデルをトレーニングする準備が整いました。`fit()`トレーニングおよび検証���ータセット、エポック数、
|
| 441 |
+
モデルを微調整するためのコールバック:
|
| 442 |
+
|
| 443 |
+
```py
|
| 444 |
+
>>> model.fit(
|
| 445 |
+
... tf_train_dataset,
|
| 446 |
+
... validation_data=tf_eval_dataset,
|
| 447 |
+
... callbacks=callbacks,
|
| 448 |
+
... epochs=num_epochs,
|
| 449 |
+
... )
|
| 450 |
+
```
|
| 451 |
+
|
| 452 |
+
おめでとう!モデルを微調整し、🤗 Hub で共有しました。これで推論に使用できるようになりました。
|
| 453 |
+
|
| 454 |
+
</tf>
|
| 455 |
+
</frameworkcontent>
|
| 456 |
+
|
| 457 |
+
|
| 458 |
+
## Inference
|
| 459 |
+
|
| 460 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 461 |
+
|
| 462 |
+
推論のために画像をロードします。
|
| 463 |
+
|
| 464 |
+
```py
|
| 465 |
+
>>> image = ds[0]["image"]
|
| 466 |
+
>>> image
|
| 467 |
+
```
|
| 468 |
+
|
| 469 |
+
<div class="flex justify-center">
|
| 470 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/semantic-seg-image.png" alt="Image of bedroom"/>
|
| 471 |
+
</div>
|
| 472 |
+
|
| 473 |
+
<frameworkcontent>
|
| 474 |
+
<pt>
|
| 475 |
+
|
| 476 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して画像セグメンテーション用の `pipeline` をインスタンス化し、それに画像を渡します。
|
| 477 |
+
|
| 478 |
+
```py
|
| 479 |
+
>>> from transformers import pipeline
|
| 480 |
+
|
| 481 |
+
>>> segmenter = pipeline("image-segmentation", model="my_awesome_seg_model")
|
| 482 |
+
>>> segmenter(image)
|
| 483 |
+
[{'score': None,
|
| 484 |
+
'label': 'wall',
|
| 485 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062690>},
|
| 486 |
+
{'score': None,
|
| 487 |
+
'label': 'sky',
|
| 488 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062A50>},
|
| 489 |
+
{'score': None,
|
| 490 |
+
'label': 'floor',
|
| 491 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062B50>},
|
| 492 |
+
{'score': None,
|
| 493 |
+
'label': 'ceiling',
|
| 494 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062A10>},
|
| 495 |
+
{'score': None,
|
| 496 |
+
'label': 'bed ',
|
| 497 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062E90>},
|
| 498 |
+
{'score': None,
|
| 499 |
+
'label': 'windowpane',
|
| 500 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062390>},
|
| 501 |
+
{'score': None,
|
| 502 |
+
'label': 'cabinet',
|
| 503 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062550>},
|
| 504 |
+
{'score': None,
|
| 505 |
+
'label': 'chair',
|
| 506 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062D90>},
|
| 507 |
+
{'score': None,
|
| 508 |
+
'label': 'armchair',
|
| 509 |
+
'mask': <PIL.Image.Image image mode=L size=640x427 at 0x7FD5B2062E10>}]
|
| 510 |
+
```
|
| 511 |
+
|
| 512 |
+
必要に応じて、`pipeline` の結果を手動で複製することもできます。画像プロセッサで画像を処理し、`pixel_values`を GPU に配置します。
|
| 513 |
+
|
| 514 |
+
```py
|
| 515 |
+
>>> device = torch.device("cuda" if torch.cuda.is_available() else "cpu") # use GPU if available, otherwise use a CPU
|
| 516 |
+
>>> encoding = image_processor(image, return_tensors="pt")
|
| 517 |
+
>>> pixel_values = encoding.pixel_values.to(device)
|
| 518 |
+
```
|
| 519 |
+
|
| 520 |
+
入力をモデルに渡し、「logits」を返します。
|
| 521 |
+
|
| 522 |
+
```py
|
| 523 |
+
>>> outputs = model(pixel_values=pixel_values)
|
| 524 |
+
>>> logits = outputs.logits.cpu()
|
| 525 |
+
```
|
| 526 |
+
|
| 527 |
+
次に、ロジットを元の画像サイズに再スケールします。
|
| 528 |
+
|
| 529 |
+
|
| 530 |
+
```py
|
| 531 |
+
>>> upsampled_logits = nn.functional.interpolate(
|
| 532 |
+
... logits,
|
| 533 |
+
... size=image.size[::-1],
|
| 534 |
+
... mode="bilinear",
|
| 535 |
+
... align_corners=False,
|
| 536 |
+
... )
|
| 537 |
+
|
| 538 |
+
>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
|
| 539 |
+
```
|
| 540 |
+
|
| 541 |
+
</pt>
|
| 542 |
+
</frameworkcontent>
|
| 543 |
+
|
| 544 |
+
<frameworkcontent>
|
| 545 |
+
<tf>
|
| 546 |
+
|
| 547 |
+
画像プロセッサをロードして画像を前処理し、入力を TensorFlow テンソルとして返します。
|
| 548 |
+
|
| 549 |
+
```py
|
| 550 |
+
>>> from transformers import AutoImageProcessor
|
| 551 |
+
|
| 552 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
|
| 553 |
+
>>> inputs = image_processor(image, return_tensors="tf")
|
| 554 |
+
```
|
| 555 |
+
|
| 556 |
+
入力をモデルに渡し、`logits`を返します。
|
| 557 |
+
|
| 558 |
+
```py
|
| 559 |
+
>>> from transformers import TFAutoModelForSemanticSegmentation
|
| 560 |
+
|
| 561 |
+
>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
|
| 562 |
+
>>> logits = model(**inputs).logits
|
| 563 |
+
```
|
| 564 |
+
|
| 565 |
+
次に、ロジットを元の画像サイズに再スケールし、クラス次元に argmax を適用します。
|
| 566 |
+
|
| 567 |
+
```py
|
| 568 |
+
>>> logits = tf.transpose(logits, [0, 2, 3, 1])
|
| 569 |
+
|
| 570 |
+
>>> upsampled_logits = tf.image.resize(
|
| 571 |
+
... logits,
|
| 572 |
+
... # We reverse the shape of `image` because `image.size` returns width and height.
|
| 573 |
+
... image.size[::-1],
|
| 574 |
+
... )
|
| 575 |
+
|
| 576 |
+
>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
|
| 577 |
+
```
|
| 578 |
+
|
| 579 |
+
</tf>
|
| 580 |
+
</frameworkcontent>
|
| 581 |
+
|
| 582 |
+
結果を視覚化するには、[データセット カラー パレット](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51) を、それぞれをマップする `ade_palette()` としてロードします。クラスを RGB 値に変換します。次に、画像と予測されたセグメンテーション マップを組み合わせてプロットできます。
|
| 583 |
+
|
| 584 |
+
```py
|
| 585 |
+
>>> import matplotlib.pyplot as plt
|
| 586 |
+
>>> import numpy as np
|
| 587 |
+
|
| 588 |
+
>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
|
| 589 |
+
>>> palette = np.array(ade_palette())
|
| 590 |
+
>>> for label, color in enumerate(palette):
|
| 591 |
+
... color_seg[pred_seg == label, :] = color
|
| 592 |
+
>>> color_seg = color_seg[..., ::-1] # convert to BGR
|
| 593 |
+
|
| 594 |
+
>>> img = np.array(image) * 0.5 + color_seg * 0.5 # plot the image with the segmentation map
|
| 595 |
+
>>> img = img.astype(np.uint8)
|
| 596 |
+
|
| 597 |
+
>>> plt.figure(figsize=(15, 10))
|
| 598 |
+
>>> plt.imshow(img)
|
| 599 |
+
>>> plt.show()
|
| 600 |
+
```
|
| 601 |
+
|
| 602 |
+
<div class="flex justify-center">
|
| 603 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/semantic-seg-preds.png" alt="Image of bedroom overlaid with segmentation map"/>
|
| 604 |
+
</div>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/summarization.md
ADDED
|
@@ -0,0 +1,404 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Summarization
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
<Youtube id="yHnr5Dk2zCI"/>
|
| 22 |
+
|
| 23 |
+
要約により、すべての重要な情報をまとめた短いバージョンの文書または記事が作成されます。これは、翻訳と並んで、シーケンス間のタスクとして定式化できるタスクのもう 1 つの例です。要約は次のようになります。
|
| 24 |
+
|
| 25 |
+
- 抽出: 文書から最も関連性の高い情報を抽出します。
|
| 26 |
+
- 抽象的: 最も関連性の高い情報を捉えた新しいテキストを生成します。
|
| 27 |
+
|
| 28 |
+
このガイドでは、次の方法を説明します。
|
| 29 |
+
|
| 30 |
+
1. 抽象的な要約のために、[BillSum](https://huggingface.co/datasets/billsum) データセットのカリフォルニア州請求書サブセットで [T5](https://huggingface.co/google-t5/t5-small) を微調整します。
|
| 31 |
+
2. 微調整したモデルを推論に使用します。
|
| 32 |
+
|
| 33 |
+
<Tip>
|
| 34 |
+
|
| 35 |
+
このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/summarization) を確認することをお勧めします。
|
| 36 |
+
|
| 37 |
+
</Tip>
|
| 38 |
+
|
| 39 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install transformers datasets evaluate rouge_score
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 46 |
+
|
| 47 |
+
```py
|
| 48 |
+
>>> from huggingface_hub import notebook_login
|
| 49 |
+
|
| 50 |
+
>>> notebook_login()
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
## Load BillSum dataset
|
| 54 |
+
|
| 55 |
+
まず、🤗 データセット ライブラリから BillSum データセットの小さいカリフォルニア州請求書サブセットを読み込みます。
|
| 56 |
+
|
| 57 |
+
```py
|
| 58 |
+
>>> from datasets import load_dataset
|
| 59 |
+
|
| 60 |
+
>>> billsum = load_dataset("billsum", split="ca_test")
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットをトレイン セットとテスト セットに分割します。
|
| 64 |
+
|
| 65 |
+
```py
|
| 66 |
+
>>> billsum = billsum.train_test_split(test_size=0.2)
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
次に、例を見てみましょう。
|
| 70 |
+
|
| 71 |
+
```py
|
| 72 |
+
>>> billsum["train"][0]
|
| 73 |
+
{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
|
| 74 |
+
'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
|
| 75 |
+
'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
使用するフィールドが 2 つあります。
|
| 79 |
+
|
| 80 |
+
- `text`: モデルへの入力となる請求書のテキスト。
|
| 81 |
+
- `summary`: モデルのターゲットとなる `text` の要約版。
|
| 82 |
+
|
| 83 |
+
## Preprocess
|
| 84 |
+
|
| 85 |
+
次のステップでは、T5 トークナイザーをロードして「text」と`summary`を処理します。
|
| 86 |
+
|
| 87 |
+
```py
|
| 88 |
+
>>> from transformers import AutoTokenizer
|
| 89 |
+
|
| 90 |
+
>>> checkpoint = "google-t5/t5-small"
|
| 91 |
+
>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
作成する前処理関数は次のことを行う必要があります。
|
| 95 |
+
|
| 96 |
+
1. T5 がこれが要約タスクであることを認識できるように、入力の前にプロンプトを付けます。複数の NLP タスクが可能な一部のモデルでは、特定のタスクのプロンプトが必要です。
|
| 97 |
+
2. ラベルをトークン化するときにキーワード `text_target` 引数を使用します。
|
| 98 |
+
3. `max_length`パラメータで設定された最大長を超えないようにシーケンスを切り詰めます。
|
| 99 |
+
|
| 100 |
+
```py
|
| 101 |
+
>>> prefix = "summarize: "
|
| 102 |
+
|
| 103 |
+
|
| 104 |
+
>>> def preprocess_function(examples):
|
| 105 |
+
... inputs = [prefix + doc for doc in examples["text"]]
|
| 106 |
+
... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
|
| 107 |
+
|
| 108 |
+
... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
|
| 109 |
+
|
| 110 |
+
... model_inputs["labels"] = labels["input_ids"]
|
| 111 |
+
... return model_inputs
|
| 112 |
+
```
|
| 113 |
+
|
| 114 |
+
データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` 関数を高速化できます。
|
| 115 |
+
|
| 116 |
+
```py
|
| 117 |
+
>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
次に、[`DataCollatorForSeq2Seq`] を使用してサンプルのバッチを作成します。データセット全体を最大長までパディングするのではなく、照合中にバッチ内の最長の長さまで文を *動的にパディング* する方が効率的です。
|
| 121 |
+
|
| 122 |
+
<frameworkcontent>
|
| 123 |
+
<pt>
|
| 124 |
+
|
| 125 |
+
```py
|
| 126 |
+
>>> from transformers import DataCollatorForSeq2Seq
|
| 127 |
+
|
| 128 |
+
>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
|
| 129 |
+
```
|
| 130 |
+
</pt>
|
| 131 |
+
<tf>
|
| 132 |
+
|
| 133 |
+
```py
|
| 134 |
+
>>> from transformers import DataCollatorForSeq2Seq
|
| 135 |
+
|
| 136 |
+
>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
|
| 137 |
+
```
|
| 138 |
+
</tf>
|
| 139 |
+
</frameworkcontent>
|
| 140 |
+
|
| 141 |
+
## Evaluate
|
| 142 |
+
|
| 143 |
+
トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) メトリックを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスをロードして計算する方法の詳細については、次を参照してください)。
|
| 144 |
+
|
| 145 |
+
```py
|
| 146 |
+
>>> import evaluate
|
| 147 |
+
|
| 148 |
+
>>> rouge = evaluate.load("rouge")
|
| 149 |
+
```
|
| 150 |
+
|
| 151 |
+
次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して ROUGE メトリクスを計算する関数を作成します。
|
| 152 |
+
|
| 153 |
+
```py
|
| 154 |
+
>>> import numpy as np
|
| 155 |
+
|
| 156 |
+
|
| 157 |
+
>>> def compute_metrics(eval_pred):
|
| 158 |
+
... predictions, labels = eval_pred
|
| 159 |
+
... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
|
| 160 |
+
... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
|
| 161 |
+
... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
|
| 162 |
+
|
| 163 |
+
... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
|
| 164 |
+
|
| 165 |
+
... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
|
| 166 |
+
... result["gen_len"] = np.mean(prediction_lens)
|
| 167 |
+
|
| 168 |
+
... return {k: round(v, 4) for k, v in result.items()}
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
|
| 172 |
+
|
| 173 |
+
## Train
|
| 174 |
+
|
| 175 |
+
<frameworkcontent>
|
| 176 |
+
<pt>
|
| 177 |
+
<Tip>
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
|
| 181 |
+
|
| 182 |
+
</Tip>
|
| 183 |
+
|
| 184 |
+
これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSeq2SeqLM`] を使用して T5 をロードします。
|
| 185 |
+
|
| 186 |
+
|
| 187 |
+
```py
|
| 188 |
+
>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
|
| 189 |
+
|
| 190 |
+
>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
この時点で残っている手順は次の 3 つだけです。
|
| 194 |
+
|
| 195 |
+
1. [`Seq2SeqTrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は ROUGE メトリクスを評価し、トレーニング チェックポイントを保存します。
|
| 196 |
+
2. トレーニング引数をモデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Seq2SeqTrainer`] に渡します。
|
| 197 |
+
3. [`~Trainer.train`] を呼び出してモデルを微調整します。
|
| 198 |
+
|
| 199 |
+
```py
|
| 200 |
+
>>> training_args = Seq2SeqTrainingArguments(
|
| 201 |
+
... output_dir="my_awesome_billsum_model",
|
| 202 |
+
... eval_strategy="epoch",
|
| 203 |
+
... learning_rate=2e-5,
|
| 204 |
+
... per_device_train_batch_size=16,
|
| 205 |
+
... per_device_eval_batch_size=16,
|
| 206 |
+
... weight_decay=0.01,
|
| 207 |
+
... save_total_limit=3,
|
| 208 |
+
... num_train_epochs=4,
|
| 209 |
+
... predict_with_generate=True,
|
| 210 |
+
... fp16=True,
|
| 211 |
+
... push_to_hub=True,
|
| 212 |
+
... )
|
| 213 |
+
|
| 214 |
+
>>> trainer = Seq2SeqTrainer(
|
| 215 |
+
... model=model,
|
| 216 |
+
... args=training_args,
|
| 217 |
+
... train_dataset=tokenized_billsum["train"],
|
| 218 |
+
... eval_dataset=tokenized_billsum["test"],
|
| 219 |
+
... processing_class=tokenizer,
|
| 220 |
+
... data_collator=data_collator,
|
| 221 |
+
... compute_metrics=compute_metrics,
|
| 222 |
+
... )
|
| 223 |
+
|
| 224 |
+
>>> trainer.train()
|
| 225 |
+
```
|
| 226 |
+
|
| 227 |
+
トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
|
| 228 |
+
|
| 229 |
+
```py
|
| 230 |
+
>>> trainer.push_to_hub()
|
| 231 |
+
```
|
| 232 |
+
</pt>
|
| 233 |
+
<tf>
|
| 234 |
+
<Tip>
|
| 235 |
+
|
| 236 |
+
Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
|
| 237 |
+
|
| 238 |
+
</Tip>
|
| 239 |
+
TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
|
| 240 |
+
|
| 241 |
+
```py
|
| 242 |
+
>>> from transformers import create_optimizer, AdamWeightDecay
|
| 243 |
+
|
| 244 |
+
>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
|
| 245 |
+
```
|
| 246 |
+
|
| 247 |
+
次に、[`TFAutoModelForSeq2SeqLM`] を使用して T5 をロードできます。
|
| 248 |
+
|
| 249 |
+
|
| 250 |
+
```py
|
| 251 |
+
>>> from transformers import TFAutoModelForSeq2SeqLM
|
| 252 |
+
|
| 253 |
+
>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
|
| 254 |
+
```
|
| 255 |
+
|
| 256 |
+
[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
|
| 257 |
+
|
| 258 |
+
```py
|
| 259 |
+
>>> tf_train_set = model.prepare_tf_dataset(
|
| 260 |
+
... tokenized_billsum["train"],
|
| 261 |
+
... shuffle=True,
|
| 262 |
+
... batch_size=16,
|
| 263 |
+
... collate_fn=data_collator,
|
| 264 |
+
... )
|
| 265 |
+
|
| 266 |
+
>>> tf_test_set = model.prepare_tf_dataset(
|
| 267 |
+
... tokenized_billsum["test"],
|
| 268 |
+
... shuffle=False,
|
| 269 |
+
... batch_size=16,
|
| 270 |
+
... collate_fn=data_collator,
|
| 271 |
+
... )
|
| 272 |
+
```
|
| 273 |
+
|
| 274 |
+
[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
|
| 275 |
+
|
| 276 |
+
```py
|
| 277 |
+
>>> import tensorflow as tf
|
| 278 |
+
|
| 279 |
+
>>> model.compile(optimizer=optimizer) # No loss argument!
|
| 280 |
+
```
|
| 281 |
+
|
| 282 |
+
トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から ROUGE スコアを計算し、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
|
| 283 |
+
|
| 284 |
+
`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
|
| 285 |
+
|
| 286 |
+
```py
|
| 287 |
+
>>> from transformers.keras_callbacks import KerasMetricCallback
|
| 288 |
+
|
| 289 |
+
>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
|
| 290 |
+
```
|
| 291 |
+
|
| 292 |
+
Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
|
| 293 |
+
|
| 294 |
+
```py
|
| 295 |
+
>>> from transformers.keras_callbacks import PushToHubCallback
|
| 296 |
+
|
| 297 |
+
>>> push_to_hub_callback = PushToHubCallback(
|
| 298 |
+
... output_dir="my_awesome_billsum_model",
|
| 299 |
+
... tokenizer=tokenizer,
|
| 300 |
+
... )
|
| 301 |
+
```
|
| 302 |
+
|
| 303 |
+
次に、コールバックをまとめてバンドルします。
|
| 304 |
+
|
| 305 |
+
```py
|
| 306 |
+
>>> callbacks = [metric_callback, push_to_hub_callback]
|
| 307 |
+
```
|
| 308 |
+
|
| 309 |
+
ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、��ールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
|
| 310 |
+
|
| 311 |
+
```py
|
| 312 |
+
>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
|
| 313 |
+
```
|
| 314 |
+
|
| 315 |
+
トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
|
| 316 |
+
|
| 317 |
+
</tf>
|
| 318 |
+
</frameworkcontent>
|
| 319 |
+
|
| 320 |
+
<Tip>
|
| 321 |
+
|
| 322 |
+
要約用にモデルを微調整する方法のより詳細な例については、対応するセクションを参照してください。
|
| 323 |
+
[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
|
| 324 |
+
または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb)。
|
| 325 |
+
|
| 326 |
+
</Tip>
|
| 327 |
+
|
| 328 |
+
## Inference
|
| 329 |
+
|
| 330 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 331 |
+
|
| 332 |
+
要約したいテキストを考え出します。 T5 の場合、作業中のタスクに応じて入力に接頭辞を付ける必要があります。要約するには、以下に示すように入力にプレフィックスを付ける必要があります。
|
| 333 |
+
|
| 334 |
+
```py
|
| 335 |
+
>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
|
| 336 |
+
```
|
| 337 |
+
|
| 338 |
+
推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して要約用の `pipeline` をインスタンス化し、テキストをそれに渡します。
|
| 339 |
+
|
| 340 |
+
```py
|
| 341 |
+
>>> from transformers import pipeline
|
| 342 |
+
|
| 343 |
+
>>> summarizer = pipeline("summarization", model="stevhliu/my_awesome_billsum_model")
|
| 344 |
+
>>> summarizer(text)
|
| 345 |
+
[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
|
| 346 |
+
```
|
| 347 |
+
|
| 348 |
+
必要に応じて、`pipeline`」の結果を手動で複製することもできます。
|
| 349 |
+
|
| 350 |
+
<frameworkcontent>
|
| 351 |
+
<pt>
|
| 352 |
+
Tokenize the text and return the `input_ids` as PyTorch tensors:
|
| 353 |
+
|
| 354 |
+
```py
|
| 355 |
+
>>> from transformers import AutoTokenizer
|
| 356 |
+
|
| 357 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
|
| 358 |
+
>>> inputs = tokenizer(text, return_tensors="pt").input_ids
|
| 359 |
+
```
|
| 360 |
+
|
| 361 |
+
[`~generation.GenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
|
| 362 |
+
|
| 363 |
+
```py
|
| 364 |
+
>>> from transformers import AutoModelForSeq2SeqLM
|
| 365 |
+
|
| 366 |
+
>>> model = AutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
|
| 367 |
+
>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
|
| 368 |
+
```
|
| 369 |
+
|
| 370 |
+
生成されたトークン ID をデコードしてテキストに戻します。
|
| 371 |
+
|
| 372 |
+
```py
|
| 373 |
+
>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
|
| 374 |
+
'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
|
| 375 |
+
```
|
| 376 |
+
</pt>
|
| 377 |
+
<tf>
|
| 378 |
+
|
| 379 |
+
テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。
|
| 380 |
+
|
| 381 |
+
```py
|
| 382 |
+
>>> from transformers import AutoTokenizer
|
| 383 |
+
|
| 384 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
|
| 385 |
+
>>> inputs = tokenizer(text, return_tensors="tf").input_ids
|
| 386 |
+
```
|
| 387 |
+
|
| 388 |
+
[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
|
| 389 |
+
|
| 390 |
+
```py
|
| 391 |
+
>>> from transformers import TFAutoModelForSeq2SeqLM
|
| 392 |
+
|
| 393 |
+
>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
|
| 394 |
+
>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
|
| 395 |
+
```
|
| 396 |
+
|
| 397 |
+
生成されたトークン ID をデコードしてテキストに戻します。
|
| 398 |
+
|
| 399 |
+
```py
|
| 400 |
+
>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
|
| 401 |
+
'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
|
| 402 |
+
```
|
| 403 |
+
</tf>
|
| 404 |
+
</frameworkcontent>
|
tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/text-to-speech.md
ADDED
|
@@ -0,0 +1,638 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
⚠️ Note that this file is in Markdown but contain specific syntax for our doc-builder (similar to MDX) that may not be
|
| 13 |
+
rendered properly in your Markdown viewer.
|
| 14 |
+
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Text to speech
|
| 18 |
+
|
| 19 |
+
[[open-in-colab]]
|
| 20 |
+
|
| 21 |
+
テキスト読み上げ (TTS) は、テキストから自然な音声を作成するタスクです。音声は複数の形式で生成できます。
|
| 22 |
+
言語と複数の話者向け。現在、いくつかのテキスト読み上げモデルが 🤗 Transformers で利用可能です。
|
| 23 |
+
[Bark](../model_doc/bark)、[MMS](../model_doc/mms)、[VITS](../model_doc/vits)、および [SpeechT5](../model_doc/speecht5)。
|
| 24 |
+
|
| 25 |
+
`text-to-audio`パイプライン (またはその別名 - `text-to-speech`) を使用して、音声を簡単に生成できます。 Bark などの一部のモデルは、
|
| 26 |
+
笑い、ため息、泣きなどの非言語コミュニケーションを生成したり、音楽を追加したりするように条件付けすることもできます。
|
| 27 |
+
Bark で`text-to-speech`パイプラインを使用する方法の例を次に示します。
|
| 28 |
+
|
| 29 |
+
```py
|
| 30 |
+
>>> from transformers import pipeline
|
| 31 |
+
|
| 32 |
+
>>> pipe = pipeline("text-to-speech", model="suno/bark-small")
|
| 33 |
+
>>> text = "[clears throat] This is a test ... and I just took a long pause."
|
| 34 |
+
>>> output = pipe(text)
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
ノートブックで結果の音声を聞くために使用できるコード スニペットを次に示します。
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
>>> from IPython.display import Audio
|
| 41 |
+
>>> Audio(output["audio"], rate=output["sampling_rate"])
|
| 42 |
+
```
|
| 43 |
+
Bark およびその他の事前トレーニングされた TTS モデルができることの詳細な例については、次のドキュメントを参照してください。
|
| 44 |
+
[音声コース](https://huggingface.co/learn/audio-course/chapter6/pre-trained_models)。
|
| 45 |
+
|
| 46 |
+
TTS モデルを微調整する場合、現在微調整できるのは SpeechT5 のみです。 SpeechT5 は、次の組み合わせで事前トレーニングされています。
|
| 47 |
+
音声からテキストへのデータとテキストから音声へのデータ。両方のテキストに共有される隠された表現の統一された空間を学習できるようにします。
|
| 48 |
+
そしてスピーチ。これは、同じ事前トレーニング済みモデルをさまざまなタスクに合わせて微調整できることを意味します。さらに、SpeechT5
|
| 49 |
+
X ベクトル スピーカーの埋め込みを通じて複数のスピーカーをサポートします。
|
| 50 |
+
|
| 51 |
+
このガイドの残りの部分では、次の方法を説明します。
|
| 52 |
+
|
| 53 |
+
1. [VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) のオランダ語 (`nl`) 言語サブセット上の英語音声で元々トレーニングされた [SpeechT5](../model_doc/speecht5) を微調整します。 データセット。
|
| 54 |
+
2. パイプラインを使用するか直接使用するかの 2 つの方法のいずれかで、洗練されたモデルを推論に使用します。
|
| 55 |
+
|
| 56 |
+
始める前に、必要なライブラリがすべてインストールされていることを確認してください。
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
```bash
|
| 60 |
+
pip install datasets soundfile speechbrain accelerate
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
SpeechT5 のすべての機能がまだ正式リリースにマージされていないため、ソースから 🤗Transformers をインストールします。
|
| 64 |
+
|
| 65 |
+
```bash
|
| 66 |
+
pip install git+https://github.com/huggingface/transformers.git
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
<Tip>
|
| 70 |
+
|
| 71 |
+
このガイドに従うには、GPU が必要です。ノートブックで作業している場合は、次の行を実行して GPU が利用可能かどうかを確認します。
|
| 72 |
+
|
| 73 |
+
```bash
|
| 74 |
+
!nvidia-smi
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
</Tip>
|
| 78 |
+
|
| 79 |
+
Hugging Face アカウントにログインして、モデルをアップロードしてコミュニティと共有することをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
|
| 80 |
+
|
| 81 |
+
```py
|
| 82 |
+
>>> from huggingface_hub import notebook_login
|
| 83 |
+
|
| 84 |
+
>>> notebook_login()
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
## Load the dataset
|
| 88 |
+
|
| 89 |
+
[VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) は、以下で構成される大規模な多言語音声コーパスです。
|
| 90 |
+
データは 2009 年から 2020 年の欧州議会のイベント記録をソースとしています。 15 件分のラベル付き音声文字起こしデータが含まれています。
|
| 91 |
+
ヨーロッパの言語。このガイドではオランダ語のサブセットを使用していますが、自由に別のサブセットを選択してください。
|
| 92 |
+
|
| 93 |
+
VoxPopuli またはその他の自動音声認識 (ASR) データセットは最適ではない可能性があることに注意してください。
|
| 94 |
+
TTS モデルをトレーニングするためのオプション。過剰なバックグラウンドノイズなど、ASR にとって有益となる機能は次のとおりです。
|
| 95 |
+
通常、TTS では望ましくありません。ただし、最高品質、多言語、マルチスピーカーの TTS データセットを見つけるのは非常に困難な場合があります。
|
| 96 |
+
挑戦的。
|
| 97 |
+
|
| 98 |
+
データをロードしましょう:
|
| 99 |
+
|
| 100 |
+
```py
|
| 101 |
+
>>> from datasets import load_dataset, Audio
|
| 102 |
+
|
| 103 |
+
>>> dataset = load_dataset("facebook/voxpopuli", "nl", split="train")
|
| 104 |
+
>>> len(dataset)
|
| 105 |
+
20968
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
微調整には 20968 個の例で十分です。 SpeechT5 はオーディオ データのサンプリング レートが 16 kHz であることを想定しているため、
|
| 109 |
+
データセット内の例がこの要件を満たしていることを確認してください。
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
```py
|
| 113 |
+
dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
## Preprocess the data
|
| 117 |
+
|
| 118 |
+
使用するモデル チェックポイントを定義し、適切なプロセッサをロードすることから始めましょう。
|
| 119 |
+
|
| 120 |
+
|
| 121 |
+
```py
|
| 122 |
+
>>> from transformers import SpeechT5Processor
|
| 123 |
+
|
| 124 |
+
>>> checkpoint = "microsoft/speecht5_tts"
|
| 125 |
+
>>> processor = SpeechT5Processor.from_pretrained(checkpoint)
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
### Text cleanup for SpeechT5 tokenization
|
| 129 |
+
|
| 130 |
+
|
| 131 |
+
まずはテキストデータをクリーンアップすることから始めます。テキストを処理するには、プロセッサのトークナイザー部分が必要です。
|
| 132 |
+
|
| 133 |
+
```py
|
| 134 |
+
>>> tokenizer = processor.tokenizer
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
データセットの例には、`raw_text`機能と `normalized_text`機能が含まれています。テキスト入力としてどの機能を使用するかを決めるときは、
|
| 138 |
+
SpeechT5 トークナイザーには数値のトークンがないことを考慮してください。 `normalized_text`には数字が書かれています
|
| 139 |
+
テキストとして出力します。したがって、これはより適切であり、入力テキストとして `normalized_text` を使用することをお勧めします。
|
| 140 |
+
|
| 141 |
+
SpeechT5 は英語でトレーニングされているため、オランダ語のデータセット内の特定の文字を認識しない可能性があります。もし
|
| 142 |
+
残っているように、これらの文字は `<unk>`トークンに変換されます。ただし、オランダ語では、`à`などの特定の文字は
|
| 143 |
+
音節を強調することに慣れています。テキストの意味を保持するために、この文字を通常の`a`に置き換えることができます。
|
| 144 |
+
|
| 145 |
+
サポートされていないトークンを識別するには、`SpeechT5Tokenizer`を使用してデータセット内のすべての一意の文字を抽出します。
|
| 146 |
+
文字をトークンとして扱います。これを行うには、以下を連結する `extract_all_chars` マッピング関数を作成します。
|
| 147 |
+
すべての例からの転写を 1 つの文字列にまとめ、それを文字セットに変換します。
|
| 148 |
+
すべての文字起こしが一度に利用できるように、`dataset.map()`で`batched=True`と`batch_size=-1`を必ず設定してください。
|
| 149 |
+
マッピング機能。
|
| 150 |
+
|
| 151 |
+
```py
|
| 152 |
+
>>> def extract_all_chars(batch):
|
| 153 |
+
... all_text = " ".join(batch["normalized_text"])
|
| 154 |
+
... vocab = list(set(all_text))
|
| 155 |
+
... return {"vocab": [vocab], "all_text": [all_text]}
|
| 156 |
+
|
| 157 |
+
|
| 158 |
+
>>> vocabs = dataset.map(
|
| 159 |
+
... extract_all_chars,
|
| 160 |
+
... batched=True,
|
| 161 |
+
... batch_size=-1,
|
| 162 |
+
... keep_in_memory=True,
|
| 163 |
+
... remove_columns=dataset.column_names,
|
| 164 |
+
... )
|
| 165 |
+
|
| 166 |
+
>>> dataset_vocab = set(vocabs["vocab"][0])
|
| 167 |
+
>>> tokenizer_vocab = {k for k, _ in tokenizer.get_vocab().items()}
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
これで、2 つの文字セットができました。1 つはデータセットの語彙を持ち、もう 1 つはトークナイザーの語彙を持ちます。
|
| 171 |
+
データセット内でサポートされていない文字を特定するには、これら 2 つのセットの差分を取ることができます。結果として
|
| 172 |
+
set には、データセットにはあるがトークナイザーには含まれていない文字が含まれます。
|
| 173 |
+
|
| 174 |
+
```py
|
| 175 |
+
>>> dataset_vocab - tokenizer_vocab
|
| 176 |
+
{' ', 'à', 'ç', 'è', 'ë', 'í', 'ï', 'ö', 'ü'}
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
前の手順で特定されたサポートされていない文字を処理するには、これらの文字を
|
| 180 |
+
有効なトークン。スペースはトークナイザーですでに `▁` に置き換えられているため、個別に処理する必要がないことに注意してください。
|
| 181 |
+
|
| 182 |
+
```py
|
| 183 |
+
>>> replacements = [
|
| 184 |
+
... ("à", "a"),
|
| 185 |
+
... ("ç", "c"),
|
| 186 |
+
... ("è", "e"),
|
| 187 |
+
... ("ë", "e"),
|
| 188 |
+
... ("í", "i"),
|
| 189 |
+
... ("ï", "i"),
|
| 190 |
+
... ("ö", "o"),
|
| 191 |
+
... ("ü", "u"),
|
| 192 |
+
... ]
|
| 193 |
+
|
| 194 |
+
|
| 195 |
+
>>> def cleanup_text(inputs):
|
| 196 |
+
... for src, dst in replacements:
|
| 197 |
+
... inputs["normalized_text"] = inputs["normalized_text"].replace(src, dst)
|
| 198 |
+
... return inputs
|
| 199 |
+
|
| 200 |
+
|
| 201 |
+
>>> dataset = dataset.map(cleanup_text)
|
| 202 |
+
```
|
| 203 |
+
|
| 204 |
+
テキスト内の特殊文字を扱ったので、今度は音声データに焦点を移します。
|
| 205 |
+
|
| 206 |
+
### Speakers
|
| 207 |
+
|
| 208 |
+
VoxPopuli データセットには複数の話者の音声が含まれていますが、データセットには何人の話者が含まれているのでしょうか?に
|
| 209 |
+
これを決定すると、一意の話者の数と、各話者がデータセットに寄与する例の数を数えることができます。
|
| 210 |
+
データセットには合計 20,968 個の例が含まれており、この情報により、分布をより深く理解できるようになります。
|
| 211 |
+
講演者とデータ内の例。
|
| 212 |
+
|
| 213 |
+
```py
|
| 214 |
+
>>> from collections import defaultdict
|
| 215 |
+
|
| 216 |
+
>>> speaker_counts = defaultdict(int)
|
| 217 |
+
|
| 218 |
+
>>> for speaker_id in dataset["speaker_id"]:
|
| 219 |
+
... speaker_counts[speaker_id] += 1
|
| 220 |
+
```
|
| 221 |
+
|
| 222 |
+
ヒストグラムをプロットすると、各話者にどれだけのデータがあるかを把握できます。
|
| 223 |
+
|
| 224 |
+
```py
|
| 225 |
+
>>> import matplotlib.pyplot as plt
|
| 226 |
+
|
| 227 |
+
>>> plt.figure()
|
| 228 |
+
>>> plt.hist(speaker_counts.values(), bins=20)
|
| 229 |
+
>>> plt.ylabel("Speakers")
|
| 230 |
+
>>> plt.xlabel("Examples")
|
| 231 |
+
>>> plt.show()
|
| 232 |
+
```
|
| 233 |
+
|
| 234 |
+
<div class="flex justify-center">
|
| 235 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/tts_speakers_histogram.png" alt="Speakers histogram"/>
|
| 236 |
+
</div>
|
| 237 |
+
|
| 238 |
+
ヒストグラムから、データセット内の話者の約 3 分の 1 の例が 100 未満であることがわかります。
|
| 239 |
+
約 10 人の講演者が 500 以上の例を持っています。トレーニング効率を向上させ、データセットのバランスをとるために、次のことを制限できます。
|
| 240 |
+
100 ~ 400 個の例を含むデータを講演者に提供します。
|
| 241 |
+
|
| 242 |
+
```py
|
| 243 |
+
>>> def select_speaker(speaker_id):
|
| 244 |
+
... return 100 <= speaker_counts[speaker_id] <= 400
|
| 245 |
+
|
| 246 |
+
|
| 247 |
+
>>> dataset = dataset.filter(select_speaker, input_columns=["speaker_id"])
|
| 248 |
+
```
|
| 249 |
+
|
| 250 |
+
残りのスピーカーの数を確認してみましょう。
|
| 251 |
+
|
| 252 |
+
```py
|
| 253 |
+
>>> len(set(dataset["speaker_id"]))
|
| 254 |
+
42
|
| 255 |
+
```
|
| 256 |
+
|
| 257 |
+
残りの例がいくつあるか見てみましょう。
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
```py
|
| 261 |
+
>>> len(dataset)
|
| 262 |
+
9973
|
| 263 |
+
```
|
| 264 |
+
|
| 265 |
+
約 40 人のユニークな講演者からの 10,000 弱の例が残りますが、これで十分です。
|
| 266 |
+
|
| 267 |
+
例が少ないスピーカーの中には、例が長い場合、実際にはより多くの音声が利用できる場合があることに注意してください。しかし、
|
| 268 |
+
各話者の音声の合計量を決定するには、データセット全体をスキャンする必要があります。
|
| 269 |
+
各オーディオ ファイルのロードとデコードを伴う時間のかかるプロセス。そのため、ここではこのステップをスキップすることにしました。
|
| 270 |
+
|
| 271 |
+
### Speaker embeddings
|
| 272 |
+
|
| 273 |
+
TTS モデルが複数のスピーカーを区別できるようにするには、サンプルごとにスピーカーの埋め込みを作成する必要があります。
|
| 274 |
+
スピーカーの埋め込みは、特定のスピーカーの音声特性をキャプチャするモデルへの追加入力です。
|
| 275 |
+
これらのスピーカー埋め込みを生成するには、事前トレーニングされた [spkrec-xvect-voxceleb](https://huggingface.co/speechbrain/spkrec-xvect-voxceleb) を使用します。
|
| 276 |
+
SpeechBrain のモデル。
|
| 277 |
+
|
| 278 |
+
入力オーディオ波形を受け取り、512 要素のベクトルを出力する関数 `create_speaker_embedding()` を作成します。
|
| 279 |
+
対応するスピーカー埋め込みが含まれます。
|
| 280 |
+
|
| 281 |
+
|
| 282 |
+
```py
|
| 283 |
+
>>> import os
|
| 284 |
+
>>> import torch
|
| 285 |
+
>>> from speechbrain.pretrained import EncoderClassifier
|
| 286 |
+
|
| 287 |
+
>>> spk_model_name = "speechbrain/spkrec-xvect-voxceleb"
|
| 288 |
+
|
| 289 |
+
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
|
| 290 |
+
>>> speaker_model = EncoderClassifier.from_hparams(
|
| 291 |
+
... source=spk_model_name,
|
| 292 |
+
... run_opts={"device": device},
|
| 293 |
+
... savedir=os.path.join("/tmp", spk_model_name),
|
| 294 |
+
... )
|
| 295 |
+
|
| 296 |
+
|
| 297 |
+
>>> def create_speaker_embedding(waveform):
|
| 298 |
+
... with torch.no_grad():
|
| 299 |
+
... speaker_embeddings = speaker_model.encode_batch(torch.tensor(waveform))
|
| 300 |
+
... speaker_embeddings = torch.nn.functional.normalize(speaker_embeddings, dim=2)
|
| 301 |
+
... speaker_embeddings = speaker_embeddings.squeeze().cpu().numpy()
|
| 302 |
+
... return speaker_embeddings
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
`speechbrain/spkrec-xvect-voxceleb`モデルは、VoxCeleb からの英語音声でトレーニングされたことに注意することが重要です。
|
| 306 |
+
データセットですが、このガイドのトレーニング例はオランダ語です。このモデルは今後も生成されると信じていますが、
|
| 307 |
+
オランダ語のデータセットに適切な話者埋め込みを行っても、この仮定はすべての場合に当てはまらない可能性があります。
|
| 308 |
+
|
| 309 |
+
最適な結果を得るには、最初にターゲット音声で X ベクトル モデルをトレーニングすることをお��めします。これにより、モデルが確実に
|
| 310 |
+
オランダ語に存在する独特の音声特徴をよりよく捉えることができます。
|
| 311 |
+
|
| 312 |
+
### Processing the dataset
|
| 313 |
+
|
| 314 |
+
最後に、モデルが期待する形式にデータを処理しましょう。を取り込む `prepare_dataset` 関数を作成します。
|
| 315 |
+
これは 1 つの例であり、`SpeechT5Processor` オブジェクトを使用して入力テキストをトークン化し、ターゲット オーディオをログメル スペクトログラムにロードします。
|
| 316 |
+
また、追加の入力としてスピーカーの埋め込みも追加する必要があります。
|
| 317 |
+
|
| 318 |
+
```py
|
| 319 |
+
>>> def prepare_dataset(example):
|
| 320 |
+
... audio = example["audio"]
|
| 321 |
+
|
| 322 |
+
... example = processor(
|
| 323 |
+
... text=example["normalized_text"],
|
| 324 |
+
... audio_target=audio["array"],
|
| 325 |
+
... sampling_rate=audio["sampling_rate"],
|
| 326 |
+
... return_attention_mask=False,
|
| 327 |
+
... )
|
| 328 |
+
|
| 329 |
+
... # strip off the batch dimension
|
| 330 |
+
... example["labels"] = example["labels"][0]
|
| 331 |
+
|
| 332 |
+
... # use SpeechBrain to obtain x-vector
|
| 333 |
+
... example["speaker_embeddings"] = create_speaker_embedding(audio["array"])
|
| 334 |
+
|
| 335 |
+
... return example
|
| 336 |
+
```
|
| 337 |
+
|
| 338 |
+
単一の例を見て、処理が正しいことを確認します。
|
| 339 |
+
|
| 340 |
+
```py
|
| 341 |
+
>>> processed_example = prepare_dataset(dataset[0])
|
| 342 |
+
>>> list(processed_example.keys())
|
| 343 |
+
['input_ids', 'labels', 'stop_labels', 'speaker_embeddings']
|
| 344 |
+
```
|
| 345 |
+
スピーカーのエンベディングは 512 要素のベクトルである必要があります。
|
| 346 |
+
|
| 347 |
+
```py
|
| 348 |
+
>>> processed_example["speaker_embeddings"].shape
|
| 349 |
+
(512,)
|
| 350 |
+
```
|
| 351 |
+
|
| 352 |
+
ラベルは、80 メル ビンを含むログメル スペクトログラムである必要があります。
|
| 353 |
+
|
| 354 |
+
```py
|
| 355 |
+
>>> import matplotlib.pyplot as plt
|
| 356 |
+
|
| 357 |
+
>>> plt.figure()
|
| 358 |
+
>>> plt.imshow(processed_example["labels"].T)
|
| 359 |
+
>>> plt.show()
|
| 360 |
+
```
|
| 361 |
+
|
| 362 |
+
<div class="flex justify-center">
|
| 363 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/tts_logmelspectrogram_1.png" alt="Log-mel spectrogram with 80 mel bins"/>
|
| 364 |
+
</div>
|
| 365 |
+
|
| 366 |
+
補足: このスペクトログラムがわかりにくいと感じる場合は、低周波を配置する規則に慣れていることが原因である可能性があります。
|
| 367 |
+
プロットの下部に高周波、上部に高周波が表示されます。ただし、matplotlib ライブラリを使用してスペクトログラムを画像としてプロットする場合、
|
| 368 |
+
Y 軸が反転され、スペクトログラムが上下逆に表示されます。
|
| 369 |
+
|
| 370 |
+
次に、処理関数をデータセット全体に適用します。これには 5 ~ 10 分かかります。
|
| 371 |
+
|
| 372 |
+
```py
|
| 373 |
+
>>> dataset = dataset.map(prepare_dataset, remove_columns=dataset.column_names)
|
| 374 |
+
```
|
| 375 |
+
|
| 376 |
+
データセット内の一部の例が、モデルが処理できる最大入力長 (600 トークン) を超えていることを示す警告が表示されます。
|
| 377 |
+
それらの例をデータセットから削除します。ここではさらに進んで、より大きなバッチ サイズを可能にするために、200 トークンを超えるものはすべて削除します。
|
| 378 |
+
|
| 379 |
+
```py
|
| 380 |
+
>>> def is_not_too_long(input_ids):
|
| 381 |
+
... input_length = len(input_ids)
|
| 382 |
+
... return input_length < 200
|
| 383 |
+
|
| 384 |
+
|
| 385 |
+
>>> dataset = dataset.filter(is_not_too_long, input_columns=["input_ids"])
|
| 386 |
+
>>> len(dataset)
|
| 387 |
+
8259
|
| 388 |
+
```
|
| 389 |
+
|
| 390 |
+
次に、基本的なトレーニング/テスト分割を作成します。
|
| 391 |
+
|
| 392 |
+
```py
|
| 393 |
+
>>> dataset = dataset.train_test_split(test_size=0.1)
|
| 394 |
+
```
|
| 395 |
+
|
| 396 |
+
### Data collator
|
| 397 |
+
|
| 398 |
+
複数の例を 1 つのバッチに結合するには、カスタム データ照合器を定義する必要があります。このコレーターは、短いシーケンスをパディングで埋め込みます。
|
| 399 |
+
トークンを使用して、すべての例が同じ長さになるようにします。スペクトログラム ラベルの場合、埋め込まれた部分は特別な値 `-100` に置き換えられます。この特別な価値は
|
| 400 |
+
スペクトログラム損失を計算するときに、スペクトログラムのその部分を無視するようにモデルに指示します。
|
| 401 |
+
|
| 402 |
+
```py
|
| 403 |
+
>>> from dataclasses import dataclass
|
| 404 |
+
>>> from typing import Any, Dict, List, Union
|
| 405 |
+
|
| 406 |
+
|
| 407 |
+
>>> @dataclass
|
| 408 |
+
... class TTSDataCollatorWithPadding:
|
| 409 |
+
... processor: Any
|
| 410 |
+
|
| 411 |
+
... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
|
| 412 |
+
... input_ids = [{"input_ids": feature["input_ids"]} for feature in features]
|
| 413 |
+
... label_features = [{"input_values": feature["labels"]} for feature in features]
|
| 414 |
+
... speaker_features = [feature["speaker_embeddings"] for feature in features]
|
| 415 |
+
|
| 416 |
+
... # collate the inputs and targets into a batch
|
| 417 |
+
... batch = processor.pad(input_ids=input_ids, labels=label_features, return_tensors="pt")
|
| 418 |
+
|
| 419 |
+
... # replace padding with -100 to ignore loss correctly
|
| 420 |
+
... batch["labels"] = batch["labels"].masked_fill(batch.decoder_attention_mask.unsqueeze(-1).ne(1), -100)
|
| 421 |
+
|
| 422 |
+
... # not used during fine-tuning
|
| 423 |
+
... del batch["decoder_attention_mask"]
|
| 424 |
+
|
| 425 |
+
... # round down target lengths to multiple of reduction factor
|
| 426 |
+
... if model.config.reduction_factor > 1:
|
| 427 |
+
... target_lengths = torch.tensor([len(feature["input_values"]) for feature in label_features])
|
| 428 |
+
... target_lengths = target_lengths.new(
|
| 429 |
+
... [length - length % model.config.reduction_factor for length in target_lengths]
|
| 430 |
+
... )
|
| 431 |
+
... max_length = max(target_lengths)
|
| 432 |
+
... batch["labels"] = batch["labels"][:, :max_length]
|
| 433 |
+
|
| 434 |
+
... # also add in the speaker embeddings
|
| 435 |
+
... batch["speaker_embeddings"] = torch.tensor(speaker_features)
|
| 436 |
+
|
| 437 |
+
... return batch
|
| 438 |
+
```
|
| 439 |
+
|
| 440 |
+
SpeechT5 では、モデルのデコーダ部分への入力が 2 分の 1 に削減されます。つまり、すべてのデータが破棄されます。
|
| 441 |
+
ターゲット シーケンスからの他のタイムステップ。次に、デコーダは 2 倍の長さのシーケンスを予測します。オリジナル以来
|
| 442 |
+
ターゲット シーケンスの長さが奇数である可能性がある場合、データ照合機能はバッチの最大長を切り捨てて、
|
| 443 |
+
2の倍数。
|
| 444 |
+
|
| 445 |
+
```py
|
| 446 |
+
>>> data_collator = TTSDataCollatorWithPadding(processor=processor)
|
| 447 |
+
```
|
| 448 |
+
|
| 449 |
+
## Train the model
|
| 450 |
+
|
| 451 |
+
プロセッサのロードに使用したのと同じチェックポイントから事前トレーニングされたモデルをロードします。
|
| 452 |
+
|
| 453 |
+
```py
|
| 454 |
+
>>> from transformers import SpeechT5ForTextToSpeech
|
| 455 |
+
|
| 456 |
+
>>> model = SpeechT5ForTextToSpeech.from_pretrained(checkpoint)
|
| 457 |
+
```
|
| 458 |
+
|
| 459 |
+
`use_cache=True`オプションは、勾配チェックポイントと互換性がありません。トレーニングのために無効にします。
|
| 460 |
+
|
| 461 |
+
```py
|
| 462 |
+
>>> model.config.use_cache = False
|
| 463 |
+
```
|
| 464 |
+
|
| 465 |
+
トレーニング引数を定義します。ここでは、トレーニング プロセス中に評価メトリクスを計算していません。代わりに、
|
| 466 |
+
損失だけを見てください。
|
| 467 |
+
|
| 468 |
+
```python
|
| 469 |
+
>>> from transformers import Seq2SeqTrainingArguments
|
| 470 |
+
|
| 471 |
+
>>> training_args = Seq2SeqTrainingArguments(
|
| 472 |
+
... output_dir="speecht5_finetuned_voxpopuli_nl", # change to a repo name of your choice
|
| 473 |
+
... per_device_train_batch_size=4,
|
| 474 |
+
... gradient_accumulation_steps=8,
|
| 475 |
+
... learning_rate=1e-5,
|
| 476 |
+
... warmup_steps=500,
|
| 477 |
+
... max_steps=4000,
|
| 478 |
+
... gradient_checkpointing=True,
|
| 479 |
+
... fp16=True,
|
| 480 |
+
... eval_strategy="steps",
|
| 481 |
+
... per_device_eval_batch_size=2,
|
| 482 |
+
... save_steps=1000,
|
| 483 |
+
... eval_steps=1000,
|
| 484 |
+
... logging_steps=25,
|
| 485 |
+
... report_to=["tensorboard"],
|
| 486 |
+
... load_best_model_at_end=True,
|
| 487 |
+
... greater_is_better=False,
|
| 488 |
+
... label_names=["labels"],
|
| 489 |
+
... push_to_hub=True,
|
| 490 |
+
... )
|
| 491 |
+
```
|
| 492 |
+
|
| 493 |
+
`Trainer`オブジェクトをインスタンス化し、モデル、データセット、データ照合器をそれに渡します。
|
| 494 |
+
|
| 495 |
+
```py
|
| 496 |
+
>>> from transformers import Seq2SeqTrainer
|
| 497 |
+
|
| 498 |
+
>>> trainer = Seq2SeqTrainer(
|
| 499 |
+
... args=training_args,
|
| 500 |
+
... model=model,
|
| 501 |
+
... train_dataset=dataset["train"],
|
| 502 |
+
... eval_dataset=dataset["test"],
|
| 503 |
+
... data_collator=data_collator,
|
| 504 |
+
... processing_class=processor,
|
| 505 |
+
... )
|
| 506 |
+
```
|
| 507 |
+
これで、トレーニングを開始する準備が整いました。トレーニングには数時間かかります。 GPU に応じて、
|
| 508 |
+
トレーニングを開始するときに、CUDA の「メモリ不足」エラーが発生する可能性があります。この場合、減らすことができます
|
| 509 |
+
`per_device_train_batch_size`を 2 倍に増分し、`gradient_accumulation_steps`を 2 倍に増やして補正します。
|
| 510 |
+
|
| 511 |
+
```py
|
| 512 |
+
>>> trainer.train()
|
| 513 |
+
```
|
| 514 |
+
パイプラインでチェックポイントを使用できるようにするには、必ずプロセッサをチェックポイントとともに保存してください。
|
| 515 |
+
|
| 516 |
+
```py
|
| 517 |
+
>>> processor.save_pretrained("YOUR_ACCOUNT_NAME/speecht5_finetuned_voxpopuli_nl")
|
| 518 |
+
```
|
| 519 |
+
|
| 520 |
+
最終モデルを 🤗 ハブにプッシュします。
|
| 521 |
+
|
| 522 |
+
```py
|
| 523 |
+
>>> trainer.push_to_hub()
|
| 524 |
+
```
|
| 525 |
+
|
| 526 |
+
## Inference
|
| 527 |
+
|
| 528 |
+
### Inference with a pipeline
|
| 529 |
+
|
| 530 |
+
モデルを微調整したので、それを推論に使用できるようになりました。
|
| 531 |
+
まず、対応するパイプラインでそれを使用する方法を見てみましょう。 `"text-to-speech"` パイプラインを作成しましょう
|
| 532 |
+
チェックポイント:
|
| 533 |
+
|
| 534 |
+
```py
|
| 535 |
+
>>> from transformers import pipeline
|
| 536 |
+
|
| 537 |
+
>>> pipe = pipeline("text-to-speech", model="YOUR_ACCOUNT_NAME/speecht5_finetuned_voxpopuli_nl")
|
| 538 |
+
```
|
| 539 |
+
|
| 540 |
+
ナレーションを希望するオランダ語のテキストを選択してください。例:
|
| 541 |
+
|
| 542 |
+
```py
|
| 543 |
+
>>> text = "hallo allemaal, ik praat nederlands. groetjes aan iedereen!"
|
| 544 |
+
```
|
| 545 |
+
|
| 546 |
+
パイプラインで SpeechT5 を使用するには、スピーカーの埋め込みが必要です。テスト データセットの例から取得してみましょう。
|
| 547 |
+
|
| 548 |
+
```py
|
| 549 |
+
>>> example = dataset["test"][304]
|
| 550 |
+
>>> speaker_embeddings = torch.tensor(example["speaker_embeddings"]).unsqueeze(0)
|
| 551 |
+
```
|
| 552 |
+
|
| 553 |
+
これで、テキストとスピーカーの埋め込みをパイプラインに渡すことができ、残りはパイプラインが処理します。
|
| 554 |
+
|
| 555 |
+
|
| 556 |
+
```py
|
| 557 |
+
>>> forward_params = {"speaker_embeddings": speaker_embeddings}
|
| 558 |
+
>>> output = pipe(text, forward_params=forward_params)
|
| 559 |
+
>>> output
|
| 560 |
+
{'audio': array([-6.82714235e-05, -4.26525949e-04, 1.06134125e-04, ...,
|
| 561 |
+
-1.22392643e-03, -7.76011671e-04, 3.29112721e-04], dtype=float32),
|
| 562 |
+
'sampling_rate': 16000}
|
| 563 |
+
```
|
| 564 |
+
|
| 565 |
+
その後、結果を聞くことができます。
|
| 566 |
+
|
| 567 |
+
|
| 568 |
+
```py
|
| 569 |
+
>>> from IPython.display import Audio
|
| 570 |
+
>>> Audio(output['audio'], rate=output['sampling_rate'])
|
| 571 |
+
```
|
| 572 |
+
|
| 573 |
+
### Run inference manually
|
| 574 |
+
|
| 575 |
+
パイプラインを使用しなくても同じ推論結果を得ることができますが、より多くの手順が必要になります。
|
| 576 |
+
|
| 577 |
+
🤗 ハブからモデルをロードします。
|
| 578 |
+
|
| 579 |
+
|
| 580 |
+
```py
|
| 581 |
+
>>> model = SpeechT5ForTextToSpeech.from_pretrained("YOUR_ACCOUNT/speecht5_finetuned_voxpopuli_nl")
|
| 582 |
+
```
|
| 583 |
+
|
| 584 |
+
テスト データセットから例を選択して、スピーカーの埋め込みを取得します。
|
| 585 |
+
|
| 586 |
+
```py
|
| 587 |
+
>>> example = dataset["test"][304]
|
| 588 |
+
>>> speaker_embeddings = torch.tensor(example["speaker_embeddings"]).unsqueeze(0)
|
| 589 |
+
```
|
| 590 |
+
|
| 591 |
+
入力テキストを定義し、トークン化します。
|
| 592 |
+
|
| 593 |
+
```py
|
| 594 |
+
>>> text = "hallo allemaal, ik praat nederlands. groetjes aan iedereen!"
|
| 595 |
+
>>> inputs = processor(text=text, return_tensors="pt")
|
| 596 |
+
```
|
| 597 |
+
|
| 598 |
+
モデルを使用してスペクトログラムを作成します。
|
| 599 |
+
|
| 600 |
+
```py
|
| 601 |
+
>>> spectrogram = model.generate_speech(inputs["input_ids"], speaker_embeddings)
|
| 602 |
+
```
|
| 603 |
+
|
| 604 |
+
次のことを行う場合は、スペクトログラムを視覚化します。
|
| 605 |
+
|
| 606 |
+
```py
|
| 607 |
+
>>> plt.figure()
|
| 608 |
+
>>> plt.imshow(spectrogram.T)
|
| 609 |
+
>>> plt.show()
|
| 610 |
+
```
|
| 611 |
+
|
| 612 |
+
<div class="flex justify-center">
|
| 613 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/tts_logmelspectrogram_2.png" alt="Generated log-mel spectrogram"/>
|
| 614 |
+
</div>
|
| 615 |
+
|
| 616 |
+
最後に、ボコーダーを使用してスペクトログラムをサウンドに変換します。
|
| 617 |
+
|
| 618 |
+
```py
|
| 619 |
+
>>> with torch.no_grad():
|
| 620 |
+
... speech = vocoder(spectrogram)
|
| 621 |
+
|
| 622 |
+
>>> from IPython.display import Audio
|
| 623 |
+
|
| 624 |
+
>>> Audio(speech.numpy(), rate=16000)
|
| 625 |
+
```
|
| 626 |
+
|
| 627 |
+
私たちの経験では、このモデルから満足のいく結果を得るのは難しい場合があります。スピーカーの品質
|
| 628 |
+
埋め込みは重要な要素であるようです。 SpeechT5 は英語の x ベクトルで事前トレーニングされているため、最高のパフォーマンスを発揮します
|
| 629 |
+
英語スピーカーの埋め込みを使用する場合。合成音声の音質が悪い場合は、別のスピーカー埋め込みを使用してみてください。
|
| 630 |
+
|
| 631 |
+
トレーニング期間を長くすると、結果の質も向上する可能性があります。それでも、そのスピーチは明らかに英語ではなくオランダ語です。
|
| 632 |
+
話者の音声特性をキャプチャします (例の元の音声と比較)。
|
| 633 |
+
もう 1 つ実験すべきことは、モデルの構成です。たとえば、`config.reduction_factor = 1`を使用してみてください。
|
| 634 |
+
これにより結果が改善されるかどうかを確認してください。
|
| 635 |
+
|
| 636 |
+
最後に、倫理的配慮を考慮することが不可欠です。 TTS テクノロジーには数多くの有用な用途がありますが、
|
| 637 |
+
また、知らないうちに誰かの声を偽装するなど、悪意のある目的に使用される可能性もあります。お願いします
|
| 638 |
+
TTS は賢明かつ責任を持って使用してください。
|