

The dataset viewer is not available for this split.
Error code:   StreamingRowsError
Exception:    CastError
Message:      Couldn't cast
chat_template: string
<|fim_prefix|>: int64
<|quad_start|>: int64
<|vision_eos|>: int64
<|fim_pad|>: int64
<tool_call>: int64
<|audio_bos|>: int64
<|fim_middle|>: int64
<|quad_end|>: int64
<|file_sep|>: int64
<|fim_suffix|>: int64
<|im_end|>: int64
<|vision_pad|>: int64
<|endoftext|>: int64
<|IMAGE|>: int64
<|repo_name|>: int64
<|box_end|>: int64
<|audio_eos|>: int64
<|VIDEO|>: int64
<|AUDIO|>: int64
</tool_call>: int64
<|vision_bos|>: int64
<|im_start|>: int64
to
{'</tool_call>': Value('int64'), '<tool_call>': Value('int64'), '<|AUDIO|>': Value('int64'), '<|IMAGE|>': Value('int64'), '<|VIDEO|>': Value('int64'), '<|audio_bos|>': Value('int64'), '<|audio_eos|>': Value('int64'), '<|box_end|>': Value('int64'), '<|endoftext|>': Value('int64'), '<|file_sep|>': Value('int64'), '<|fim_middle|>': Value('int64'), '<|fim_pad|>': Value('int64'), '<|fim_prefix|>': Value('int64'), '<|fim_suffix|>': Value('int64'), '<|im_end|>': Value('int64'), '<|im_start|>': Value('int64'), '<|quad_end|>': Value('int64'), '<|quad_start|>': Value('int64'), '<|repo_name|>': Value('int64'), '<|vision_bos|>': Value('int64'), '<|vision_eos|>': Value('int64'), '<|vision_pad|>': Value('int64')}
because column names don't match
Traceback:    Traceback (most recent call last):
                File "/src/services/worker/src/worker/utils.py", line 147, in get_rows_or_raise
                  return get_rows(
                      dataset=dataset,
                  ...<4 lines>...
                      column_names=column_names,
                  )
                File "/src/libs/libcommon/src/libcommon/utils.py", line 272, in decorator
                  return func(*args, **kwargs)
                File "/src/services/worker/src/worker/utils.py", line 127, in get_rows
                  rows_plus_one = list(itertools.islice(safe_iter(ds, dataset=dataset), rows_max_number + 1))
                File "/src/services/worker/src/worker/utils.py", line 483, in safe_iter
                  yield from ds.decode(False) if ds.features else ds
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2951, in __iter__
                  for key, example in ex_iterable:
                                      ^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2461, in __iter__
                  for key, pa_table in self._iter_arrow():
                                       ~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2486, in _iter_arrow
                  for key, pa_table in self.ex_iterable._iter_arrow():
                                       ~~~~~~~~~~~~~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 547, in _iter_arrow
                  for key, pa_table in iterator:
                                       ^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 430, in _iter_arrow
                  for key, pa_table in self.generate_tables_fn(**gen_kwags):
                                       ~~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 343, in _generate_tables
                  self._cast_table(pa_table, json_field_paths=json_field_paths),
                  ~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 132, in _cast_table
                  pa_table = table_cast(pa_table, self.info.features.arrow_schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2378, in table_cast
                  return cast_table_to_schema(table, schema)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2306, in cast_table_to_schema
                  raise CastError(
                  ...<3 lines>...
                  )
              datasets.table.CastError: Couldn't cast
              chat_template: string
              <|fim_prefix|>: int64
              <|quad_start|>: int64
              <|vision_eos|>: int64
              <|fim_pad|>: int64
              <tool_call>: int64
              <|audio_bos|>: int64
              <|fim_middle|>: int64
              <|quad_end|>: int64
              <|file_sep|>: int64
              <|fim_suffix|>: int64
              <|im_end|>: int64
              <|vision_pad|>: int64
              <|endoftext|>: int64
              <|IMAGE|>: int64
              <|repo_name|>: int64
              <|box_end|>: int64
              <|audio_eos|>: int64
              <|VIDEO|>: int64
              <|AUDIO|>: int64
              </tool_call>: int64
              <|vision_bos|>: int64
              <|im_start|>: int64
              to
              {'</tool_call>': Value('int64'), '<tool_call>': Value('int64'), '<|AUDIO|>': Value('int64'), '<|IMAGE|>': Value('int64'), '<|VIDEO|>': Value('int64'), '<|audio_bos|>': Value('int64'), '<|audio_eos|>': Value('int64'), '<|box_end|>': Value('int64'), '<|endoftext|>': Value('int64'), '<|file_sep|>': Value('int64'), '<|fim_middle|>': Value('int64'), '<|fim_pad|>': Value('int64'), '<|fim_prefix|>': Value('int64'), '<|fim_suffix|>': Value('int64'), '<|im_end|>': Value('int64'), '<|im_start|>': Value('int64'), '<|quad_end|>': Value('int64'), '<|quad_start|>': Value('int64'), '<|repo_name|>': Value('int64'), '<|vision_bos|>': Value('int64'), '<|vision_eos|>': Value('int64'), '<|vision_pad|>': Value('int64')}
              because column names don't match
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
ROMA: LLM System for Real-World Object-Centric
Multi-Sensory Active Perception
I saw. I touched. I understood.


Ruoxuan Feng*, Yutong Chen*, Ruihua Song, Huan Yang, Zhongyuan Wang, Guocai Yao, Di Hu✉
*Equal contribution ✉Corresponding author
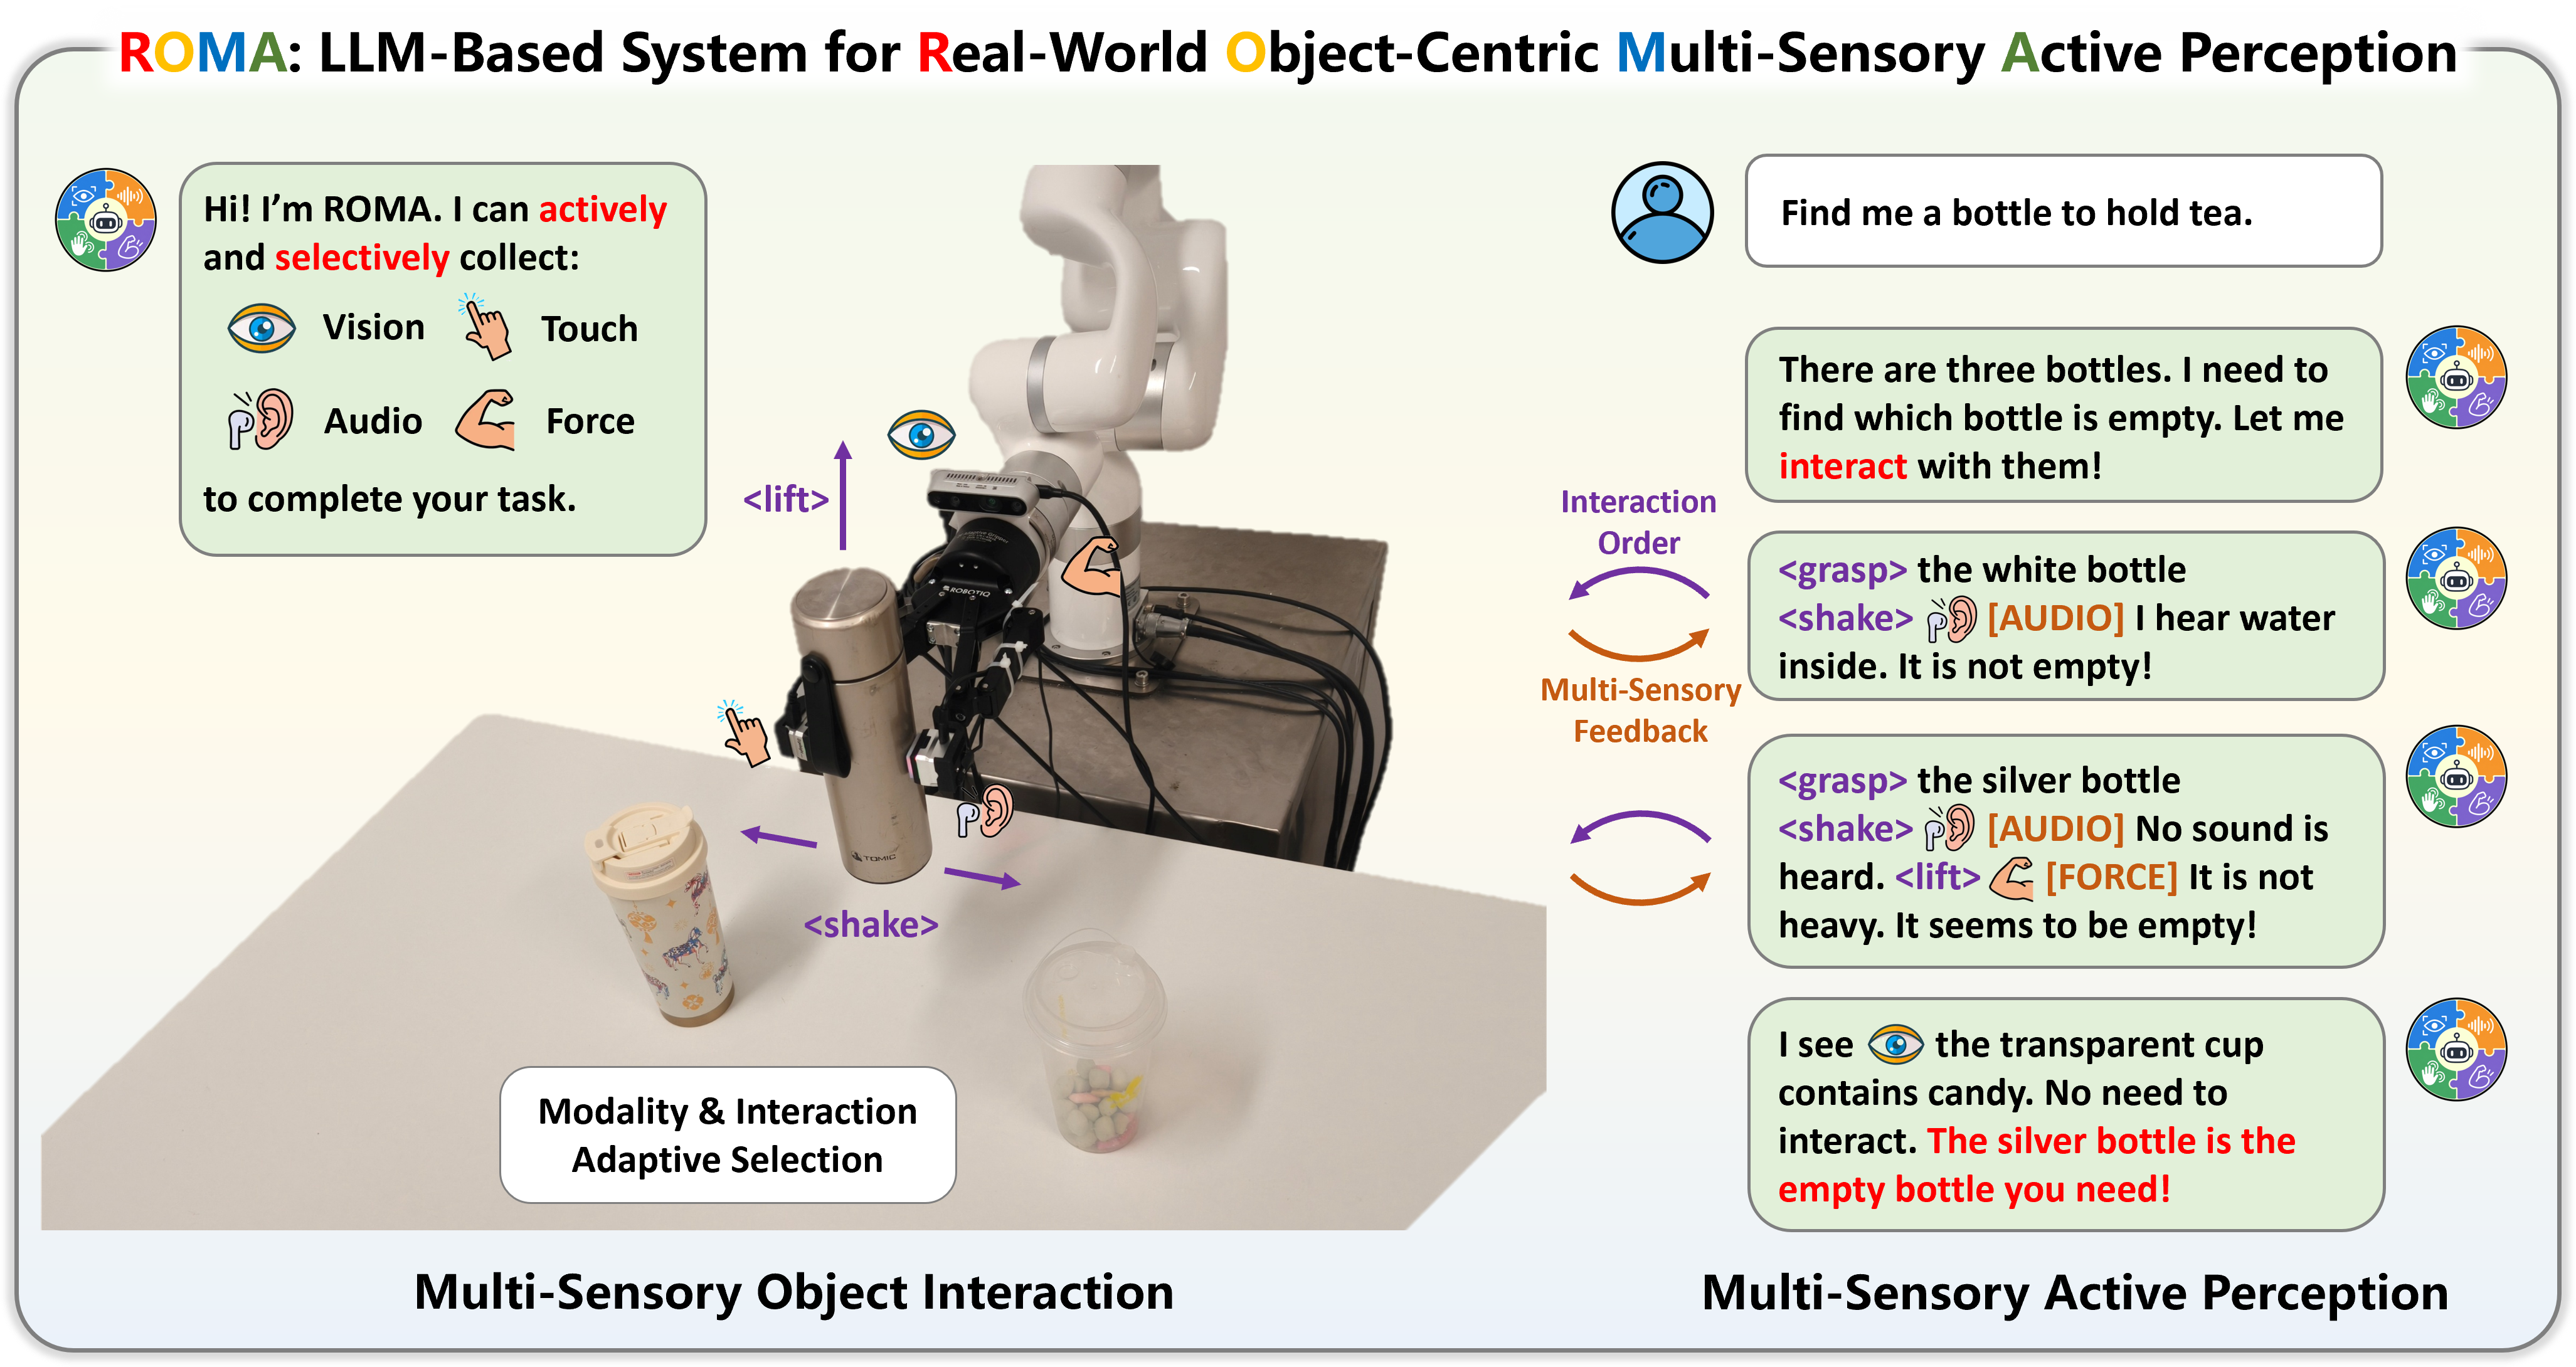
This repository hosts the checkpoint and dataset of ROMA, an LLM-based system for Real-World Object-Centric Multi-Sensory Active Perception. ROMA integrates vision, audio, touch, and force into a reasoning-interaction-feedback loop: the LLM identifies the missing evidence and selects the target object, the interaction (lift, press, collide, shake, rotate, squeeze), and the sensory modalities, while a physical interface executes the interaction and returns the multi-sensory feedback.
What's Inside
| Component | Description | Status |
|---|---|---|
| ROMA-7B checkpoint | Multi-sensory LLM built on Qwen2.5-Omni with action / modality tokens, an audio branch, and an AnyTouch 2 tactile branch, trained with multi-sensory alignment followed by active-perception SFT. | Available |
| ROMI-2K | Real-world multi-sensory object interaction dataset covering nearly 2,000 objects and 6 atomic interactions with synchronized visual, audio, tactile, and force feedback. | Coming soon |
| ROMA Bench | 2,100 scene-level tasks (single-chain, multi-chain, and intent-driven) for evaluating active perception. | Coming soon |
| Demo example scene | One recorded tabletop scene (example_data/1) used by the local web demo. |
Available |
Checkpoint
The ROMA-7B checkpoint directory (ROMA-Qwen2.5-Omni-7B) contains:
ROMA-Qwen2.5-Omni-7B/
├── xxx.safetensors      # base Qwen2.5-Omni-7B model
├── anytouch2.pth        # tactile encoder
├── audio.bin            # fine-tuned audio adapter and encoder
├── tactile.bin          # fine-tuned tactile adapter
└── ROMA-LLM.bin         # ROMA LLM weights
The weights are loaded in this order: base Qwen2.5-Omni, tactile encoder, new action / modality tokens, audio adapter, tactile adapter, ROMA LLM. The loading code is in demo.py of the GitHub repository.
Dataset
ROMI-2K and ROMA Bench are coming soon. They will contain:
- Handheld object collection: 1,657 object-content combinations, each interacted with at 3 grasp locations using 6 atomic interactions, with wrist and third-person views, audio, and tactile feedback.
- Tabletop scene collection (Training Set): 400 scenes recorded with a robotic arm, with visual, audio, tactile, and force feedback, object bounding boxes, and annotations.
- ROMA Bench: 2,100 scene-level active-perception tasks built from the held-out test scenes.
Usage
git clone https://github.com/GeWu-Lab/ROMA.git
cd ROMA
# see the GitHub README for environment setup

hf download GeWu-Lab/ROMA --repo-type dataset --local-dir resources
Citation
@article{feng2026roma,
  title   = {ROMA: LLM System for Real-World Object-Centric Multi-Sensory Active Perception},
  author  = {Feng, Ruoxuan and Chen, Yutong and Song, Ruihua and Yang, Huan and Wang, Zhongyuan and Yao, Guocai and Hu, Di},
  journal = {arXiv preprint},
  year    = {2026}
}
- Downloads last month
- 6