

Orca: Progressive Learning from Complex Explanation Traces of GPT-4
Paper • 2306.02707 • Published • 51
Error code: TooBigContentError
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
YAML Metadata Warning:The task_categories "conversational" is not in the official list: text-classification, token-classification, table-question-answering, question-answering, zero-shot-classification, translation, summarization, feature-extraction, text-generation, fill-mask, sentence-similarity, text-to-speech, text-to-audio, automatic-speech-recognition, audio-to-audio, audio-classification, audio-text-to-text, voice-activity-detection, depth-estimation, image-classification, object-detection, image-segmentation, text-to-image, image-to-text, image-to-image, image-to-video, unconditional-image-generation, video-classification, reinforcement-learning, robotics, tabular-classification, tabular-regression, tabular-to-text, table-to-text, multiple-choice, text-ranking, text-retrieval, time-series-forecasting, text-to-video, image-text-to-text, image-text-to-image, image-text-to-video, visual-question-answering, document-question-answering, zero-shot-image-classification, graph-ml, mask-generation, zero-shot-object-detection, text-to-3d, image-to-3d, image-feature-extraction, video-text-to-text, keypoint-detection, visual-document-retrieval, any-to-any, video-to-video, other
YAML Metadata Warning:The task_categories "text2text-generation" is not in the official list: text-classification, token-classification, table-question-answering, question-answering, zero-shot-classification, translation, summarization, feature-extraction, text-generation, fill-mask, sentence-similarity, text-to-speech, text-to-audio, automatic-speech-recognition, audio-to-audio, audio-classification, audio-text-to-text, voice-activity-detection, depth-estimation, image-classification, object-detection, image-segmentation, text-to-image, image-to-text, image-to-image, image-to-video, unconditional-image-generation, video-classification, reinforcement-learning, robotics, tabular-classification, tabular-regression, tabular-to-text, table-to-text, multiple-choice, text-ranking, text-retrieval, time-series-forecasting, text-to-video, image-text-to-text, image-text-to-image, image-text-to-video, visual-question-answering, document-question-answering, zero-shot-image-classification, graph-ml, mask-generation, zero-shot-object-detection, text-to-3d, image-to-3d, image-feature-extraction, video-text-to-text, keypoint-detection, visual-document-retrieval, any-to-any, video-to-video, other
FLAN Collection を拡張した指示と応答のデータ。1 行が 1 件の指示で、system_prompt にシステムの指示、question に問い、response に応答が入る。応答はカードによれば GPT-4 と GPT-3.5 の補完で、Orca 論文の分布に沿って表にしたものである。OpenAI の出力であり、その利用規約の対象になる。
| 項目 | 値 |
|---|---|
| 行数 | 約 2,941,952(1 構成・1 分割の合計) |
| 列数 | 4 |
| 容量 | 4.10 GB(ファイル 5 本) |
| ファイルの形式 | parquet 2、png 1 |
| 言語 | en |
| 公開 | public |
| 構成(config) | 分割(split)ごとの行数 | 列数 |
|---|---|---|
default |
train 約 2,941,952 |
4 |
default・分割 train)
| 列 | 型 | 先頭の行の値 |
|---|---|---|
id |
string |
niv.242684 |
system_prompt |
string |
|
question |
string |
You will be given a definition of a task first, … |
response |
string |
[ ["AFC Ajax (amateurs)", "has ground", "Sport… |
行数と列は HF のデータセットビューアの集計(元のデータセットの現在の版で数えたもの)。全データセットの一覧は HYUKI5/dataset-catalog にある。
Open-Orca/OpenOrca をリビジョン e9c87b4abb2609913751f9b26553fdb9c061796c の時点でそのまま複製したもの。中身は変えていない。判断モデル Laya(convaiinnovations/laya)の微調整に使う候補として、調査メモ(Laya 学習用データセット調査)に載せたデータを集めている。
e9c87b4abb2609913751f9b26553fdb9c061796c(2025-02-19 07:32:36+00:00)mitデータセットの作成
作成の根拠
このデータセットは、研究者と開発者に拡張されたテキストデータの供給源を提供するために作られた。 データポイントは主に、GPT-3.5 と GPT-4 の段階的で詳細な推論能力に依拠する、中核の FLAN Collection データを強化することを意図している。 この「推論トレース」による拡張は卓越した成果を示しており、このデータで学習させた LLaMA-13B モデルは、100B 未満のパラメータのすべてのモデルが従来は著しく苦手としていた、難しい推論タスクの幅広い集合で、GPT-3.5 に匹敵するか上回ることを可能にした。
元データ
データは、以下に示す点を除き、Orca 論文で示された分布に沿う手法を用いて生成されている:
合わせると、元の Orca 論文よりもデータポイントが約 1.5M 少ない。データセットを完成させる作業は継続中である。
| メモ | 節 | ライセンス(記載) | 確認 | 注記 |
|---|---|---|---|---|
frontier_closed_reasoning_logs.md |
Q4. 正誤・採点ラベルが付いたクローズドモデルの推論ログ・回答(金融・判断に近いものを含む)は何があるか (L117) | mit | 確認済 | 生成元モデルの出力規約が別に及ぶ(Q4) / 原文注記: OpenAI の出力で、規約の対象(Q5)。response が 2,048 を超える割合は未測 |
以下は元のデータセットのカードの本文を日本語に訳したもの(機械翻訳)。訳に疑問があるときは、末尾の原文を確かめる。
OpenOrca データセットの公開をお知らせできることを大変嬉しく思う! この豊富な、拡張された FLAN データの集まりは、Orca 論文 で示された分布に、可能な限り沿うように作られている。 このデータセットは、高性能なモデルのチェックポイントを生成するうえで重要な役割を果たしてきた。すべての NLP の研究者と開発者にとって価値のある資源である!
最新のモデル である。30B 未満のすべての従来のモデルより総合スコアが高い、初の 7B モデルである。 完全に公開された 7B モデルで、Llama2-70b-chat の性能の 98% を達成している!
3 番目のモデル である。HuggingFace Leaderboard で LLaMA1-65B を上回るスコアを出した、初の 13B モデルである! Platypus との提携で公開された。
2 番目のモデル である。Orca 論文で報告された性能を上回ったことを示している。 公開時点では #1 であったが、現在は当方の OpenOrca-Platypus2-13B に上回られている。 OpenChat との提携で公開された。
OpenOrca-Preview1-13B このモデルは、1 日足らずで、200 ドル未満の費用で、当方のデータの 10% 未満を使って学習された。 公開時点で、BigBench-Hard と AGIEval において当時の最先端モデルを上回った。Orca 論文で報告された改善の約 60% を達成している。
OpenOrca データセットは、拡張された FLAN Collection データ の集まりである。 現在、約 1M 件の GPT-4 の補完と、約 3.2M 件の GPT-3.5 の補完を含む。 ORCA 論文で示された分布に沿って表形式にしており、現在は意図した全体のデータセットの一部を補完したものである。範囲を広げるため、生成を続けている。 このデータは、主に自然言語処理の分野における学習と評価に用いられる。
以下の貢献者の多大な努力と献身に対し、特別な謝意を表したい:
Teknium
WingLian/Caseus
Eric Hartford
NanoBit
Pankaj
Winddude
Rohan

http://AlignmentLab.ai:
Autometa
Entropi
AtlasUnified
NeverendingToast
NanoBit
WingLian/Caseus
もちろん、いつものとおり、コミュニティ全体の基盤を支えてくれた TheBloke にも感謝する。
Axolotl の開発者である NanoBit と Caseus に感謝する。両者は、manticore、minotaur、その他多くのモデルを開発・学習したプラットフォームに関する専門知識を貸してくれた!
これらのモデルを、その価値に見合う規模で構築するため、スポンサーや協力者を歓迎している。SNS からご連絡いただきたい: http://Alignmentlab.ai https://discord.gg/n9hXaBPWxx
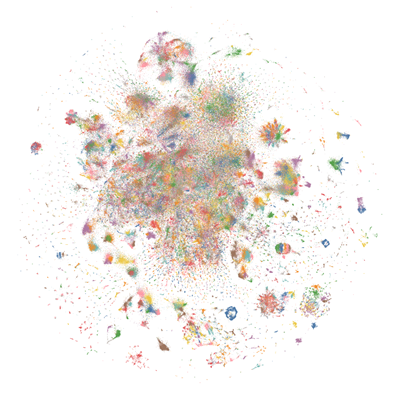
データセット全体を可視化したいか? Nomic Atlas Map を見てほしい。
このデータセットは、言語モデリング、テキスト生成、テキスト拡張を含む、さまざまなタスクに対応している。 単体テストで卓越した性能を示した、高性能なモデルのチェックポイントを複数生成するうえで重要な役割を果たした。 リーダーボードに関する情報は、利用可能になり次第更新する。
データの言語は主に英語である。
このデータセットのデータのインスタンスは、FLAN Collection からのエントリを表す。そのエントリの質問を GPT-4 または GPT-3.5 に送って拡張したものである。 その後、応答が response フィールドに入る。
フィールドは次のとおり:
データは分割されていない。
このデータセットは、研究者と開発者に拡張されたテキストデータの供給源を提供するために作られた。 データポイントは主に、GPT-3.5 と GPT-4 の段階的で詳細な推論能力に依拠する、中核の FLAN Collection データを強化することを意図している。 この「推論トレース」による拡張は卓越した成果を示しており、このデータで学習させた LLaMA-13B モデルは、100B 未満のパラメータのすべてのモデルが従来は著しく苦手としていた、難しい推論タスクの幅広い集合で、GPT-3.5 に匹敵するか上回ることを可能にした。
データは、以下に示す点を除き、Orca 論文で示された分布に沿う手法を用いて生成されている:
合わせると、元の Orca 論文よりもデータポイントが約 1.5M 少ない。データセットを完成させる作業は継続中である。
このデータセットは、言語理解、自然言語処理、機械学習モデルの学習、モデル性能の評価に関するタスクに利用できる。
これは作業中のデータセットであるため、更新や改善を定期的に確認することを推奨する。 さらに、データは Orca 論文に示されたガイドラインと推奨事項に従って利用すべきである。
このデータセットは、Hugging Face の datasets ライブラリでそのまま読み込めるように構成されている。 ファイルのサイズが大きいため、ストリーミングの利用を推奨する。 定期的な更新とデータ生成の進捗は、Hugging Face 上の OpenOrca リポジトリで確認できる。
@misc{OpenOrca,
  title = {OpenOrca: An Open Dataset of GPT Augmented FLAN Reasoning Traces},
  author = {Wing Lian and Bleys Goodson and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://https://huggingface.co/datasets/Open-Orca/OpenOrca}},
}
@misc{mukherjee2023orca,
      title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
      author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
      year={2023},
      eprint={2306.02707},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
@misc{longpre2023flan,
      title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
      author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
      year={2023},
      eprint={2301.13688},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
@misc{touvron2023llama,
    title={Llama 2: Open Foundation and Fine-Tuned Chat Models},
    author={Hugo Touvron and Louis Martin and Kevin Stone and Peter Albert and Amjad Almahairi and Yasmine Babaei and Nikolay Bashlykov and Soumya Batra and Prajjwal Bhargava and Shruti Bhosale and Dan Bikel and Lukas Blecher and Cristian Canton Ferrer and Moya Chen and Guillem Cucurull and David Esiobu and Jude Fernandes and Jeremy Fu and Wenyin Fu and Brian Fuller and Cynthia Gao and Vedanuj Goswami and Naman Goyal and Anthony Hartshorn and Saghar Hosseini and Rui Hou and Hakan Inan and Marcin Kardas and Viktor Kerkez and Madian Khabsa and Isabel Kloumann and Artem Korenev and Punit Singh Koura and Marie-Anne Lachaux and Thibaut Lavril and Jenya Lee and Diana Liskovich and Yinghai Lu and Yuning Mao and Xavier Martinet and Todor Mihaylov and Pushkar Mishra and Igor Molybog and Yixin Nie and Andrew Poulton and Jeremy Reizenstein and Rashi Rungta and Kalyan Saladi and Alan Schelten and Ruan Silva and Eric Michael Smith and Ranjan Subramanian and Xiaoqing Ellen Tan and Binh Tang and Ross Taylor and Adina Williams and Jian Xiang Kuan and Puxin Xu and Zheng Yan and Iliyan Zarov and Yuchen Zhang and Angela Fan and Melanie Kambadur and Sharan Narang and Aurelien Rodriguez and Robert Stojnic and Sergey Edunov and Thomas Scialom},
    year={2023},
    eprint= arXiv 2307.09288
}
@software{touvron2023llama,
  title={LLaMA: Open and Efficient Foundation Language Models},
  author={Touvron, Hugo and Lavril, Thibaut and Izacard, Gautier and Martinet, Xavier and Lachaux, Marie-Anne and Lacroix, Timoth{\'e}e and Rozi{\`e}re, Baptiste and Goyal, Naman and Hambro, Eric and Azhar, Faisal and Rodriguez, Aurelien and Joulin, Armand and Grave, Edouard and Lample, Guillaume},
  journal={arXiv preprint arXiv:2302.13971},
  year={2023}
}
We are thrilled to announce the release of the OpenOrca dataset! This rich collection of augmented FLAN data aligns, as best as possible, with the distributions outlined in the Orca paper. It has been instrumental in generating high-performing model checkpoints and serves as a valuable resource for all NLP researchers and developers!
Our latest model, the first 7B to score better overall than all previous models below 30B. 98% of Llama2-70b-chat's performance, in a completely open 7B!
Our third model, the first 13B model to score higher than LLaMA1-65B on the HuggingFace Leaderboard! Released in partnership with Platypus.
Our second model, highlighting that we've surpassed the performance reported in the Orca paper. Was #1 at release time, now surpassed by our own OpenOrca-Platypus2-13B. Released in partnership with OpenChat.
OpenOrca-Preview1-13B This model was trained in less than a day, for <$200, with <10% of our data. At release, it beat the current state of the art models on BigBench-Hard and AGIEval. Achieves ~60% of the improvements reported in the Orca paper.
The OpenOrca dataset is a collection of augmented FLAN Collection data. Currently ~1M GPT-4 completions, and ~3.2M GPT-3.5 completions. It is tabularized in alignment with the distributions presented in the ORCA paper and currently represents a partial completion of the full intended dataset, with ongoing generation to expand its scope. The data is primarily used for training and evaluation in the field of natural language processing.
We would like to give special recognition to the following contributors for their significant efforts and dedication:
Teknium
WingLian/Caseus
Eric Hartford
NanoBit
Pankaj
Winddude
Rohan

http://AlignmentLab.ai:
Autometa
Entropi
AtlasUnified
NeverendingToast
NanoBit
WingLian/Caseus
Also of course, as always, TheBloke, for being the backbone of the whole community.
Many thanks to NanoBit and Caseus, makers of Axolotl, for lending us their expertise on the platform that developed and trained manticore, minotaur, and many others!
We are welcoming sponsors or collaborators to help us build these models to the scale they deserve. Please reach out via our socials: http://Alignmentlab.ai https://discord.gg/n9hXaBPWxx
Want to visualize our full dataset? Check out our Nomic Atlas Map.
This dataset supports a range of tasks including language modeling, text generation, and text augmentation. It has been instrumental in the generation of multiple high-performing model checkpoints which have exhibited exceptional performance in our unit testing. Further information on leaderboards will be updated as they become available.
The language of the data is primarily English.
A data instance in this dataset represents entries from the FLAN collection which have been augmented by submitting the listed question to either GPT-4 or GPT-3.5. The response is then entered into the response field.
The fields are:
The data is unsplit.
The dataset was created to provide a source of augmented text data for researchers and developers. The datapoints are intended primarily to provide an enhancement of the core FLAN Collection data which relies upon the detailed step by step reasoning capabilities of GPT-3.5 and GPT-4. This "reasoning trace" augmentation has demonstrated exceptional results, allowing a LLaMA-13B model trained with this data to rival or beat GPT-3.5 on broad sets of hard reasoning tasks which all models below 100B parameters had previously performed dramatically worse on.
The data is generated using techniques in alignment with the distributions outlined in the Orca paper, except as noted below:
Combined, this gave us ~1.5M fewer datapoints than in the original Orca paper. Completing the set is an ongoing work.
The dataset can be used for tasks related to language understanding, natural language processing, machine learning model training, and model performance evaluation.
Given that this is a work-in-progress dataset, it is recommended to regularly check for updates and improvements. Further, the data should be used in accordance with the guidelines and recommendations outlined in the Orca paper.
This dataset is organized such that it can be naively loaded via Hugging Face datasets library. We recommend using streaming due to the large size of the files. Regular updates and data generation progress can be monitored through the OpenOrca repository on Hugging Face.
@misc{OpenOrca,
  title = {OpenOrca: An Open Dataset of GPT Augmented FLAN Reasoning Traces},
  author = {Wing Lian and Bleys Goodson and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://https://huggingface.co/datasets/Open-Orca/OpenOrca}},
}
@misc{mukherjee2023orca,
      title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
      author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
      year={2023},
      eprint={2306.02707},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
@misc{longpre2023flan,
      title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
      author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
      year={2023},
      eprint={2301.13688},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
@misc{touvron2023llama,
    title={Llama 2: Open Foundation and Fine-Tuned Chat Models},
    author={Hugo Touvron and Louis Martin and Kevin Stone and Peter Albert and Amjad Almahairi and Yasmine Babaei and Nikolay Bashlykov and Soumya Batra and Prajjwal Bhargava and Shruti Bhosale and Dan Bikel and Lukas Blecher and Cristian Canton Ferrer and Moya Chen and Guillem Cucurull and David Esiobu and Jude Fernandes and Jeremy Fu and Wenyin Fu and Brian Fuller and Cynthia Gao and Vedanuj Goswami and Naman Goyal and Anthony Hartshorn and Saghar Hosseini and Rui Hou and Hakan Inan and Marcin Kardas and Viktor Kerkez and Madian Khabsa and Isabel Kloumann and Artem Korenev and Punit Singh Koura and Marie-Anne Lachaux and Thibaut Lavril and Jenya Lee and Diana Liskovich and Yinghai Lu and Yuning Mao and Xavier Martinet and Todor Mihaylov and Pushkar Mishra and Igor Molybog and Yixin Nie and Andrew Poulton and Jeremy Reizenstein and Rashi Rungta and Kalyan Saladi and Alan Schelten and Ruan Silva and Eric Michael Smith and Ranjan Subramanian and Xiaoqing Ellen Tan and Binh Tang and Ross Taylor and Adina Williams and Jian Xiang Kuan and Puxin Xu and Zheng Yan and Iliyan Zarov and Yuchen Zhang and Angela Fan and Melanie Kambadur and Sharan Narang and Aurelien Rodriguez and Robert Stojnic and Sergey Edunov and Thomas Scialom},
    year={2023},
    eprint= arXiv 2307.09288
}
@software{touvron2023llama,
  title={LLaMA: Open and Efficient Foundation Language Models},
  author={Touvron, Hugo and Lavril, Thibaut and Izacard, Gautier and Martinet, Xavier and Lachaux, Marie-Anne and Lacroix, Timoth{\'e}e and Rozi{\`e}re, Baptiste and Goyal, Naman and Hambro, Eric and Azhar, Faisal and Rodriguez, Aurelien and Joulin, Armand and Grave, Edouard and Lample, Guillaume},
  journal={arXiv preprint arXiv:2302.13971},
  year={2023}
}