
Datasets:

license: apache-2.0
pretty_name: TIGER-Lab/WebInstruct-verified (mirror)
source_datasets:
  - TIGER-Lab/WebInstruct-verified
tags:
  - laya
  - laya-finetune
  - mirror
  - domain-science
  - domain-general
  - use-conditional
  - genre-exam
  - label-text
  - annot-natural
  - lang-en
language:
  - en
task_categories:
  - question-answering
size_categories:
  - 100K<n<1M
configs:
  - config_name: default
    data_files:
      - split: train
        path: data/train-*
      - split: test
        path: data/test-*
      - split: train_legacy
        path: data/train_legacy-*
dataset_info:
  features:
    - name: id
      dtype: string
    - name: question
      dtype: string
    - name: answer
      dtype: string
    - name: answer_type
      dtype: string
    - name: category
      dtype: string
    - name: difficulty
      dtype: string
  splits:
    - name: train
      num_bytes: 80312361
      num_examples: 228736
    - name: test
      num_bytes: 348127
      num_examples: 1000
    - name: train_legacy
      num_bytes: 79050440
      num_examples: 231833
  download_size: 87751510
  dataset_size: 159710928
TIGER-Lab/WebInstruct-verified(複製)
データの内容
物理・化学・金融・人文学などにまたがる、答えの検証できる質問のデータ。1 行が 1 問で、question に問題文、answer に短い答え、answer_type に答えの形式が入り、推論の過程は含まれない。Web のページを再クロールして人手の答えがあるものだけを残し、Gemini の候補解答で全て誤りの質問と全て正解の易しい質問を除いている。一部の選択式には選択肢が質問文から欠けた古い版(train_legacy)があり、最新版では直されている。
データの概要
| 項目 | 値 |
|---|---|
| 行数 | 461,569(1 構成・3 分割の合計) |
| 列数 | 6 |
| 容量 | 87.76 MB(ファイル 5 本) |
| ファイルの形式 | parquet 3 |
| 言語 | en |
| 公開 | public |
構成と分割
| 構成(config) | 分割(split)ごとの行数 | 列数 |
|---|---|---|
default |
train 228,736、test 1,000、train_legacy 231,833 |
6 |
列(構成 default・分割 train)
| 列 | 型 | 先頭の行の値 |
|---|---|---|
id |
string |
1177521 |
question |
string |
Write a formula for the fourth degree polynomial… |
answer |
string |
y(x) = -3x^4 + 54x^2 + 10 |
answer_type |
string |
Expression |
category |
string |
Mathematics |
difficulty |
string |
University |
行数と列は HF のデータセットビューアの集計(元のデータセットの現在の版で数えたもの)。全データセットの一覧は HYUKI5/dataset-catalog にある。
複製について
TIGER-Lab/WebInstruct-verified をリビジョン 3e8a350b3a935d68fe70bdf379692500abc9ff51 の時点でそのまま複製したもの。中身は変えていない。判断モデル Laya(convaiinnovations/laya)の微調整に使う候補として、調査メモ(Laya 学習用データセット調査)に載せたデータを集めている。
出典
- 元のデータセット: https://huggingface.co/datasets/TIGER-Lab/WebInstruct-verified
- 複製したリビジョン:
3e8a350b3a935d68fe70bdf379692500abc9ff51(2025-11-27 22:39:38+00:00) - 元のライセンス表記:
apache-2.0
論文
アノテーションの方法
(元のカードに該当の見出しが無いので、ラベルの付け方に触れた段落を抜き出した)
- Gemini が生成した 8 件の答えがすべて誤っている 質問は捨てる。これにより、Web スクレイピングの際に生じた曖昧でノイズの多い項目を除く。
- また、過度に単純な質問、すなわち 8 件の候補の答えがすべて正しい 質問も除く。データセットの複雑さを保ち、モデルの汎化をより強く試すためである。
微調整に使うときの注意
- 調査メモの台帳での区分: B(継承条件・gated・モデル由来の条件・上流の規約などが付く)。区分は記載の文言で機械的に付けたもので、法的な判定ではない。学習に入れる前に元のカードとライセンスの原文で確かめる。
- Laya の入力は 2,048 token まで(ModernBERT-large / mmBERT)。長い本文は先頭から黙って切られるので、切れる行は事前に除くか、要約・切り出しをしてから入れる。
- 分割は記事・文書単位で行い、同じ本文から作った別の問いを学習側と較正側に分けない。温度と閾値は学習に使っていない分割で別々に当てる。
調査メモの記述
| メモ | 節 | ライセンス(記載) | 確認 | 注記 |
|---|---|---|---|---|
open_weight_reasoning_logs.md |
Q3. 難易度ラベル・ドメイン列・検証可能な短答を持つ質問データ(トレースが無い、または質問側に価値があるもの)は何があるか (L82) | apache-2.0 | 確認済 | 生成元モデルの出力規約が別に及ぶ(Q4) / 原文注記: トレースが無い(質問と短答のみ)。カードによれば train_legacy は一部の多肢選択で選択肢が質問文から欠けているデータで、train で修正された。「全 8 回答が正解の質問を除外」しているので、易しい質問が落 |
jev_sources_tasksource_bekko.csv |
CSV(tasksource-jev-typed-decisions) | apache-2.0 / license_use=commercial | 確認済 | license_use=commercial / [Jev 元データ source] source_annotation_converted(deterministic recast; no model r |
jev_sources_tasksource_bekko.csv |
CSV(tasksource-jev-typed-decisions) | apache-2.0 / license_use=commercial | 確認済 | license_use=commercial / [Jev 元データ source] source_annotation_converted(deterministic recast; no model r |
元のカード(日本語訳)
以下は元のデータセットのカードの本文を日本語に訳したもの(機械翻訳)。訳に疑問があるときは、末尾の原文を確かめる。
General-Reasoner: Advancing LLM Reasoning Across All Domains
💻 コード | 📄 論文 | 📊 データセット | 🤗 モデル | 🌐 プロジェクトページ
概要
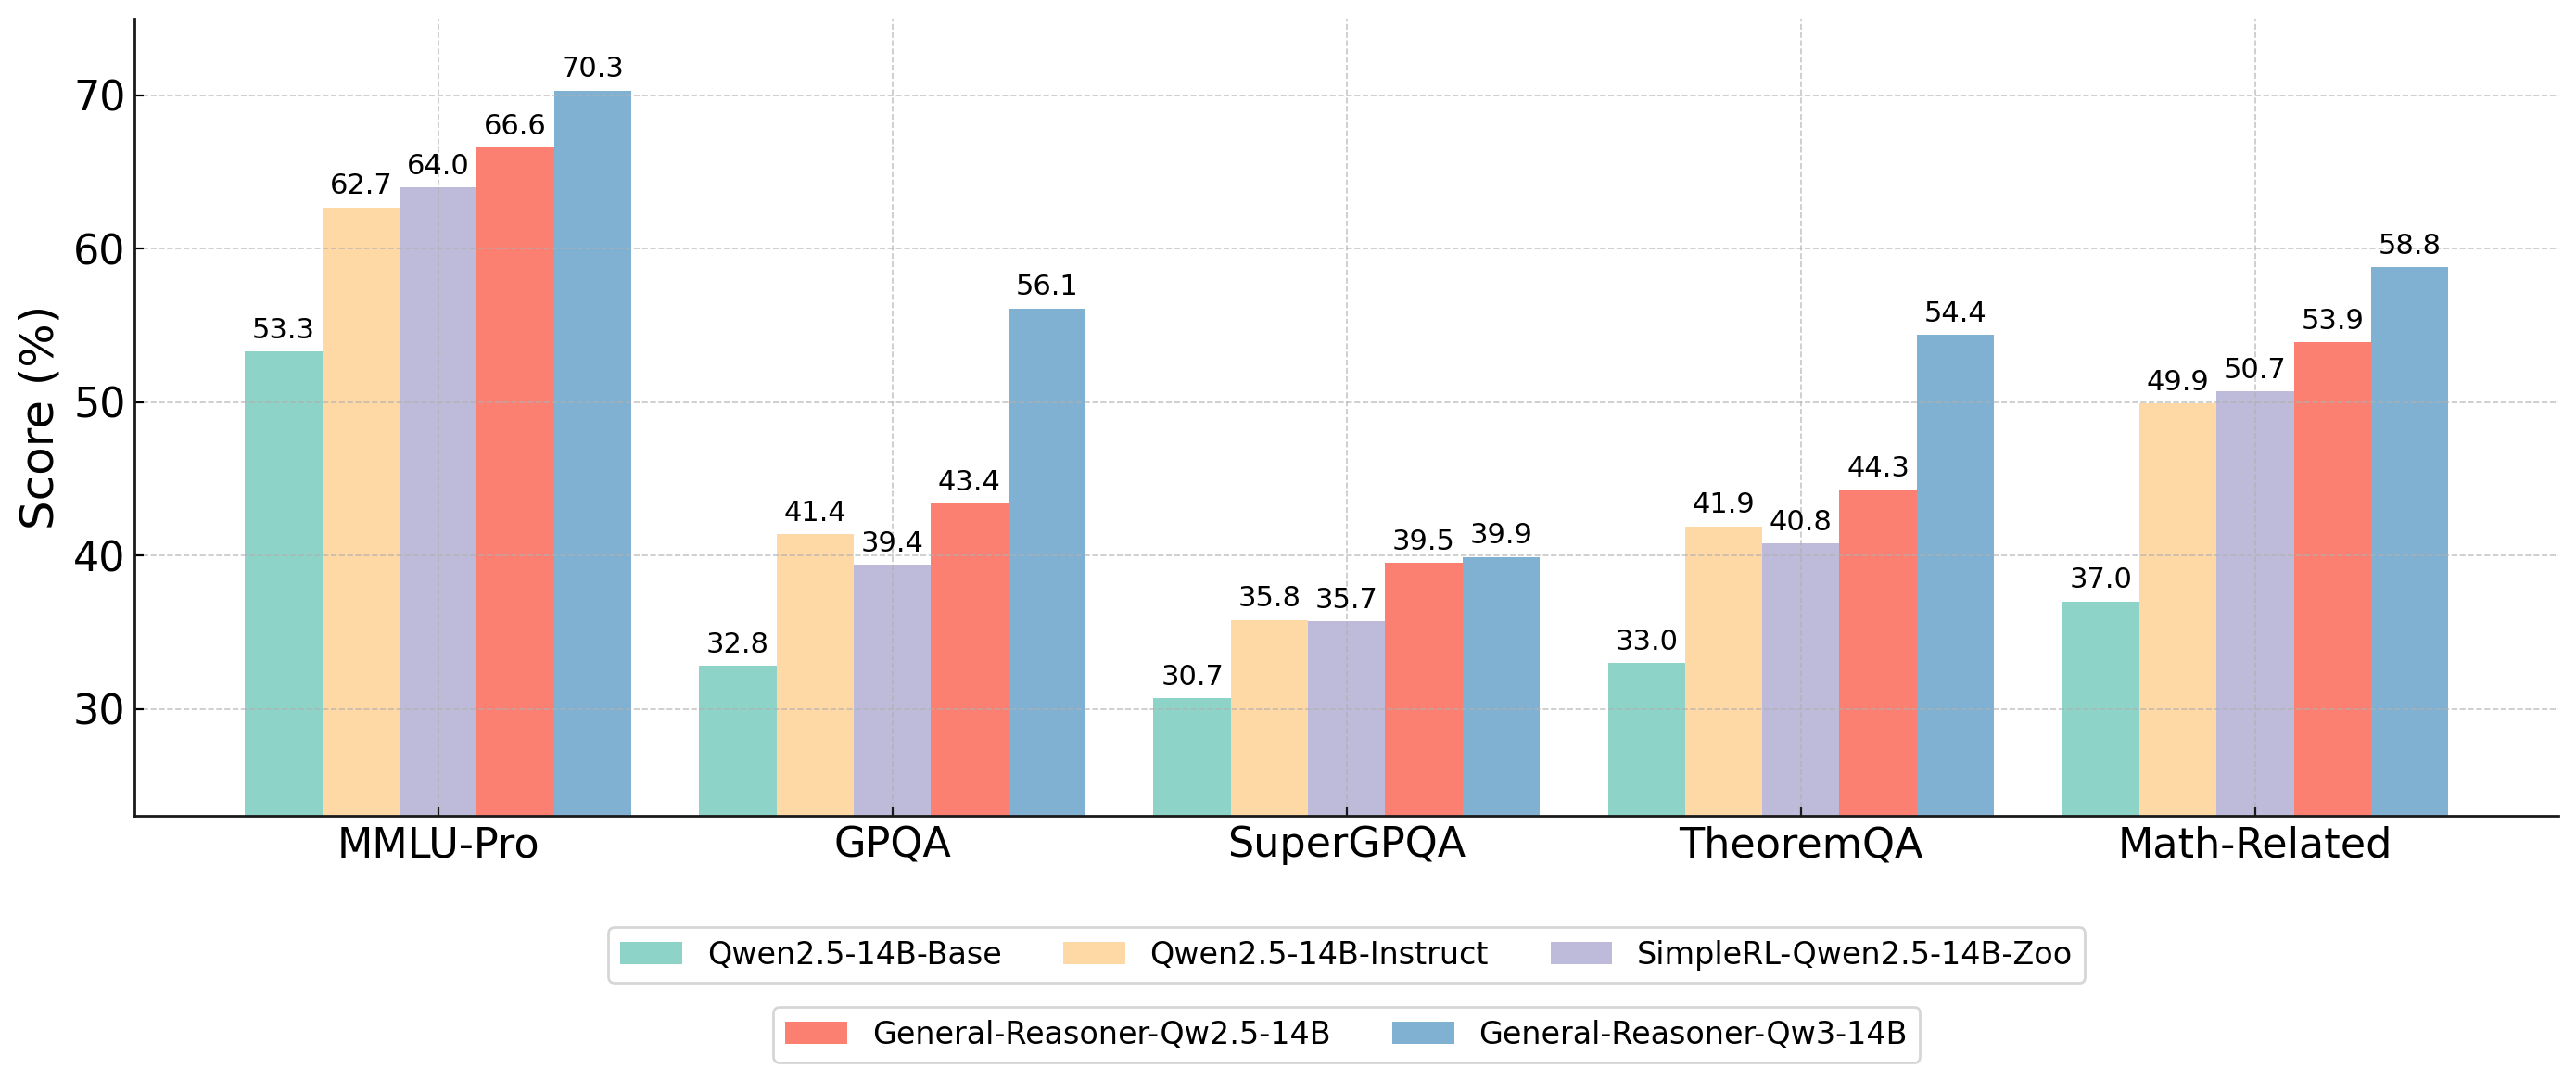
図: モデルベースの検証器を使い、多様な検証可能な推論問題で学習した General-Reasoner の、さまざまな推論タスクにおける効果(ベースラインの手法との比較)。
General-Reasoner は、大規模言語モデル(LLM)の学習パラダイムであり、数学やコードだけでなく、物理、化学、金融、人文学などを含む多様な分野で推論能力を頑健に高めるように設計されている。
主な特徴:
- Zero RL 学習: 中間の教師あり段階を経ず、ベースの LLM から直接強化学習を行う。
- 多様な推論データ: Web から集め、分野を越えて答えの検証可能性でフィルタリングした、230K 件以上の高品質で検証可能な問題。
- モデルベースの検証器: 文脈を考慮し、思考の連鎖を伴って答えを検証する、1.5B のコンパクトな生成型の検証モデル。従来のルールベースの手法より高い性能を示す。
本リポジトリには、多様な推論データ WebInstruct-verified が含まれる。
データセットの詳細
数学を超えて広い分野で頑健な推論能力を育てるため、多様で高品質なデータセットを構築した。
WebInstruct のデータを元の Web ページまで遡り、質問と答えの組を再クロールした。
元のページに人の手で書かれた答えがない場合は、その項目を捨てた。これにより、再クロールされたすべての項目が人の手で検証済みであり、したがって各答えの品質が信頼できることを保証する。Gemini‑1.5‑Pro を使い、明確に検証可能な短い答えを持つ質問を選択的に抽出する。 これによりデータセットの信頼性がさらに高まる。
次に Gemini‑2.0‑Flash が、追加のフィルタリングのために質問ごとに 8 件の候補の答えを生成する:
- Gemini が生成した 8 件の答えがすべて誤っている 質問は捨てる。これにより、Web スクレイピングの際に生じた曖昧でノイズの多い項目を除く。
- また、過度に単純な質問、すなわち 8 件の候補の答えがすべて正しい 質問も除く。データセットの複雑さを保ち、モデルの汎化をより強く試すためである。
これらの手順により、構築したデータセットの正しさが保証される。
分布
分野の分布は次の図のとおり。

検証
短い答えの形式は、float、array、matrix、latex など多様である。これらの答えを検証するには、GPT/Gemini を使うか、https://huggingface.co/TIGER-Lab/general-verifier でローカルに提供されているモデルを使う。
注記
- discussion_3 で @zlk が指摘したとおり、一部の選択式問題では、質問文から選択肢が欠けていた。最新のデータセットではこれを修正した。元のバージョンのデータセットは
train_legacysplit にある。
引用
本研究が役立つと考えられる場合は、次のように引用すること:
@inproceedings{
  ma2025generalreasoner,
  title={{G}eneral-{R}easoner: Advancing {LLM} Reasoning Across All Domains},
  author={Xueguang Ma and Qian Liu and Dongfu Jiang and Ge Zhang and Zejun MA and Wenhu Chen},
  booktitle={The Thirty-ninth Annual Conference on Neural Information Processing Systems},
  year={2025},
  url={https://openreview.net/forum?id=pBFVoll8Xa}
}
原文(英語)
General-Reasoner: Advancing LLM Reasoning Across All Domains
💻 Code | 📄 Paper | 📊 Dataset | 🤗 Model | 🌐 Project Page
Overview
Figure: Effectiveness of General-Reasoner trained with diverse verifiable reasoning questions using model-based verifier compared to baseline methods on various reasoning tasks.
General-Reasoner is a training paradigm for large language models (LLMs), designed to robustly enhance reasoning abilities across diverse domains—not just mathematics and coding, but also physics, chemistry, finance, humanities, and more.
Key features:
- Zero RL Training: Direct reinforcement learning from base LLMs, bypassing intermediate supervised stages.
- Diverse Reasoning Data: 230K+ high-quality, verifiable questions sourced from the web and filtered for answer verifiability across disciplines.
- Model-Based Verifier: Compact 1.5B generative verifier model for context-aware, chain-of-thought answer validation, outperforming traditional rule-based methods.
**This repo contains the Diverse Reasoning Data WebInstruct-verified **
Dataset Details
We construct a diverse, high‑quality dataset to facilitate robust reasoning capabilities across a broad range of domains, extending beyond the commonly studied mathematical problems.
We trace back the data in WebInstruct to its original web page to re‑crawl the question–answer pairs.
If the original page lacks human‑written answers, we drop the entry. This ensures every re‑crawled item is human‑verified and, therefore, that each answer is of reliable quality.Gemini‑1.5‑Pro is employed to selectively extract questions with clearly verifiable short answers, further boosting dataset reliability.
Gemini‑2.0‑Flash then generates eight candidate answers per question for additional filtering:
- We discard any question for which all eight Gemini‑generated answers are incorrect, eliminating ambiguous or noisy items that arose during web scraping.
- We also remove overly simple questions—those for which all eight candidate answers are correct—to preserve dataset complexity and better challenge model generalization.
These steps ensure the correctness of the constructed dataset.
Distribution
The distribution of disciplines is depicted as follows:
Verification
The short answers have different forms, including float, array, matrix, latex, etc. To verify these answers, please use GPT/Gemini or use the locally-served model at https://huggingface.co/TIGER-Lab/general-verifier.
Notes
- As discussed in discussion_3, noticed by @zlk, some multiple choice questions have options missing from the question. We have fixed this in the latest dataset. The original version of the dataset can be found in the
train_legacysplit.
Citation
If you feel our work is helpful, please cite:
@inproceedings{
  ma2025generalreasoner,
  title={{G}eneral-{R}easoner: Advancing {LLM} Reasoning Across All Domains},
  author={Xueguang Ma and Qian Liu and Dongfu Jiang and Ge Zhang and Zejun MA and Wenhu Chen},
  booktitle={The Thirty-ninth Annual Conference on Neural Information Processing Systems},
  year={2025},
  url={https://openreview.net/forum?id=pBFVoll8Xa}
}