| --- |
| language: |
| - en |
| - zh |
| - ko |
| - ja |
| - fr |
| license: apache-2.0 |
| task_categories: |
| - image-text-to-text |
| configs: |
| - config_name: default |
| data_files: |
| - split: test |
| path: MMTR.jsonl |
| --- |
| |
| # MMTR-Bench: Multimodal Masked Text Reconstruction Benchmark |
| <div align="center Krank"> |
| <a href="https://mmtr-bench-dataset.github.io/MMTR-Bench/">🏠 HomePage</a> | |
| <a href="https://huggingface.co/datasets/MMTR-Bench/MMTR-Bench-Dataset">📊 Dataset</a> | |
| <a href="https://huggingface.co/papers/2604.21277">📄 Paper</a> | |
| <a href="https://github.com/MMTR-Bench-Dataset/MMTR-Bench-eval">💻 Code</a> |
| </div> |
|
|
|
|
| ## 📖 Abstract |
|
|
| We present **MMTR-Bench** (Multimodal Masked Text Reconstruction Benchmark) to evaluate native visual context reconstruction in complex multimodal inputs. Unlike traditional question-answering tasks, MMTR-Bench presents models with masked single- or multi-image inputs from diverse real-world scenarios, such as documents and webpages. |
|
|
| To solve the task, models must recover the hidden text by relying on the remaining layout structure, visual cues, and relevant world knowledge. By removing question-based guidance, this task challenges models to autonomously parse and reason over complex visual structures, testing their fundamental capacity for end-to-end document parsing and structured reading. The benchmark contains 2,771 test samples spanning multiple languages and varying target lengths. To fairly assess this diversity, we introduce a level-aware scoring mechanism. Extensive experiments on representative models demonstrate that MMTR-Bench remains highly challenging, particularly for sentence- and paragraph-level recovery. |
|
|
| --- |
|
|
| ## 📊 Dataset Overview |
|
|
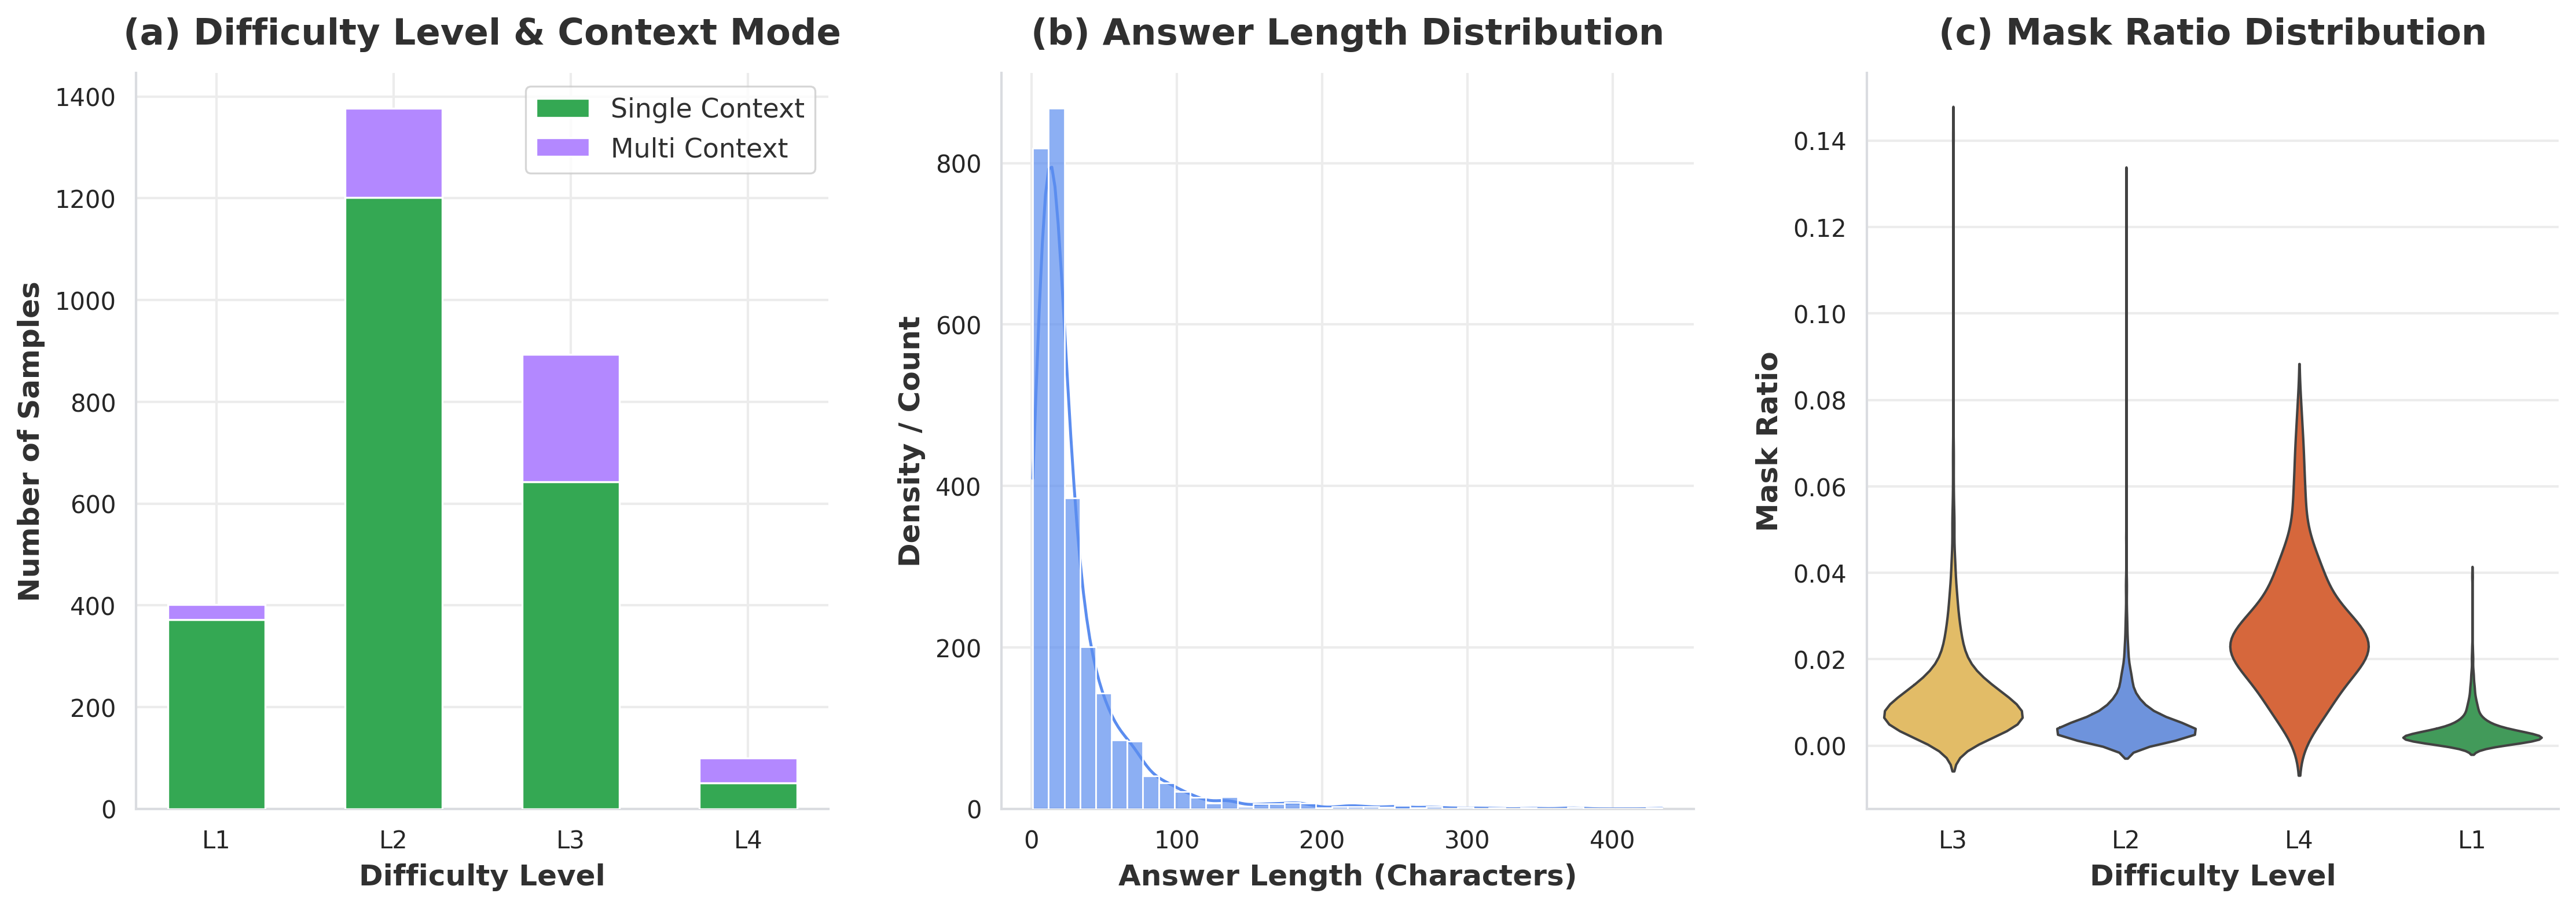
| MMTR-Bench evaluates a model's ability to maintain a continuous, structured reading flow across complex multimodal layouts. The dataset is rigorously balanced across various dimensions to ensure a comprehensive evaluation of current Multimodal Large Language Models (MLLMs). |
|
|
|  |
|
|
| The distributions in the dataset highlight our multi-faceted evaluation strategy: |
| * **Difficulty Level & Context Mode:** The dataset is categorized into four distinct difficulty levels (L1 to L4), scaling from word-level completion to complex paragraph-level reconstruction. It incorporates both Single Context (single-page) and Multi Context (multi-page) scenarios, demanding robust cross-page reasoning. |
| * **Answer Length Distribution:** Target texts span a wide spectrum of character lengths, ensuring models are tested on both concise factual recall and extended, coherent text generation based on visual context. |
| * **Mask Ratio Distribution:** The proportion of masked content varies dynamically across difficulty levels, pushing the boundaries of how much missing information a model can infer purely from surrounding document structures and visual semantics. |
|
|
| --- |
|
|
| ## 🏆 Leaderboard & Evaluation |
|
|
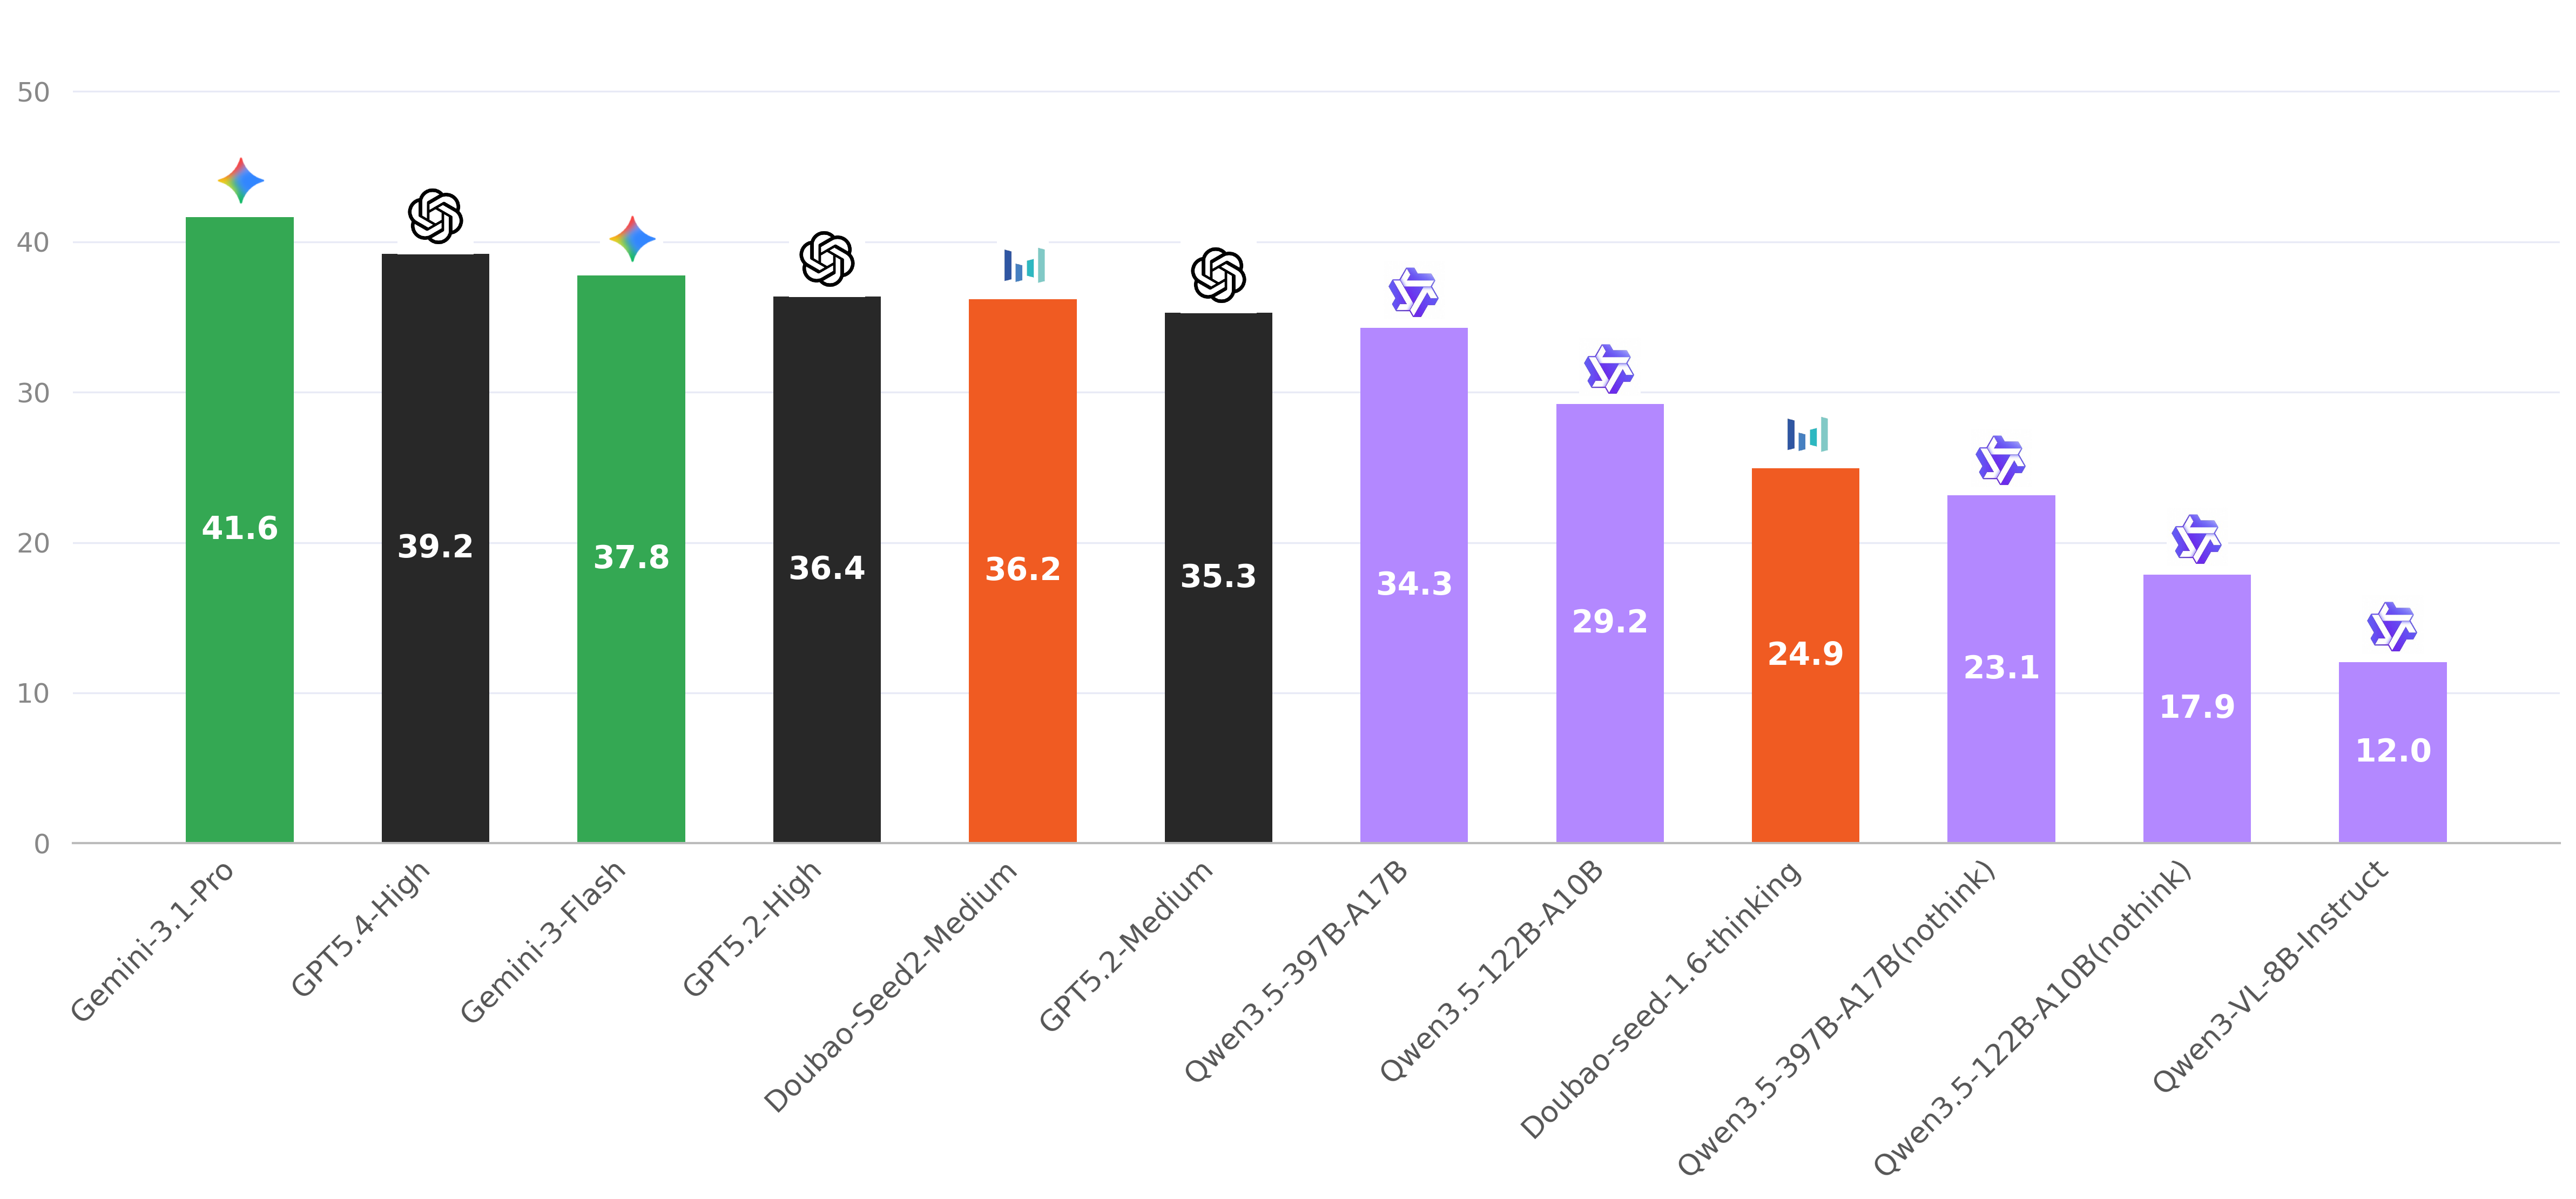
| The benchmark assesses models using a specialized level-aware scoring mechanism to account for the varying complexities of L1 through L4 tasks. The inclusion of explicit reasoning ("Thinking") models reveals a significant paradigm shift in how MLLMs approach visual text reconstruction. |
|
|
|  |
|
|
| ### Main Results |
|
|
| *Note: "Think" marks models with explicit reasoning capabilities, except for variants explicitly marked as "nothink" or "Instruct". All numbers are reported as percentages.* |
|
|
| | Models | Think | Single-page | Multi-page | L1 | L2 | L3 | L4 | Final | |
| | :--- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | |
| | Gemini-3.1-Pro | ✅ | 42.57 | 38.70 | 64.17 | 44.64 | 37.50 | 31.86 | **41.87** | |
| | GPT5.4-High | ✅ | 41.00 | 30.98 | 57.46 | 41.20 | 35.72 | 30.92 | 39.18 | |
| | Gemini-3-Flash | ✅ | 38.49 | 34.90 | 56.75 | 38.51 | 34.86 | 29.46 | 37.84 | |
| | GPT5.2-High | ✅ | 36.64 | 37.62 | 51.49 | 38.61 | 34.02 | 29.42 | 36.81 | |
| | Doubao-Seed2-Medium | ✅ | 37.06 | 31.96 | 52.46 | 36.10 | 33.63 | 31.28 | 36.13 | |
| | GPT5.2-Medium | ✅ | 35.39 | 36.61 | 50.27 | 37.22 | 32.72 | 30.51 | 35.61 | |
| | Qwen3.5-397B-A17B | ✅ | 34.67 | 30.10 | 48.39 | 34.67 | 31.46 | 26.68 | 33.84 | |
| | Qwen3.5-122B-A10B | ✅ | 30.37 | 23.94 | 43.91 | 27.23 | 27.84 | 23.92 | 29.20 | |
| | Doubao-Seed1.6-Thinking | ✅ | 25.50 | 23.01 | 33.81 | 22.10 | 24.74 | 25.02 | 25.04 | |
| | Qwen3.5-397B-A17B | | 24.25 | 18.96 | 31.94 | 20.75 | 22.91 | 22.37 | 23.29 | |
| | Qwen3.5-112B-A10B | | 18.56 | 15.47 | 18.79 | 13.62 | 19.31 | 23.40 | 18.00 | |
| | Qwen3-VL-8B-Instruct | | 12.16 | 11.38 | 7.94 | 7.12 | 14.19 | 20.11 | 12.02 | |
|
|
| --- |
|
|
| ## 🚀 How to Use |
|
|
| MMTR-Bench is an evaluation-only benchmark designed to test Multimodal LLMs. There is no training set. |
|
|
| ### 1. Installation |
| Ensure you have the required libraries installed: |
| ```bash |
| pip install datasets |
| ``` |
|
|
| ### 2. Loading the Benchmark |
|
|
| ```python |
| from datasets import load_dataset |
| |
| # Load the benchmark dataset |
| dataset = load_dataset( |
| "MMTR-Bench/MMTR-Bench-Dataset", |
| data_files="MMTR.jsonl" |
| ) |
| benchmark_data = dataset["test"] |
| |
| # Inspect the first evaluation sample |
| sample = benchmark_data[0] |
| |
| print(f"Sample ID: {sample['sample_id']}") |
| print(f"Difficulty Level: L{sample['level']}") |
| print(f"Ground Truth Answer: {sample['answer']}") |
| print(f"Context Image Paths: {sample['context_img_paths']}") |
| ``` |
|
|
| --- |
|
|
| ## 📜 Citation |
|
|
| If you find our benchmark, models, or data useful in your research, please consider citing our paper: |
|
|
| ```bibtex |
| @article{mmtrbench2026, |
| title={Can MLLMs "Read" What is Missing?}, |
| author={Anonymous Authors}, |
| journal={arXiv preprint arXiv:2604.21277}, |
| year={2026} |
| } |
| ``` |


