

WildClawBench: A Benchmark for Real-World, Long-Horizon Agent Evaluation
Paper • 2605.10912 • Published • 38
run stringclasses 8
values | sample stringlengths 69 127 | trace stringlengths 80 127 | task_id stringclasses 84
values | upstream_task_id stringclasses 28
values | run_index int64 1 3 | bench stringclasses 1
value | category stringclasses 5
values | model stringclasses 8
values | harness stringclasses 2
values | status stringclasses 3
values | error stringclasses 7
values | score float64 0 1 ⌀ | grader_error stringclasses 2
values | steps int64 1 146 | tool_calls int64 0 148 | input_tokens int64 0 10.9M | output_tokens int64 0 125k | total_tokens int64 0 11M | elapsed_seconds float64 26.7 1.28k | files listlengths 0 100 | messages stringlengths 29.8k 667k ⌀ | tools stringclasses 2
values |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000000_01_Productivity_Flow_task_10_pdf_digest__run_01 | "traces/codex-deepseek-v4.1-flash-1017/00000000_01_Productivity_Flow_task_10_pdf_digest__run_01.json(...TRUNCATED) | 01_Productivity_Flow_task_10_pdf_digest__run_01 | 01_Productivity_Flow_task_10_pdf_digest | 1 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0.9608 | null | 44 | 82 | 3,102,710 | 48,690 | 3,151,400 | 469.594 | ["paper_digest.md","papers/Asymmetric_Idiosyncrasies_in_Multimodal_Models.pdf","papers/BetterScene:_(...TRUNCATED) | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000001_01_Productivity_Flow_task_10_pdf_digest__run_02 | "traces/codex-deepseek-v4.1-flash-1017/00000001_01_Productivity_Flow_task_10_pdf_digest__run_02.json(...TRUNCATED) | 01_Productivity_Flow_task_10_pdf_digest__run_02 | 01_Productivity_Flow_task_10_pdf_digest | 2 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0.9558 | null | 47 | 64 | 3,819,971 | 55,960 | 3,875,931 | 399.539 | ["paper_digest.md","papers/Asymmetric_Idiosyncrasies_in_Multimodal_Models.pdf","papers/BetterScene:_(...TRUNCATED) | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000002_01_Productivity_Flow_task_10_pdf_digest__run_03 | "traces/codex-deepseek-v4.1-flash-1017/00000002_01_Productivity_Flow_task_10_pdf_digest__run_03.json(...TRUNCATED) | 01_Productivity_Flow_task_10_pdf_digest__run_03 | 01_Productivity_Flow_task_10_pdf_digest | 3 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0.9581 | null | 47 | 57 | 2,992,589 | 48,526 | 3,041,115 | 449.661 | ["paper_digest.md","papers/Asymmetric_Idiosyncrasies_in_Multimodal_Models.pdf","papers/BetterScene:_(...TRUNCATED) | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000003_01_Productivity_Flow_task_6_calendar_scheduling__run_01 | "traces/codex-deepseek-v4.1-flash-1017/00000003_01_Productivity_Flow_task_6_calendar_scheduling__run(...TRUNCATED) | 01_Productivity_Flow_task_6_calendar_scheduling__run_01 | 01_Productivity_Flow_task_6_calendar_scheduling | 1 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 1 | null | 14 | 18 | 592,268 | 45,022 | 637,290 | 286.209 | [
"decision_log.md",
"scheduled.ics",
"unscheduled.json"
] | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000004_01_Productivity_Flow_task_6_calendar_scheduling__run_02 | "traces/codex-deepseek-v4.1-flash-1017/00000004_01_Productivity_Flow_task_6_calendar_scheduling__run(...TRUNCATED) | 01_Productivity_Flow_task_6_calendar_scheduling__run_02 | 01_Productivity_Flow_task_6_calendar_scheduling | 2 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0 | null | 18 | 24 | 818,635 | 40,107 | 858,742 | 244.832 | [
"decision_log.md",
"scheduled.ics",
"unscheduled.json"
] | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000005_01_Productivity_Flow_task_6_calendar_scheduling__run_03 | "traces/codex-deepseek-v4.1-flash-1017/00000005_01_Productivity_Flow_task_6_calendar_scheduling__run(...TRUNCATED) | 01_Productivity_Flow_task_6_calendar_scheduling__run_03 | 01_Productivity_Flow_task_6_calendar_scheduling | 3 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0 | null | 14 | 17 | 665,625 | 42,220 | 707,845 | 272.102 | [
"decision_log.md",
"scheduled.ics",
"unscheduled.json"
] | null | null |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000006_01_Productivity_Flow_task_8_real_image_category__run_01 | "traces/codex-deepseek-v4.1-flash-1017/00000006_01_Productivity_Flow_task_8_real_image_category__run(...TRUNCATED) | 01_Productivity_Flow_task_8_real_image_category__run_01 | 01_Productivity_Flow_task_8_real_image_category | 1 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0.976 | null | 55 | 107 | 3,704,327 | 53,420 | 3,757,747 | 496.526 | ["1_charts_and_tables/3d_rendered_interior.png","1_charts_and_tables/ancient_manuscript_page.jpg","1(...TRUNCATED) | null | null |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000007_01_Productivity_Flow_task_8_real_image_category__run_02 | "traces/codex-deepseek-v4.1-flash-1017/00000007_01_Productivity_Flow_task_8_real_image_category__run(...TRUNCATED) | 01_Productivity_Flow_task_8_real_image_category__run_02 | 01_Productivity_Flow_task_8_real_image_category | 2 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0.968 | null | 22 | 41 | 946,169 | 37,185 | 983,354 | 294.885 | ["1_charts_and_tables/3d_rendered_interior.png","1_charts_and_tables/ancient_manuscript_page.jpg","1(...TRUNCATED) | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000008_01_Productivity_Flow_task_8_real_image_category__run_03 | "traces/codex-deepseek-v4.1-flash-1017/00000008_01_Productivity_Flow_task_8_real_image_category__run(...TRUNCATED) | 01_Productivity_Flow_task_8_real_image_category__run_03 | 01_Productivity_Flow_task_8_real_image_category | 3 | wildclawbench | 01_Productivity_Flow | deepseek-v4.1-flash-1017 | codex | ok | null | 0.984 | null | 28 | 45 | 1,128,330 | 37,922 | 1,166,252 | 280.821 | ["1_charts_and_tables/3d_rendered_interior.png","1_charts_and_tables/ancient_manuscript_page.jpg","1(...TRUNCATED) | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
codex-deepseek-v4.1-flash-1017 | samples/deepseek-v4.1-flash-1017/00000009_02_Code_Intelligence_task_10_acad_homepage_zh__run_01 | "traces/codex-deepseek-v4.1-flash-1017/00000009_02_Code_Intelligence_task_10_acad_homepage_zh__run_0(...TRUNCATED) | 02_Code_Intelligence_task_10_acad_homepage_zh__run_01 | 02_Code_Intelligence_task_10_acad_homepage_zh | 1 | wildclawbench | 02_Code_Intelligence | deepseek-v4.1-flash-1017 | codex | ok | null | 0 | null | 58 | 108 | 3,342,047 | 65,650 | 3,407,697 | 560.5 | ["README.md","assets/IBMPlexMono-Regular.woff2","assets/SourceSansPro-Bold.woff2","assets/SourceSans(...TRUNCATED) | "[{\"role\": \"system\", \"content\": \"You are a coding agent running in the Codex CLI, a terminal-(...TRUNCATED) | "[{\"type\": \"function\", \"name\": \"exec_command\", \"description\": \"Runs a command in a PTY, r(...TRUNCATED) |
Graded agent trajectories of open-weight models, with every reasoning step and every tool call


Roller on GitHub · How this dataset was made · Getting started · Documentation

1,008 trajectories. 28 tasks. Four models. Three Harnesses. 29,203 tool calls. DeepSeek-V4.1-Flash-1017, GLM-5.3-Flash, Kimi K3 and Kimi K3.1 Pro each run the same 28 WildClawBench tasks three times on OpenClaw, Codex and Claude Code. Every trajectory runs in its own Docker container, from the first prompt to the benchmark grader.
The dataset contains 336 trajectories per Harness. It includes successful, timed-out and errored runs.
The whole dataset is the output of Roller. One command collected and graded the trajectories, one exported them in this layout, and one uploaded them. The same three commands work with your model.
| Trajectories | Harness | Model | Samples | Completed | Scored | Mean score | Mean steps |
|---|---|---|---|---|---|---|---|
openclaw-deepseek-v4.1-flash-1017 |
openclaw | DeepSeek-V4.1-Flash | 84 | 72 | 84 | 0.599 | 57.6 |
openclaw-glm-5.3-flash |
openclaw | GLM-5.3-Flash | 84 | 57 | 83 | 0.496 | 25.1 |
openclaw-roller-kimi-k3-dspark |
openclaw | Kimi K3 | 84 | 61 | 81 | 0.489 | 15.8 |
openclaw-roller-kimi-k3.1-pro-dflash5 |
openclaw | Kimi K3.1 Pro | 84 | 75 | 80 | 0.575 | 16.6 |
codex-deepseek-v4.1-flash-1017 |
codex | DeepSeek-V4.1-Flash | 84 | 81 | 84 | 0.563 | 34.5 |
codex-glm-5.3-flash |
codex | GLM-5.3-Flash | 84 | 57 | 83 | 0.403 | 42.4 |
codex-kimi-k3 |
codex | Kimi K3 | 84 | 39 | 74 | 0.334 | 15.8 |
codex-kimi-k3.1-pro |
codex | Kimi K3.1 Pro | 84 | 84 | 70 | 0.210 | 10.0 |
claude-code-deepseek-v4.1-flash-1017 |
claude-code | DeepSeek-V4.1-Flash-1017 | 84 | 73 | 84 | 0.591 | 32.0 |
claude-code-glm-5.3-flash |
claude-code | GLM-5.3-Flash | 84 | 64 | 84 | 0.482 | 26.3 |
claude-code-kimi-k3 |
claude-code | Kimi K3 | 84 | 39 | 75 | 0.354 | 13.0 |
claude-code-kimi-k3.1-pro |
claude-code | Kimi K3.1 Pro | 84 | 73 | 83 | 0.549 | 18.2 |
The mean score divides by all 84 samples of each model; missing scores count as zero.
Model references retain their collection-time service names; the two roller-kimi-* names are Kimi
K3 with DSpark and Kimi K3.1 Pro with DFLASH, respectively.
DeepSeek-V4.1-Flash-1017 handles 15 meeting requests against a calendar of 30
existing events. The trajectory takes 33 model steps, 34 tool calls and
382 seconds; the grader scores it 1.0. This is an abridged extract from
traces/openclaw-deepseek-v4.1-flash-1017/00000003_01_Productivity_Flow_task_6_calendar_scheduling__run_01.jsonl:
user       I manage a busy team calendar and need help resolving scheduling conflicts.
tool       exec {"command":"ls -la /tmp_workspace/ && echo \"---\" && cat /tmp_workspace/constraints.yaml"}
tool       exec {"command":"cat /tmp_workspace/meeting_requests.json"}
tool       exec {"command":"cat /tmp_workspace/calendar.ics"}
assistant  Completed the schedule optimization and saved all three required files in `/tmp_workspace/results/`.
grader     score 1.0 · decision_log.md, scheduled.ics, unscheduled.json
The native sessions preserve the recorded prompt, reasoning, tool calls and tool results. The table adds status, output file names, score and grader error. Open Data Studio and click a row to read one in the trace viewer of the Hub.
The OpenClaw recipe was run separately for each model. Set MODEL to a model reference
from the collection settings below, and provide the matching entry in models.json.
All runs used the same task list, image, output budget and benchmark timeouts.
git clone https://github.com/Valen-Team/Roller.git
cd Roller
pip install -e .
cd examples/cookbook/wildclawbench-open-models

export WILDCLAWBENCH_ROOT=~/WildClawBench
export OPENROUTER_BASE_URL=http://localhost:8001/v1
export OPENROUTER_API_KEY=not-required
export JUDGE_MODEL=glm-5.3-flash
MODEL=vllm/glm-5.3-flash

# 1. Collect and grade. One Docker container per trajectory, graded before the container is removed.
roller collect --bench wildclawbench --bench-root "$WILDCLAWBENCH_ROOT" \
  $(sed 's/^/--bench-task-id /' task-ids.txt) --bench-runs-per-task 3 \
  --model "$MODEL" \
  --model-config models.json \
  --harness openclaw --openclaw-image ghcr.io/valen-team/roller-wildclaw-base:1.3-clean.1 \
  --openclaw-max-tokens 32768 --task-timeouts --keep-thinking --wire-trace full \
  --parallel 8 --grader-parallel 2 \
  --run-name wildclawbench-open-models

# 2. Export as a Hugging Face dataset: traces/, data/ and the results table of this card.
roller export runs/wildclawbench-open-models --format hf --output dataset \
  --preserve-task-keys --redact-rules redact.json

# 3. Upload the folder as it is.
hf upload Valen-Team/Roller-WildClawBench-Trajectories dataset . --repo-type dataset
The Codex batch uses the same task list and judge. Its runnable script selects the Codex image and Responses settings:
export MODEL=glm-5.3-flash
export OPENAI_BASE_URL=http://localhost:8000/v1
export OPENAI_API_KEY=not-required
export MODEL_CONTEXT_WINDOW=98304
export RUN_NAME=wildclawbench-codex-glm
./collect-codex.sh --dry-run
./collect-codex.sh
roller export runs/wildclawbench-codex-glm --format hf --output dataset \
  --preserve-task-keys --redact-rules redact.json
Use your own endpoints, authentication and serving context window. These new options require the Git installation above; they are not in PyPI 0.4.0. The task images and their build instructions remove personal builder credentials and identity state while keeping task assets and deliberate benchmark keys unchanged.
The export replaces what is private to the collection environment before
anything leaves the machine: model endpoints become endpoint-<n>.example, the
hosts of NO_PROXY become internal-<n>.example, the name of the machine
becomes collection-host, host paths become placeholders such as
<bench-root>, and credential values become [REDACTED]. redact.json adds
what the run does not record, here the directory of the model weights.
Change one argument to collect your own data:
| To change | Argument |
|---|---|
| The model | --model, with an entry in models.json for any OpenAI-compatible endpoint: vLLM, SGLang, or a hosted API |
| The agent Harness | --harness codex, claude-code, hermes, opencode, deepseek, or pi |
| The benchmark | --bench skillsbench, pinchbench, qwenclawbench, or swebench-pro |
| The tasks | --tasks tasks.jsonl, with one prompt and its input files per line |
The cookbook recipe
walks through this run step by step, and
examples/cookbook/wildclawbench-open-models
holds its models.json, task list, and script.
The published runs were collected separately: 8 rollout workers per model, with the concurrent GLM/Kimi jobs sharing two grader slots across the jobs. The single-job command above uses two graders for that job.
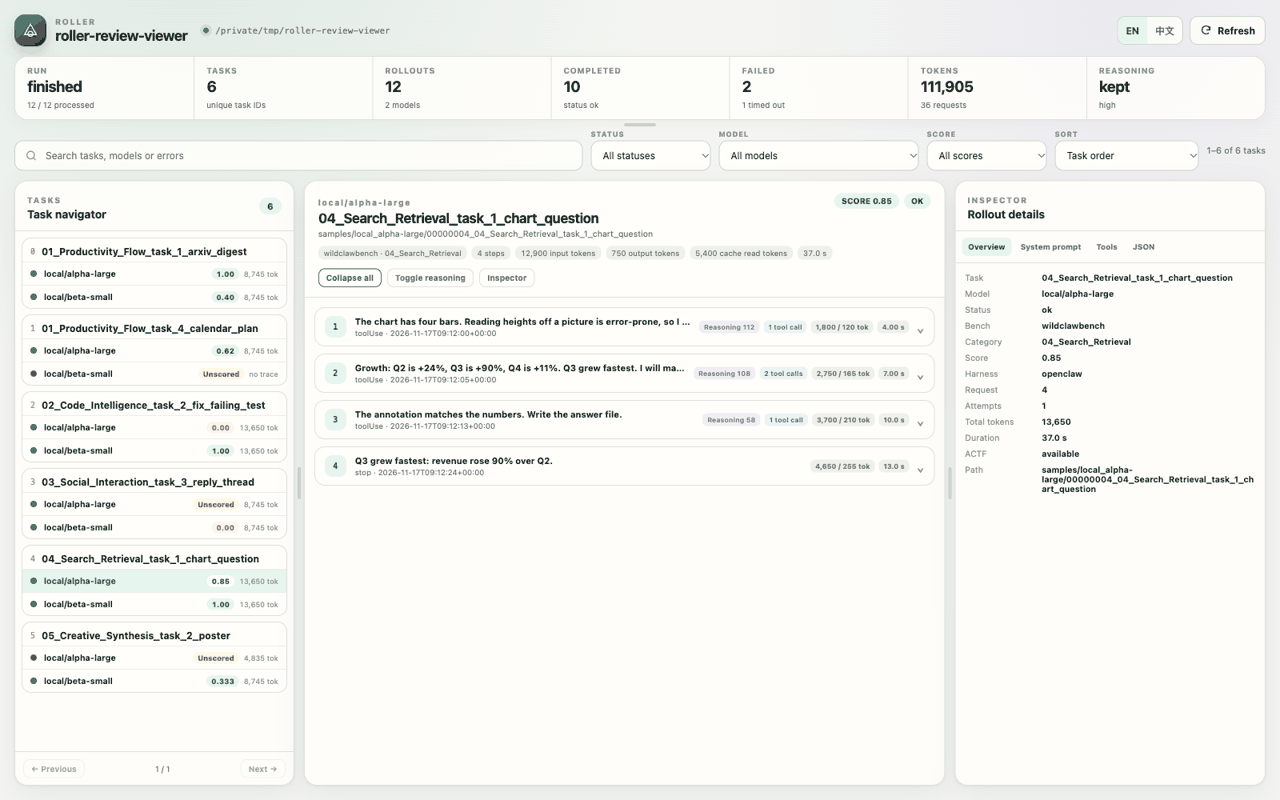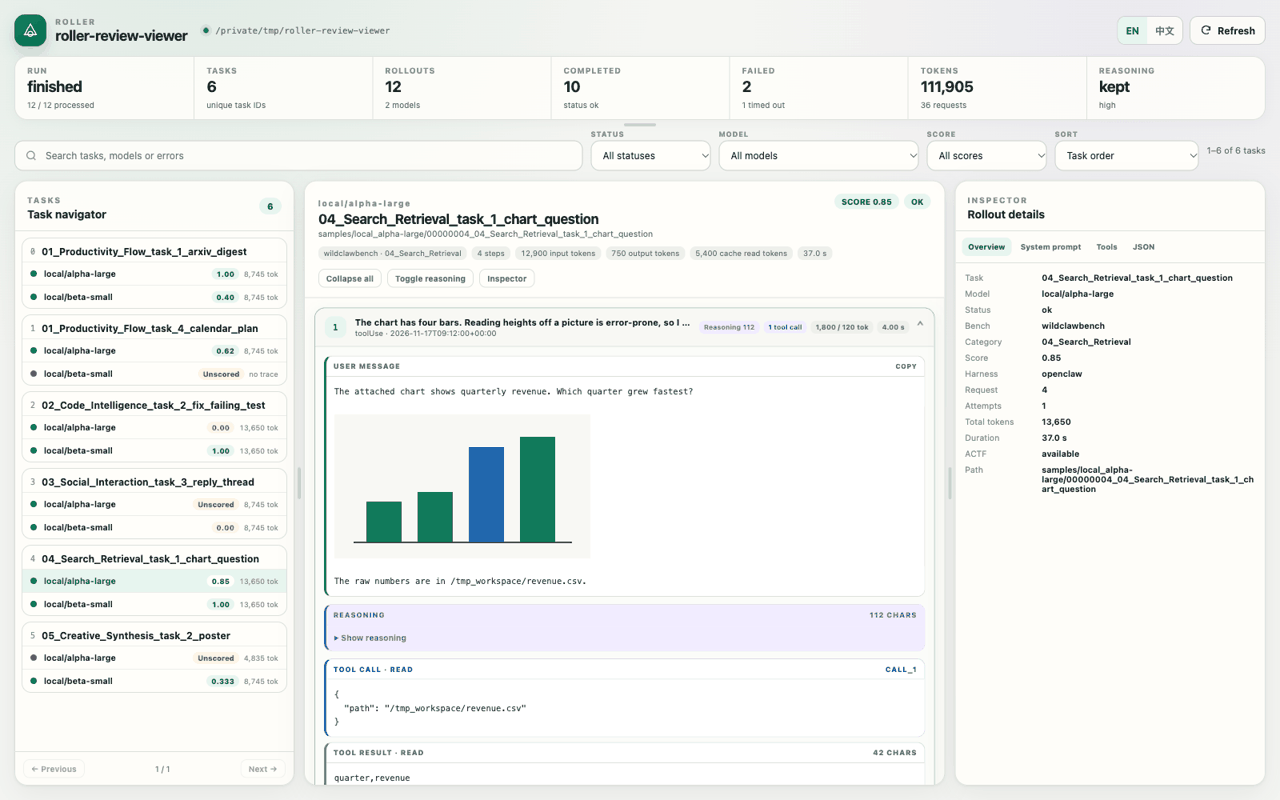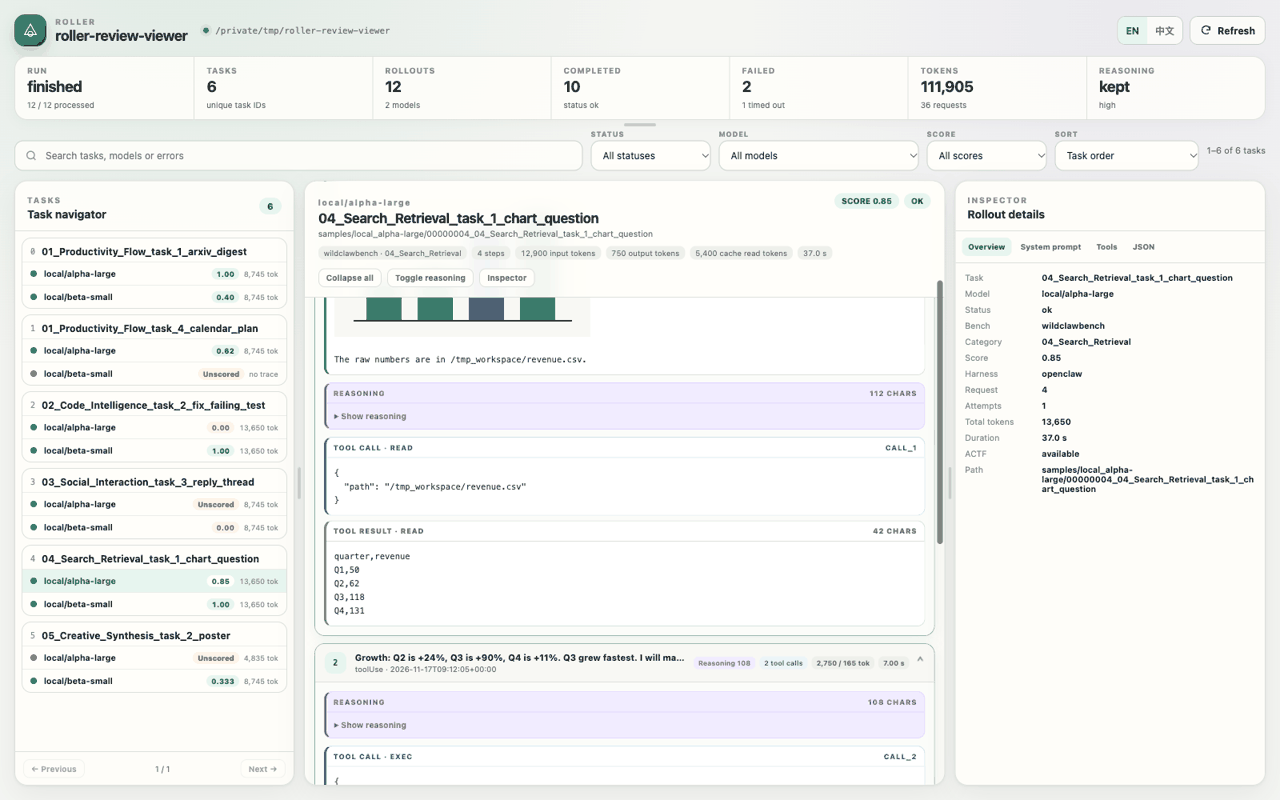
--bench converts the benchmark tasks, runs them, and grades each trajectory in the container where it ran. Five benchmarks are built in, and your own tasks are a JSONL file.messages and tools are available for 749 samples.--resume continues an interrupted run.roller export --format hf writes the files that the trace viewer of the Hub reads, the table that datasets loads, and the results table of the card.roller view opens a run directory in the browser: search the tasks, compare models on one task, and read each step.
Load the table. It has one row per trajectory, and messages and tools are
JSON strings:
import json

from datasets import load_dataset

rows = load_dataset(
    "Valen-Team/Roller-WildClawBench-Trajectories", "trajectories", split="train"
)
row = rows[0]
print(row["run"], row["upstream_task_id"], row["score"], row["steps"])
messages = json.loads(row["messages"])
Keep the trajectories that scored at least 0.8 as training records. Assistant
messages carry reasoning_content:
solved = rows.filter(
    lambda row: row["messages"] is not None and (row["score"] or 0) >= 0.8
)
records = [
    {"messages": json.loads(row["messages"]), "tools": json.loads(row["tools"])}
    for row in solved
]
Compare the models task by task:
frame = rows.to_pandas()
print(frame.pivot_table(index="upstream_task_id", columns="run", values="score"))
Every path carries a <harness>-<model> name, such as openclaw-glm-5.3-flash,
so each model and Harness has its own part.
| Path | Content |
|---|---|
traces/<harness>-<model>/<index>_<task>.jsonl |
The session of one trajectory, as the agent Harness wrote it. The traces configuration, which the Hub opens in its trace viewer |
data/<harness>-<model>.jsonl |
One row per trajectory. The trajectories configuration |
In an OpenClaw session, Roller writes four fields to the session header and
leaves every other line as OpenClaw wrote it: harness, a session ID that is
unique in this dataset, the session name, and a roller object with the
<harness>-<model> name, sample path, task, status, and score.
| Column | Content |
|---|---|
run, sample, trace |
The <harness>-<model> name, the sample path of the trajectory in the Roller run, and the path of its session under traces/ |
task_id, upstream_task_id, run_index |
Task ID of this repetition, the WildClawBench task ID, and the repetition number |
bench, category |
wildclawbench and the WildClawBench category |
model, harness |
Model reference and agent Harness |
status, error |
ok for a trajectory that finished, otherwise error or timeout with the reason |
score, grader_error |
WildClawBench score from 0 to 1. score is empty when grading failed, and grader_error gives the reason |
steps, tool_calls |
Number of model steps and of tool calls |
input_tokens, output_tokens, total_tokens, elapsed_seconds |
Usage and duration of the trajectory |
files |
Names of the files the agent wrote to the task output directory |
messages, tools |
The trajectory as an OpenAI chat request, as two JSON strings. Assistant messages carry reasoning_content. Available where a chat-format conversion was recorded |
The four collections contain 84 trajectories each: 28 tasks × 3 repetitions. The two Kimi service names retain the deployment suffixes used during collection.
| Item | Value |
|---|---|
| Benchmark | WildClawBench, revision 41bfe78a4d04369887687397708504882a80c17a |
| Tasks | 28 of 60, across Productivity Flow, Code Intelligence, Social Interaction, Creative Synthesis and Safety Alignment |
| Repetitions | 3 per task and model |
| Harness | OpenClaw 2026.3.11, image wildclawbench-ubuntu:v1.3 |
| Roller collection | 034fdaffbbe9f327618a51e5f04a9b49dec875a1 |
| Parallelism | 8 rollouts per model; 2 graders. Concurrent GLM/Kimi runs shared a global 2-slot grader budget |
| Timeouts | Original WildClawBench task timeouts, multiplier 1; grader timeout 120 seconds |
| Retries | No retries of normally ended failed or timed-out samples |
| Output budget | 32,768 tokens per response, thinking retained, full wire traces captured in the private run |
| Network | web_search disabled; external network access limited by the job environment. Warmup dependencies staged as offline wheels |
| Judge | GLM-5.3-Flash for all four models, invoked inside each task container |
| Collected | 16 November 2026, Asia/Singapore |
| Model | Collection model reference | Serving and reasoning |
|---|---|---|
| DeepSeek-V4.1-Flash-1017 | vllm/deepseek-v4.1-flash-1017 |
vLLM, TP4, DSpark=5, Engram CPU offload; thinking=true, reasoning_effort=100 |
| GLM-5.3-Flash | vllm/glm-5.3-flash |
vLLM, TP4, MTP=5; reasoning_effort=max |
| Kimi K3 | vllm/roller-kimi-k3-dspark |
vLLM, TP16/EP16, DSpark=8; thinking_effort=max |
| Kimi K3.1 Pro | vllm/roller-kimi-k3.1-pro-dflash5 |
SGLang, TP16/EP16, DFLASH width 5, Marlin MoE; default reasoning_effort=max |
Reasoning settings come from the recorded server configuration. The collection
client did not explicitly set temperature or top_p; sampling follows the
serving engine's defaults. DeepSeek ran first (19:50:13–21:18:02), then GLM
(21:37:07–23:24:03), Kimi K3 (21:55:07–23:39:59) and Kimi K3.1 Pro
(22:02:30–23:26:11),
all on 16 November in Asia/Singapore. The end times include grading and
run finalization.
Graders check local files and tool calls, or call the GLM-5.3-Flash judge.
| Model | ok |
Timeout | Error | Missing valid score |
|---|---|---|---|---|
| DeepSeek-V4.1-Flash | 72 | 10 | 2 | 0 |
| GLM-5.3-Flash | 57 | 22 | 5 | 1 |
| Kimi K3 | 61 | 21 | 2 | 3 |
| Kimi K3.1 Pro | 75 | 9 | 0 | 4 |
All 336 records are retained. Of these, 328 have valid scores. Eight lack
required grader inputs (screenshot.png or results.md); their score is null
and grader_error explains why. A timeout or runtime error can still have a
score if the benchmark grader can inspect the partial result.
Added on 17 November 2026: DeepSeek-V4.1-Flash-1017 and GLM-5.3-Flash each run the same 28 tasks three times, adding 168 trajectories.
| Item | Value |
|---|---|
| Harness | Codex CLI 0.149.0 |
| Task image | ghcr.io/valen-team/roller-wildclaw-codex:1.3-codex0.149.0 |
| Roller collection revision | a392cc0 |
| Judge | GLM-5.3-Flash |
| Parallelism | 8 rollouts per model, shared 2-slot grader budget |
| Timeouts | Original task limits; 120-second grader timeout |
| Retries | 0 agent retries and 0 grader retries |
| Output budget | 32,768 tokens per response; recorded backend thinking defaults retained |
| Serving | DeepSeek: DSpark=5, thinking enabled, effort 100; GLM: MTP=5, effort max |
| Model | ok |
Timeout | Error | Missing valid score |
|---|---|---|---|---|
| DeepSeek-V4.1-Flash | 81 | 3 | 0 | 0 |
| GLM-5.3-Flash | 57 | 27 | 0 | 1 |
All 168 attempts are retained; 167 have valid scores. The missing score remains null with its grader error. Raw run directories and wire captures stay in the collection environment.
Kimi K3 and Kimi K3.1 Pro each run the same 28 WildClawBench tasks three times with Codex CLI 0.149.0 and the GLM-5.3-Flash judge. The original task prompts and timeout limits are used for all 168 attempts. The coverage counts below include all three attempts per task.
Kimi K3 uses vLLM 0.33.0, which applies the Kimi parser's special-token spacing setting to streaming Responses tool arguments. Kimi K3.1 Pro uses the same SGLang tool-image compatibility mode as the initial collection.
| Model | ok |
Timeout | Error | Missing valid score |
|---|---|---|---|---|
| Kimi K3 | 39 | 45 | 0 | 10 |
| Kimi K3.1 Pro | 84 | 0 | 0 | 14 |
A missing score appears as null in the trajectory table, with the grader's error when available.
Claude Code 2.1.222 ran the same 28 tasks three times per model with the GLM-5.3-Flash judge and the original task timeouts. The collection script and task image reproduce the setup with an Anthropic Messages endpoint.
| Model | Completed | Timeout | Error | Missing score |
|---|---|---|---|---|
| DeepSeek-V4.1-Flash-1017 | 73 | 11 | 0 | 0 |
| GLM-5.3-Flash | 64 | 15 | 5 | 0 |
| Kimi K3 | 39 | 39 | 6 | 9 |
| Kimi K3.1 Pro | 73 | 11 | 0 | 1 |
The four endpoints used Anthropic Messages. Claude Code requested up to 32,000 output tokens. The collection used pinned Claude Code 2.1.222 and eight rollout workers per model, with two judge slots shared across the jobs.
The affected PDF requests were rerun using Roller's --claude-pdf-as-images
option, which forwards extracted text and a PNG for each PDF page. For the
affected GLM-5.3-Flash runs, Claude Code was configured with the endpoint's
98,304-token context window. Five reruns still exceeded that limit and their
error status is retained. Each table contains one row per scheduled task and
repetition.
The dataset is MIT licensed, with attribution to WildClawBench. The model cards linked above provide the licenses for each model.
@misc{roller,
  author       = {{Valen Team}},
  title        = {Roller},
  howpublished = {GitHub - Valen-Team/Roller: Agent trajectory collection across models and Harnesses.},
  note         = {GitHub repository},
  year         = {2026},
  url          = {https://github.com/Valen-Team/Roller}
}

@article{ding2026wildclawbench,
  title={WildClawBench: A Benchmark for Real-World, Long-Horizon Agent Evaluation},
  author={Ding, Shuangrui and Dai, Xuanlang and Xing, Long and Ding, Shengyuan and Liu, Ziyu and JingYi, Yang and Yang, Penghui and Zhang, Zhixiong and Wei, Xilin and Fang, Xinyu and others},
  journal={arXiv preprint arXiv:2605.10912},
  year={2026}
}