
Datasets:

File size: 10,702 Bytes
3a7e97b ffed732 34fa27c 3a7e97b 34fa27c 3a7e97b 34fa27c 3a7e97b 34fa27c 3a7e97b 34fa27c 3a7e97b 34fa27c 99f432f 34fa27c 3a7e97b ffed732 3a7e97b 34fa27c ffed732 34fa27c 3a7e97b 34fa27c ffed732 34fa27c 3a7e97b 34fa27c 3a7e97b 34fa27c 3a7e97b b3a631f 34fa27c | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 203 204 205 206 207 208 209 210 211 212 213 214 215 216 | ---
license: mit
pretty_name: "Stepwise Token Learning: Token-Level Loss Trajectories Along Scaling Axes"
task_categories:
- text-generation
tags:
- scaling-laws
- learning-dynamics
- training-dynamics
- token-loss
- loss-curves
- language-modeling
- interpretability
- neurips-2026
size_categories:
- 1M<n<10M
configs:
- config_name: step_axis_1m
default: true
data_files:
- split: preview
path: previews/step_axis_1m.parquet
- config_name: d_axis_1m
data_files:
- split: preview
path: previews/d_axis_1m.parquet
- config_name: m_axis_1m
data_files:
- split: preview
path: previews/m_axis_1m.parquet
- config_name: synthetic_mano_uniform_validation_10k
data_files:
- split: full
path: previews/synthetic_mano_uniform_validation_10k.parquet
- config_name: axes
data_files:
- split: full
path: previews/axes.parquet
---
<p align="center">
<a href="https://applewpj.github.io/stepwise-token-learning/"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/banner.png" width="100%" alt="Smooth Scaling Laws Hide Stepwise Token Learning, NeurIPS 2026 Spotlight. Each token's loss falls in one sigmoid-shaped step, and their average is the smooth loss curve."></a>
</p>
<p align="center">
<a href="https://applewpj.github.io/stepwise-token-learning/" style="display: inline-block; margin: 3px;"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-page.svg" alt="Interactive project page" style="display: inline-block; vertical-align: middle; margin: 0;"></a>
<a href="https://openreview.net/forum?id=THZDVZArRH" style="display: inline-block; margin: 3px;"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-paper.svg" alt="Paper on OpenReview" style="display: inline-block; vertical-align: middle; margin: 0;"></a>
<a href="https://github.com/applewpj/stepwise-token-learning" style="display: inline-block; margin: 3px;"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-code.svg" alt="Code on GitHub" style="display: inline-block; vertical-align: middle; margin: 0;"></a>
<a href="https://colab.research.google.com/github/applewpj/stepwise-token-learning/blob/main/notebooks/quickstart.ipynb" style="display: inline-block; margin: 3px;"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-colab.svg" alt="Quickstart in Colab" style="display: inline-block; vertical-align: middle; margin: 0;"></a>
<a href="#citation" style="display: inline-block; margin: 3px;"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-bibtex.svg" alt="BibTeX" style="display: inline-block; vertical-align: middle; margin: 0;"></a>
</p>
# Stepwise Token Learning: Token-Level Loss Trajectories
Per-token validation-loss trajectories for **one million contextualized tokens**
along each of three scaling axes of LLM pre-training (training steps *T*, data
scale *D*, model scale *M*), plus a synthetic arithmetic example. They are the
inputs to the analysis in
**[Smooth Scaling Laws Hide Stepwise Token Learning](https://openreview.net/forum?id=THZDVZArRH)**
(NeurIPS 2026, Spotlight).
> **See these trajectories move.** The
> [interactive project page](https://applewpj.github.io/stepwise-token-learning/)
> plots tokens from these matrices, shows how they add up to the loss curve,
> and lets you play with the mechanism. The
> [code on GitHub](https://github.com/applewpj/stepwise-token-learning)
> downloads these files and reproduces every figure with one command.
## What the Matrices Show
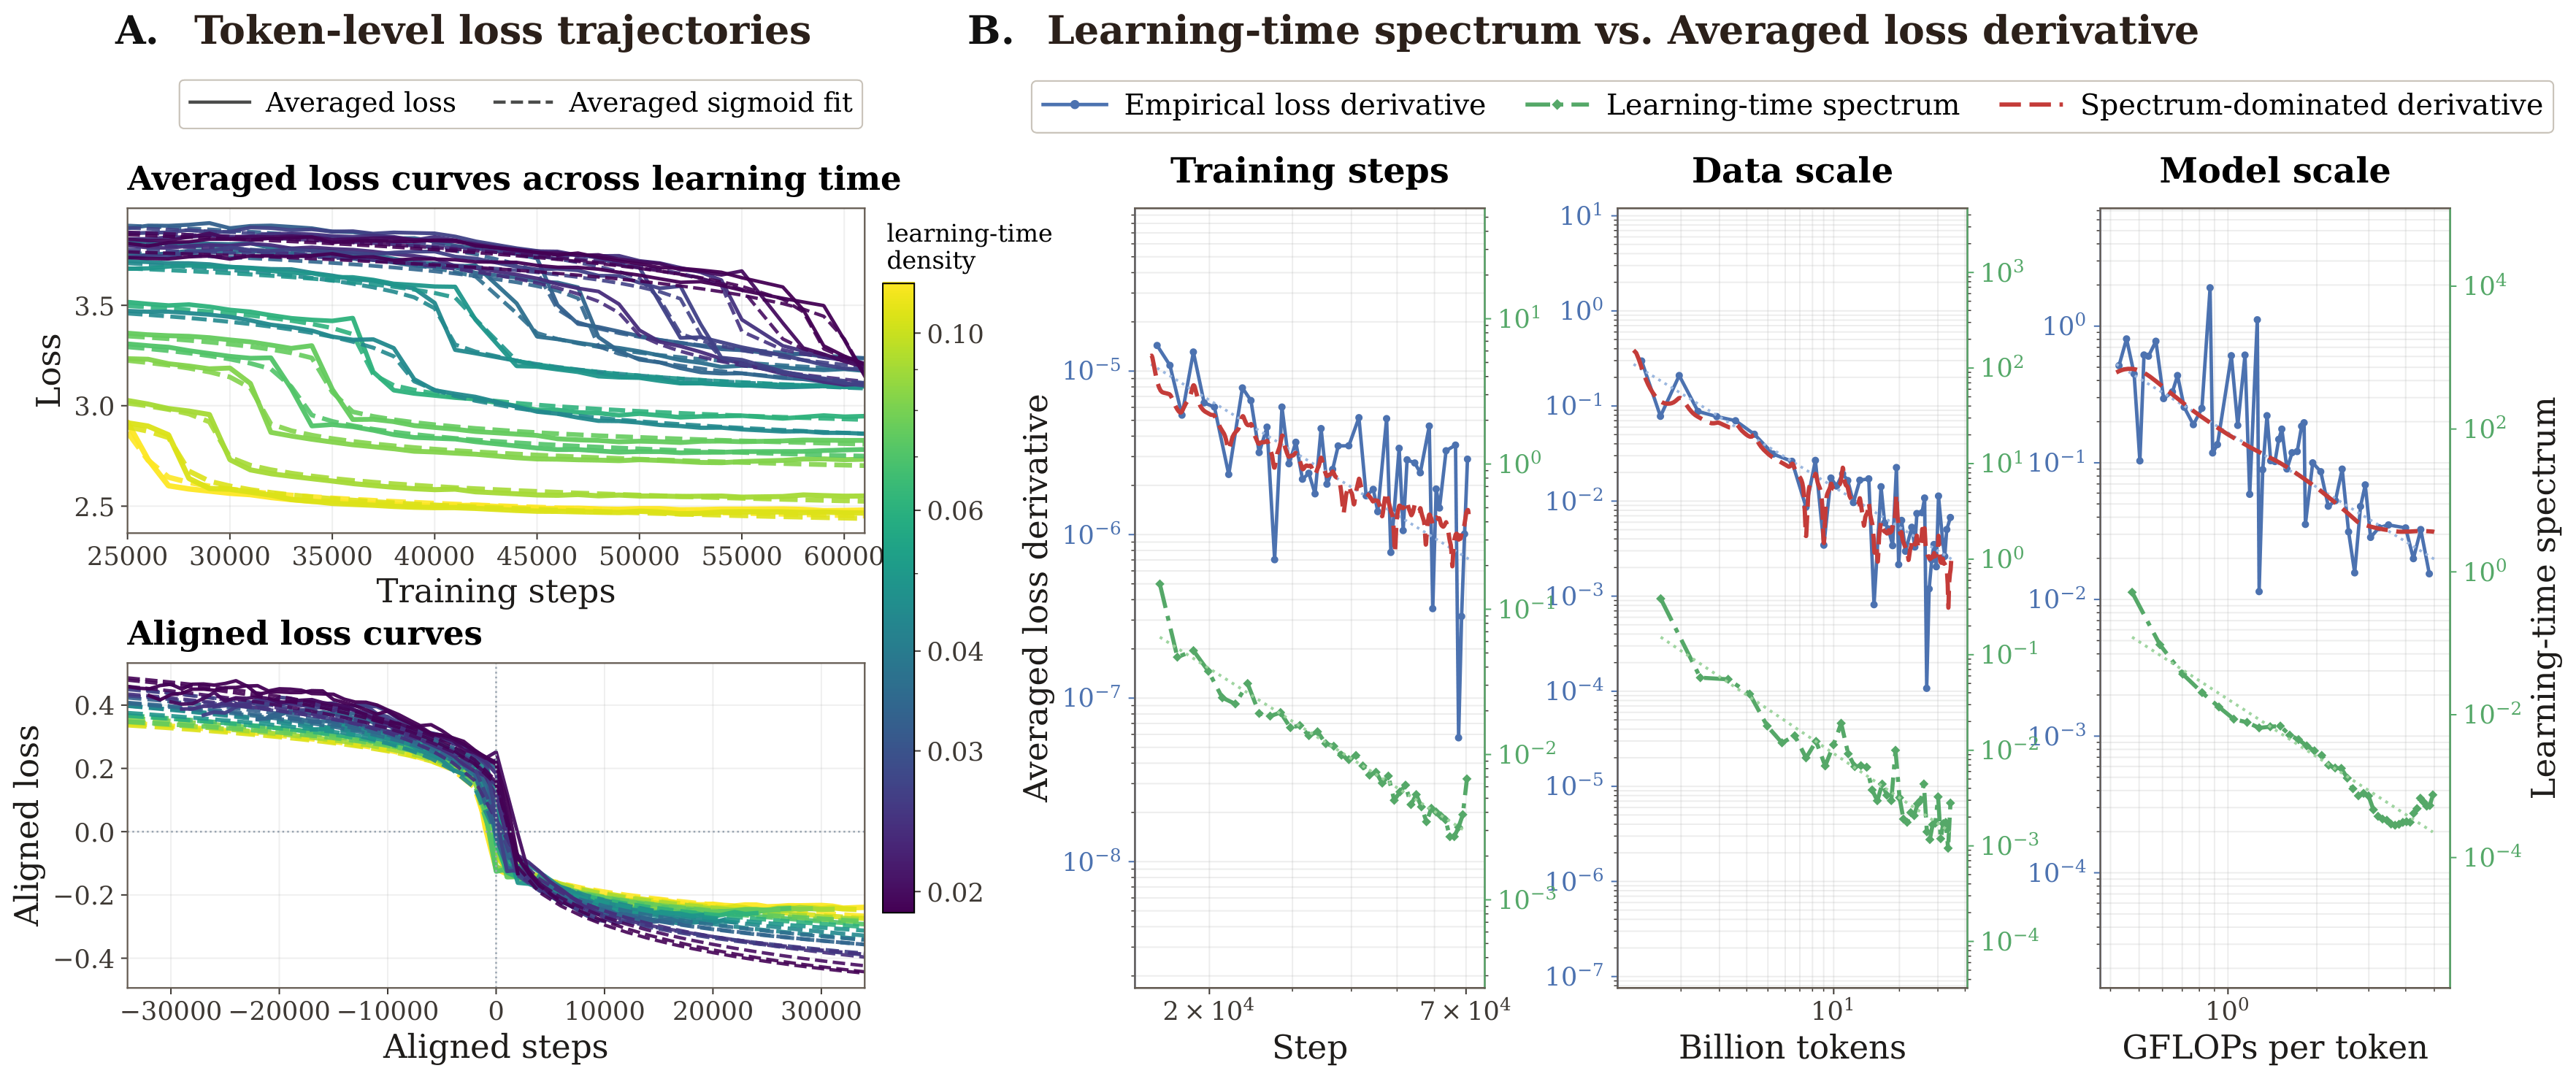
Each row is one contextualized token, and each column is a checkpoint or a run
along the scaling axis *a*. Individual rows drop in localized, sigmoid-like
steps, which the paper fits with one learning event per token:
$$
\ell_i(a) \approx \ell_i^{\mathrm{post}} + \Delta_i \left[ 1 - \sigma\big( \lambda_i (a - \tau_i) \big) \right]
$$
Here τ is when the token is learned, λ how abruptly, and Δ how much loss it
sheds. The learning pulses share one shape *g*, so the slope of the averaged
loss *L* is the distribution of learning times, the learning-time spectrum
*p*(τ), smoothed by *g*:
$$
-\frac{\mathrm{d}L}{\mathrm{d}a} \approx \int p(\tau) \thinspace g(a - \tau) \thinspace \mathrm{d}\tau
$$
## Contents
| Asset | Scaling axis | Rows × points | Axis range | NPZ size | Paper | Viewer config |
| --- | --- | ---: | --- | ---: | --- | --- |
| [`step_axis_1m`](examples/step_axis_1m/losses.npz) | Training steps *T* | 1,000,000 × 54 | 15,000–71,000 steps | 196.7 MB | Figure 3 | `step_axis_1m` (10K-row preview) |
| [`d_axis_1m`](examples/d_axis_1m/losses.npz) | Data scale *D* | 1,000,000 × 50 | 1.196–34.662B tokens | 183.0 MB | Figure 4 | `d_axis_1m` (10K-row preview) |
| [`m_axis_1m`](examples/m_axis_1m/losses.npz) | Model scale *M* | 1,000,000 × 60 | 0.416–4.999 GFLOPs/token | 219.3 MB | Figure 5 | `m_axis_1m` (10K-row preview) |
| [`synthetic_mano_uniform_validation_10k`](examples/synthetic_mano_uniform_validation_10k/losses.npz) | Training steps | 10,000 × 80 | 5,000–400,000 steps | 1.5 MB | Appendix | `synthetic_mano_uniform_validation_10k` (all rows) |
The full matrices are the `losses.npz` files. The Dataset Viewer shows Parquet
previews: a seeded random sample of 10,000 rows from each T/D/M matrix, the
complete synthetic matrix, and an `axes` table with the axis values of every
asset. Byte sizes and SHA256 checksums are listed in
[`manifest.yaml`](manifest.yaml).
## Quick Start
Browse a preview with 🤗 Datasets:
```python
from datasets import load_dataset
repo = "applewpj/stepwise-token-learning"
preview = load_dataset(repo, "step_axis_1m", split="preview") # columns: row, loss[54]
axes = load_dataset(repo, "axes", split="full") # axis values per asset
```
Load a full matrix with NumPy:
```python
import numpy as np
from huggingface_hub import hf_hub_download
path = hf_hub_download(
repo_id="applewpj/stepwise-token-learning",
repo_type="dataset",
filename="examples/step_axis_1m/losses.npz",
)
with np.load(path, allow_pickle=False) as data:
steps = data["axis_values"] # (54,) training steps
losses = data["loss_matrix"] # (1000000, 54) float32, one row per token
mean_loss = losses.mean(axis=0) # the aggregate validation-loss curve
```
Reproduce the paper figures from these files with the
[analysis code](https://github.com/applewpj/stepwise-token-learning). Each
command downloads the matrix it needs, verifies its checksum, fits it, and
checks the result against reference numbers:
```bash
git clone https://github.com/applewpj/stepwise-token-learning
cd stepwise-token-learning
pip install -e .
tokenlearning reproduce fig3 --quick # Figure 3 from 50,000 tokens, about a minute on CPU
tokenlearning reproduce all # Figures 3-5 and the appendix at the paper setting
```
The [Colab quickstart](https://colab.research.google.com/github/applewpj/stepwise-token-learning/blob/main/notebooks/quickstart.ipynb)
runs the same pipeline in the browser.
## Data Structure
Each `losses.npz` contains:
```text
axis_values: float64 [K] ordered positions along the scaling axis
loss_matrix: float32 [N, K] loss of token row i at axis point j
axis_name: string [1] e.g. "training step"
```
Rows are aligned: `loss_matrix[i, j]` is the same contextualized token at every
axis point `j`, which is what makes token-level trajectories meaningful. The
synthetic matrix adds per-row metadata: `sample_id`, `token_pos`, `difficulty`,
`seed`, and `question` (the arithmetic expression).
The Parquet previews have one row per token with columns `row` (index into the
full `loss_matrix`), any per-row metadata, and `loss` (the trajectory as a list
of `K` floats). The `axes` config has one row per asset with `asset`,
`axis_name`, `n_points`, `n_tokens`, `preview_rows`, and `axis_values`.
## Provenance
| Asset | How it was produced |
| --- | --- |
| `step_axis_1m` | A 1.5B dense model trained on 300B tokens of a mixed corpus (Chinese, English, mathematics, reasoning, books, papers, code); 54 checkpoints. |
| `d_axis_1m` | A 290M MoE model; a 50-run sweep over training budgets from 1B to 35B tokens, each run with a complete warmup-constant-decay schedule, used to construct the data-scale frontier. |
| `m_axis_1m` | A 60-run sweep of model variants from 0.42 to 5.00 GFLOPs/token (≈400M–6B parameters), each trained on 10B tokens and tuned toward a near-optimal model-scale frontier. |
| `synthetic_mano_uniform_validation_10k` | The public synthetic arithmetic (Mano) pipeline adapted from [PhysicsLM4](https://github.com/facebookresearch/PhysicsLM4); 10,000 validation samples scored at 80 checkpoints. |
The T/D/M losses are measured on held-out validation tokens; for the step axis,
the validation set is sampled from the same distribution as the training
corpus. The matrices are sanitized analysis artifacts: they keep aligned token
losses and axis values only, and do not include model architectures, weights,
tokenizers, validation text, training-data composition, experiment registries,
or checkpoint paths.
## Uses and Limitations
Suited for reproducing the paper's analysis, testing alternative learning-time
estimators or curve-fitting methods, and studying token-level learning dynamics
along scaling axes.
- Rows of the T/D/M matrices cannot be mapped back to token strings or text.
- These are loss measurements, not a language-model training corpus.
- Per-token trajectories are noisy; the paper's sigmoid fits describe the
dominant transition, not every fluctuation.
## Citation
```bibtex
@inproceedings{wang2026smooth,
title = {Smooth Scaling Laws Hide Stepwise Token Learning},
author = {Wang, Pingjie and Hu, Zechen and Yang, Peiru and Guo, Fu and Zhang, Debing},
booktitle = {Advances in Neural Information Processing Systems},
year = {2026},
url = {https://openreview.net/forum?id=THZDVZArRH}
}
```
## License and Contact
The matrices are released under the
[MIT License](https://huggingface.co/datasets/applewpj/stepwise-token-learning/blob/main/LICENSE).
Questions and issues are welcome on the
[GitHub issue tracker](https://github.com/applewpj/stepwise-token-learning/issues).
|