| --- |
| configs: |
| - config_name: default |
| data_files: |
| - split: train |
| path: data/train-* |
| dataset_info: |
| features: |
| - name: image |
| dtype: image |
| - name: output |
| dtype: string |
| - name: file_name |
| dtype: string |
| splits: |
| - name: train |
| num_bytes: 63343704014 |
| num_examples: 151945 |
| download_size: 0 |
| dataset_size: 63343704014 |
| license: other |
| task_categories: |
| - image-classification |
| size_categories: |
| - 100K<n<1M |
| license_name: mixed-creative-commons |
| license_link: https://github.com/inaturalist/inaturalist-open-data |
| --- |
| |
| # NE Plant Classes |
|
|
| Plant photographs from the [iNaturalist open data](https://github.com/inaturalist/inaturalist-open-data) |
| archive, filtered to a New England bounding box (latitude 41 to 48, longitude |
| -74 to -67) and each labelled by a vision language model with the kind of |
| subject it depicts. |
|
|
| Labels come from [Qwen/Qwen3.5-9B](https://huggingface.co/Qwen/Qwen3.5-9B); |
| they are model output, not human annotation, and have not been checked against |
| a hand-labelled sample. |
|
|
| 151,945 images in a single `train` split. |
|
|
| ## Columns |
|
|
| - `image` - the photograph, embedded in the dataset |
| - `output` - the model's one-word classification |
| - `file_name` - the original image filename, named after the iNaturalist photo id |
|
|
| ## Labels |
|
|
| The prompt sorts each photo into one of five classes, falling back to `other` |
| when none of the first four fit. |
|
|
| 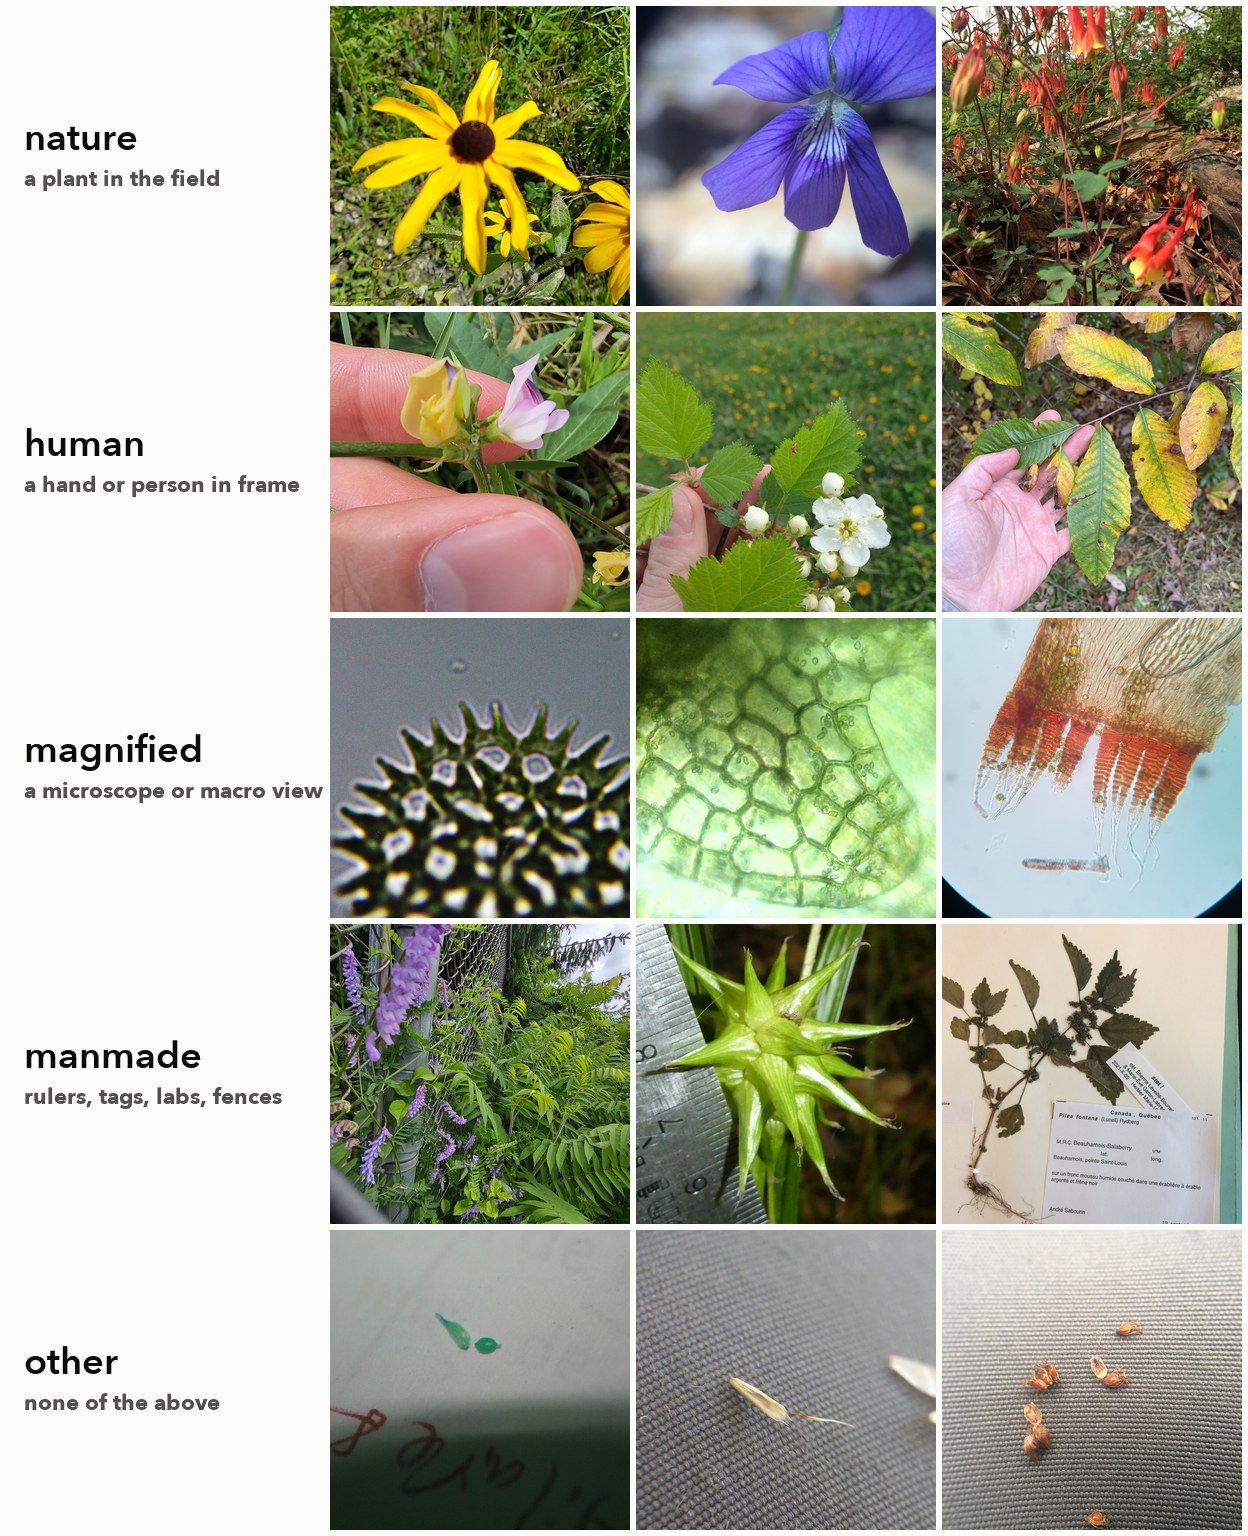 |
|
|
| | label | count | share | |
| |-----------|--------:|-------:| |
| | nature | 114,192 | 75.2% | |
| | human | 33,702 | 22.2% | |
| | manmade | 2,310 | 1.5% | |
| | magnified | 1,715 | 1.1% | |
| | other | 26 | <0.1% | |
|
|
| ## Label Quality |
|
|
| The labels are model output and some of them are wrong. A ViT classifier |
| trained on this dataset |
| ([blambert/ne_plant_classes_vit](https://huggingface.co/blambert/ne_plant_classes_vit)) |
| disagrees with the label on 1.6% of held-out photos, and a review of 160 of |
| those disagreements suggested the label, not the classifier, was wrong about |
| two thirds of the time. That puts **roughly 1% of the dataset, on the order of |
| 1,500 photos, under a wrong label**, and that is a lower bound: the classifier |
| learned the labeller's habits, so mistakes the two share are invisible to it. |
|
|
| The errors are concentrated: |
|
|
| | label | disagreement rate | note | |
| |-----------|------------------:|----------------------------------------------------------| |
| | nature | 0.9% | mostly photos with a hand or a ruler in frame | |
| | human | 1.5% | often no hand visible at all | |
| | magnified | 9.9% | | |
| | manmade | 31.4% | roughly 1 in 6 `manmade` labels looks wrong | |
|
|
| `manmade` is the least reliable label, partly because the prompt never settled |
| what it means: a plant growing in a sidewalk crack or beside a road is |
| sometimes `manmade` and sometimes `nature`. |
|
|
| This is still good enough for some purposes. Separating `nature` from `human` |
| is reliable enough for coarse filtering, which is what |
| [blambert/ne_plant_photos](https://huggingface.co/datasets/blambert/ne_plant_photos) |
| does. Treat the small classes, and any per-label accuracy measured against |
| these labels, with more caution, and hand-label a sample before trusting them |
| as ground truth. |
|
|
| ## Licensing |
|
|
| The photographs keep whichever license each iNaturalist observer chose, so the |
| collection is not under a single license and most of it is non-commercial. |
|
|
| | license | count | share | |
| |-------------|--------:|-------:| |
| | CC-BY-NC | 114,639 | 75.4% | |
| | CC-BY | 22,883 | 15.1% | |
| | CC0 | 10,080 | 6.6% | |
| | CC-BY-NC-SA | 3,292 | 2.2% | |
| | CC-BY-SA | 1,051 | 0.7% | |
|
|
| Everything but the CC0 portion requires attribution. Observer and photo |
| metadata live in the iNaturalist open data archive, joinable on the photo id in |
| `file_name`. The sample photos on this card are all CC0. |
|
|
| ## Provenance |
|
|
| Labelled by running `vlm process` with `prompts/inat_classify.txt` over the |
| downloaded images, then uploaded with `vlm upload-dataset`. Both commands come |
| from the [vlm-toolkit](https://github.com/belambert/vlm-toolkit) repo; the |
| filtering and download steps are in [plant-pics](https://github.com/belambert/plant-pics). |
|
|

