
Diffusers documentation
من صورة إلى صورة
من صورة إلى صورة
يُشبه التحويل من صورة إلى صورة التحويل من نص إلى صورة، لكن بالإضافة إلى الأمر النصي، يمكنك أيضًا تمرير صورة أولية كنقطة انطلاق لعملية الانتشار. يتم ترميز الصورة الأولية إلى الفضاء الكامن وإضافة ضوضاء إليها. ثم يأخذ نموذج الانتشار الكامن الأمر النصي والصورة الكمنية الضوضائية، ويتنبأ بالضوضاء المضافة، ويزيل الضوضاء المتنبأ بها من الصورة الكمنية الأولية للحصول على الصورة الكمنية الجديدة. أخيرًا، يقوم فك الترميز بفك ترميز الصورة الكمنية الجديدة مرة أخرى إلى صورة.
مع 🤗 Diffusers، الأمر سهل للغاية:
- حمّل نقطة تفتيش إلى فئة AutoPipelineForImage2Image؛ تتولى هذه المسار تلقائيًا تحميل فئة المسار الصحيحة بناءً على نقطة التفتيش:
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import load_image, make_image_grid

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "kandinsky-community/kandinsky-2-2-decoder", dtype=torch.float16, use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()
ستلاحظ طوال الدليل أننا نستخدم enable_model_cpu_offload() و enable_xformers_memory_efficient_attention() لتوفير الذاكرة وزيادة سرعة الاستدلال. إذا كنت تستخدم PyTorch 2.0، فلا تحتاج إلى استدعاء enable_xformers_memory_efficient_attention() على خط الأنابيب الخاص بك لأنه سيستخدم بالفعل scaled-dot product attention الأصلية في PyTorch 2.0.
- قم بتحميل صورة لتمريرها إلى خط الأنابيب:
init_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cat.png")- مرّر موجهًا (prompt) وصورة إلى خط الأنابيب (pipeline) لتوليد صورة:
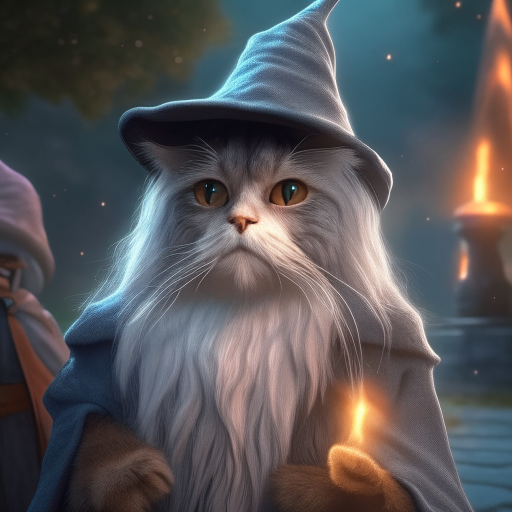
prompt = "cat wizard, gandalf, lord of the rings, detailed, fantasy, cute, adorable, Pixar, Disney, 8k"
image = pipeline(prompt, image=init_image).images[0]
make_image_grid([init_image, image], rows=1, cols=2)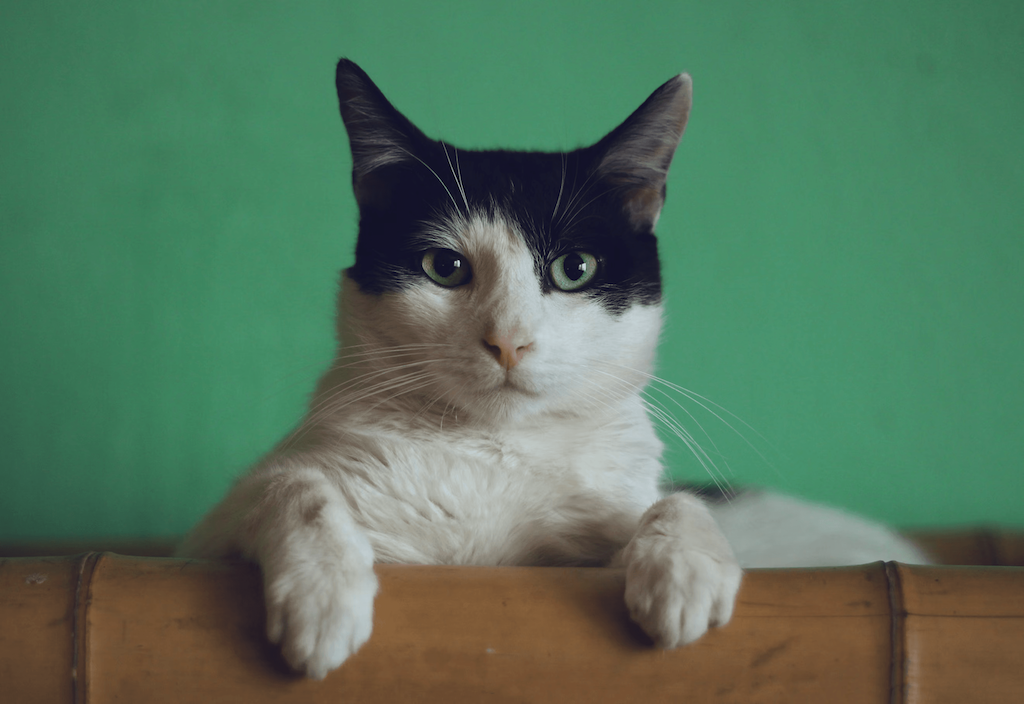
النماذج الشائعة
تُعدّ أكثر نماذج التحويل من صورة إلى صورة شيوعًا هي Stable Diffusion v1.5 وStable Diffusion XL (SDXL) وKandinsky 2.2. تختلف النتائج التي تُنتجها نماذج Stable Diffusion وKandinsky بسبب اختلافات البنية المعمارية وعملية التدريب؛ وبشكل عام، يمكن توقع أن تُنتج SDXL صورًا بجودة أعلى من Stable Diffusion v1.5. دعونا نلقي نظرة سريعة على كيفية استخدام كلٍّ من هذه النماذج ومقارنة نتائجها.
Stable Diffusion v1.5
Stable Diffusion v1.5 هو نموذج انتشار كامن (latent diffusion model) مُهيّأ من نقطة تحقق (checkpoint) سابقة، وخضع لتدريب دقيق إضافي لمدة 595 ألف خطوة على صور بأبعاد 512x512. لاستخدام هذا الخطّ (pipeline) لتحويل الصورة إلى صورة، ستحتاج إلى تجهيز صورة أولية لتُمرَّر إلى الخطّ. ثم يمكنك تمرير وصف (prompt) والصورة إلى الخطّ لتوليد صورة جديدة:
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

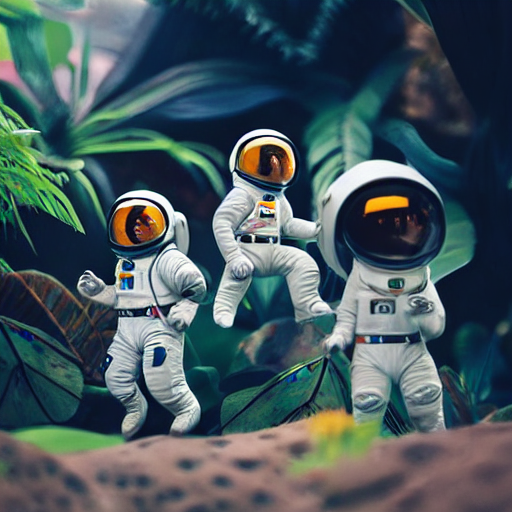
prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image = pipeline(prompt, image=init_image).images[0]
make_image_grid([init_image, image], rows=1, cols=2)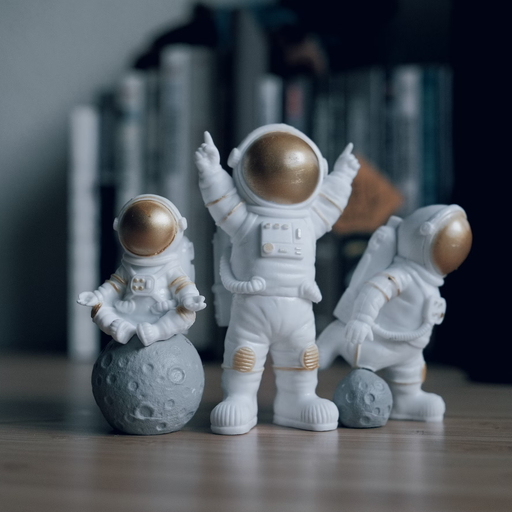
Stable Diffusion XL (SDXL)
SDXL هو إصدار أقوى من نموذج Stable Diffusion. يستخدم نموذجًا أساسيًا أكبر، بالإضافة إلى نموذج تحسين إضافي لزيادة جودة مخرجات النموذج الأساسي. اقرأ دليل SDXL للحصول على شرح أكثر تفصيلًا لكيفية استخدام هذا النموذج، والتقنيات الأخرى التي يستخدمها لإنتاج صور عالية الجودة.
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stabilityai/stable-diffusion-xl-refiner-1.0", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-sdxl-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image = pipeline(prompt, image=init_image, strength=0.5).images[0]
make_image_grid([init_image, image], rows=1, cols=2)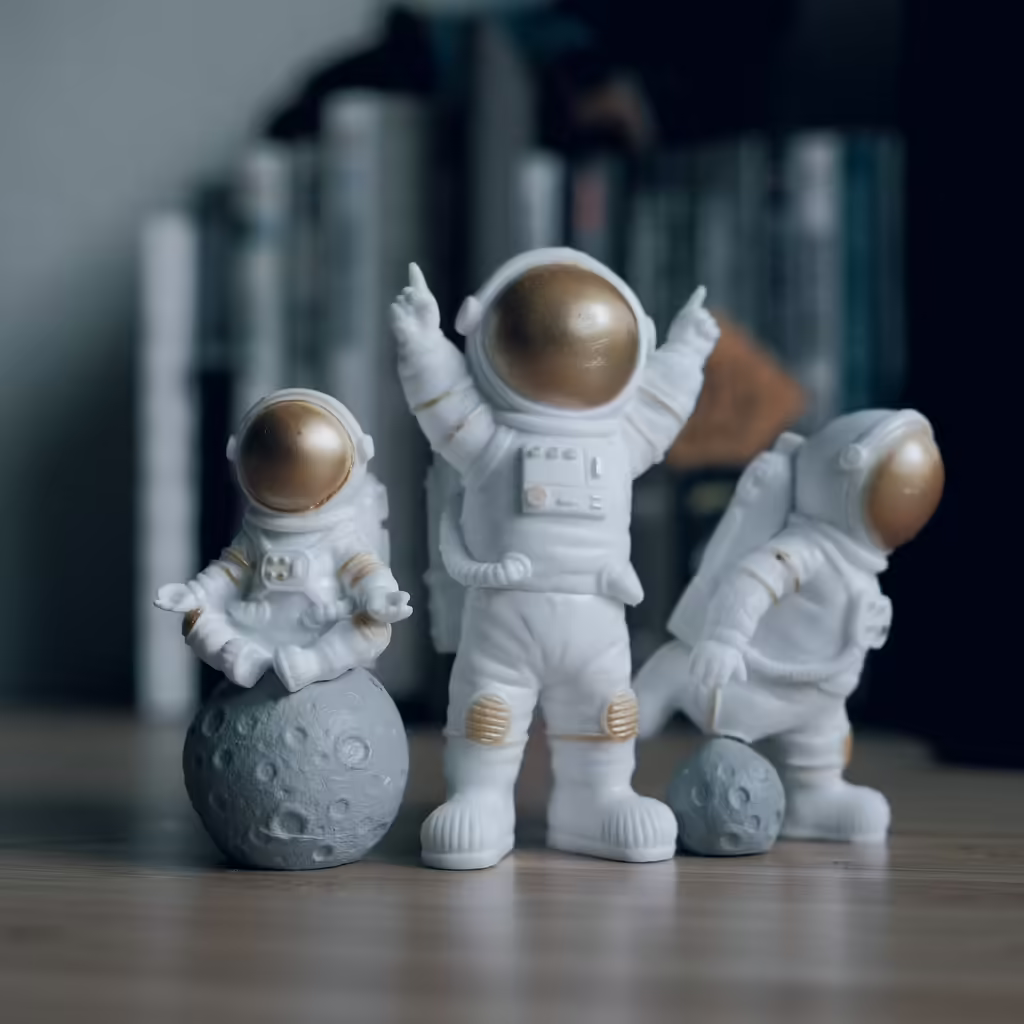

Kandinsky 2.2
يختلف نموذج Kandinsky عن نماذج Stable Diffusion لأنه يستخدم نموذجًا مسبقًا للصور لإنشاء تمثيلات (embeddings) للصور. تساعد هذه التمثيلات في تحقيق توافق أفضل بين النص والصور، مما يتيح لنموذج الانتشار الكامن (latent diffusion model) توليد صور أفضل.
أبسط طريقة لاستخدام Kandinsky 2.2 هي:
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "kandinsky-community/kandinsky-2-2-decoder", dtype=torch.float16, use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image = pipeline(prompt, image=init_image).images[0]
make_image_grid([init_image, image], rows=1, cols=2) 
إعداد معلمات خط الأنابيب
توجد عدة معاملات مهمة يمكنك ضبطها في خط الأنابيب pipeline تؤثر على عملية توليد الصور وجودة الصور. دعونا ننظر عن كثب إلى ما تفعله هذه المعاملات وكيف يؤثر تغييرها على المخرجات.
القوة
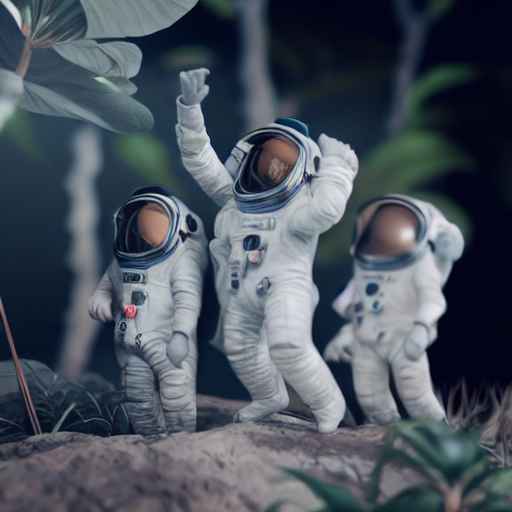
strength هو أحد أهم المعايير التي يجب مراعاتها، وسيكون له تأثير كبير على الصورة التي يتم توليدها. فهو يحدد مدى تشابه الصورة المولّدة مع الصورة الأولية. بعبارة أخرى:
- 📈 كلما زادت قيمة
strength، ازدادت “الإبداعية” الممنوحة للنموذج لتوليد صورة مختلفة عن الصورة الأولية؛ فقيمةstrengthتساوي 1.0 تعني أن الصورة الأولية تُتجاهل إلى حد كبير - 📉 قيمة
strengthأدنى تعني أن الصورة المولّدة ستكون أكثر تشابهًا مع الصورة الأولية
ترتبط معالِتا strength وnum_inference_steps ببعضهما لأن strength يحدد عدد خطوات الضوضاء المضافة. على سبيل المثال، إذا كان num_inference_steps يساوي 50 وكان strength يساوي 0.8، فهذا يعني إضافة 40 (50 * 0.8) خطوة من الضوضاء إلى الصورة الأولية ثم إزالة الضوضاء على مدى 40 خطوة للحصول على الصورة المولَّدة حديثًا.
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image = pipeline(prompt, image=init_image, strength=0.8).images[0]
make_image_grid([init_image, image], rows=1, cols=2)
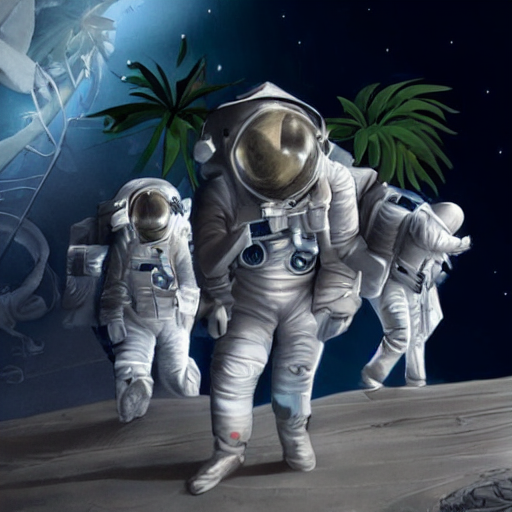
مقياس التوجيه
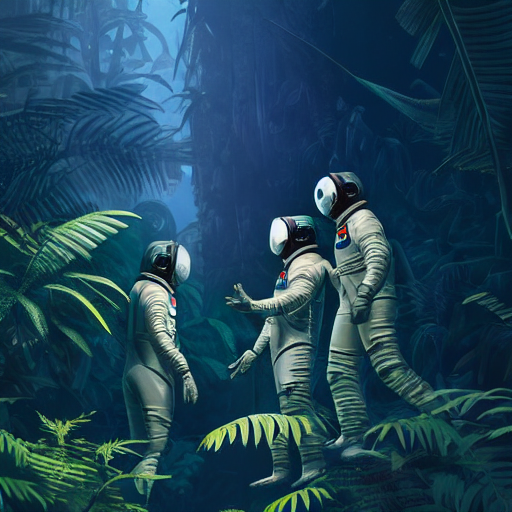
يُستخدم معامل guidance_scale للتحكم في مدى التوافق بين الصورة المولَّدة وموجّه النص. فكلما ارتفعت قيمة guidance_scale، زاد توافق الصورة المولَّدة مع الموجّه، بينما كلما انخفضت قيمة guidance_scale، ازداد هامش انحراف الصورة المولَّدة عن الموجّه.
يمكنك دمج guidance_scale مع strength للحصول على تحكم أدق في مدى تعبيرية النموذج. على سبيل المثال، ادمج قيمة عالية لـ strength + guidance_scale للحصول على أقصى قدر من الإبداع، أو استخدم مزيجًا من قيمة منخفضة لـ strength وقيمة منخفضة لـ guidance_scale لتوليد صورة تشبه الصورة الأولية لكنها ليست مرتبطة ارتباطًا صارمًا بالموجّه النصي.
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image = pipeline(prompt, image=init_image, guidance_scale=8.0).images[0]
make_image_grid([init_image, image], rows=1, cols=2)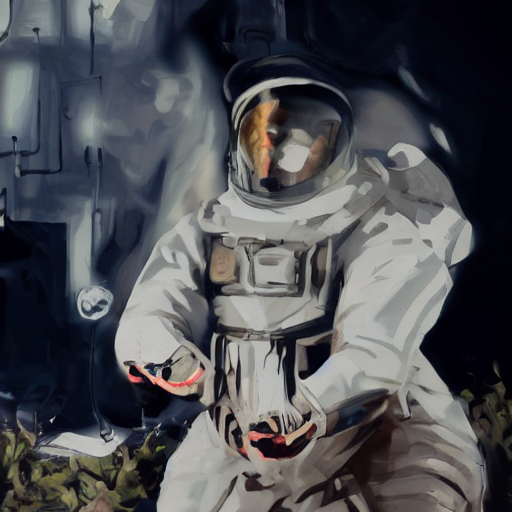

الموجّه السلبي
يُشترط النموذج من خلال موجه سلبي بعدم تضمين عناصر معينة في الصورة، ويمكن استخدامه لتحسين جودة الصورة أو تعديلها. على سبيل المثال، يمكنك تحسين جودة الصورة من خلال تضمين موجهات سلبية مثل “تفاصيل رديئة” أو “ضبابية” لتشجيع النموذج على توليد صورة بجودة أعلى. أو يمكنك تعديل الصورة عن طريق تحديد العناصر التي يجب استبعادها منها.
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stabilityai/stable-diffusion-xl-refiner-1.0", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"
negative_prompt = "ugly, deformed, disfigured, poor details, bad anatomy"

# pass prompt and image to pipeline
image = pipeline(prompt, negative_prompt=negative_prompt, image=init_image).images[0]
make_image_grid([init_image, image], rows=1, cols=2)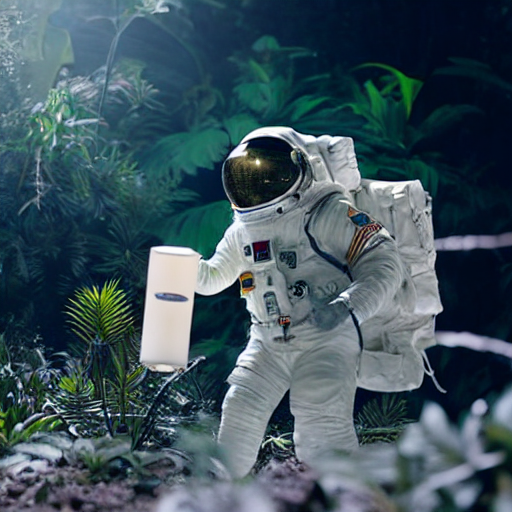
خطوط أنابيب تحويل الصورة إلى صورة متسلسلة
توجد طرق أخرى مثيرة للاهتمام لاستخدام خط أنابيب تحويل الصورة إلى صورة، بخلاف مجرد توليد صورة (على الرغم من أن ذلك مثير للاهتمام أيضاً). يمكنك الذهاب خطوة أبعد وربطه بخطوط أنابيب أخرى.
من النص إلى الصورة إلى الصورة
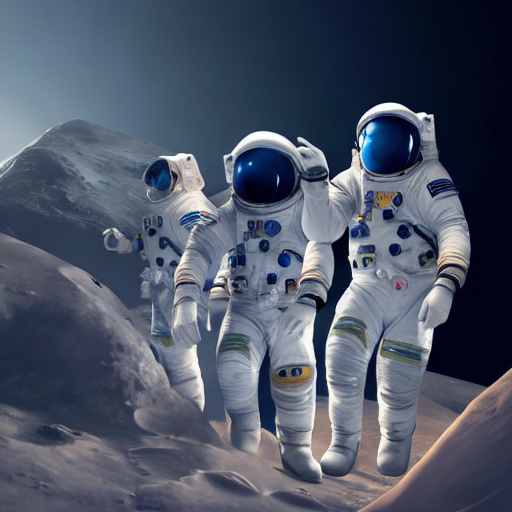
يسمح لكِ بسلسلة خط أنابيب من النص إلى الصورة وخط أنابيب من الصورة إلى الصورة بتوليد صورة من النص واستخدام الصورة المولّدة كصورة أولية لخط أنابيب من الصورة إلى الصورة. يكون هذا مفيدًا إذا كنت ترغب في توليد صورة من الصفر تمامًا. على سبيل المثال، لنسلسل نموذج Stable Diffusion ونموذج Kandinsky.
ابدأ بتوليد صورة باستخدام خط أنابيب النص إلى صورة:
from diffusers import AutoPipelineForText2Image, AutoPipelineForImage2Image
import torch
from diffusers.utils import make_image_grid

pipeline = AutoPipelineForText2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

text2image = pipeline("Astronaut in a jungle, cold color palette, muted colors, detailed, 8k").images[0]
text2image
الآن يمكنك تمرير هذه الصورة المولّدة إلى خط أنابيب الصورة إلى الصورة:
pipeline = AutoPipelineForImage2Image.from_pretrained(
    "kandinsky-community/kandinsky-2-2-decoder", dtype=torch.float16, use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

image2image = pipeline("Astronaut in a jungle, cold color palette, muted colors, detailed, 8k", image=text2image).images[0]
make_image_grid([text2image, image2image], rows=1, cols=2)
صورة إلى صورة إلى صورة
يمكنك أيضًا ربط خطوط أنابيب متعددة من صورة إلى صورة معًا لإنشاء صور أكثر إثارة للاهتمام. وقد يكون ذلك مفيدًا لأداء نقل الأسلوب على صورة بشكل تكراري، أو توليد مقاطع GIF قصيرة، أو استعادة اللون لصورة، أو استعادة المناطق المفقودة من صورة.
ابدأ بتوليد صورة:
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image = pipeline(prompt, image=init_image, output_type="latent").images[0]
من المهم تحديد
output_type="latent"في خط الأنابيب للحفاظ على جميع المخرجات في الفضاء الكامن وتجنب خطوة فك الترميز ثم الترميز غير الضرورية. يعمل هذا فقط إذا كانت خطوط الأنابيب المتسلسلة تستخدم نفس نموذج VAE.
مرّر المخرجات الكامنة من خط الأنابيب هذا إلى خط الأنابيب التالي لتوليد صورة بأسلوب فن الكتب المصورة:
pipeline = AutoPipelineForImage2Image.from_pretrained(
    "ogkalu/Comic-Diffusion", dtype=torch.float16
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# need to include the token "charliebo artstyle" in the prompt to use this checkpoint
image = pipeline("Astronaut in a jungle, charliebo artstyle", image=image, output_type="latent").images[0]
كرر مرة أخرى لتوليد الصورة النهائية بأسلوب فن البكسل:
pipeline = AutoPipelineForImage2Image.from_pretrained(
    "kohbanye/pixel-art-style", dtype=torch.float16
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# need to include the token "pixelartstyle" in the prompt to use this checkpoint
image = pipeline("Astronaut in a jungle, pixelartstyle", image=image).images[0]
make_image_grid([init_image, image], rows=1, cols=2)
من صورة إلى مُكبِّر إلى دقة فائقة
طريقة أخرى يمكنك بها ربط خط أنابيب تحويل الصورة إلى صورة هي استخدام خط أنابيب للتكبير ودقة فائقة لزيادة مستوى التفاصيل في الصورة بشكل كبير.
ابدأ بخط أنابيب من صورة إلى صورة:
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import make_image_grid, load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)

prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
image_1 = pipeline(prompt, image=init_image, output_type="latent").images[0]
من المهم تحديد
output_type="latent"في خط الأنابيب للحفاظ على جميع المخرجات في فضاء latent لتجنب خطوة فك الترميز والترميز غير الضرورية. يعمل هذا فقط إذا كانت خطوط الأنابيب المتسلسلة تستخدم نفس VAE.
اربطه بخط أنابيب لتحسين الدقة لزيادة دقة الصورة:
from diffusers import StableDiffusionLatentUpscalePipeline

upscaler = StableDiffusionLatentUpscalePipeline.from_pretrained(
    "stabilityai/sd-x2-latent-upscaler", dtype=torch.float16, use_safetensors=True
)
upscaler.enable_model_cpu_offload()
upscaler.enable_xformers_memory_efficient_attention()

image_2 = upscaler(prompt, image=image_1).images[0]
أخيرًا، اربطه بخط أنابيب فائق الدقة لتعزيز الدقة بشكل أكبر:
from diffusers import StableDiffusionUpscalePipeline

super_res = StableDiffusionUpscalePipeline.from_pretrained(
    "stabilityai/stable-diffusion-x4-upscaler", dtype=torch.float16, variant="fp16", use_safetensors=True
)
super_res.enable_model_cpu_offload()
super_res.enable_xformers_memory_efficient_attention()

image_3 = super_res(prompt, image=image_2).images[0]
make_image_grid([init_image, image_3.resize((512, 512))], rows=1, cols=2)
التحكم في توليد الصور
قد يكون من الصعب توليد صورة تبدو تمامًا كما تريد، ولهذا السبب تكون تقنيات النماذج التوليدية الخاضعة للتحكم مفيدة للغاية. فبينما يمكنك استخدام negative_prompt للتحكم جزئيًا في توليد الصور، توجد طرق أكثر متانة مثل وزن الأوامر النصية وControlNets.
وزن الأوامر
تتيح لك أوزان الأوامر (Prompt weighting) ضبط تمثيل كل مفهوم في الأمر. على سبيل المثال، في أمر مثل “Astronaut in a jungle, cold color palette, muted colors, detailed, 8k”, يمكنك اختيار زيادة أو تقليل التضمينات (embeddings) الخاصة بـ “astronaut” و “jungle”. يوفر مكتبة Compel صياغة بسيطة لضبط أوزان الأوامر وتوليد التضمينات. يمكنك معرفة كيفية إنشاء التضمينات في دليل Prompt weighting.
يحتوي AutoPipelineForImage2Image على معامل prompt_embeds (وnegative_prompt_embeds إذا كنت تستخدم موجهًا سلبيًا) حيث يمكنك تمرير التضمينات التي تحل محل معامل prompt.
from diffusers import AutoPipelineForImage2Image
import torch

pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

image = pipeline(prompt_embeds=prompt_embeds, # generated from Compel
    negative_prompt_embeds=negative_prompt_embeds, # generated from Compel
    image=init_image,
).images[0]
ControlNet
توفر ControlNets طريقةً أكثر مرونة ودقةً للتحكم في توليد الصور، إذ يمكنك استخدام صورة شرطية إضافية. يمكن أن تكون الصورة الشرطية صورة canny، أو خريطة عمق، أو تقسيم صورة، وحتى خربشات! مهما كان نوع الصورة الشرطية الذي تختاره، فإن ControlNet يولّد صورةً تحافظ على المعلومات الواردة فيها.
على سبيل المثال، لنشرط صورة بخريطة عمق للحفاظ على المعلومات المكانية في الصورة.
from diffusers.utils import load_image, make_image_grid

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)
init_image = init_image.resize((958, 960)) # resize to depth image dimensions
depth_image = load_image("https://huggingface.co/lllyasviel/control_v11f1p_sd15_depth/resolve/main/images/control.png")
make_image_grid([init_image, depth_image], rows=1, cols=2)
حمّل نموذج ControlNet مشروطًا بخرائط العمق وAutoPipelineForImage2Image:
from diffusers import ControlNetModel, AutoPipelineForImage2Image
import torch

controlnet = ControlNetModel.from_pretrained("lllyasviel/control_v11f1p_sd15_depth", dtype=torch.float16, variant="fp16", use_safetensors=True)
pipeline = AutoPipelineForImage2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5", controlnet=controlnet, dtype=torch.float16, variant="fp16", use_safetensors=True
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()
الآن، أنشئ صورة جديدة مشروطة على خريطة العمق والصورة الأولية والأمر النصي:
prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"
image_control_net = pipeline(prompt, image=init_image, control_image=depth_image).images[0]
make_image_grid([init_image, depth_image, image_control_net], rows=1, cols=3) 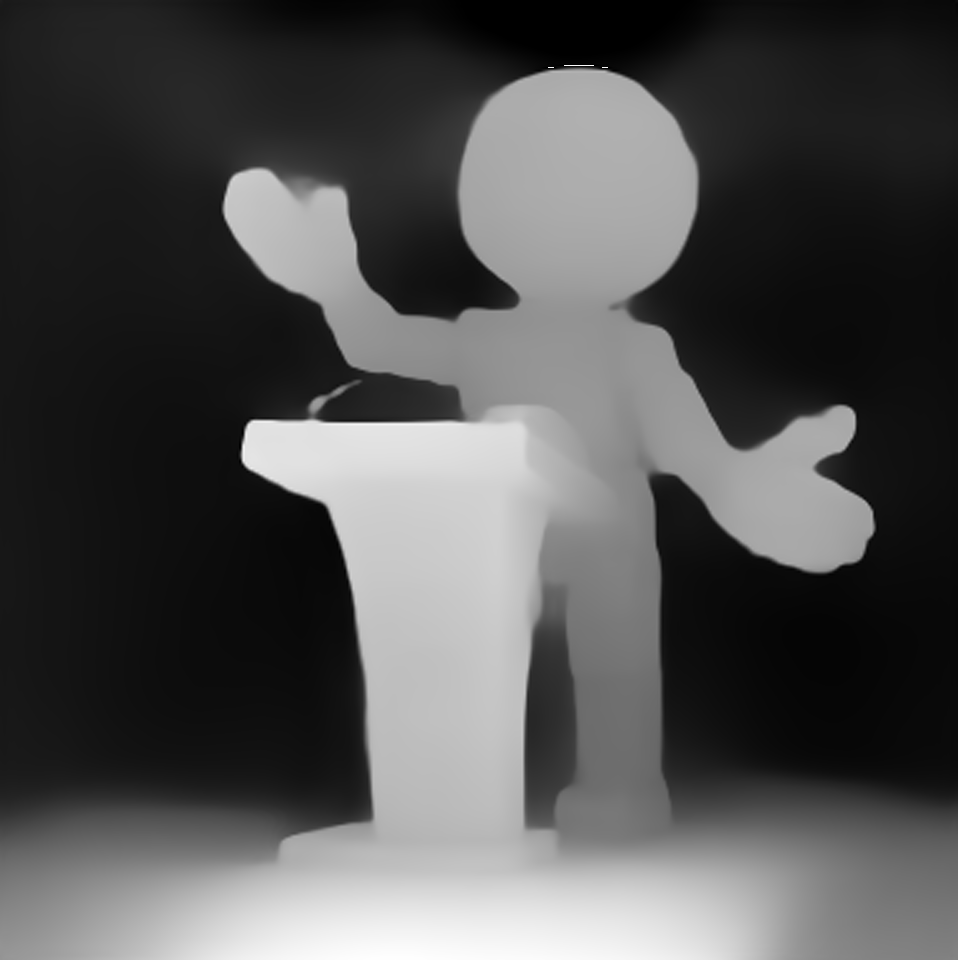
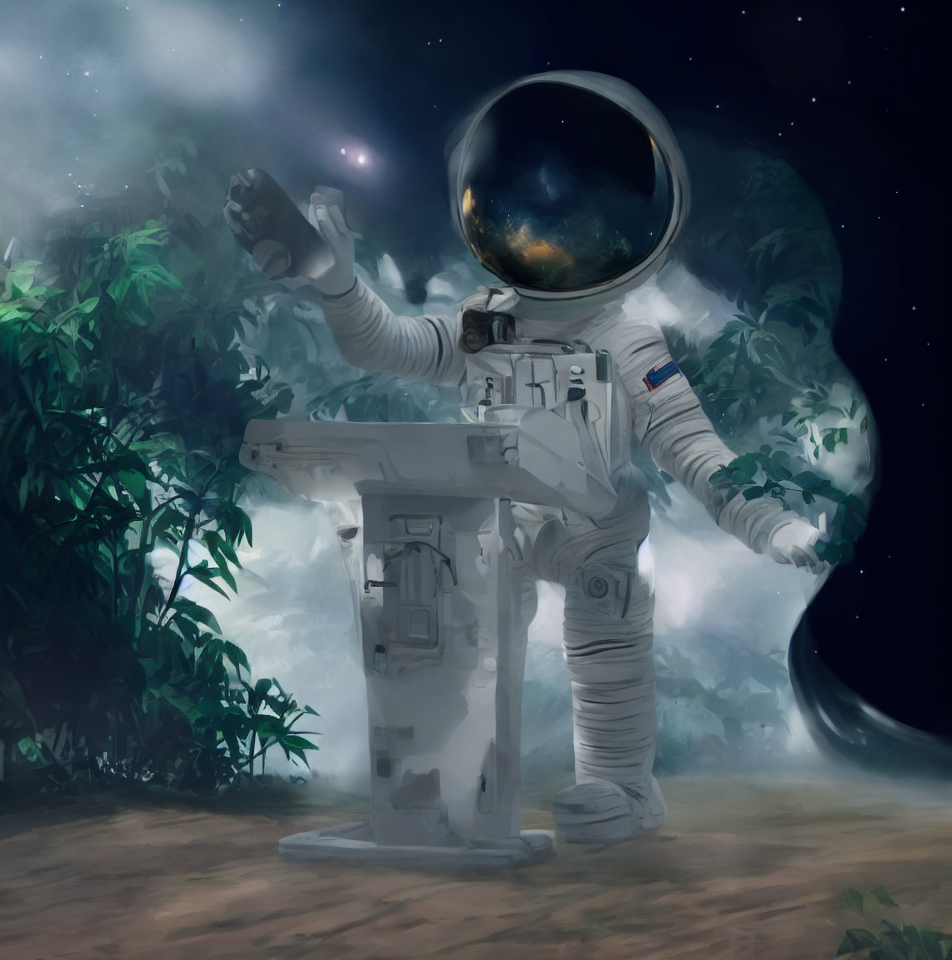
لنطبّق أسلوبًا جديدًا على الصورة المولّدة من ControlNet عن طريق ربطها بخط أنابيب من صورة إلى صورة:
pipeline = AutoPipelineForImage2Image.from_pretrained(
    "nitrosocke/elden-ring-diffusion", dtype=torch.float16,
)
pipeline.enable_model_cpu_offload()
# remove following line if xFormers is not installed or you have PyTorch 2.0 or higher installed
pipeline.enable_xformers_memory_efficient_attention()

prompt = "elden ring style astronaut in a jungle" # include the token "elden ring style" in the prompt
negative_prompt = "ugly, deformed, disfigured, poor details, bad anatomy"

image_elden_ring = pipeline(prompt, negative_prompt=negative_prompt, image=image_control_net, strength=0.45, guidance_scale=10.5).images[0]
make_image_grid([init_image, depth_image, image_control_net, image_elden_ring], rows=2, cols=2)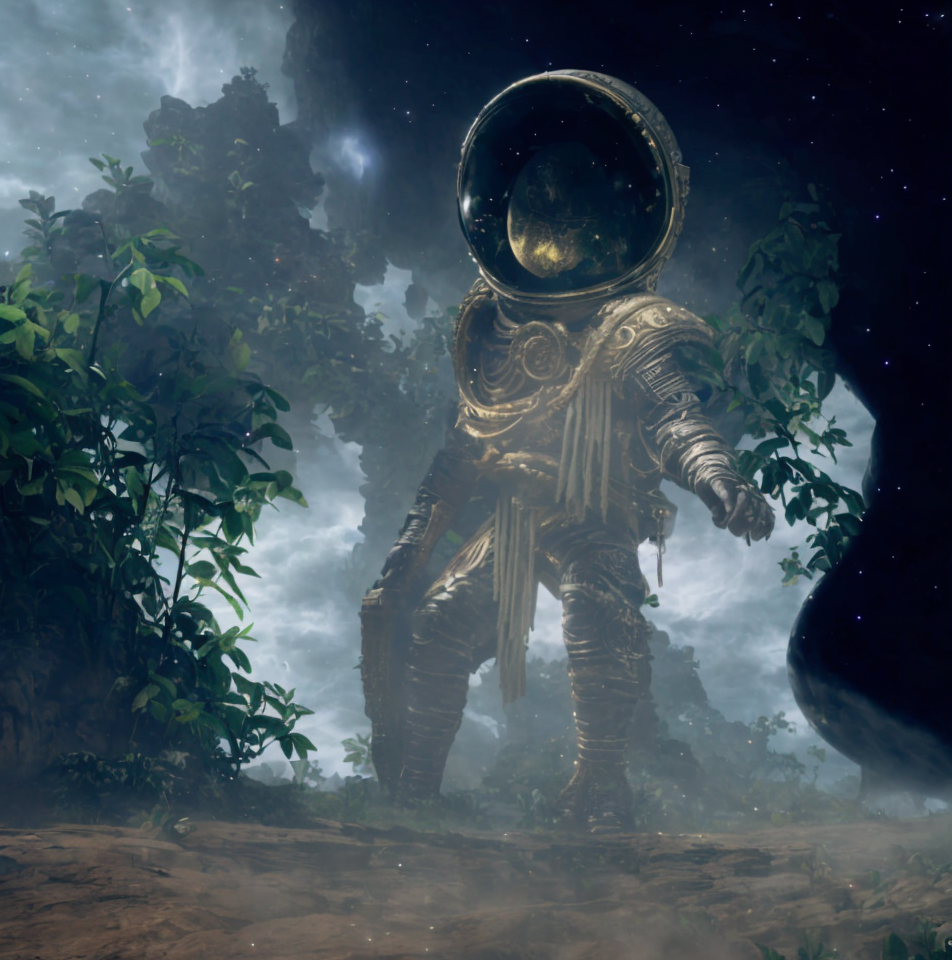
تحسين
تشغيل نماذج الانتشار مكلف ومكثف من الناحية الحسابية، ولكن باستخدام بعض حيل التحسين، من الممكن تمامًا تشغيلها على وحدات معالجة الرسوميات المخصصة للمستهلكين وعلى الطبقة المجانية. على سبيل المثال، يمكنك استخدام شكل أكثر كفاءة في استخدام الذاكرة للانتباه مثل scaled-dot product attention في PyTorch 2.0 أو xFormers (يمكنك استخدام أحدهما أو الآخر، لكن لا حاجة لاستخدام الاثنين معًا). كما يمكنك نقل النموذج إلى وحدة معالجة الرسوميات بينما تنتظر مكونات خط الأنابيب الأخرى على وحدة المعالجة المركزية.
+ pipeline.enable_model_cpu_offload()
+ pipeline.enable_xformers_memory_efficient_attention()
باستخدام torch.compile، يمكنك زيادة سرعة الاستدلال بشكل أكبر عن طريق تغليف UNet الخاص بك به:
pipeline.unet = torch.compile(pipeline.unet, mode="reduce-overhead", fullgraph=True)للمزيد من التفاصيل، راجع أدلة تقليل استهلاك الذاكرة وتسريع الاستدلال.
Update on GitHub