
Diffusers documentation
Stable Video Diffusion
Stable Video Diffusion
Stable Video Diffusion 由 Andreas Blattmann、Tim Dockhorn、Sumith Kulal、Daniel Mendelevitch、Maciej Kilian、Dominik Lorenz、Yam Levi、Zion English、Vikram Voleti、Adam Letts、Varun Jampani 和 Robin Rombach 在 Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets 中提出。
该论文的摘要如下:
我们提出了 Stable Video Diffusion——一种用于高分辨率、最先进的文本到视频和图像到视频生成的潜在视频扩散模型。近期,为 2D 图像合成训练的潜在扩散模型通过插入时间层并在小型高质量视频数据集上进行微调,被转化为生成式视频模型。然而,文献中的训练方法差异很大,该领域尚未就视频数据整理的统一策略达成共识。在本文中,我们识别并评估了成功训练视频 LDM 的三个不同阶段:文本到图像预训练、视频预训练以及高质量视频微调。此外,我们证明了精心整理的预训练数据集对于生成高质量视频的必要性,并提出了一个系统化的整理流程来训练强大的基础模型,包括字幕生成和过滤策略。然后,我们探讨了在高质量数据上微调基础模型的影响,并训练了一个与闭源视频生成具有竞争力的文本到视频模型。我们还表明,我们的基础模型为图像到视频生成等下游任务提供了强大的运动表示,并且能够适应针对特定相机运动的 LoRA 模块。最后,我们证明我们的模型提供了强大的多视角 3D 先验,可以作为基础来微调一个多视角扩散模型,该模型以前馈方式联合生成物体的多个视角,在计算预算仅为基于图像方法的一小部分的情况下,性能优于这些方法。我们在此 https URL 发布了代码和模型权重。
请前往 Stability AI Hub 组织,查看 base 和 extended frame 检查点!
请确保已安装以下库。
# Uncomment to install the necessary libraries in Colab
!pip install -q -U diffusers transformers accelerate该模型有两个变体:SVD 和 SVD-XT。SVD 检查点经过训练以生成 14 帧,而 SVD-XT 检查点在此基础上进一步微调,以生成 25 帧。
在本指南中,您将使用 SVD-XT 检查点。
import torch

from diffusers import StableVideoDiffusionPipeline
from diffusers.utils import load_image, export_to_video

pipe = StableVideoDiffusionPipeline.from_pretrained(
    "stabilityai/stable-video-diffusion-img2vid-xt", dtype=torch.float16, variant="fp16"
)
pipe.enable_model_cpu_offload()

# Load the conditioning image
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/svd/rocket.png")
image = image.resize((1024, 576))

generator = torch.manual_seed(42)
frames = pipe(image, decode_chunk_size=8, generator=generator).frames[0]

export_to_video(frames, "generated.mp4", fps=7)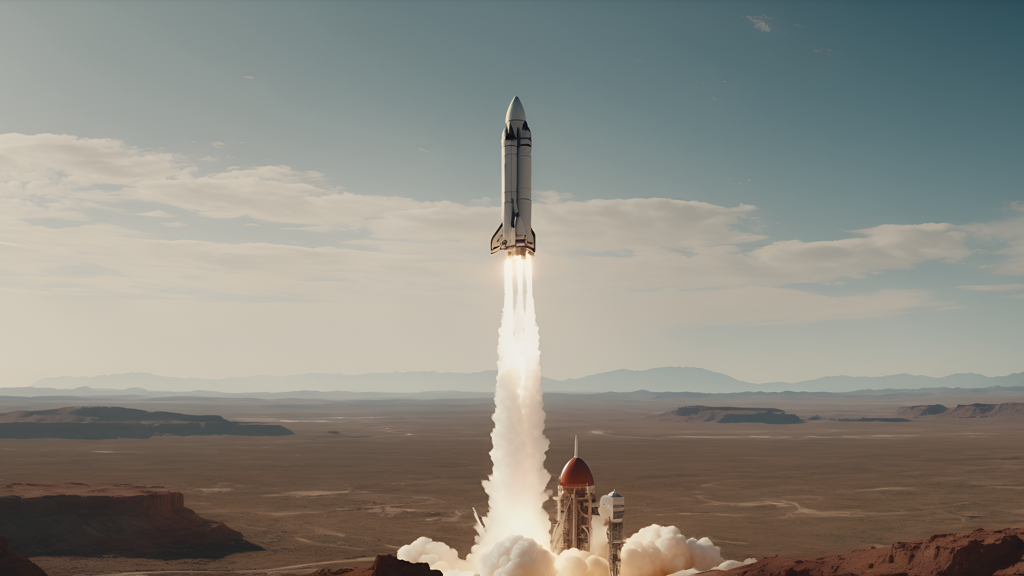
torch.compile
通过编译 UNet,你可以获得 20-25% 的速度提升,代价是内存占用略有增加。
- pipe.enable_model_cpu_offload()
+ pipe.to("cuda")  # or "mps", "xpu", "cpu"
+ pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
减少内存使用
视频生成对内存的需求非常高,因为本质上是一次性生成 num_frames 帧,类似于使用大批量大小进行文本到图像生成。为了降低内存需求,有多种选项可以在推理速度和更低的内存需求之间进行权衡:
- 启用模型卸载:当流水线中的某个组件不再需要时,将其卸载到 CPU。
- 启用前馈分块:前馈层通过循环执行,而不是以巨大的批量大小运行单次前馈。
- 减小
decode_chunk_size:VAE 会分块解码帧,而不是一次性解码所有帧。将decode_chunk_size=1设置为 1 可逐帧解码,内存占用最少(建议根据 GPU 显存调整此值),但视频可能会出现闪烁。
- pipe.enable_model_cpu_offload()
- frames = pipe(image, decode_chunk_size=8, generator=generator).frames[0]
+ pipe.enable_model_cpu_offload()
+ pipe.unet.enable_forward_chunking()
+ frames = pipe(image, decode_chunk_size=2, generator=generator, num_frames=25).frames[0]
将这些技巧结合使用,应将显存需求降低到 8GB 以下。
微条件
除了条件图像外,Stable Diffusion Video 还支持微条件输入(micro-conditioning),从而允许对生成的视频进行更精细的控制:
fps:生成视频的每秒帧数。motion_bucket_id:用于生成视频的运动桶 ID。可用于控制生成视频的运动幅度。增大运动桶 ID 会增加生成视频的运动幅度。noise_aug_strength:添加到条件图像中的噪声量。该值越高,生成的视频与条件图像的差异越大。提高此值还会增加生成视频的运动幅度。
例如,要生成运动幅度更大的视频,请使用 motion_bucket_id 和 noise_aug_strength 微条件参数:
import torch

from diffusers import StableVideoDiffusionPipeline
from diffusers.utils import load_image, export_to_video

pipe = StableVideoDiffusionPipeline.from_pretrained(
  "stabilityai/stable-video-diffusion-img2vid-xt", dtype=torch.float16, variant="fp16"
)
pipe.enable_model_cpu_offload()

# Load the conditioning image
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/svd/rocket.png")
image = image.resize((1024, 576))

generator = torch.manual_seed(42)
frames = pipe(image, decode_chunk_size=8, generator=generator, motion_bucket_id=180, noise_aug_strength=0.1).frames[0]
export_to_video(frames, "generated.mp4", fps=7)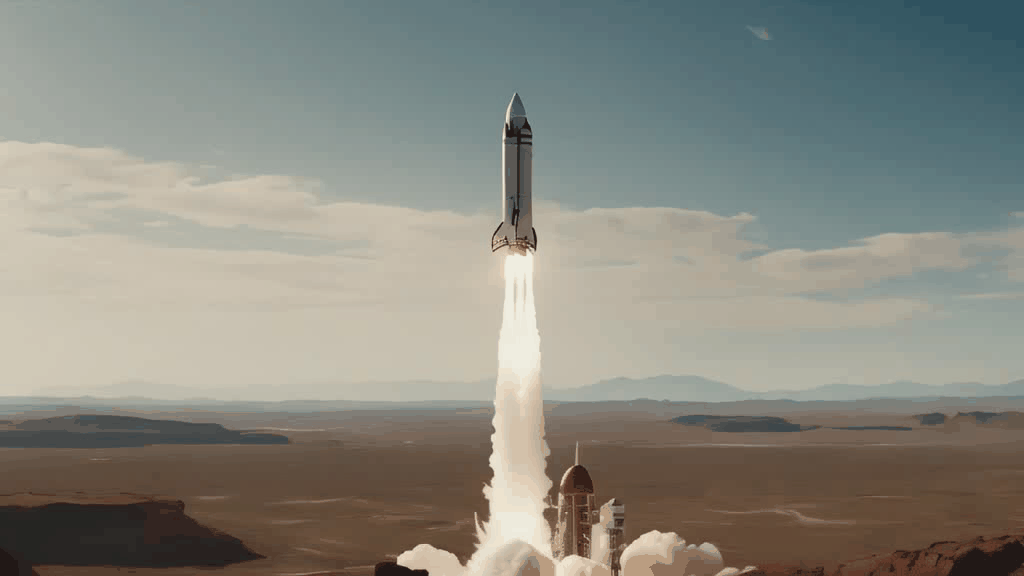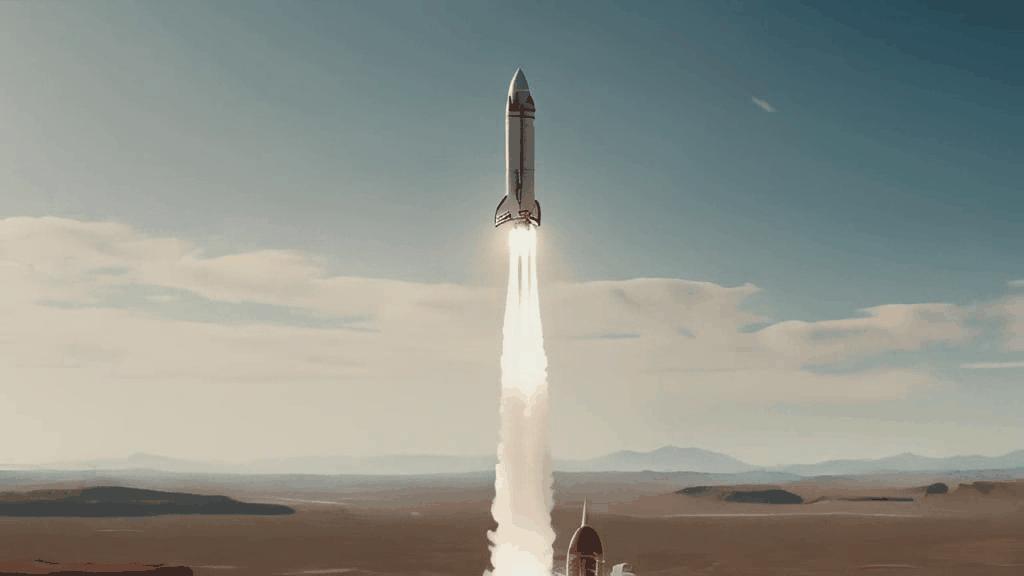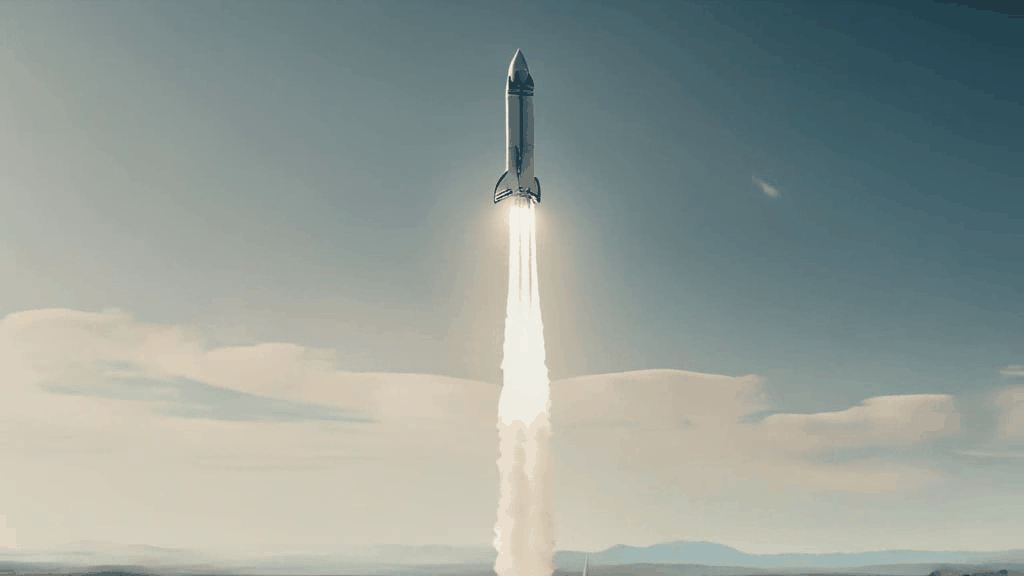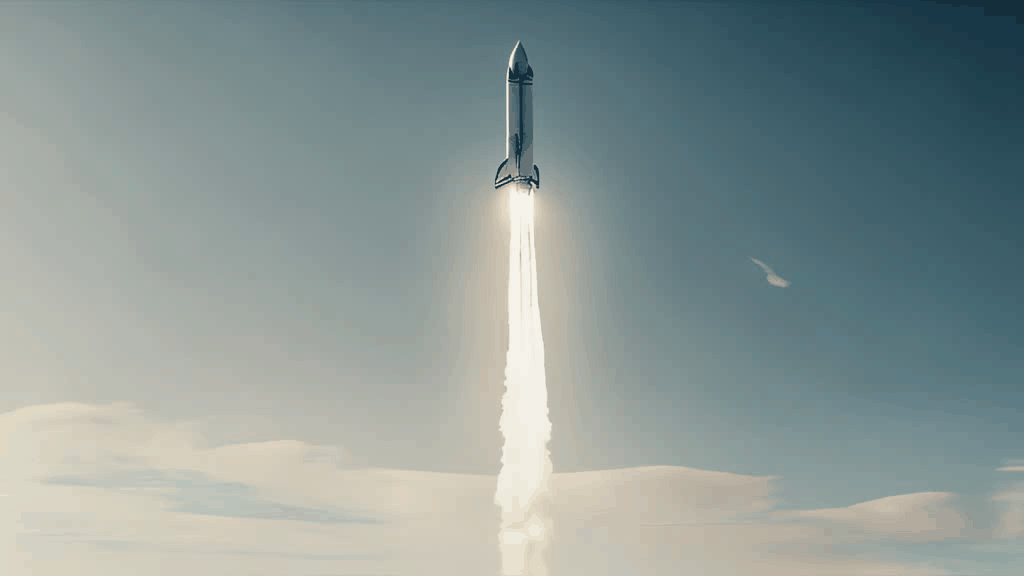
StableVideoDiffusionPipeline
类 diffusers.StableVideoDiffusionPipeline
< source >( vae: AutoencoderKLTemporalDecoderimage_encoder: CLIPVisionModelWithProjectionunet: UNetSpatioTemporalConditionModelscheduler: EulerDiscreteSchedulerfeature_extractor: CLIPImageProcessorPil )
参数
- vae (
AutoencoderKLTemporalDecoder) — 变分自编码器(VAE)模型,用于将图像编码为潜在表示,以及从潜在表示解码为图像。 - image_encoder (CLIPVisionModelWithProjection) — 冻结的 CLIP 图像编码器 (laion/CLIP-ViT-H-14-laion2B-s32B-b79K)。
- unet (
UNetSpatioTemporalConditionModel) — 用于对编码后的图像潜变量进行去噪的UNetSpatioTemporalConditionModel。 - scheduler(EulerDiscreteScheduler)——
用于与
unet配合,对编码后的图像潜变量进行去噪的调度器。 - feature_extractor (CLIPImageProcessor) —
用于从生成图像中提取特征的
CLIPImageProcessor。
使用 Stable Video Diffusion 从输入图像生成视频的 Pipeline。
该模型继承自 DiffusionPipeline。有关为所有 pipeline 实现的通用方法(下载、保存、在特定设备上运行等),请参阅父类文档。
StableVideoDiffusionPipelineOutput
class diffusers.pipelines.stable_video_diffusion.StableVideoDiffusionPipelineOutput
< source >( frames: typing.Union[list[list[PIL.Image.Image]], numpy.ndarray, torch.Tensor] )
Stable Video Diffusion 管道的输出类。