
Diffusers documentation
训练扩散模型
训练扩散模型
无条件图像生成是扩散模型的一个热门应用,它能够生成与训练数据集中图像风格相似的图片。通常,在特定数据集上微调预训练模型可以获得最佳效果。你可以在 Hub 上找到许多此类检查点,但如果你找不到满意的,也可以随时训练自己的模型!
本教程将教你如何从零开始,在 Smithsonian Butterflies 数据集的一个子集上训练 UNet2DModel,以生成你自己的 🦋 蝴蝶 🦋。
💡 本训练教程基于 Training with 🧨 Diffusers 笔记本。如需了解扩散模型(例如其工作原理)的更多细节和背景信息,请查阅该笔记本!
在开始之前,请确保已安装 🤗 Datasets 以加载和预处理图像数据集,并安装 🤗 Accelerate 以简化在任意数量 GPU 上的训练。以下命令还会安装 TensorBoard 用于可视化训练指标(你也可以使用 Weights & Biases 来跟踪训练过程)。
# uncomment to install the necessary libraries in Colab
#!pip install diffusers[training]
我们鼓励您与社区分享您的模型。为此,您需要登录您的 Hugging Face 账户(如果您还没有账户,可以在此创建一个!)。您可以从 notebook 中登录,并在提示时输入您的 token。请确保您的 token 具有写入权限。
>>> from huggingface_hub import notebook_login

>>> notebook_login()
或者从终端登录:
hf auth login
由于模型检查点文件较大,请安装 Git-LFS 来对这些大文件进行版本管理:
!sudo apt -qq install git-lfs
!git config --global credential.helper store
训练配置
为了方便起见,创建一个包含训练超参数的 TrainingConfig 类(您可以自由调整这些参数):
>>> from dataclasses import dataclass

>>> @dataclass
... class TrainingConfig:
...     image_size = 128  # the generated image resolution
...     train_batch_size = 16
...     eval_batch_size = 16  # how many images to sample during evaluation
...     num_epochs = 50
...     gradient_accumulation_steps = 1
...     learning_rate = 1e-4
...     lr_warmup_steps = 500
...     save_image_epochs = 10
...     save_model_epochs = 30
...     mixed_precision = "fp16"  # `no` for float32, `fp16` for automatic mixed precision
...     output_dir = "ddpm-butterflies-128"  # the model name locally and on the HF Hub

...     push_to_hub = True  # whether to upload the saved model to the HF Hub
...     hub_model_id = "<your-username>/<my-awesome-model>"  # the name of the repository to create on the HF Hub
...     hub_private_repo = None
...     overwrite_output_dir = True  # overwrite the old model when re-running the notebook
...     seed = 0


>>> config = TrainingConfig()
加载数据集
您可以轻松使用 🤗 Datasets 库加载 Smithsonian Butterflies 数据集:
>>> from datasets import load_dataset

>>> config.dataset_name = "huggan/smithsonian_butterflies_subset"
>>> dataset = load_dataset(config.dataset_name, split="train")
💡 你可以在 HugGan Community Event 中找到更多数据集,也可以通过创建本地
ImageFolder来使用自己的数据集。如果数据集来自 HugGan Community Event,请将config.dataset_name设置为该数据集的仓库 id;如果你使用的是自己的图像,则将其设置为imagefolder。
🤗 Datasets 使用 Image 功能自动解码图像数据,并将其加载为 PIL.Image,以便我们进行可视化:
>>> import matplotlib.pyplot as plt

>>> fig, axs = plt.subplots(1, 4, figsize=(16, 4))
>>> for i, image in enumerate(dataset[:4]["image"]):
...     axs[i].imshow(image)
...     axs[i].set_axis_off()
>>> fig.show()
不过,这些图像的尺寸各不相同,因此您需要先对其进行预处理:
Resize会将图像尺寸更改为config.image_size中定义的尺寸。RandomHorizontalFlip通过随机镜像图像来增强数据集。Normalize很重要,它可以将像素值重新缩放到 [-1, 1] 范围内,这正是模型所期望的。
>>> from torchvision import transforms

>>> preprocess = transforms.Compose(
...     [
...         transforms.Resize((config.image_size, config.image_size)),
...         transforms.RandomHorizontalFlip(),
...         transforms.ToTensor(),
...         transforms.Normalize([0.5], [0.5]),
...     ]
... )
使用 🤗 Datasets 的 set_transform 方法,在训练过程中即时应用 preprocess 函数:
>>> def transform(examples):
...     images = [preprocess(image.convert("RGB")) for image in examples["image"]]
...     return {"images": images}


>>> dataset.set_transform(transform)
您可以再次可视化这些图像,以确认它们已被调整大小。现在,您可以将数据集包装在 DataLoader 中用于训练了!
>>> import torch

>>> train_dataloader = torch.utils.data.DataLoader(dataset, batch_size=config.train_batch_size, shuffle=True)
创建 UNet2DModel
🧨 Diffusers 中的预训练模型可以轻松地通过其模型类以及所需的参数来创建。例如,要创建一个 UNet2DModel:
>>> from diffusers import UNet2DModel

>>> model = UNet2DModel(
...     sample_size=config.image_size,  # the target image resolution
...     in_channels=3,  # the number of input channels, 3 for RGB images
...     out_channels=3,  # the number of output channels
...     layers_per_block=2,  # how many ResNet layers to use per UNet block
...     block_out_channels=(128, 128, 256, 256, 512, 512),  # the number of output channels for each UNet block
...     down_block_types=(
...         "DownBlock2D",  # a regular ResNet downsampling block
...         "DownBlock2D",
...         "DownBlock2D",
...         "DownBlock2D",
...         "AttnDownBlock2D",  # a ResNet downsampling block with spatial self-attention
...         "DownBlock2D",
...     ),
...     up_block_types=(
...         "UpBlock2D",  # a regular ResNet upsampling block
...         "AttnUpBlock2D",  # a ResNet upsampling block with spatial self-attention
...         "UpBlock2D",
...         "UpBlock2D",
...         "UpBlock2D",
...         "UpBlock2D",
...     ),
... )
通常,快速检查样本图像的形状是否与模型输出的形状匹配是一个好主意:
>>> sample_image = dataset[0]["images"].unsqueeze(0)
>>> print("Input shape:", sample_image.shape)
Input shape: torch.Size([1, 3, 128, 128])

>>> print("Output shape:", model(sample_image, timestep=0).sample.shape)
Output shape: torch.Size([1, 3, 128, 128])
很好!接下来,你需要一个调度器(scheduler)来为图像添加一些噪声。
创建调度器
调度器的行为取决于你是将模型用于训练还是推理。在推理阶段,调度器从噪声生成图像。在训练阶段,调度器会获取扩散过程中特定时间点的模型输出(或样本),并根据噪声调度和更新规则对图像施加噪声。
让我们来看看 DDPMScheduler,并使用 add_noise 方法为之前的 sample_image 添加一些随机噪声:
>>> import torch
>>> from PIL import Image
>>> from diffusers import DDPMScheduler

>>> noise_scheduler = DDPMScheduler(num_train_timesteps=1000)
>>> noise = torch.randn(sample_image.shape)
>>> timesteps = torch.LongTensor([50])
>>> noisy_image = noise_scheduler.add_noise(sample_image, noise, timesteps)

>>> Image.fromarray(((noisy_image.permute(0, 2, 3, 1) + 1.0) * 127.5).type(torch.uint8).numpy()[0])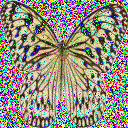
该模型的训练目标是预测添加到图像中的噪声。此步骤的损失可通过以下公式计算:
>>> import torch.nn.functional as F

>>> noise_pred = model(noisy_image, timesteps).sample
>>> loss = F.mse_loss(noise_pred, noise)
训练模型
到目前为止,你已经掌握了开始训练模型所需的大部分组件,剩下的就是将它们整合在一起。
首先,你需要一个优化器和学习率调度器:
>>> from diffusers.optimization import get_cosine_schedule_with_warmup

>>> optimizer = torch.optim.AdamW(model.parameters(), lr=config.learning_rate)
>>> lr_scheduler = get_cosine_schedule_with_warmup(
...     optimizer=optimizer,
...     num_warmup_steps=config.lr_warmup_steps,
...     num_training_steps=(len(train_dataloader) * config.num_epochs),
... )
然后,你需要一种方式来评估模型。对于评估,你可以使用 DDPMPipeline 生成一批样本图像并将其保存为网格:
>>> from diffusers import DDPMPipeline
>>> from diffusers.utils import make_image_grid
>>> import os

>>> def evaluate(config, epoch, pipeline):
...     # Sample some images from random noise (this is the backward diffusion process).
...     # The default pipeline output type is `List[PIL.Image]`
...     images = pipeline(
...         batch_size=config.eval_batch_size,
...         generator=torch.Generator(device='cpu').manual_seed(config.seed), # Use a separate torch generator to avoid rewinding the random state of the main training loop
...     ).images

...     # Make a grid out of the images
...     image_grid = make_image_grid(images, rows=4, cols=4)

...     # Save the images
...     test_dir = os.path.join(config.output_dir, "samples")
...     os.makedirs(test_dir, exist_ok=True)
...     image_grid.save(f"{test_dir}/{epoch:04d}.png")
现在,你可以使用 🤗 Accelerate 将这些组件整合到一个训练循环中,以便轻松实现 TensorBoard 日志记录、梯度累积和混合精度训练。要将模型上传到 Hub,请编写一个函数以获取你的仓库名称和信息,然后将其推送到 Hub。
💡 下面的训练循环可能看起来有些复杂且冗长,但当你之后只需一行代码就能启动训练时,你会发现这一切都是值得的!如果你迫不及待想要开始生成图像,可以直接复制并运行下面的代码。你随时可以稍后再回来仔细研究训练循环,比如在你等待模型完成训练的时候。🤗
>>> from accelerate import Accelerator
>>> from huggingface_hub import create_repo, upload_folder
>>> from tqdm.auto import tqdm
>>> from pathlib import Path
>>> import os

>>> def train_loop(config, model, noise_scheduler, optimizer, train_dataloader, lr_scheduler):
...     # Initialize accelerator and tensorboard logging
...     accelerator = Accelerator(
...         mixed_precision=config.mixed_precision,
...         gradient_accumulation_steps=config.gradient_accumulation_steps,
...         log_with="tensorboard",
...         project_dir=os.path.join(config.output_dir, "logs"),
...     )
...     if accelerator.is_main_process:
...         if config.output_dir is not None:
...             os.makedirs(config.output_dir, exist_ok=True)
...         if config.push_to_hub:
...             repo_id = create_repo(
...                 repo_id=config.hub_model_id or Path(config.output_dir).name, exist_ok=True
...             ).repo_id
...         accelerator.init_trackers("train_example")

...     # Prepare everything
...     # There is no specific order to remember, you just need to unpack the
...     # objects in the same order you gave them to the prepare method.
...     model, optimizer, train_dataloader, lr_scheduler = accelerator.prepare(
...         model, optimizer, train_dataloader, lr_scheduler
...     )

...     global_step = 0

...     # Now you train the model
...     for epoch in range(config.num_epochs):
...         progress_bar = tqdm(total=len(train_dataloader), disable=not accelerator.is_local_main_process)
...         progress_bar.set_description(f"Epoch {epoch}")

...         for step, batch in enumerate(train_dataloader):
...             clean_images = batch["images"]
...             # Sample noise to add to the images
...             noise = torch.randn(clean_images.shape, device=clean_images.device)
...             bs = clean_images.shape[0]

...             # Sample a random timestep for each image
...             timesteps = torch.randint(
...                 0, noise_scheduler.config.num_train_timesteps, (bs,), device=clean_images.device,
...                 dtype=torch.int64
...             )

...             # Add noise to the clean images according to the noise magnitude at each timestep
...             # (this is the forward diffusion process)
...             noisy_images = noise_scheduler.add_noise(clean_images, noise, timesteps)

...             with accelerator.accumulate(model):
...                 # Predict the noise residual
...                 noise_pred = model(noisy_images, timesteps, return_dict=False)[0]
...                 loss = F.mse_loss(noise_pred, noise)
...                 accelerator.backward(loss)

...                 if accelerator.sync_gradients:
...                     accelerator.clip_grad_norm_(model.parameters(), 1.0)
...                 optimizer.step()
...                 lr_scheduler.step()
...                 optimizer.zero_grad()

...             progress_bar.update(1)
...             logs = {"loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0], "step": global_step}
...             progress_bar.set_postfix(**logs)
...             accelerator.log(logs, step=global_step)
...             global_step += 1

...         # After each epoch you optionally sample some demo images with evaluate() and save the model
...         if accelerator.is_main_process:
...             pipeline = DDPMPipeline(unet=accelerator.unwrap_model(model), scheduler=noise_scheduler)

...             if (epoch + 1) % config.save_image_epochs == 0 or epoch == config.num_epochs - 1:
...                 evaluate(config, epoch, pipeline)

...             if (epoch + 1) % config.save_model_epochs == 0 or epoch == config.num_epochs - 1:
...                 if config.push_to_hub:
...                     upload_folder(
...                         repo_id=repo_id,
...                         folder_path=config.output_dir,
...                         commit_message=f"Epoch {epoch}",
...                         ignore_patterns=["step_*", "epoch_*"],
...                     )
...                 else:
...                     pipeline.save_pretrained(config.output_dir)
呼,代码量确实不少!不过现在你终于可以使用 🤗 Accelerate 的 notebook_launcher 函数来启动训练了。请将训练循环、所有训练参数以及用于训练的处理进程数(你可以将此值更改为你可用的 GPU 数量)作为参数传入该函数:
>>> from accelerate import notebook_launcher

>>> args = (config, model, noise_scheduler, optimizer, train_dataloader, lr_scheduler)

>>> notebook_launcher(train_loop, args, num_processes=1)
训练完成后,看看你的扩散模型生成的最终 🦋 图像 🦋 吧!
>>> import glob

>>> sample_images = sorted(glob.glob(f"{config.output_dir}/samples/*.png"))
>>> Image.open(sample_images[-1])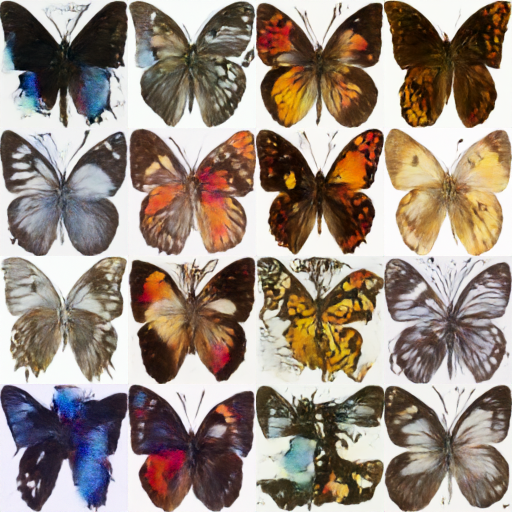
后续步骤
无条件图像生成是可以训练的任务之一。您可以访问 🧨 Diffusers 训练示例 页面来探索其他任务和训练技术。以下是一些您可以学习的内容示例:
- Textual Inversion,一种用于让模型学习特定视觉概念并将其融入生成图像的算法。
- DreamBooth,一种在给定主体若干输入图像的情况下,生成该主体个性化图像的技术。
- 微调 Stable Diffusion 模型的指南,使用您自己的数据集。
- 使用 LoRA 的指南,这是一种内存高效的微调技术,可加速对超大模型的微调。