

Multimodal Flow: Unified Flow Modeling of Language and Vision in Embedding Spaces
Paper • 2609.40362 • Published
Unified Flow Modeling of Language and Vision in Embedding Spaces
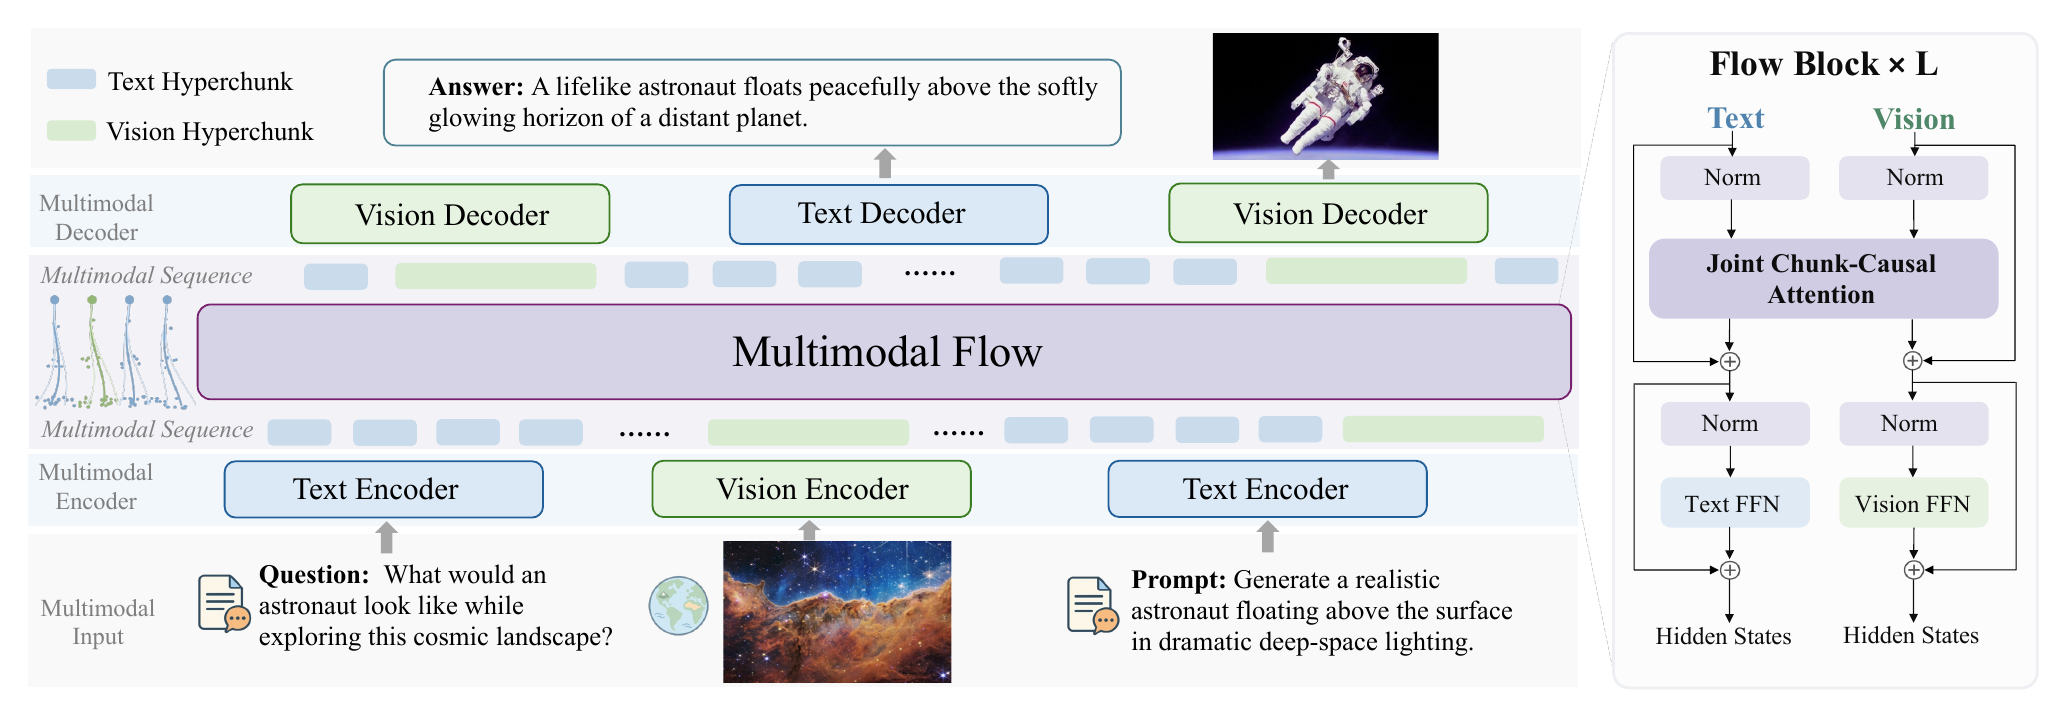
Multimodal Flow (MF) is a fully continuous framework for multimodal understanding and generation. Language and vision remain continuous states, organized as ordered hyperchunks in a shared causal stream. The same model interface supports text continuation, image understanding, and image generation.
Hongyuan Tao, Xinggang Wang, Lianghui Zhu, Yongkang Li, Yunchao Wei, Bin Feng, Shaoyu Chen, Qian Zhang, Chang Huang, and Kai Yu.
Huazhong University of Science and Technology · Beijing Jiaotong University · Horizon Robotics
| Path | Description |
|---|---|
MF/pretrain |
1.6B pretraining model |
MF/sft |
1.6B supervised fine-tuned model |
Text Decoder/ |
Shared BF16 text decoder |
Vision statistics/ |
Shared FP32 vision normalization statistics |
The model weights are BF16. The release contains inference weights and configuration only; training states and optimizer states are not included.
Use the models with the open-source code:
# Text continuation
mf infer --checkpoint ./MF/pretrain text \
  --prompt "A short language model can"

# Image understanding
mf infer --checkpoint ./MF/sft caption \
  --image /path/to/image.jpg \
  --prompt "Describe this image."

# Text-to-image generation
mf infer --checkpoint ./MF/sft image \
  --prompt "A quiet observatory above the clouds." \
  --output outputs/sample.png
Text inference uses the model package directly. Image understanding and image
generation additionally require the compatible Scale RAE decoder assets; set
MF_ASSETS_ROOT to a directory containing scale_rae_decoder/.
MIT License. Please also review the licenses of external encoder, tokenizer, and decoder assets used with the models.
@article{tao2026multimodalflow,
  title={Multimodal Flow: Unified Flow Modeling of Language and Vision in Embedding Spaces},
  author={Tao, Hongyuan and Wang, Xinggang and Zhu, Lianghui and Li, Yongkang and Wei, Yunchao and Feng, Bin and Chen, Shaoyu and Zhang, Qian and Huang, Chang and Yu, Kai},
  journal={arXiv preprint arXiv:2609.40362},
  year={2026},
  url={https://arxiv.org/abs/2609.40362}
}