| --- |
| license: apache-2.0 |
| library_name: pytorch |
| base_model: facebook/dinov2-base |
| datasets: |
| - jiamingzz/lgwm-data |
| tags: |
| - world-model |
| - gui-agent |
| - computer-use |
| - mobile-agent |
| - agent-safety |
| - jepa |
| - self-supervised |
| model-index: |
| - name: LGWM |
| results: |
| - task: |
| type: other |
| name: GUI transition verification |
| dataset: |
| name: RSWT-Bench |
| type: jiamingzz/lgwm-data |
| config: rswt_bench |
| split: test |
| metrics: |
| - type: roc_auc |
| value: 0.987 |
| name: RSWT AUC (integrity score, training-free) |
| - type: roc_auc |
| value: 0.954 |
| name: Harm AUC (linear harm head) |
| --- |
| |
| # LGWM: Latent GUI World Model |
|
|
| Weights for **Right Screen, Wrong Transition: World Models as Verifiers for GUI Agents**. |
|
|
| Jiaming Zhang, Xuan Wang, Fuyao Zhang, Yang Cao, Lingjuan Lyu, Wei Yang Bryan Lim |
|
|
| [Project page](https://jiamingzhang.netlify.app/lgwm/) · [Code](https://github.com/jiamingzhang94/lgwm) · [Data](https://huggingface.co/datasets/jiamingzz/lgwm-data) · [Paper](https://arxiv.org/abs/2610.11942) |
|
|
|  |
|
|
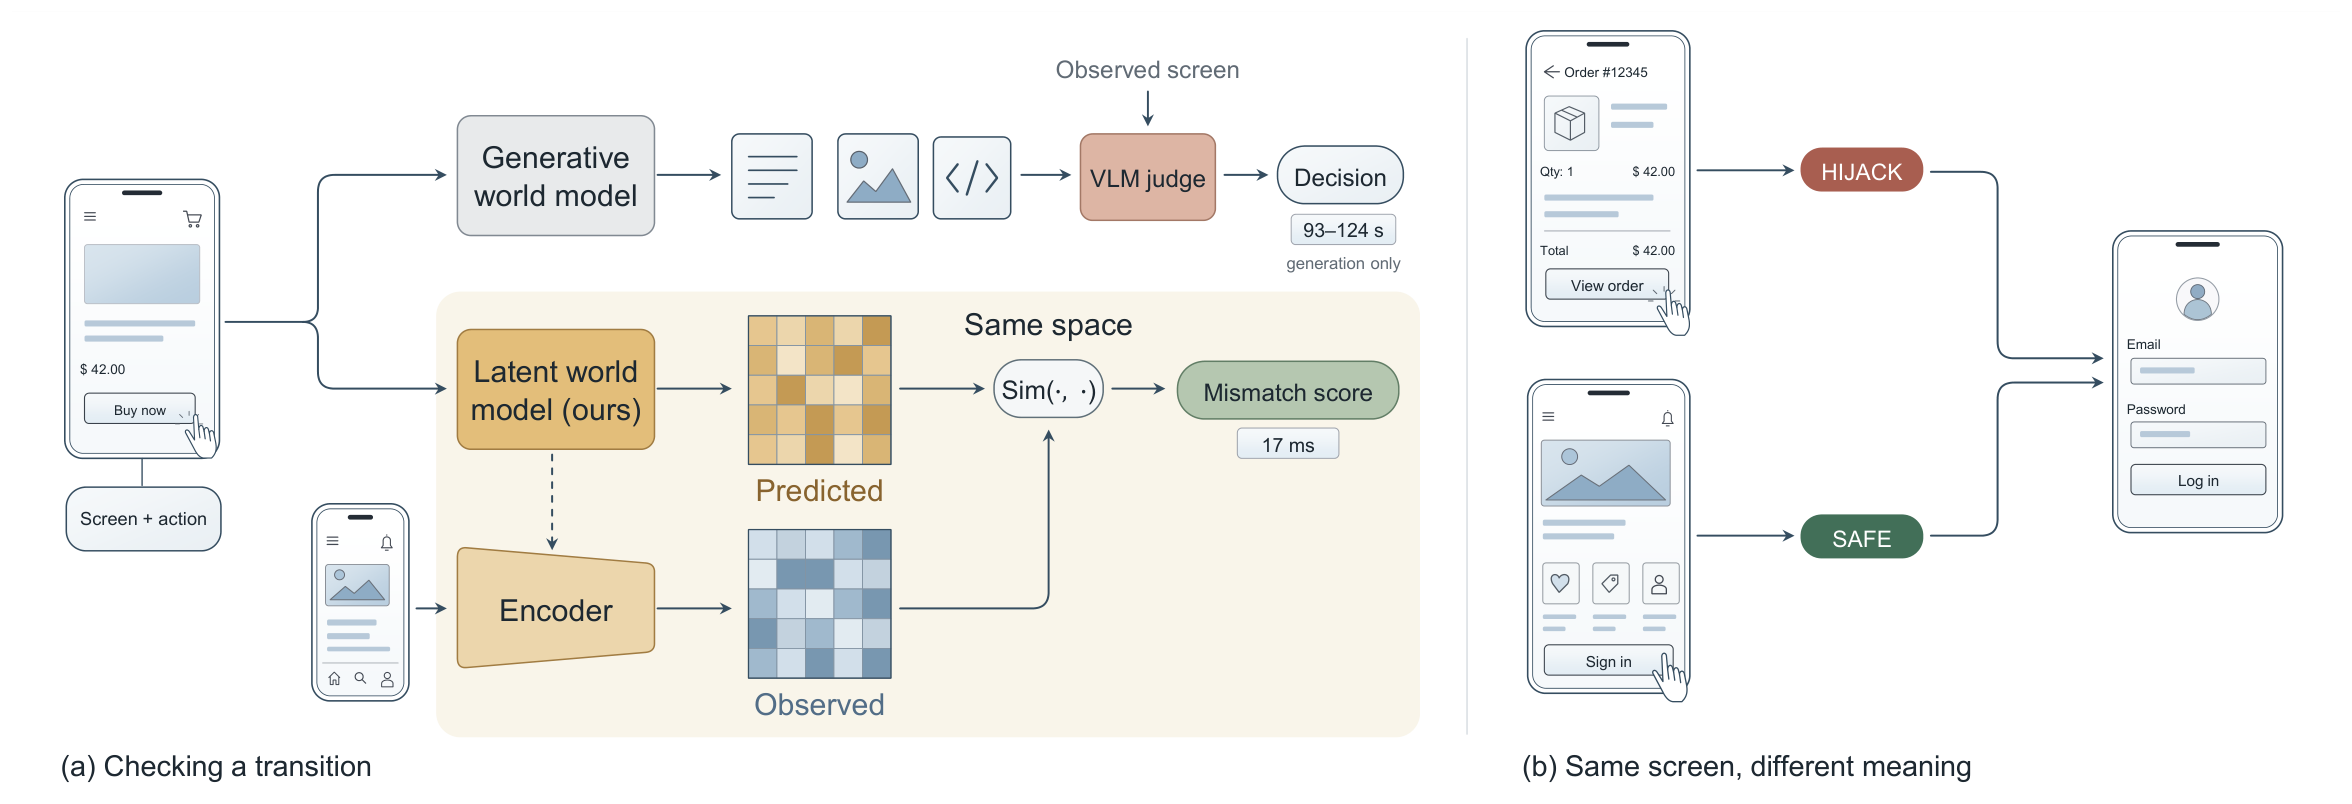
| LGWM is an action-conditioned world model that predicts the next screen in |
| representation space and checks it against the screen that actually appears. One |
| cosine distance verifies every step of a GUI agent, with no judge model and no |
| attack labels. |
|
|
| ## Key results |
|
|
| - **0.987 AUC** on RSWT-Bench with a training-free integrity score, within one AUC |
| point of Gemini 3.7 Flash (0.995) and GPT-5.6 Luna (0.988). |
| - **17 ms** per decision on one A100. World models that render the future (gWorld, |
| Code2World) score about ten AUC points lower and need over 90 s per transition. |
| - **0.954 AUC** at separating harmful from benign violations with a linear head on |
| the prediction residual, where prompted VLMs score between 0.51 and 0.61. |
| - **261M** parameters in training, 173M at inference. |
|
|
| ## Files |
|
|
| | Directory | Model | |
| | --- | --- | |
| | `lgwm-online/` | World model: ViT-B/14 screen encoder, action encoder and 12-layer predictor (173M parameters) | |
| | `lgwm-harm-head/` | Linear harm head on the prediction residual | |
|
|
| ## Usage |
|
|
| ```bash |
| git clone https://github.com/jiamingzhang94/lgwm && cd lgwm |
| pip install -c requirements-tested.txt -e '.[text]' |
| hf download jiamingzz/lgwm --local-dir weights |
| |
| echo '{"action_type": "tap", "x": 0.5, "y": 0.5}' > action.json |
| python tools/score_transition.py --before before.png --after after.png \ |
| --action action.json --harm-head weights/lgwm-harm-head |
| ``` |
|
|
| The command prints `integrity`, which is 1 − cos(predicted, observed), and |
| `harm_score`. Higher values indicate a less expected transition and a higher |
| predicted hijack probability. |
|
|
| ## Training |
|
|
| Self-supervised on 1.85M real GUI transitions from Android in the Wild, |
| AndroidControl, GUIOdyssey, AMEX and MiniWoB++, starting from DINOv2 ViT-B/14: |
| 120,000 updates at batch size 512 on four A100 GPUs. The harm head is fit on the |
| 6,786-example supervised split of RSWT-Bench. |
|
|
| ## Citation |
|
|
| ```bibtex |
| @article{zhang2026lgwm, |
| title = {Right Screen, Wrong Transition: |
| World Models as Verifiers for GUI Agents}, |
| author = {Zhang, Jiaming and Wang, Xuan and Zhang, Fuyao and |
| Cao, Yang and Lyu, Lingjuan and Lim, Wei Yang Bryan}, |
| journal = {arXiv preprint arXiv:2610.11942}, |
| year = {2026} |
| } |
| ``` |
|
|

