| --- |
| pipeline_tag: image-text-to-text |
| datasets: |
| - laiyingxin/TouchReason |
| tags: |
| - tactile-reasoning |
| - multimodal |
| - physical-reasoning |
| - reinforcement-learning |
| - robotics |
| - arxiv:2605.27154 |
| --- |
| |
| # Touch-R1 |
|
|
| ### Reinforcing Touch Reasoning in MLLMs |
|
|
| [Paper](https://arxiv.org/abs/2605.27154) · [Project Page](https://laiyingxin2.github.io/Touch-R1/) · [GitHub](https://github.com/laiyingxin2/Touch-R1) · [TouchReason Dataset](https://huggingface.co/datasets/laiyingxin/TouchReason) |
|
|
| **Touch-R1 brings explicit reasoning to physical contact.** It connects optical tactile observations with vision and language, enabling multimodal models to use contact evidence when judging physical properties and revising misleading visual impressions. |
|
|
| > **Release status:** Model card available. Model weights and verified inference instructions are coming soon. The GitHub repository currently hosts the project website; research code is forthcoming. |
|
|
|  |
|
|
| ## Model Summary |
|
|
| | Item | Description | |
| | :--- | :--- | |
| | Model type | Tactile reasoning multimodal large language model | |
| | Backbone reported in the paper | Qwen2.5-VL-7B | |
| | Research data | TouchReason-1M and TouchReason-Bench | |
| | Inputs | Optical tactile observations, visual context, and language questions | |
| | Outputs | Structured textual reasoning and physical-property judgments | |
|
|
| ## Approach |
|
|
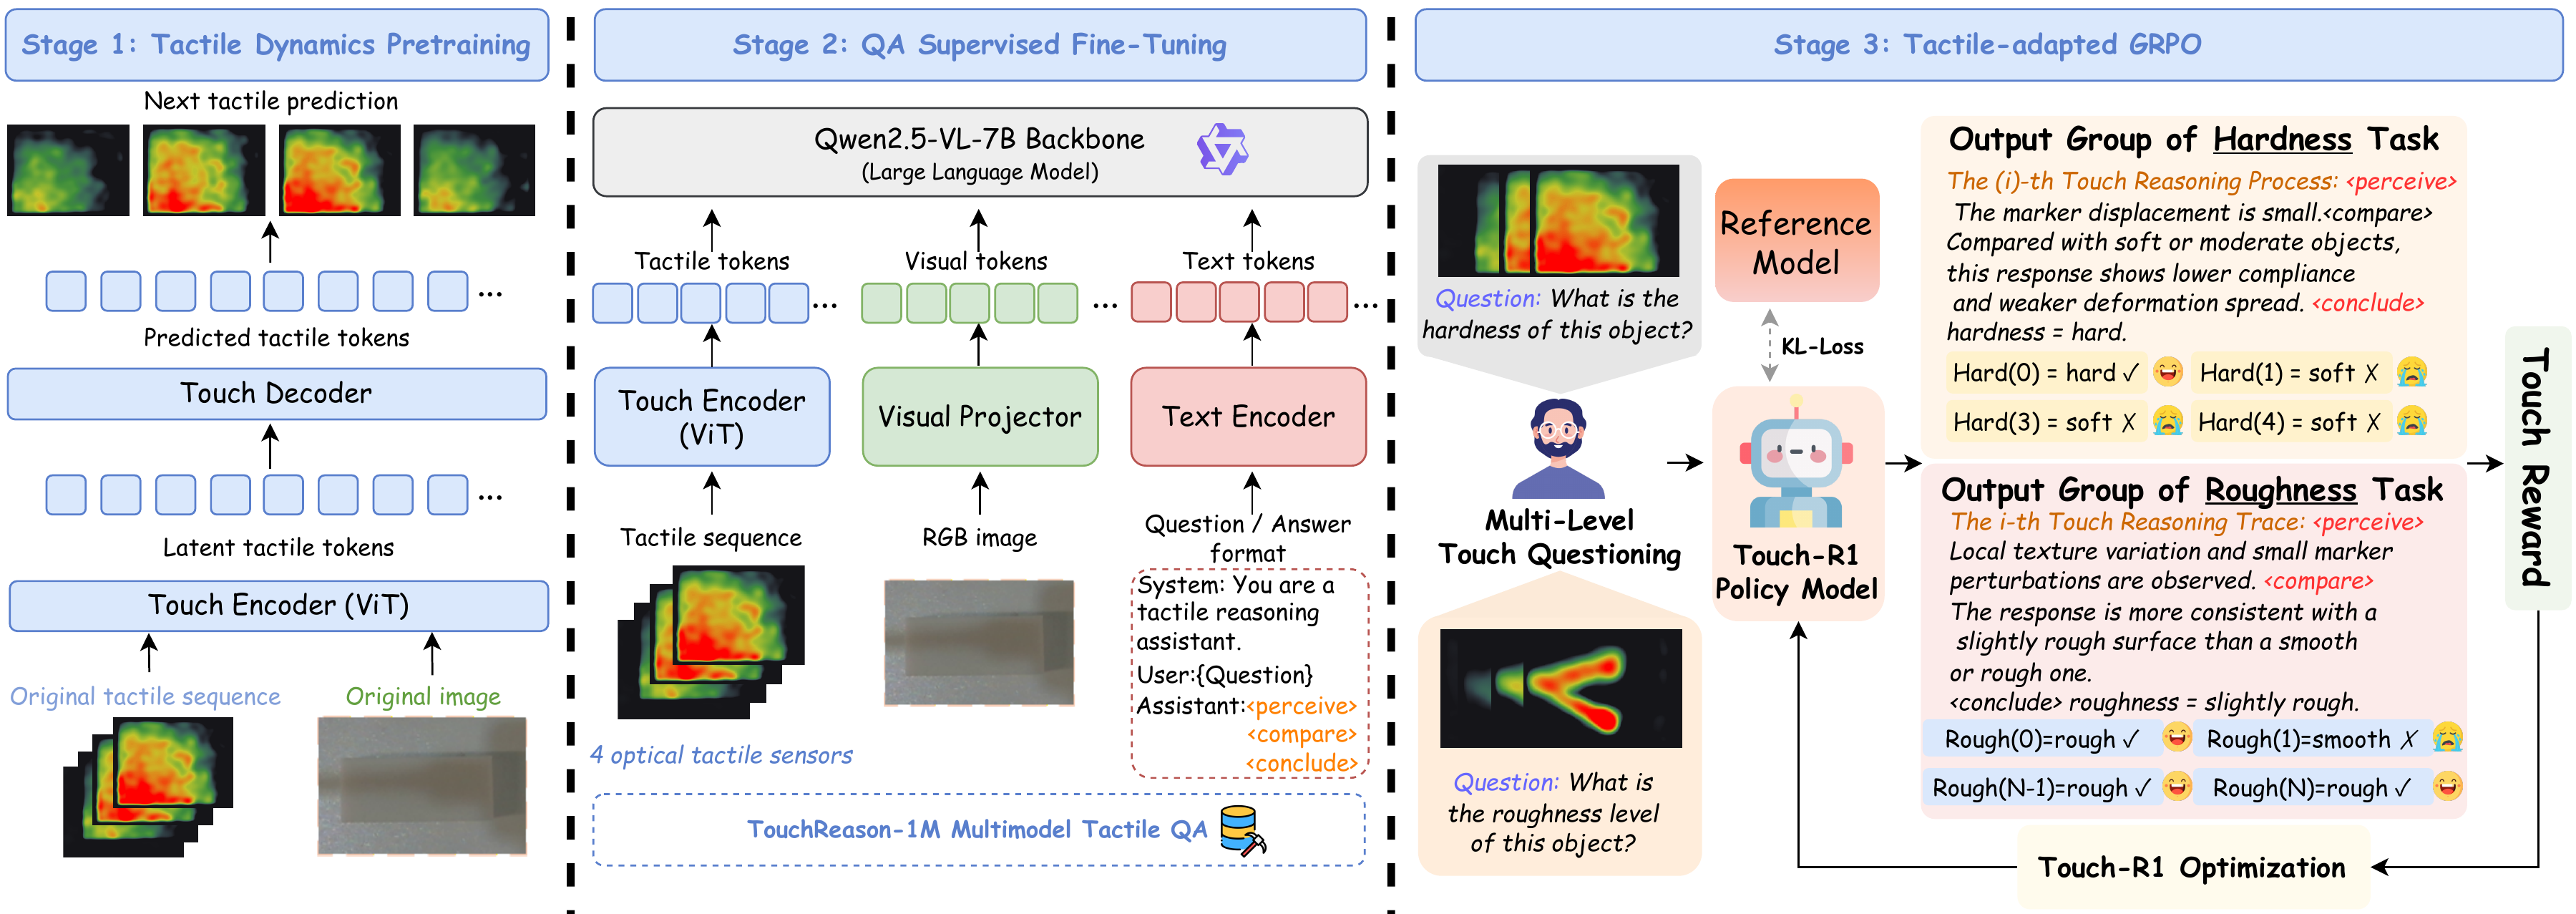
| The training pipeline combines three stages: |
|
|
| 1. **Tactile dynamics pretraining** learns contact-sensitive representations by predicting future tactile tokens. |
| 2. **QA supervised fine-tuning** aligns touch, vision, and language with structured reasoning. |
| 3. **Tactile-grounded GRPO** combines ordinal-aware accuracy, cross-sensor physical consistency, and structured-format rewards with an input-side tactile grounding objective. |
|
|
| Responses organize evidence through `<perceive>`, `<compare>`, and `<conclude>` stages. Counterfactual tactile inputs—removed, shuffled, or noise-masked—help identify predictions that depend on genuine contact evidence. |
|
|
| ## Research Use |
|
|
| Touch-R1 is designed for physical-property inference, ordinal comparison, cross-sensor reasoning, and visual–tactile conflict resolution. Its intended interface is tactile/visual question answering with structured textual judgments. |
|
|
| The paper reports a **60.1 average score** for Touch-R1-7B on TouchReason-Bench. See the [paper](https://arxiv.org/abs/2605.27154) for the evaluation protocol and complete results. |
|
|
| ## Related Resources |
|
|
| - **Dataset:** [TouchReason](https://huggingface.co/datasets/laiyingxin/TouchReason) |
| - **Project page:** [Method, acquisition videos, and object atlas](https://laiyingxin2.github.io/Touch-R1/) |
| - **Project repository:** [Touch-R1](https://github.com/laiyingxin2/Touch-R1) |
|
|
| ## Citation |
|
|
| ```bibtex |
| @misc{lai2026touchr1reinforcingtouchreasoning, |
| title = {{Touch-R1}: Reinforcing Touch Reasoning in {MLLMs}}, |
| author = {Yingxin Lai and Yafei Zhou and Fucai Zhu and Siyu Zhu and Weihao Yuan}, |
| year = {2026}, |
| eprint = {2605.27154}, |
| archivePrefix = {arXiv}, |
| primaryClass = {cs.CV}, |
| url = {https://arxiv.org/abs/2605.27154} |
| } |
| ``` |
|
|

