

han2ids v0.2
Read an ideographic description sequence
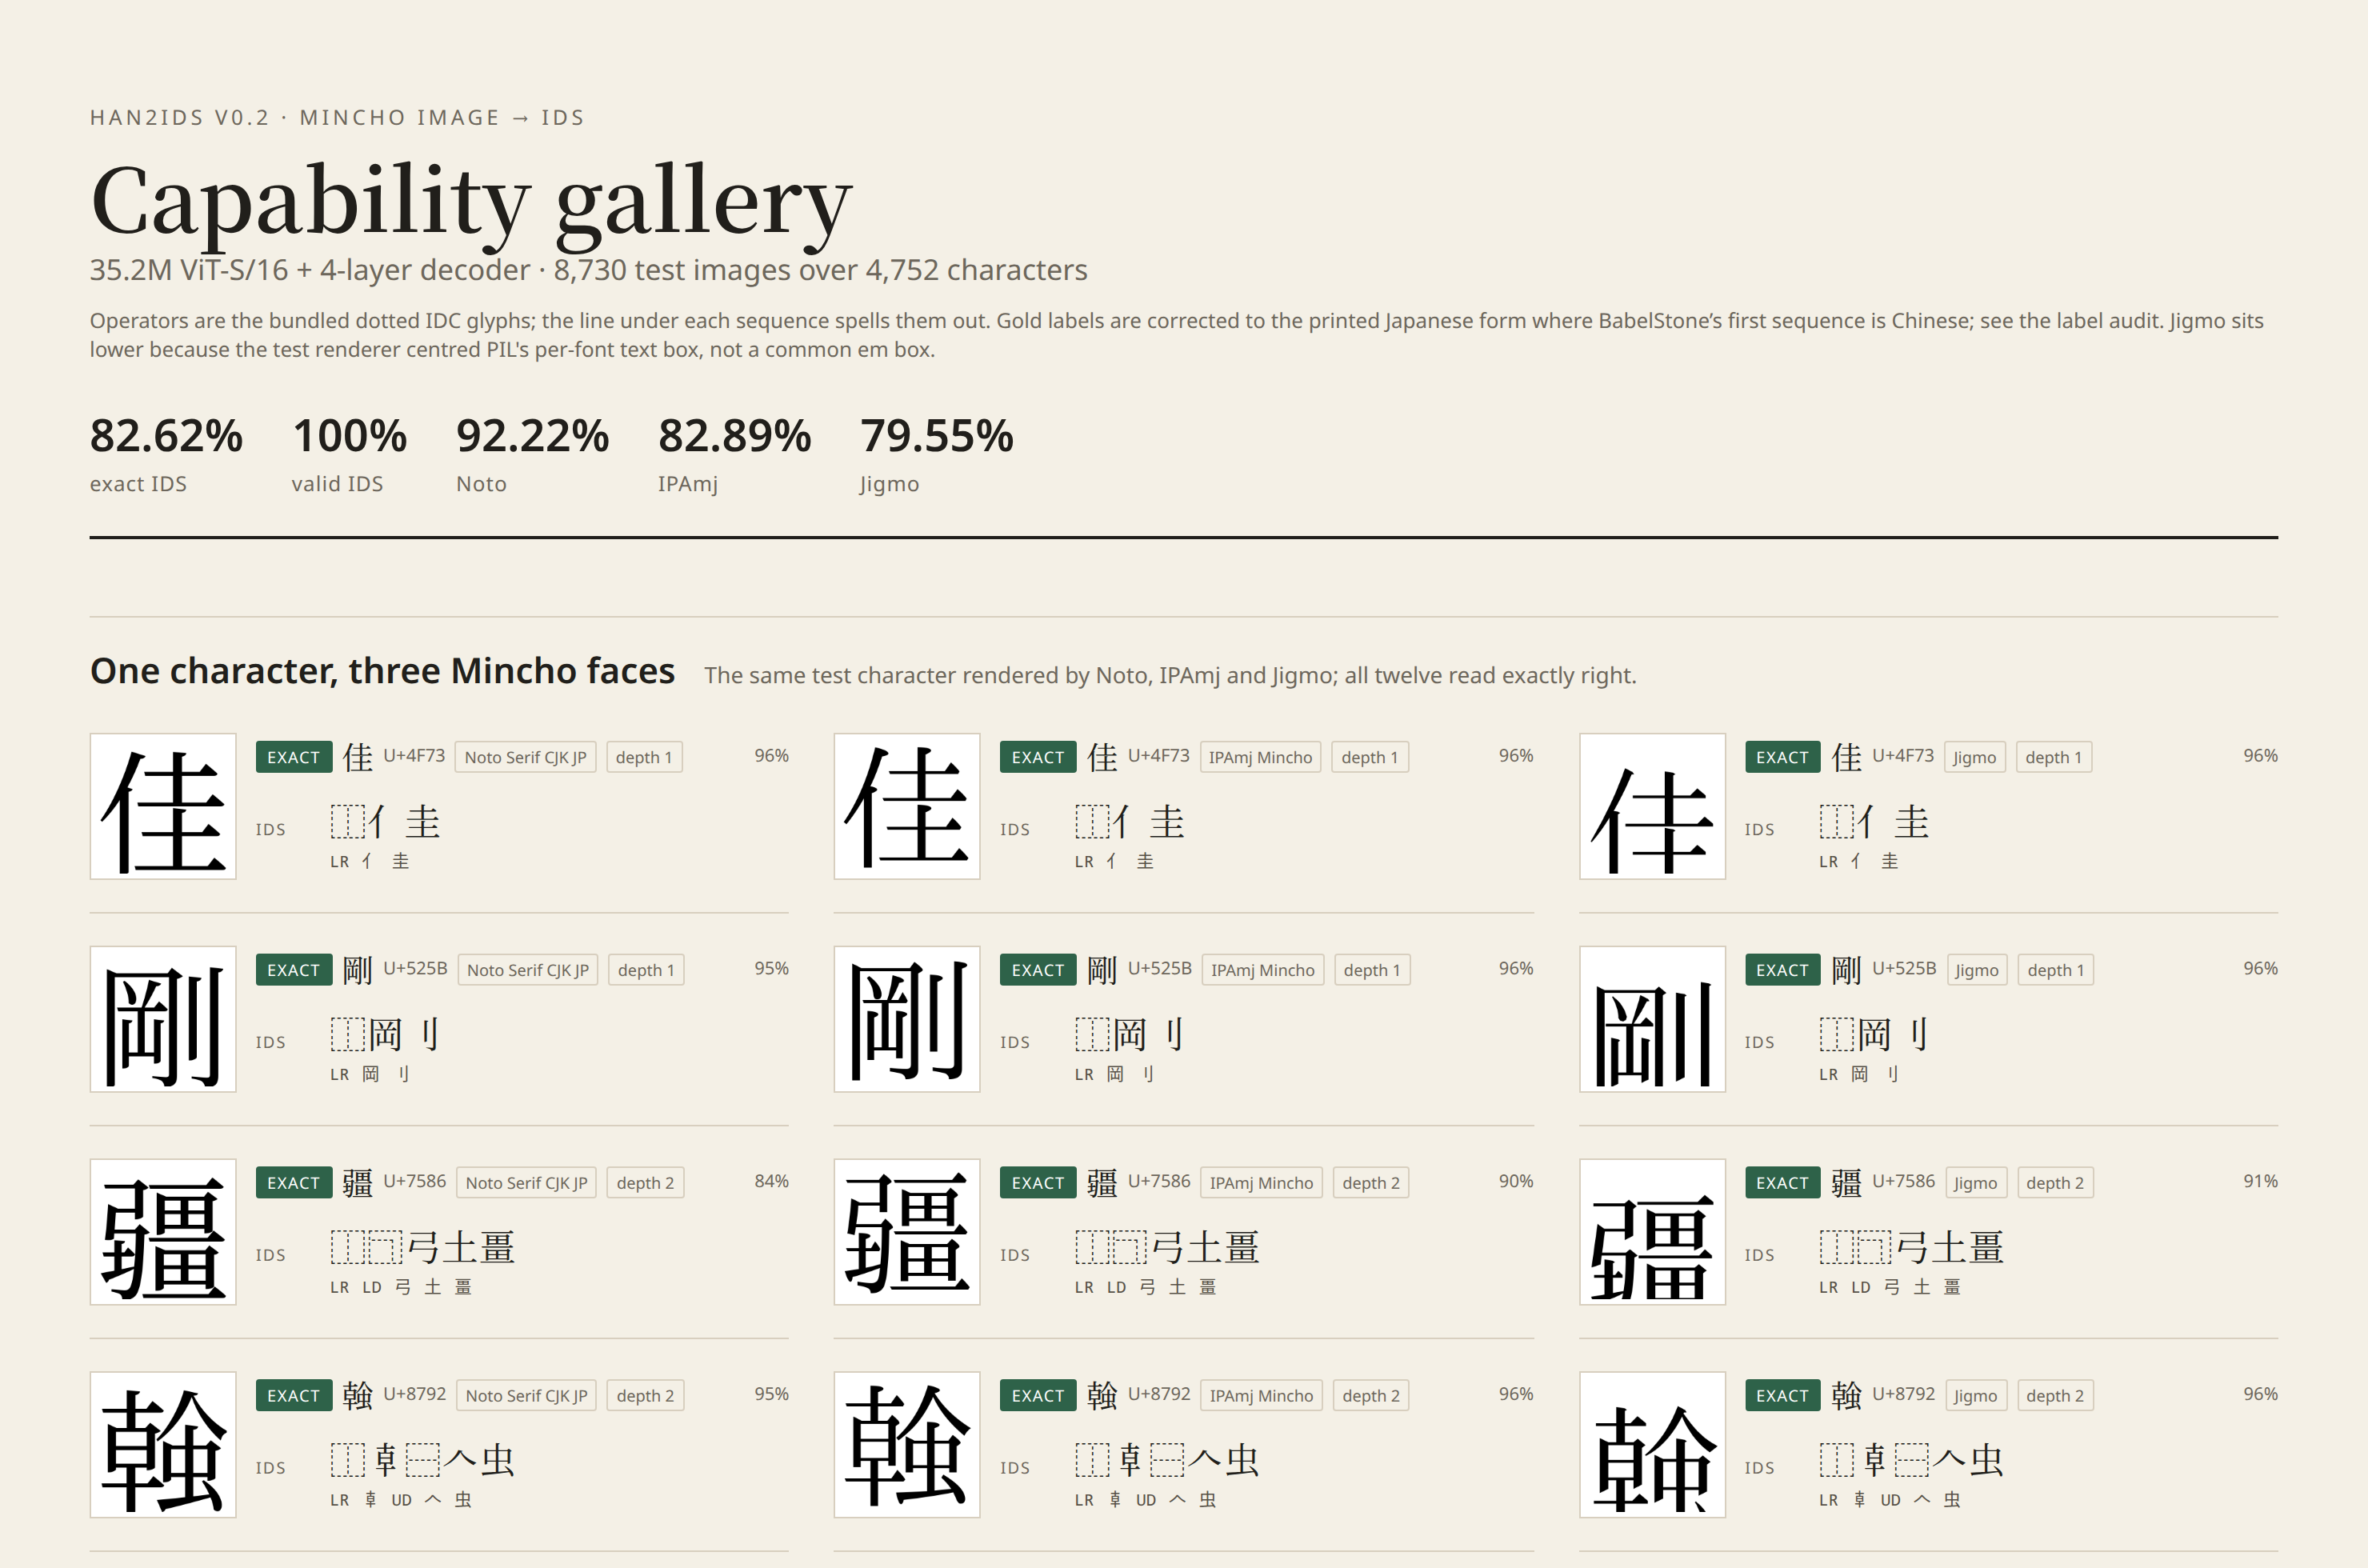
(IDS) from a Mincho / 宋体 glyph image. Input is one glyph image; output is a sequence such as
⿰𠤕⿱龴疋.
Scope is deliberately narrow: Mincho and Song serif faces only. Kai, handwriting and sans faces are out of scope.
Results
The v0.2 test split is 8,730 images over 4,752 characters, mixed across Noto Serif CJK JP, IPAmj Mincho and the Jigmo family.
| exact IDS | valid IDS | |
|---|---|---|
| overall | 82.59% | 100% |
| Noto Serif CJK JP | 92.15% | |
| IPAmj Mincho | 82.85% | |
| Jigmo family | 79.52% |
The previous v0.1 checkpoint reaches 74.27% on the same rows. The score uses Japanese-region labels and three image-specific overrides; BabelStone’s uncorrected labels give 82.45%. The three overrides and the 79-character 争/爭 review are in the label audit.
Architecture
- 35.2M parameters.
- ViT-S/16 encoder (
vit_small_patch16_224.augreg_in21k_ft_in1k), 224×224 grayscale repeated to RGB. - Four transformer decoder layers, 384 wide, 6 heads, cross-attention.
- Character-level output vocabulary of 10,442 tokens, maximum length 48.
- Greedy decoding constrained by the IDS operand stack, so every output is syntactically valid.
han2ids-v0.2.pt is a state dict with itos and args; load it with
han2ids.infer.Han2IDS.
Usage
pip install git+https://github.com/mkpoli/han2ids
huggingface-cli download mkpoli/han2ids-v0.2 han2ids-v0.2.pt --local-dir models
han2ids glyph.png --checkpoint models/han2ids-v0.2.pt
For beam alternatives:
han2ids glyph.png --checkpoint models/han2ids-v0.2.pt --top-k 3 --json
The training data and labels are in the han2ids repository. v0.1 is at mkpoli/han2ids-v0.1.
Training data
- BabelStone IDS (public domain): 97,680 Han records, of which 95,927 have a usable sequence and a font.
- 176,960 images: Noto Serif CJK JP (29,847), IPAmj Mincho 006.01 (52,518), Jigmo family (97,680).
- Four epochs, batch 32; the encoder starts from ImageNet-21k and the decoder is trained from scratch.
Limits
Trained on clean em-box renders. Tight crops, scans, unusual weights and Kai or sans faces are outside the training distribution. The CLI tries four crop placements, but this is not a document OCR model. Variant components that have no IDS code point (for example a 隹 with one fewer horizontal) cannot be named by this vocabulary.
Terms
Code MIT. Fonts and labels keep their own terms; see NOTICE.md and LICENSE in this repository.
The checkpoint is derived from renders of Noto Serif CJK JP (SIL OFL 1.1), IPAmj Mincho (IPA Font
License 1.0) and Jigmo (CC0 1.0).
- Downloads last month
- -