

Product development
Collection
Models that support product discovery in mobility, starting with jobs-to-be-done extraction. • 1 item • Updated
Version 0.1.1 · 2026-10-07 · status: experimental · topic: Product development · task: jtbd
Experimental. The output format may change in a minor version before 1.0.0.
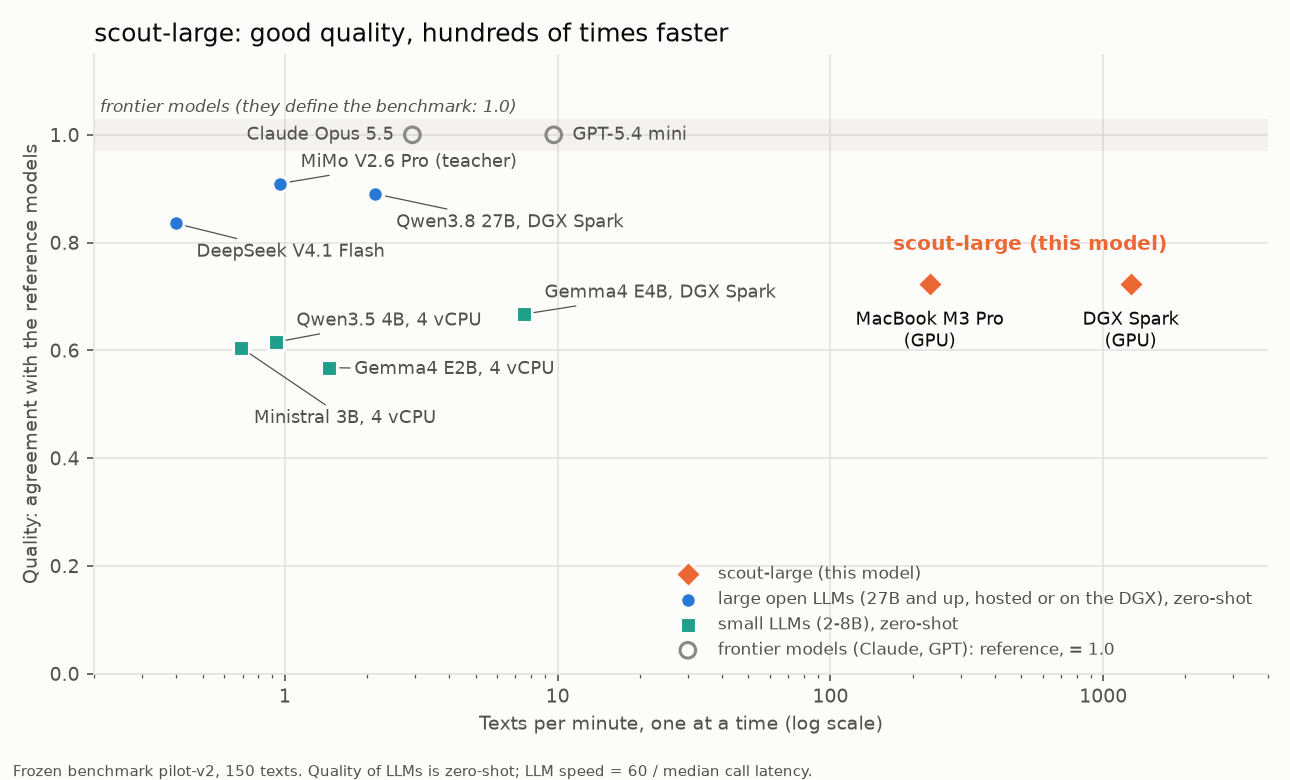
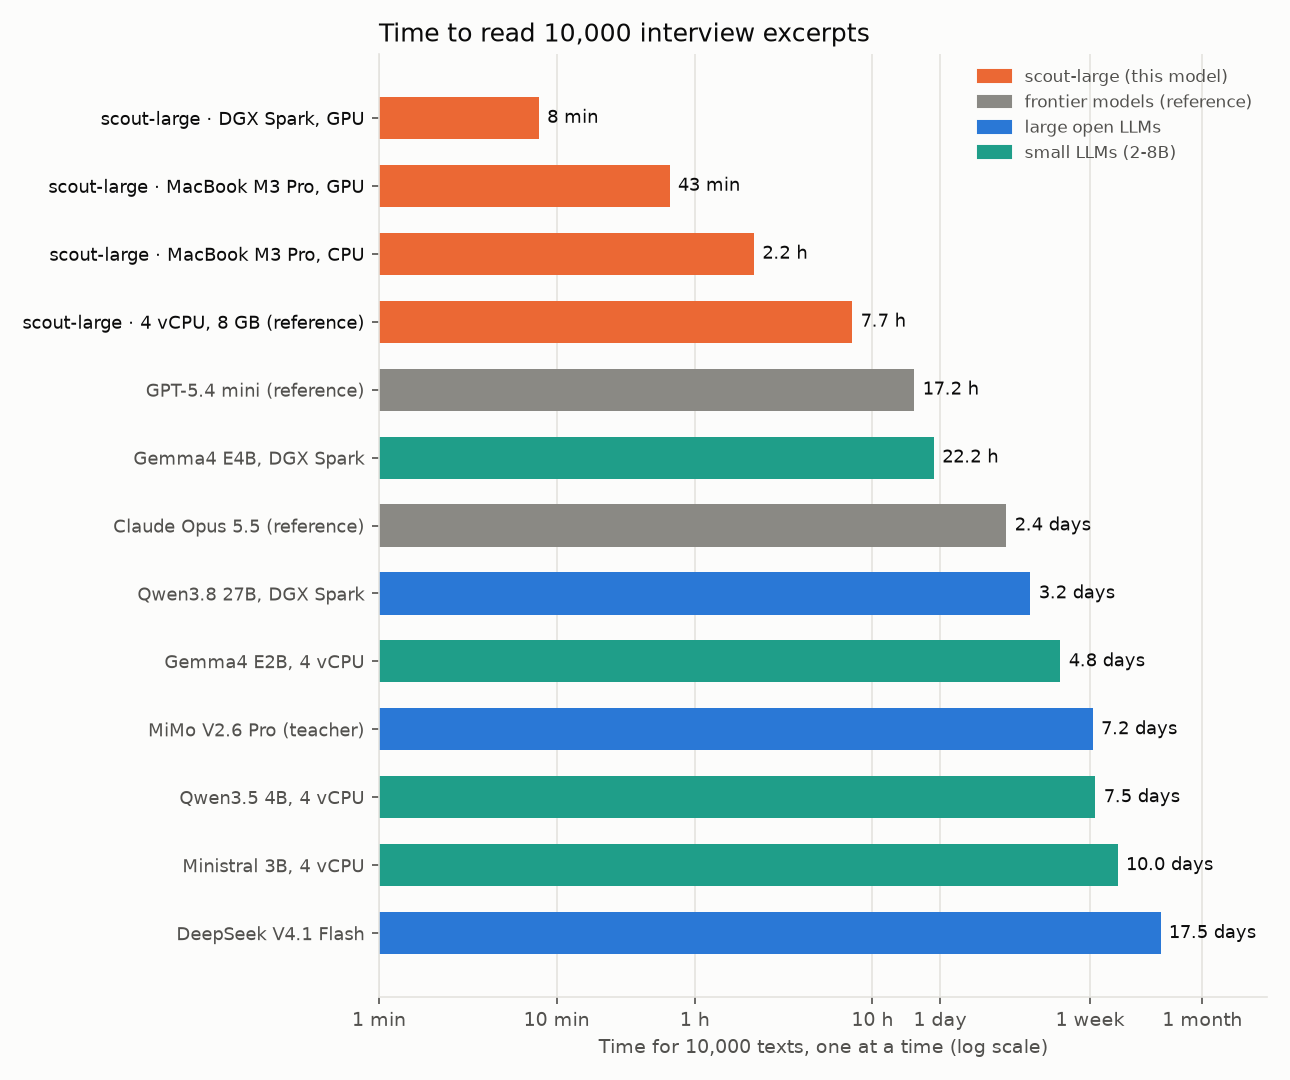
Finds jobs-to-be-done, pains and gains in German and English mobility texts and quotes them verbatim, with actor type, evidence type and evidence scope. On the frozen benchmark pilot-v2 (guideline v2) it reaches a comparison composite of 0.72, against 0.67 for the best zero-shot small model, measured as agreement with two frontier reference models (Claude and the GPT mini tier). It reads a 9,240-character interview in 8.1 s on 4 CPU cores with 2.5 GB of memory, in 0.84 s on the GPU of a MacBook M3 Pro and in 0.12 s on a DGX Spark, where it processes 1,260 texts per minute; the generative models of the pilot manage between 0.4 and 10 per minute.
scout-large belongs to the topic Product development (productdev), task jtbd, variant large. Base model: FacebookAI/xlm-roberta-large.
Product discovery in mobility: finding what people try to get done (jobs), what gets in their way (pains) and what they would gain, in interviews, forum posts, reviews, studies and other texts. Every item comes with the sentence or clause it was found in, so a person can check it. The output is input for later steps (deduplication, clustering, prioritization), which this model does not do.
Decisions about individuals; profiling or identifying the authors of texts; texts outside mobility (it was trained on mobility texts only); treating the output as a complete or final list of needs without human review.
Input: a text in German or English, any length (it is read in overlapping 512-token windows). Output: JSON in the format jtbd-span-v1: output_format_version; relevant (does the text contain jobs, pains or gains at all) and relevance_probability; dimensions, the attribute dimensions this model produces (here actor_type, evidence_type and evidence_scope); and items. Each item has kind (job, pain or gain), quote with its character offsets start and end (always a verbatim span of the input), a score, and one value per produced dimension. An empty list is a valid result.
pip install "mobility-model-zoo @ git+https://github.com/mhabedank/mobility-model-zoo@scout-large/v0.1.1"
import json

from mobility_model_zoo.productdev.jtbd.span import SpanExtractor

model = SpanExtractor.from_pretrained("mobility-model-zoo/scout-large", revision="v0.1.1")
print(json.dumps(model.extract("Ich wohne am Stadtrand und arbeite im Schichtdienst. Nach 22 Uhr fährt kein Bus mehr, also nehme ich das Auto, obwohl ich lieber Bahn fahren würde. Wenn es einen Nachtbus gäbe, würde ich das Auto verkaufen."), ensure_ascii=False, indent=2))
The tag v0.1.1 always points to this version. For strict reproducibility, pin the commit hash of that tag instead (revision="<commit>").
01-night-shift.txt
Input:
Ich wohne am Stadtrand und arbeite im Schichtdienst. Nach 22 Uhr fährt kein Bus mehr, also nehme ich das Auto, obwohl ich lieber Bahn fahren würde. Wenn es einen Nachtbus gäbe, würde ich das Auto verkaufen.
Output:
{
  "output_format_version": "jtbd-span-v1",
  "relevant": true,
  "relevance_probability": 0.9999,
  "dimensions": [
    "actor_type",
    "evidence_type",
    "evidence_scope"
  ],
  "items": [
    {
      "kind": "pain",
      "quote": "Nach 22 Uhr fährt kein Bus mehr, also nehme ich das Auto, obwohl ich lieber Bahn fahren würde.",
      "start": 53,
      "end": 147,
      "score": 0.9571,
      "actor_type": "individual",
      "evidence_type": "routine",
      "evidence_scope": "multiple"
    }
  ]
}
02-depot-charging.txt
Input:
Our fleet manager told us that charging the delivery vans takes most of the night. Two of the six chargers in the depot are often broken, so drivers start their morning routes with half a battery.
Output:
{
  "output_format_version": "jtbd-span-v1",
  "relevant": true,
  "relevance_probability": 0.9999,
  "dimensions": [
    "actor_type",
    "evidence_type",
    "evidence_scope"
  ],
  "items": [
    {
      "kind": "pain",
      "quote": "Our fleet manager told us that charging the delivery vans takes most of the night.",
      "start": 0,
      "end": 82,
      "score": 0.9738,
      "actor_type": "worker",
      "evidence_type": "observation",
      "evidence_scope": "multiple"
    },
    {
      "kind": "pain",
      "quote": "Two of the six chargers in the depot are often broken, so drivers start their morning routes with half a battery.",
      "start": 83,
      "end": 196,
      "score": 0.9977,
      "actor_type": "worker",
      "evidence_type": "observation",
      "evidence_scope": "quantified"
    }
  ]
}
03-cargo-bike.txt
Input:
Mit dem Lastenrad bringe ich die Kinder in zehn Minuten zur Kita. Schwierig wird es nur, wenn der Radweg zugeparkt ist und ich auf die Straße ausweichen muss.
Output:
{
  "output_format_version": "jtbd-span-v1",
  "relevant": true,
  "relevance_probability": 0.9997,
  "dimensions": [
    "actor_type",
    "evidence_type",
    "evidence_scope"
  ],
  "items": [
    {
      "kind": "job",
      "quote": "Mit dem Lastenrad bringe ich die Kinder in zehn Minuten zur Kita.",
      "start": 0,
      "end": 65,
      "score": 0.9909,
      "actor_type": "individual",
      "evidence_type": "routine",
      "evidence_scope": "quantified"
    },
    {
      "kind": "pain",
      "quote": "Schwierig wird es nur, wenn der Radweg zugeparkt ist und ich auf die Straße ausweichen muss.",
      "start": 66,
      "end": 158,
      "score": 0.9975,
      "actor_type": "individual",
      "evidence_type": "routine",
      "evidence_scope": "multiple"
    }
  ]
}
These numbers are agreement with the consensus of claude-reference and gpt-mini-reference (frontier reference models); they are not measured against human ground truth. Benchmark: pilot-v2.
| Metric | Value | What it measures | Reference | Benchmark | Items | Date |
|---|---|---|---|---|---|---|
agreement_relevance |
0.5392 | Agreement with the reference on relevance (kappa), 95% CI 0.249986-0.764049 | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 147 | 2026-10-07 |
agreement_item_matching |
0.5882 | Agreement with the reference on item matching (f1), 95% CI 0.548562-0.625282 | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 1164 | 2026-10-07 |
agreement_kind |
0.8315 | Agreement with the reference on kind (kappa), 95% CI 0.778463-0.883767 | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 412 | 2026-10-07 |
agreement_actor_type |
0.7743 | Agreement with the reference on actor type (kappa), 95% CI 0.69857-0.838218 | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 404 | 2026-10-07 |
agreement_evidence_type |
0.8489 | Agreement with the reference on evidence type (quadratic_weighted_kappa), 95% CI 0.76975-0.908006 | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 340 | 2026-10-07 |
agreement_evidence_scope |
0.7582 | Agreement with the reference on evidence scope (kappa), 95% CI 0.6683-0.833914 | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 380 | 2026-10-07 |
comparison_composite |
0.7234 | Mean agreement over the dimensions this model outputs (relevance, item matching, kind, actor type, evidence type, evidence scope) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
quotes_verbatim_rate |
1 | Share of quotes that are verbatim spans of the input | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 1441 | 2026-10-07 |
schema_valid_rate |
1 | Share of outputs valid against the jtbd-span-v1 schema | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
consistency_rate |
1 | Share of passed consistency checks (dimensions, order, relevance) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
contested_items |
1574 | Benchmark items the reference models disagree on, reported separately and scored neutrally | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_best_baseline |
0.6672 | Same composite for the best zero-shot small baseline (baseline-gemma4-e4b) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_teacher |
0.9095 | Same composite for the teacher (teacher-or-mimo-v2.6-pro) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_reference |
1 | Same composite for the two reference models against each other, on consensus units | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_reference_85pct |
0.85 | 85% of the reference value: the pilot's bar for a usable small model | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_mimo |
0.9095 | Same composite for MiMo V2.6 Pro (teacher) (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_deepseek |
0.8357 | Same composite for DeepSeek V4.1 Flash (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_qwen3_8_27b_dgx |
0.8904 | Same composite for Qwen3.8 27B, DGX Spark (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_gemma4_e4b_dgx |
0.6672 | Same composite for Gemma4 E4B, DGX Spark (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_qwen3_5_4b |
0.6153 | Same composite for Qwen3.5 4B, 4 vCPU (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_ministral_3b |
0.6044 | Same composite for Ministral 3B, 4 vCPU (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
comparison_composite_gemma4_e2b |
0.5679 | Same composite for Gemma4 E2B, 4 vCPU (zero-shot, from its benchmark run) | the consensus of claude-reference and gpt-mini-reference (frontier reference models) | pilot-v2 | 150 | 2026-10-07 |
Budget: 4 GB RAM, no GPU. Measured on: railway service, 4 vCPU limit, 8 GB RAM limit, no GPU (x86_64, 4 vCPU, 8.0 GB RAM, AMD EPYC 9655 96-Core Processor, CPU only).
| Metric | Value | Unit | What it measures | Hardware | Items | Date |
|---|---|---|---|---|---|---|
latency_9k_chars_s |
8.106 | s | Median time to process a 9240-character text, model loaded | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU (x86_64, 4 vCPU, 8.0 GB RAM, AMD EPYC 9655 96-Core Processor, CPU only) | 2026-10-07 | |
load_time_s |
12.23 | s | Time to load the model from local files | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU (x86_64, 4 vCPU, 8.0 GB RAM, AMD EPYC 9655 96-Core Processor, CPU only) | 2026-10-07 | |
peak_ram_gb |
2.488 | GB | Peak memory of the process while loading and processing | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU (x86_64, 4 vCPU, 8.0 GB RAM, AMD EPYC 9655 96-Core Processor, CPU only) | 2026-10-07 | |
chunks_per_min |
21.62 | chunks/min | Throughput over the 150 benchmark chunks | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU (x86_64, 4 vCPU, 8.0 GB RAM, AMD EPYC 9655 96-Core Processor, CPU only) | 150 | 2026-10-07 |
chunks_per_min_mac_m3pro_cpu |
77.35 | chunks/min | Throughput over the 150 benchmark chunks, one at a time (development hardware) | MacBook Pro, Apple M3 Pro, 36 GB, CPU only | 150 | 2026-10-07 |
latency_9k_chars_s_mac_m3pro_cpu |
1.936 | s | Median time to process the 9,240-character text, model loaded (development hardware) | MacBook Pro, Apple M3 Pro, 36 GB, CPU only | None | 2026-10-07 |
chunks_per_min_mac_m3pro_gpu |
231.1 | chunks/min | Throughput over the 150 benchmark chunks, one at a time (development hardware) | MacBook Pro, Apple M3 Pro, 36 GB, GPU (MPS) | 150 | 2026-10-07 |
latency_9k_chars_s_mac_m3pro_gpu |
0.8404 | s | Median time to process the 9,240-character text, model loaded (development hardware) | MacBook Pro, Apple M3 Pro, 36 GB, GPU (MPS) | None | 2026-10-07 |
chunks_per_min_dgx_spark_gpu |
1260 | chunks/min | Throughput over the 150 benchmark chunks, one at a time (development hardware) | NVIDIA DGX Spark (GB10), GPU (CUDA) | 150 | 2026-10-07 |
latency_9k_chars_s_dgx_spark_gpu |
0.1219 | s | Median time to process the 9,240-character text, model loaded (development hardware) | NVIDIA DGX Spark (GB10), GPU (CUDA) | None | 2026-10-07 |
comparison_chunks_per_min_claude |
2.934 | chunks/min | Claude Opus 5.5 (reference): texts per minute on the benchmark chunks (60 / median call latency while labeling the benchmark) | Anthropic, Claude Code CLI (subscription) | 150 | 2026-10-07 |
comparison_chunks_per_min_gpt_mini |
9.677 | chunks/min | GPT-5.4 mini (reference): texts per minute on the benchmark chunks (sample at concurrency 1) | OpenAI via OpenRouter | 20 | 2026-10-07 |
comparison_chunks_per_min_mimo |
0.9583 | chunks/min | MiMo V2.6 Pro (teacher): texts per minute on the benchmark chunks (60 / median call latency while labeling the benchmark) | OpenRouter, provider chosen per request | 150 | 2026-10-07 |
comparison_chunks_per_min_deepseek |
0.3978 | chunks/min | DeepSeek V4.1 Flash: texts per minute on the benchmark chunks (60 / median call latency while labeling the benchmark) | OpenRouter, provider chosen per request | 182 | 2026-10-07 |
comparison_chunks_per_min_qwen3_8_27b_dgx |
2.148 | chunks/min | Qwen3.8 27B, DGX Spark: texts per minute on the benchmark chunks (60 / median call latency while labeling the benchmark) | NVIDIA DGX Spark (GB10), GPU, Ollama | 150 | 2026-10-07 |
comparison_chunks_per_min_gemma4_e4b_dgx |
7.509 | chunks/min | Gemma4 E4B, DGX Spark: texts per minute on the benchmark chunks (60 / median call latency while labeling the benchmark) | NVIDIA DGX Spark (GB10), GPU, Ollama | 150 | 2026-10-07 |
comparison_chunks_per_min_qwen3_5_4b |
0.9249 | chunks/min | Qwen3.5 4B, 4 vCPU: texts per minute on the benchmark chunks (jtbd perf on the reference machine, one chunk at a time) | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU | 150 | 2026-10-07 |
comparison_chunks_per_min_ministral_3b |
0.6933 | chunks/min | Ministral 3B, 4 vCPU: texts per minute on the benchmark chunks (jtbd perf on the reference machine, one chunk at a time) | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU | 150 | 2026-10-07 |
comparison_chunks_per_min_gemma4_e2b |
1.456 | chunks/min | Gemma4 E2B, 4 vCPU: texts per minute on the benchmark chunks (jtbd perf on the reference machine, one chunk at a time) | railway service, 4 vCPU limit, 8 GB RAM limit, no GPU | 150 | 2026-10-07 |
| Teacher | License basis | Training on outputs permitted |
|---|---|---|
teacher-or-mimo-v2.6-pro |
MIT (HF XiaomiMiMo/MiMo-V2.6-Pro-RL); HF XiaomiMiMo/MiMo-V2.6-Pro-RL license tag mit, checked 2026-10-06 | yes |
The training data itself is not published. Datasets stay internal so that the people who wrote the source texts are protected and source terms are respected (project constitution, Principle VI); the model, the method, the prompts and the evaluation results are published.
4a7091af7166b9e5a6c802e7d5c6ec9f9a45de46| Version | Date | Status | Change | Changes | agreement_relevance |
agreement_item_matching |
agreement_kind |
|---|---|---|---|---|---|---|---|
| 0.1.1 | 2026-10-07 | experimental | patch | Card only, same model files as 0.1.0: comparison figures with the y-axis from 0 and the models grouped (frontier reference models, large open LLMs, small LLMs), shorter labels; README links. No change to the model, its quality or speed numbers. | 0.5392 | 0.5882 | 0.8315 |
| 0.1.0 | 2026-10-07 | experimental | initial | First production release of the span extractor, rebuilt without spike data. | 0.5392 | 0.5882 | 0.8315 |
Apache-2.0
@misc{mobility-model-zoo-scout,
  title  = {Scout (large): jobs, pains and gains in mobility texts, mobility-model-zoo},
  author = {Habedank, Martin},
  year   = {2026},
  url    = {https://huggingface.co/mobility-model-zoo/scout-large}
}
Part of mobility-model-zoo, a collection of small, fast mobility models grouped by topic. Topic collection: Product development. Source code, recipes and release records: https://github.com/mhabedank/mobility-model-zoo.
Base model
FacebookAI/xlm-roberta-large