

Learning to Act with World Models by Valuing What Comes Next
Paper • 2611.12200 • Published
Chenghao Gao*, Zhi Zhang*, Dian Jin, Yihe Pan, Doudou Zhou† · National University of Singapore · University of California, Los Angeles · Fudan University · *Equal contribution · †Corresponding author
📄 Paper (arXiv:2611.12200) · 💻 Code
A sparse terminal reward tells an agent whether it succeeded. The environment's transitions contain information about how each action changed its chances of succeeding.
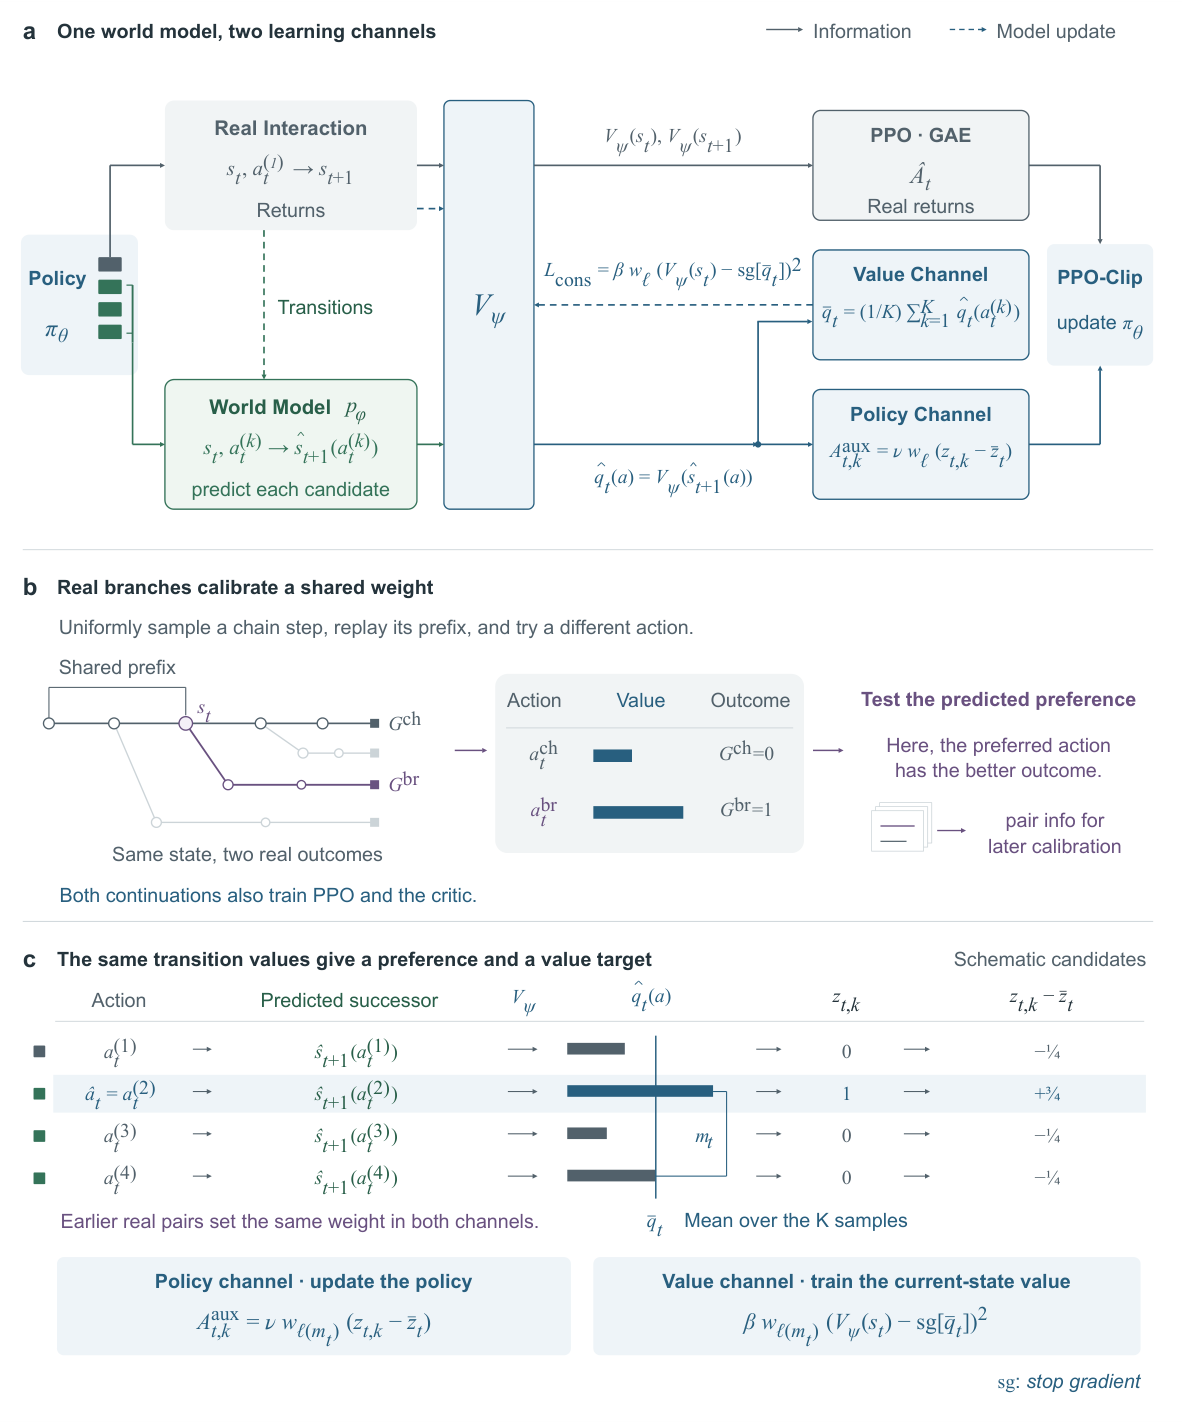
WM-PPO learns to use that information. A world model, trained on real transitions, predicts what the policy's candidate actions would change; PPO's critic values the predicted successor states. These transition values inform both policy and critic learning (a policy channel and a value channel), and a shared gate calibrates their weight against real branch outcomes. Only the policy is needed at inference; no teacher model or privileged environment information is used.
| Greedy policy-only success, mean of three runs | PPO-160 | WM-PPO |
|---|---|---|
| ALFWorld | 63.5% | 87.5% |
| ScienceWorld | 39.3% | 52.9% |
WM-PPO run 1 on ALFWorld (iteration 36), ScienceWorld (iteration 60) and text Sokoban (iteration 36): policy, critic and world model, with the shared warm-up and the initial world model of each environment. Every component is a LoRA adapter on Qwen3-4B-Instruct-2507; the critic adds a value head. Model cards: alfworld/README.md, scienceworld/README.md, sokoban/README.md. Checksums: SHA256SUMS; file list with sizes: MANIFEST.tsv.
Download into weights/ of the code repository, where its commands expect the checkpoints, and evaluate a policy:
hf download nuskonghou/wm-ppo --local-dir weights
(cd weights && sha256sum -c SHA256SUMS)
scripts/wmppo eval alfworld weights/alfworld/wmppo_run1_it036/policy wmppo_run1_it036 --gpu 0
Setup, training and the paper's tables are described in the code repository's README.
@misc{gao2026learning,
  title         = {Learning to Act with World Models by Valuing What Comes Next},
  author        = {Gao, Chenghao and Zhang, Zhi and Jin, Dian and Pan, Yihe and Zhou, Doudou},
  year          = {2026},
  eprint        = {2611.12200},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://arxiv.org/abs/2611.12200}
}
Base model
Qwen/Qwen3-4B-Instruct-2507