

RF-DETR: Neural Architecture Search for Real-Time Detection Transformers
Paper • 2511.09554 • Published • 14

View on Pictograph · Pictograph Research · Keypoint Detection · RF-DETR Keypoint Preview · FP32 · Custom License
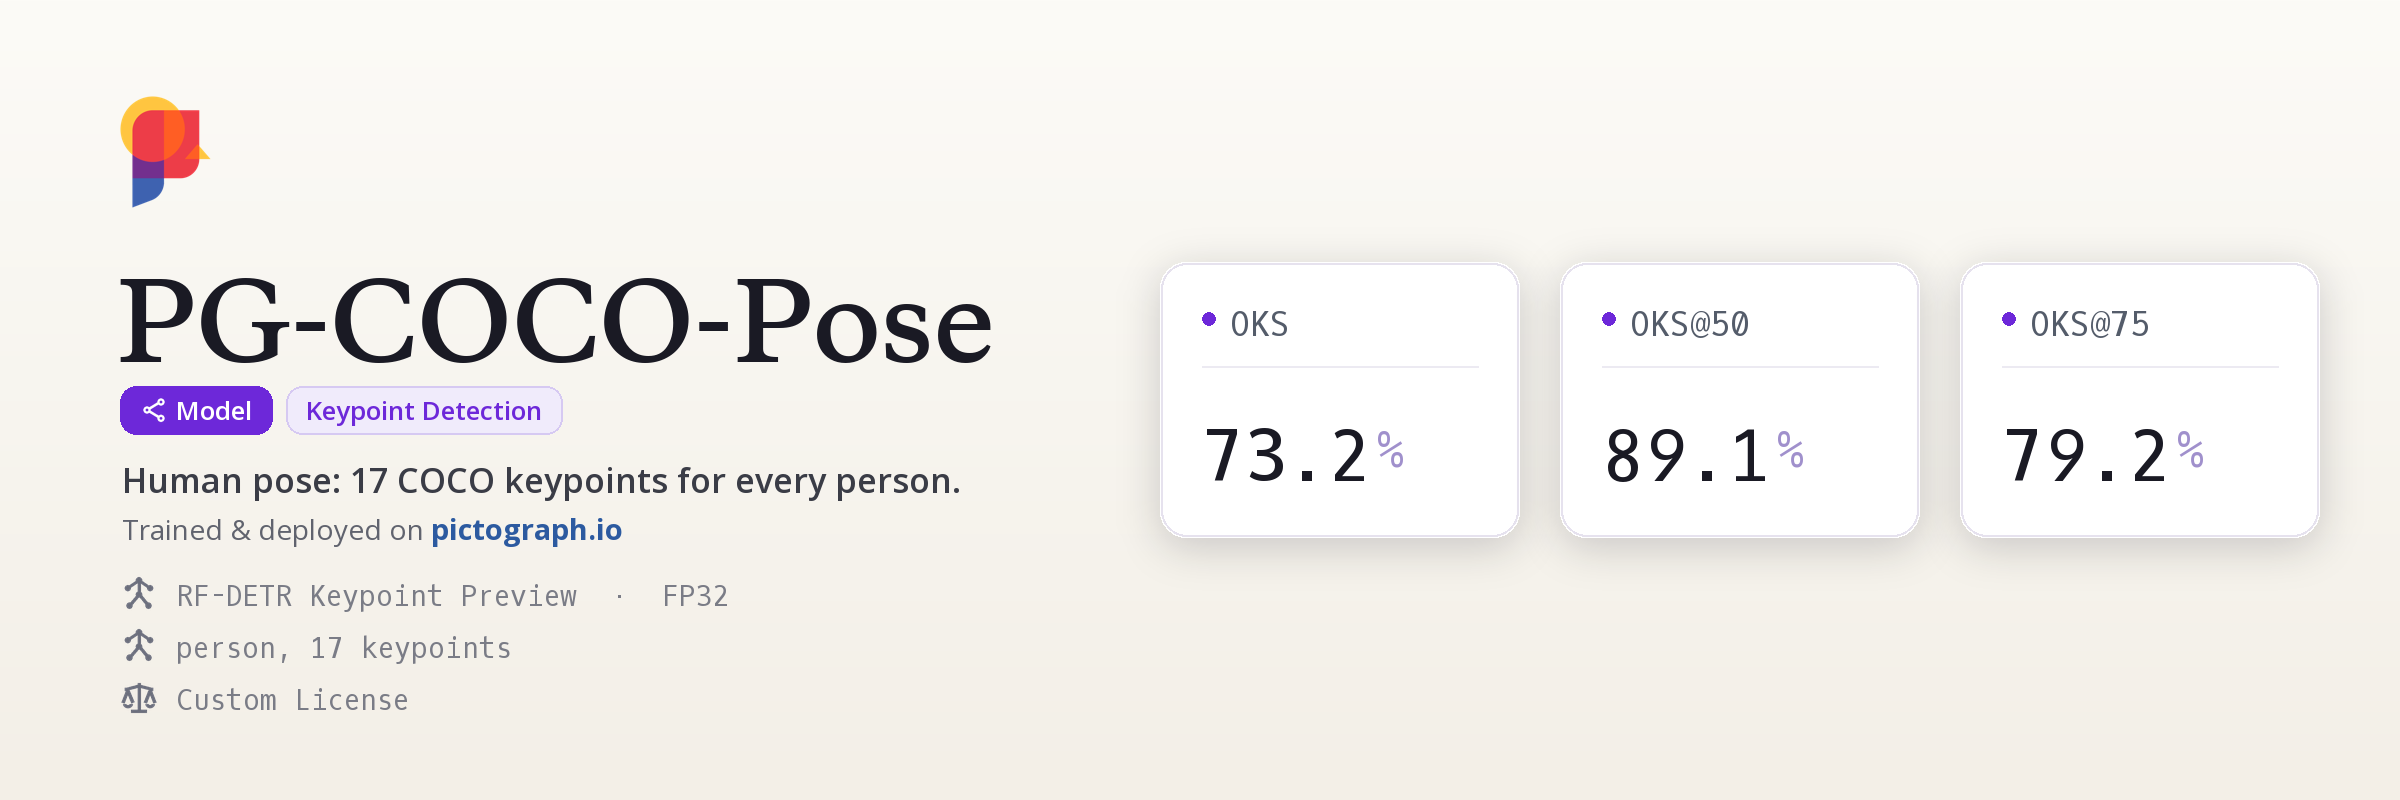
This is a keypoint detection model built on RF-DETR Keypoint Preview, trained on the COCO 2017 Pose dataset. It expects 576x576 input and runs in FP32 precision. It finds each person and its 17 keypoints: the Skeleton section lists them in output order, with the joints each connects to. The ONNX weights are in this repo; run them with the Pictograph SDK (below) or open the model on Pictograph to test it in-browser, call the hosted API, or deploy it as an always-on endpoint.
Headline: 73.2% OKS.
| Metric | Value |
|---|---|
| OKS | 73.2% |
| OKS@50 | 89.1% |
| OKS@75 | 79.2% |
| Recall | 78.8% |
OKS is COCO's keypoint AP: the average precision over object keypoint similarity (OKS) thresholds 0.50 to 0.95. OKS@50 and OKS@75 are the AP at one threshold; Recall is the average recall over 0.50 to 0.95.
Each object the model finds is one instance: its keypoints share an instance_id, are named for their joint and carry their own confidence. The keypoint index is the model's output order.
| # | Keypoint | Connects to |
|---|---|---|
| 0 | nose | left_eye, right_eye |
| 1 | left_eye | right_eye, nose, left_ear |
| 2 | right_eye | left_eye, nose, right_ear |
| 3 | left_ear | left_eye, left_shoulder |
| 4 | right_ear | right_eye, right_shoulder |
| 5 | left_shoulder | left_hip, right_shoulder, left_elbow, left_ear |
| 6 | right_shoulder | right_hip, left_shoulder, right_elbow, right_ear |
| 7 | left_elbow | left_shoulder, left_wrist |
| 8 | right_elbow | right_shoulder, right_wrist |
| 9 | left_wrist | left_elbow |
| 10 | right_wrist | right_elbow |
| 11 | left_hip | left_knee, right_hip, left_shoulder |
| 12 | right_hip | right_knee, left_hip, right_shoulder |
| 13 | left_knee | left_ankle, left_hip |
| 14 | right_knee | right_ankle, right_hip |
| 15 | left_ankle | left_knee |
| 16 | right_ankle | right_knee |
| Setting | Value |
|---|---|
| Base dataset | COCO 2017 Pose |
| Dataset size | 10,799 images |
| Input size | 576x576 |
| Epochs | 12 |
| Batch size | 4 |
| Learning rate | 0.0001 |
| Model size | preview |
| Precision | FP32 |
| Version | 1.0.0 |
The weights ship as ONNX (pg-coco-pose.onnx) with a config.json. The Pictograph SDK applies the model's exact pre/post-processing for you:
pip install "pictograph[inference]"
from huggingface_hub import hf_hub_download
from pictograph import load_model, KeypointModel

onnx = hf_hub_download("pictograph/pg-coco-pose", "pg-coco-pose.onnx")
config = hf_hub_download("pictograph/pg-coco-pose", "config.json")

model: KeypointModel = load_model(onnx, config, task="keypoint_detection")
result = model.predict("photo.jpg")   # KeypointResult
for obj in result.instances:           # one list of joints per object
    print(f"instance {obj[0].instance_id}: {len(obj)} joints")
    for j in obj:                      # j.name IS the joint class
        print(f"  {j.name} ({j.keypoint.x:.0f},{j.keypoint.y:.0f}) {j.confidence:.2f}")
Example output (illustrative; your exact values depend on the image):
instance 1: 17 joints
  nose (512,143) 0.97
  left_eye (498,131) 0.96
instance 2: 17 joints
  nose (188,160) 0.93
from huggingface_hub import hf_hub_download
import onnxruntime as ort

onnx = hf_hub_download("pictograph/pg-coco-pose", "pg-coco-pose.onnx")
sess = ort.InferenceSession(onnx, providers=["CPUExecutionProvider"])
inp = sess.get_inputs()[0]
print(inp.name, inp.shape)   # NCHW float32; input size + normalization in config.json
# outputs = sess.run(None, {inp.name: preprocessed_batch})
# Decoding is architecture-specific; the Pictograph SDK (above) does it for you.
Non-commercial use only. Trained on COCO 2017 Pose, whose images are COCO's: the COCO Consortium does not own their copyright; each image comes from Flickr under its own license, recorded per image in COCO's annotation files, and most of them (68.9% of train2017) are Creative Commons NonCommercial. COCO's annotations are CC BY 4.0, the COCO Consortium. The RF-DETR Keypoint base model is Apache 2.0 (Roboflow). Cite Lin et al., Microsoft COCO: Common Objects in Context (ECCV 2014).
This model uses the RF-DETR Keypoint Preview architecture:
@inproceedings{robinson2026rfdetr,
  title     = {RF-DETR: Real-Time Detection Transformer},
  author    = {Robinson, Isaac and Robicheaux, Peter and Popov, Matvei and Ramanan, Deva and Peri, Neehar},
  booktitle = {International Conference on Learning Representations (ICLR)},
  year      = {2026},
  url       = {https://arxiv.org/abs/2511.09554}
}
It was trained on COCO 2017 Pose, from:
@inproceedings{lin2014coco,
  title = {Microsoft {COCO}: Common Objects in Context},
  author = {Lin, Tsung-Yi and Maire, Michael and Belongie, Serge and Hays, James and Perona, Pietro and Ramanan, Deva and Doll{\'a}r, Piotr and Zitnick, C. Lawrence},
  booktitle = {Computer Vision - ECCV 2014},
  pages = {740--755},
  publisher = {Springer},
  year = {2014}
}
Trained and published with Pictograph - annotate, train, and deploy from one API.