| --- |
| library_name: pytorch |
| license: mit |
| tags: |
| - backbone |
| - android |
| pipeline_tag: image-classification |
|
|
| --- |
| |
|  |
|
|
| # NetVLAD: Optimized for Qualcomm Devices |
|
|
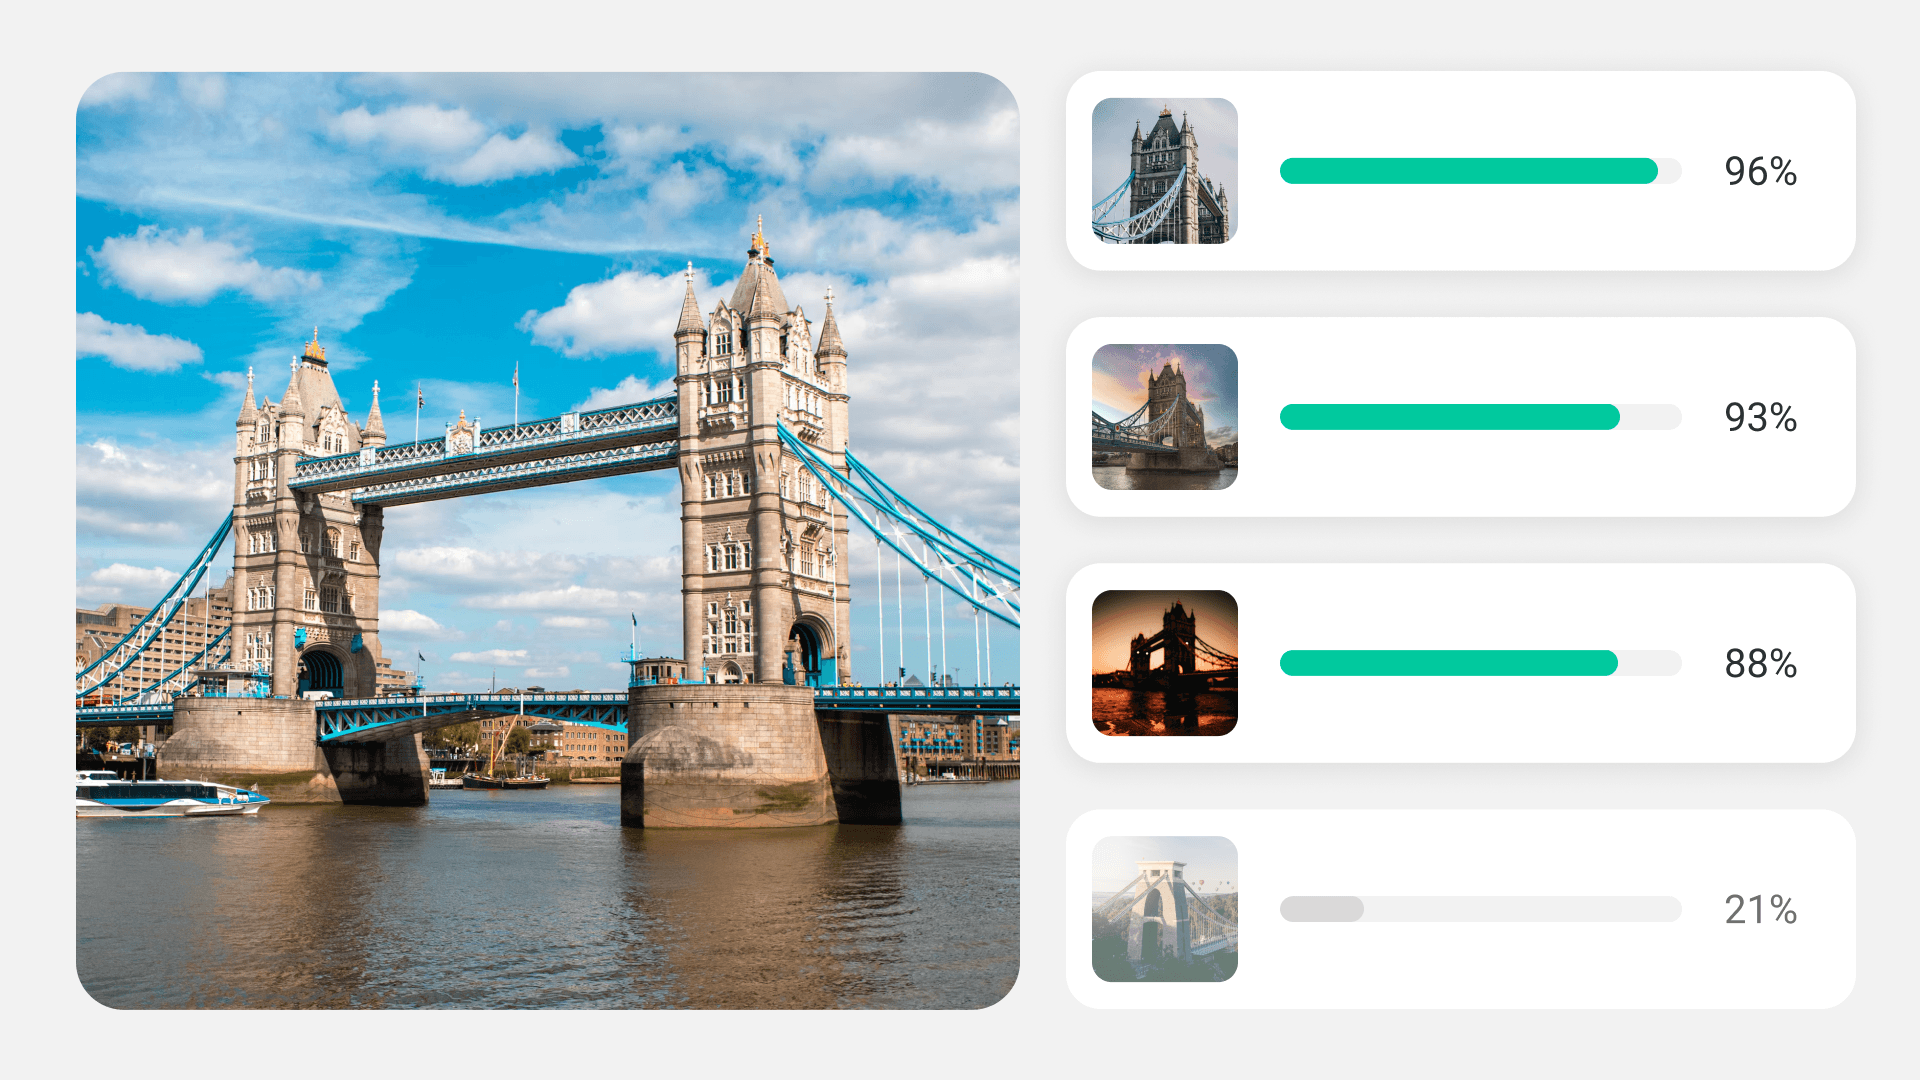
| NetVLAD is a CNN-based visual place recognition model that aggregates dense local descriptors into a compact VLAD descriptor using a differentiable soft assignment to learned cluster centroids. Built on a VGG-16 backbone, it produces a 32,768-d L2-normalized descriptor suitable for nearest-neighbour place retrieval across images taken under varying conditions. |
|
|
| This is based on the implementation of NetVLAD found [here](https://github.com/Nanne/pytorch-NetVlad). |
| This repository contains pre-exported model files optimized for Qualcomm® devices. You can use the [Qualcomm® AI Hub Models](https://github.com/qualcomm/ai-hub-models/blob/v0.66.0/src/qai_hub_models/models/netvlad) library to export with custom configurations. More details on model performance across various devices, can be found [here](#performance-summary). |
|
|
| Qualcomm AI Hub Models uses [Qualcomm AI Hub Workbench](https://workbench.aihub.qualcomm.com) to compile, profile, and evaluate this model. [Sign up](https://myaccount.qualcomm.com/signup) to run these models on a hosted Qualcomm® device. |
|
|
| ## Getting Started |
| There are two ways to deploy this model on your device: |
|
|
| ### Option 1: Download Pre-Exported Models |
|
|
| Below are pre-exported model assets ready for deployment. |
|
|
| | Runtime | Precision | Chipset | SDK Versions | Download | |
| |---|---|---|---|---| |
| | ONNX | float | Universal | QAIRT 2.50, ONNX Runtime 1.30.0 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/netvlad/releases/v0.66.0/netvlad-onnx-float.zip) |
| | ONNX | w8a8_mixed_int16 | Universal | QAIRT 2.50, ONNX Runtime 1.30.0 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/netvlad/releases/v0.66.0/netvlad-onnx-w8a8_mixed_int16.zip) |
| | QNN_DLC | float | Universal | QAIRT 2.50 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/netvlad/releases/v0.66.0/netvlad-qnn_dlc-float.zip) |
| | QNN_DLC | w8a8_mixed_int16 | Universal | QAIRT 2.50 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/netvlad/releases/v0.66.0/netvlad-qnn_dlc-w8a8_mixed_int16.zip) |
| | TFLITE | float | Universal | QAIRT 2.50 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/netvlad/releases/v0.66.0/netvlad-tflite-float.zip) |
|
|
| For more device-specific assets and performance metrics, visit **[NetVLAD on Qualcomm® AI Hub](https://aihub.qualcomm.com/models/netvlad)**. |
|
|
|
|
| ### Option 2: Export with Custom Configurations |
|
|
| Use the [Qualcomm® AI Hub Models](https://github.com/qualcomm/ai-hub-models/blob/v0.66.0/src/qai_hub_models/models/netvlad) Python library to compile and export the model with your own: |
| - Custom weights (e.g., fine-tuned checkpoints) |
| - Custom input shapes |
| - Target device and runtime configurations |
|
|
| This option is ideal if you need to customize the model beyond the default configuration provided here. |
|
|
| See our repository for [NetVLAD on GitHub](https://github.com/qualcomm/ai-hub-models/blob/v0.66.0/src/qai_hub_models/models/netvlad) for usage instructions. |
|
|
| ## Model Details |
|
|
| **Model Type:** Model_use_case.image_classification |
| |
| **Model Stats:** |
| |
| |
| ## Performance Summary |
| | Model | Runtime | Precision | Chipset | Inference Time (ms) | Peak Memory Range (MB) | Primary Compute Unit |
| |---|---|---|---|---|---|--- |
| | NetVLAD | ONNX | float | Snapdragon® 8 Elite For Galaxy Mobile | 11.288 ms | 0 - 141 MB | NPU |
| | NetVLAD | ONNX | float | Qualcomm® Dragonwing™ Q-8750 | 11.288 ms | 0 - 141 MB | NPU |
| | NetVLAD | ONNX | w8a8_mixed_int16 | Snapdragon® 8 Elite For Galaxy Mobile | 3.211 ms | 0 - 144 MB | NPU |
| | NetVLAD | ONNX | w8a8_mixed_int16 | Qualcomm® Dragonwing™ Q-8750 | 3.211 ms | 0 - 144 MB | NPU |
| | NetVLAD | QNN_DLC | float | Snapdragon® 8 Elite For Galaxy Mobile | 12.49 ms | 4 - 143 MB | NPU |
| | NetVLAD | QNN_DLC | float | Qualcomm® Dragonwing™ Q-8750 | 12.49 ms | 4 - 143 MB | NPU |
| | NetVLAD | QNN_DLC | w8a8_mixed_int16 | Snapdragon® 8 Elite For Galaxy Mobile | 3.16 ms | 0 - 142 MB | NPU |
| | NetVLAD | QNN_DLC | w8a8_mixed_int16 | Qualcomm® Dragonwing™ Q-8750 | 3.16 ms | 0 - 142 MB | NPU |
| | NetVLAD | TFLITE | float | Snapdragon® 8 Elite For Galaxy Mobile | 11.272 ms | 0 - 145 MB | NPU |
| | NetVLAD | TFLITE | float | Qualcomm® Dragonwing™ Q-8750 | 11.272 ms | 0 - 145 MB | NPU |
| |
| ## License |
| * The license for the original implementation of NetVLAD can be found |
| [here](https://github.com/relja/netvlad/blob/master/LICENCE). |
| |
| ## References |
| * [NetVLAD: CNN architecture for weakly supervised place recognition](https://arxiv.org/abs/1511.07247) |
| * [Source Model Implementation](https://github.com/Nanne/pytorch-NetVlad) |
| |
| ## Community |
| * Join [our AI Hub Slack community](https://aihub.qualcomm.com/community/slack) to collaborate, post questions and learn more about on-device AI. |
| * For questions or feedback please [reach out to us](mailto:ai-hub-support@qti.qualcomm.com). |
| |