

FlexiWorld: Learning and Planning via Flexible Action Chunks Across Multiple Time Scales
Paper • 2609.35138 • Published
Paper | Project Page | Code
Shidu Ren, Qilin Gu, Zhenghao Ni, Junhan Sun, Jiaqi Wang, Damien Scieur, Yunze Liu
Official pretrained checkpoints for FlexiWorld, a JEPA-based latent world model for visual goal-directed planning. Mixed-span goal supervision and variable-length action chunks jointly train latent prediction and autoregressive action generation. The same checkpoint supports Direct, search-free action generation, and ARCEM, action-residual search with within-chunk autoregressive feedback.
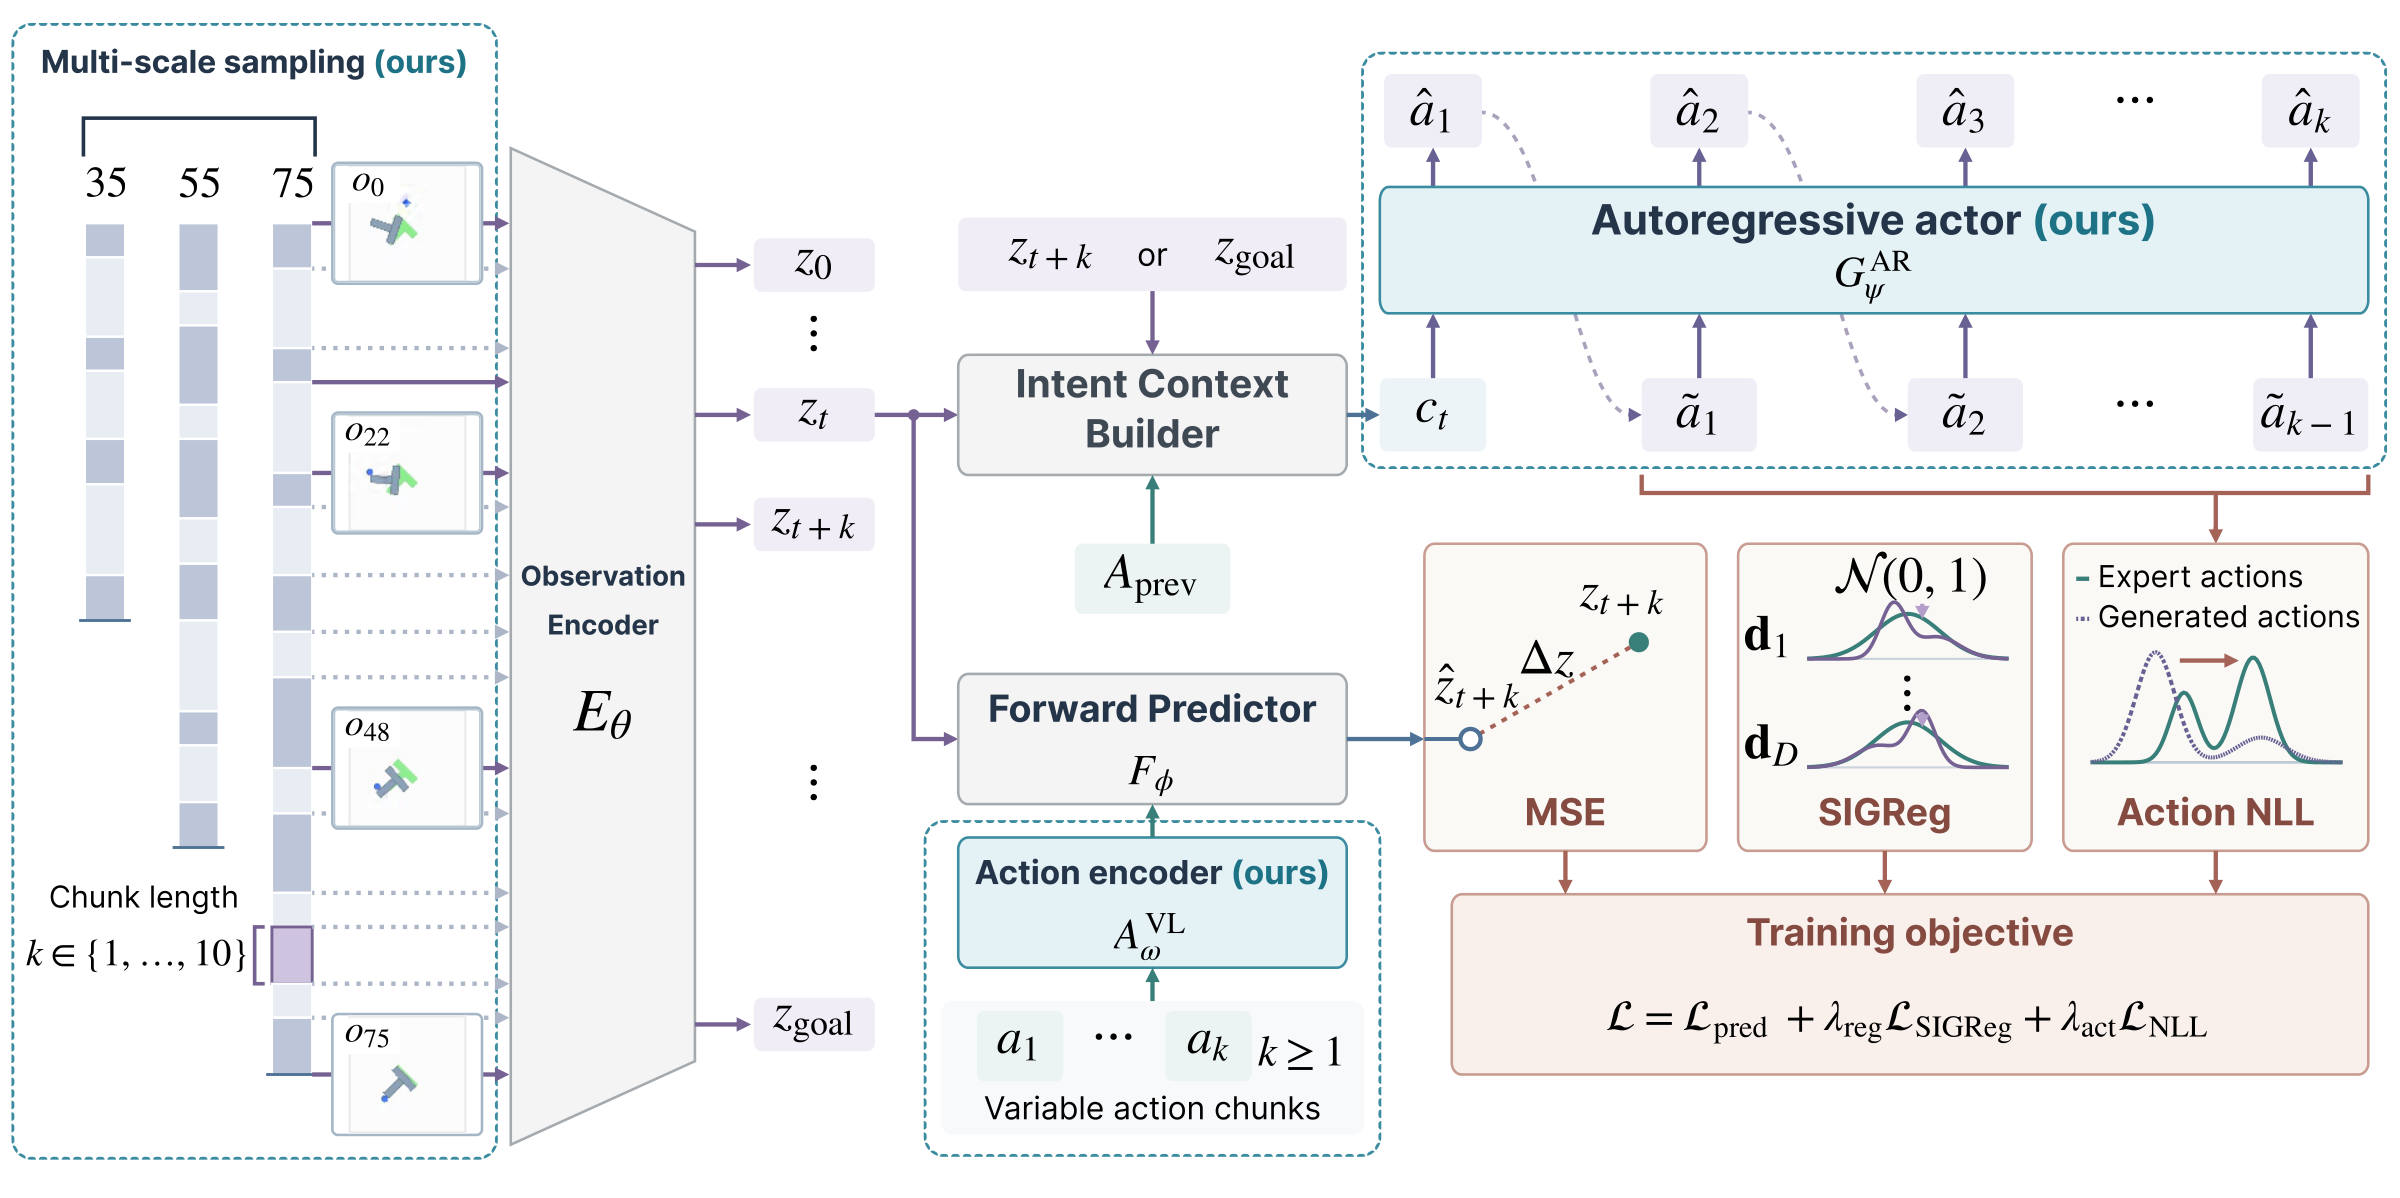
One complete model is provided for each benchmark, all trained with seed 3072. Each includes the visual encoder, latent predictor, causal action encoder, and autoregressive actor. No separate weights are needed for Direct and ARCEM.
| Benchmark | Checkpoint directory | Planners |
|---|---|---|
| PushT | pusht/seed3072 |
Direct, ARCEM |
| Cube | cube/seed3072 |
Direct, ARCEM |
| Reacher | reacher/seed3072 |
Direct, ARCEM |
| TwoRoom | tworoom/seed3072 |
Direct, ARCEM |
Each directory contains weights.pt (PyTorch state dictionary), model.yaml (Hydra model configuration), config.json (architecture metadata), and train_config.yaml (task and training metadata). Checksums are available in SHA256SUMS.
Use Linux, Python 3.12, and an NVIDIA GPU with a compatible CUDA driver. From the code repository, install the environment and download the checkpoints:
git clone https://github.com/Shidu-Ren/FlexiWorld.git
cd FlexiWorld
python3.12 -m venv .venv
source .venv/bin/activate
pip install -r requirements-env.txt
pip install huggingface_hub
hf download ryanren0330/FlexiWorld --local-dir checkpoints
For a single benchmark, replace the download command with:
hf download ryanren0330/FlexiWorld --include "pusht/seed3072/*" --local-dir checkpoints
Prepare the benchmark data following the data guide, then choose a planner:
# Search-free control
python src/eval.py --task pusht --checkpoint checkpoints/pusht/seed3072 \
  --planner direct --cache-dir ./data_cache

# Action-residual search
python src/eval.py --task pusht --checkpoint checkpoints/pusht/seed3072 \
  --planner arcem --cache-dir ./data_cache
Replace pusht and its checkpoint directory with cube, reacher, or tworoom for the other benchmarks. These checkpoints use the FlexiWorld model classes and evaluation entry point in the linked code repository.
The default evaluation covers goal distances 25, 50, 75, and 100, with 100 episodes per distance and evaluation seed, using seeds 0, 1, and 42. Add --distance 75 to evaluate a single distance.
Both planners use five-action chunks. ARCEM uses 128 candidates, three search iterations, 16 elites, and residual scale 0.2. Each episode permits one reobservation and replan after the initial execution segment.
Per-run results and summary.json are saved under results/<task>_s3072_<planner>/. The summary reports mean success and SD across evaluation seeds for the selected checkpoint. See the evaluation guide for details.
The paper reports the following mean success rates (%), averaged over four goal distances and three evaluation seeds, then over three training seeds. These are paper-level aggregates, not scores for the single released seed.
| Planner | PushT | Cube | Reacher | TwoRoom | Average |
|---|---|---|---|---|---|
| Direct | 60.39 | 91.36 | 99.06 | 96.36 | 86.79 |
| ARCEM | 68.89 | 91.94 | 99.72 | 96.61 | 89.29 |
See the paper for variability across training seeds, comparisons, and ablations, and the project page for demonstrations.
The checkpoints are released under the MIT license for research in latent world models and goal-directed control. Evaluation is in simulation on the four benchmarks; real-world robot deployment and safety-critical use have not been validated. Benchmark datasets and environments retain their respective licenses.
@misc{ren2026flexiworld,
  title={FlexiWorld: Learning and Planning via Flexible Action Chunks Across Multiple Time Scales},
  author={Shidu Ren and Qilin Gu and Zhenghao Ni and Junhan Sun and Jiaqi Wang and Damien Scieur and Yunze Liu},
  year={2026},
  eprint={2609.35138},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2609.35138}
}
Built on INTACT, LeWM, stable-worldmodel, and stable-pretraining. ARCEM builds on the action-residual search principle of POPLIN.