

File size: 4,884 Bytes
44cfb54 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 | ---
license: mit
language:
- en
library_name: pytorch
pipeline_tag: text-generation
tags:
- recurrent
- cnn
- vla
- no-attention
datasets:
- HuggingFaceFW/fineweb
- HuggingFaceTB/smollm-corpus
- HuggingFaceFV/finevideo
---
# VLA (recurrent CNN), v485
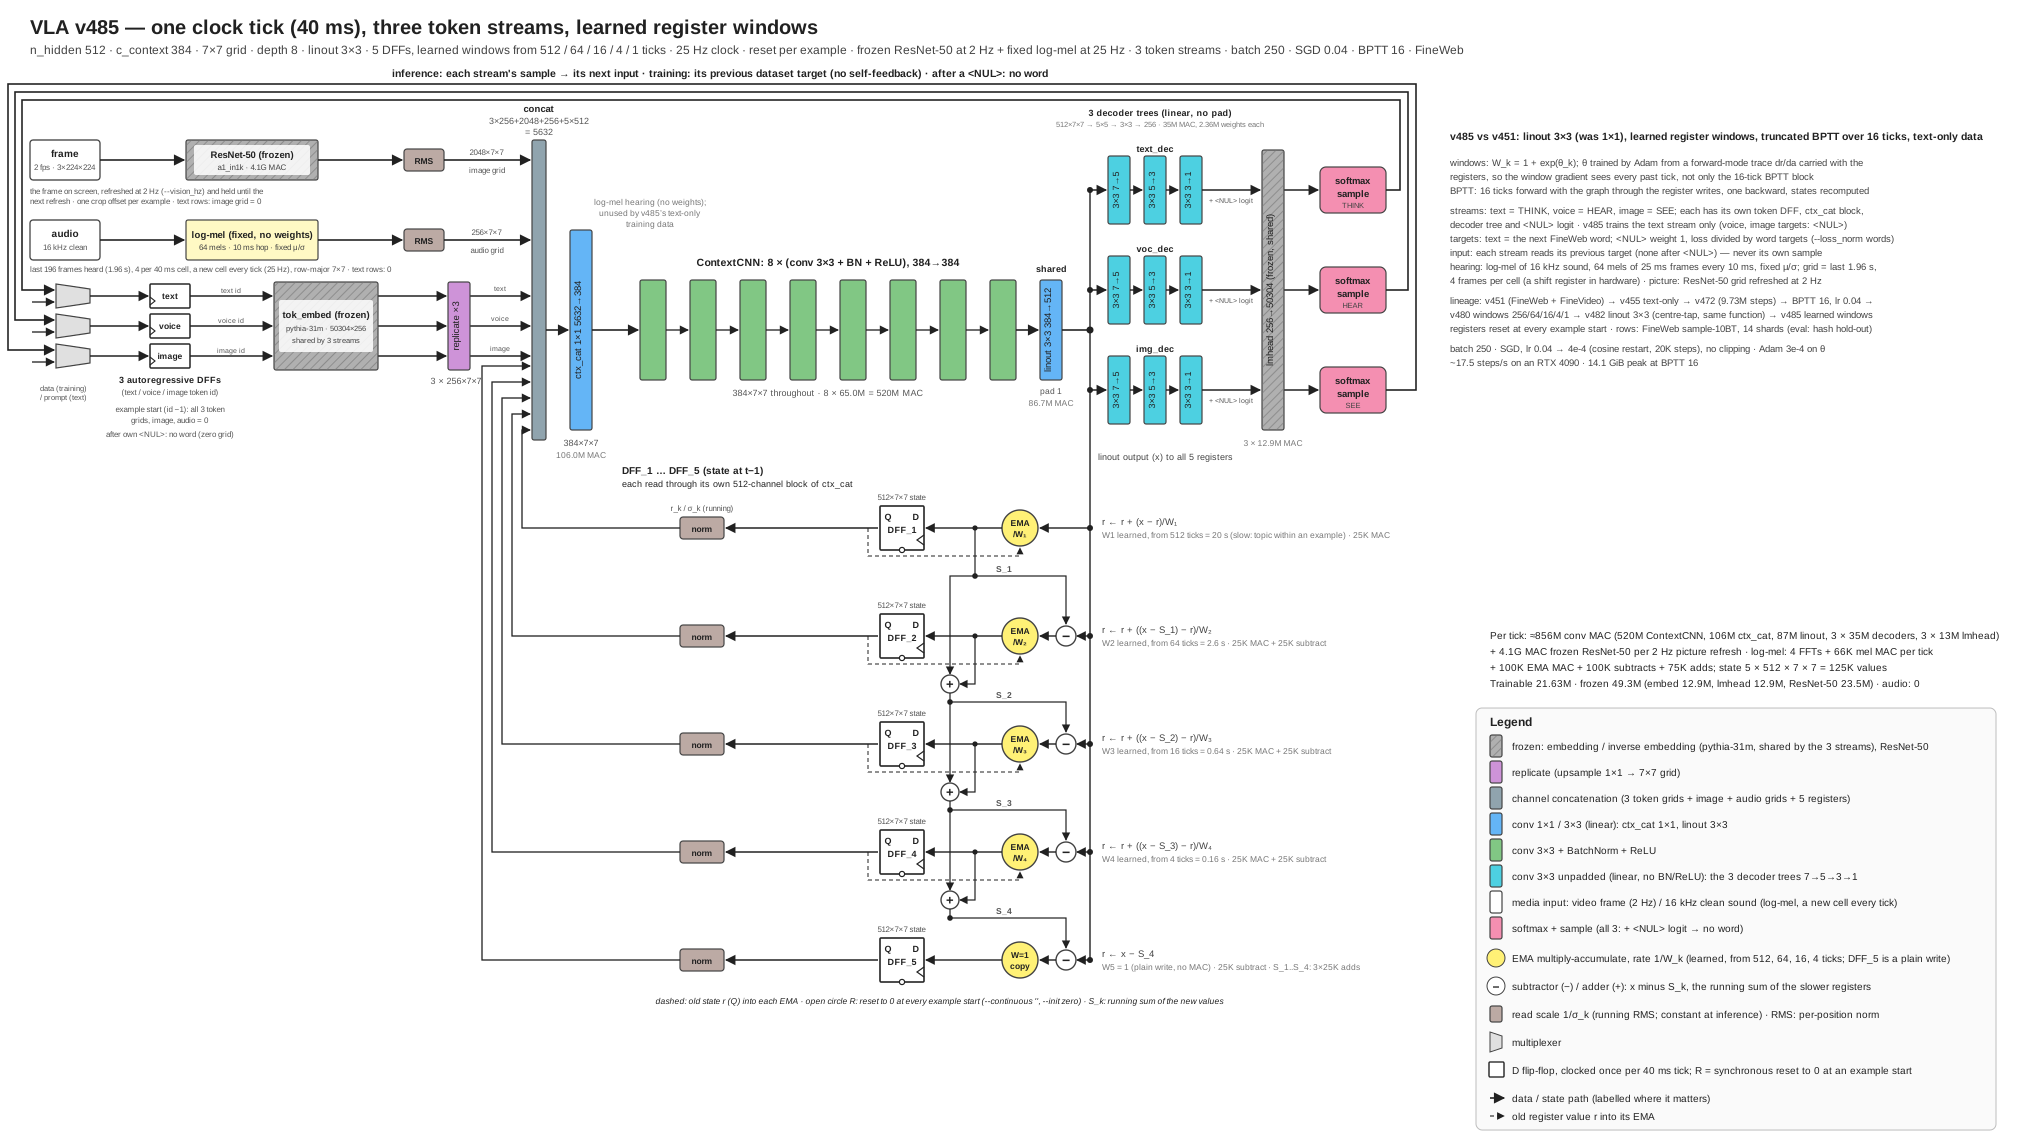
A language model with no attention and no positional encoding. Its memory is five 2-D registers of
512 × 7 × 7. Every tick, one convolutional network reads the current token together with the registers and
writes the registers back. It is the text-trained core of a vision-language-action design aimed at a single chip
running at 100 Hz or more with no external components: no off-chip memory, every weight stored on the chip. A CNN
makes that possible because it is parameter-efficient: the same small kernels run at every grid position and
every tick.
Code, functional spec and figures: [github.com/siliconperception/vla](https://github.com/siliconperception/vla)
## Use
```bash
git clone https://github.com/siliconperception/vla && cd vla && pip install -r requirements.txt
for p in "The colors of the rainbow are" \
"The best way to learn a new language is" \
"My grandmother's recipe for apple pie starts with" \
"When you plant a vegetable garden, the first thing to do is" \
"The history of the bicycle began in"; do
python vla.py --pretrained --generate --n 120 --prompt "$p" --device cuda
done
# prompt tuning: fit the starting registers (weights frozen) until the model predicts the prompt,
# then continue from them; prints the cold and the tuned continuation
python vla.py --pretrained --generate --prompt_tune 200 --n 120 --prompt "The colors of the rainbow are" --device cuda
```
`--pretrained` downloads `model.safetensors` and `vla_args.json` (the settings the weights were trained with)
and restores both. The weights are not a `transformers` model; load them through `vla.py`.
## Model
| | |
|---|---|
| Parameters | 70.9 M: 21.6 M trained, 49.3 M frozen (token embedding and output layer from pythia-31m, a ResNet-50) |
| State | 5 registers × 512 × 7 × 7 = 125,440 values |
| Register windows | learned: 530 / 57 / 15 / 3.8 / 1 ticks (21 s, 2.3 s, 0.61 s, 0.15 s and one tick at 25 Hz) |
| State update | 1×1 mix (5,632 → 384), 8 × (3×3 conv, BatchNorm, ReLU) at 384, 3×3 project (384 → 512), cascade write |
| Readout | 3 decoders (text, voice, image), each a tree of three 3×3 convs and the frozen pythia-31m output layer |
| Tokenizer | pythia-31m BPE (50,304) plus a `<NUL>` token ("say nothing this tick") |
## Training
- 10.18 M steps × 250 rows, one token per row per step, plain SGD.
- Up to step 9.73 M (run v472): learning rate cycling 1e-4 → 1e-2, the gradient stopped at the registers.
- Since then: learning rate 0.04, truncated backpropagation through time over 16 steps, the register projection
widened to 3×3 (from its 1×1 weights, the same function at the switch), and learned register windows (from
512 / 64 / 16 / 4). The windows are trained by Adam from a forward-mode sensitivity of the registers to their
rates, so their gradient sees every past step, not only the last 16.
- Data across its lineage: FineWeb-Edu (SmolLM corpus), FineWeb sample-10BT, and FineVideo and VALOR (speech,
captions and frames); text-only FineWeb in its latest phase.
## Evaluation (at the published step, 10,180,000)
| | Score |
|---|---|
| FineWeb held-out (100 documents, nats/token) | 4.527 |
| BabyLM 2026 dev (100 pieces, nats/token) | 4.518 |
| BLiMP (1,005 pairs from all 67 paradigms) | 70.1 % |
| ComVE (999 pairs, common-sense) | 66.3 % |
The BLiMP and ComVE pairs are scored the same way as for these reference models (each sentence read without
context; the lower total loss wins):
| Model | Size | BLiMP | ComVE |
|---|---|---|---|
| pythia-14m | 14 M | 69.7 | 64.7 |
| pythia-31m | 31 M | 71.1 | 66.9 |
| babyllama-10m-2024 | trained on 10 M words | 70.0 | 63.7 |
| SmolLM2-135M | 135 M | 80.9 | 79.3 |
| **this model** | 21.6 M trained | 70.1 | 66.3 |
## Limits
A small model: it writes fluent text that is often not factual or consistent. Not instruction-tuned, not safety
filtered beyond its training corpora. The voice and image decoders are present but this checkpoint was last
trained on text. Training is continuing; this card describes the step above.
## License
MIT, Copyright (c) 2024-2026 Silicon Perception Inc. The license covers the software and these weights and grants
no patent rights; see [PATENTS](https://github.com/siliconperception/vla/blob/main/PATENTS). Frozen third-party
weights inside: EleutherAI [pythia-31m](https://huggingface.co/EleutherAI/pythia-31m) embedding and output
layer (Apache-2.0), [timm/resnet50.a1_in1k](https://huggingface.co/timm/resnet50.a1_in1k) (Apache-2.0).
|