| --- |
| license: cc-by-nc-4.0 |
| pipeline_tag: text-to-3d |
| tags: |
| - 4d-generation |
| - gaussian-splatting |
| - 4d-gaussian-splatting |
| - world-model |
| - video-diffusion |
| - image-to-3d |
| - wan2.1 |
| - neurips-2026 |
| --- |
| |
| <div align="center"> |
|
|
| # AEON: Unifying Video and 3D World Models |
|
|
| ### NeurIPS 2026 |
|
|
| [Weiqi Zhang](https://weiqi-zhang.github.io/), [Wenyuan Zhang](https://wen-yuan-zhang.github.io/), [Yu-Shen Liu](https://yushen-liu.github.io/)<sup>†</sup>, [Junsheng Zhou](https://junshengzhou.github.io/)<sup>†</sup> |
|
|
| School of Software, Tsinghua University · <sup>†</sup> Corresponding authors |
|
|
| [**Paper**](https://huggingface.co/papers/2610.28631) | [**Project Page**](https://weiqi-zhang.github.io/AEON/) | [**Code**](https://github.com/weiqi-zhang/AEON) |
|
|
| </div> |
|
|
|  |
|
|
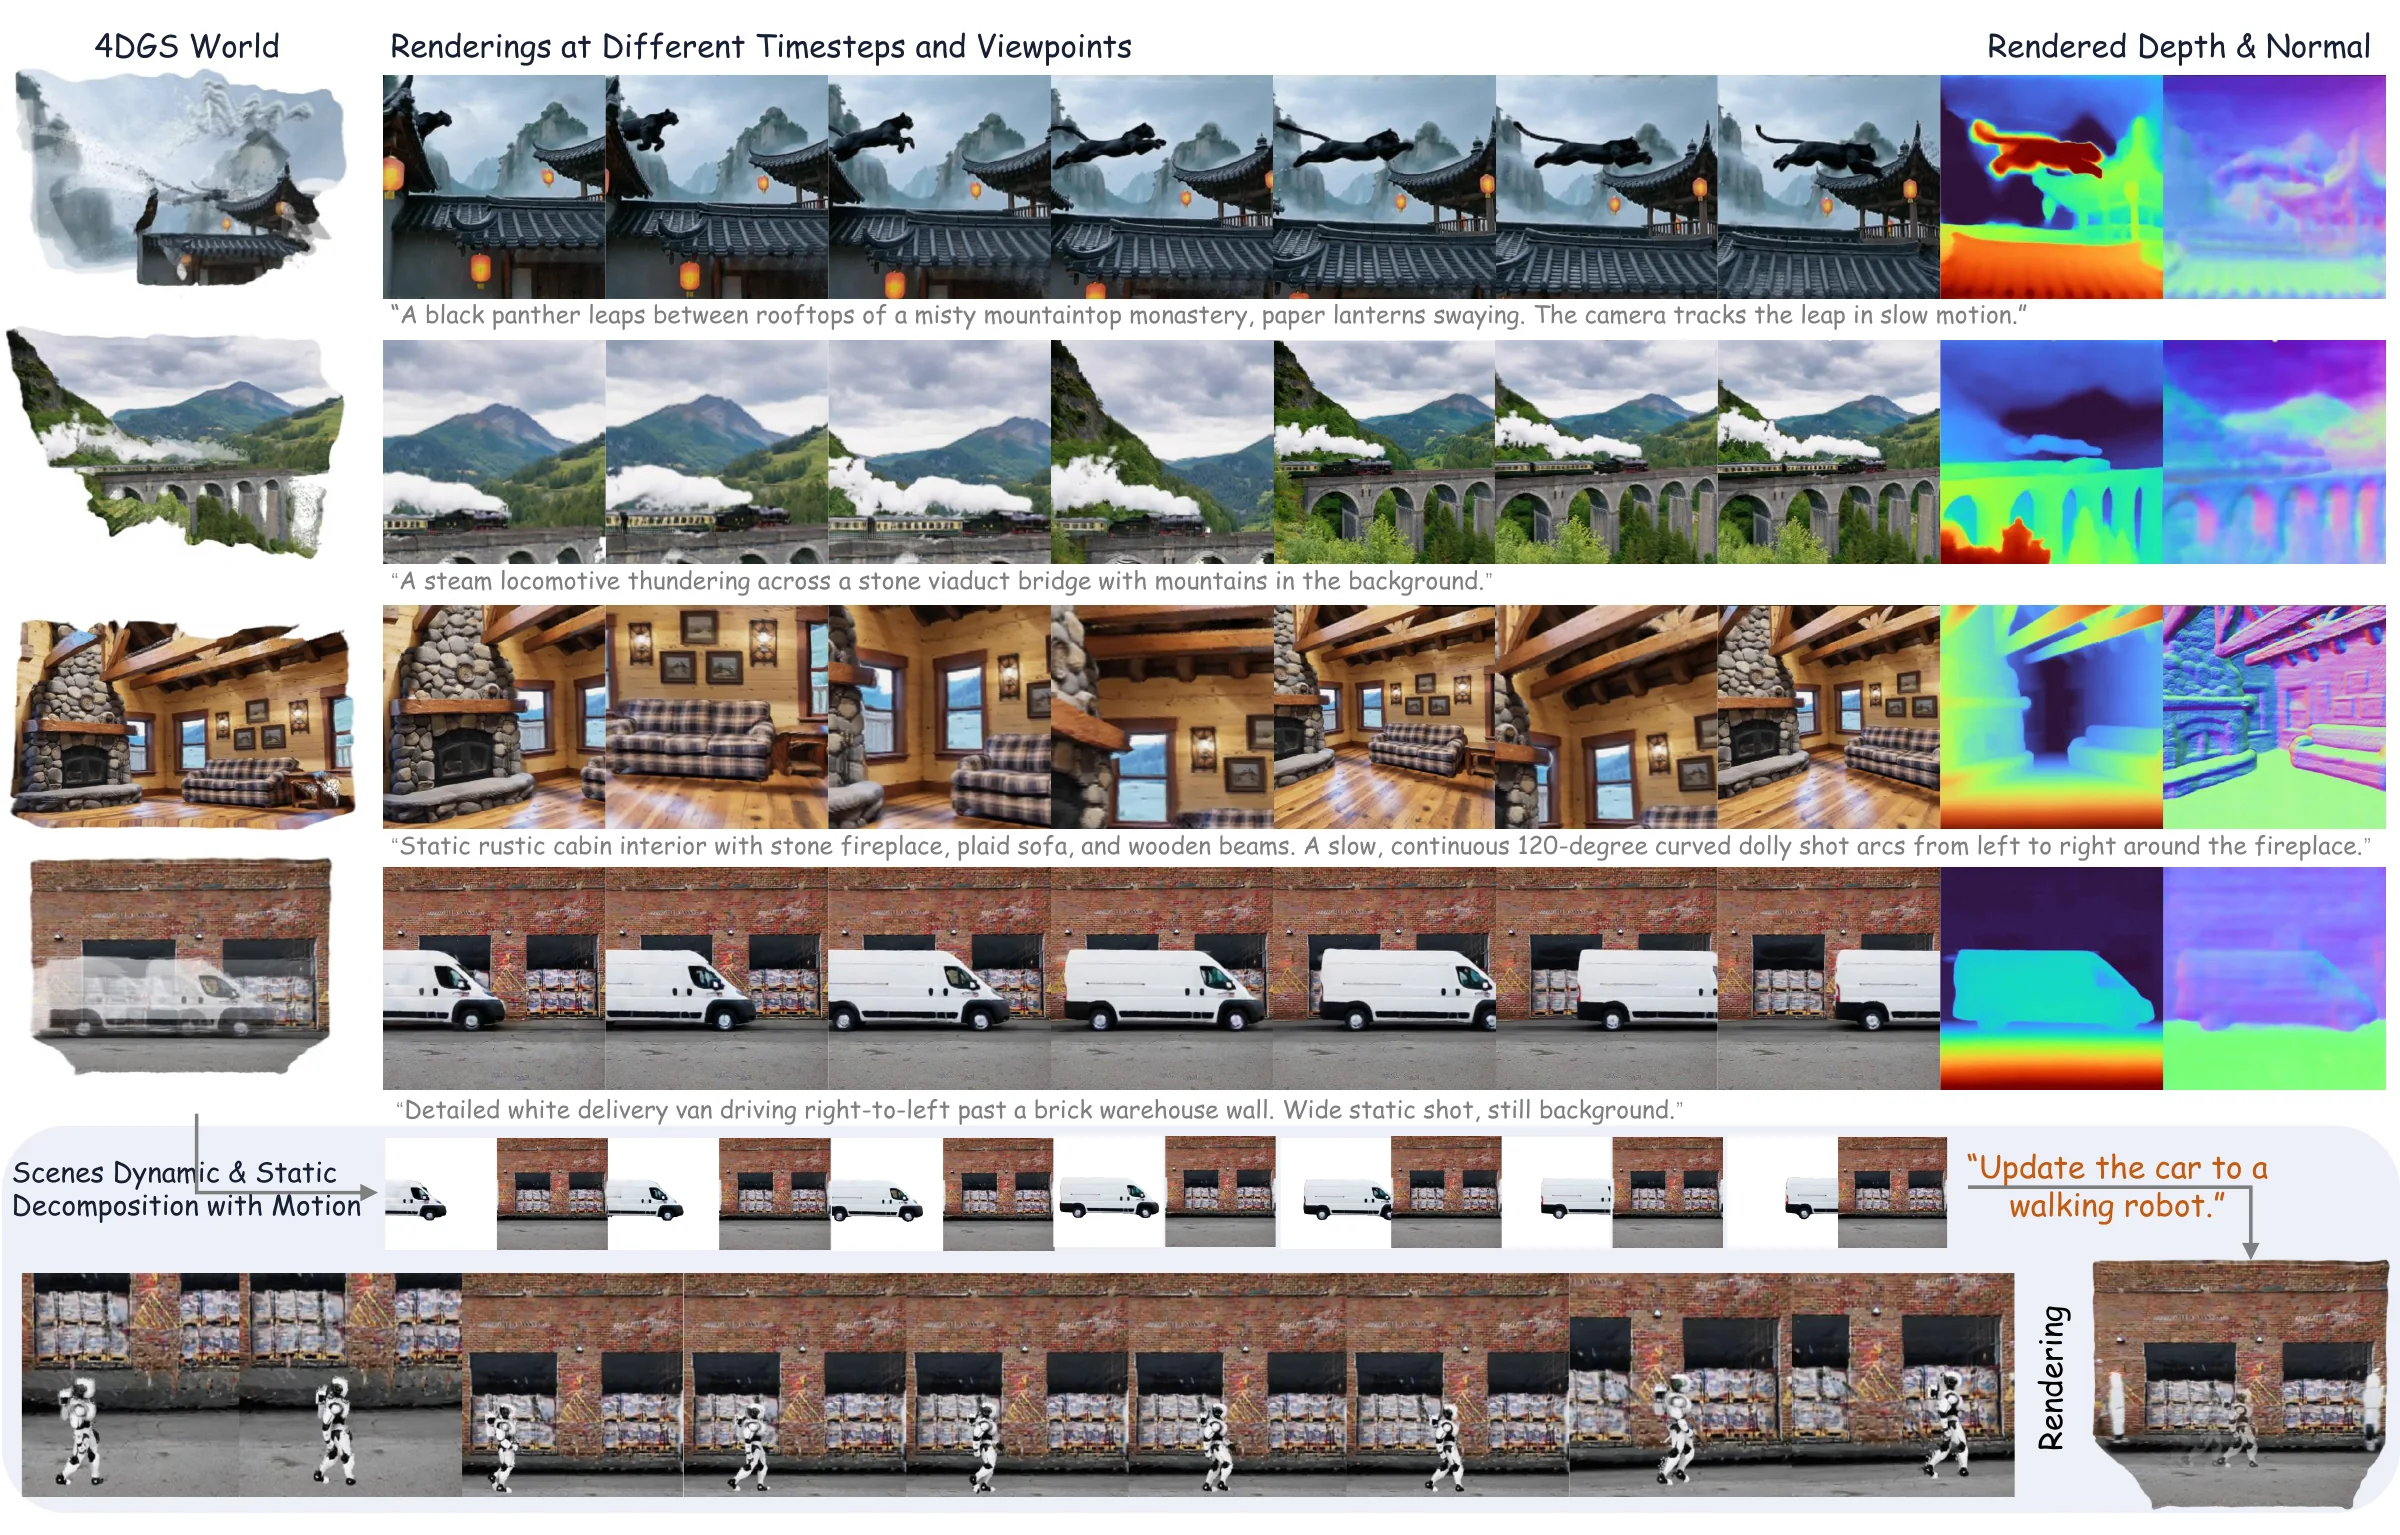
| AEON ([paper](https://huggingface.co/papers/2610.28631)) is a generative world model that unifies video-based and 3D-based world models. It works in the latent space |
| of a pretrained video diffusion model and produces an explicit **4D Gaussian Splatting (4DGS)** world together with |
| its camera trajectory. The 4DGS world can be rendered in real time at any timestep and from new viewpoints, and it |
| can be edited or used for simulation. |
|
|
| This repository hosts the weights of the **AEON decoder**. The inference code is on |
| [GitHub](https://github.com/weiqi-zhang/AEON), and more generated worlds, with videos, are on the |
| [project page](https://weiqi-zhang.github.io/AEON/#worlds). |
|
|
| ## Model details |
|
|
| | | | |
| |---|---| |
| | File | `aeon.safetensors`: 3.26 GB, float32, about 812M parameters | |
| | Components | domain adapter, a Conv3D + Perceiver bridge (`stitching_layer.*`), and student 4D Gaussian Reconstruction Model, 4DRM (`stitched_4d_model.*`) | |
| | 4DRM backbone | DINOv2-Large encoder and an alternating-attention multi-view transformer, adapted from MapAnything | |
| | Input | a Wan2.1 video latent, and the frames the Wan VAE decodes from it | |
| | Output | per-pixel 4D Gaussians and per-frame cameras | |
| | Video models | [Wan2.1-T2V-1.3B](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B-Diffusers) for text-to-4DGS, [Wan2.1-I2V-14B-480P](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P-Diffusers) for image-to-4DGS | |
|
|
| The Wan2.1 models stay frozen and are not included in this repository. Both share the same VAE, so the same decoder |
| serves both pipelines. |
|
|
| ## Method |
|
|
|  |
|
|
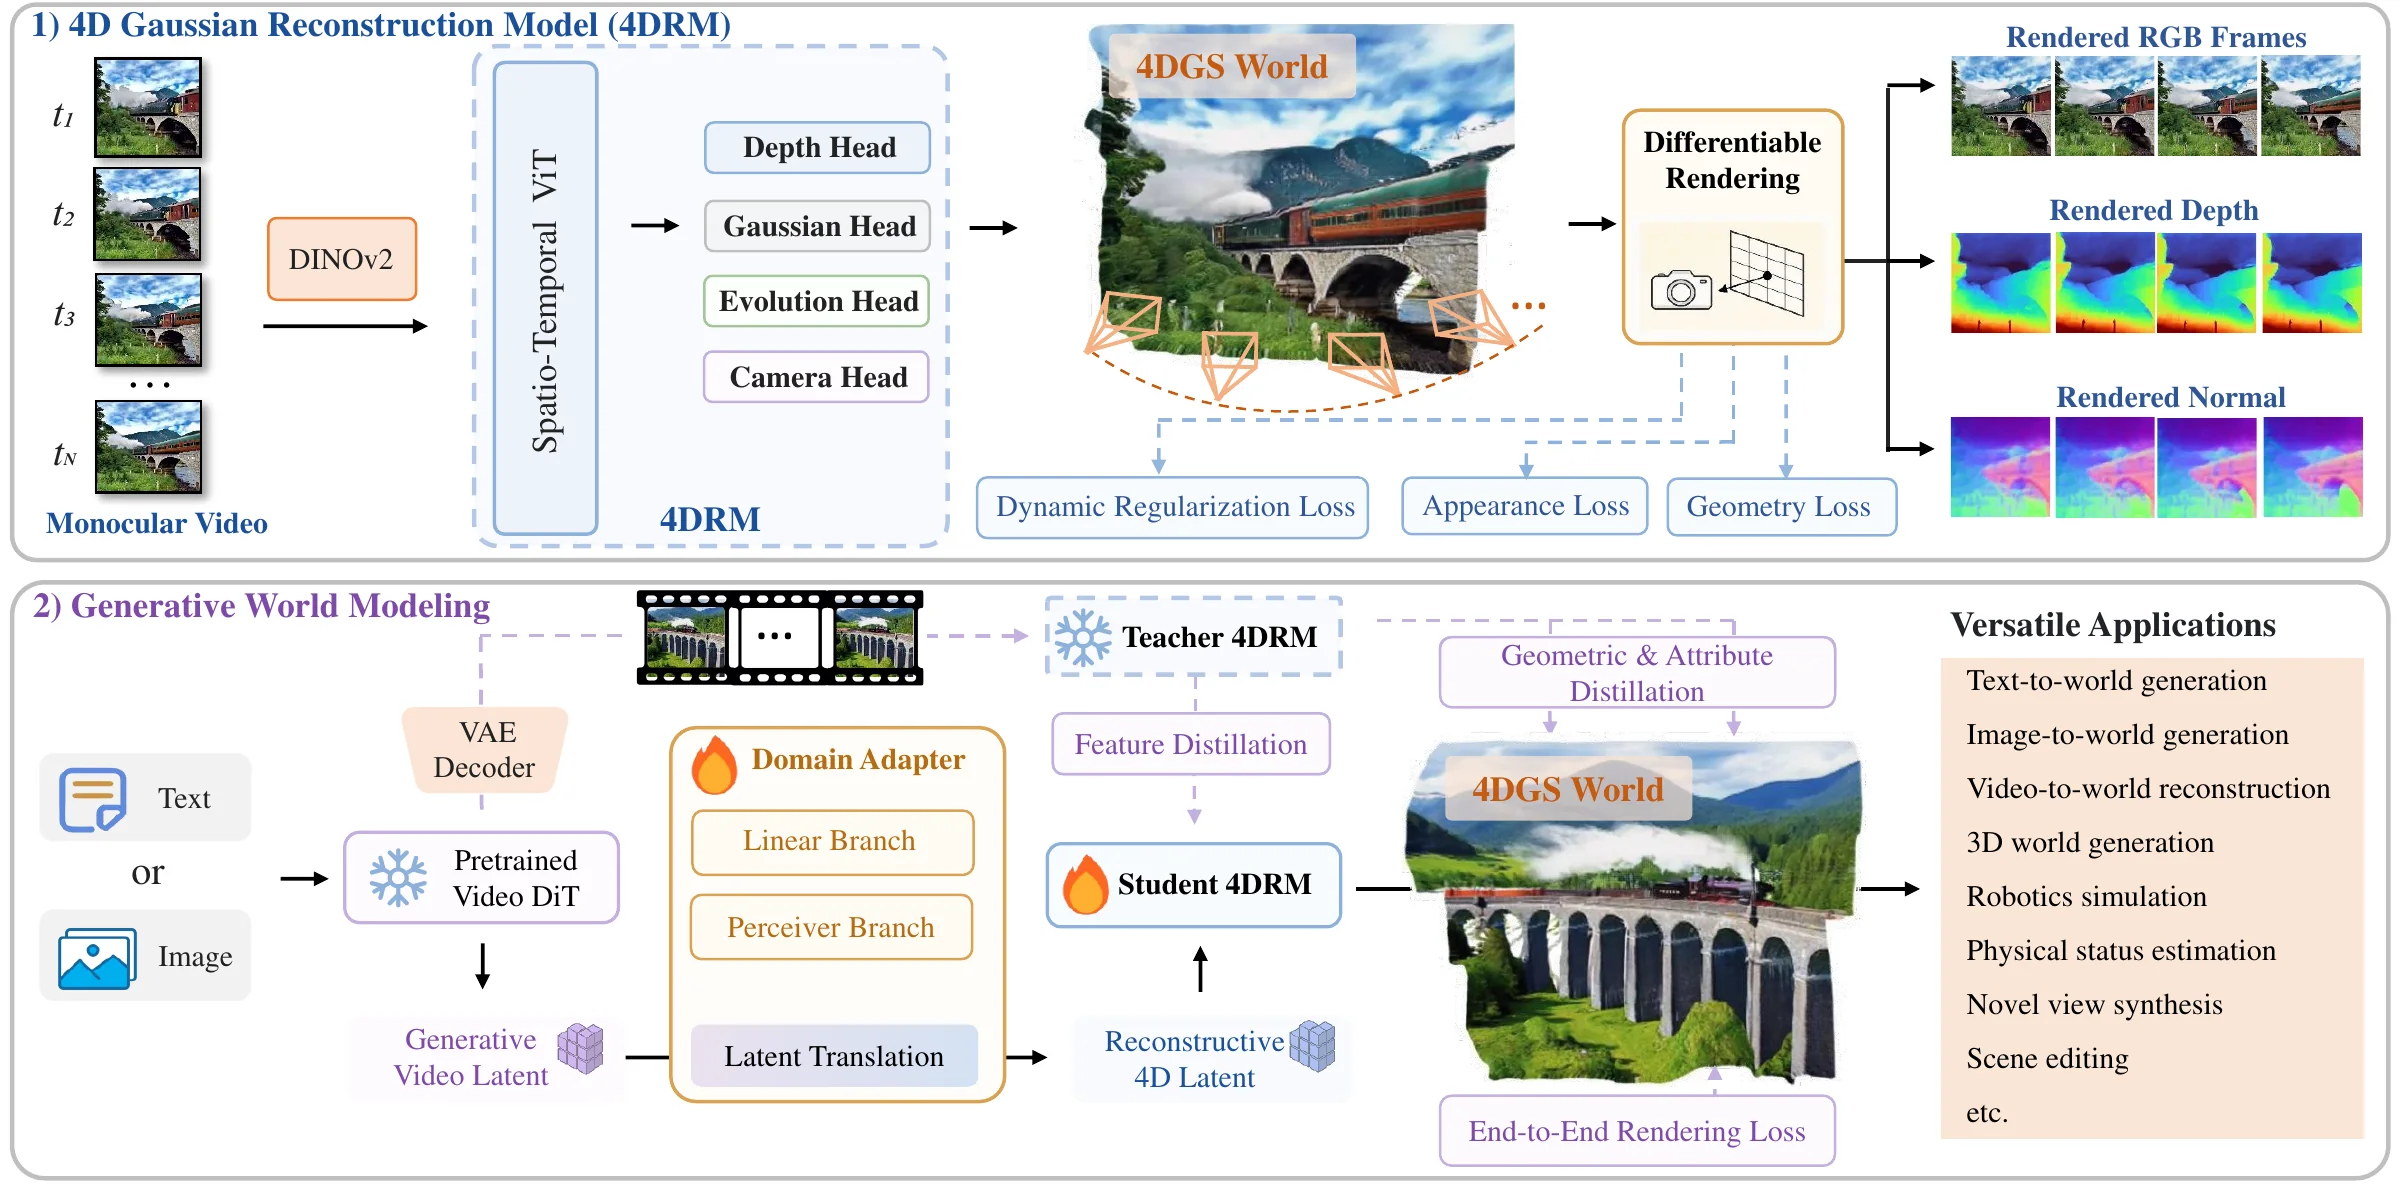
| A 4D Gaussian Reconstruction Model (4DRM) first learns to recover a 4DGS world from monocular video. AEON then |
| connects a frozen video diffusion model to this reconstruction model through a domain adapter, which translates |
| generative video latents into reconstructive 4D latents. The adapter and a student 4DRM are trained by distillation, |
| so a generated video latent can be decoded directly into 4D Gaussians. |
|
|
| At inference time: |
|
|
| 1. Wan2.1 generates a video latent from the prompt (and the image, for I2V). The Wan VAE decodes it into frames. |
| 2. The domain adapter and the student 4DRM map the latent to per-pixel 4D Gaussians and per-frame cameras. |
| 3. The Gaussians are rasterized with gsplat along the predicted cameras and, optionally, along a spiral novel-view |
| path. |
|
|
| ## Usage |
|
|
| Requirements: Python 3.10 or newer, a CUDA GPU, PyTorch built for your CUDA version, and the CUDA toolkit (`nvcc`) |
| and `ninja` on `PATH`. gsplat compiles its CUDA kernels the first time it runs. |
|
|
| ```bash |
| git clone https://github.com/weiqi-zhang/AEON.git |
| cd AEON |
| pip install -r requirements.txt |
| pip install -e . |
| |
| # AEON decoder -> weights/aeon.safetensors, where the default config looks for it |
| huggingface-cli download wiki1231/AEON aeon.safetensors --local-dir weights |
| |
| # Text -> 4DGS, plus a spiral novel-view video and an export of the Gaussians |
| aeon-generate --prompt "A red fox running through deep snow, slow motion" --spiral --save_4dgs |
| |
| # Image + text -> 4DGS with the 14B model (--cpu_offload keeps GPU memory around 50 GB) |
| aeon-generate --pipeline i2v --image ref.png --prompt "The cat walks to the window" --cpu_offload |
| ``` |
|
|
| The Wan2.1 models are loaded by their Hugging Face ids; pass `--wan_model` to use a local copy. Each sample writes |
| the generated video, RGB / depth / normal renders of the 4DGS world and, with `--save_4dgs` or `--save_3dgs`, the |
| Gaussians themselves (a static, Inria-format `point_cloud.ply` for standard 3DGS viewers in the latter case). Run |
| `aeon-generate -h` for all options. |
|
|
| From Python: |
|
|
| ```python |
| import torch |
| from huggingface_hub import hf_hub_download |
| from aeon4d.pipeline import (DEFAULT_CONFIG, denoise_video_latents, load_aeon, load_config, |
| load_wan_pipeline, reconstruct_4dgs, zero_dxyzt_) |
| from aeon4d.rendering import render_4dgs |
| |
| config = load_config(DEFAULT_CONFIG) |
| device = torch.device("cuda:0") |
| torch.manual_seed(42) |
| pipe = load_wan_pipeline("Wan-AI/Wan2.1-T2V-1.3B-Diffusers", "t2v", flow_shift=3.0, device=device) |
| model = load_aeon(config, hf_hub_download("wiki1231/AEON", "aeon.safetensors"), device) |
| |
| latents = denoise_video_latents(pipe, "A red fox running through deep snow", height=512, width=512, |
| num_frames=81, num_inference_steps=50, guidance_scale=5.0, |
| negative_prompt="Blurred, artifacts, low quality, distorted, deformed") |
| video, views, res, gs_params = reconstruct_4dgs(model, pipe.vae, latents, vae_resolution=512, |
| ff_resolution=448, device=device) |
| zero_dxyzt_(gs_params) |
| render = render_4dgs(gs_params, res, device, render_h=448, render_w=448, fix_k_mode="none") |
| ``` |
|
|
| ## Resource usage |
|
|
| - **T2V-1.3B:** about 60 GB of GPU memory at peak. |
| - **I2V-14B with** `--cpu_offload`**:** about 50 GB. Without offload, it needs roughly 90 GB. |
| - **Speed:** a sample with the 14B model takes about 5–8× longer than one with the 1.3B model. |
|
|
| Tested with PyTorch 2.13 + CUDA 13.0 on Python 3.12. |
|
|
| ## Citation |
|
|
| ```bibtex |
| @inproceedings{zhang2026aeon, |
| title={{AEON}: Unifying Video and {3D} World Models}, |
| author={Zhang, Weiqi and Zhang, Wenyuan and Liu, Yu-Shen and Zhou, Junsheng}, |
| booktitle={Advances in Neural Information Processing Systems (NeurIPS)}, |
| year={2026} |
| } |
| ``` |
|
|
| ## Acknowledgements |
|
|
| AEON builds on [Wan2.1](https://github.com/Wan-Video/Wan2.1), |
| [MapAnything](https://github.com/facebookresearch/map-anything), [UniCeption](https://github.com/castacks/UniCeption), |
| [DINOv2](https://github.com/facebookresearch/dinov2), [EasyVolcap](https://github.com/zju3dv/EasyVolcap), |
| [diffusers](https://github.com/huggingface/diffusers) and [gsplat](https://github.com/nerfstudio-project/gsplat). |
| We thank their authors for releasing their code and models. |
|
|
| ## License |
|
|
| The weights in this repository are released under the [CC BY-NC 4.0](https://creativecommons.org/licenses/by-nc/4.0/) |
| license and may be used for non-commercial research only: the 4DRM is initialized from |
| [MapAnything](https://github.com/facebookresearch/map-anything) weights, and the training data include datasets |
| licensed for non-commercial research only, such as DynamicReplica and Panda-70M. |
|
|
| The AEON inference code is released under the [MIT License](https://github.com/weiqi-zhang/AEON/blob/main/LICENSE). |
| The third-party code it includes keeps its original licenses, listed in |
| [THIRD_PARTY_NOTICES.md](https://github.com/weiqi-zhang/AEON/blob/main/THIRD_PARTY_NOTICES.md). The Wan2.1 models |
| are distributed by their authors under the Apache-2.0 license. |


