
Datasets:

license: mit
pretty_name: EC²-Bench (EC2-Bench)
language:
  - en
  - zh
size_categories:
  - n<1K
task_categories:
  - text-generation
tags:
  - agents
  - llm-agents
  - benchmark
  - edge-cloud-collaboration
  - edge-ai
  - on-device
  - llm-routing
  - privacy
  - openclaw
configs:
  - config_name: default
    data_files:
      - split: test
        path: data/tasks.jsonl
EC²-Bench (EC2-Bench)
Empowering Edge Agents: A Systematic Analysis of Edge-Cloud Collaboration in LLM Agent Execution
📄 Paper (arXiv 2610.17816) · 💻 Code (GitHub) · 🌐 Project Page
EC2-Bench is a benchmark for edge-cloud collaboration in long-horizon LLM agents, jointly measuring task performance, resource usage and privacy exposure.
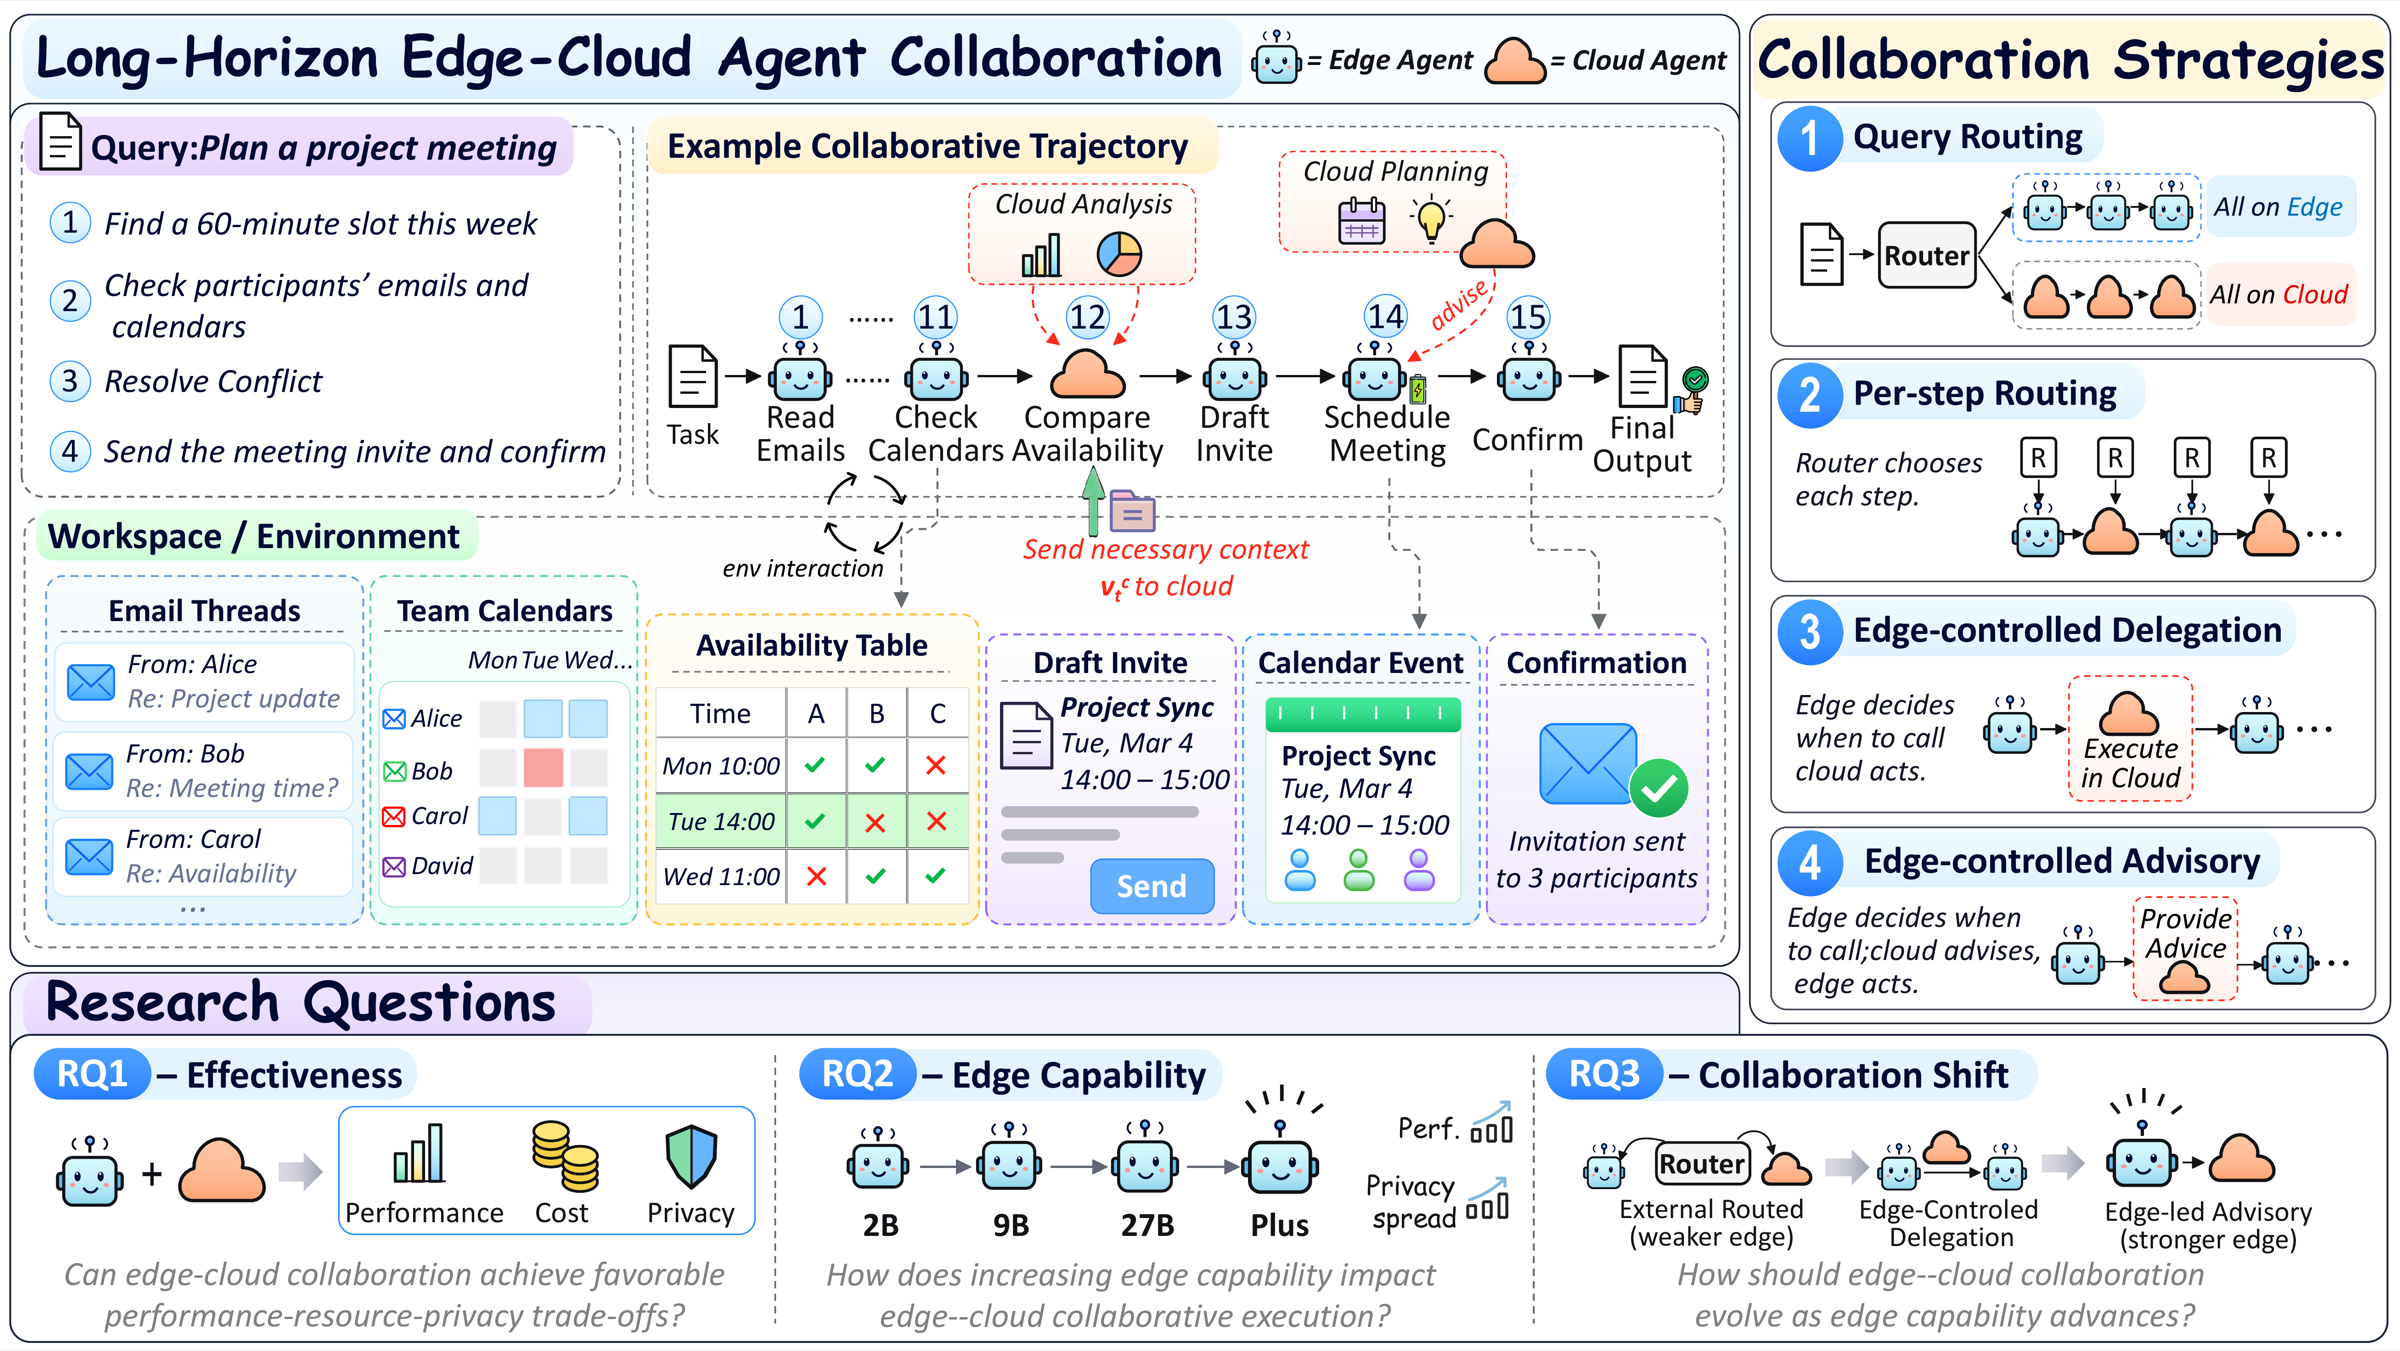
Edge-side models keep data local and cost little, but are weak at demanding planning and tool use. Cloud-hosted frontier models are far more capable, but expensive, and they see everything they are sent. In long-horizon agent execution, cloud participation is no longer a one-shot routing decision per query: it is interleaved throughout the trajectory, so every cloud call shapes later steps, accumulates cost, and decides how much workspace information leaves the device.
What is in this dataset
| Path | What it is |
|---|---|
data/tasks.jsonl |
Index of all 128 tasks (shown in the viewer above): prompt, expected behavior, grading criteria, category, source benchmark, language, and the number of annotated sensitivity units |
workspace/ACE_Bench.tar.gz |
All task workspaces in one tarball (files, mock services, and privacy ground truth under gt/sensitive_items.json) |
workspace/ACE_Bench/ |
The same workspaces, unpacked, for browsing |
Images/acebench-openclaw-v1.0.tar.gz |
Prebuilt Docker image (docker save tarball) bundling the OpenClaw harness and per-task mock services |
The executable task definitions (with inline grade() verifiers) and the evaluation code live in the GitHub repo. Task IDs keep the benchmark's earlier working name (ACE_Bench).
At a glance
- 128 executable digital-workspace tasks in 6 categories (office & daily tasks, information search, safety & security, development & operations, data analysis, automation), in English and Chinese.
- 100 tasks with fine-grained privacy annotations: 3,385 sensitivity units covering personal and organizational information.
- Tasks are adapted from Claw-Eval, WildClawBench, QwenClawBench, LiveClawBench, PinchBench and ClawBench, plus 7 newly curated tasks, and standardized to one OpenClaw runtime.
Evaluation axes
- Task performance: weighted completion score (rule-based checks, environment-state auditing, rubric-based LLM judge) and Pass³.
- Resource usage: cloud input / cache-read / output tokens with USD cost, plus edge-side FLOPs.
- Privacy exposure: fraction of annotated sensitivity units that become visible to the cloud anywhere along the trajectory (lower is better).
Four collaboration strategies are studied: Query Routing, Per-step Routing, Edge-controlled Delegation and Edge-controlled Advisory, against edge-only and cloud-only baselines.
Quick start
# task workspaces
hf download chengpingan/EC2-Bench workspace/ACE_Bench.tar.gz --repo-type dataset --local-dir .
tar -xzf workspace/ACE_Bench.tar.gz

# prebuilt Docker image (Hugging Face is not a Docker registry: download, then docker load)
hf download chengpingan/EC2-Bench Images/acebench-openclaw-v1.0.tar.gz --repo-type dataset --local-dir .
docker load -i Images/acebench-openclaw-v1.0.tar.gz
from datasets import load_dataset
tasks = load_dataset("chengpingan/EC2-Bench", split="test")
See the GitHub README for running edge-only, cloud-only and collaborative agents and for grading.
Key findings
- Collaboration works for long-horizon agents. Partial cloud participation improves on edge-only execution at a fraction of cloud-only cost and exposure.
- Stronger edges close the performance gap, not the privacy gap. As the edge model gets stronger, completion differences across strategies shrink, while privacy exposure stays strongly strategy-dependent.
- The best collaboration mode shifts with edge capability, from external routing and direct cloud execution toward edge-controlled invocation and cloud advisory. Deciding when to invoke the cloud and following cloud guidance are the two edge-side abilities that matter.
Full results: paper and leaderboard.
Citation
@article{huang2026ec2bench,
  title   = {Empowering Edge Agents: A Systematic Analysis of Edge-Cloud Collaboration in LLM Agent Execution},
  author  = {Huang, Pengcheng and Liu, Zhenghao and Ren, Shixin and Yu, Shi and Yao, Sijia and Yan, Yukun and Xiao, Chaojun and Sun, Maosong},
  journal = {arXiv preprint arXiv:2610.17816},
  year    = {2026}
}
License
MIT, same as the code repository. Adapted tasks are used under the licenses of their source benchmarks: Claw-Eval, WildClawBench, QwenClawBench, LiveClawBench and PinchBench are MIT-licensed, and ClawBench is Apache-2.0.