
Datasets:

license: cc-by-4.0
pretty_name: 'Receipts: do the tests in a fix catch the bug?'
language:
  - en
tags:
  - code
  - testing
  - software-engineering
  - ai-agents
  - coding-agents
  - claude
  - claude-code
  - agent-skills
  - pull-requests
  - red-green
  - tdd
size_categories:
  - n<1K
task_categories:
  - text-classification
configs:
  - config_name: changes
    data_files: data/changes.jsonl
    default: true
  - config_name: tests
    data_files: data/tests.jsonl
Receipts study: do the tests in a fix catch the bug?
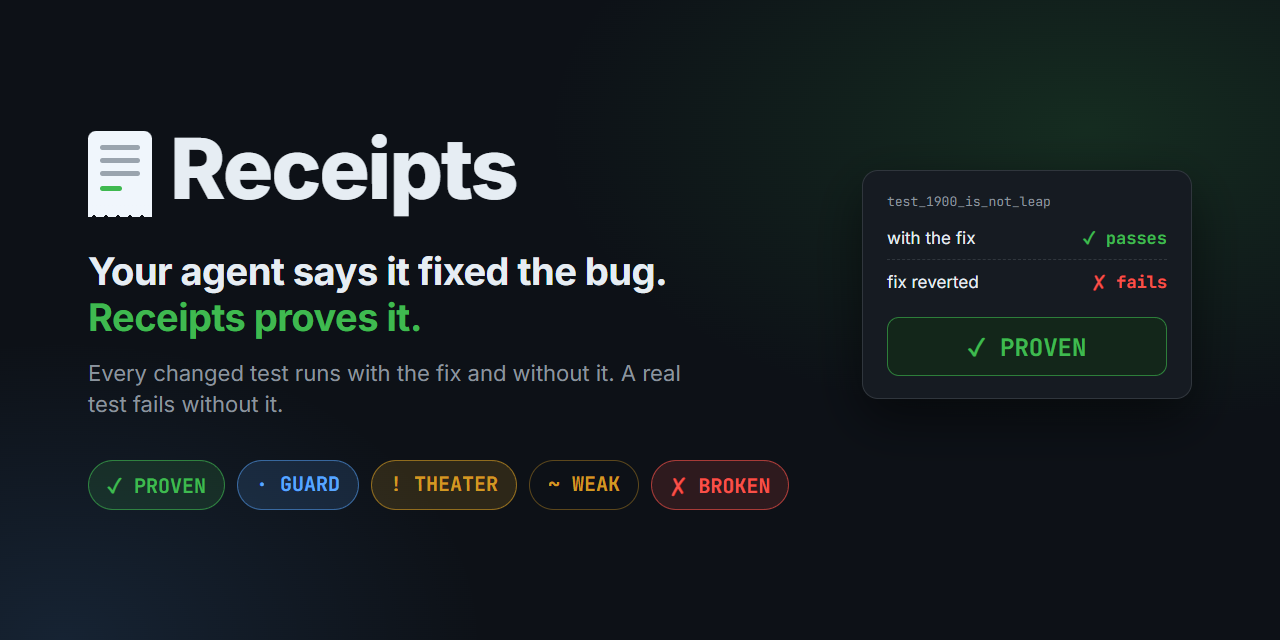
181 real code changes from 17 open-source repositories. For each one, every test the change added or edited was run twice: with the change, and with the changed source files reverted to the parent commit or the pull request's merge base. A test for a fix should fail without it.
Made with Receipts, which does this check for any pull request (CLI, GitHub Action, and a skill for Claude Code and other coding agents).
Try it on your own branch, nothing to install: npx github:syntaxixr/receipts check
Results
| Changes | Judged | Proven | Mixed | Unproven | Weak only | |
|---|---|---|---|---|---|---|
| Maintainer fix commits | 81 | 71 | 64 (90%) | 2 (3%) | 5 (7%) | 0 (0%) |
| Agent pull requests | 100 | 91 | 75 (82%) | 5 (5%) | 2 (2%) | 9 (10%) |
Percentages are of judged changes. The gap that shows up only in agent work is weak only: every test fails on the old code just because it imports a name the change adds, so no test ever runs against the old behavior. No maintainer commit had that shape.
Configurations
changes(default): one row per change.groupismaintainer(fix commits on the default branch) oragent(pull requests whose commits carry a coding agent's fingerprint: Claude Code, Codex, Cursor, Copilot).outcomeisproven,mixed,unproven,weak, orenvwhen the tests could not be judged in this environment. The verdict columns count the change's tests per verdict.tests: one row per judged test, with its verdict and the raw outcomes with and without the change (with_change,without_change; failures were re-run to spot flakes).
Verdicts
| Verdict | With the change | Without it | Meaning |
|---|---|---|---|
| PROVEN | passes | fails | The test catches what the change fixes |
| GUARD | passes | passes | Guards neighboring behavior next to a PROVEN test |
| THEATER | passes | passes | No test proves the change |
| WEAK | passes | fails on import | The code it calls did not exist yet |
| BROKEN | fails | The change does not pass its own test | |
| FLAKY | mixed | mixed | Different results on the same code |
| SKIPPED | skipped | The test did not run | |
| PRESERVED / CHANGED | For behavior-preserving changes: passes on both sides / fails on the old code |
Method and caveats
Maintainer sample: recent single-parent commits on the default branch whose message mentions a fix, a bug or an issue, and that change both code and tests (click, itsdangerous, markupsafe, sqlparse, humanize, marshmallow, more-itertools, tomlkit, dateutil, dayjs, ufo, defu). Agent sample: up to 20 pull requests per repository, newest first, open and closed alike (anthropics/claude-agent-sdk-python, openai/openai-agents-python, PrefectHQ/fastmcp, modelcontextprotocol/python-sdk, simonw/llm).
Each project was installed once at the tip of its default branch, so older changes can fail for environmental reasons; those are env and excluded from the percentages. The samples are small and not random: the numbers describe these projects, not the ecosystem. "Agent-authored" means an agent's fingerprint appears in the PR's commits; humans steer those agents. Full method: docs/study.md. Scripts to reproduce: study/.
License
The data (verdicts, test ids, commit subjects and links) is released under CC BY 4.0. The code it describes belongs to its projects under their own licenses.