Diffusers documentation
IP-Adapter
IP-Adapter
IP-Adapter, metin komutunu korurken bir referans görüntü ile önceden eğitilmiş bir difüzyon modelini yönlendirir. Temel modeli dondurur ve küçük bir görüntü çapraz dikkat katmanı seti ekler; bu da ince ayar yapmadan bir fotoğraftaki konuyu veya stili eşleştirmek için pratik hale getirir.
text prompt                         reference image
    |                                     |
 text encoder                        image encoder
    |                                     |
    v                                     v
 text cross-attn  (frozen)          IP-Adapter cross-attn
    \                                     /
     \                                   /
      +-------->  denoiser  <-----------+
                  (frozen base)
IP-Adapter checkpoint'ları genellikle ~100MB'dır çünkü tam bir model değil, adaptör ağırlıklarını saklar. Önce bir temel pipeline yükleyin, ardından adaptörü load_ip_adapter() ile yükleyin.
IP-Adapters, Flux ve Stable Diffusion 3 gibi birçok modelde kullanılabilir. Bu kılavuzdaki örnekler Stable Diffusion ve Stable Diffusion XL kullanır.
IP-Adapter'ın üretimi ne kadar güçlü yönlendirdiğini kontrol etmek için set_ip_adapter_scale() kullanın. 1.0 adaptörü tam güçle uygular; 0.5 genellikle metin ve görsel istemleri dengeler.
Aşağıdaki örnekler, IP-Adapter'ın yaygın görevlerde kullanımını göstermektedir.
import torch
from diffusers import AutoPipelineForText2Image
from diffusers.utils import load_image

pipeline = AutoPipelineForText2Image.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name="ip-adapter_sdxl.bin"
)
pipeline.set_ip_adapter_scale(0.8)
Bir görüntüyü ip_adapter_image parametresine, metin istemcisiyle birlikte iletin ve bir görüntü oluşturun.
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_diner.png")
pipeline(
    prompt="a polar bear sitting in a chair drinking a milkshake",
    ip_adapter_image=image,
    negative_prompt="deformed, ugly, wrong proportion, low res, bad anatomy, worst quality, low quality",
).images[0]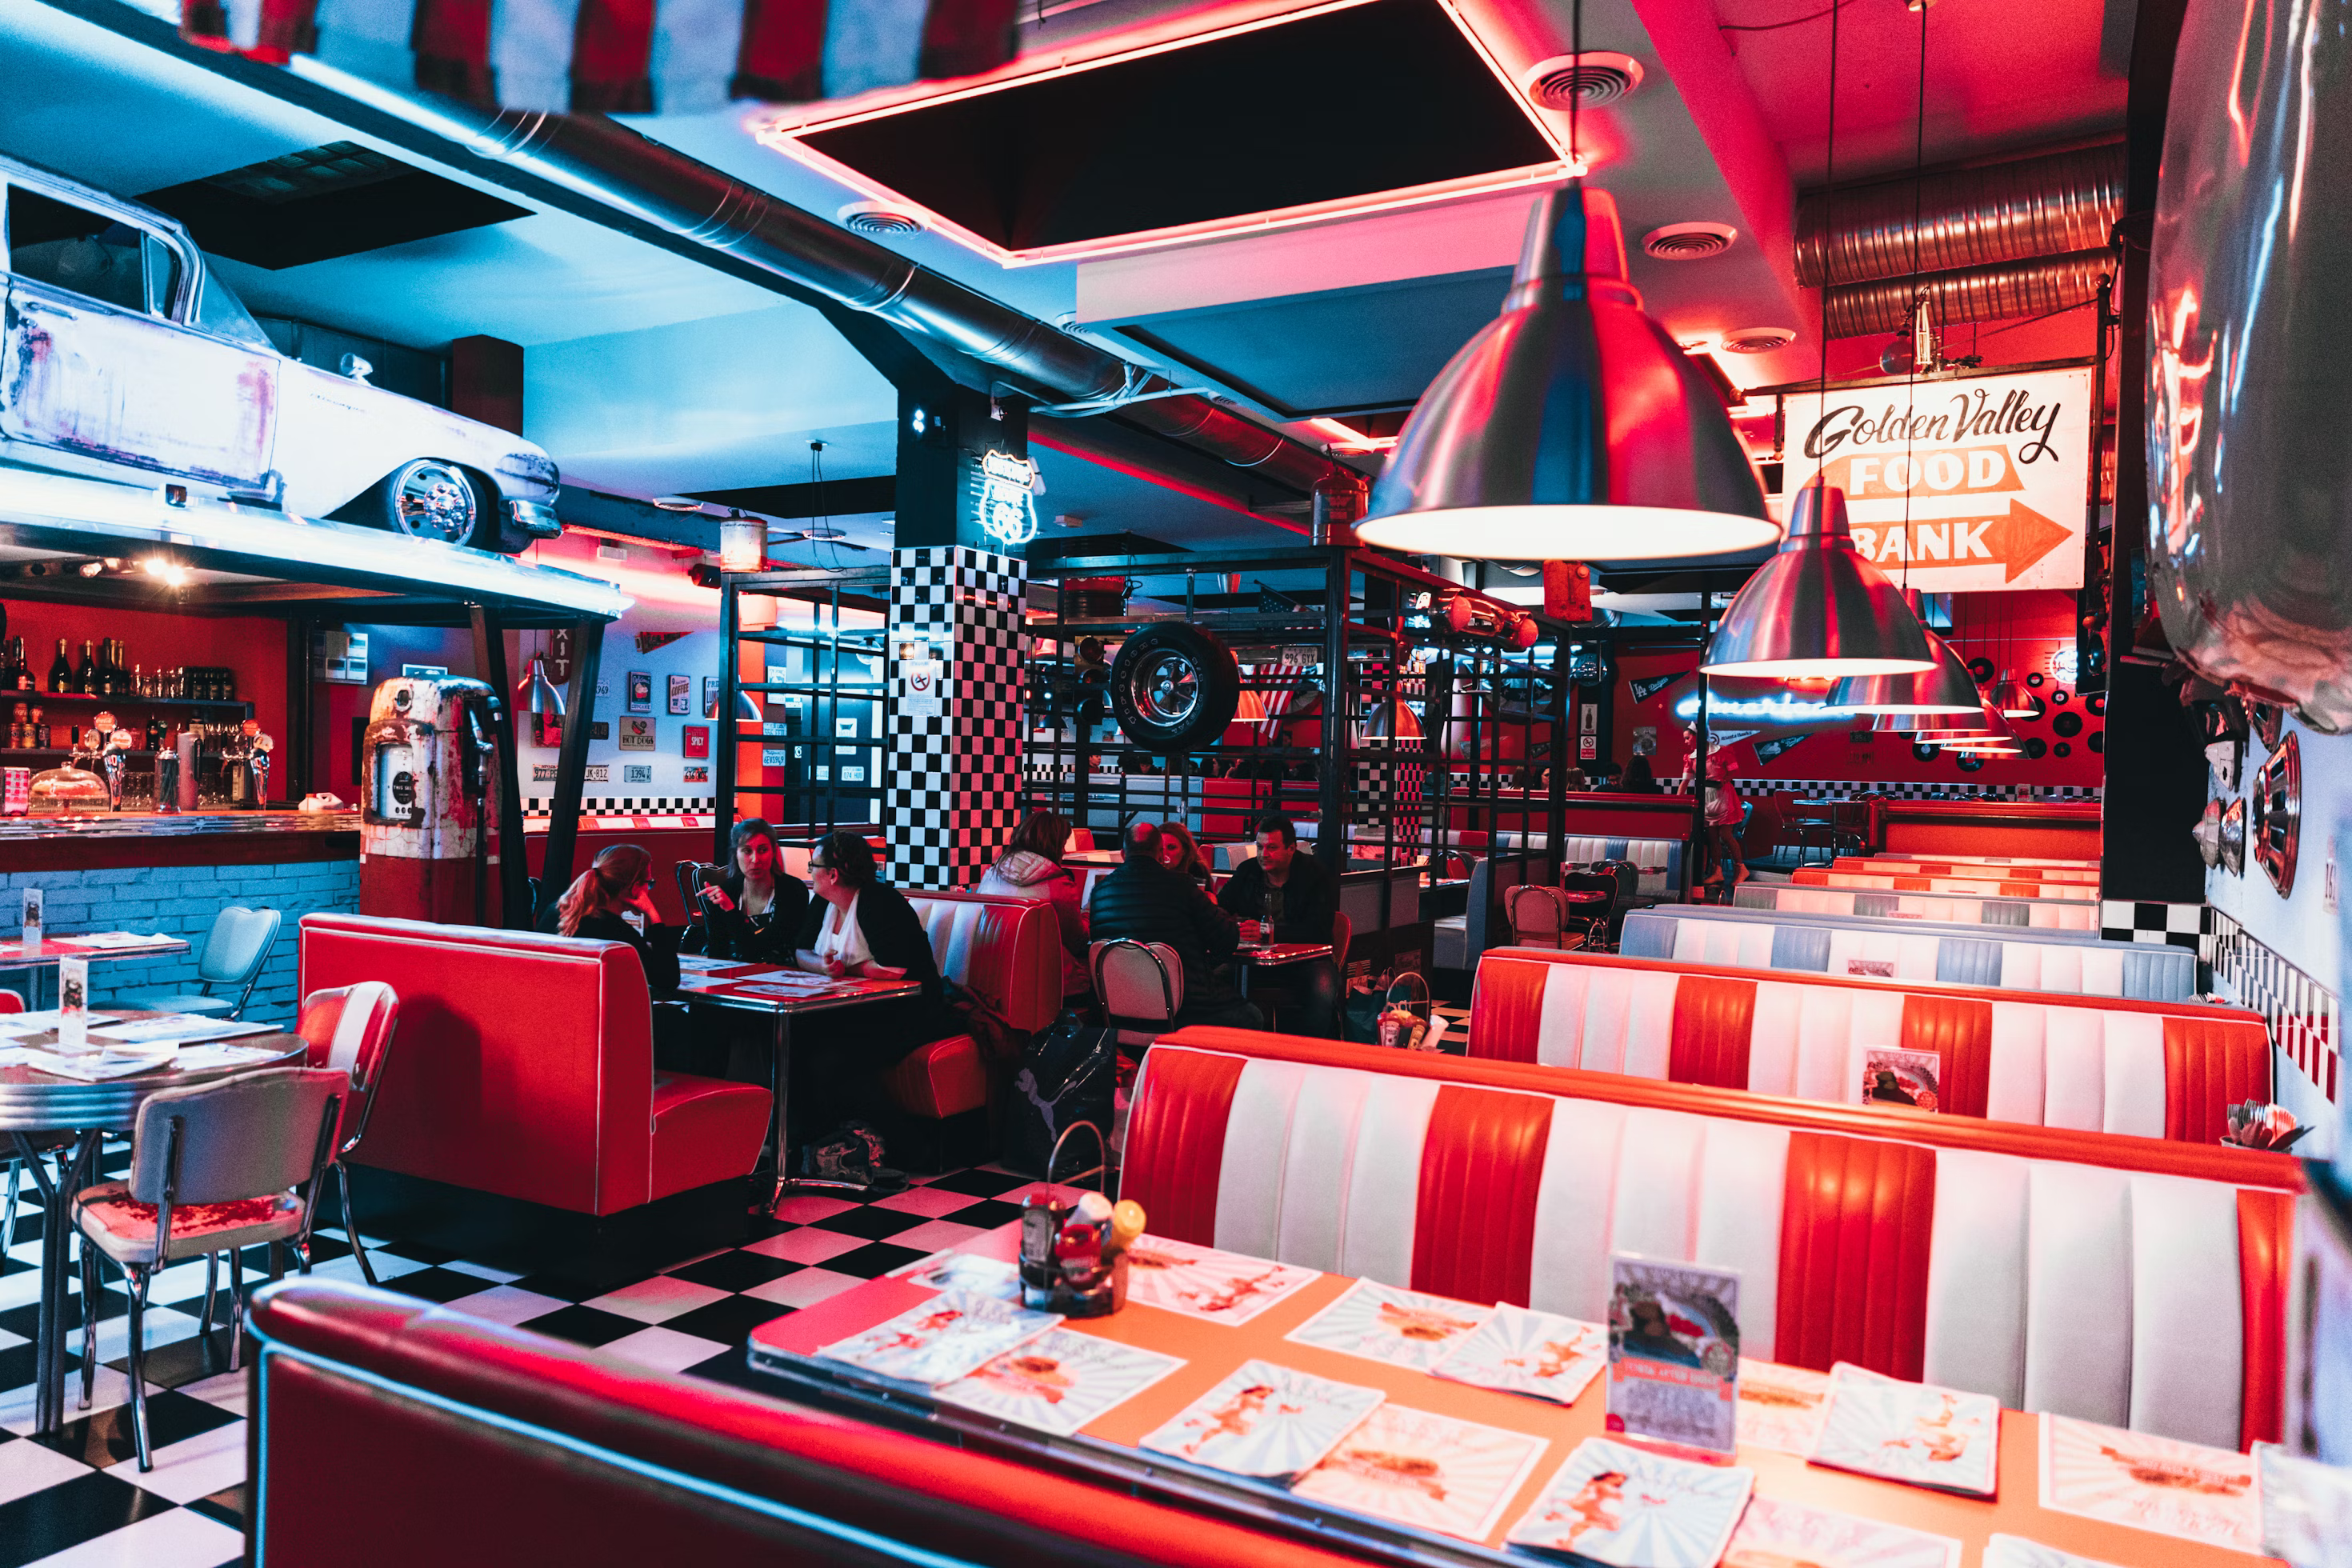
import torch
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import load_image

pipeline = AutoPipelineForImage2Image.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name="ip-adapter_sdxl.bin"
)
pipeline.set_ip_adapter_scale(0.8)

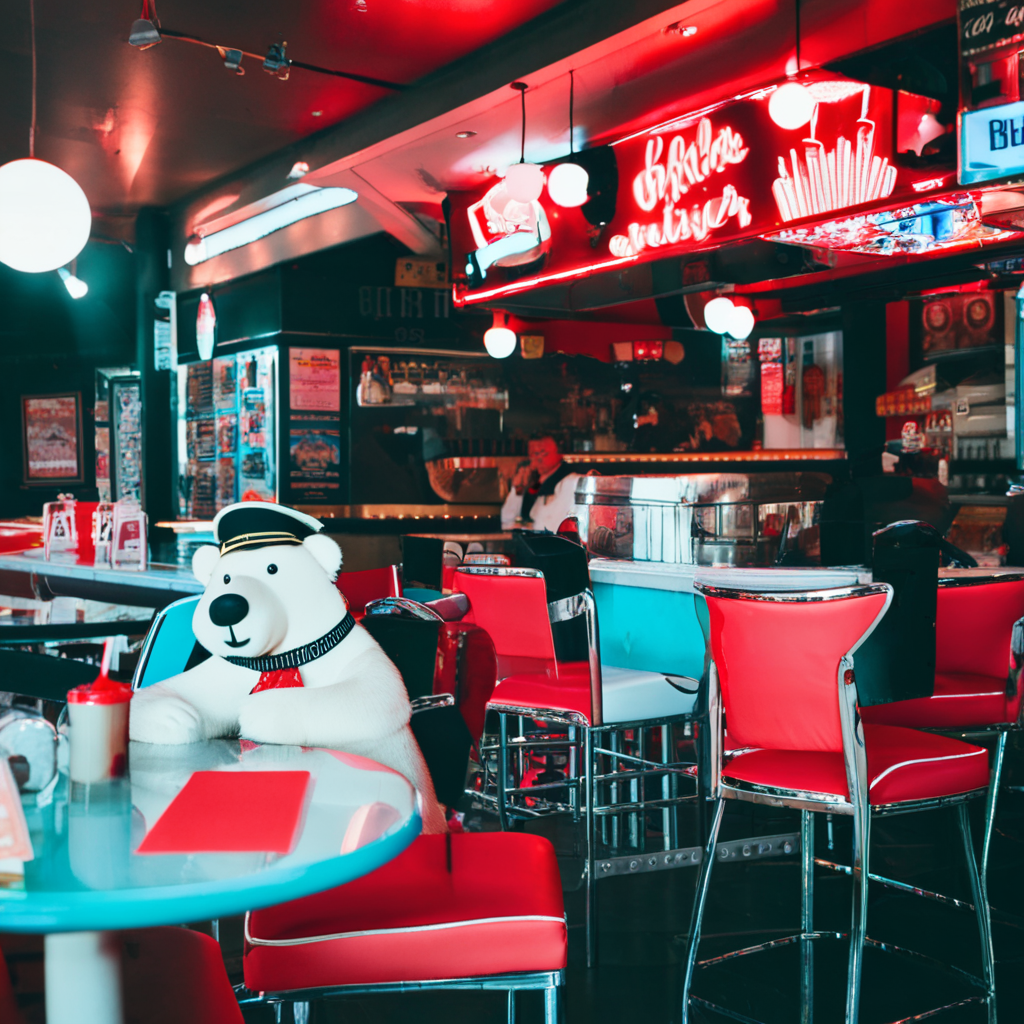
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_bear_1.png")
ip_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_gummy.png")
pipeline(
    prompt="best quality, high quality",
    image=image,
    ip_adapter_image=ip_image,
    strength=0.5,
).images[0]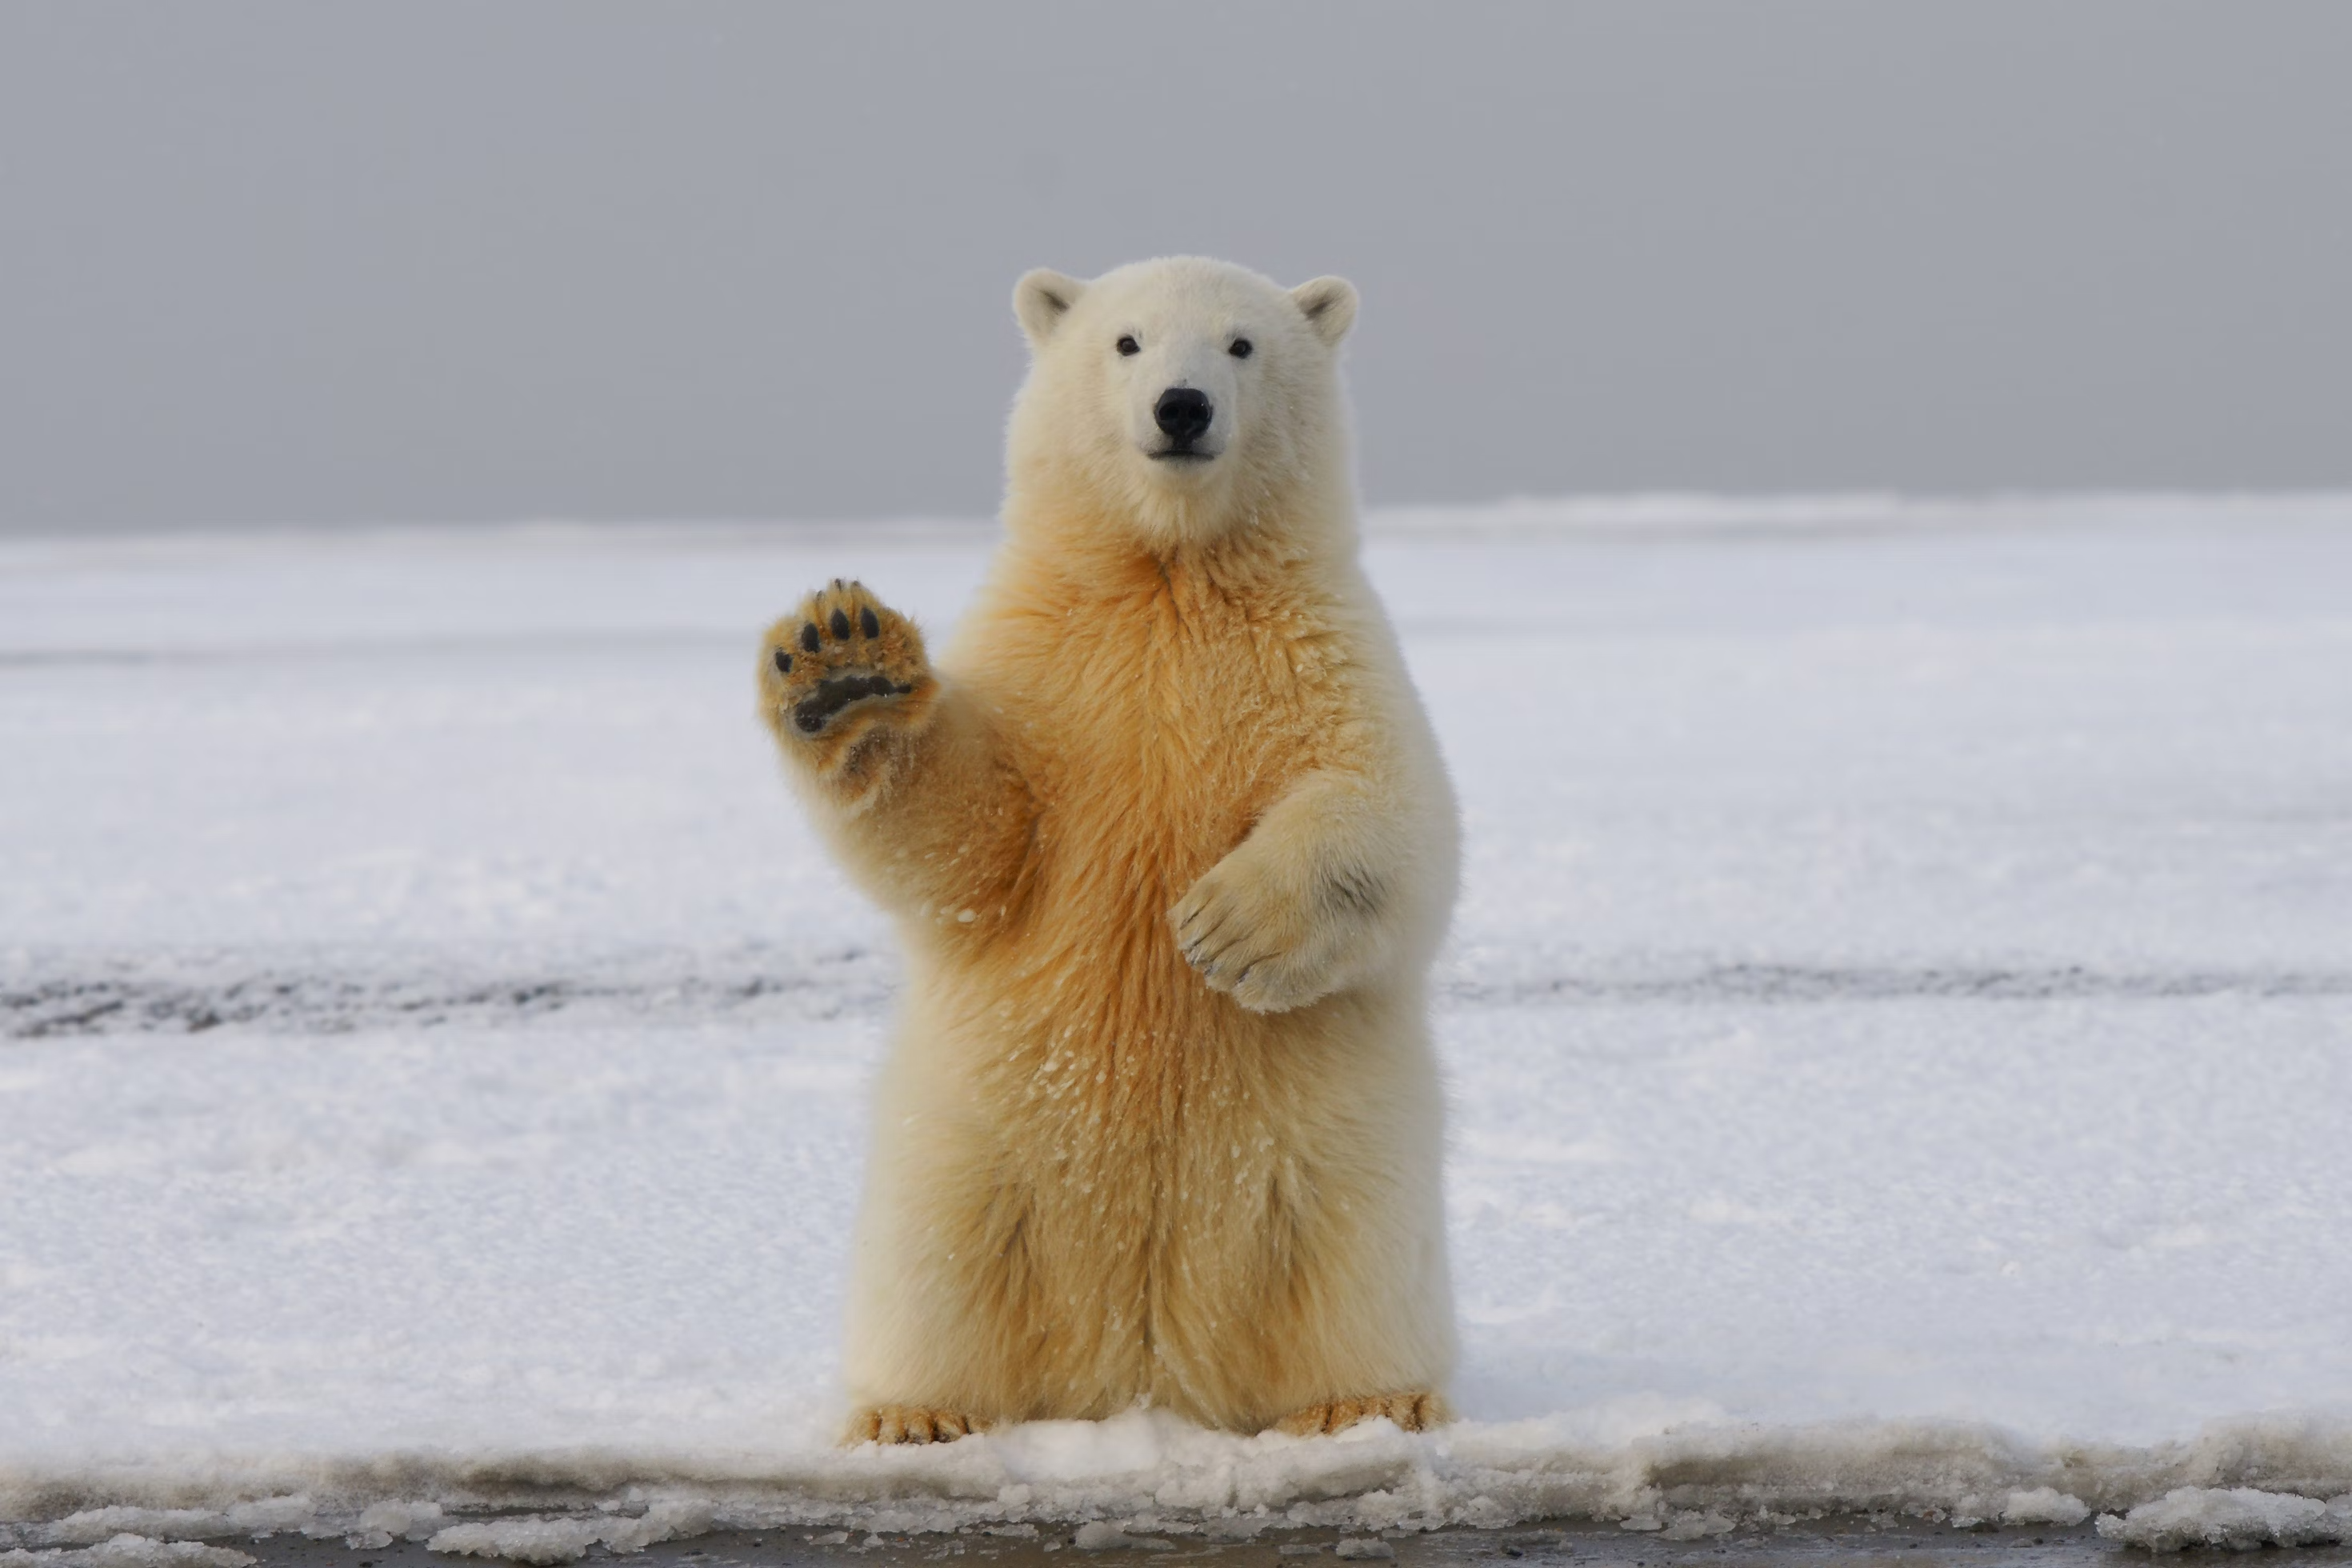
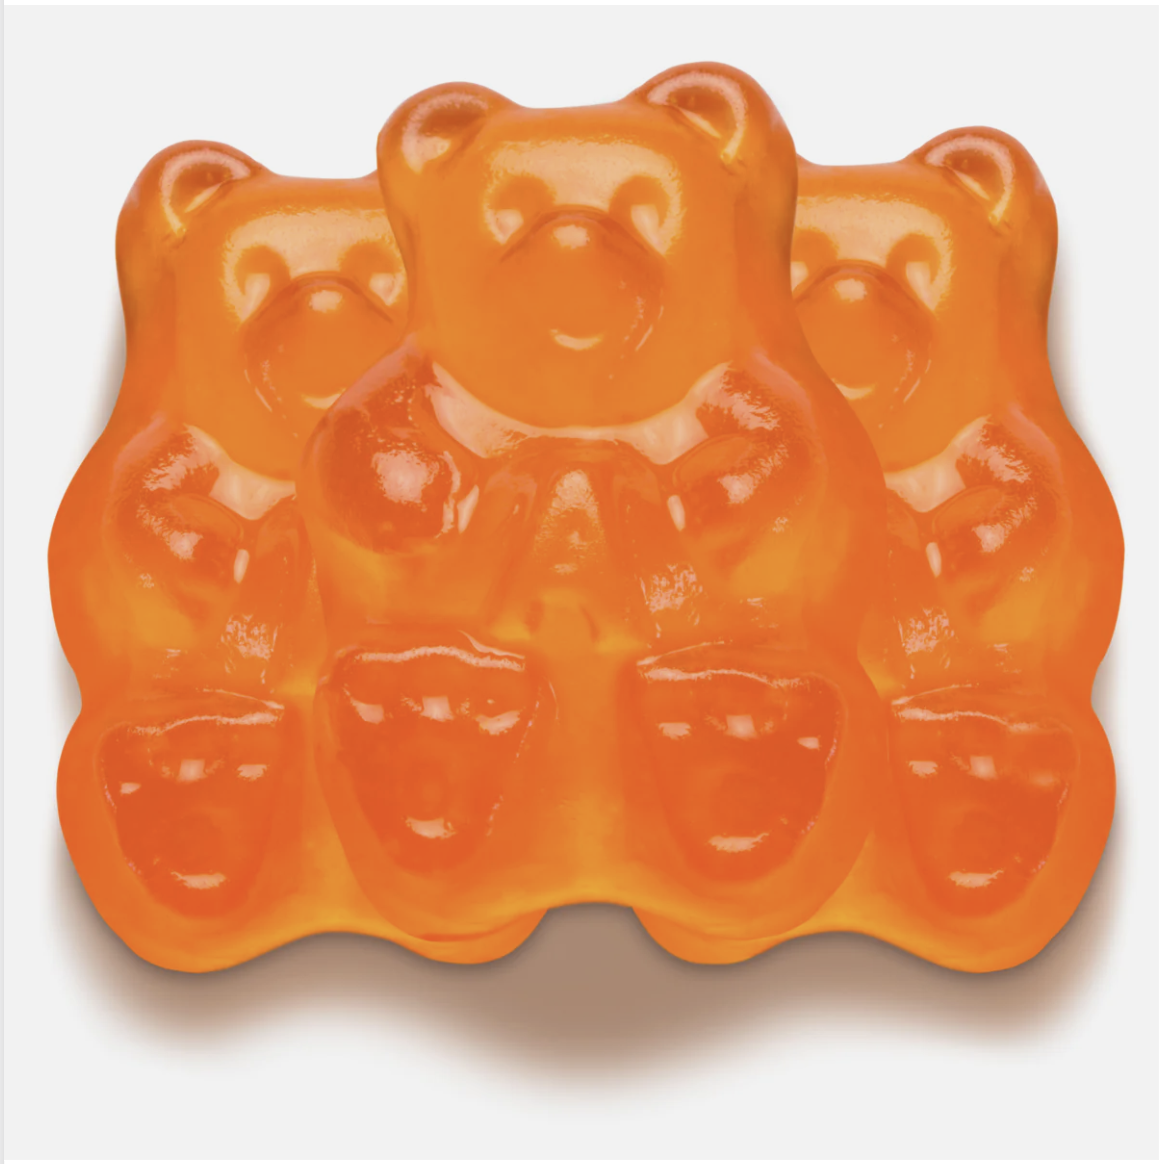
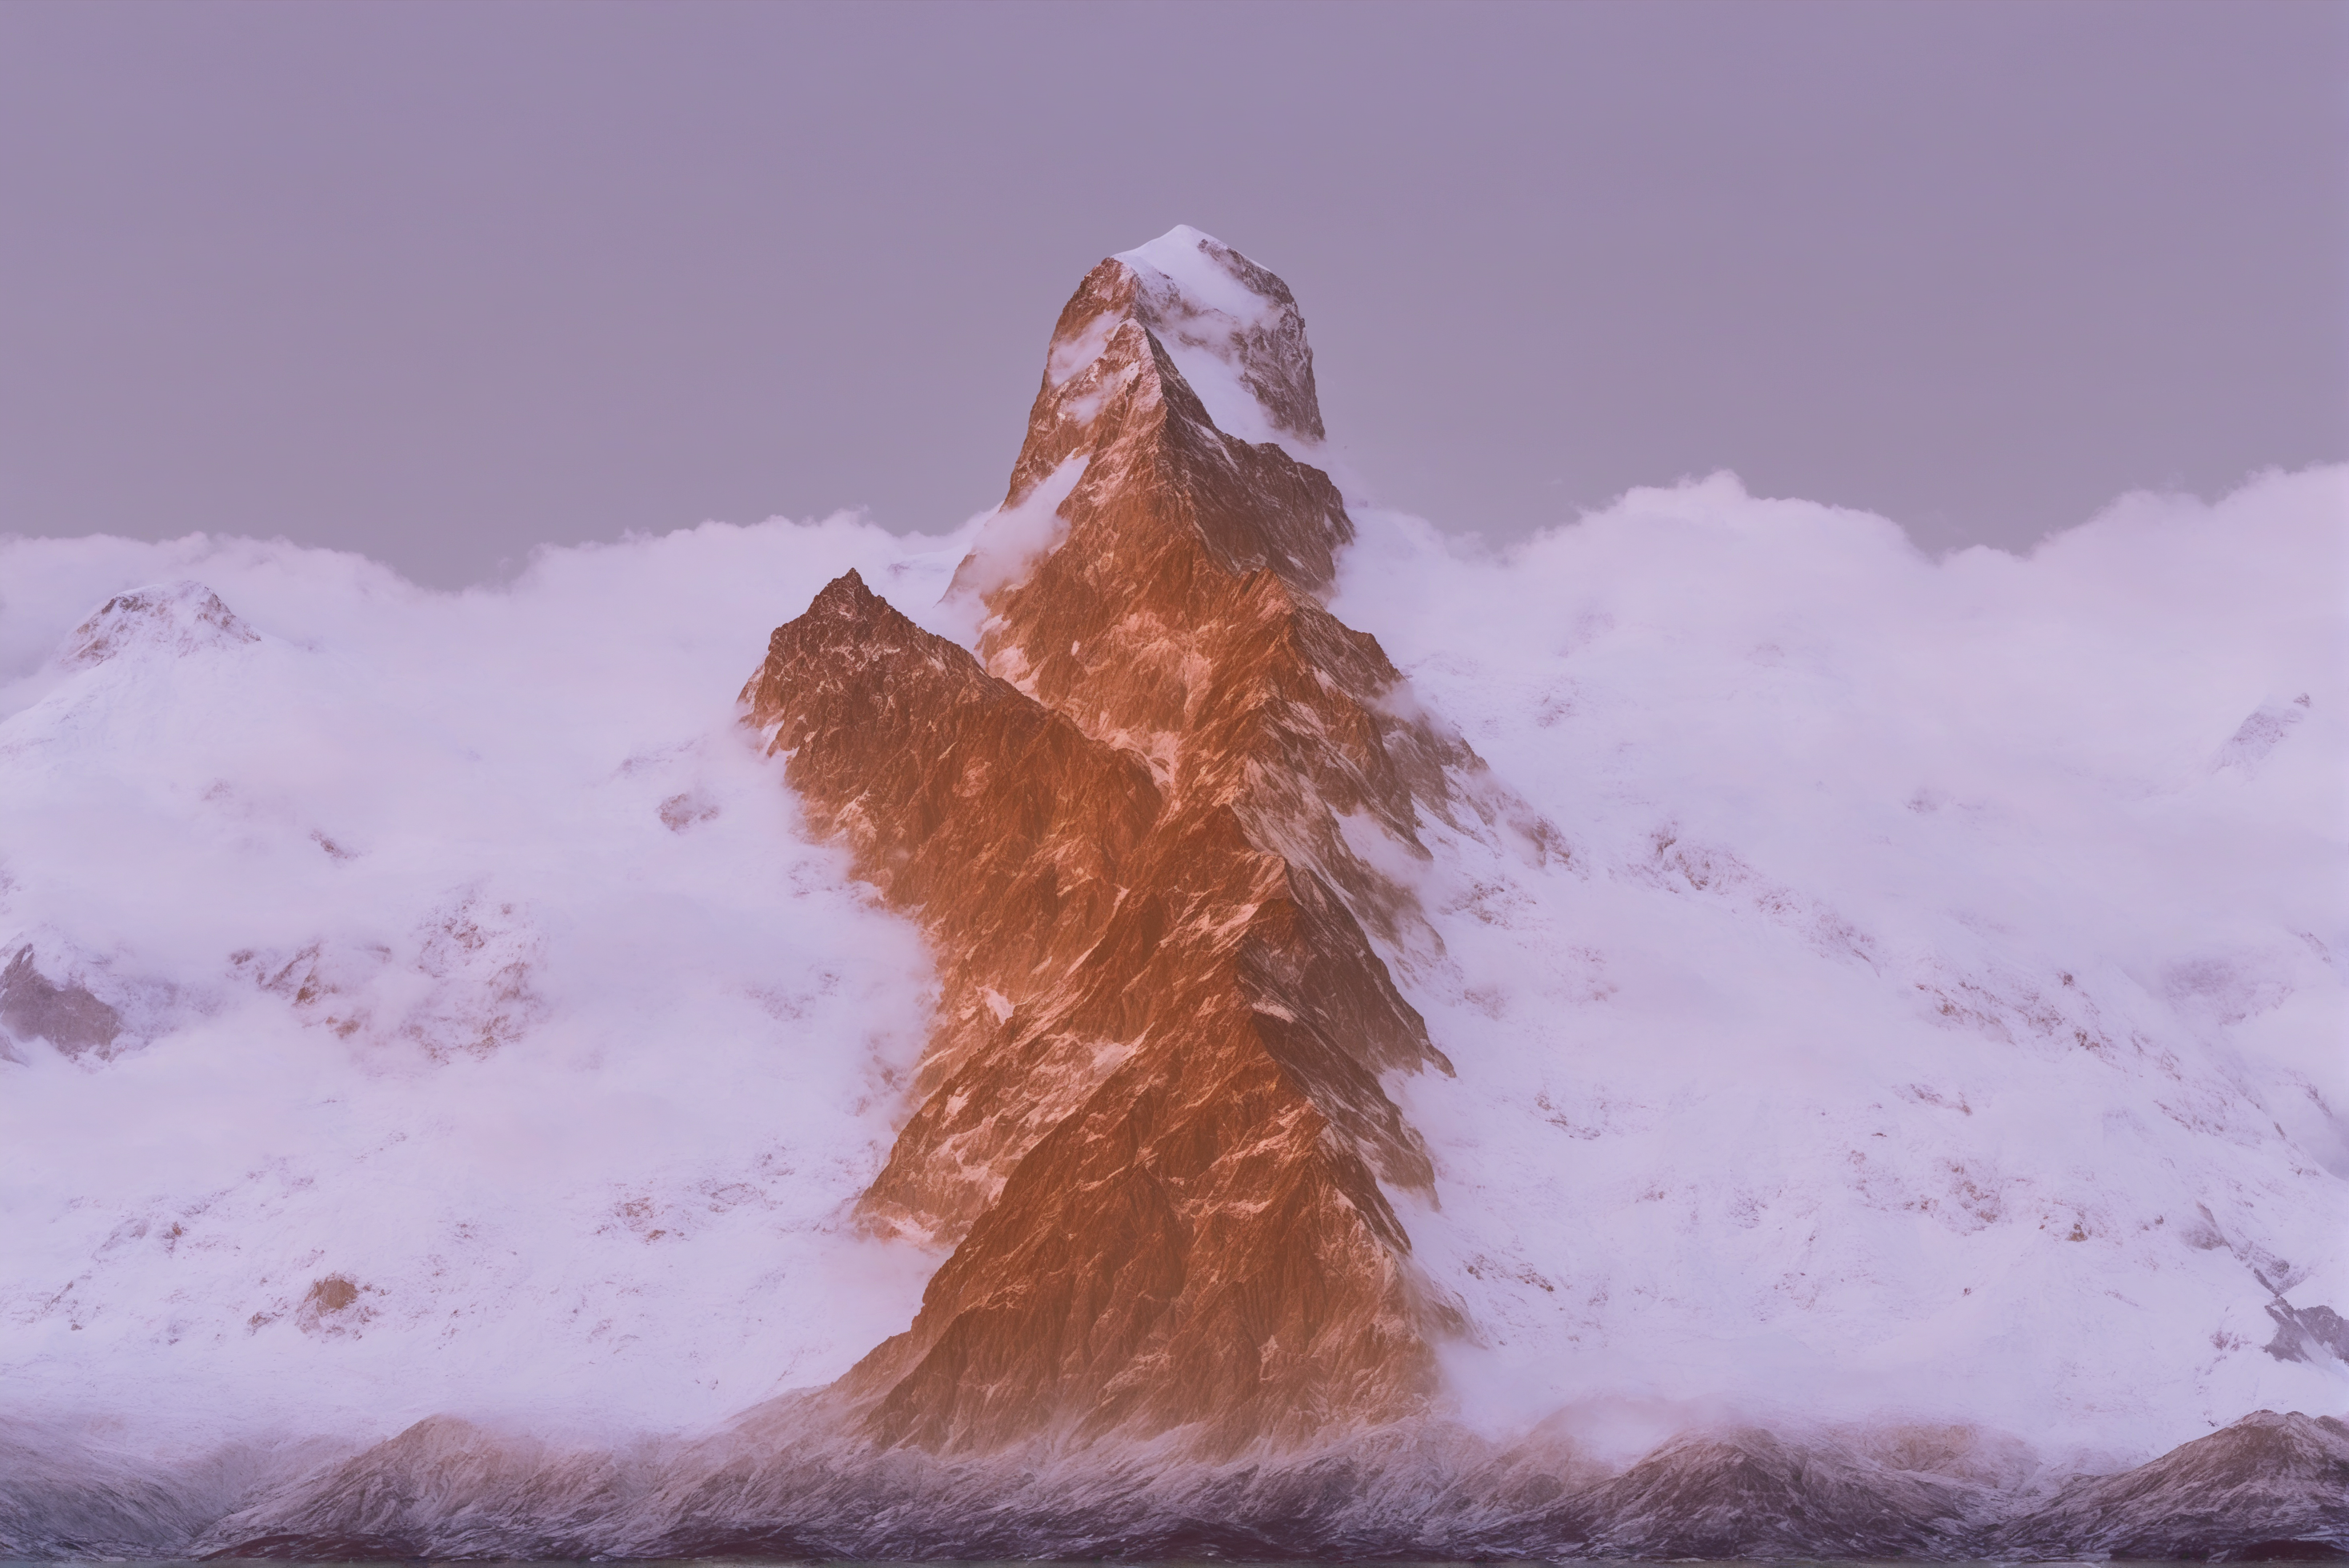
import torch
from diffusers import AutoPipelineForInpainting
from diffusers.utils import load_image

pipeline = AutoPipelineForInpainting.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name="ip-adapter_sdxl.bin"
)
pipeline.set_ip_adapter_scale(0.6)

mask_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_mask.png")
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_bear_1.png")
ip_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_gummy.png")
pipeline(
    prompt="a cute gummy bear waving",
    image=image,
    mask_image=mask_image,
    ip_adapter_image=ip_image,
).images[0] 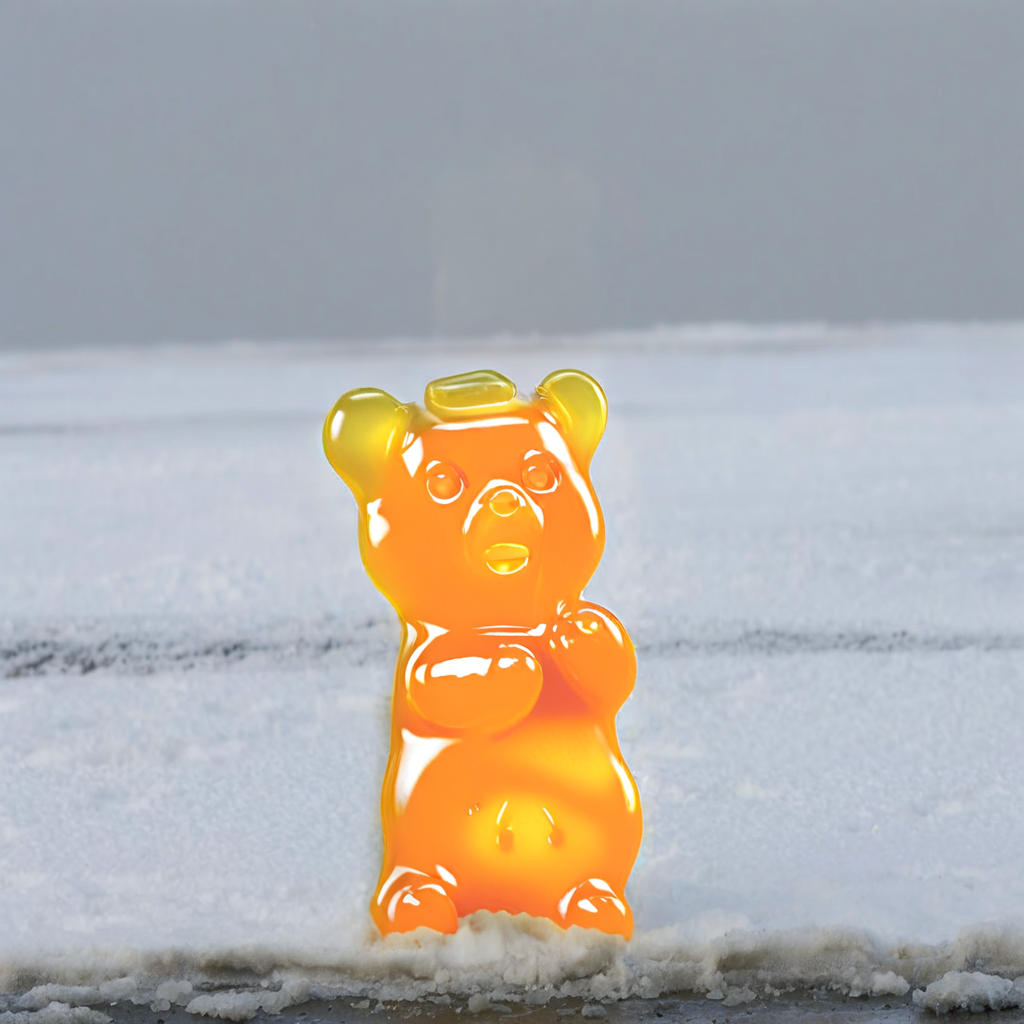
enable_model_cpu_offload() yöntemi belleği azaltmak için kullanışlıdır ve IP-Adapter yüklendikten sonra etkinleştirilmelidir. Aksi takdirde, IP-Adapter'ın görüntü kodlayıcısı da CPU'ya taşınır ve bir hata döner.
import torch
from diffusers import AnimateDiffPipeline, DDIMScheduler, MotionAdapter
from diffusers.utils import export_to_gif
from diffusers.utils import load_image

adapter = MotionAdapter.from_pretrained(
  "guoyww/animatediff-motion-adapter-v1-5-2",
  dtype=torch.float16
)
pipeline = AnimateDiffPipeline.from_pretrained(
  "emilianJR/epiCRealism",
  motion_adapter=adapter,
  dtype=torch.float16
)
scheduler = DDIMScheduler.from_pretrained(
    "emilianJR/epiCRealism",
    subfolder="scheduler",
    clip_sample=False,
    timestep_spacing="linspace",
    beta_schedule="linear",
    steps_offset=1,
)
pipeline.scheduler = scheduler
pipeline.vae.enable_slicing()
pipeline.load_ip_adapter("h94/IP-Adapter", subfolder="models", weight_name="ip-adapter_sd15.bin")
pipeline.enable_model_cpu_offload()

ip_adapter_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_inpaint.png")
pipeline(
    prompt="A cute gummy bear waving",
    negative_prompt="bad quality, worse quality, low resolution",
    ip_adapter_image=ip_adapter_image,
    num_frames=16,
    guidance_scale=7.5,
    num_inference_steps=50,
).frames[0] 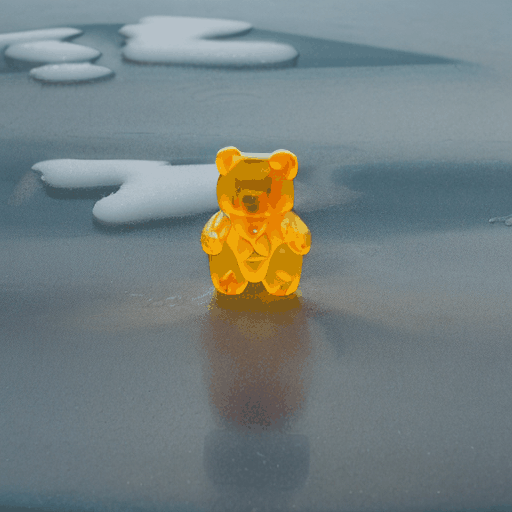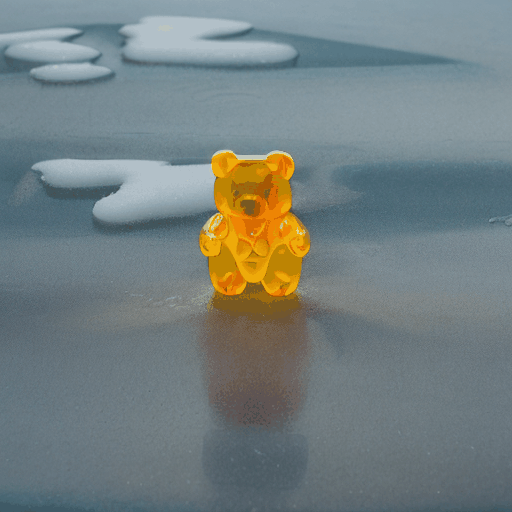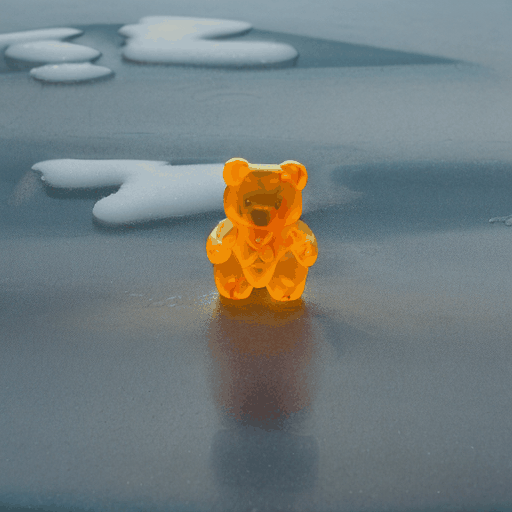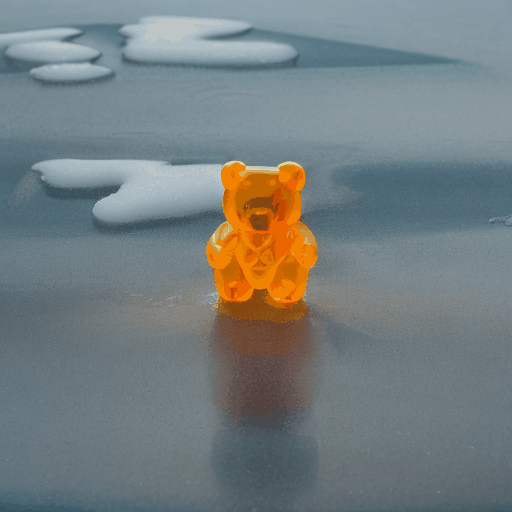
Checkpoint varyantları
Referans görüntüdeki detayların en önemli olduğu durumda Plus'ı yükleyin. CLIP görüntü gömme yerine InsightFace kimlik gömme gerektirdiğinizde FaceID'yi yükleyin.
import torch
from transformers import CLIPVisionModelWithProjection
from diffusers import AutoPipelineForText2Image

image_encoder = CLIPVisionModelWithProjection.from_pretrained(
    "h94/IP-Adapter",
    subfolder="models/image_encoder",
    dtype=torch.float16
)

pipeline = AutoPipelineForText2Image.from_pretrained(
    "stabilityai/stable-diffusion-xl-base-1.0",
    image_encoder=image_encoder,
    dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"

pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name="ip-adapter-plus_sdxl_vit-h.safetensors"
)
FaceID checkpoint'ları, CLIP gömme yerine InsightFace yüz gömme kullanır. FaceID modelleri için DDIMScheduler veya EulerDiscreteScheduler kullanın. Yüz gömme'leri çıkarın ve bunları ip_adapter_image_embeds parametresine tensör listesi olarak iletin.
# pip install insightface
import cv2
import numpy as np
import torch
from diffusers import StableDiffusionPipeline, DDIMScheduler
from diffusers.utils import load_image
from insightface.app import FaceAnalysis

pipeline = StableDiffusionPipeline.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5",
    dtype=torch.float16,
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.scheduler = DDIMScheduler.from_config(pipeline.scheduler.config)
pipeline.load_ip_adapter(
  "h94/IP-Adapter-FaceID",
  subfolder=None,
  weight_name="ip-adapter-faceid_sd15.bin",
  image_encoder_folder=None
)
pipeline.set_ip_adapter_scale(0.6)

image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_mask_girl1.png")

ref_images_embeds = []
app = FaceAnalysis(name="buffalo_l", providers=['CUDAExecutionProvider', 'CPUExecutionProvider'])
app.prepare(ctx_id=0, det_size=(640, 640))
image = cv2.cvtColor(np.asarray(image), cv2.COLOR_RGB2BGR)
faces = app.get(image)
image = torch.from_numpy(faces[0].normed_embedding)
ref_images_embeds.append(image.unsqueeze(0))
ref_images_embeds = torch.stack(ref_images_embeds, dim=0).unsqueeze(0)
neg_ref_images_embeds = torch.zeros_like(ref_images_embeds)
id_embeds = torch.cat([neg_ref_images_embeds, ref_images_embeds]).to(dtype=torch.float16, device="cuda")

pipeline(
    prompt="A photo of a girl",
    ip_adapter_image_embeds=[id_embeds],
    negative_prompt="monochrome, lowres, bad anatomy, worst quality, low quality",
).images[0]
FaceID Plus için görüntü kodlayıcı olarak CLIPVisionModelWithProjection yükleyin.
import torch
from transformers import CLIPVisionModelWithProjection
from diffusers import AutoPipelineForText2Image

image_encoder = CLIPVisionModelWithProjection.from_pretrained(
    "laion/CLIP-ViT-H-14-laion2B-s32B-b79K",
    dtype=torch.float16,
)

pipeline = AutoPipelineForText2Image.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5",
    image_encoder=image_encoder,
    dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"

pipeline.load_ip_adapter(
  "h94/IP-Adapter-FaceID",
  subfolder=None,
  weight_name="ip-adapter-faceid-plus_sd15.bin"
)
FaceID Plus ve Plus v2, InsightFace gömme değerlerinin yanı sıra CLIP görüntü gömme değerlerine de ihtiyaç duyar. Yüz gömme değerlerini hazırladıktan sonra referans görüntüyü kodlayın ve CLIP gömme değerlerini görüntü projeksiyon katmanına atayın.
import torch
from diffusers.utils import load_image

ip_adapter_images = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_mask_girl1.png")
num_images = 1
clip_embeds = pipeline.prepare_ip_adapter_image_embeds(
    ip_adapter_image=[ip_adapter_images],
    ip_adapter_image_embeds=None,
    device=torch.device("cuda"),
    num_images_per_prompt=num_images,
    do_classifier_free_guidance=True,
)[0]

pipeline.unet.encoder_hid_proj.image_projection_layers[0].clip_embeds = clip_embeds.to(dtype=torch.float16)
# set to True if using IP-Adapter FaceID Plus v2
pipeline.unet.encoder_hid_proj.image_projection_layers[0].shortcut = False
Görsel gömleleri
prepare_ip_adapter_image_embeds(), IP-Adapter görsellerini kaydedip yeniden kullanabileceğiniz gömütlere dönüştürür. Her pipeline çalıştırmasında aynı görselleri yükleyip kodlamak yerine, bunları bir kez önceden hesaplayın.
import torch
from diffusers import AutoPipelineForText2Image
from diffusers.utils import load_image

pipeline = AutoPipelineForText2Image.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name="ip-adapter_sdxl.bin"
)

image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_adapter_bear_1.png")
image_embeds = pipeline.prepare_ip_adapter_image_embeds(
    ip_adapter_image=image,
    ip_adapter_image_embeds=None,
    device="cuda",
    num_images_per_prompt=1,
    do_classifier_free_guidance=True,
)

torch.save(image_embeds, "image_embeds.ipadpt")
Görsel gömme vektörlerini ip_adapter_image_embeds parametresine ileterek yeniden yükleyin. Görsel gömme vektörlerini üretmek için artık görsel kodlayıcıya ihtiyacınız olmadığından image_encoder_folder değerini None olarak ayarlayın.
ComfyUI gibi diğer kaynaklardan da görsel gömme (embedding) yükleyebilirsiniz.
pipeline = AutoPipelineForText2Image.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  image_encoder_folder=None,
  weight_name="ip-adapter_sdxl.bin"
)
pipeline.set_ip_adapter_scale(0.8)
image_embeds = torch.load("image_embeds.ipadpt")
pipeline(
    prompt="a polar bear sitting in a chair drinking a milkshake",
    ip_adapter_image_embeds=image_embeds,
    negative_prompt="deformed, ugly, wrong proportion, low res, bad anatomy, worst quality, low quality",
    num_inference_steps=100,
).images[0]
Maskelama
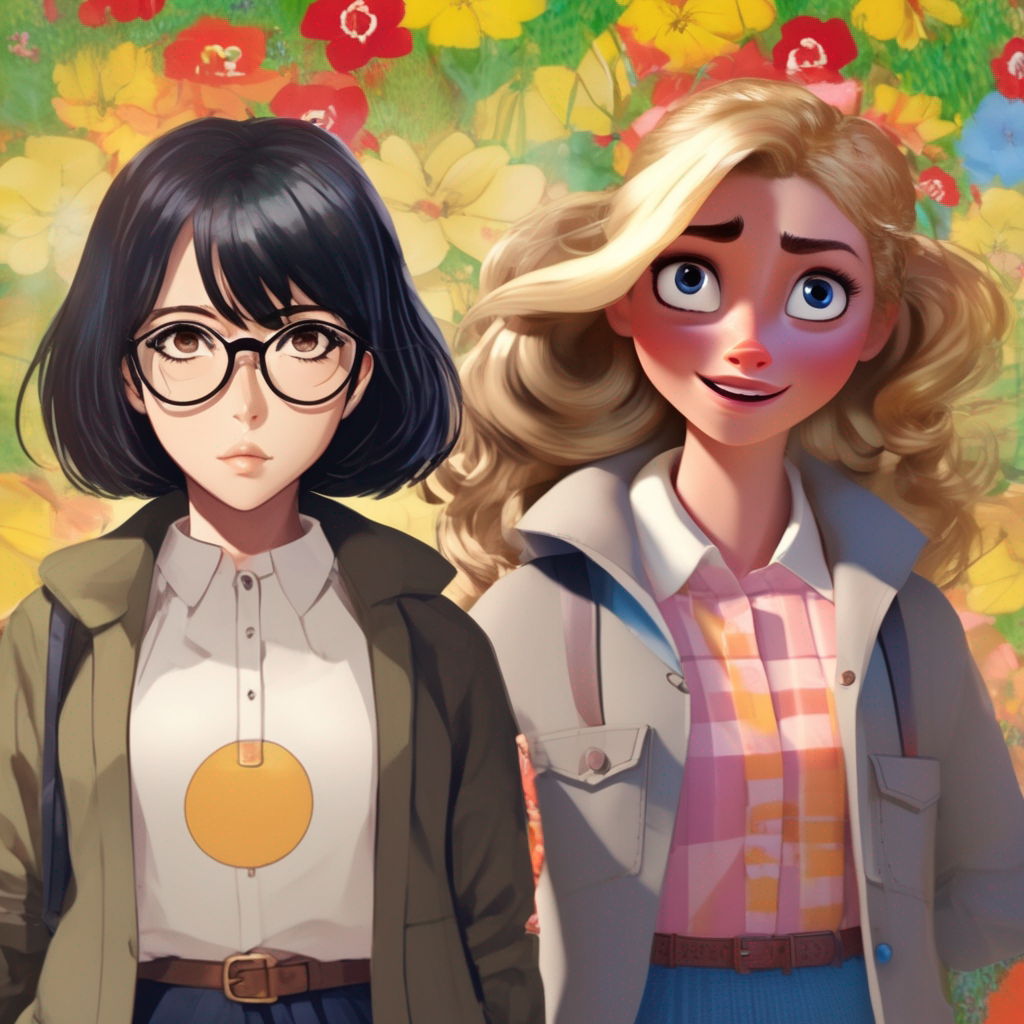
İkili maskeleme, bir IP-Adapter görselini çıktı görselinin belirli bir alanına atamayı mümkün kılar ve bu da birden fazla IP-Adapter görselini bir araya getirmek için faydalıdır. Her IP-Adapter görseli için bir ikili maske gereklidir.
Görsel maskelerini ön işlemek için IPAdapterMaskProcessor yükleyin. En iyi sonuçlar için, farklı en-boy oranlarına sahip maskelerin uygun boyutlandırılmasını sağlamak üzere çıktı height ve width değerlerini belirtin. Girdi maskeleri zaten üretilen görselin en-boy oranıyla eşleşiyorsa, height ve width değerlerini ayarlamanıza gerek yoktur.
import torch
from diffusers import AutoPipelineForText2Image
from diffusers.image_processor import IPAdapterMaskProcessor
from diffusers.utils import load_image

pipeline = AutoPipelineForText2Image.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"

mask1 = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_mask_mask1.png")
mask2 = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_mask_mask2.png")

processor = IPAdapterMaskProcessor()
masks = processor.preprocess([mask1, mask2], height=1024, width=1024)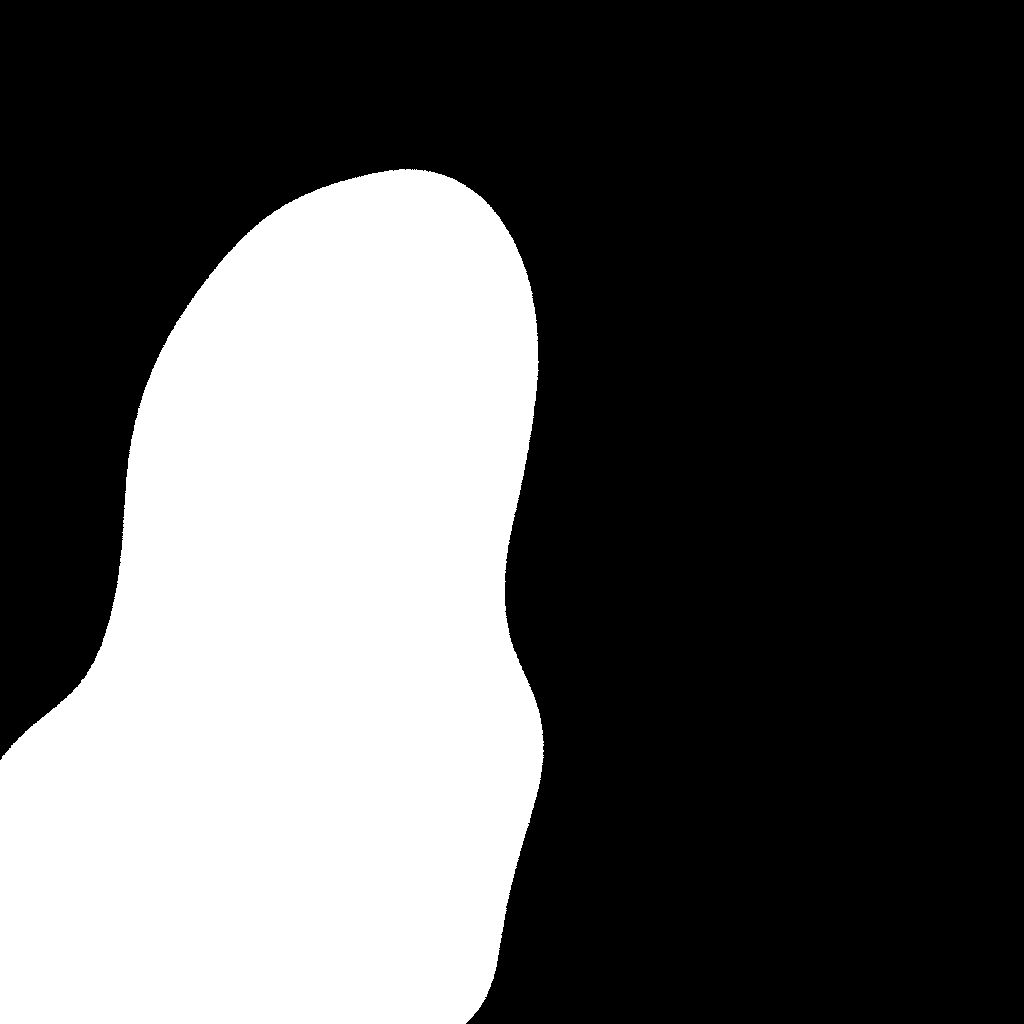
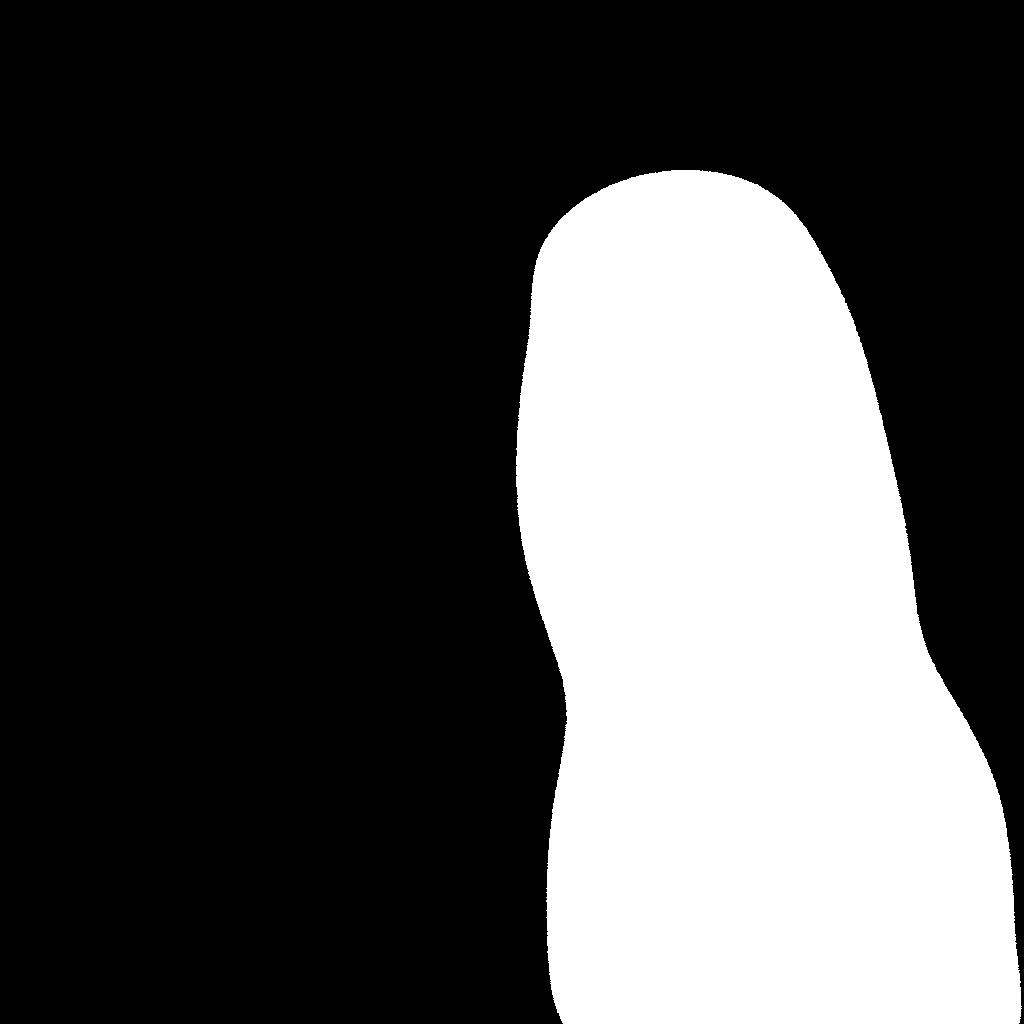
IP-Adapter görsellerini ve ölçeklerini bir liste olarak sağlayın. Ön işlenmiş maskeleri cross_attention_kwargs parametresi üzerinden pipeline'a iletin.
face_image1 = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_mask_girl1.png")
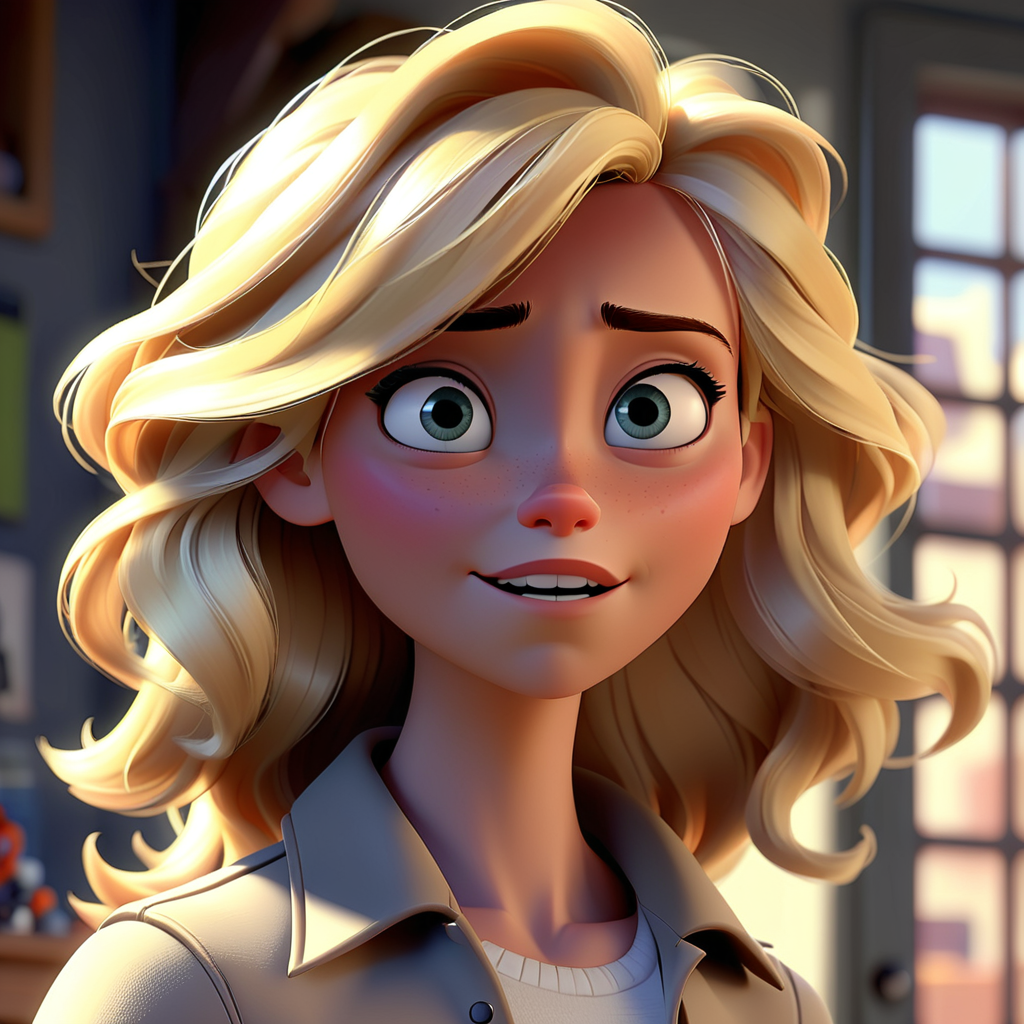
face_image2 = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ip_mask_girl2.png")

pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name=["ip-adapter-plus-face_sdxl_vit-h.safetensors"]
)
pipeline.set_ip_adapter_scale([[0.7, 0.7]])

ip_images = [[face_image1, face_image2]]
masks = [masks.reshape(1, masks.shape[0], masks.shape[2], masks.shape[3])]

pipeline(
  prompt="2 girls",
  ip_adapter_image=ip_images,
  negative_prompt="monochrome, lowres, bad anatomy, worst quality, low quality",
  cross_attention_kwargs={"ip_adapter_masks": masks}
).images[0]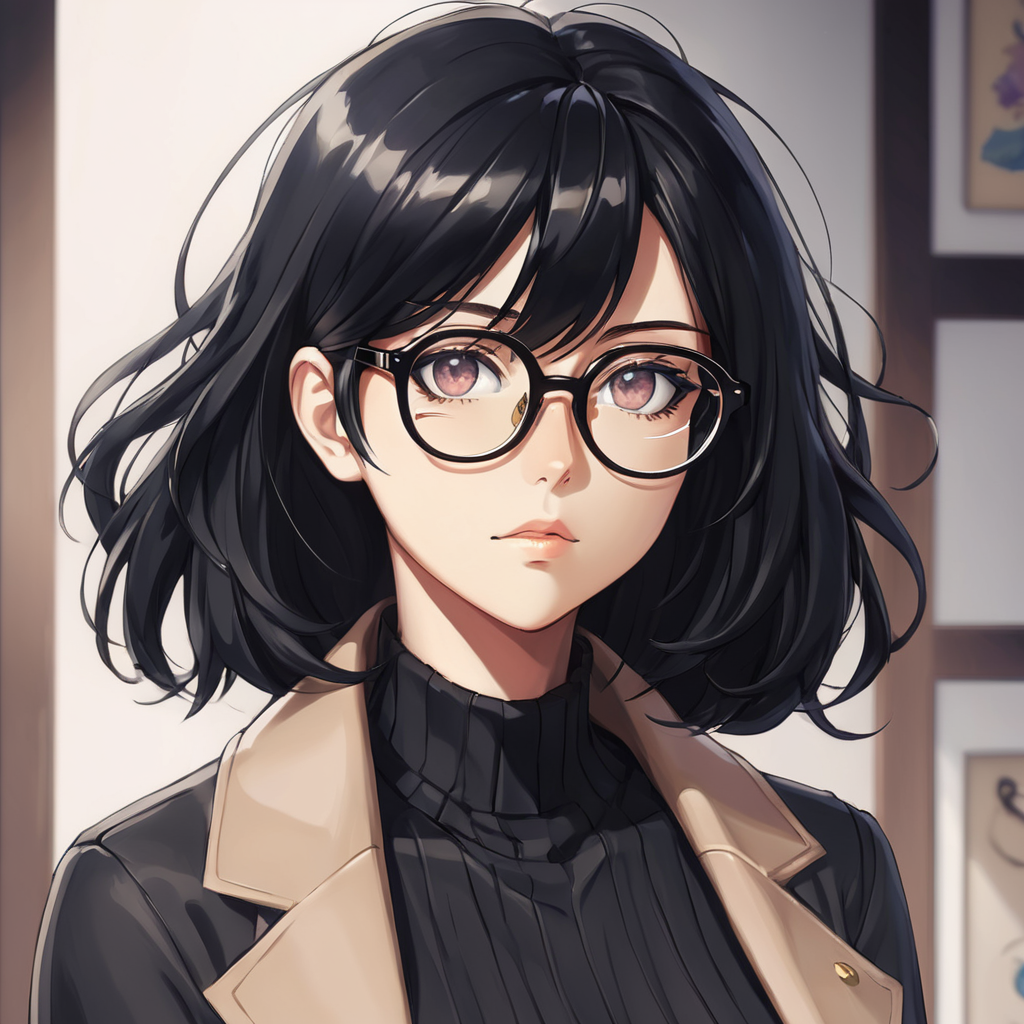
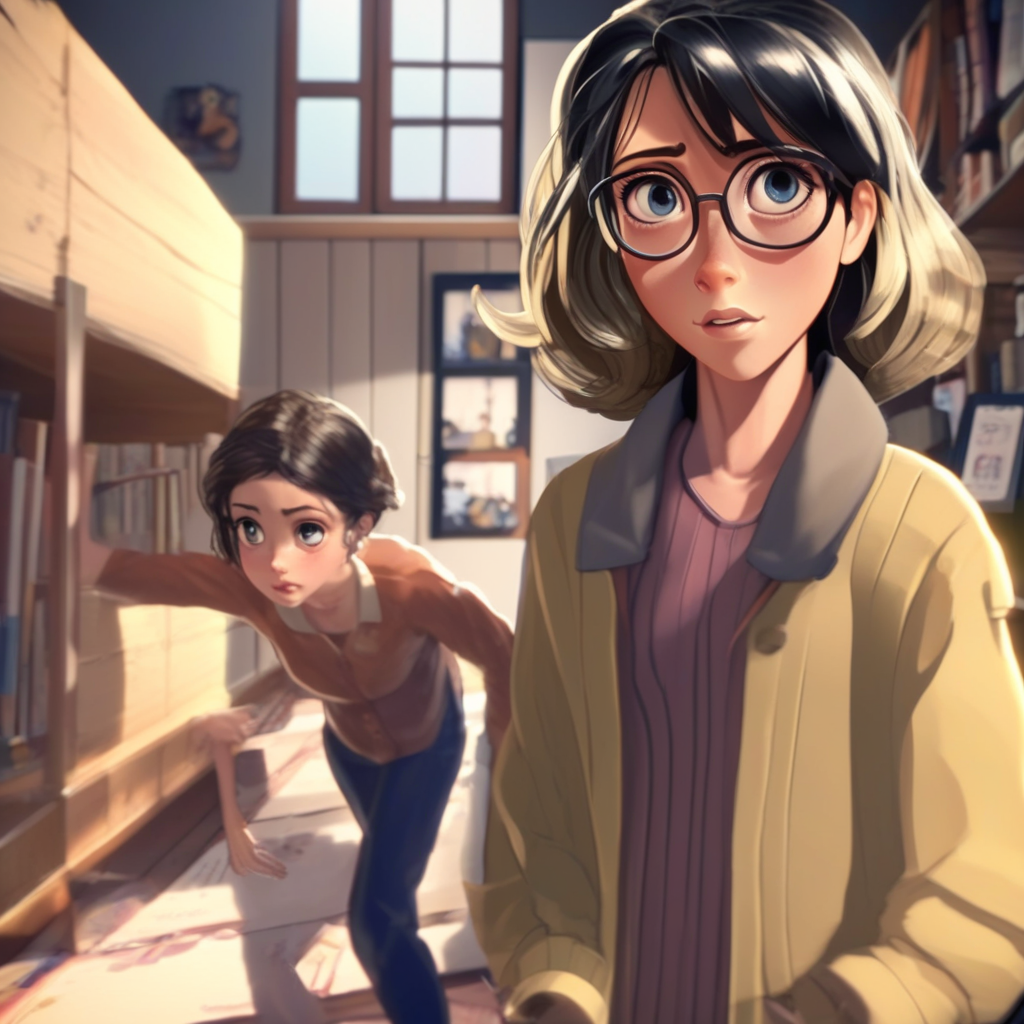
Tarifler
Tek bir referans görselinin yeterli olmadığı durumlarda, IP-Adapter'ı birden çok adaptör, ControlNet, InstantStyle veya az adımlı LCM gibi diğer adaptörler veya pipeline'larla birleştirin.
Birden Çok IP-Adapter
Birden fazla IP-Adapter birleştirerek daha çeşitli stillerde görseller oluşturabilirsiniz. Örneğin, tutarlı yüzler ve karakterler oluşturmak için IP-Adapter Face, bu yüzleri belirli stillerde oluşturmak için IP-Adapter Plus kullanabilirsiniz.
Bir görüntü kodlayıcıyı CLIPVisionModelWithProjection ile yükleyin.
import torch
from diffusers import AutoPipelineForText2Image, DDIMScheduler
from transformers import CLIPVisionModelWithProjection
from diffusers.utils import load_image

image_encoder = CLIPVisionModelWithProjection.from_pretrained(
    "h94/IP-Adapter",
    subfolder="models/image_encoder",
    dtype=torch.float16,
)
Bir temel model, zamanlayıcı ve aşağıdaki IP-Adapters'ları yükleyin.
- ip-adapter-plus_sdxl_vit-h, yama gömme ve ViT-H görüntü kodlayıcı kullanır
- ip-adapter-plus-face_sdxl_vit-h, yama gömmelemelerini ve ViT-H görüntü kodlayıcısını kullanır ancak kırpılmış yüz görüntülerine koşullandırılmıştır
pipeline = AutoPipelineForText2Image.from_pretrained(
    "stabilityai/stable-diffusion-xl-base-1.0",
    dtype=torch.float16,
    image_encoder=image_encoder,
)
pipeline.scheduler = DDIMScheduler.from_config(pipeline.scheduler.config)
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name=["ip-adapter-plus_sdxl_vit-h.safetensors", "ip-adapter-plus-face_sdxl_vit-h.safetensors"]
)
pipeline.set_ip_adapter_scale([0.7, 0.3])
# enable_model_cpu_offload to reduce memory usage
pipeline.enable_model_cpu_offload()
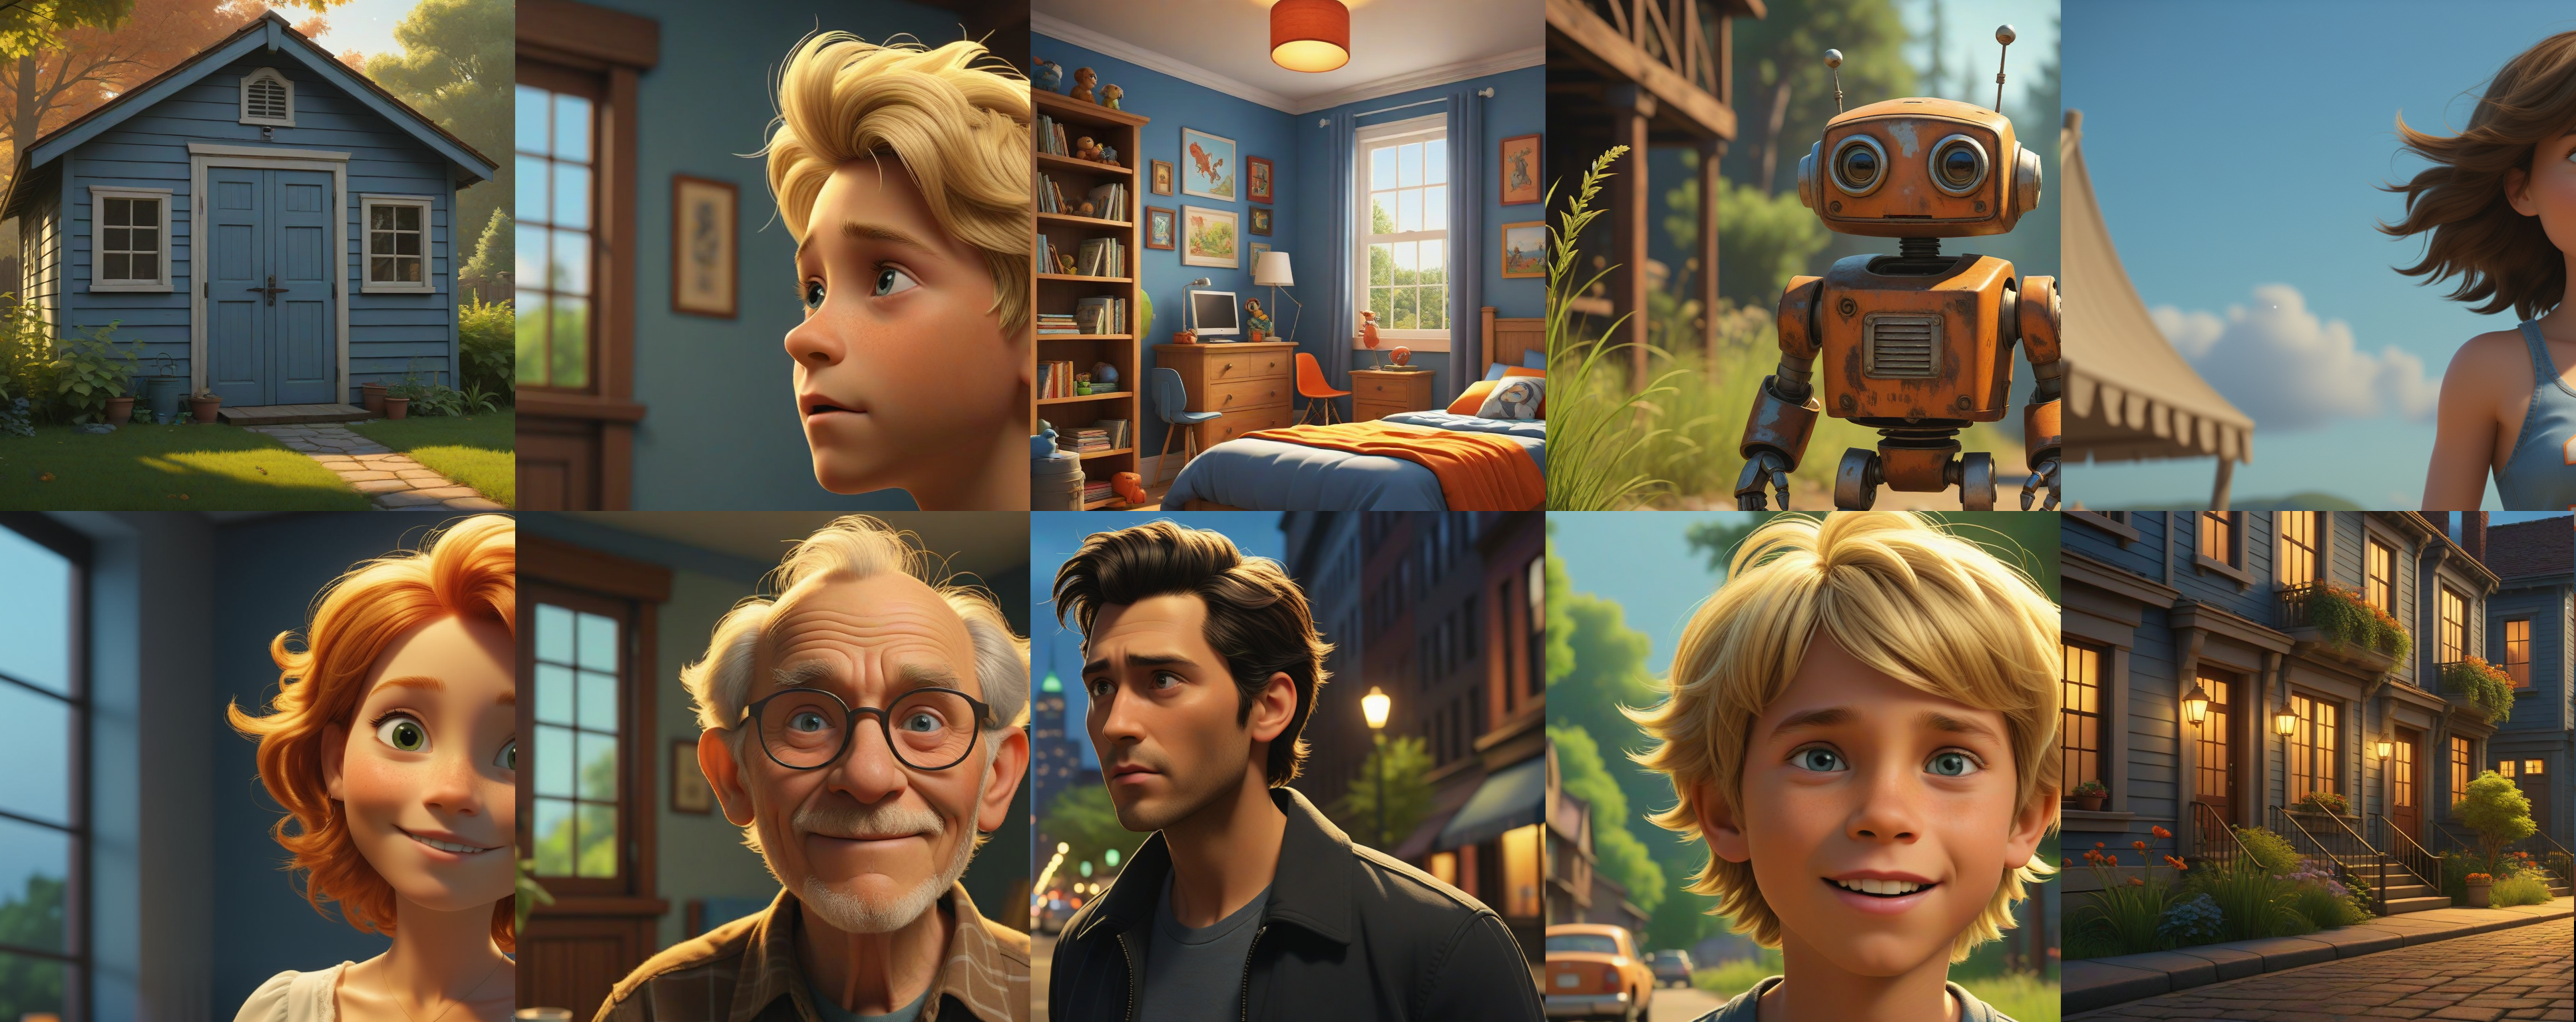
Uygulanacak belirli bir stildeki görselleri içeren bir görsel ve klasör yükleyin.
face_image = load_image("https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/women_input.png")
style_folder = "https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/style_ziggy"
style_images = [load_image(f"{style_folder}/img{i}.png") for i in range(10)]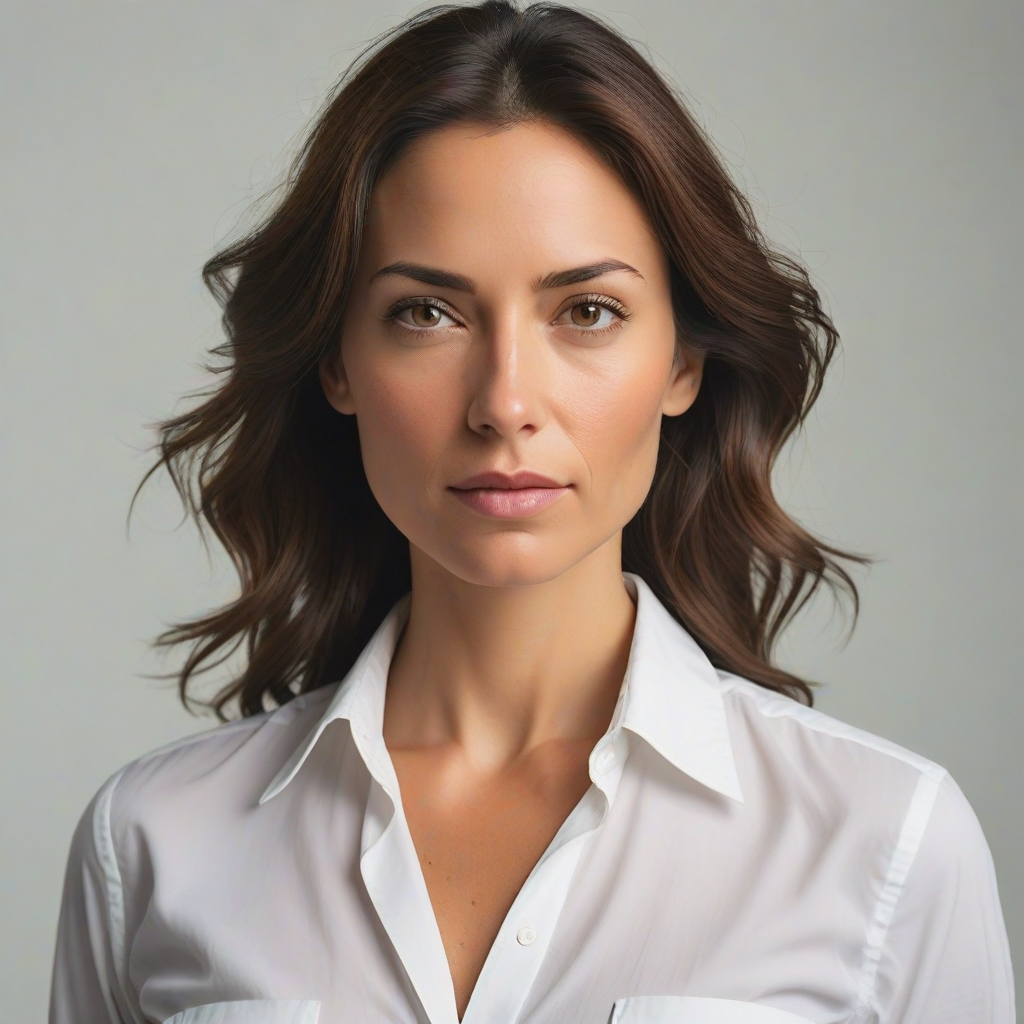
Stil ve yüz görsellerini ip_adapter_image parametresine bir liste olarak iletin.
generator = torch.Generator(device="cpu").manual_seed(0)

pipeline(
    prompt="wonderwoman",
    ip_adapter_image=[style_images, face_image],
    negative_prompt="monochrome, lowres, bad anatomy, worst quality, low quality",
).images[0]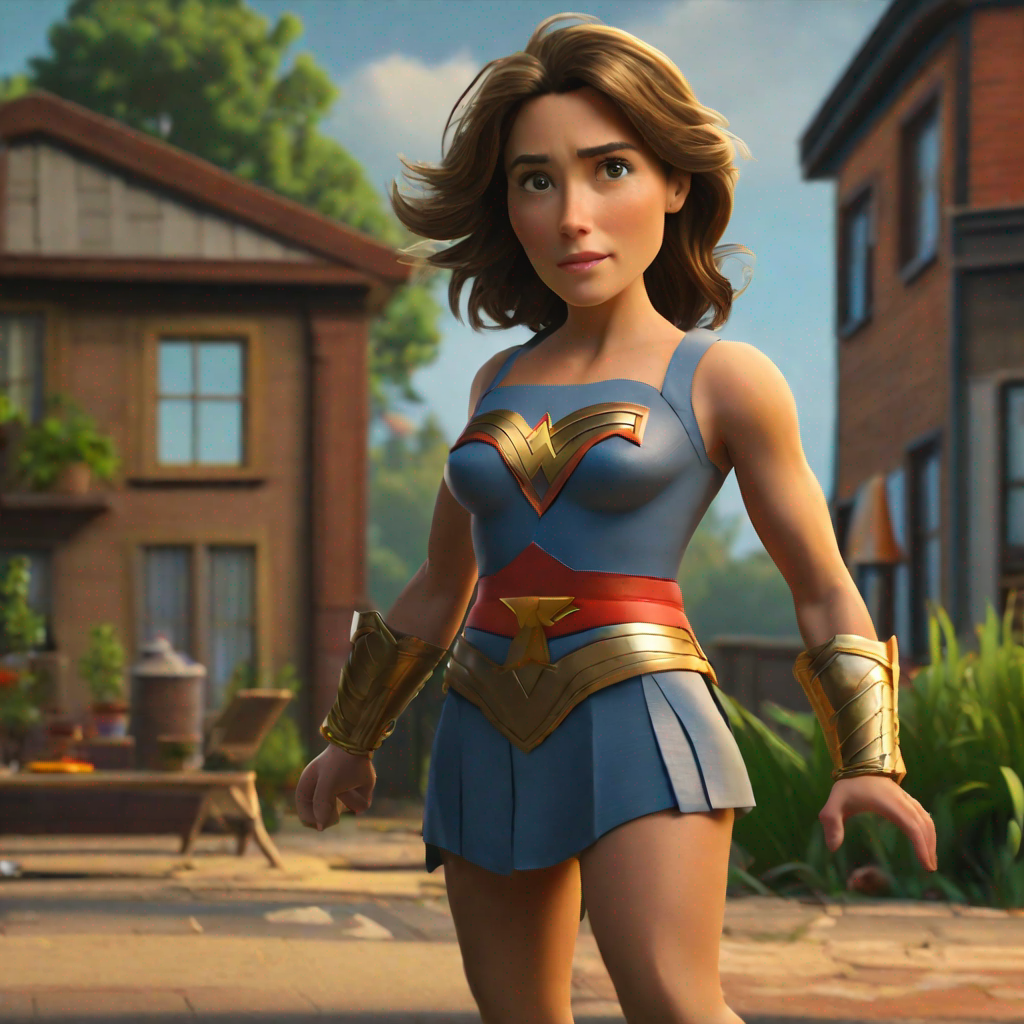
Yapısal kontrol
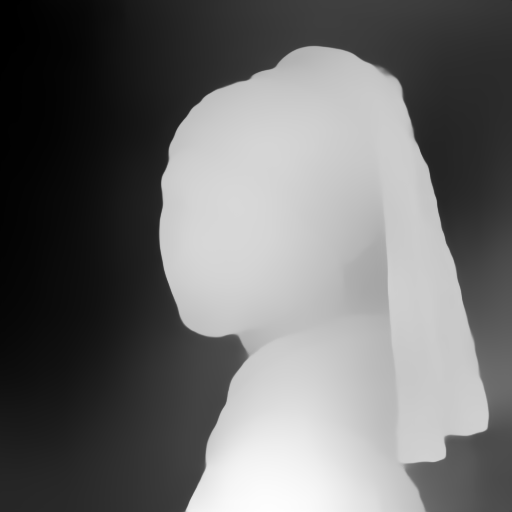
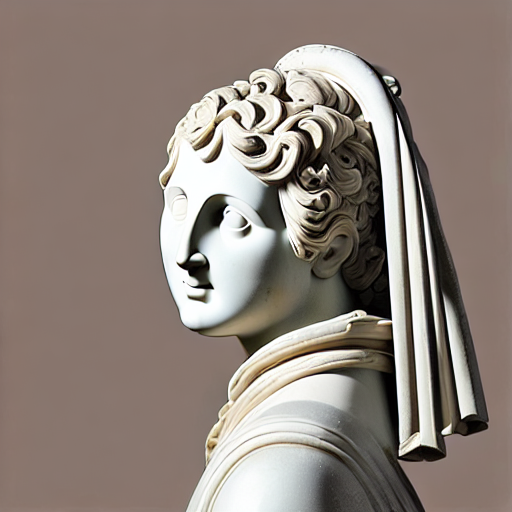
Yapısal kontrol için, IP-Adapter'ı derinlik haritaları, kenar haritaları, poz tahminleri ve daha fazlası ile koşullandırılmış ControlNet ile birleştirin.
Aşağıdaki örnek, derinlik haritalarına koşullu bir ControlNetModel kontrol noktasını yükler ve bunu bir IP-Adapter ile birleştirir.
import torch
from diffusers.utils import load_image
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel

controlnet = ControlNetModel.from_pretrained(
  "lllyasviel/control_v11f1p_sd15_depth",
  dtype=torch.float16
)

pipeline = StableDiffusionControlNetPipeline.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5",
    controlnet=controlnet,
    dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="models",
  weight_name="ip-adapter_sd15.bin"
)
Derinlik haritasını ve IP-Adapter görselini pipeline'a iletin.
depth_map = load_image("https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/depth.png")
ip_adapter_image = load_image("https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/statue.png")
pipeline(
  prompt="best quality, high quality",
  image=depth_map,
  ip_adapter_image=ip_adapter_image,
  negative_prompt="monochrome, lowres, bad anatomy, worst quality, low quality",
).images[0]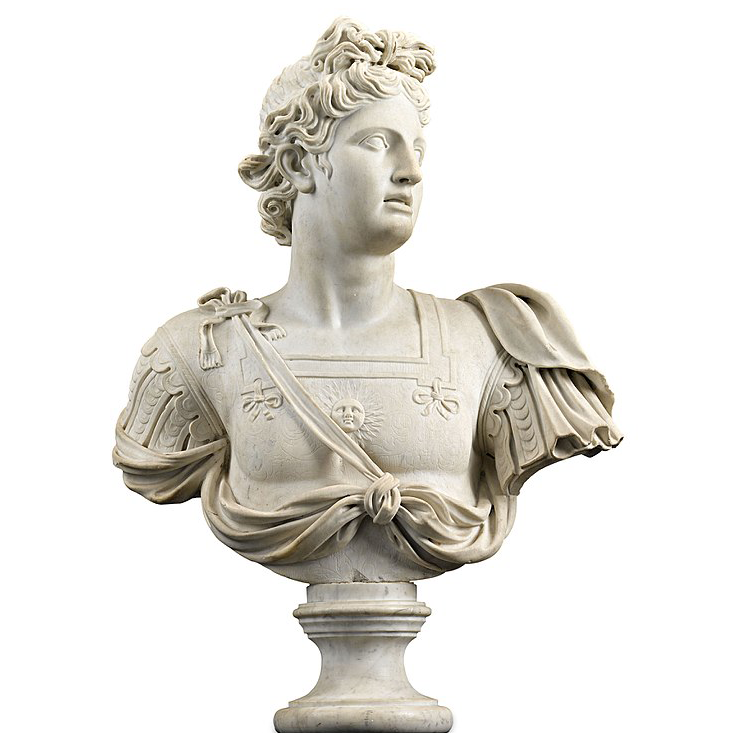
Stil ve yerleşim kontrolü
Stil ve yerleşim kontrolü için IP-Adapter'ı InstantStyle ile birleştirin. InstantStyle, stili (renk, doku, genel his) içerikten ayırır ve stili yalnızca stile özgü bloklarda uygular; böylece içerik alanları olduğu gibi kalır. Bu, daha güçlü stil tutarlılığı ve daha net yerleşim kontrolü sağlar.
IP-Adapter'ı yalnızca seçili katmanlarda set_ip_adapter_scale() ile etkinleştirin. Aşağıdaki örnek, modelin aşağı yönlü block_2 (yerleşim) ve yukarı yönlü block_0 (stil) bloklarında bunu etkinleştirir.
import torch
from diffusers import AutoPipelineForText2Image
from diffusers.utils import load_image

pipeline = AutoPipelineForText2Image.from_pretrained(
  "stabilityai/stable-diffusion-xl-base-1.0",
  dtype=torch.float16
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="sdxl_models",
  weight_name="ip-adapter_sdxl.bin"
)

scale = {
    "down": {"block_2": [0.0, 1.0]},
    "up": {"block_0": [0.0, 1.0, 0.0]},
}
pipeline.set_ip_adapter_scale(scale)
Stil görüntüsünü yükleyin ve bir görüntü oluşturun.
style_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/0052a70beed5bf71b92610a43a52df6d286cd5f3/diffusers/rabbit.jpg")

pipeline(
    prompt="a cat, masterpiece, best quality, high quality",
    ip_adapter_image=style_image,
    negative_prompt="text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
    guidance_scale=5,
).images[0]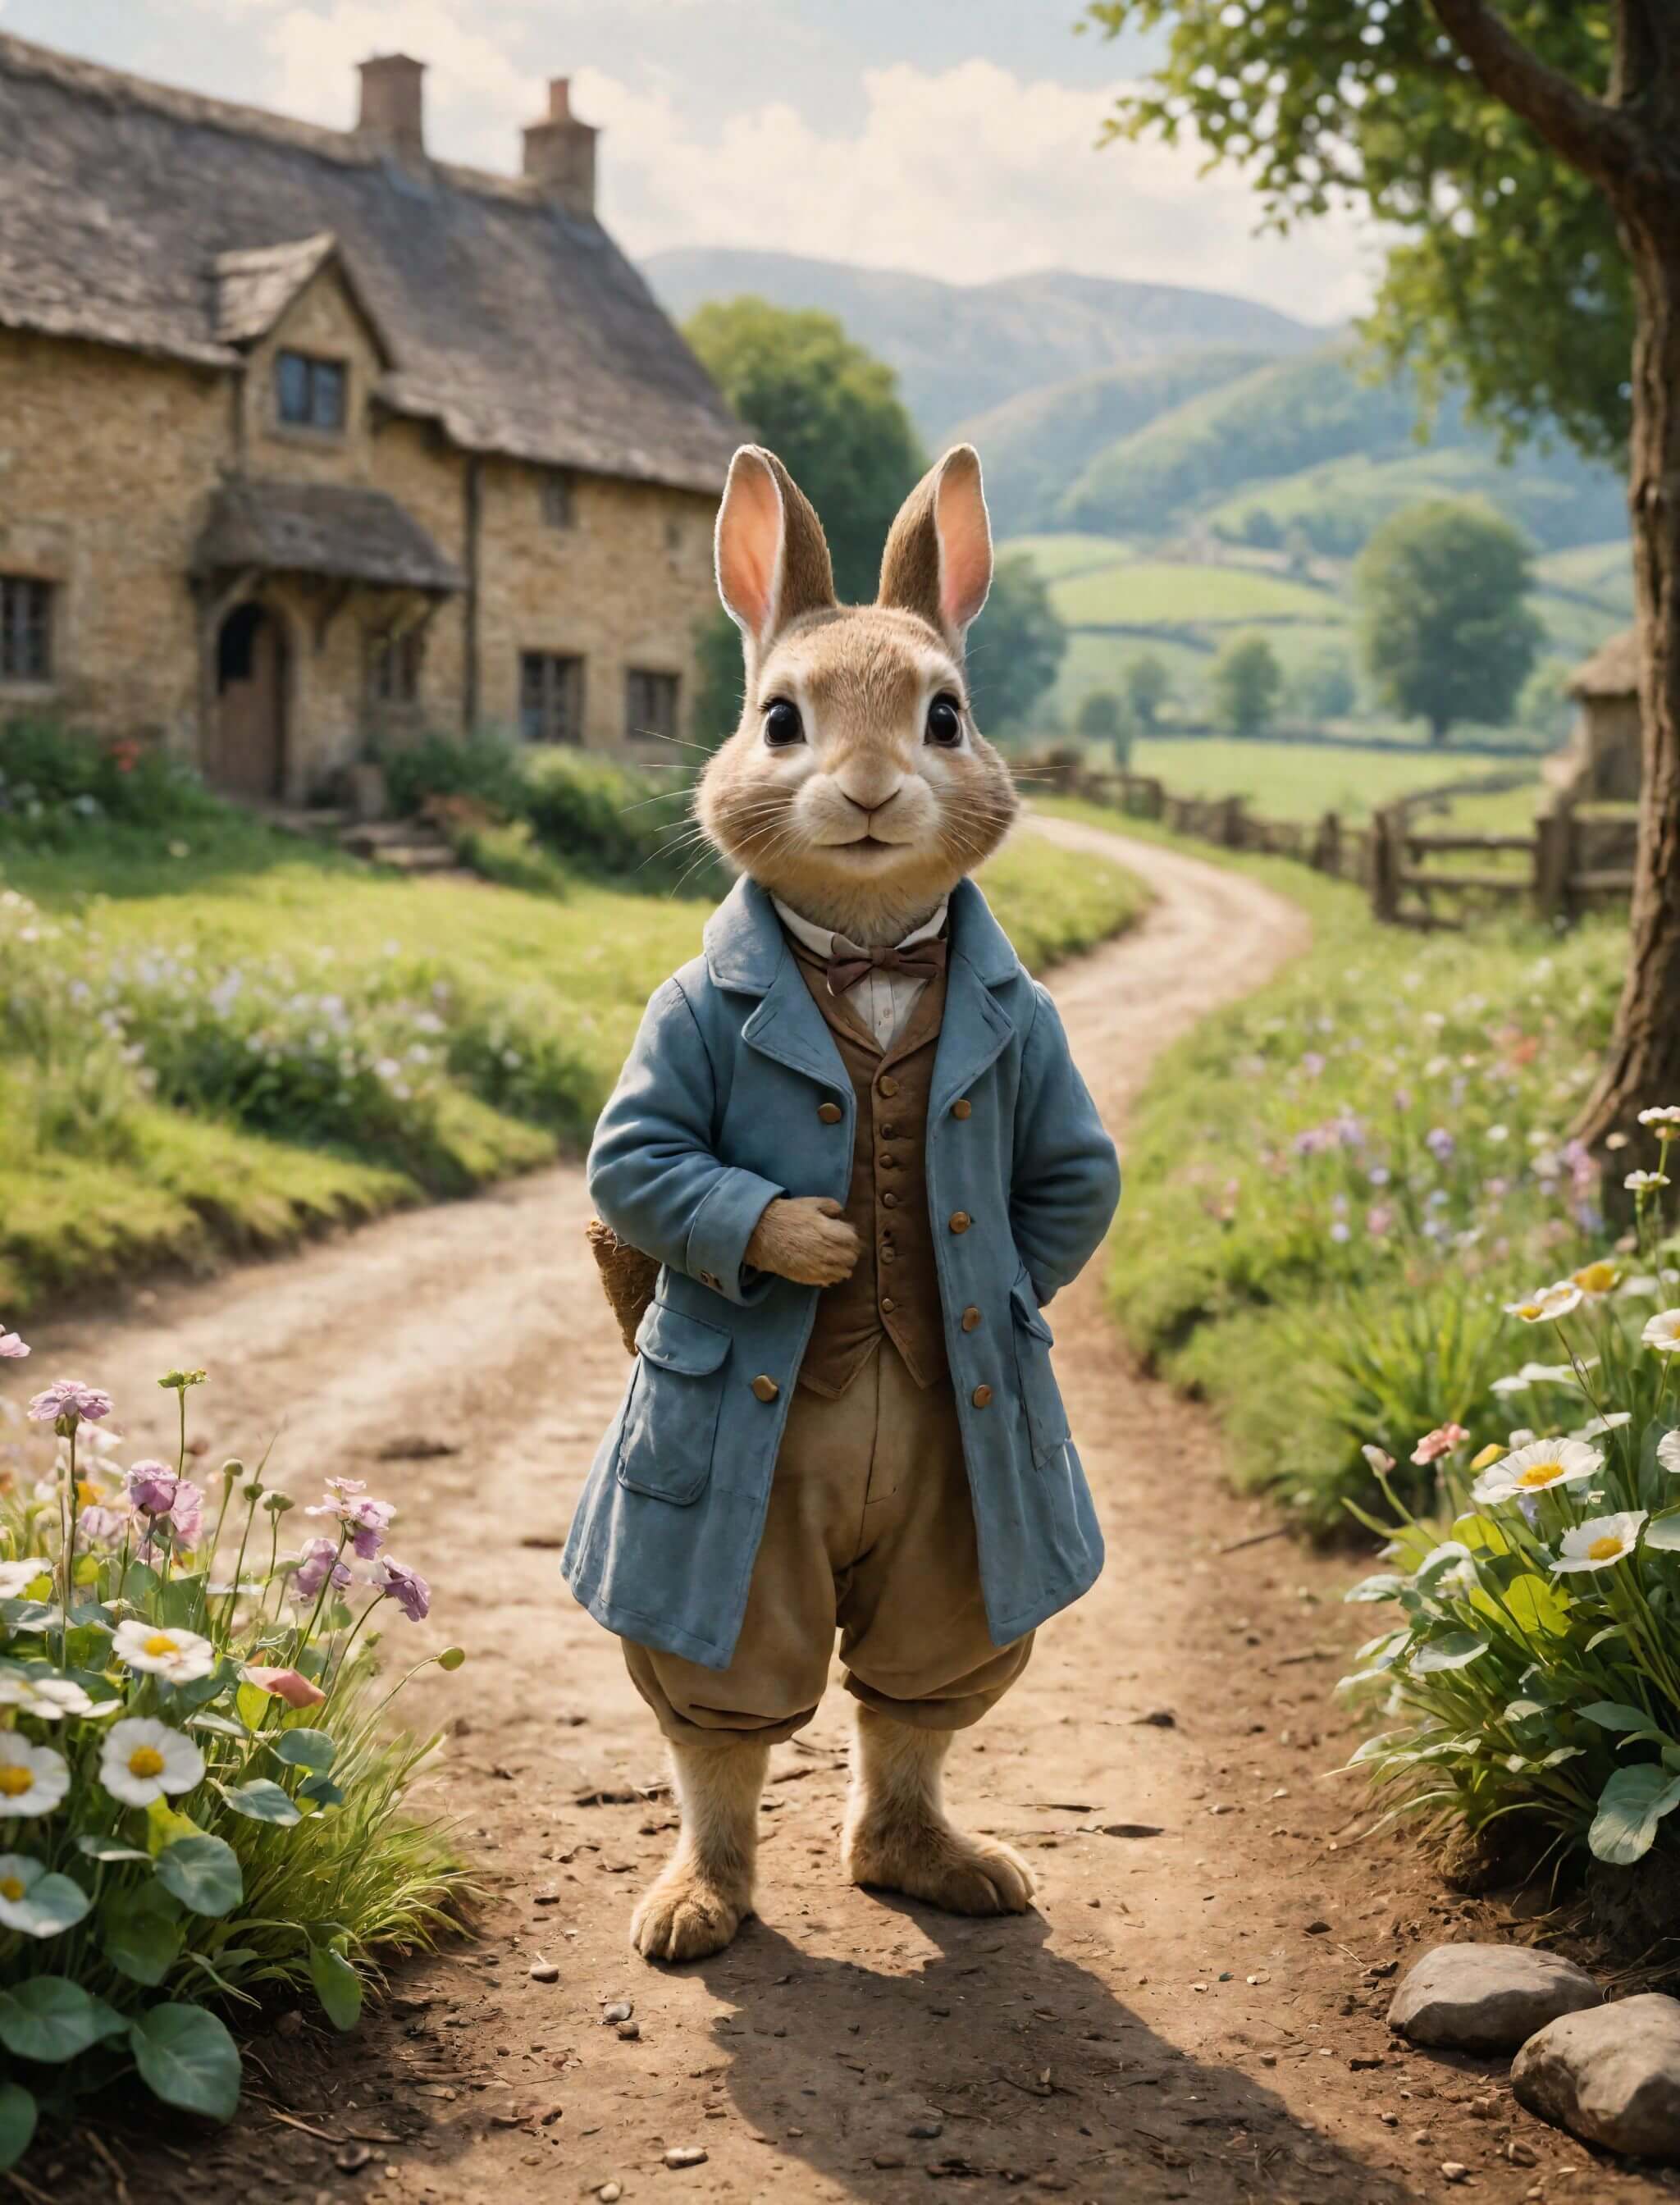
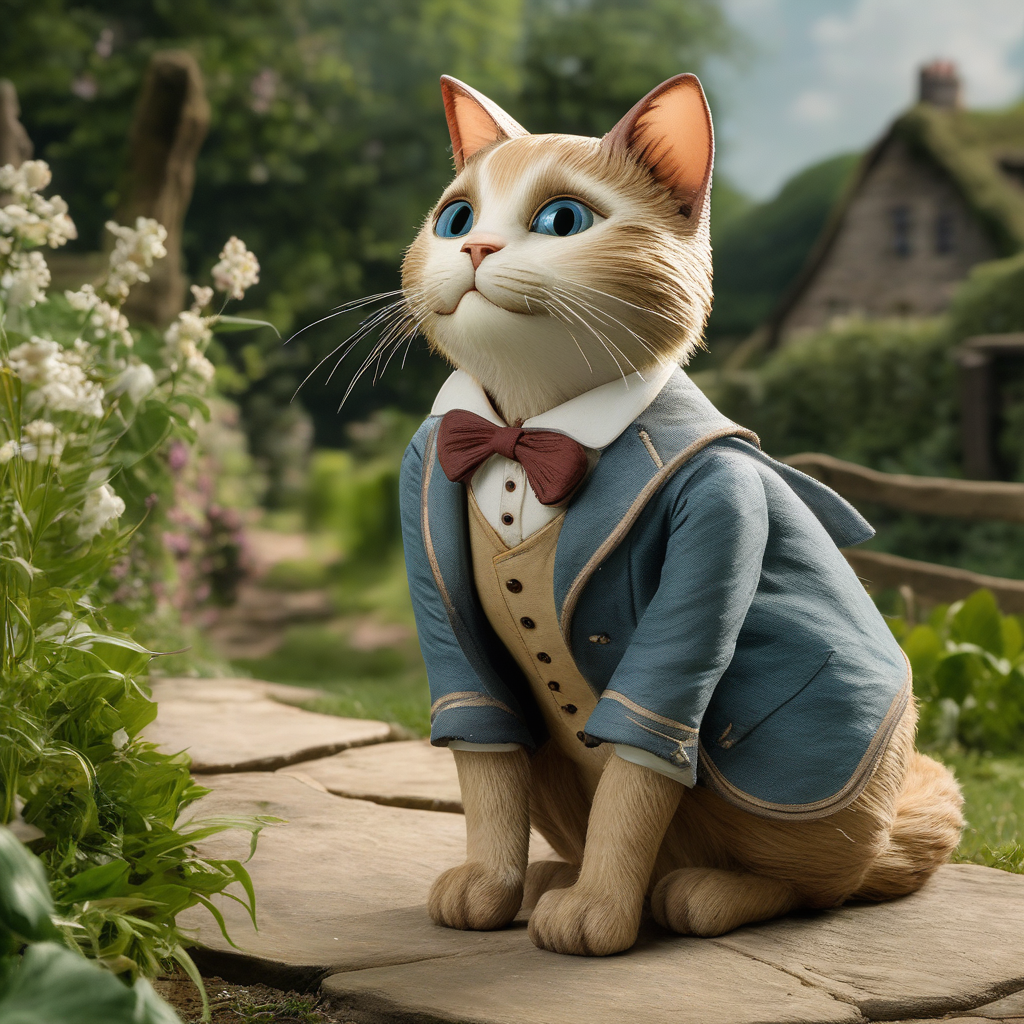
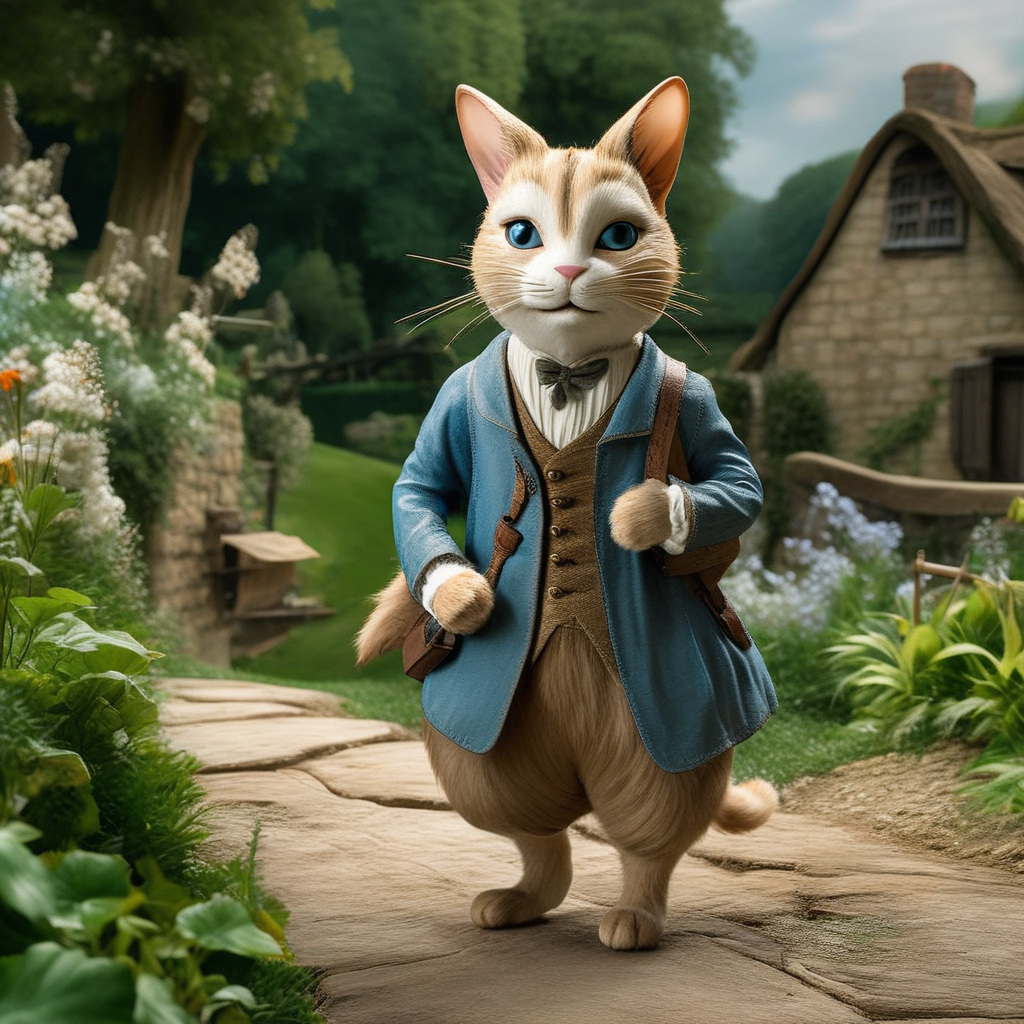
Aşağıdaki şekiller, InstantStyle’ın yalnızca stil aktivasyonunu (block_0 üstü) ile IP-Adapter’ın tüm katmanlarda etkinleştirilmesini karşılaştırır. Tüm katmanlar genellikle görüntü komutunu daha güçlü şekilde takip eder ve çeşitliliği azaltabilir. InstantStyle’ın yerleşimi koruyan davranışını istediğinizde yalnızca stil ölçeğini tercih edin.
scalesözlüğünde tüm katmanları belirtmeniz gerekmez. Dahil edilmeyen katmanlar 0 olarak ayarlanır; bu, IP-Adapter'ın devre dışı bırakıldığı anlamına gelir.
scale = {
    "up": {"block_0": [0.0, 1.0, 0.0]},
}
pipeline.set_ip_adapter_scale(scale)

pipeline(
    prompt="a cat, masterpiece, best quality, high quality",
    ip_adapter_image=style_image,
    negative_prompt="text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
    guidance_scale=5,
).images[0]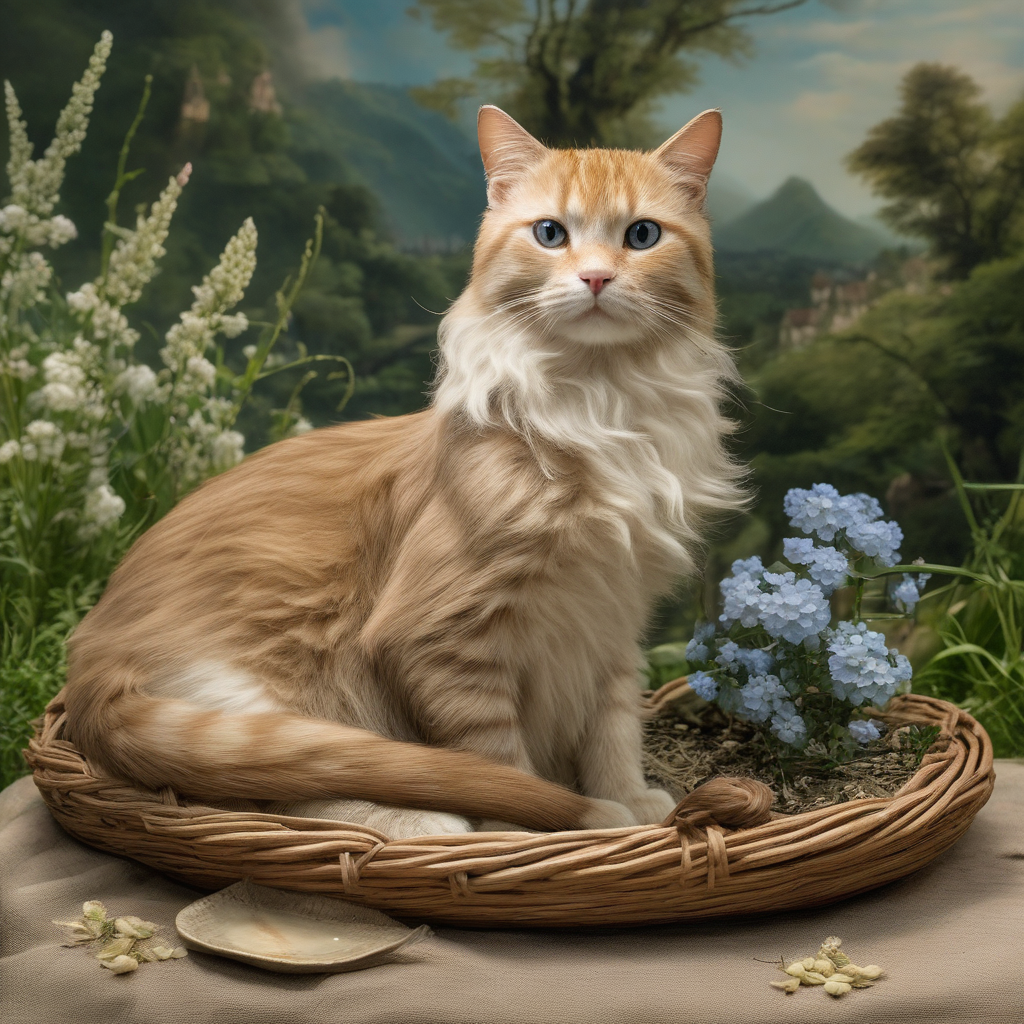
Anında üretim
IP-Adapter'ı, az adımlı üretim için bir LCM LoRA ile birleştirin.
import torch
from diffusers import DiffusionPipeline, LCMScheduler
from diffusers.utils import load_image

pipeline = DiffusionPipeline.from_pretrained(
  "sd-dreambooth-library/herge-style",
  dtype=torch.float16
)
pipeline.load_ip_adapter(
  "h94/IP-Adapter",
  subfolder="models",
  weight_name="ip-adapter_sd15.bin"
)
pipeline.load_lora_weights("latent-consistency/lcm-lora-sdv1-5")
pipeline.scheduler = LCMScheduler.from_config(pipeline.scheduler.config)
pipeline.enable_model_cpu_offload()

pipeline.set_ip_adapter_scale(0.4)
ip_adapter_image = load_image("https://user-images.githubusercontent.com/24734142/266492875-2d50d223-8475-44f0-a7c6-08b51cb53572.png")
pipeline(
    prompt="herge_style woman in armor, best quality, high quality",
    ip_adapter_image=ip_adapter_image,
    num_inference_steps=4,
    guidance_scale=1,
).images[0]