
Diffusers documentation
SDXL Turbo
SDXL Turbo
Stable Diffusion XL (SDXL) Turbo는 Axel Sauer, Dominik Lorenz, Andreas Blattmann, Robin Rombach가 Adversarial Diffusion Distillation에서 제안했습니다.
해당 논문의 초록은 다음과 같습니다:
Adversarial Diffusion Distillation(ADD)을 소개합니다. ADD는 대규모 기반 이미지 diffusion 모델의 샘플링을 1~4단계만으로 효율적으로 수행하면서도 높은 이미지 품질을 유지하는 새로운 학습 방법입니다. score distillation을 활용하여 대규모 off-the-shelf 이미지 diffusion 모델을 teacher signal로 활용하고, 이를 adversarial loss와 결합하여 1~2단계의 저단계 샘플링 환경에서도 높은 이미지 충실도를 보장합니다. 분석 결과, 제안한 모델은 단일 단계에서 기존 few-step 방법(GAN, Latent Consistency Models)보다 명확하게 우수한 성능을 보이며, 단 4단계만으로 최첨단 diffusion 모델(SDXL)의 성능에 도달합니다. ADD는 foundation model을 활용한 단일 단계, 실시간 이미지 합성을 가능하게 한 최초의 방법입니다.
팁
- SDXL Turbo는 SDXL과 정확히 동일한 아키텍처를 사용하므로 동일한 API를 제공합니다. 자세한 내용은 SDXL API 참고 문서를 참조하세요.
- SDXL Turbo는
guidance_scale=0.0으로 설정하여 guidance scale을 비활성화해야 합니다. - SDXL Turbo는 스케줄러에
timestep_spacing='trailing'을 사용하고 1~4단계 사이를 사용해야 합니다. - SDXL Turbo는 512x512 크기의 이미지를 생성하도록 학습되었습니다.
- SDXL Turbo는 오픈 액세스이지만 오픈 소스는 아니므로, 상업적 목적으로 사용하려면 모델 라이선스를 구매해야 할 수 있습니다. 자세한 내용은 공식 모델 카드를 참고하세요.
공식 base 및 refiner 모델 체크포인트는 Stability AI Hub 조직에서 확인해 보세요!
다음 라이브러리가 설치되어 있는지 확인하세요.
# uncomment to install the necessary libraries in Colab
#!pip install -q diffusers transformers accelerate
모델 체크포인트 로드
모델 가중치가 Hub 또는 로컬에서 별도의 하위 폴더에 저장된 경우, from_pretrained() 메서드를 사용해야 합니다:
from diffusers import AutoPipelineForText2Image
import torch

pipeline = AutoPipelineForText2Image.from_pretrained("stabilityai/sdxl-turbo", dtype=torch.float16, variant="fp16")
pipeline = pipeline.to("cuda")  # or "mps", "xpu", "cpu"
Hub 또는 로컬에서 단일 파일 형식(.ckpt 또는 .safetensors)으로 저장된 모델 체크포인트를 로드하려면 from_single_file() 메서드를 사용할 수도 있습니다. 이 로드 방법을 사용하려면 timestep_spacing="trailing"을 설정해야 합니다(더 나은 결과를 얻기 위해 다른 스케줄러 구성 값을 자유롭게 실험해 보세요):
from diffusers import StableDiffusionXLPipeline, EulerAncestralDiscreteScheduler
import torch

pipeline = StableDiffusionXLPipeline.from_single_file(
    "https://huggingface.co/stabilityai/sdxl-turbo/blob/main/sd_xl_turbo_1.0_fp16.safetensors",
    dtype=torch.float16, variant="fp16")
pipeline = pipeline.to("cuda")  # or "mps", "xpu", "cpu"
pipeline.scheduler = EulerAncestralDiscreteScheduler.from_config(pipeline.scheduler.config, timestep_spacing="trailing")
텍스트-이미지
텍스트-이미지 생성의 경우 텍스트 프롬프트를 전달합니다. 기본적으로 SDXL Turbo는 512x512 이미지를 생성하며, 이 해상도가 가장 좋은 결과를 제공합니다. height와 width 매개변수를 768x768 또는 1024x1024로 설정해 볼 수 있지만, 이렇게 하면 품질이 저하될 수 있습니다.
모델이 해당 설정 없이 학습되었으므로 비활성화하려면 guidance_scale을 0.0으로 설정해야 합니다. 단일 추론 단계만으로도 고품질 이미지를 생성할 수 있습니다.
단계 수를 2, 3 또는 4로 늘리면 이미지 품질이 향상됩니다.
from diffusers import AutoPipelineForText2Image
import torch

pipeline_text2image = AutoPipelineForText2Image.from_pretrained("stabilityai/sdxl-turbo", dtype=torch.float16, variant="fp16")
pipeline_text2image = pipeline_text2image.to("cuda")  # or "mps", "xpu", "cpu"

prompt = "A cinematic shot of a baby racoon wearing an intricate italian priest robe."

image = pipeline_text2image(prompt=prompt, guidance_scale=0.0, num_inference_steps=1).images[0]
image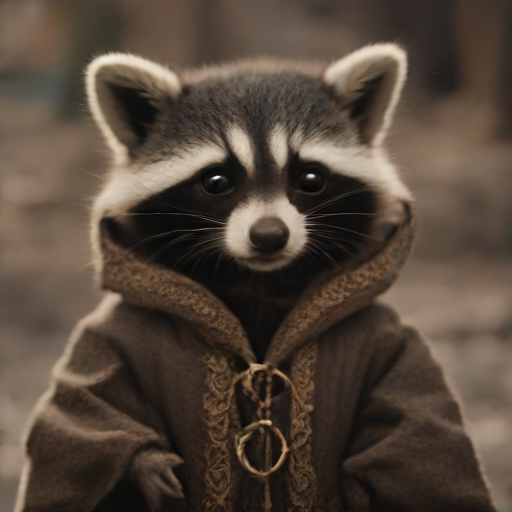
이미지-이미지
이미지-이미지 생성의 경우 num_inference_steps * strength가 1 이상인지 확인하세요.
이미지-이미지 파이프라인은 int(num_inference_steps * strength) 단계 동안 실행되며, 예를 들어 아래 예시에서는 0.5 * 2.0 = 1 단계로 실행됩니다.
from diffusers import AutoPipelineForImage2Image
from diffusers.utils import load_image, make_image_grid

# use from_pipe to avoid consuming additional memory when loading a checkpoint
pipeline_image2image = AutoPipelineForImage2Image.from_pipe(pipeline_text2image).to("cuda")  # or "mps", "xpu", "cpu"

init_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cat.png")
init_image = init_image.resize((512, 512))

prompt = "cat wizard, gandalf, lord of the rings, detailed, fantasy, cute, adorable, Pixar, Disney, 8k"

image = pipeline_image2image(prompt, image=init_image, strength=0.5, guidance_scale=0.0, num_inference_steps=2).images[0]
make_image_grid([init_image, image], rows=1, cols=2)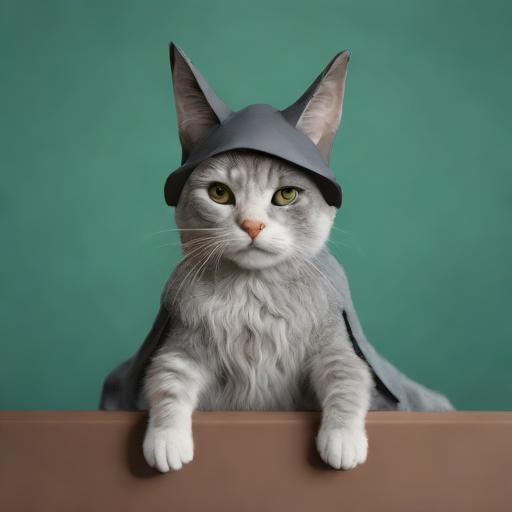
SDXL Turbo를 더 빠르게
- PyTorch 2.0 이상 버전을 사용하는 경우 UNet을 컴파일하세요. 첫 번째 추론 실행은 매우 느리지만, 이후 실행은 훨씬 빠릅니다.
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)- 기본 VAE를 사용할 때는 각 생성 작업 전후에 발생하는 비용이 큰
dtype변환을 피하기 위해float32로 유지하세요. 이 작업은 첫 번째 생성 전에 한 번만 수행하면 됩니다:
pipe.upcast_vae()
대안으로, float32로 업캐스팅할 필요가 없는 커뮤니티 멤버 @madebyollin가 만든 16-bit VAE를 사용할 수도 있습니다.